GPQA Diamond
- OpenAI
- Anthropic
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| Claude Opus 4.716 Apr 2026 · Anthropic | 94.2% | Introducing Claude Opus 4.7Source image | Not yet |
| GPT-5.45 Mar 2026 · OpenAI | 92.8% | Introducing GPT-5.4 | Not yet |
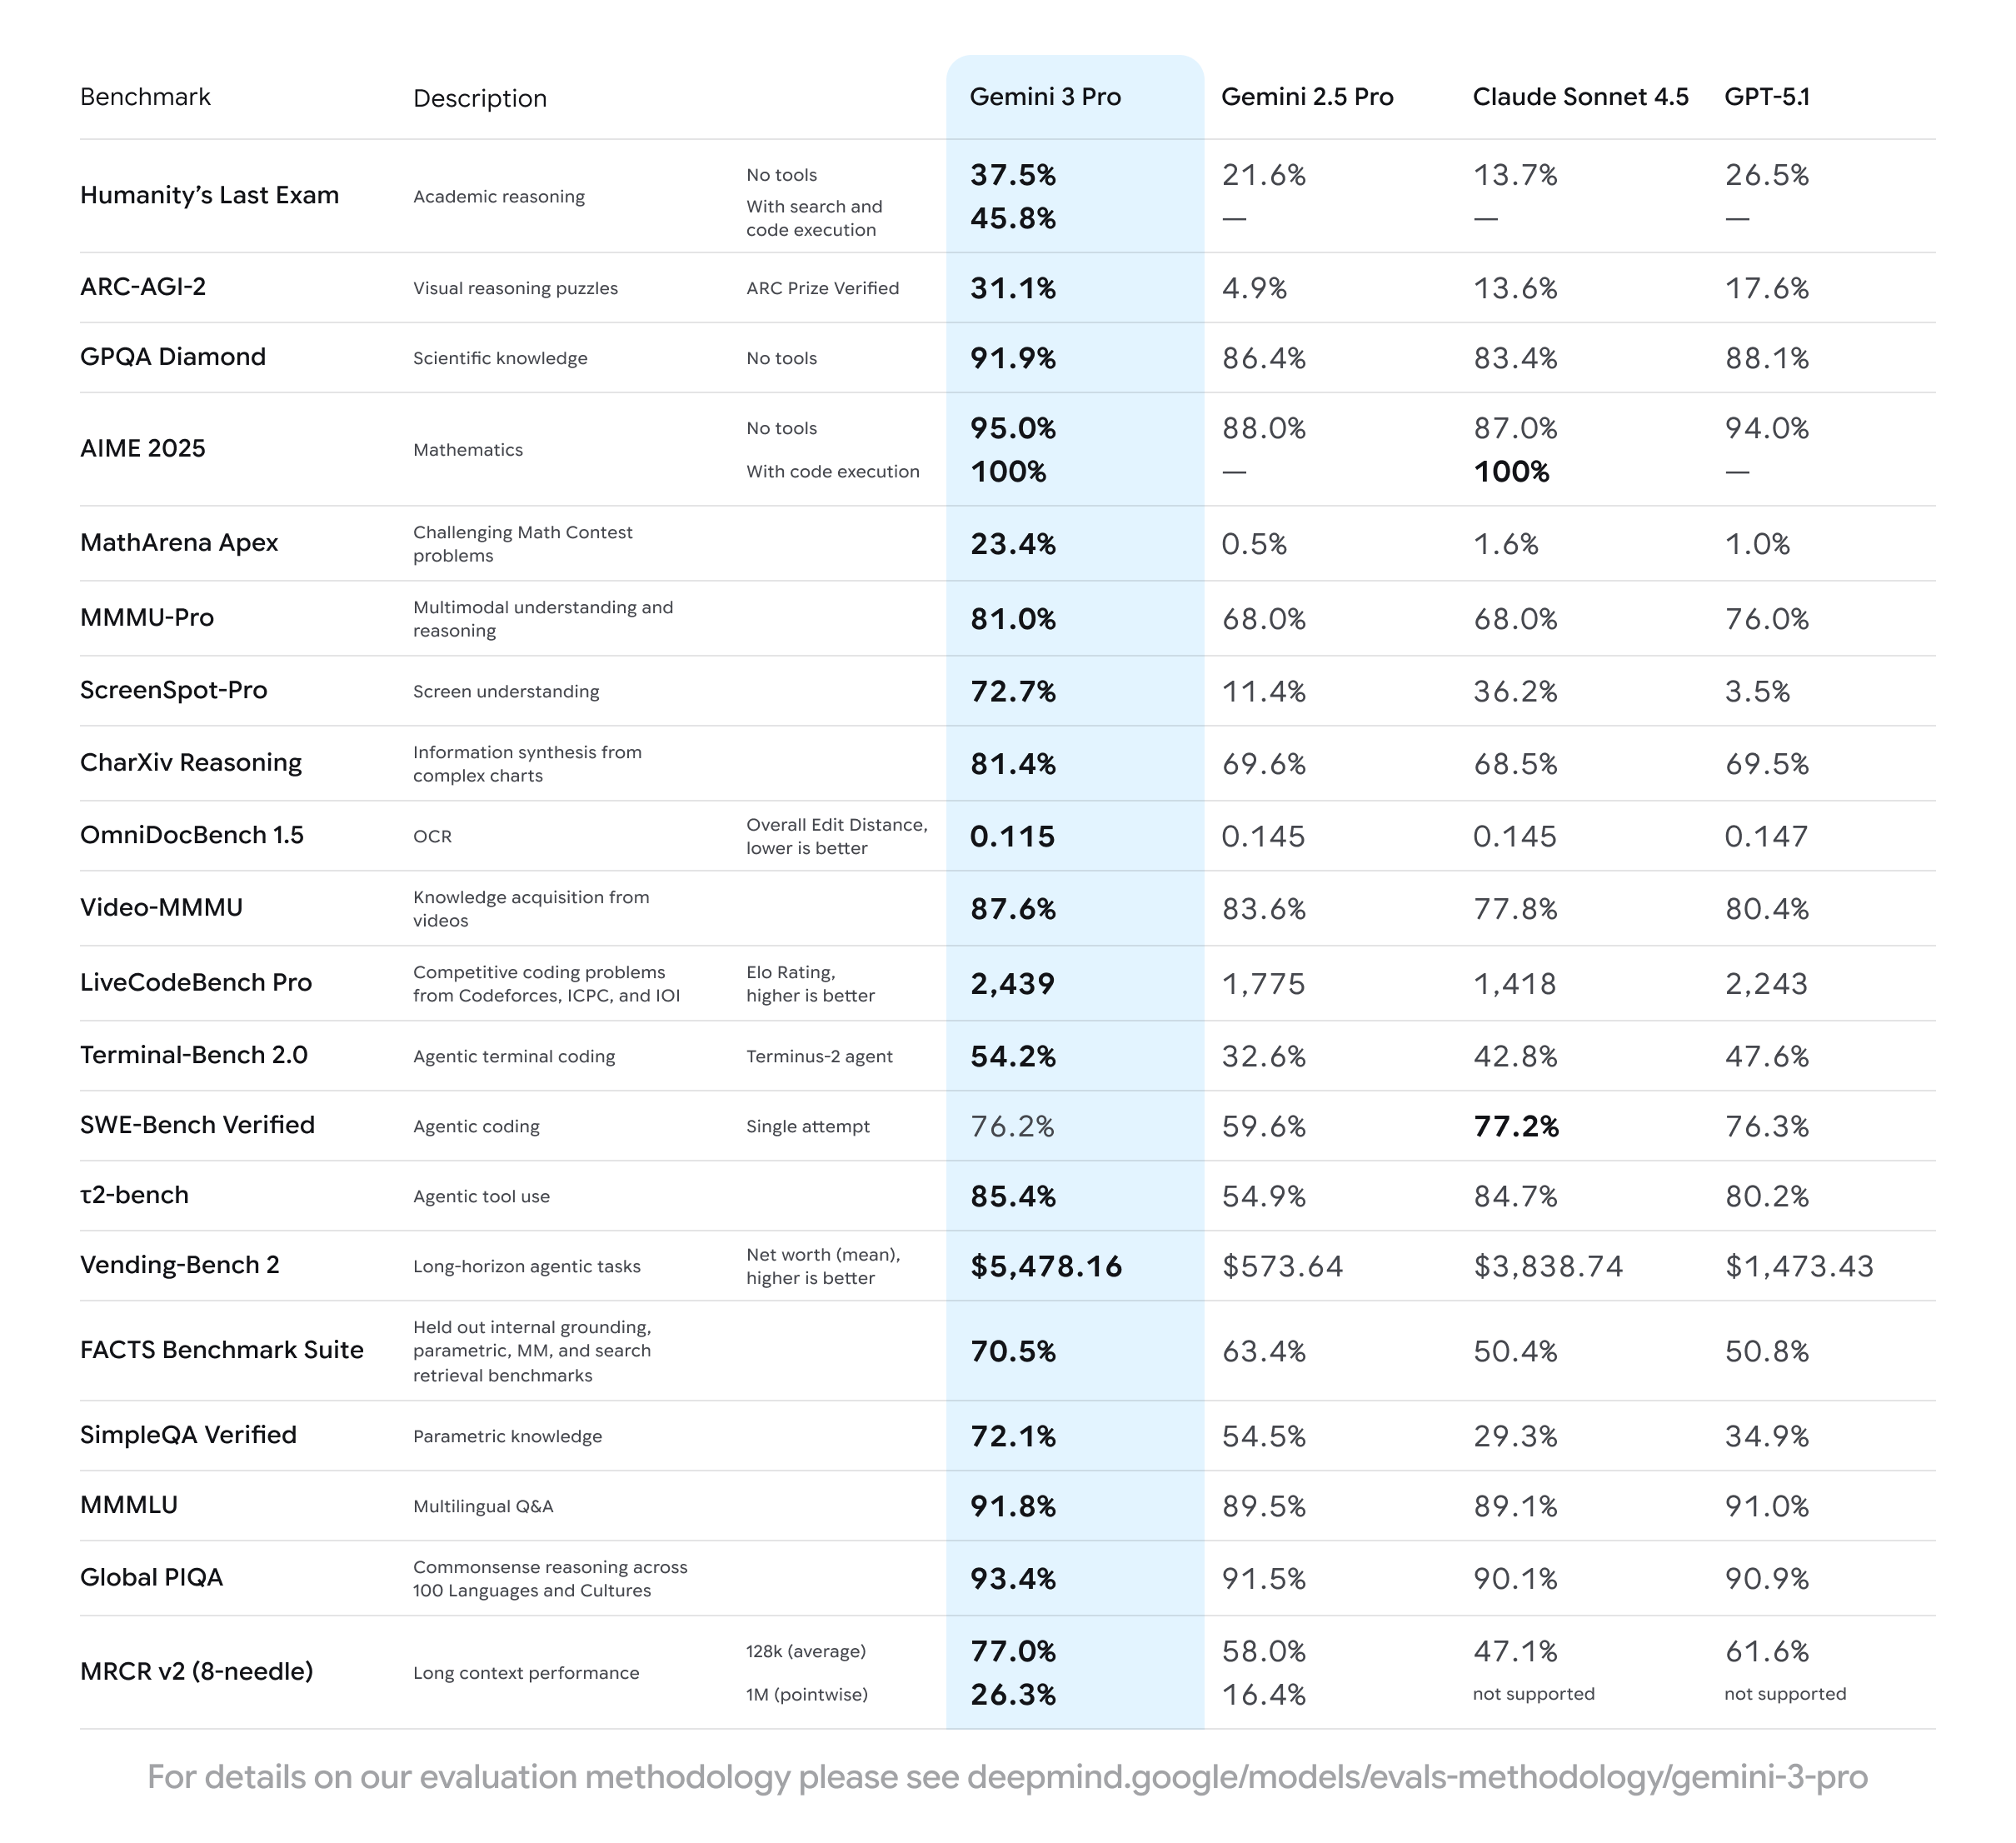
| Gemini 3.1 Pro19 Feb 2026 · Google | 94.3% | Gemini 3.1 Pro: A smarter model for your most complex tasksno tools; Thinking (High)Source image | Not yet |
| Claude Opus 4.65 Feb 2026 · Anthropic | 91.3% | Claude Opus 4.6Source image | Not yet |
| GPT-5.211 Dec 2025 · OpenAI | 92.4% | Introducing GPT-5.2no tools | Not yet |
| Claude Opus 4.524 Nov 2025 · Anthropic | 87.0% | Introducing Claude Opus 4.564K thinking budget, default effort (high), averaged over 5 trials (methodology)Source image | Not yet |
| Gemini 3 Pro18 Nov 2025 · Google | 91.9% | Start building with Gemini 3no toolsSource image | Not yet |
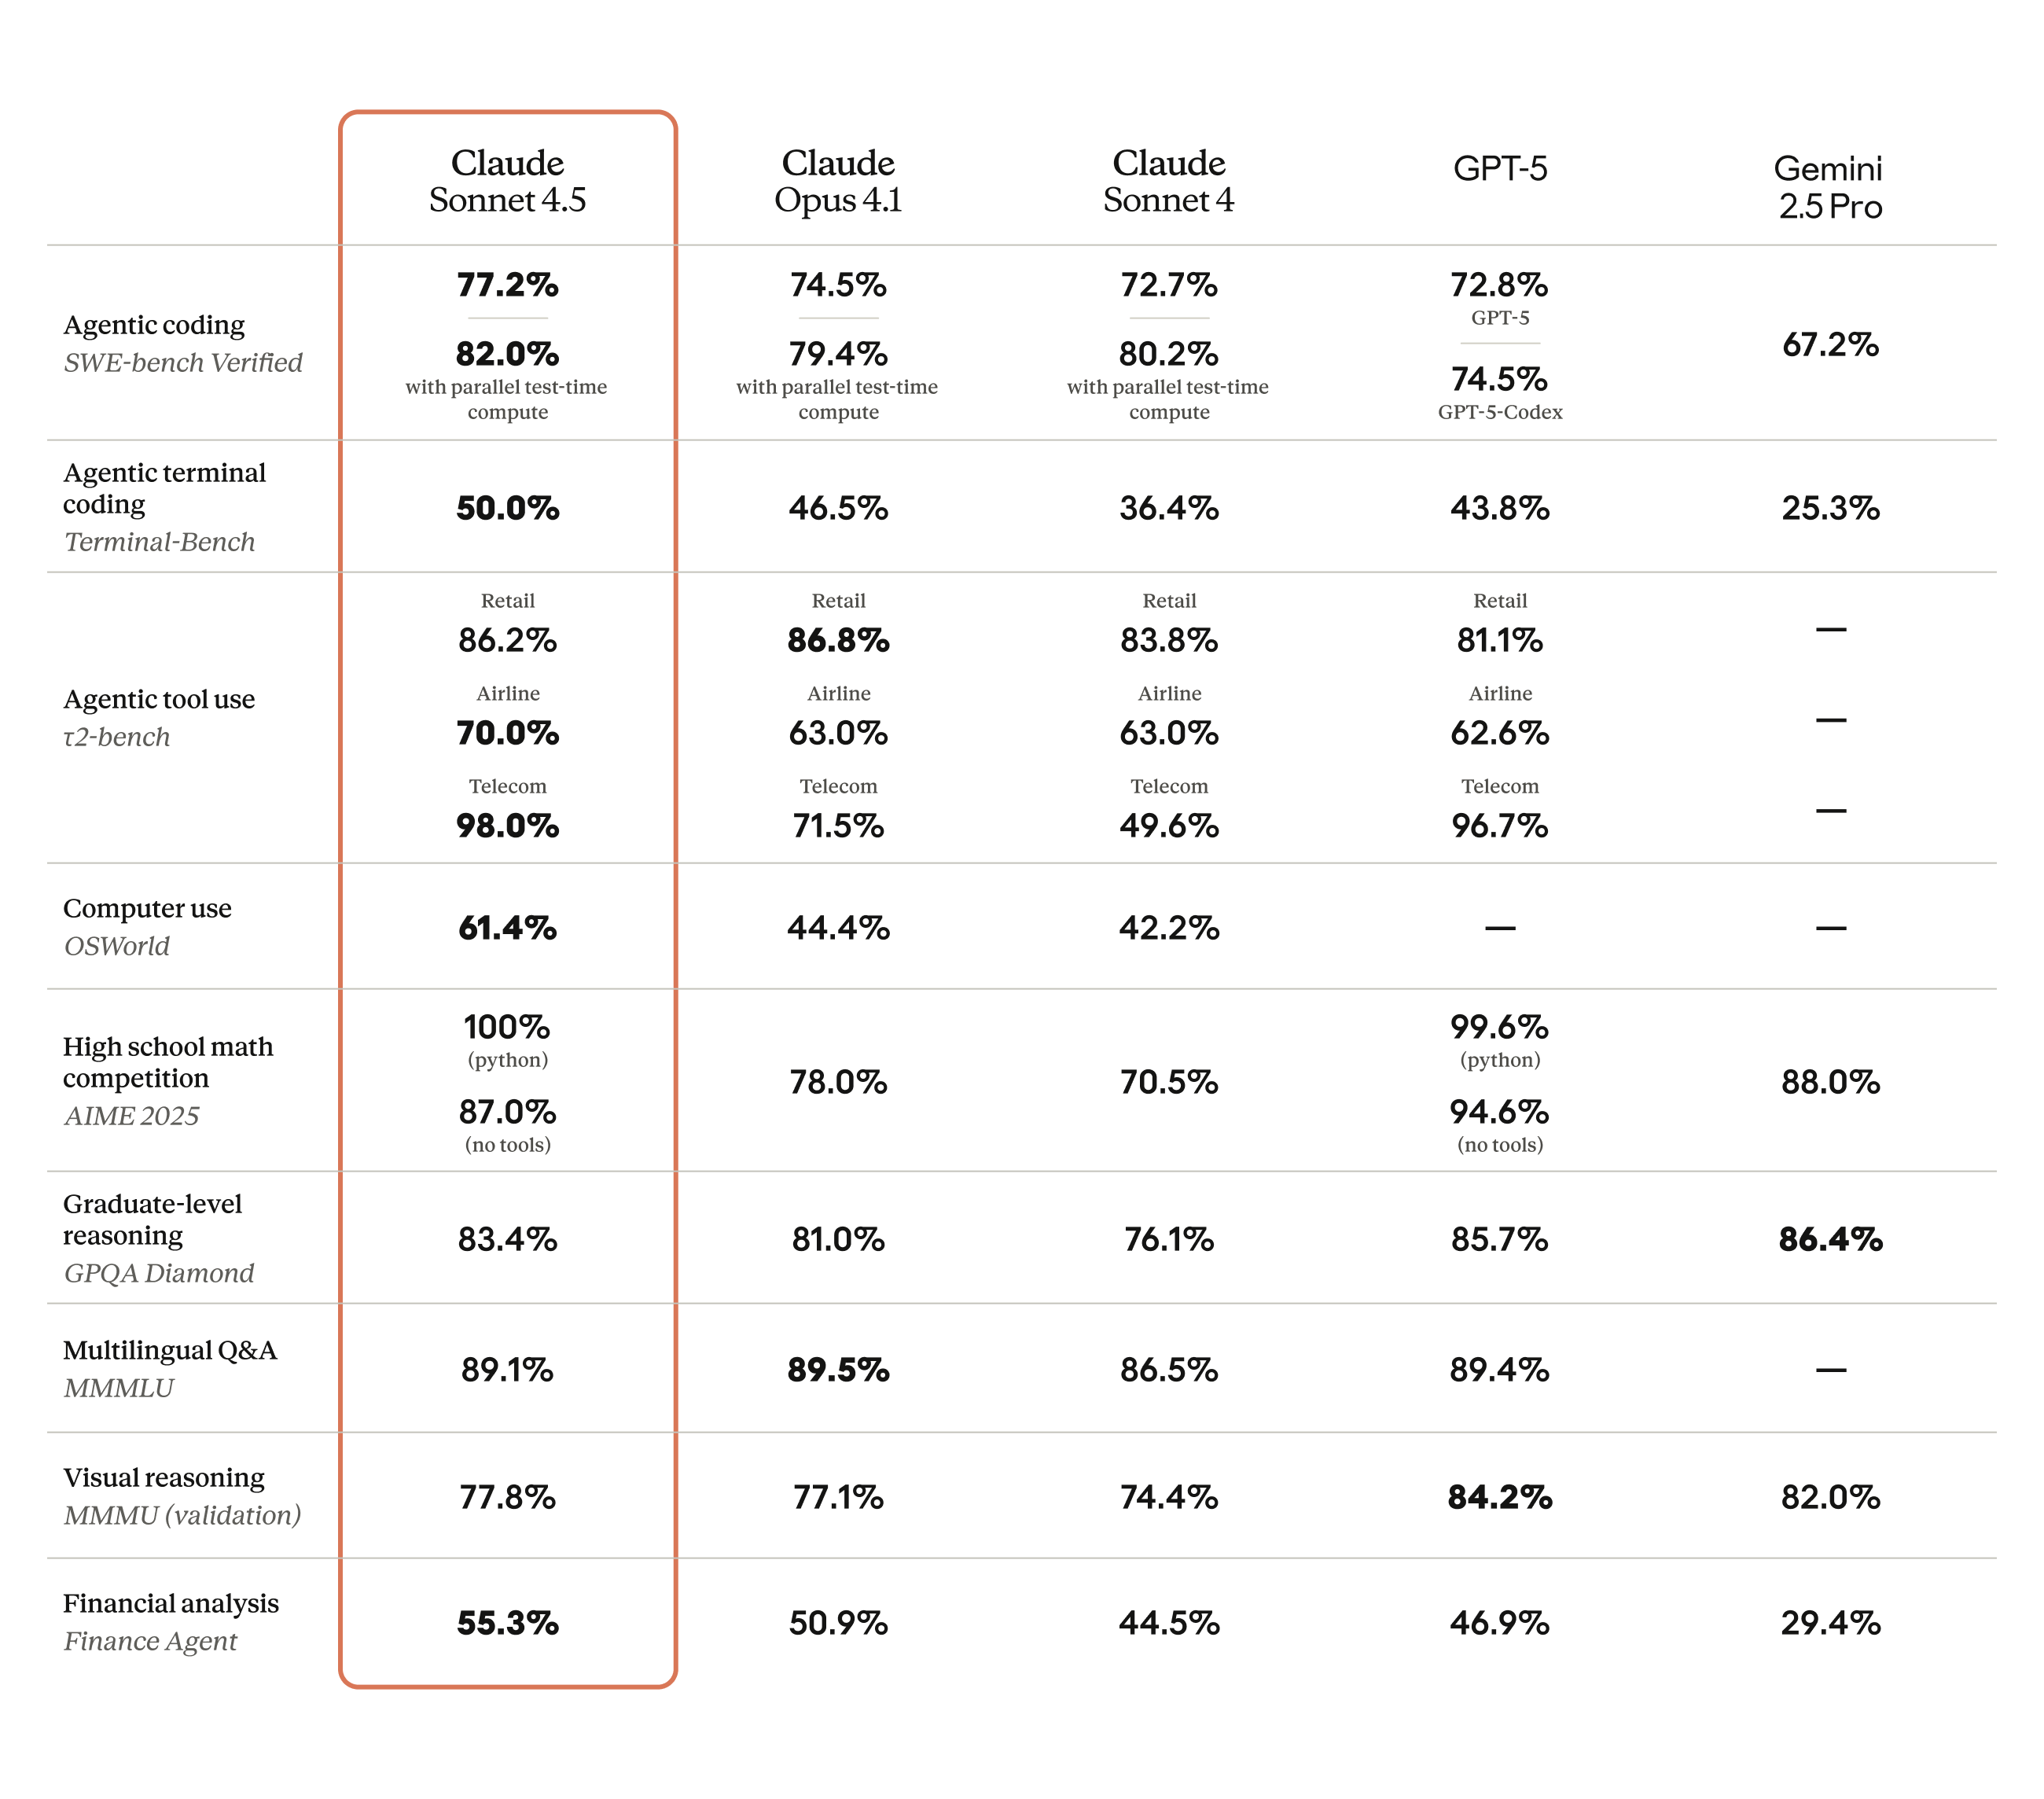
| Claude Sonnet 4.529 Sep 2025 · Anthropic | 83.4% | Introducing Claude Sonnet 4.5Source image | Not yet |
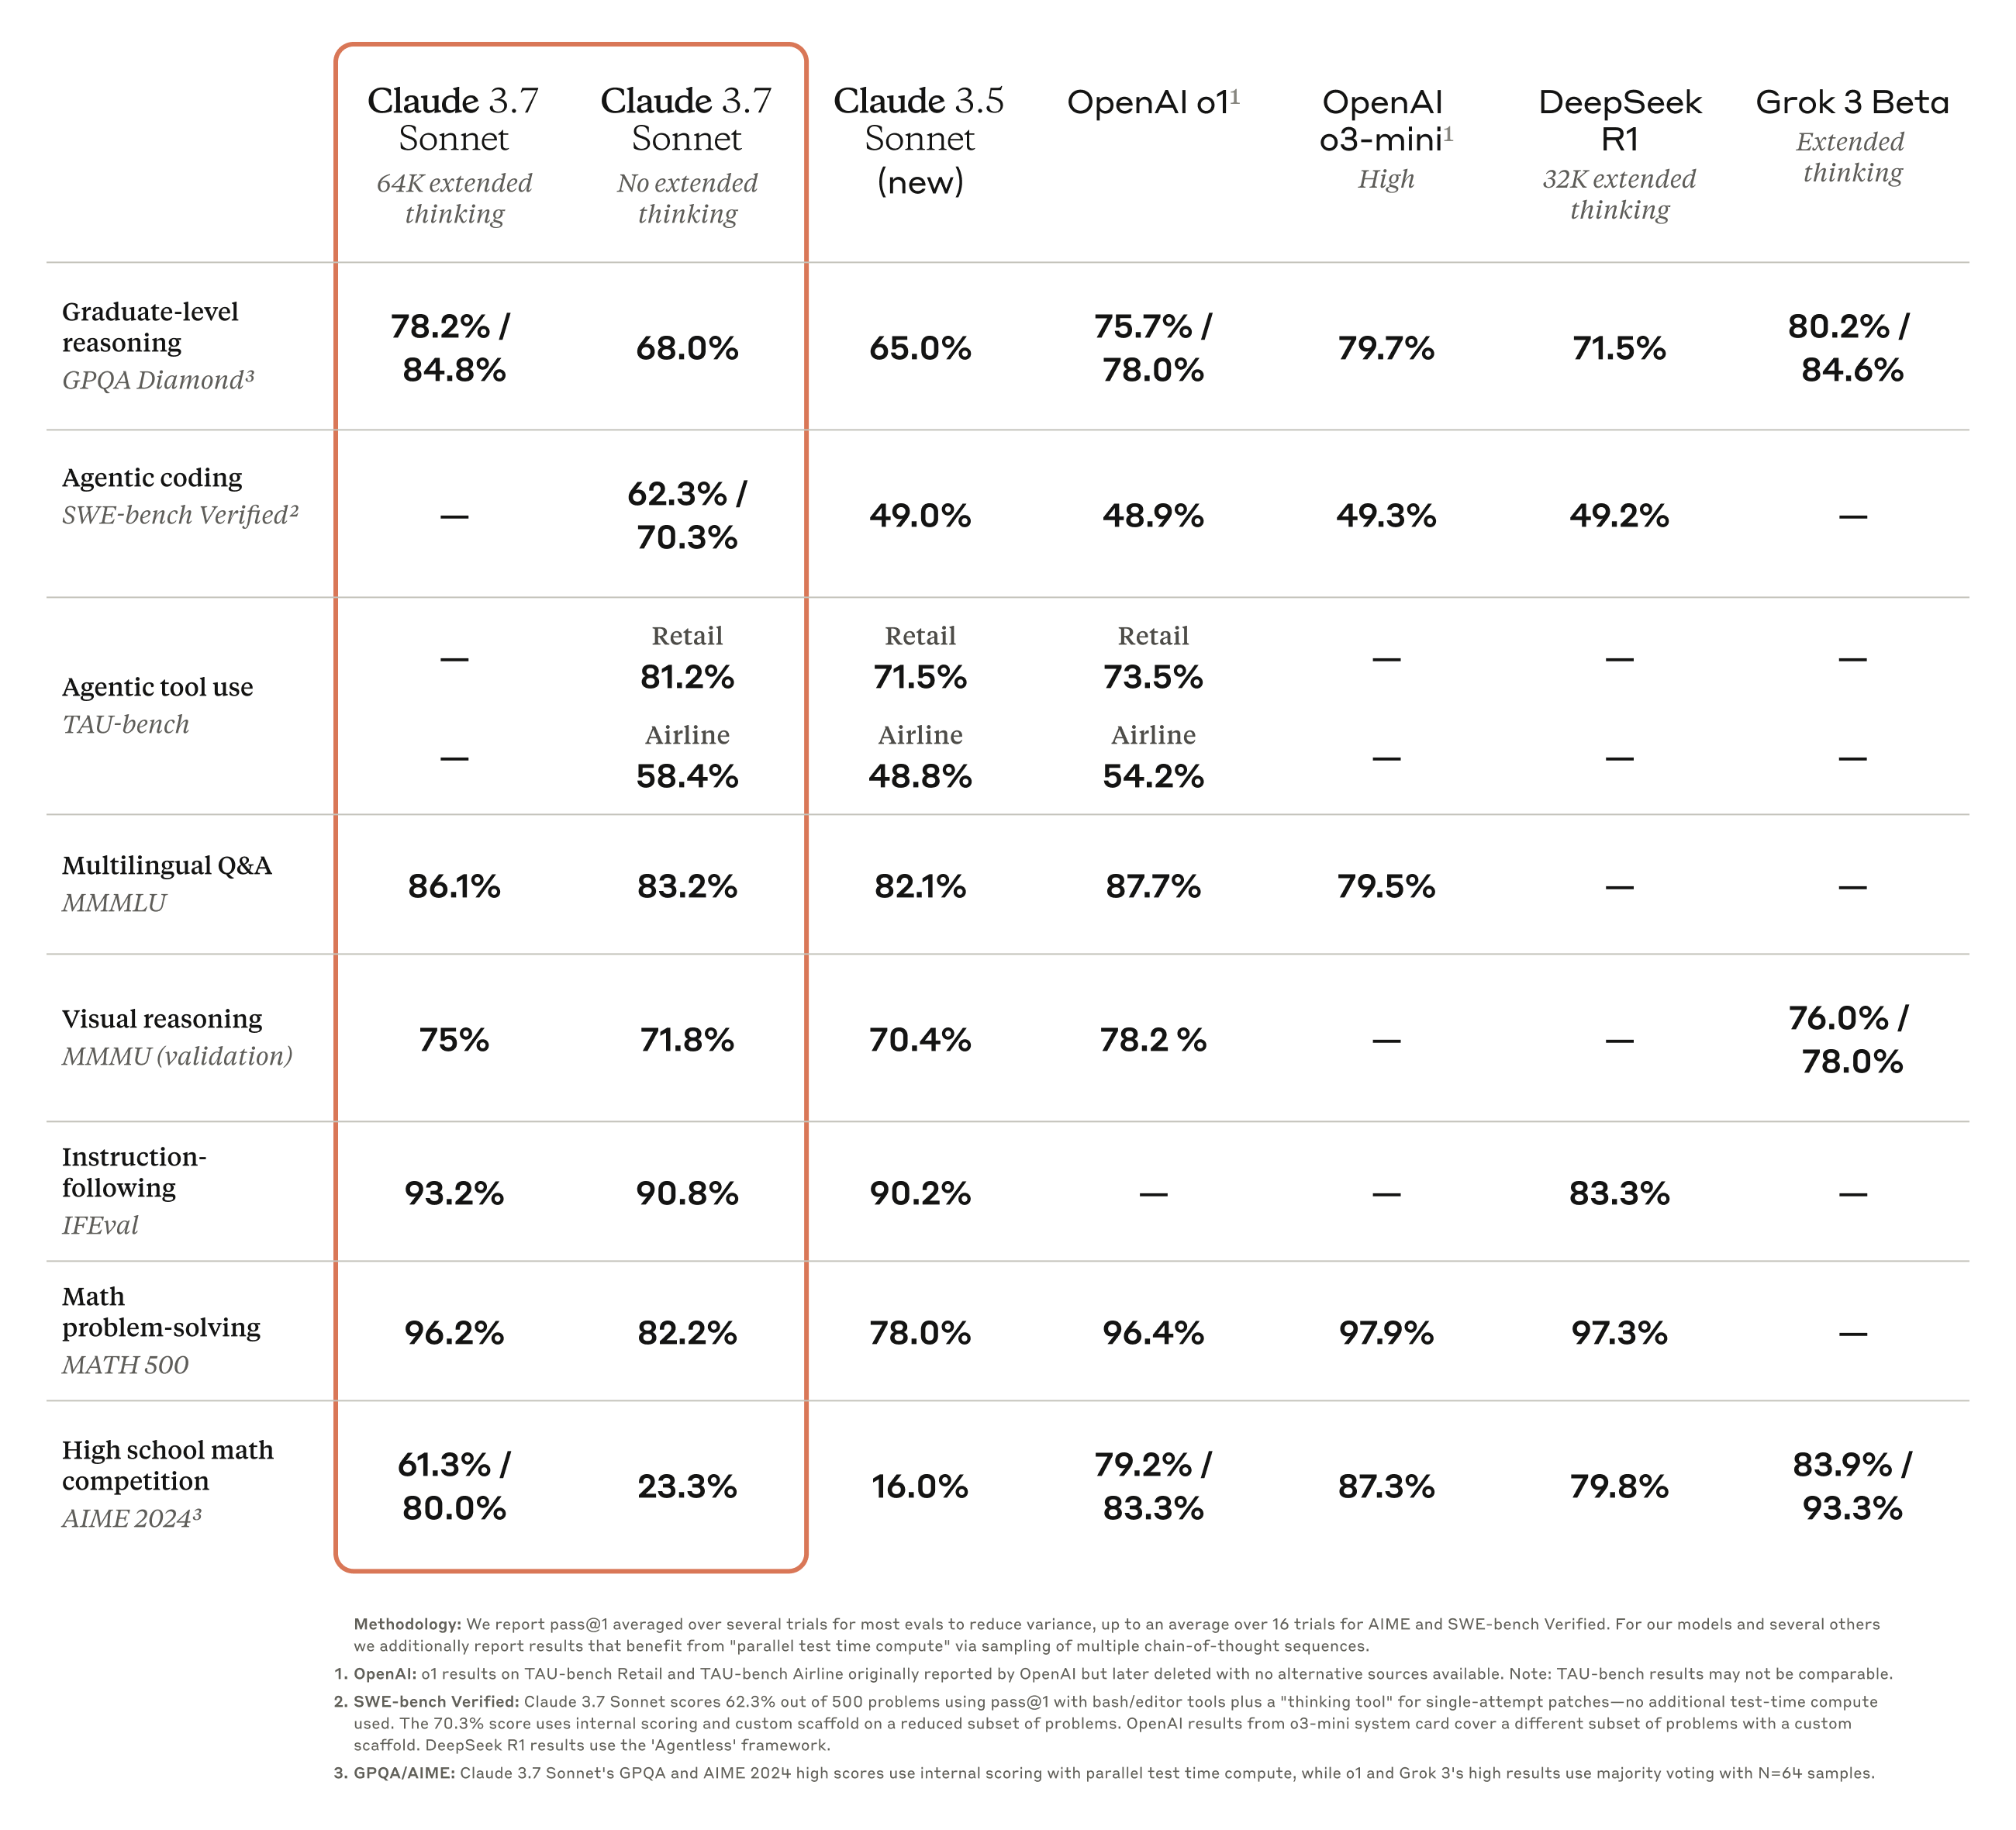
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 78.2% | Claude 3.7 Sonnet and Claude Codepass@1 averaged over several trials (methodology note)Source image | Yes |
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 84.8% | Claude 3.7 Sonnet and Claude Codeparallel test-time compute; internal scoring with parallel test-time compute (footnote 3)Source image | Yes |
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 68.0% | Claude 3.7 Sonnet and Claude Codeanother report, not charted; no extended thinkingSource image | Yes |
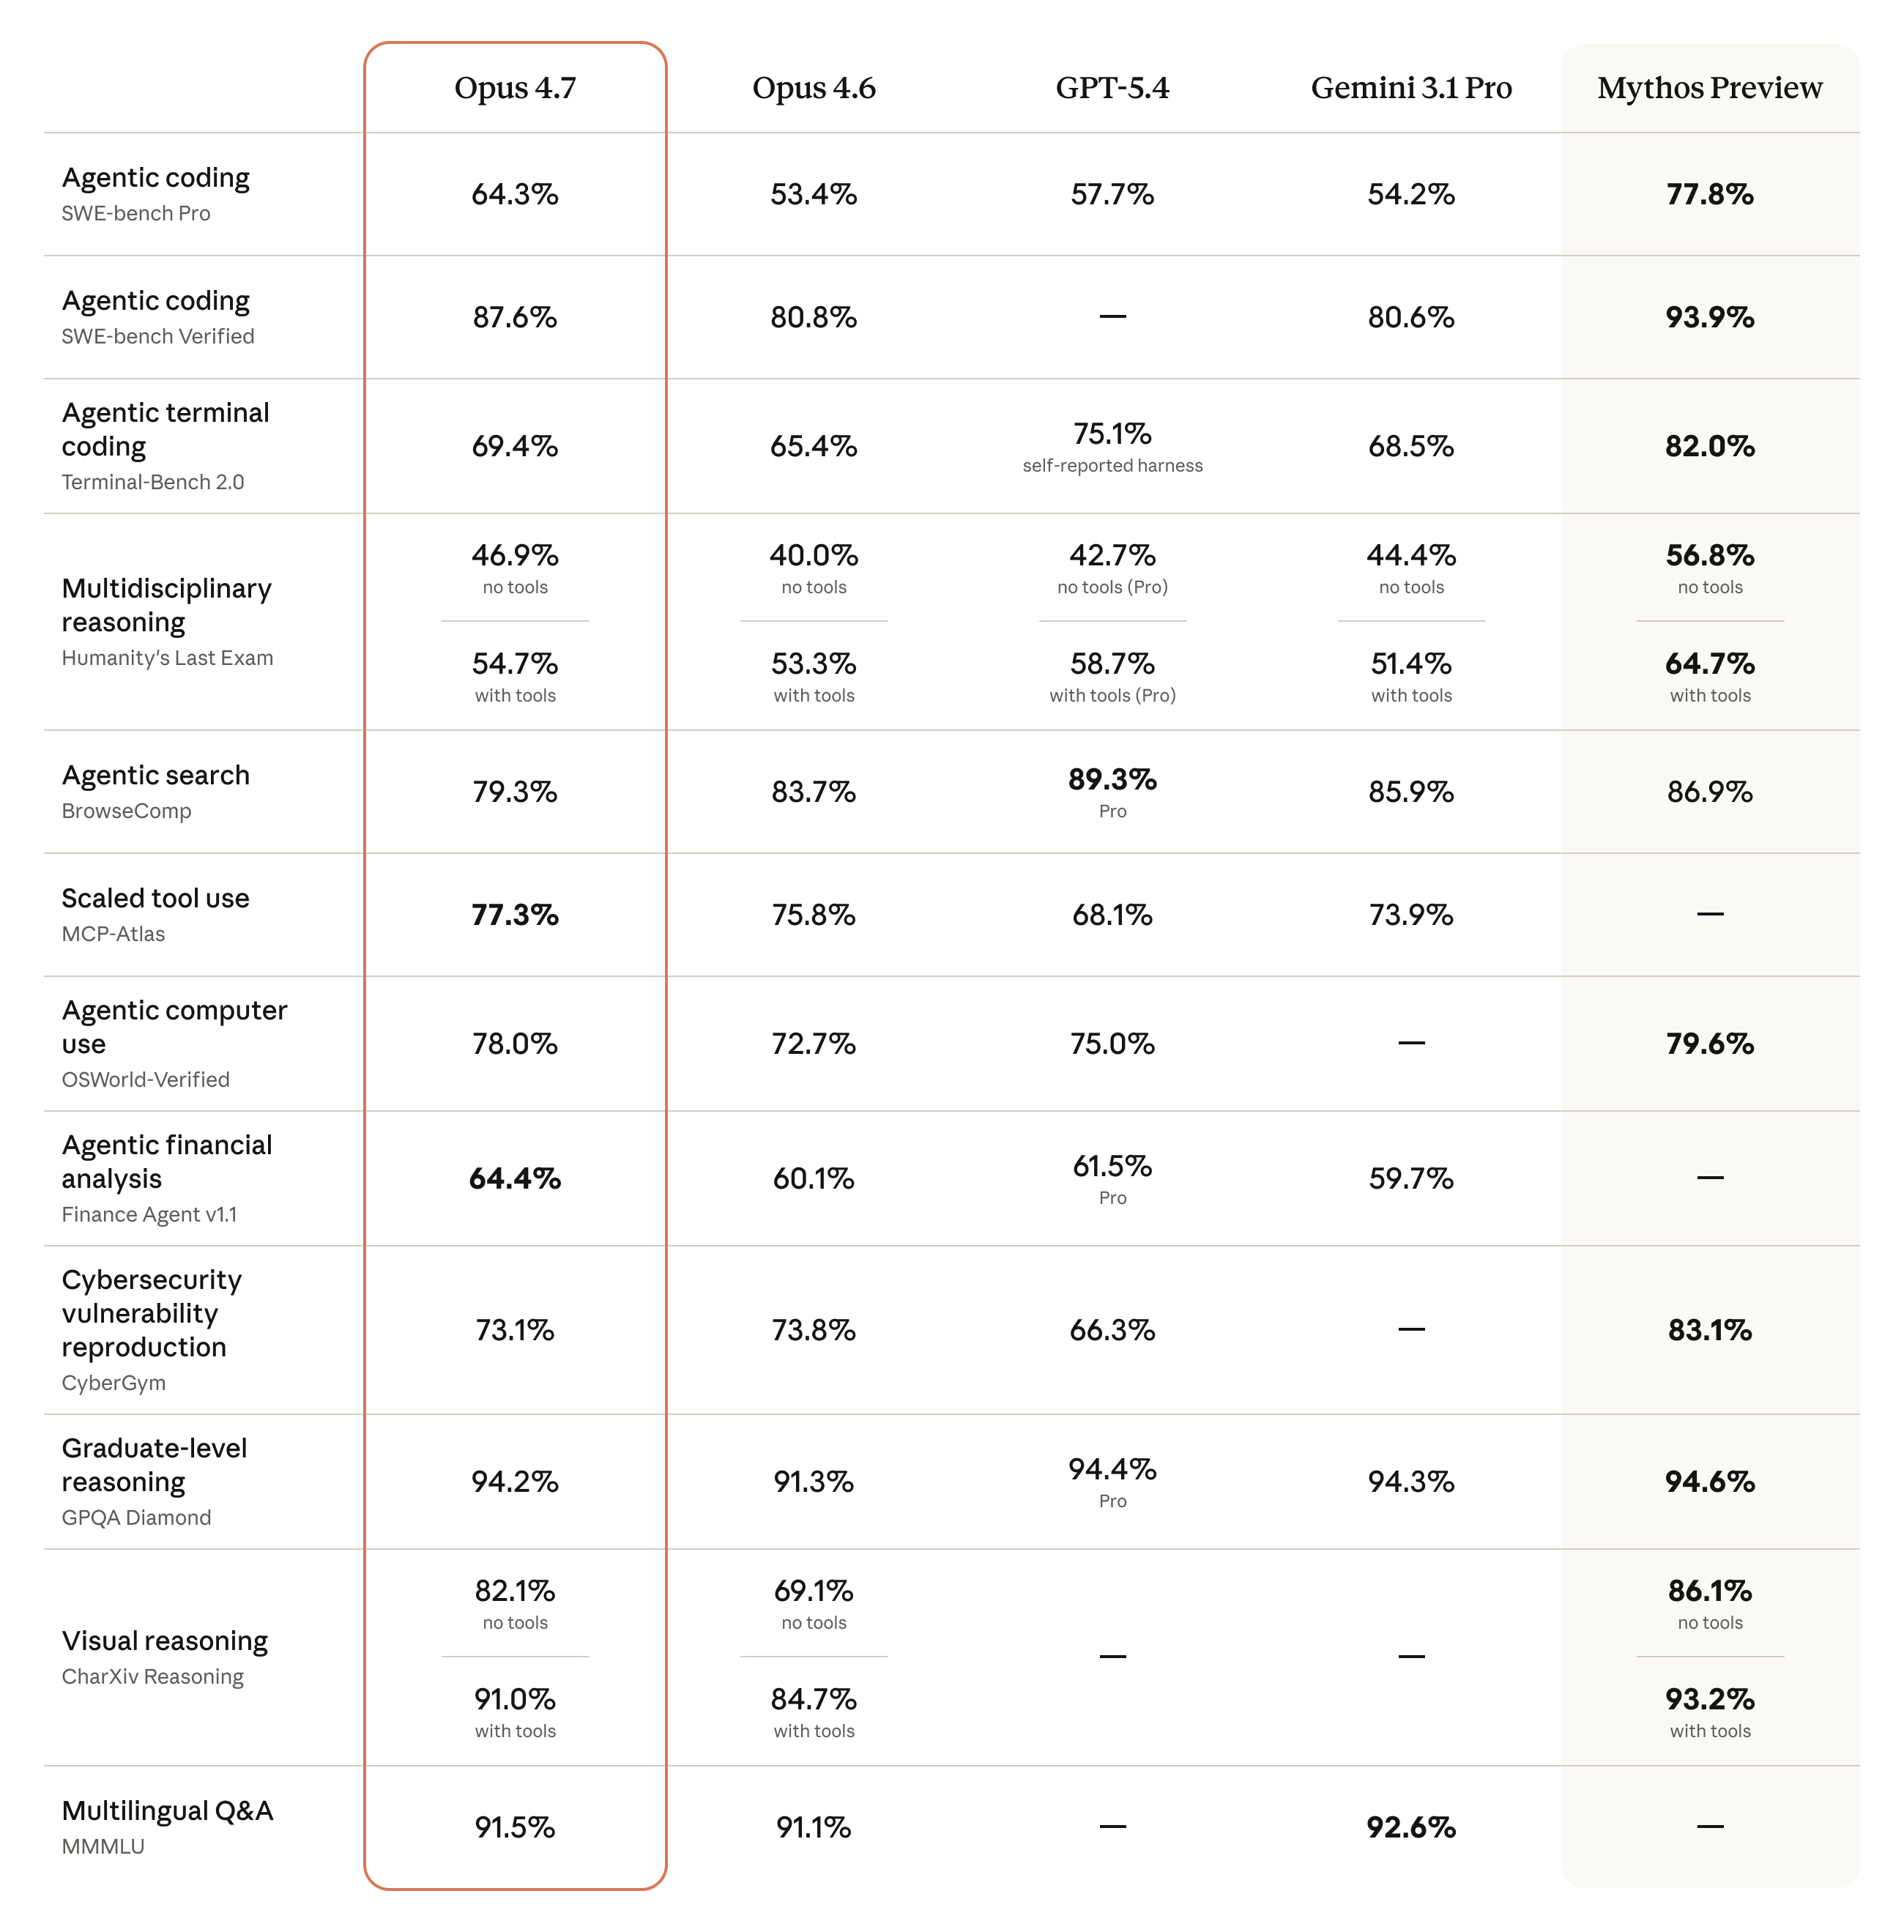
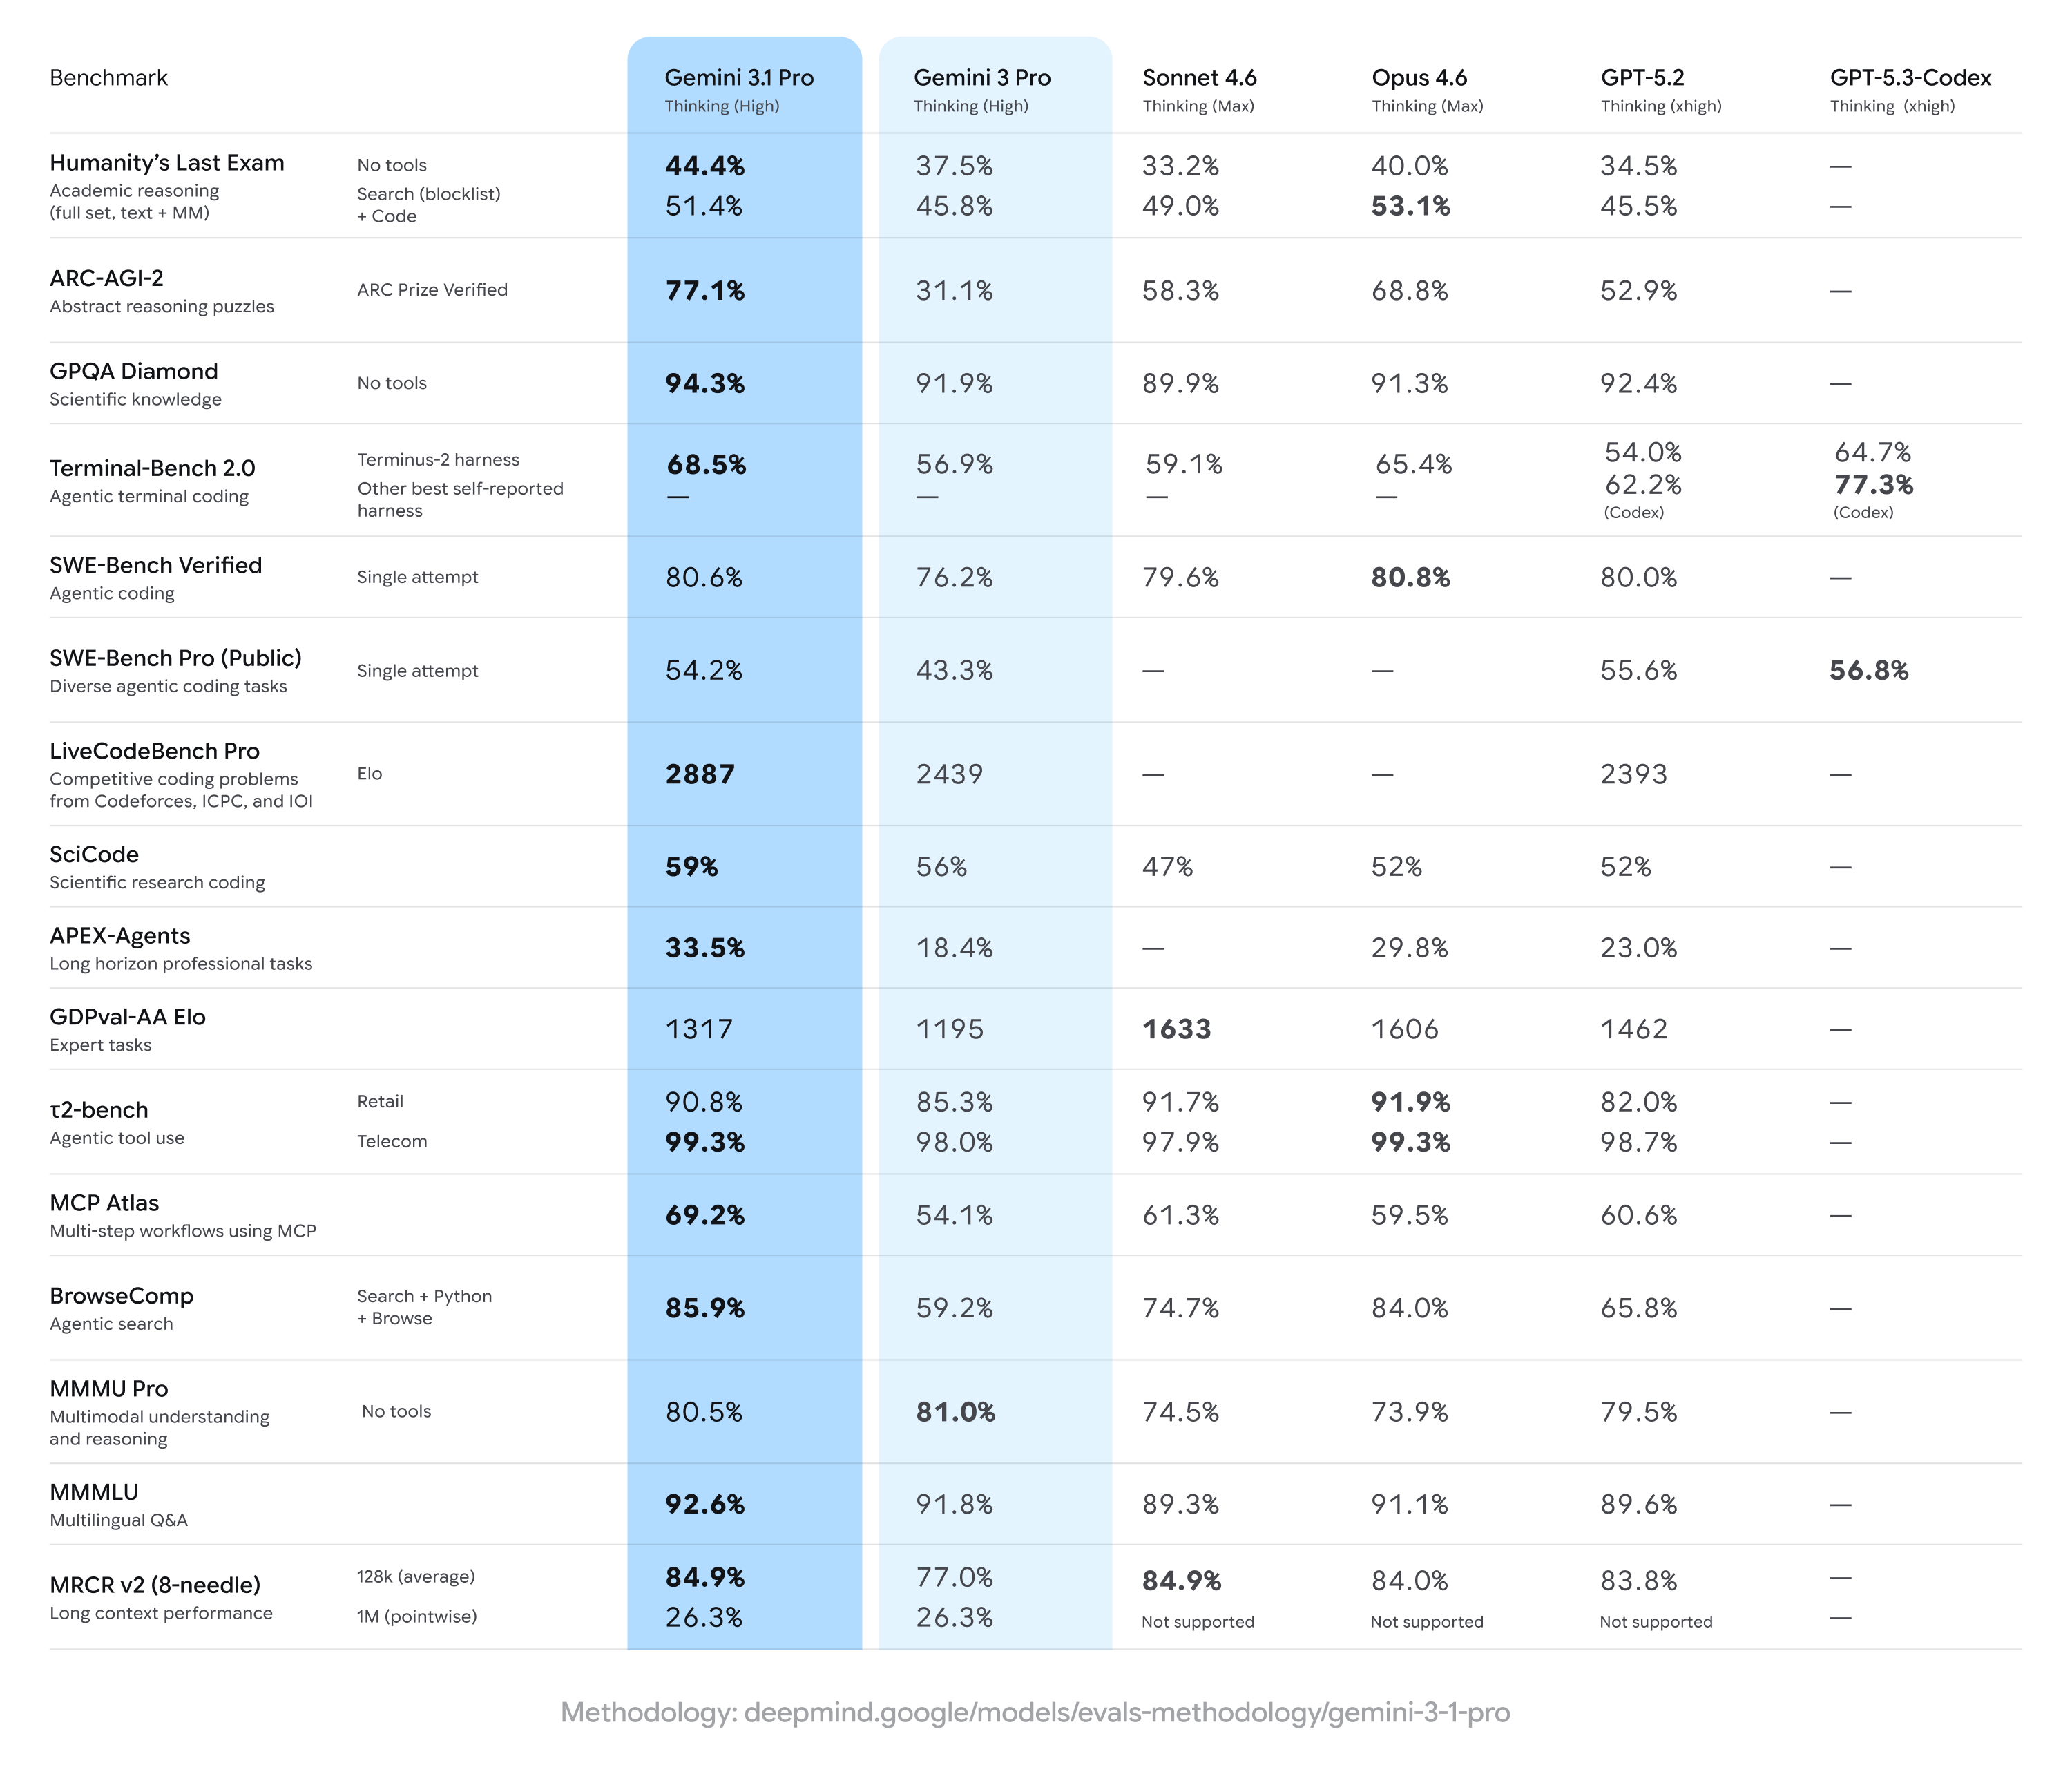
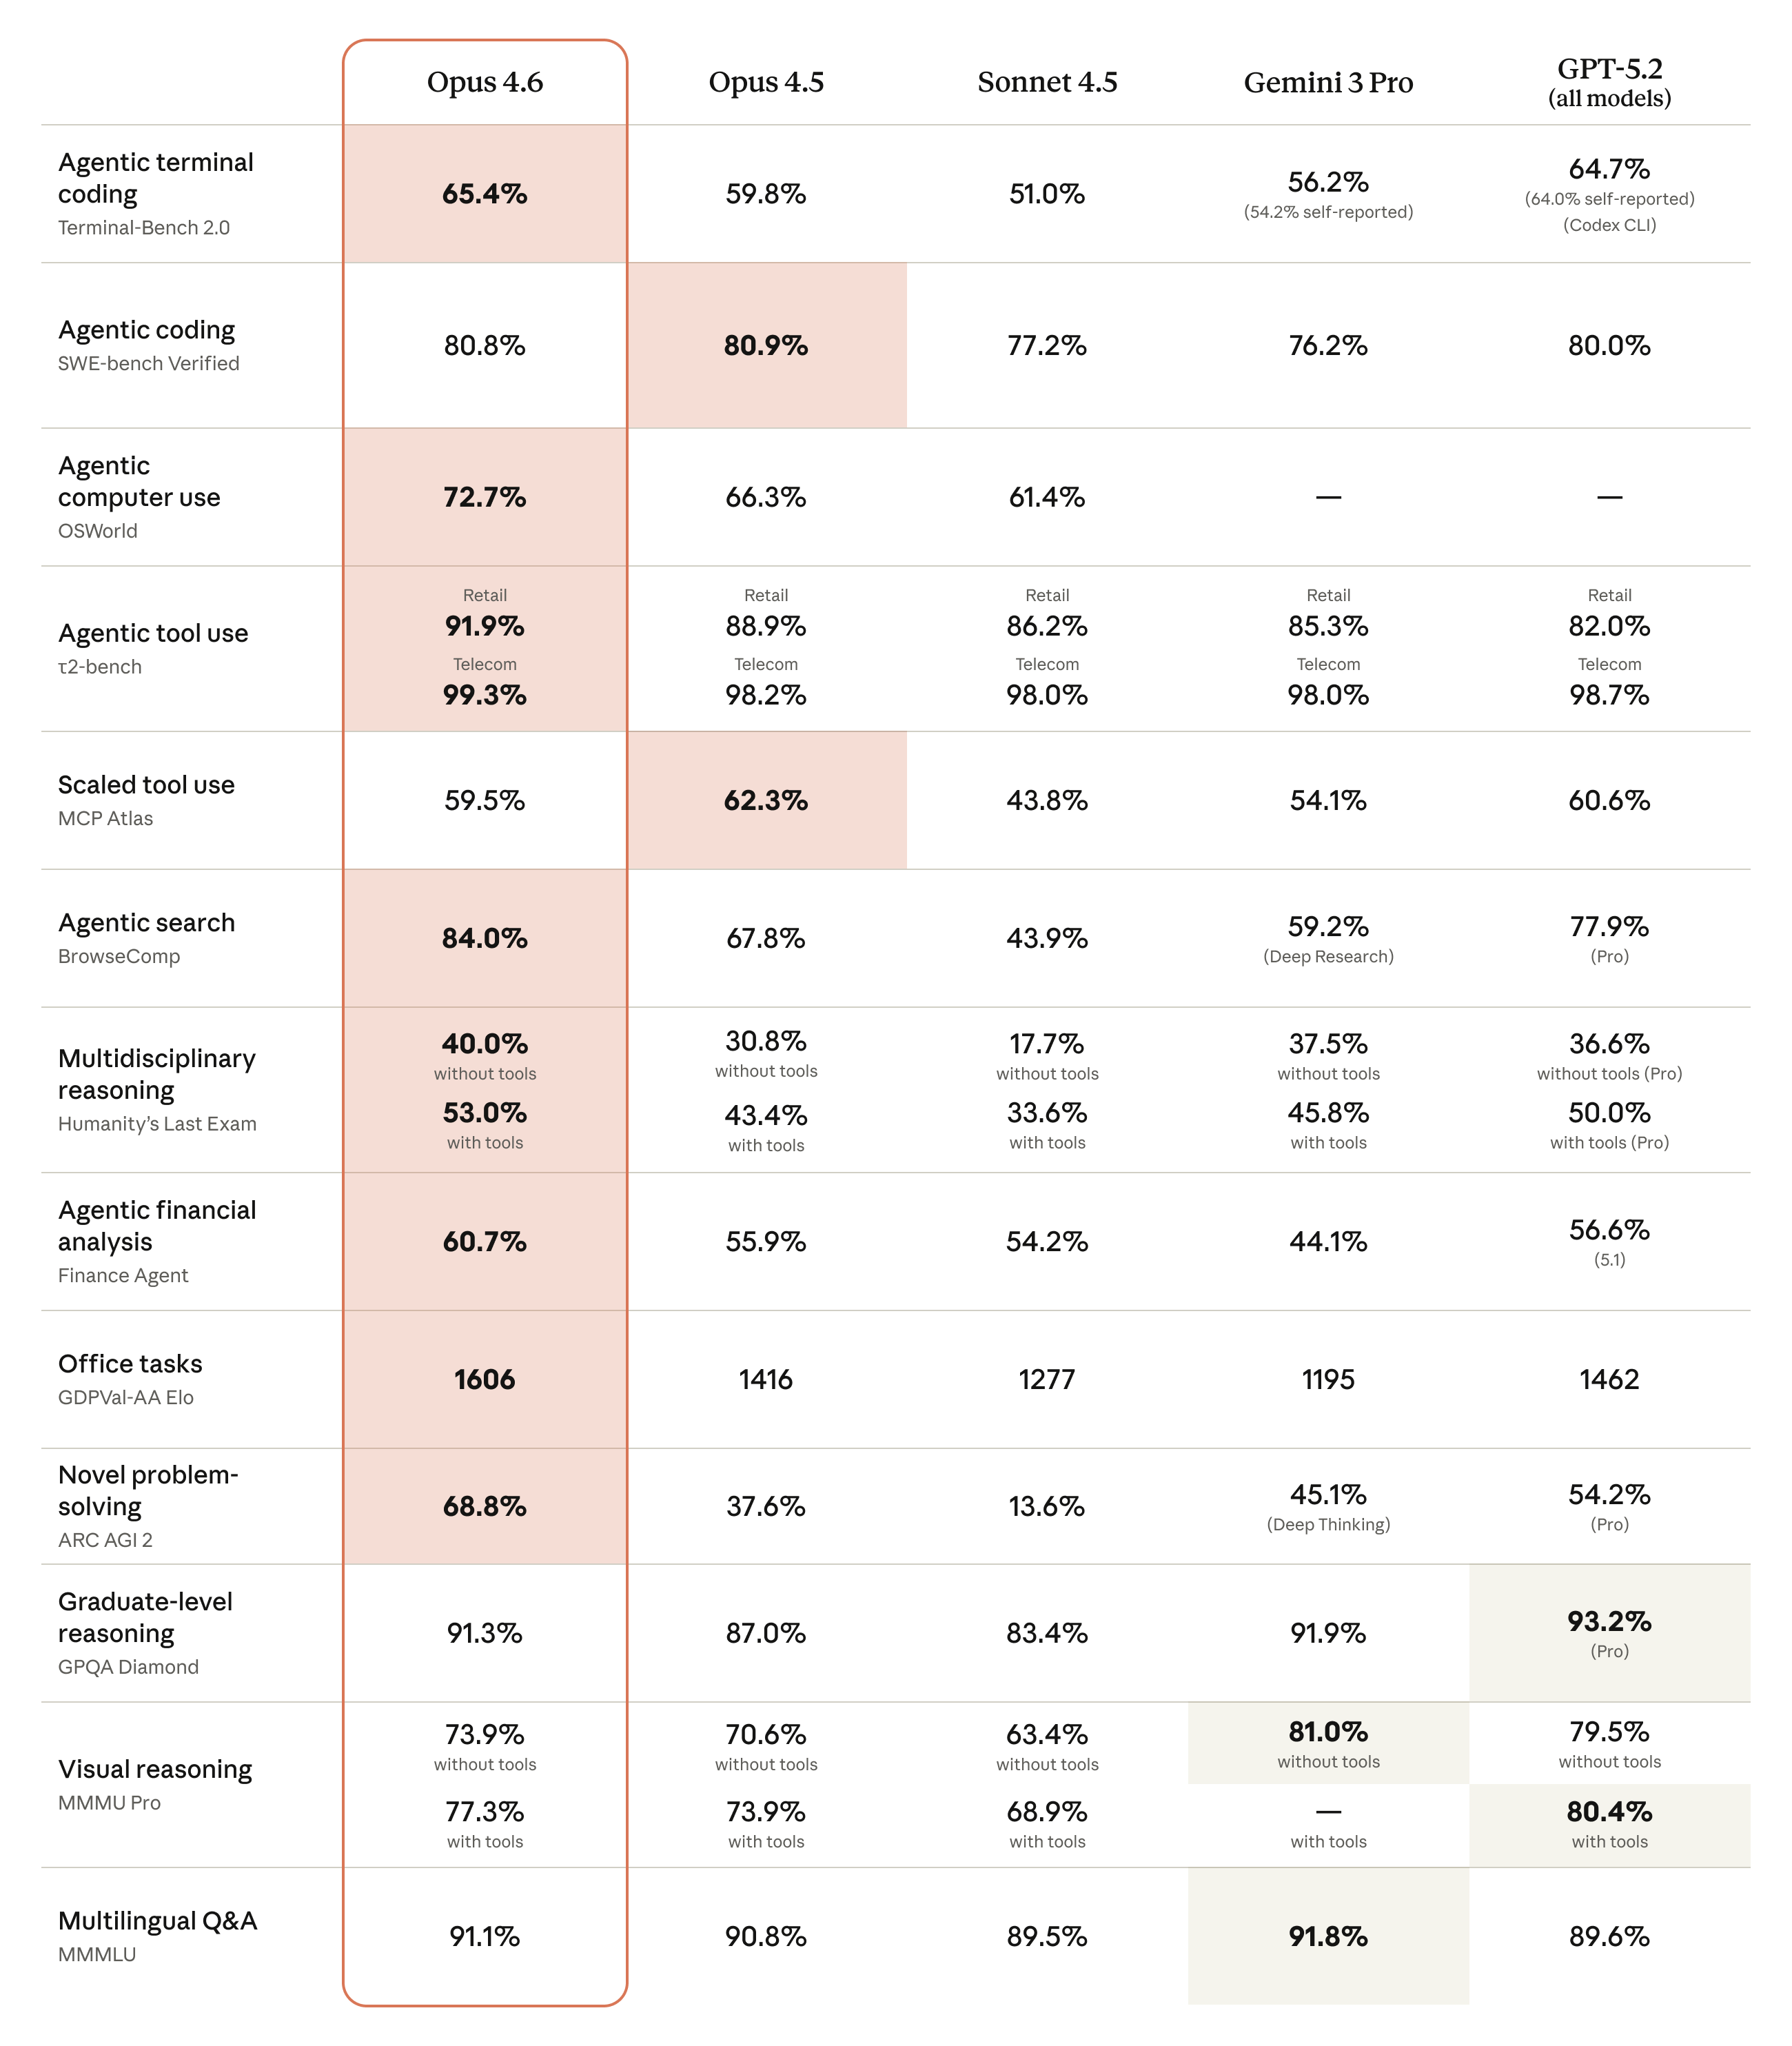
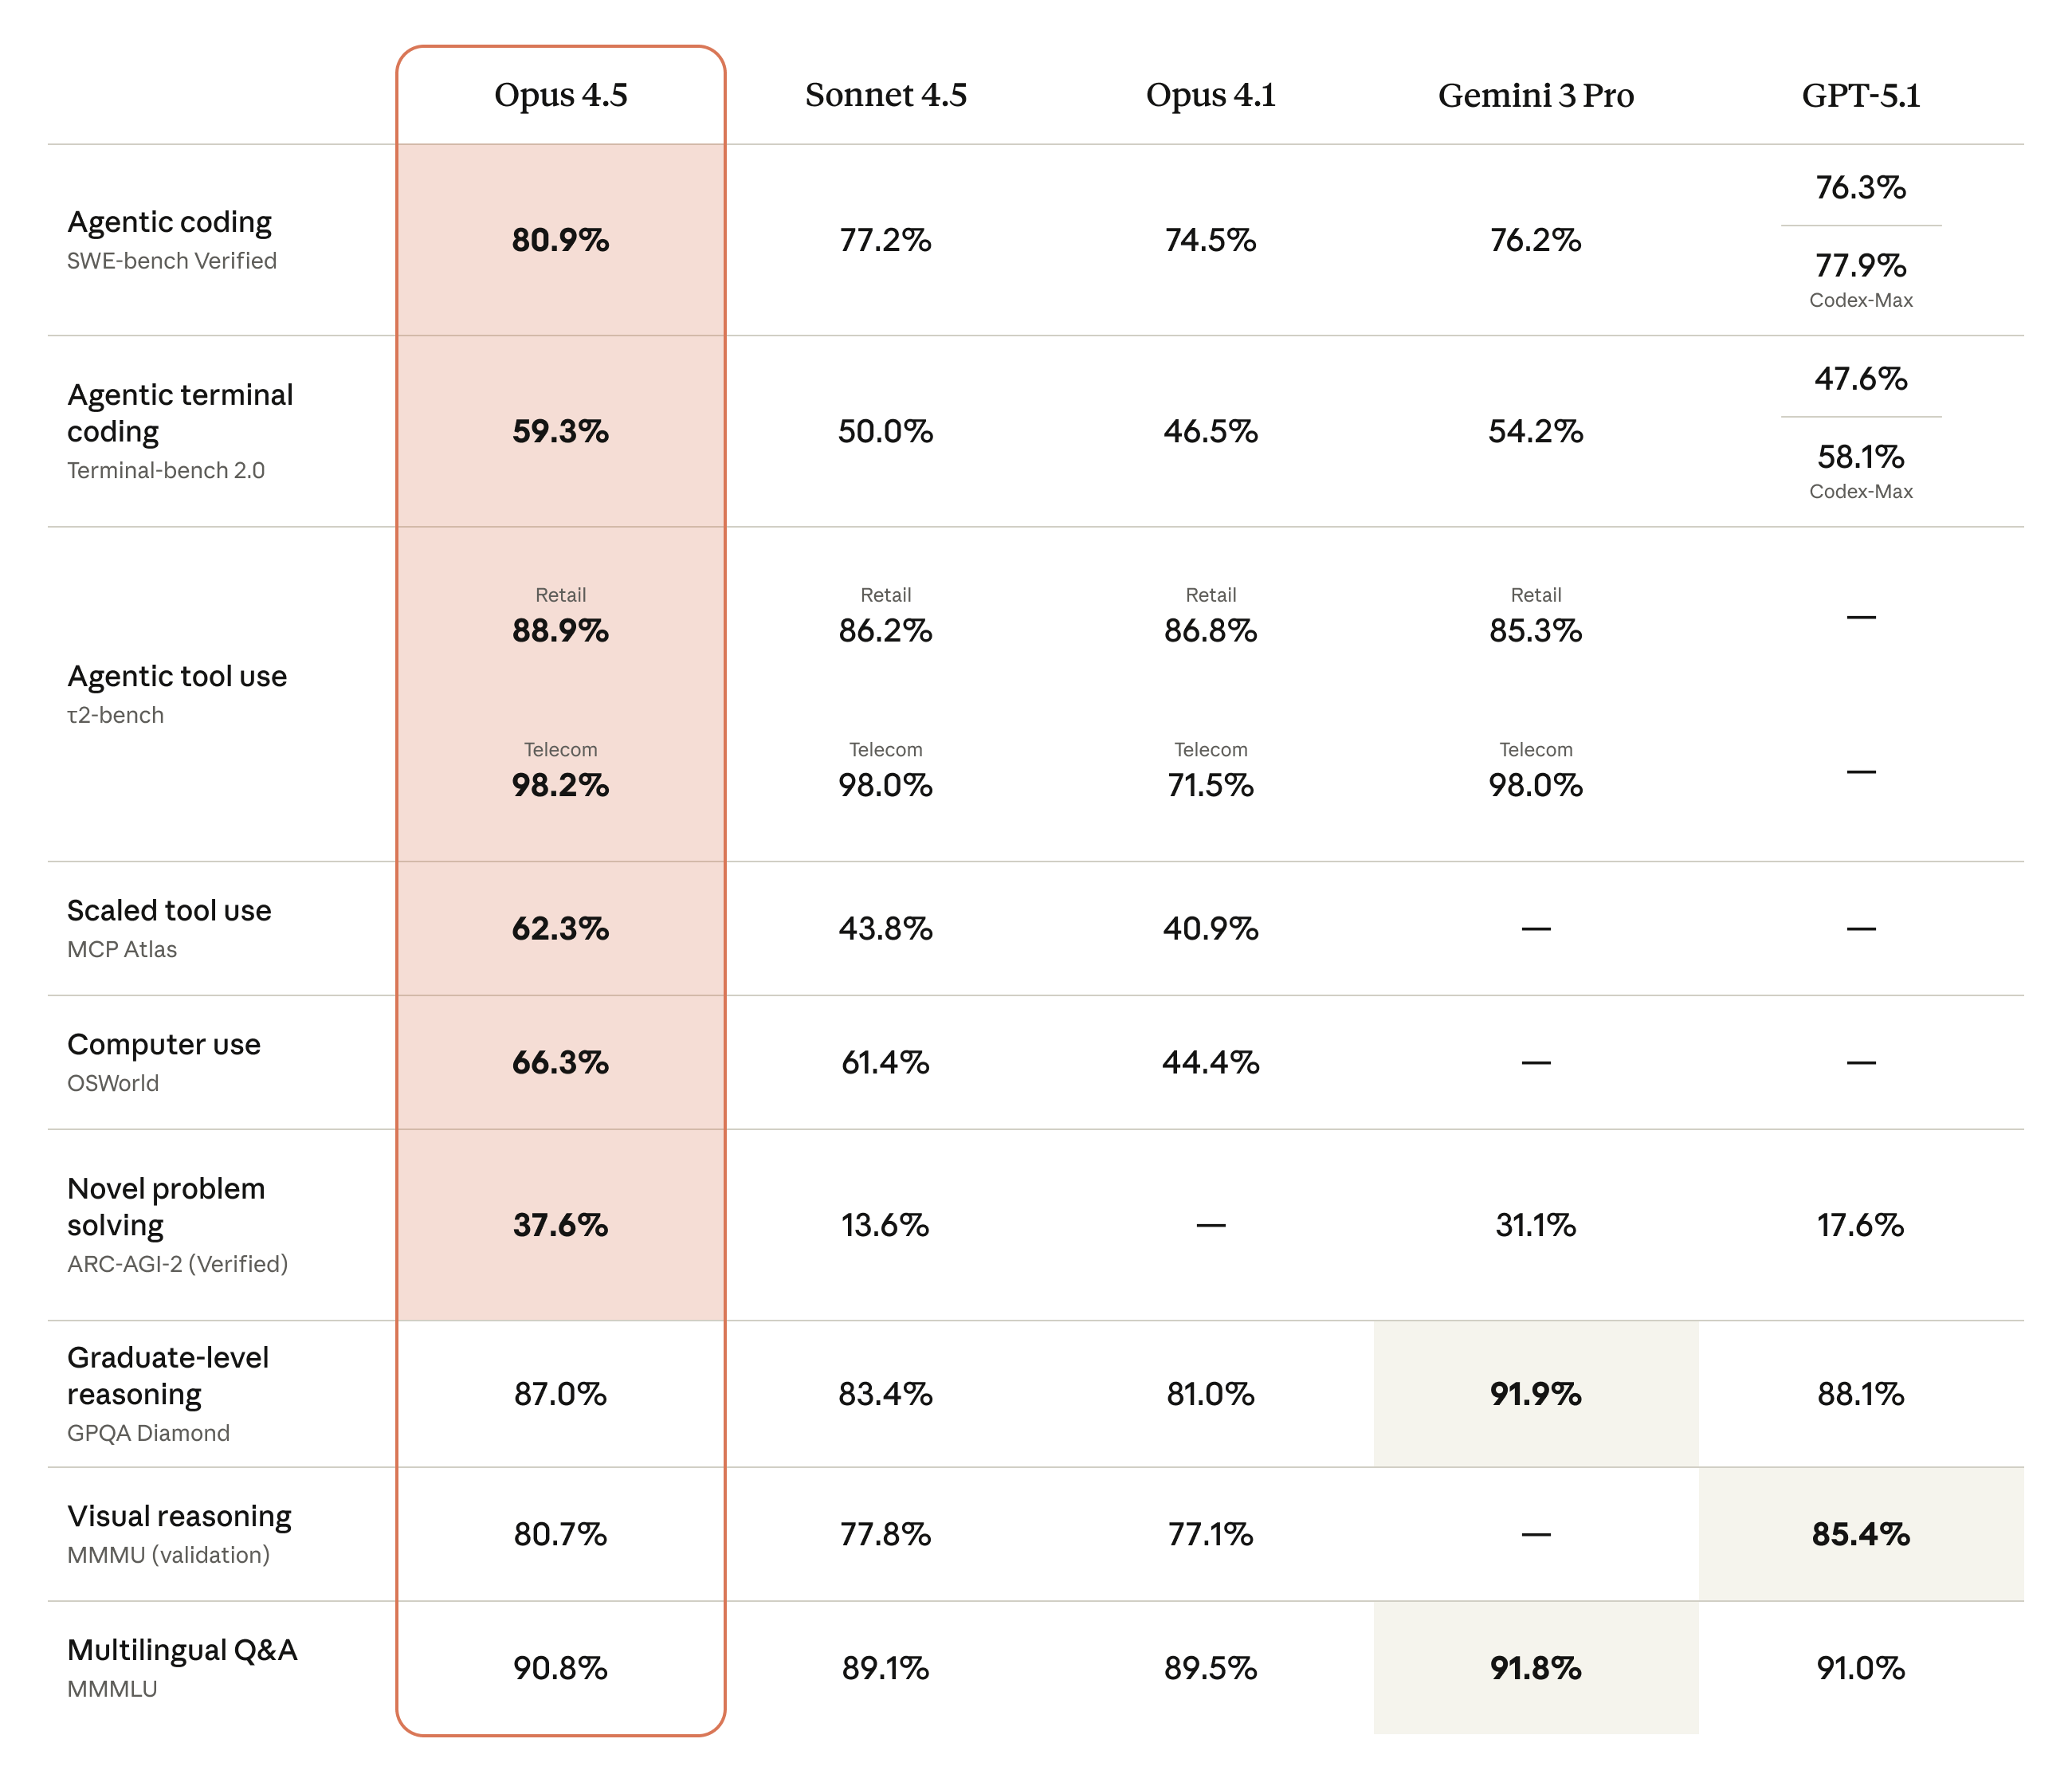
Benchmark
github.comHigher is better