Qwen3.7-Max
- Made by
- Alibaba
- Released
- Announced in
- Qwen3.7: The Agent Frontierqwen.ai
- Event
- Qwen3.7-Max
- API record
- /api/v1/models/qwen3-7-max
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
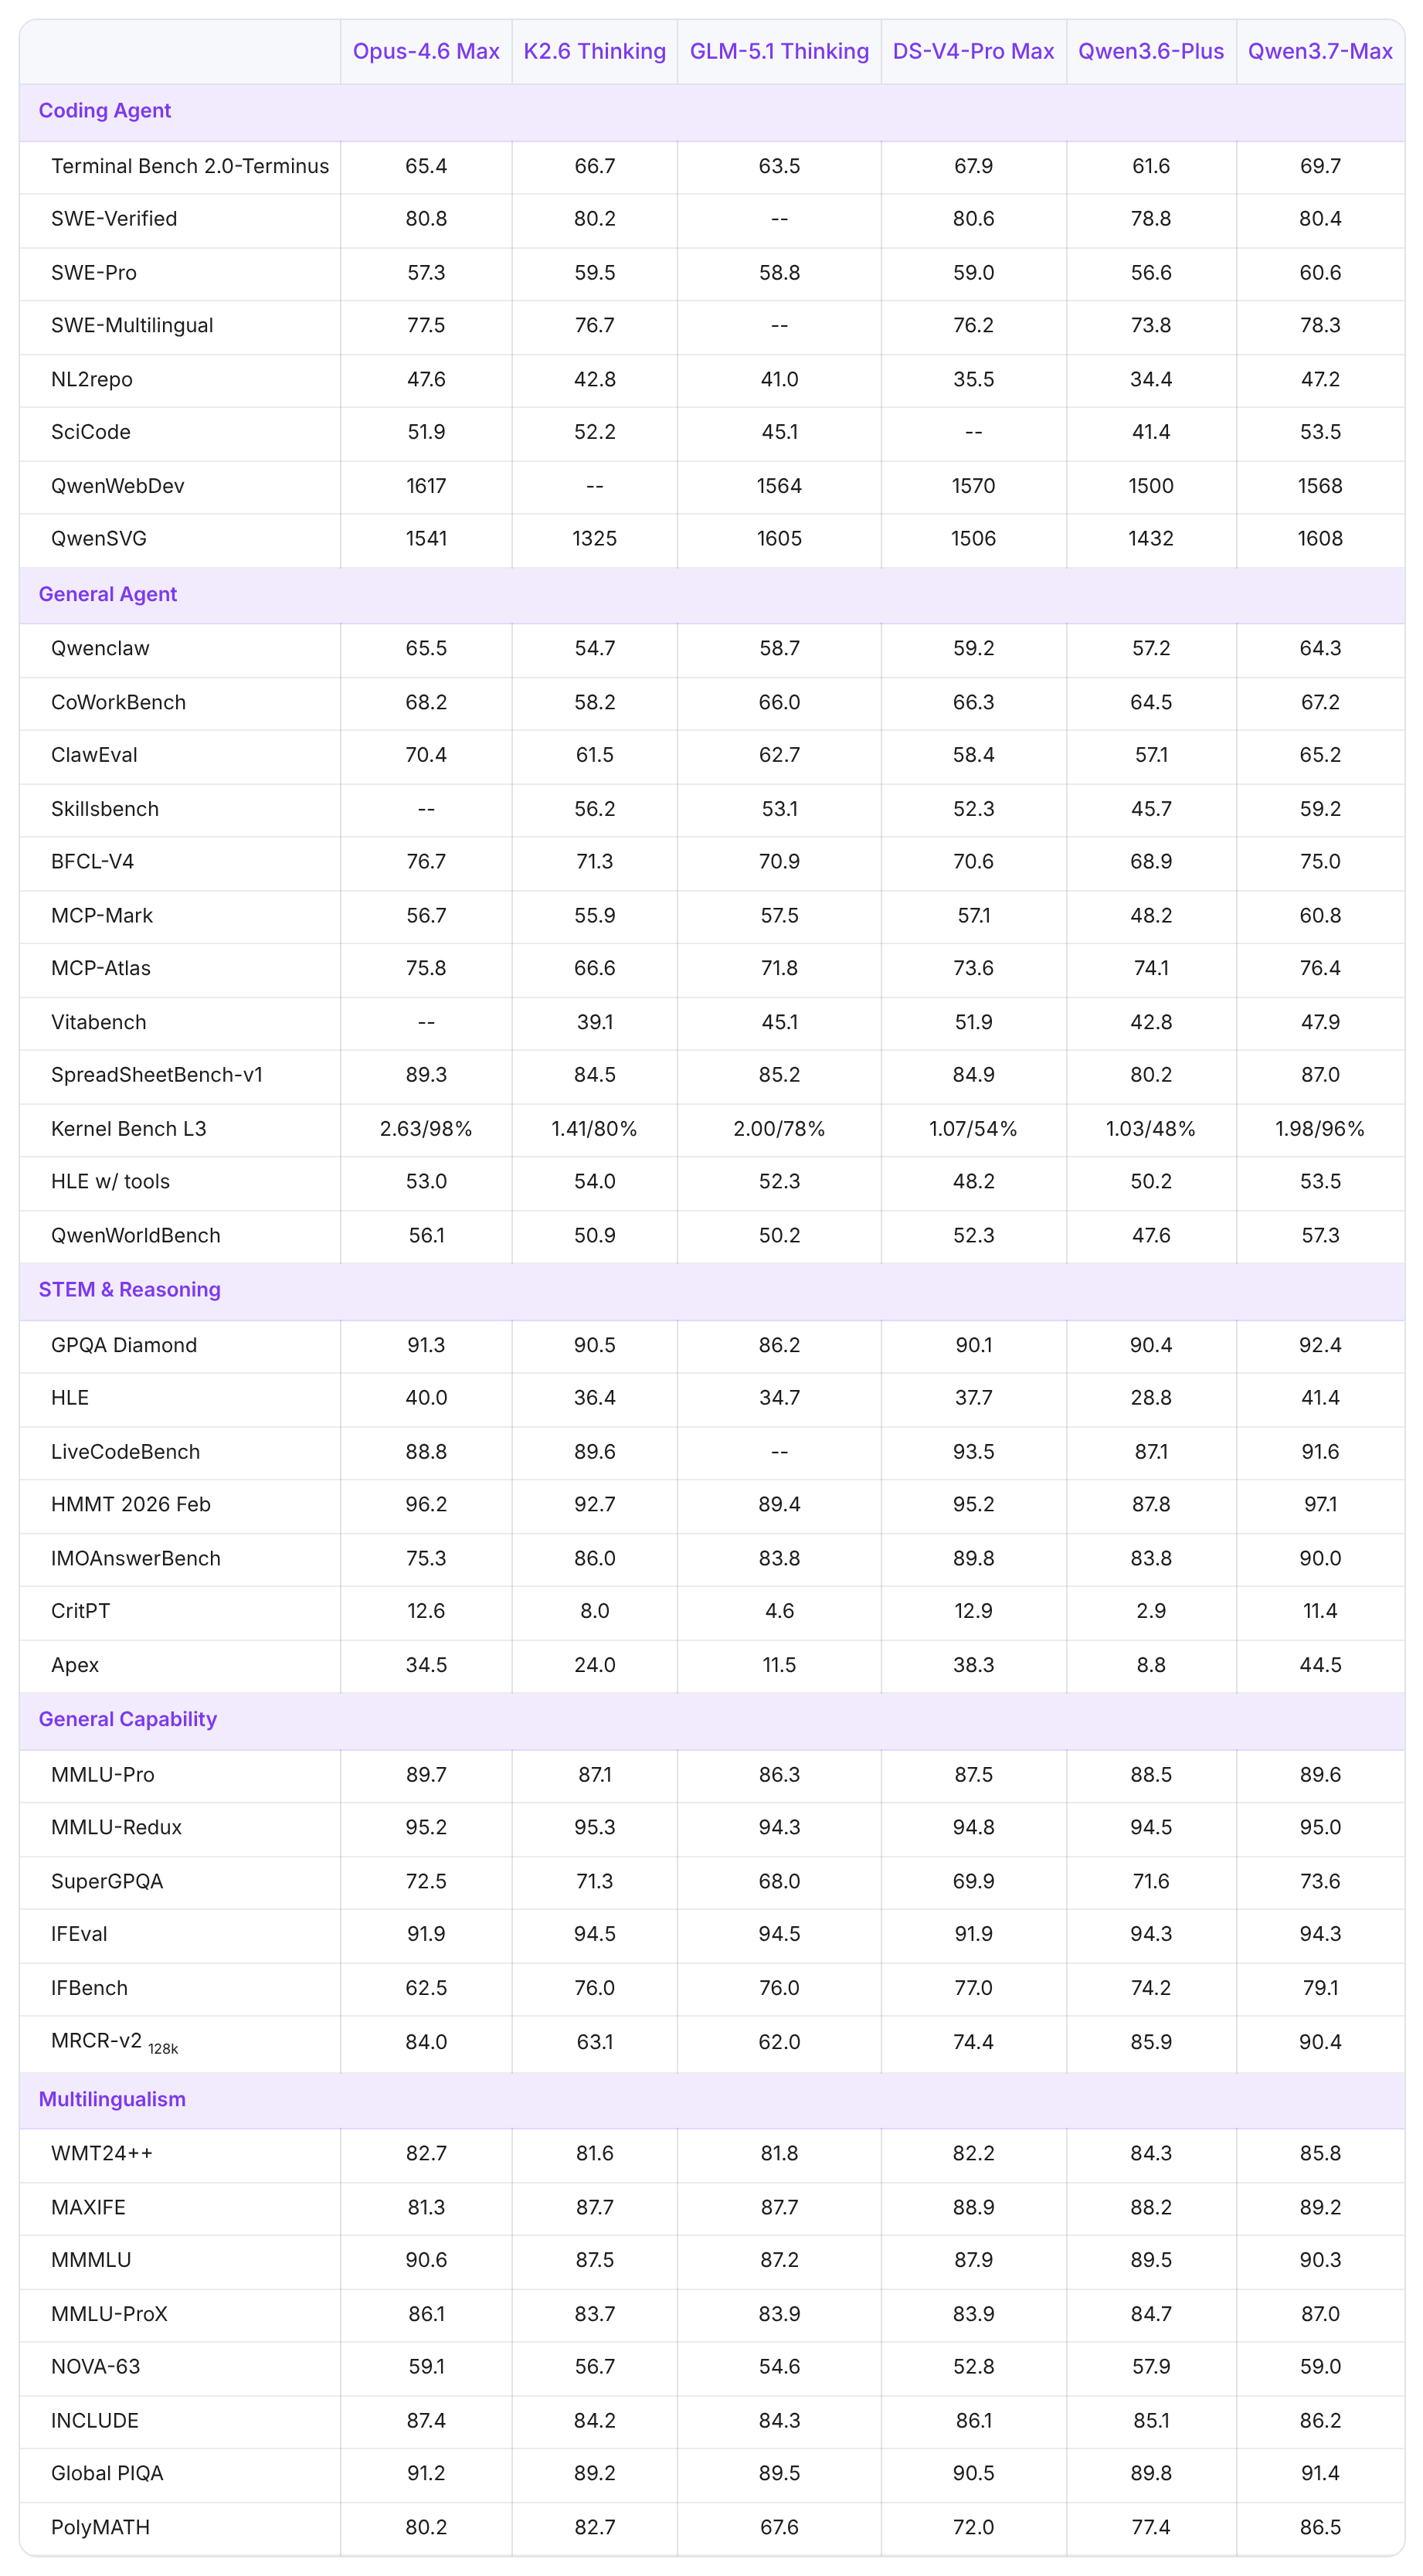
| Humanity's Last ExamNo tools · xhigh reasoning effort | 41.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Humanity's Last ExamWith tools | 53.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| SWE-bench Verifiedinternal harness with bash and file-edit tools; 200K context | 80.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Prointernal harness with bash and file-edit tools; 200K context · Run on the lab's own corrected version of the public set | 60.6% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| GPQA Diamondxhigh reasoning effort | 92.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 2.0Terminus 2 harness on Harbor; 5h timeout; 256K context; average of 5 runs | 69.7% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
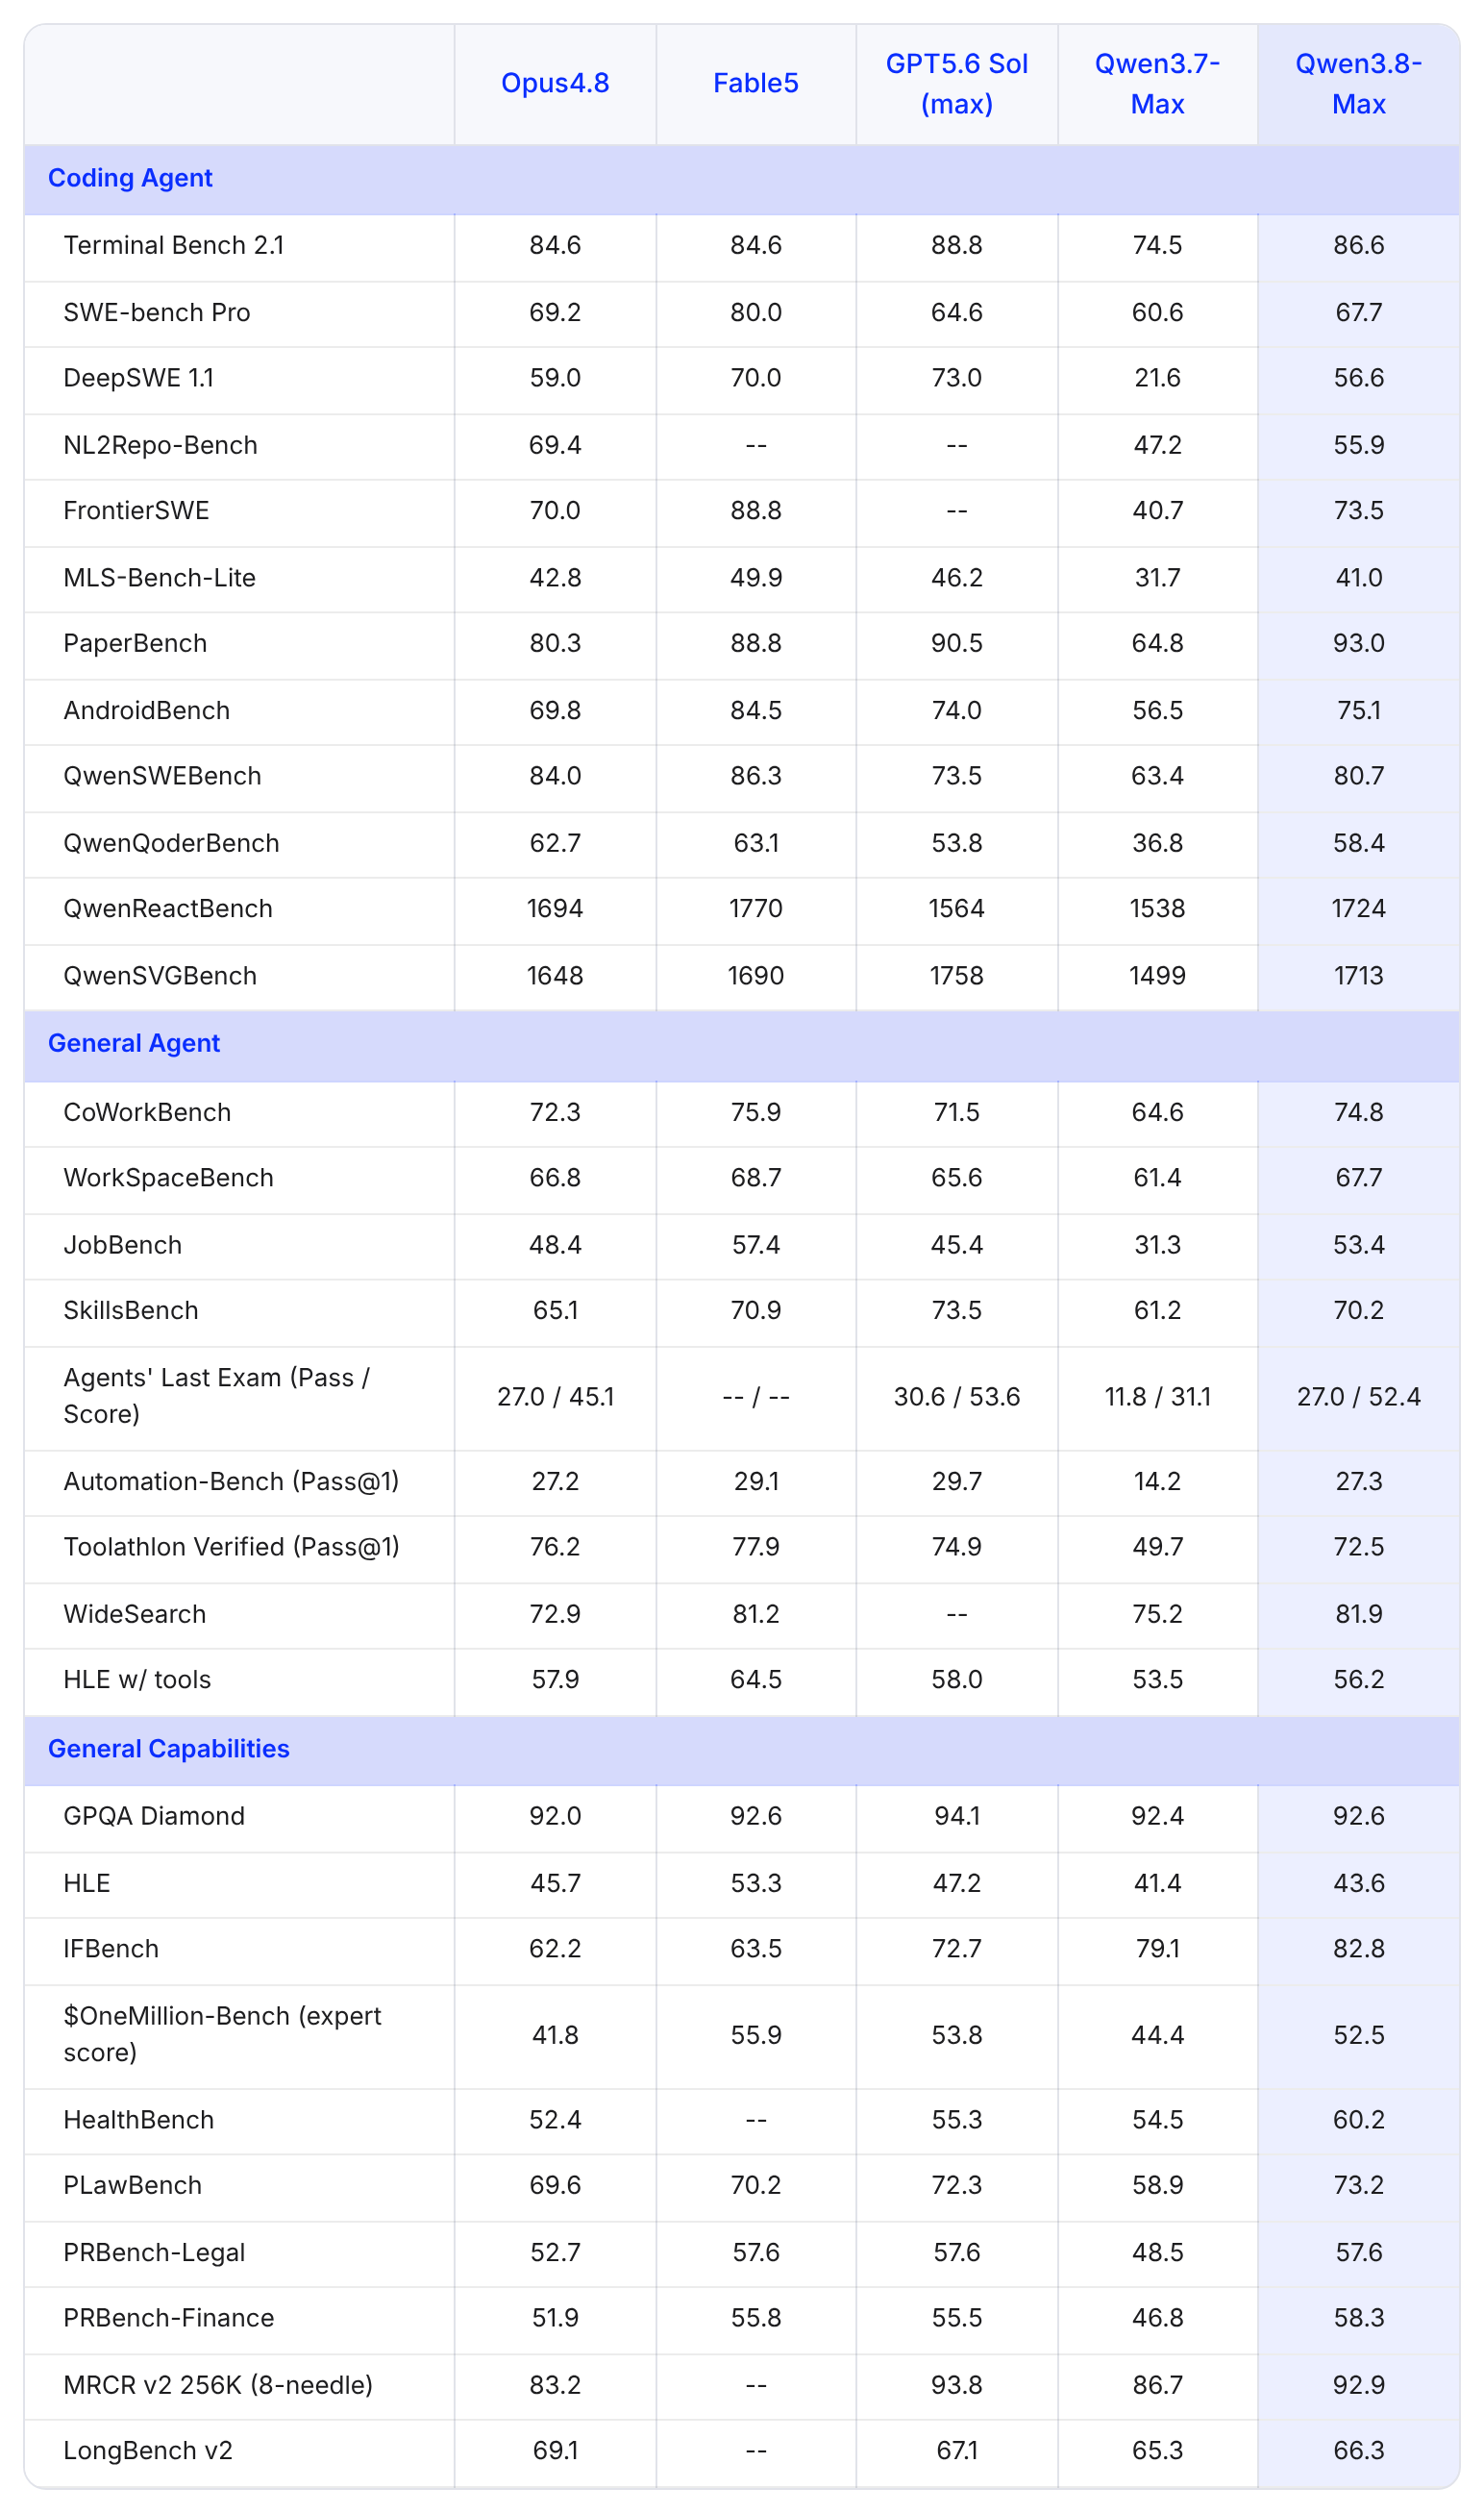
| AutomationBench600-task public subset; pass@1 · reported later, in Qwen3.8-Max: A New Bar for Coding and Cowork | 14.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| DeepSWE v1.1the higher of the Claude Code and mini-SWE-agent harnesses · reported later, in Qwen3.8-Max: A New Bar for Coding and Cowork | 21.6% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 2.1harness not stated · reported later, in Qwen3.8-Max: A New Bar for Coding and Cowork | 74.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| MMLU-Pro | 89.6% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| LiveCodeBenchproblem window not stated | 91.6% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| MCP Atlaspublic set; Gemini 2.5 Pro judge | 76.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
Sources
Reported by Alibaba
- Qwen3.7: The Agent Frontierqwen.ai · 20 May 2026
Our capture of the source - Qwen3.8-Max: A New Bar for Coding and Coworkqwen.ai · 3 Aug 2026
Our capture of the source