Terminal-Bench 2.1
- OpenAI
- Anthropic
- DeepSeek
- Alibaba
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
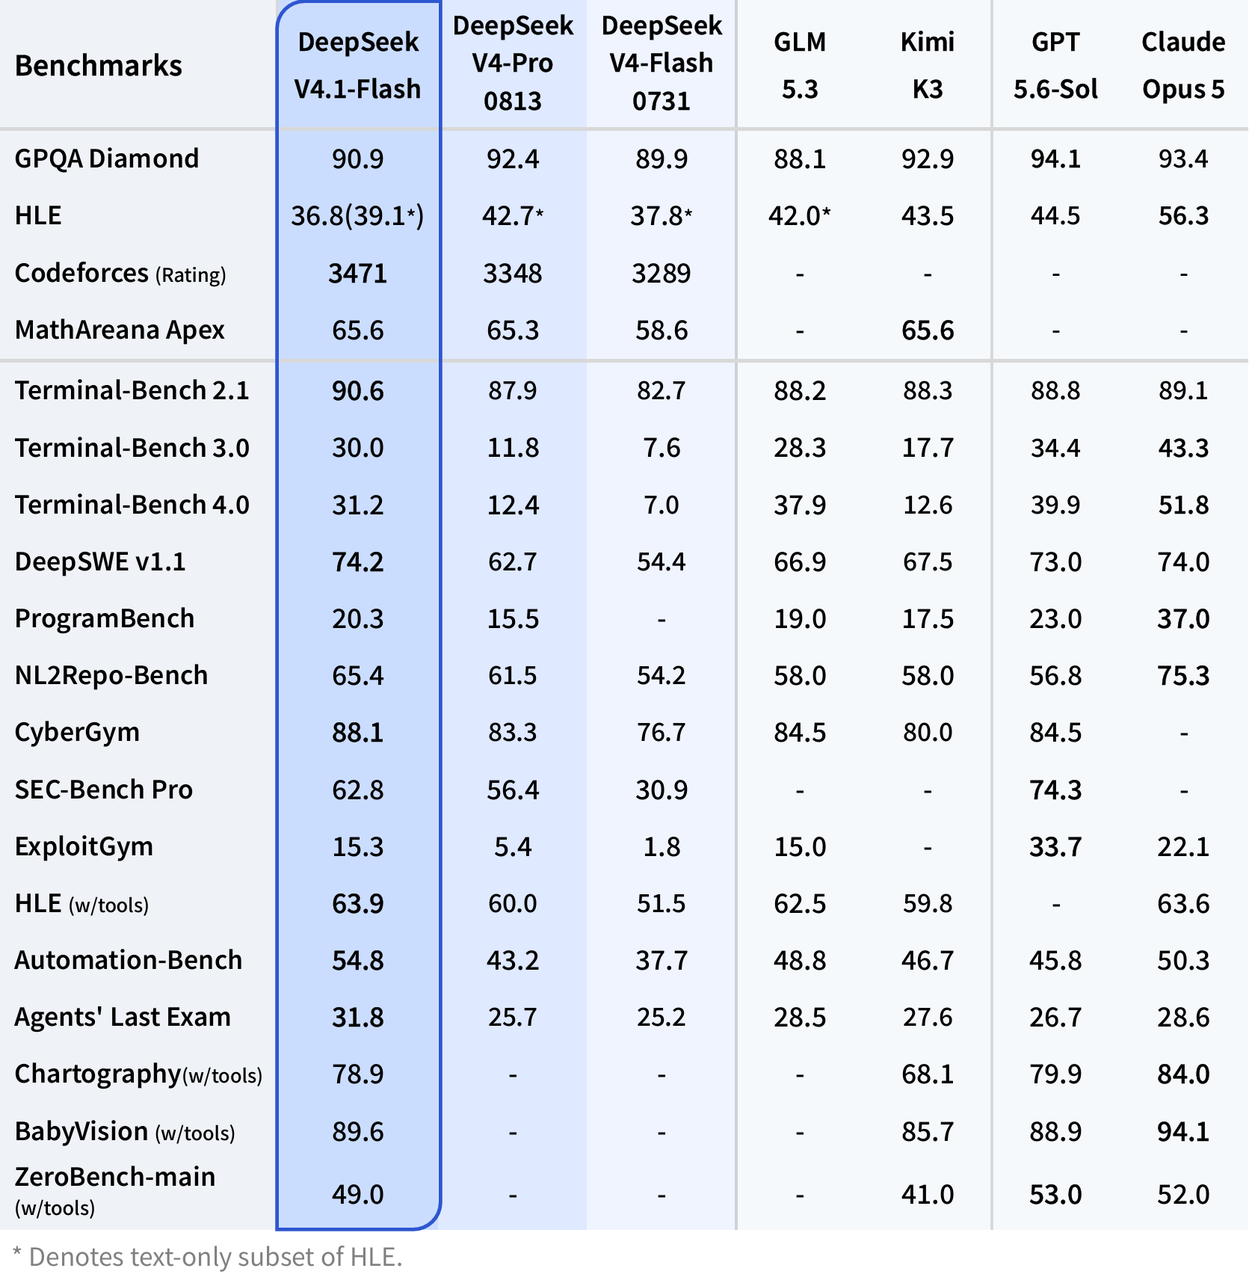
| DeepSeek-V4.1-Flash10 Sep 2026 · DeepSeek | 90.6% | DeepSeek-V4.1-Flash: Smarter, Faster, More EfficientNo harness or effort printed for this row. The post's bar chart covers Terminal-Bench 3.0, not 2.1.Source image | Yes |
| Qwen3.8-Max3 Aug 2026 · Alibaba | 86.6% | Qwen3.8-Max: A New Bar for Coding and CoworkFootnote 2: Evaluated with Claude Code (avg@10), 5-hour timeout, max_tokens=131,072. Default reasoning_effort per post is xhigh. Post HTML via https://qwen.ai/api/v2/article/?language=en-US&path=qwen3.8&type=qwen_ai. | Yes |
| GPT-5.6 Sol9 Jul 2026 · OpenAI | 88.8% | GPT-5.6: Frontier intelligence that scales with your ambitionTable also has a 'GPT‑5.6 Sol Ultra' column (separate row recorded). The fetched page text was truncated, so footnotes without a % sign are not visible in the extract. | Yes |
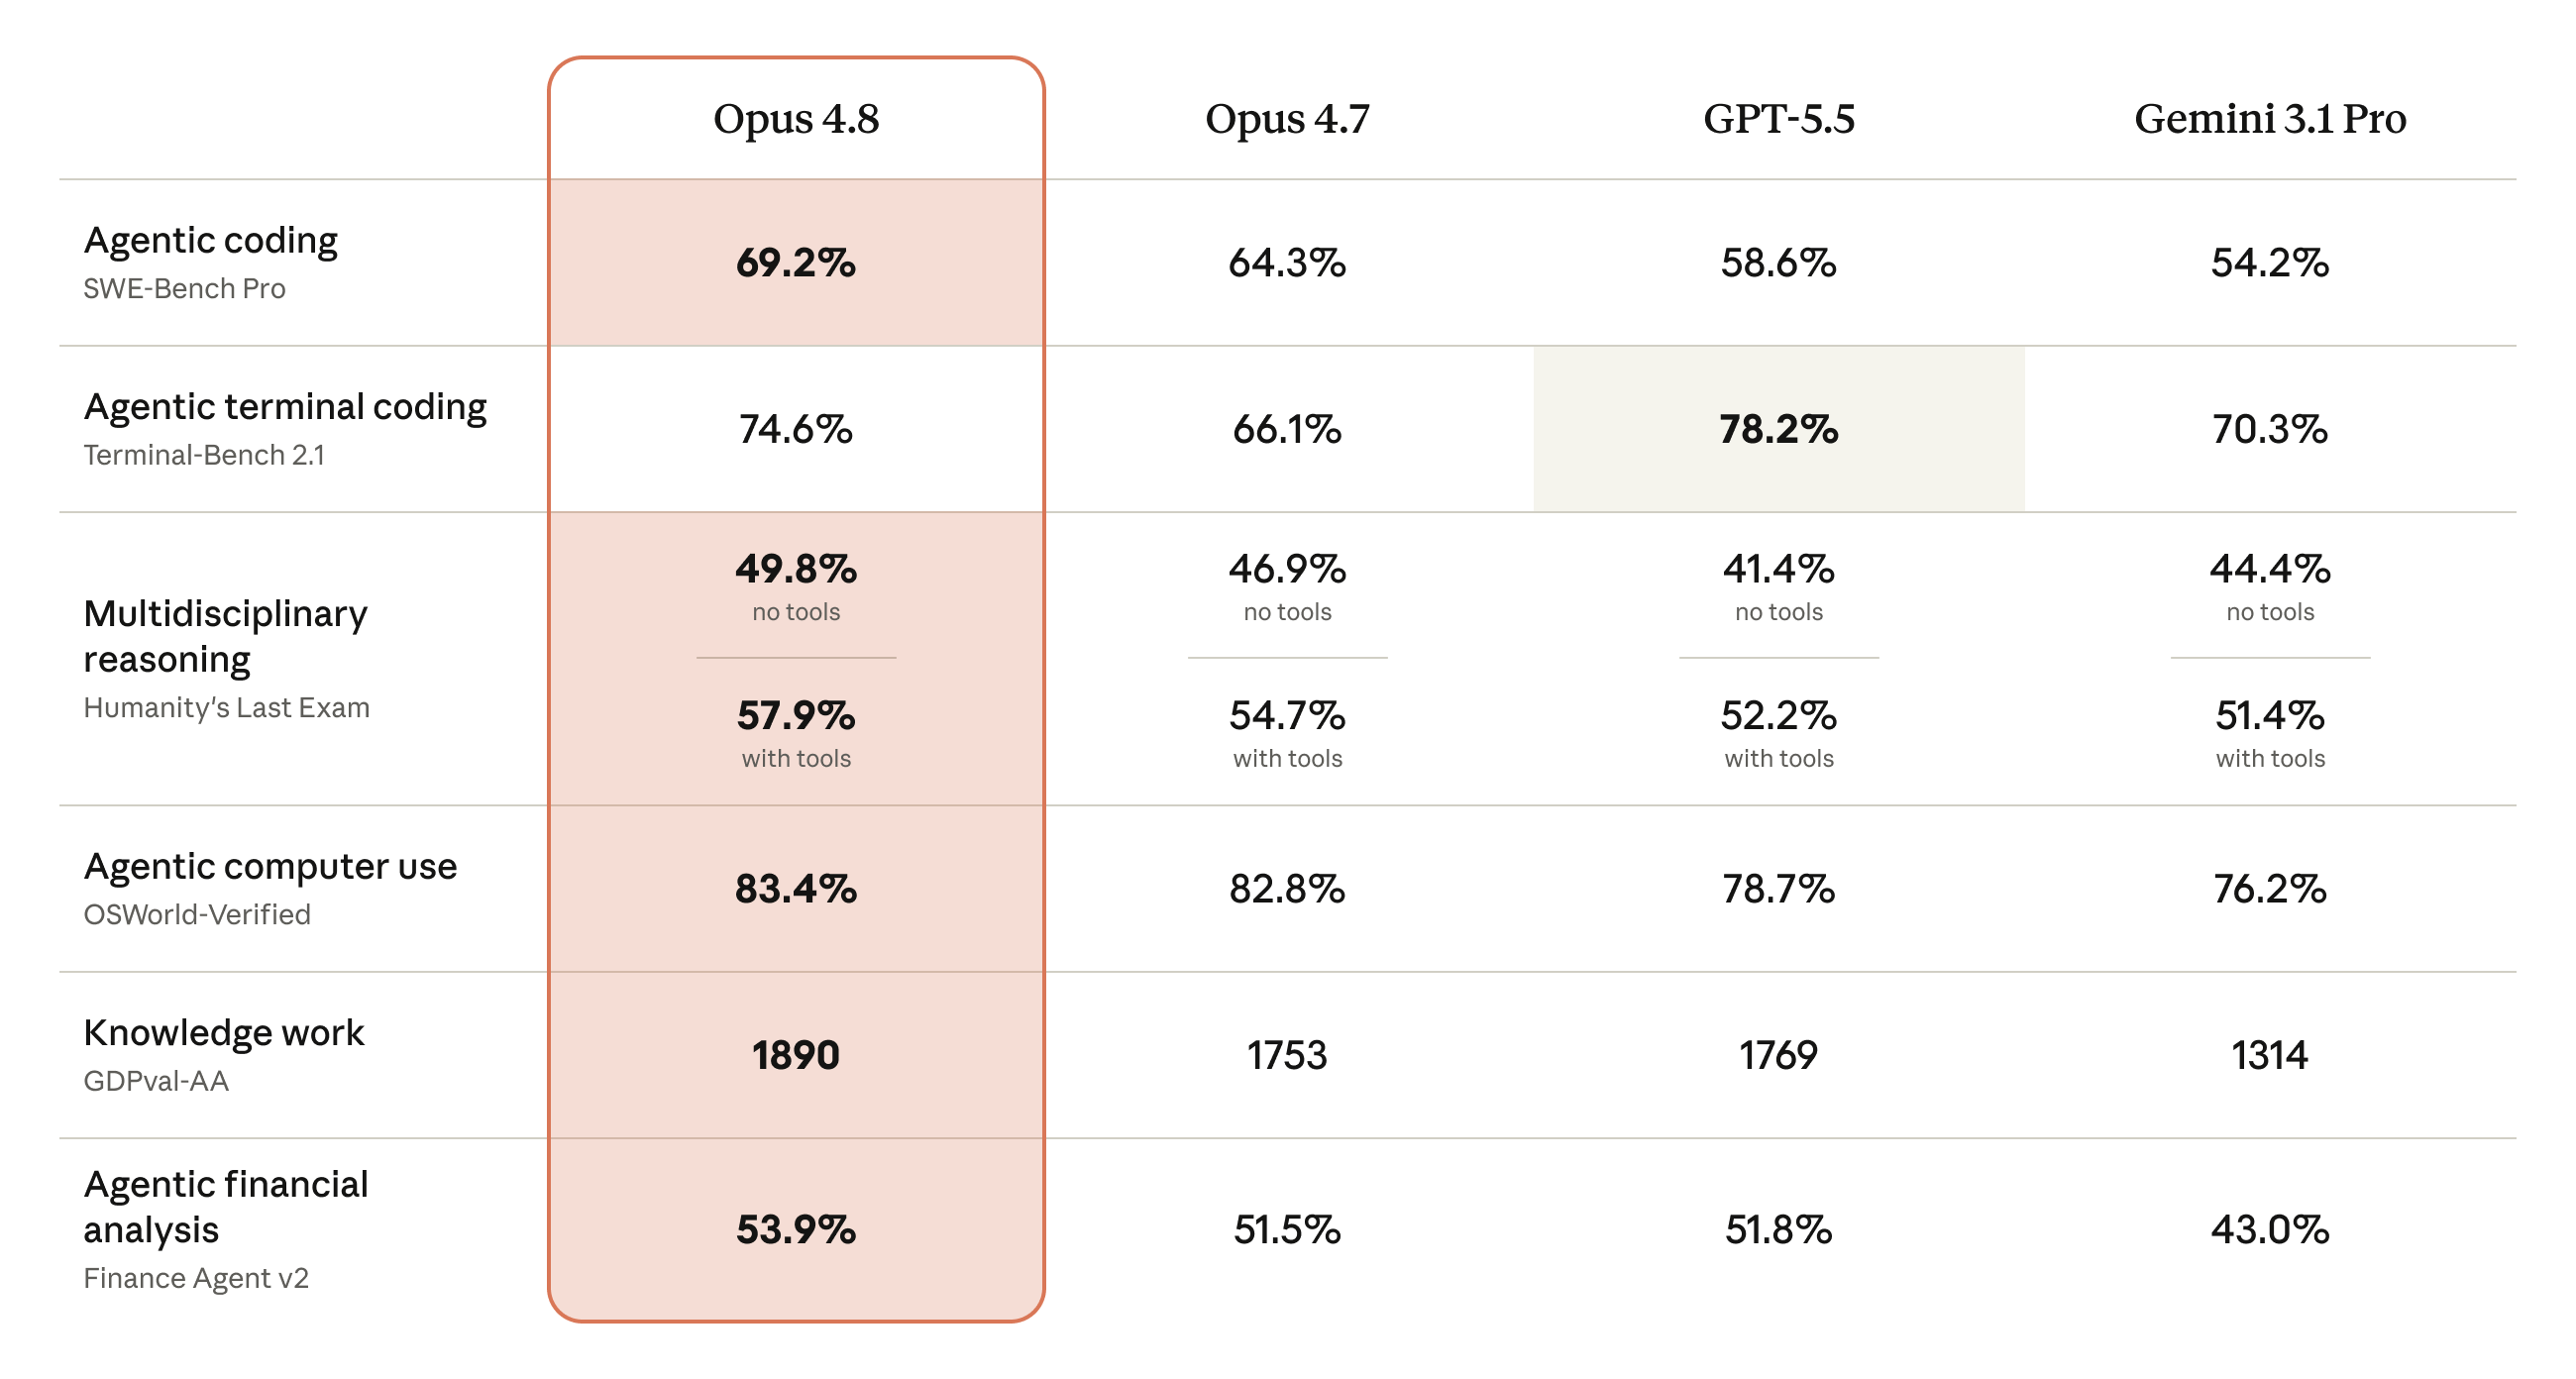
| Claude Opus 4.828 May 2026 · Anthropic | 74.6% | Introducing Claude Opus 4.8Footnote: all models run with the Terminus-2 public harness. Opus 4.8 defaults to high effort (post text); effort for the table not stated.Source image | Yes |
Benchmark
tbench.aiHigher is better
Stanford University and Laude InstituteIntroduced 6 May 2026