Terminal-Bench 1.0
- Anthropic
- DeepSeek
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
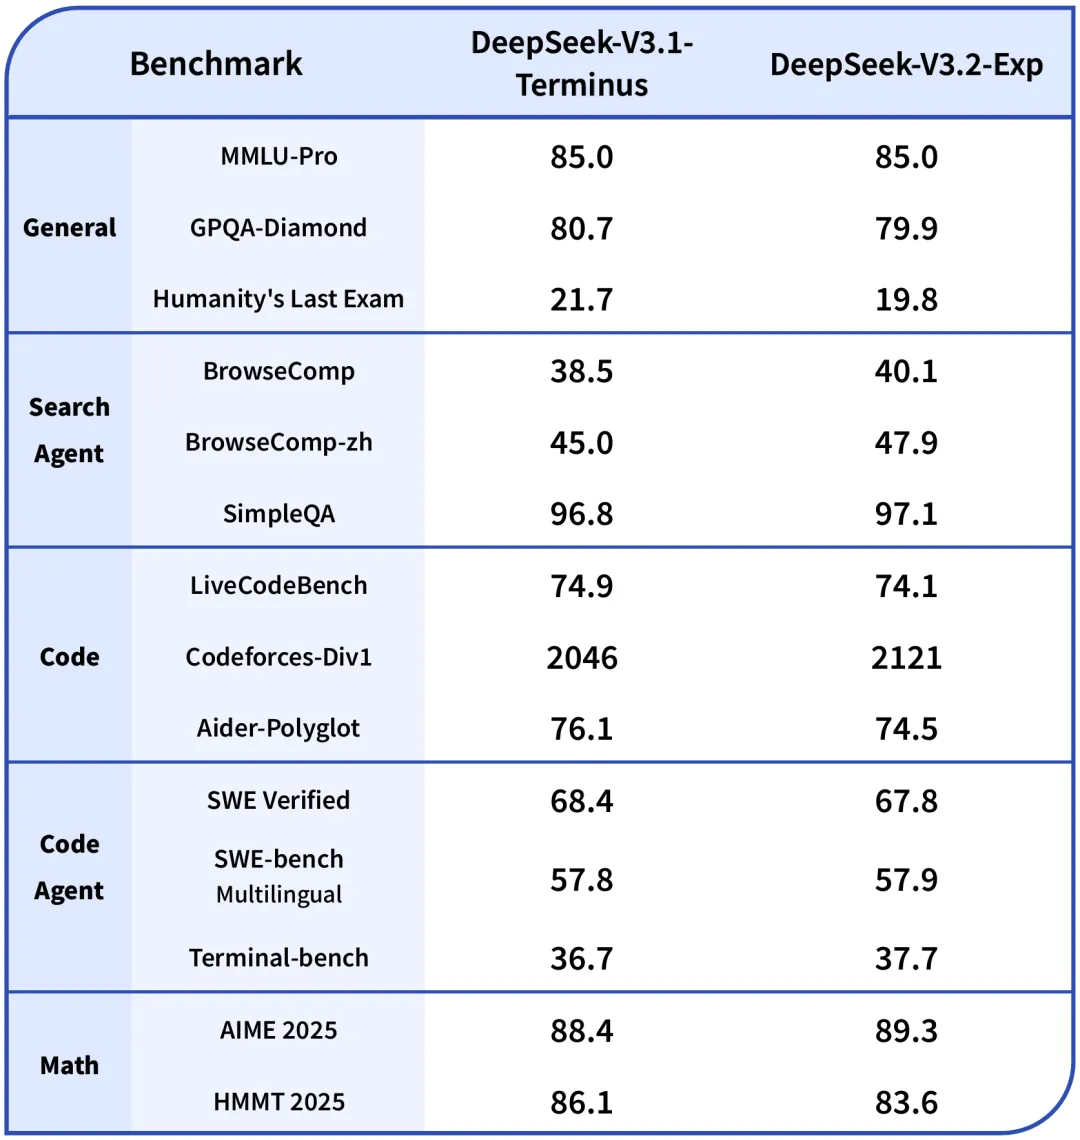
| DeepSeek-V3.2-Exp29 Sep 2025 · DeepSeek | 37.7% | Introducing DeepSeek-V3.2-ExpRow printed as 'Terminal-bench' with no version (2025). No metric or harness printed.Source image | Yes |
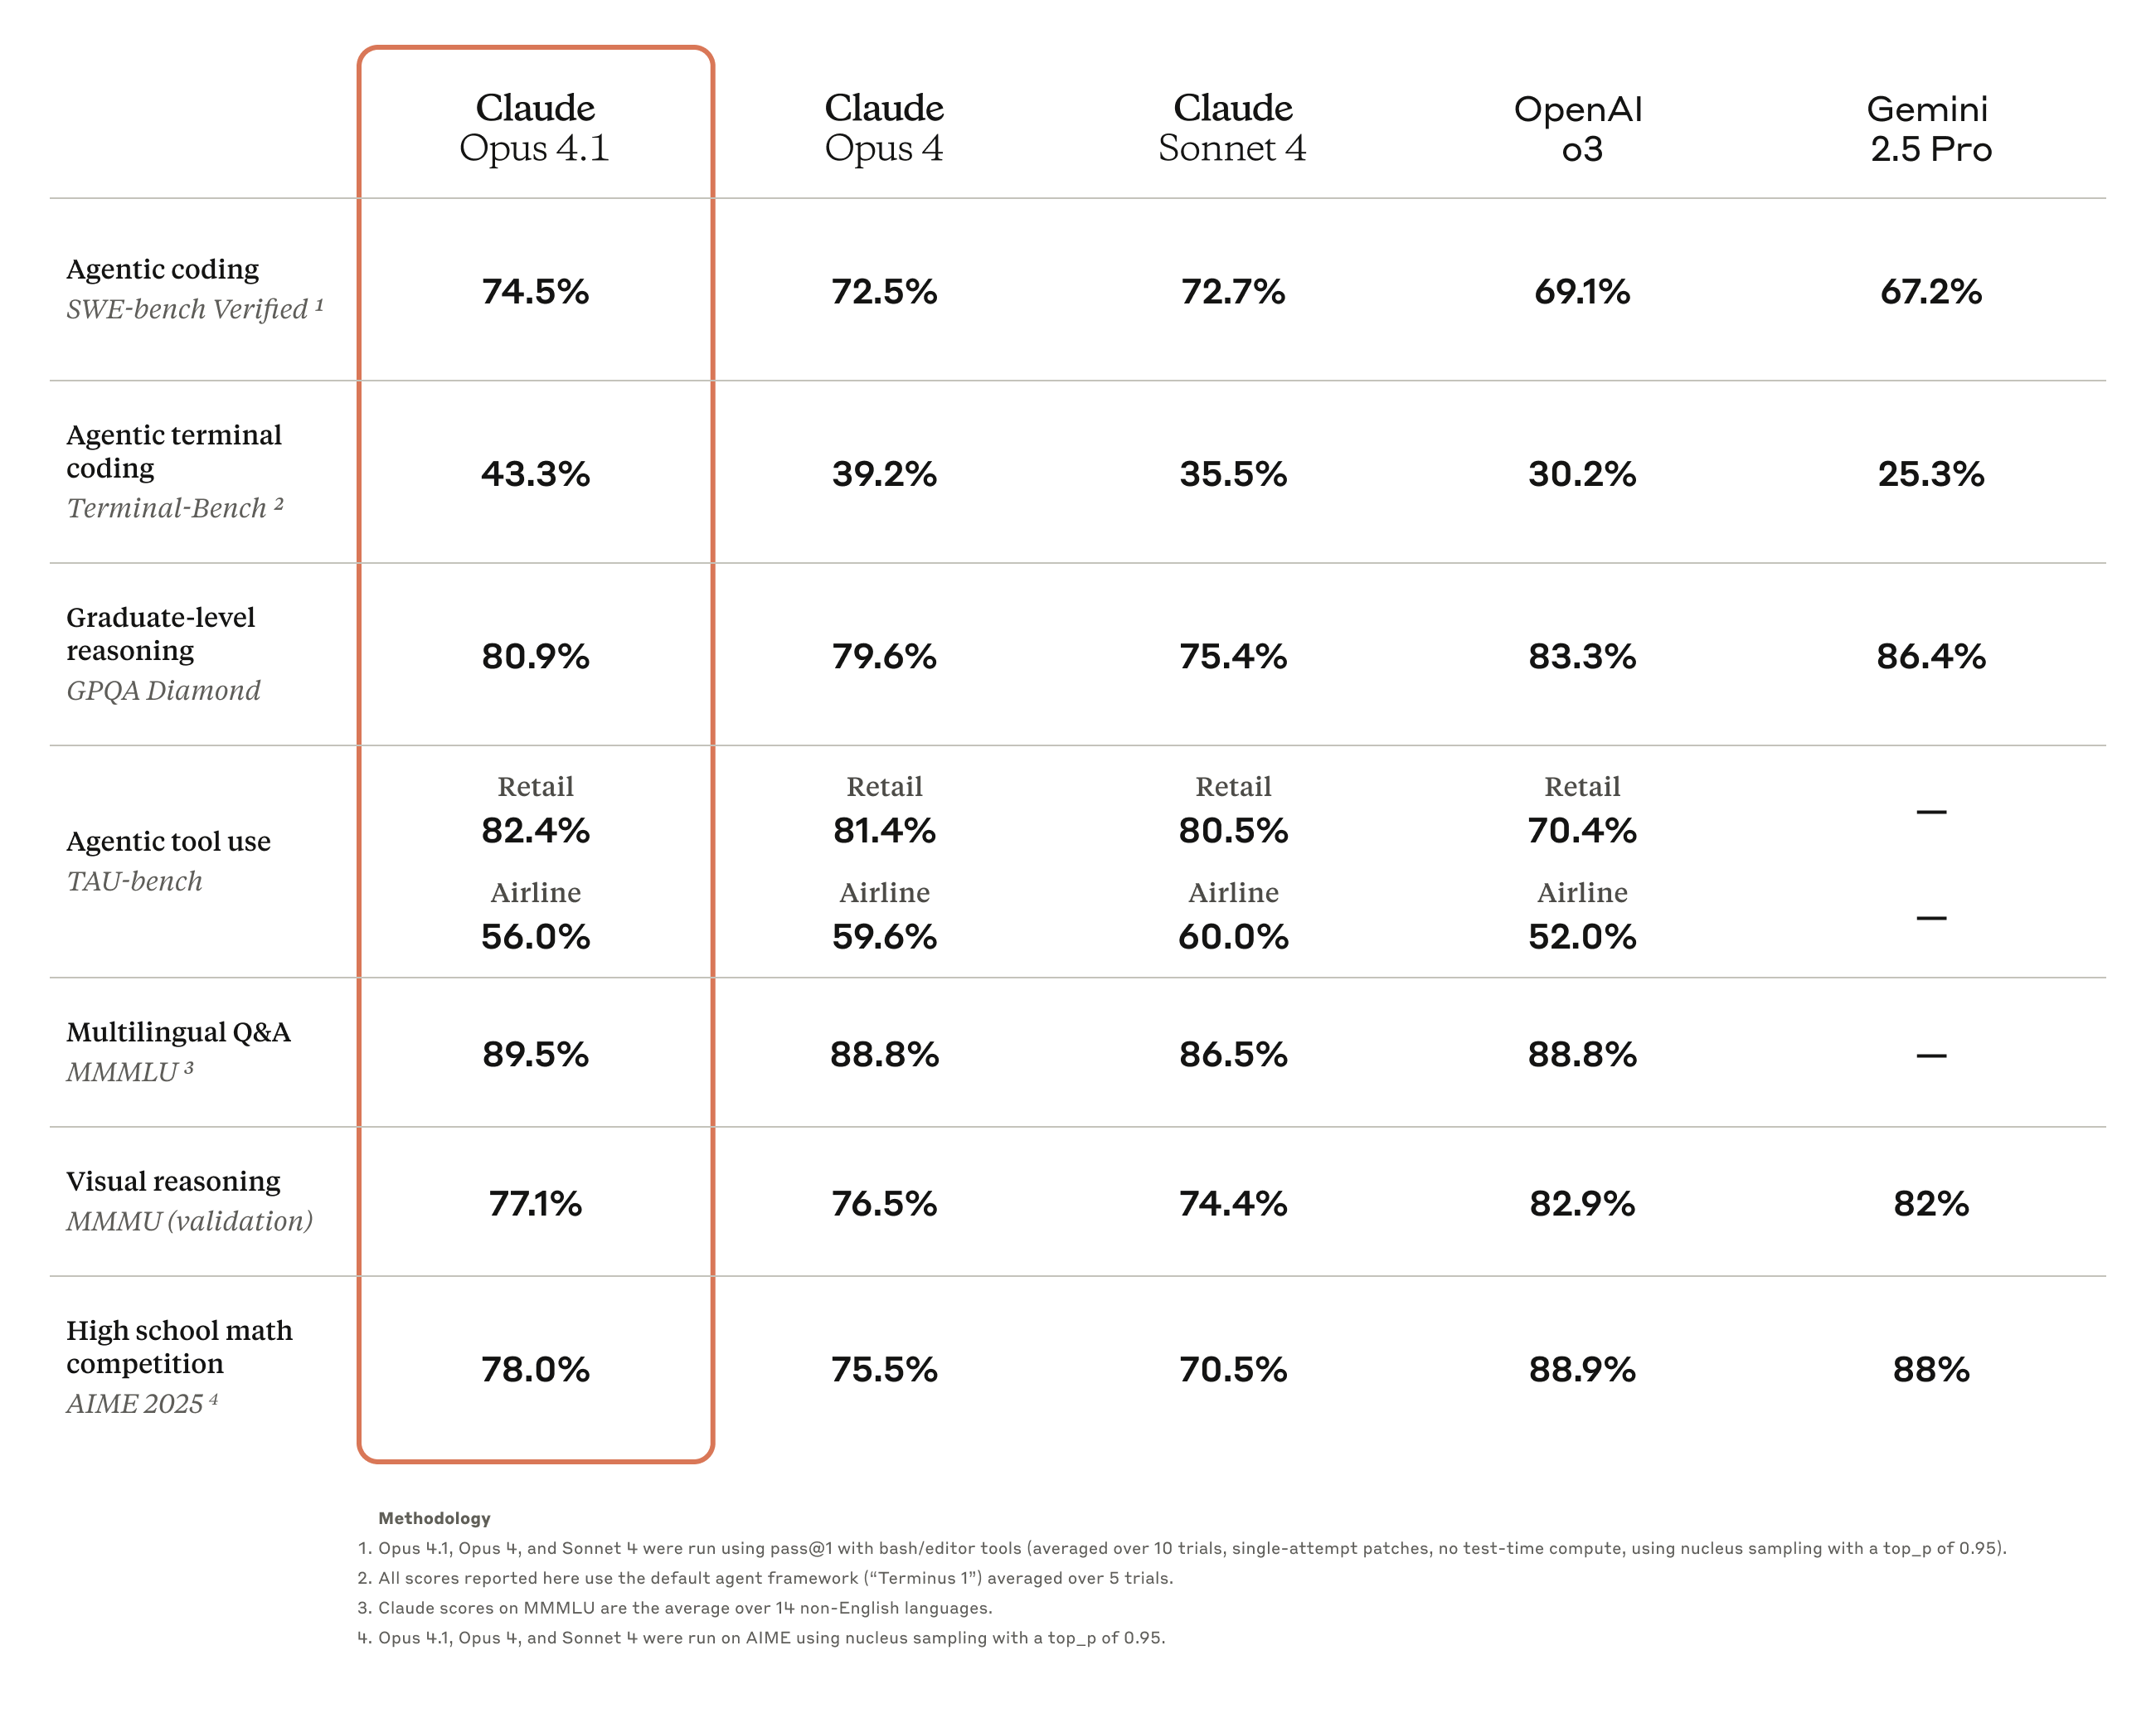
| Claude Opus 4.15 Aug 2025 · Anthropic | 43.3% | Claude Opus 4.1No extended thinking (appendix). Footnote 2: default agent framework ('Terminus 1'), averaged over 5 trials. Printed as 'Terminal-Bench' without version (2025).Source image | Yes |
| Claude Opus 422 May 2025 · Anthropic | 43.2% | Introducing Claude 4No extended thinking (appendix). Footnote 2: Claude Code as agent framework. Same number also in the intro sentence: 'leading on SWE-bench (72.5%) and Terminal-bench (43.2%)'. Printed as 'Terminal-bench' without version (2025). | Yes |
| Claude Opus 422 May 2025 · Anthropic | 50.0% | Introducing Claude 4parallel test-time compute; Footnote 5: parallel test-time compute, sampling multiple sequences and selecting the best via an internal scoring model. Claude Code as agent framework. | Yes |
| Claude Opus 422 May 2025 · Anthropic | 39.2% | Introducing Claude 4another report, not charted; pass@1 with the same agent as non-Claude models (not Claude Code); no extended thinking. | Yes |
Benchmark
tbench.aiHigher is better
Stanford University and Laude InstituteIntroduced 19 May 2025