GLM-4.5
- Made by
- Z.ai
- Released
- Announced in
- GLM-4.5: Reasoning, Coding, and Agentic Abililtiesz.ai
- Event
- GLM-4.5 and GLM-4.5-Air
- API record
- /api/v1/models/glm-4-5
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
| Humanity's Last ExamNo tools · thinking mode; text-only questions; GPT-4o judge | 14.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
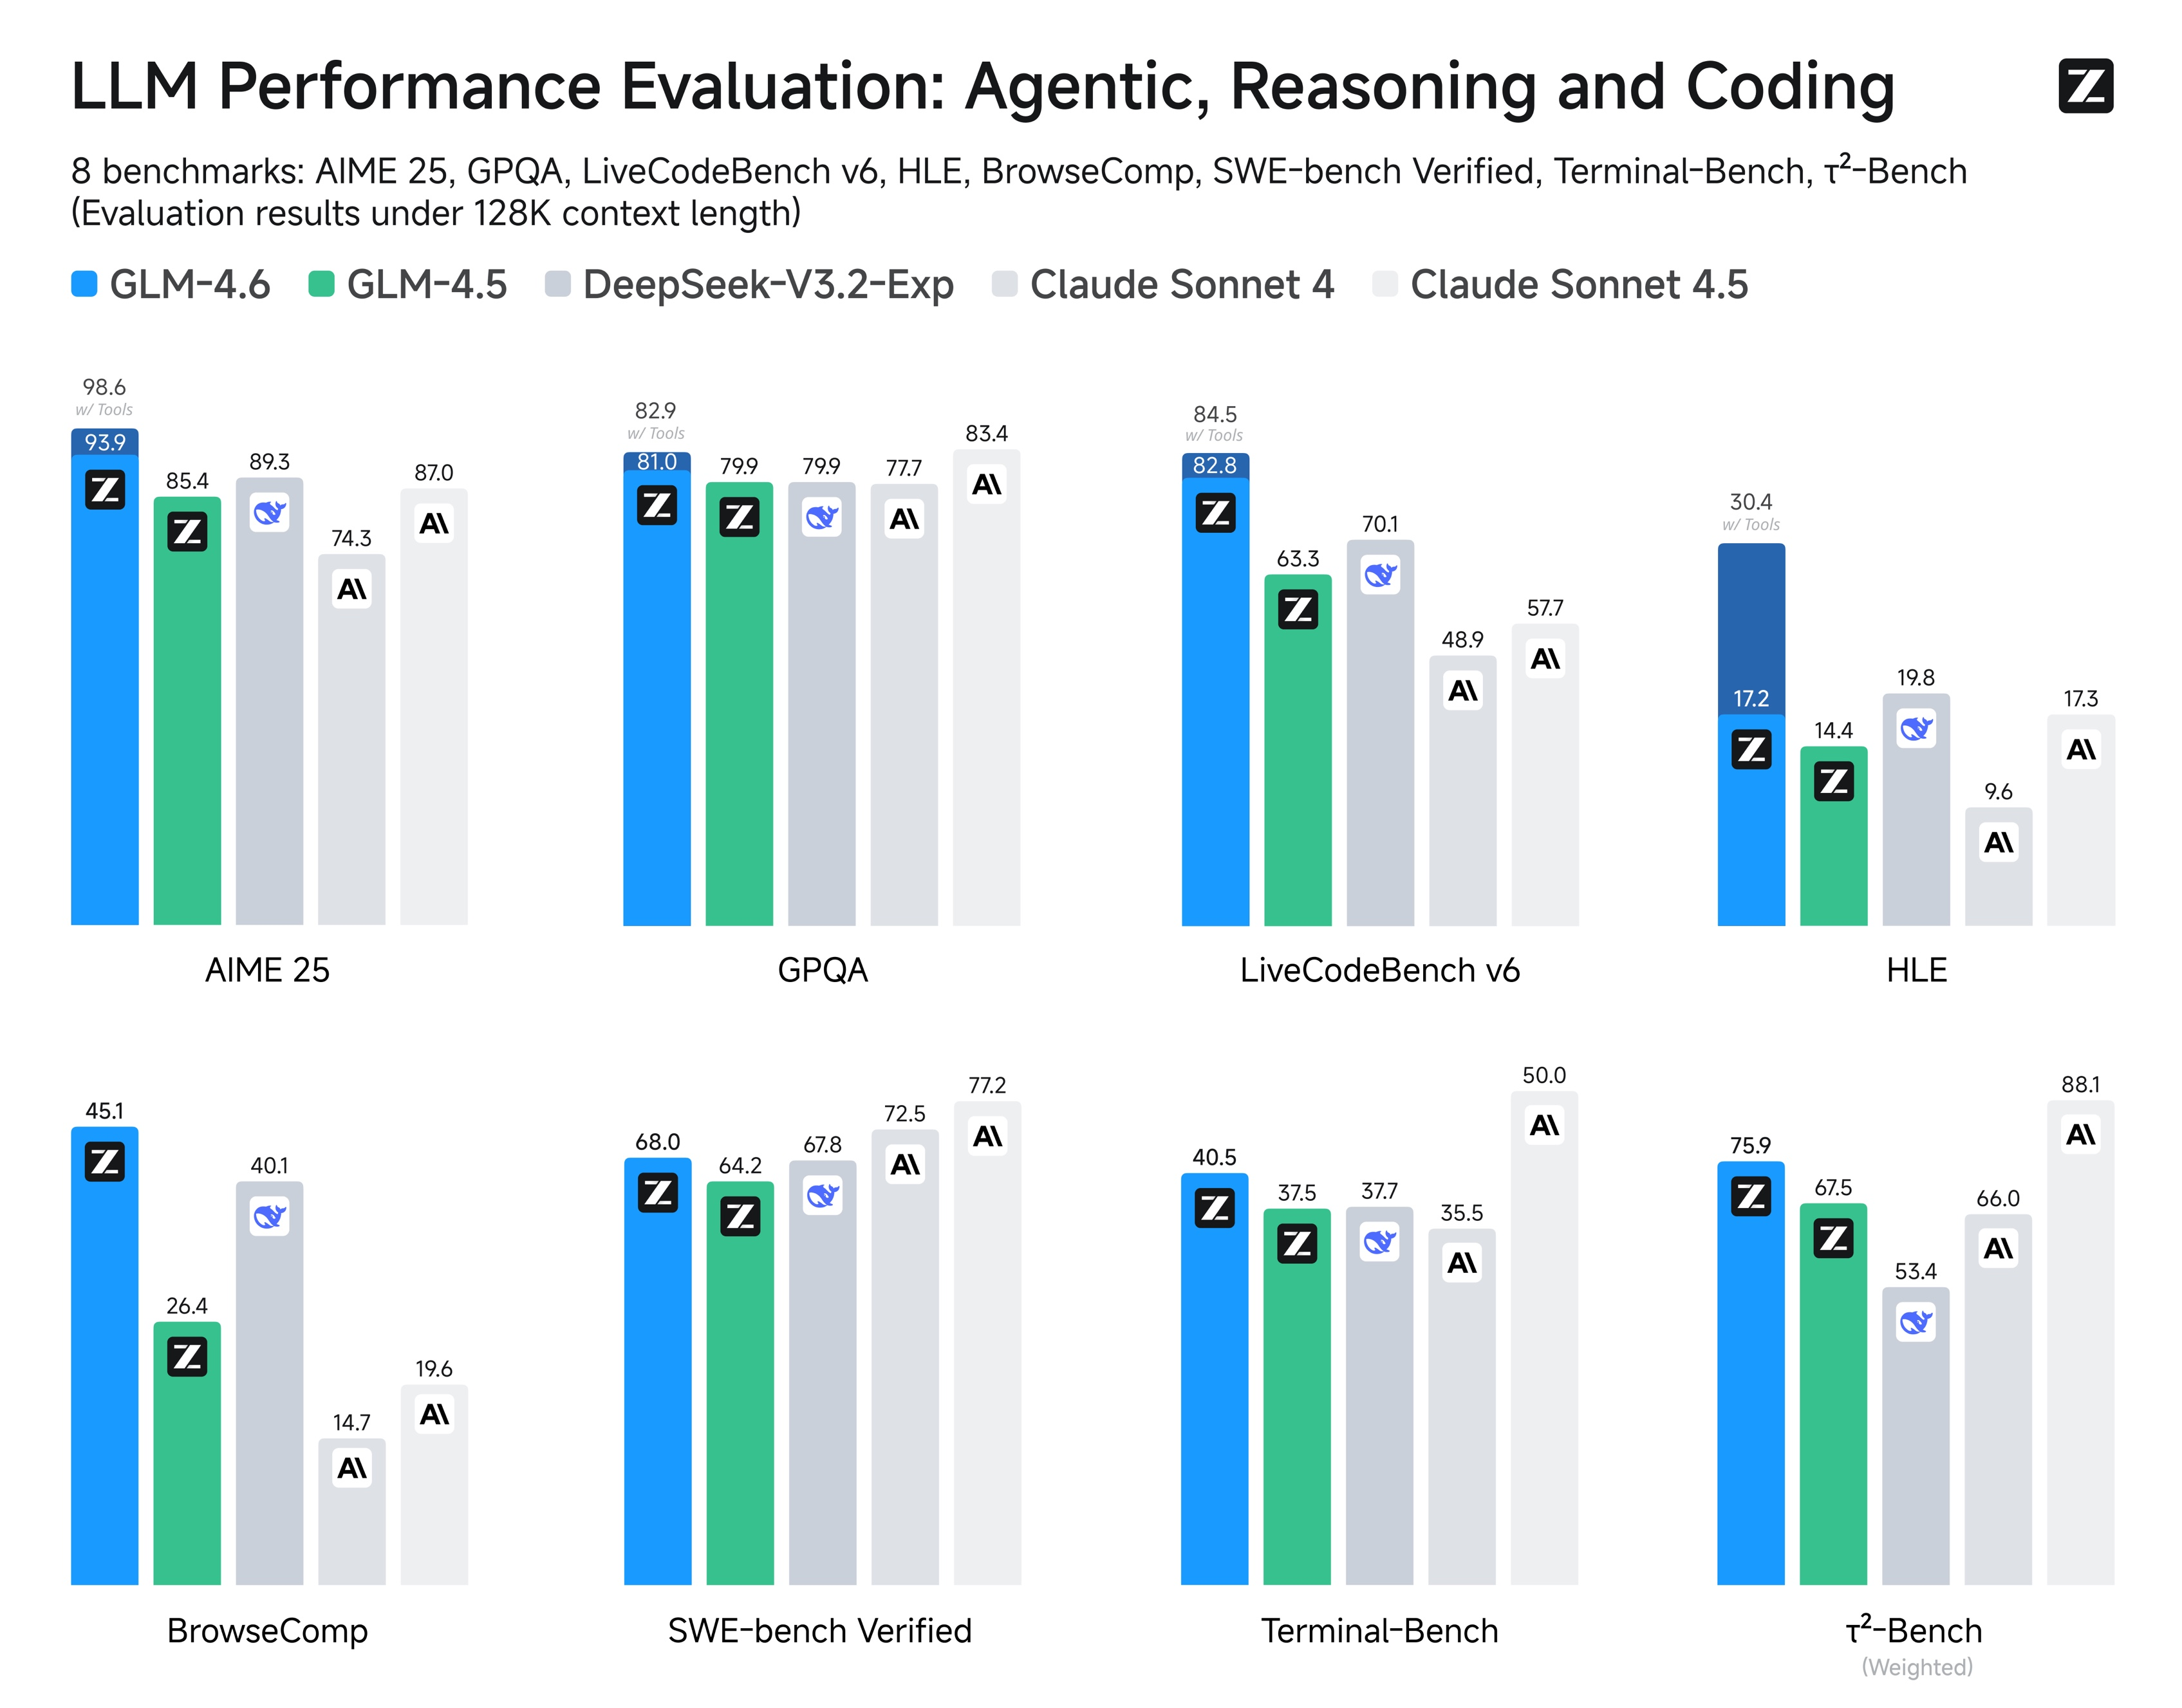
| SWE-bench VerifiedOpenHands v0.34.0; up to 100 iterations; 128K context with history truncation | 64.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| GPQA Diamondthinking mode; average over 8 samples | 79.1% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
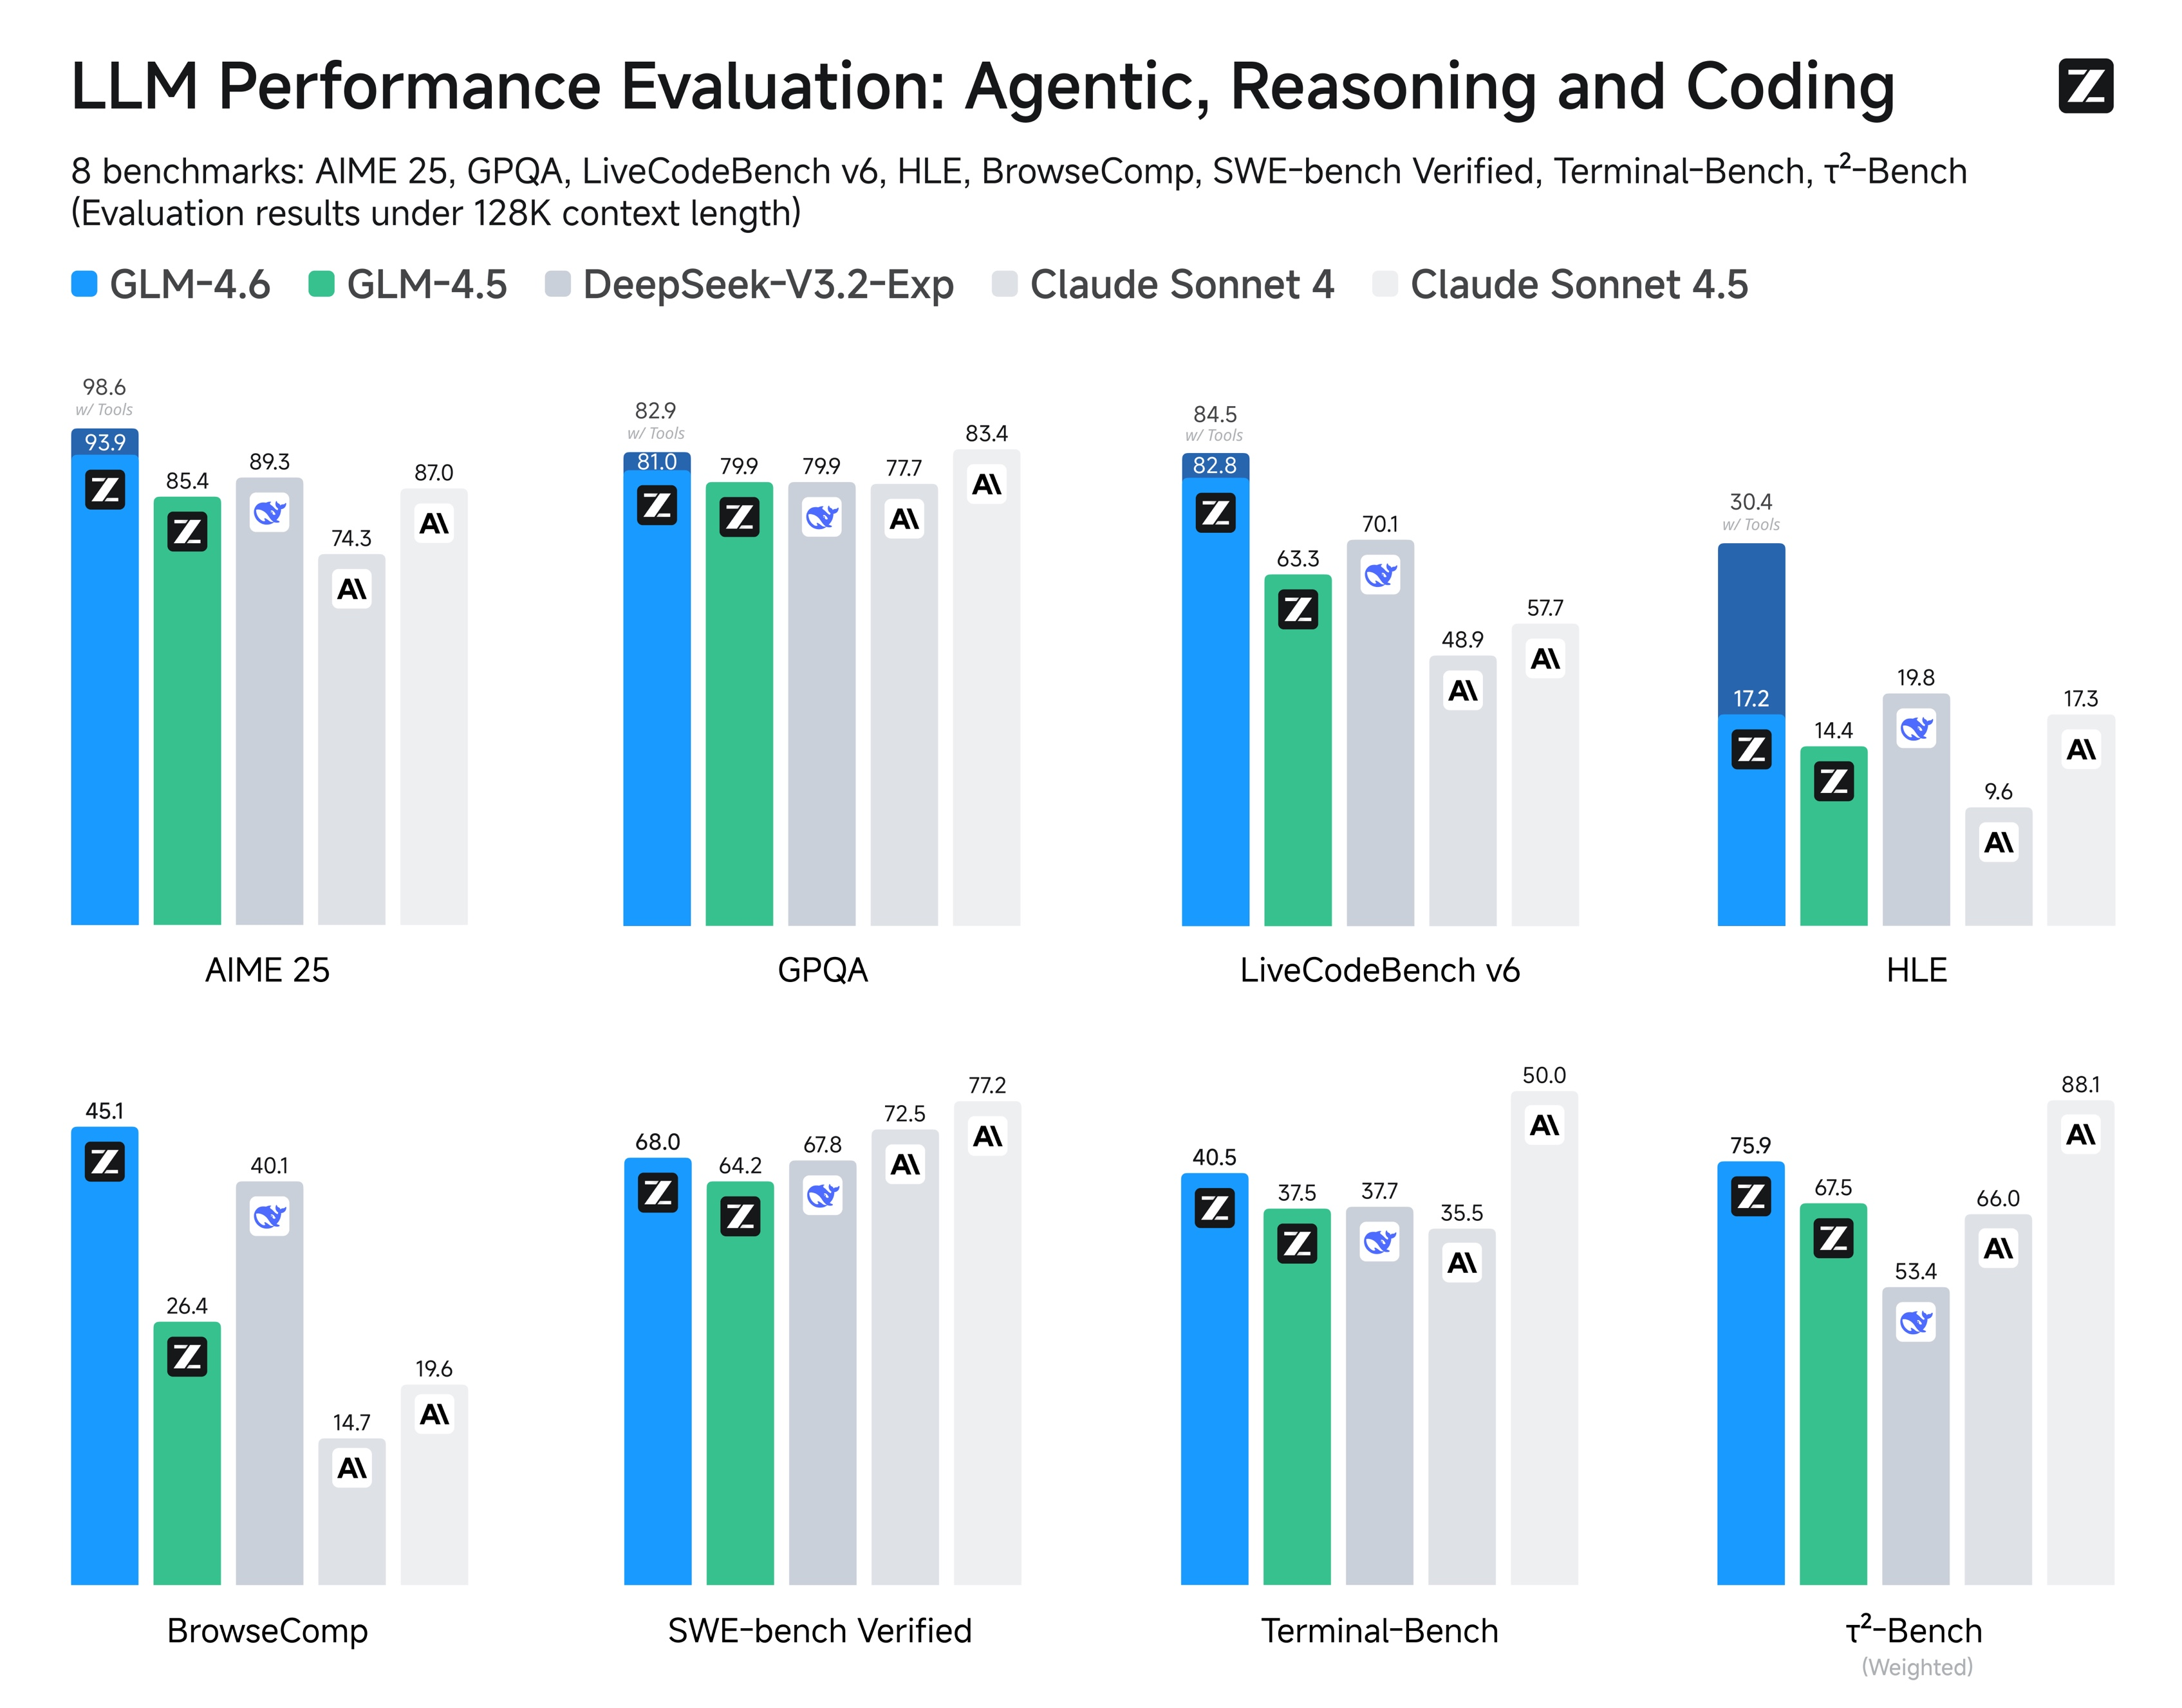
| 128K context · reported later, in GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities | 79.9% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
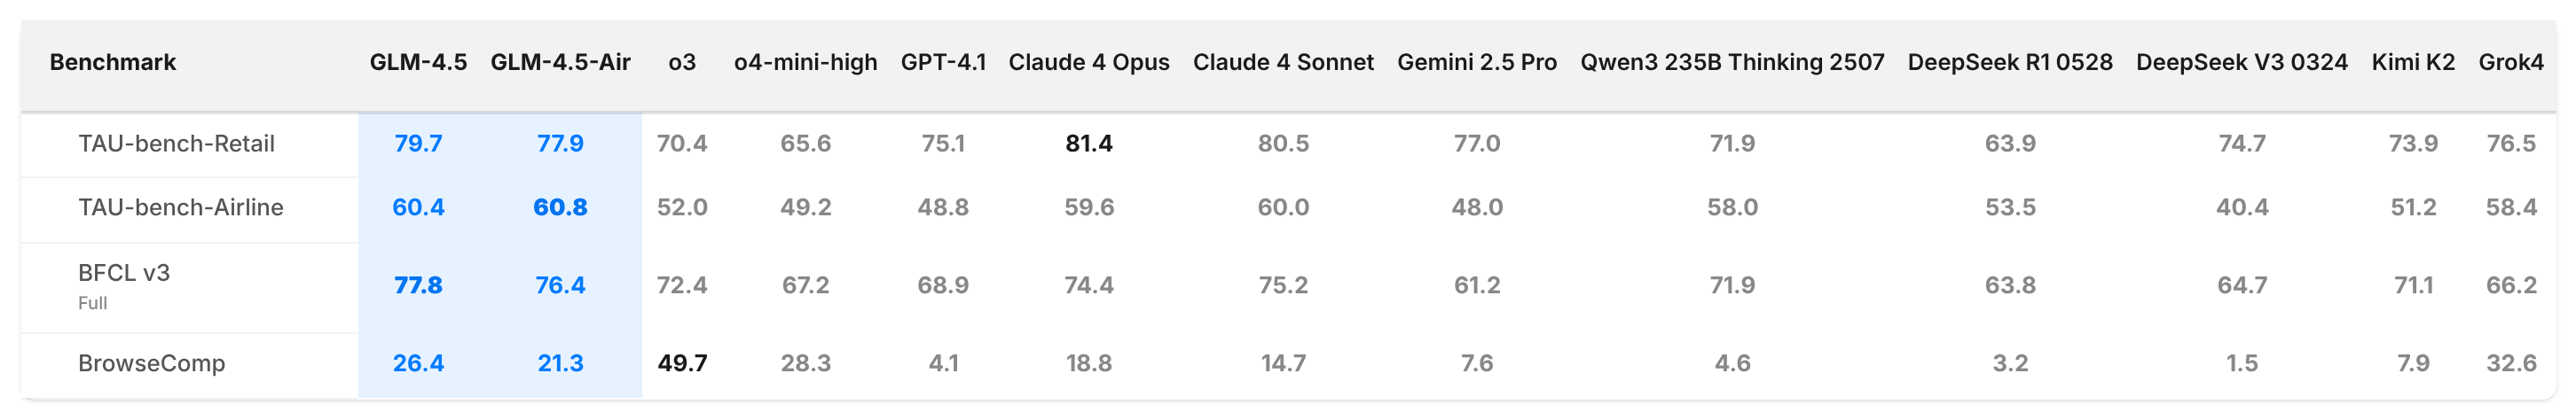
| BrowseCompweb browsing tool | 26.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| AIME 2024No tools · thinking mode; average over 32 samples, answers checked by an LLM | 91.0% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| AIME 2025No tools · 128K context · reported later, in GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities | 85.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 1.0Terminus harness, standard function calling | 37.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| MMLU-Prothinking mode | 84.6% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| LiveCodeBenchthinking mode; problems from Jul 2024 to Jan 2025 | 72.9% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| LiveCodeBench v6; 128K context · reported later, in GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilities | 63.3% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by Z.ai
- GLM-4.5: Reasoning, Coding, and Agentic Abililtiesz.ai · 28 Jul 2025
Our capture of the source 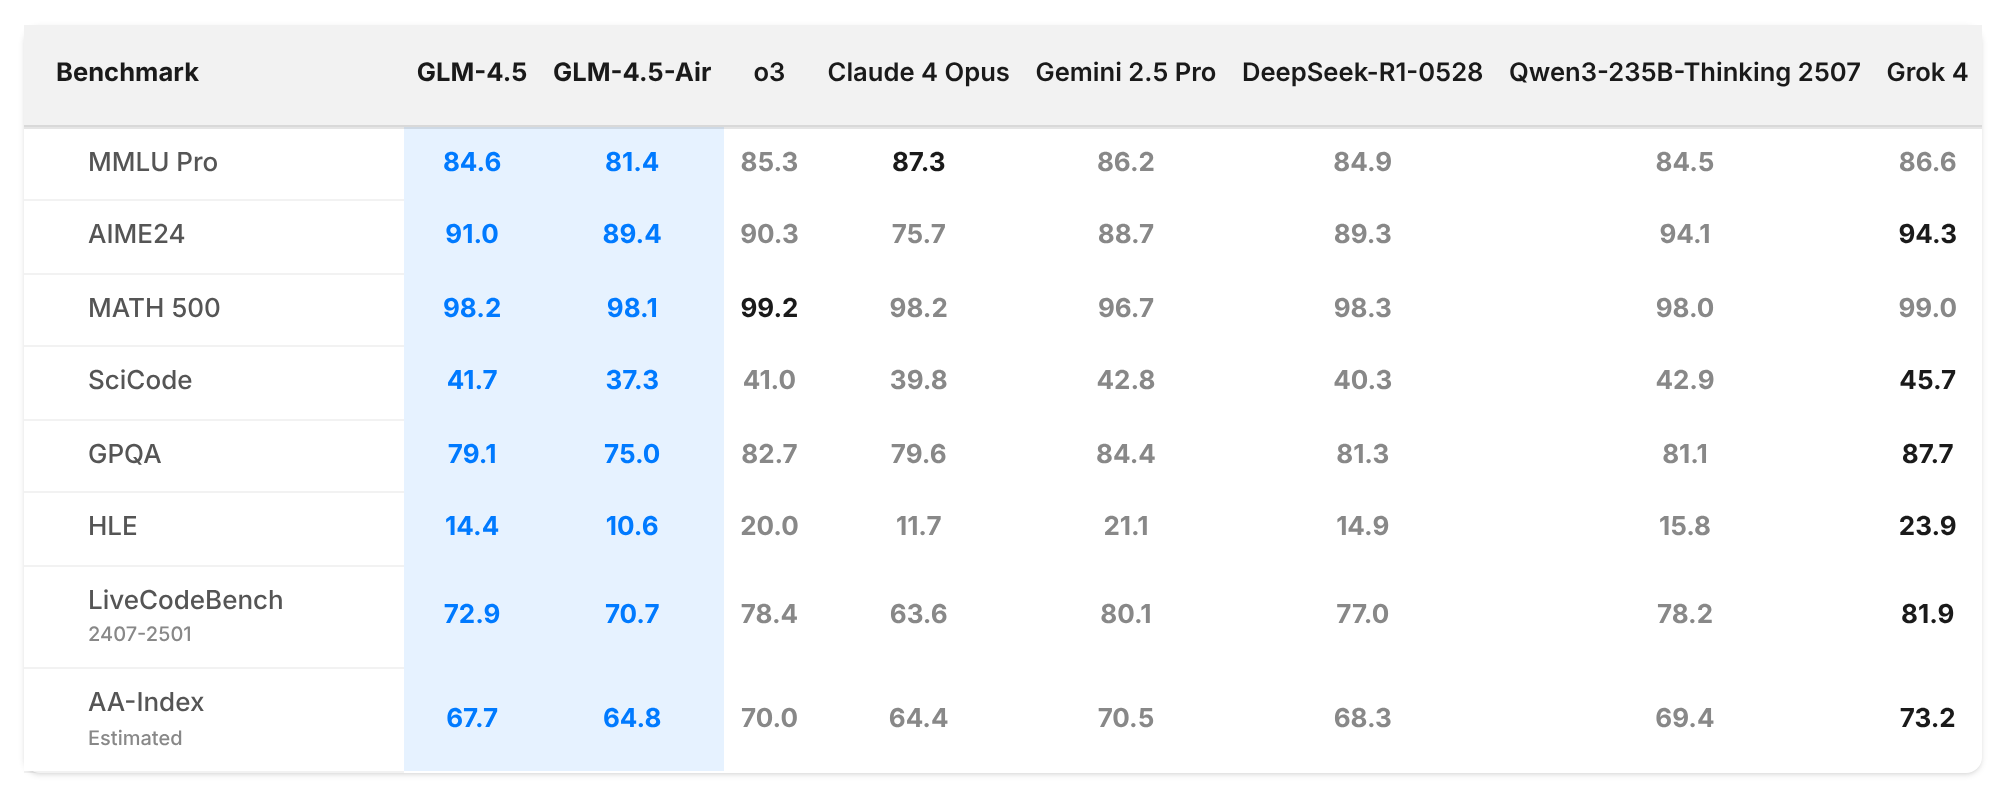
Our capture of the source 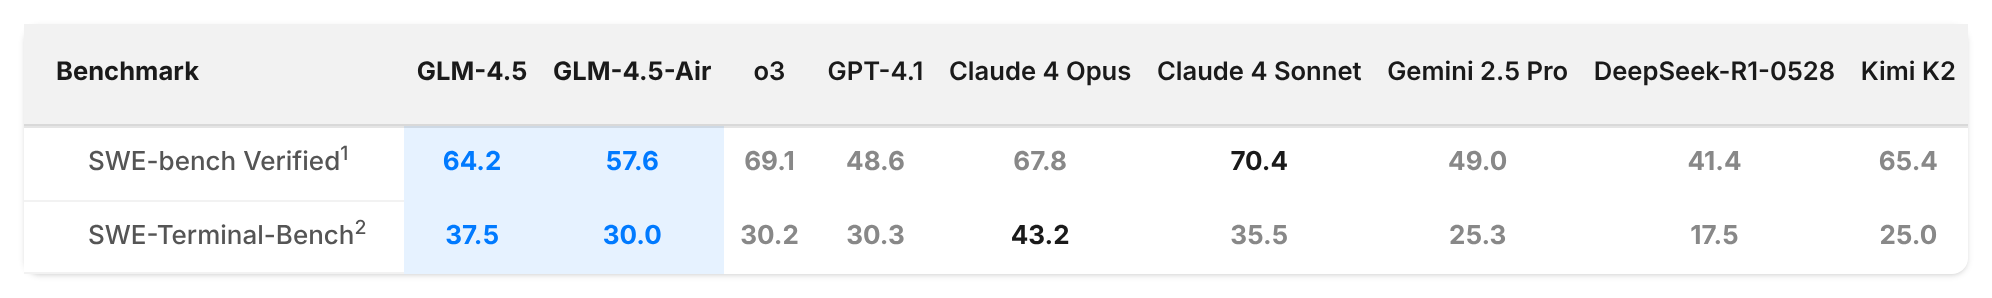
Our capture of the source - GLM-4.6: Advanced Agentic, Reasoning and Coding Capabilitiesz.ai · 30 Sep 2025
Original image