LiveCodeBench, no release named
Created by UC Berkeley, MIT and Cornell, 12 Mar 2024 · Higher is better · Website
- Other labs
- Reported in a later post or card
Results
| Model | Score | Source | Source check |
|---|---|---|---|
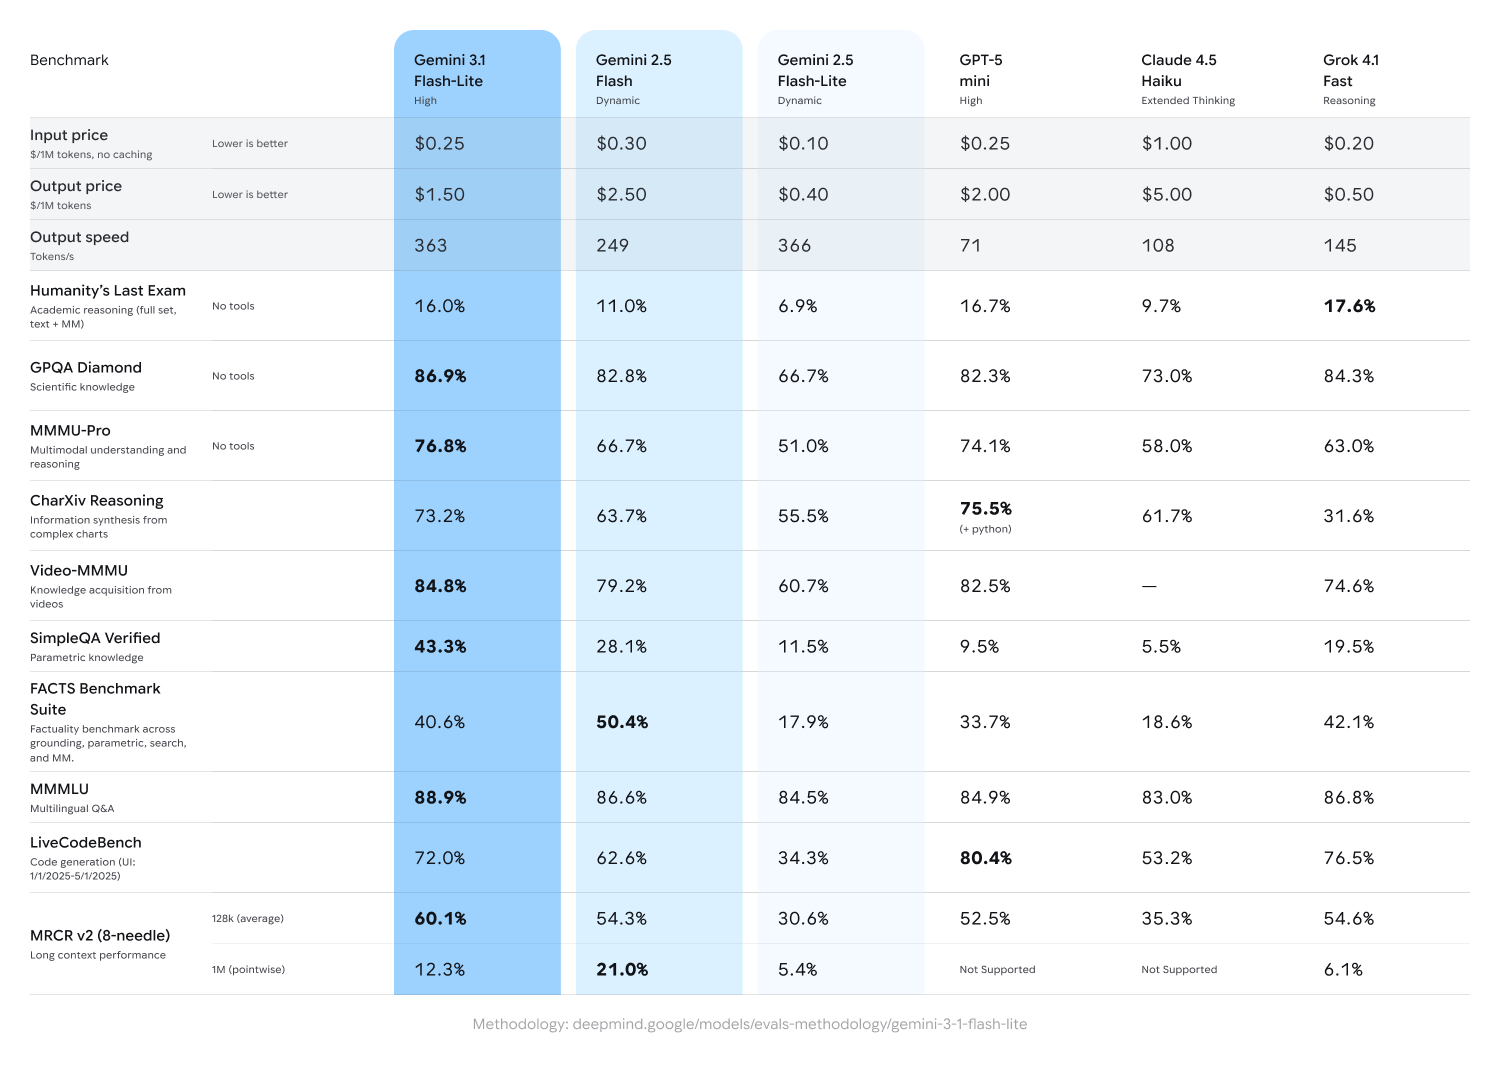
| Gemini 3.1 Flash-Lite3 Mar 2026 · Google | 72.0% | Gemini 3.1 Flash-Lite: Built for intelligence at scalehigh thinking; problems from 1/1/2025 to 5/1/2025Source image | CheckedA person checked this number against its source on 29 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| LongCat-Flash-Thinking-260120 Jan 2026 · Meituan | 82.8% | 美团 LongCat-Flash-Thinking-2601 发布,工具调用能力登顶开源 SOTA!average of 4 runs; problems from Aug 2024 to May 2025 | |
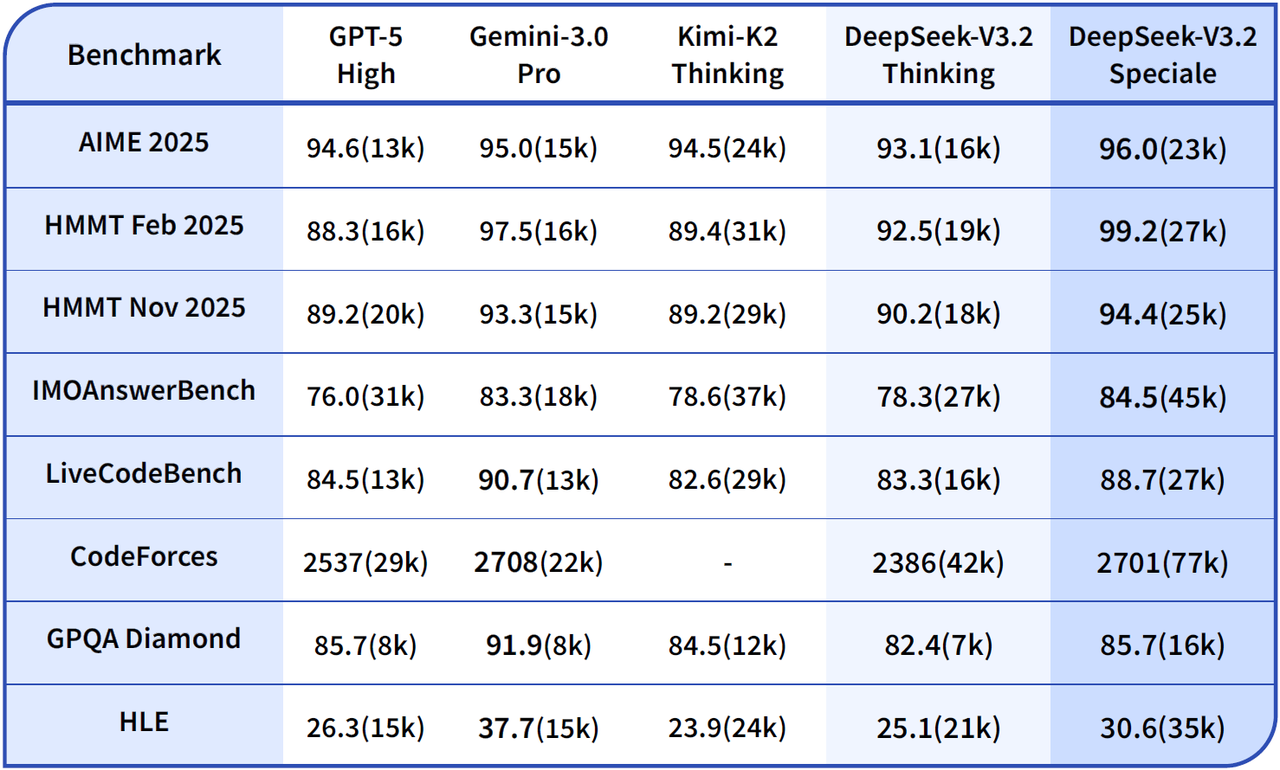
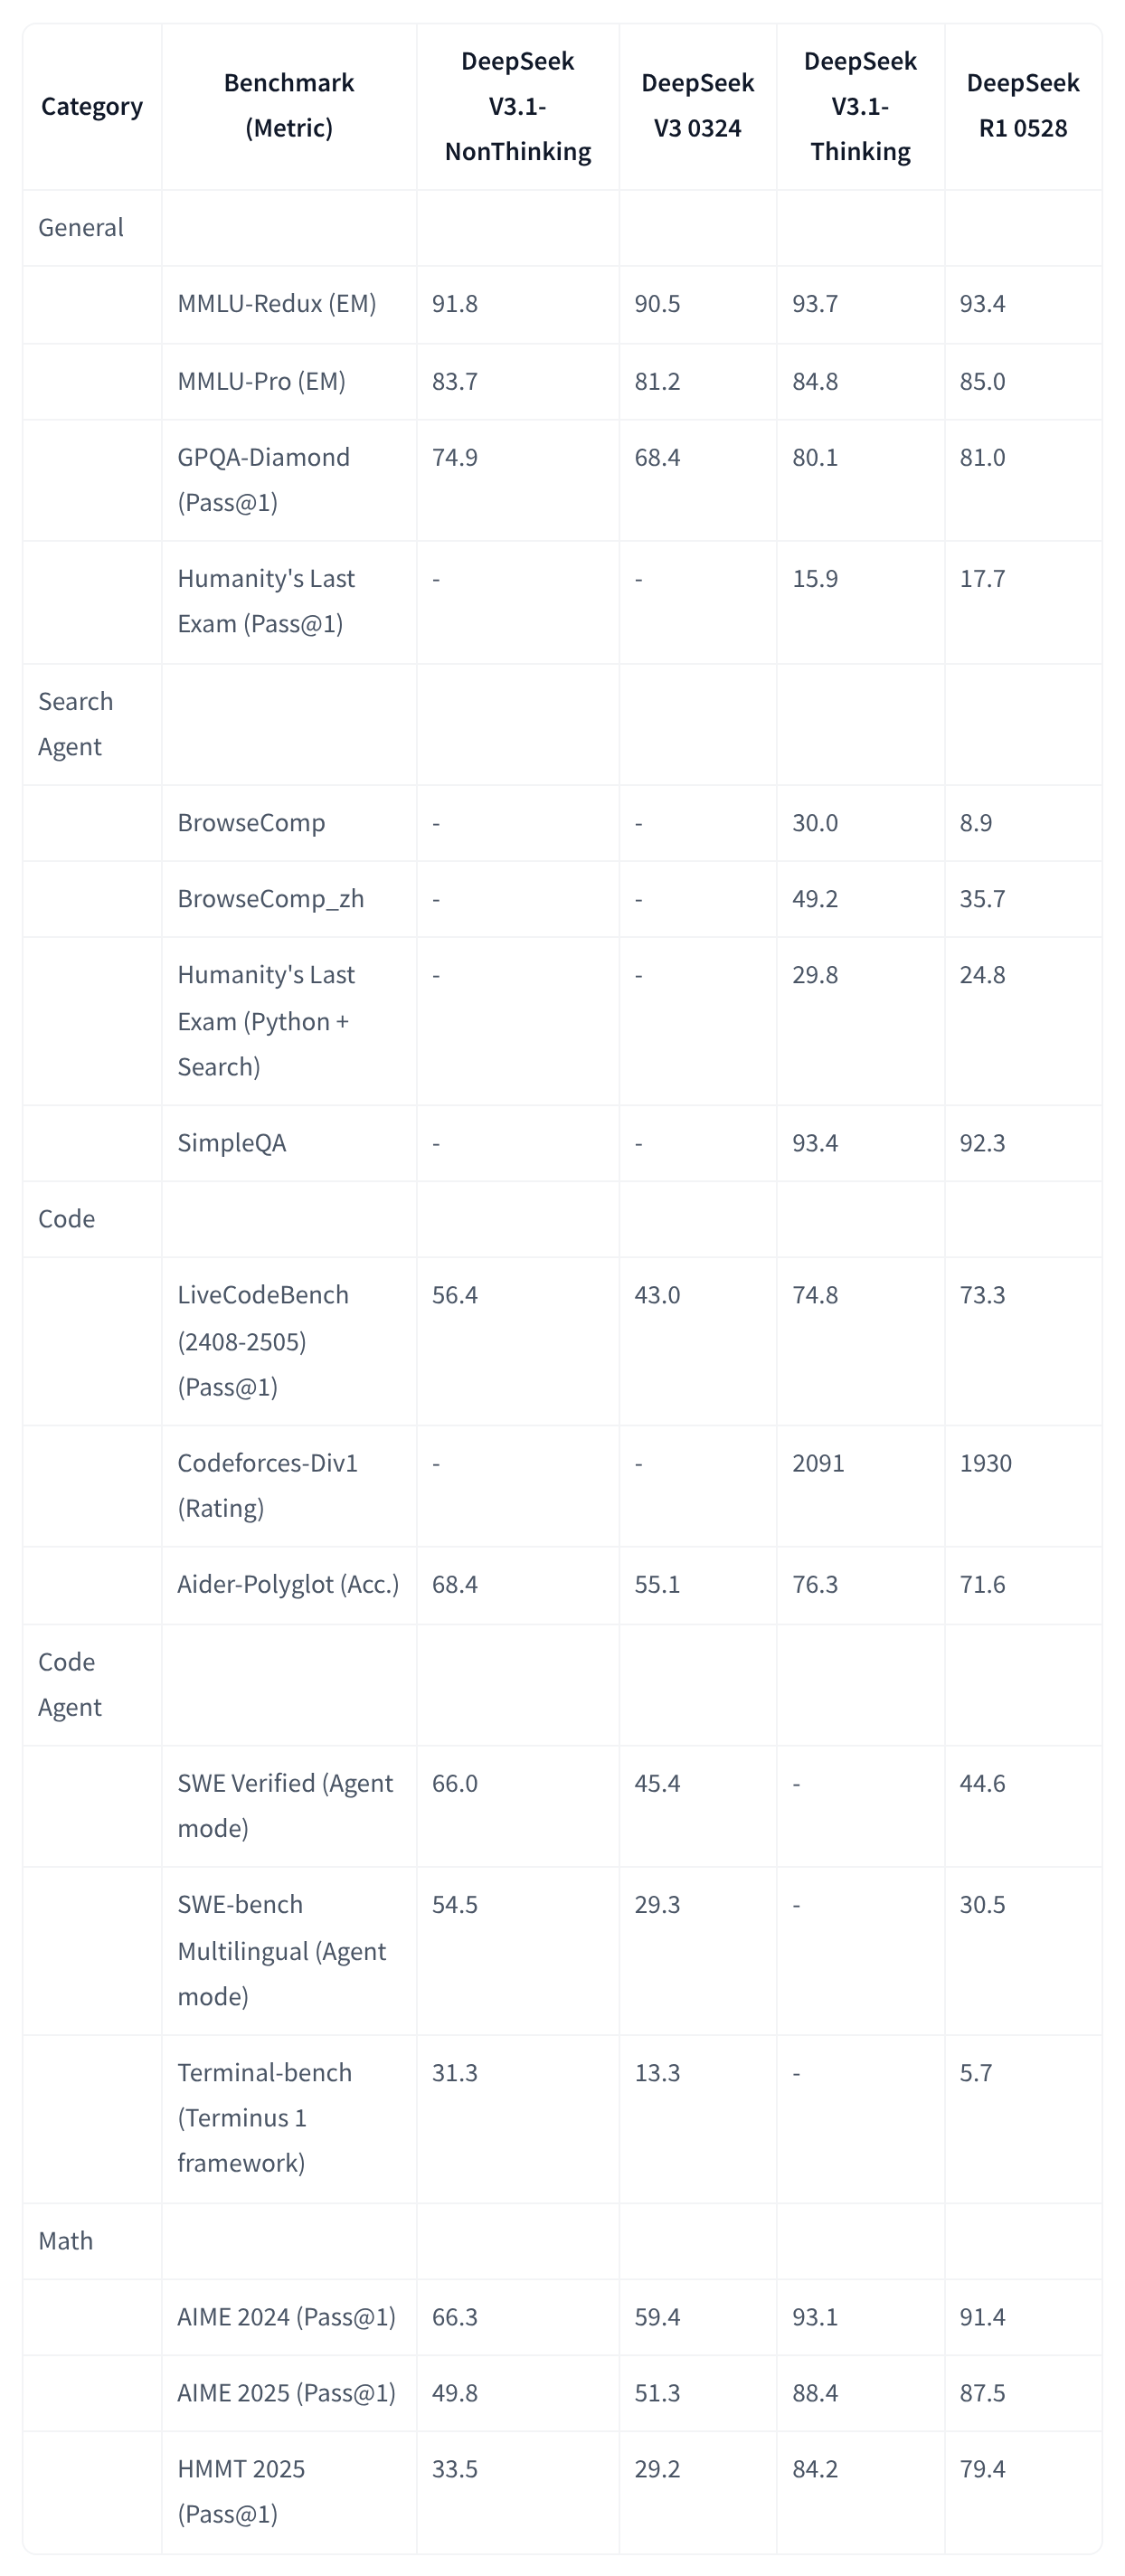
| DeepSeek-V3.21 Dec 2025 · DeepSeek | 83.3% | DeepSeek-V3.2 Releasethinking mode; 16K output tokens; problems from Aug 2024 to Apr 2025Source image | CorroboratedThe same number is printed in 1 other lab document: 1 |
| DeepSeek-V3.2-Speciale1 Dec 2025 · DeepSeek | 88.7% | DeepSeek-V3.2 Release27K output tokens; problems from Aug 2024 to Apr 2025Source image | CorroboratedThe same number is printed in 1 other lab document: 1 |
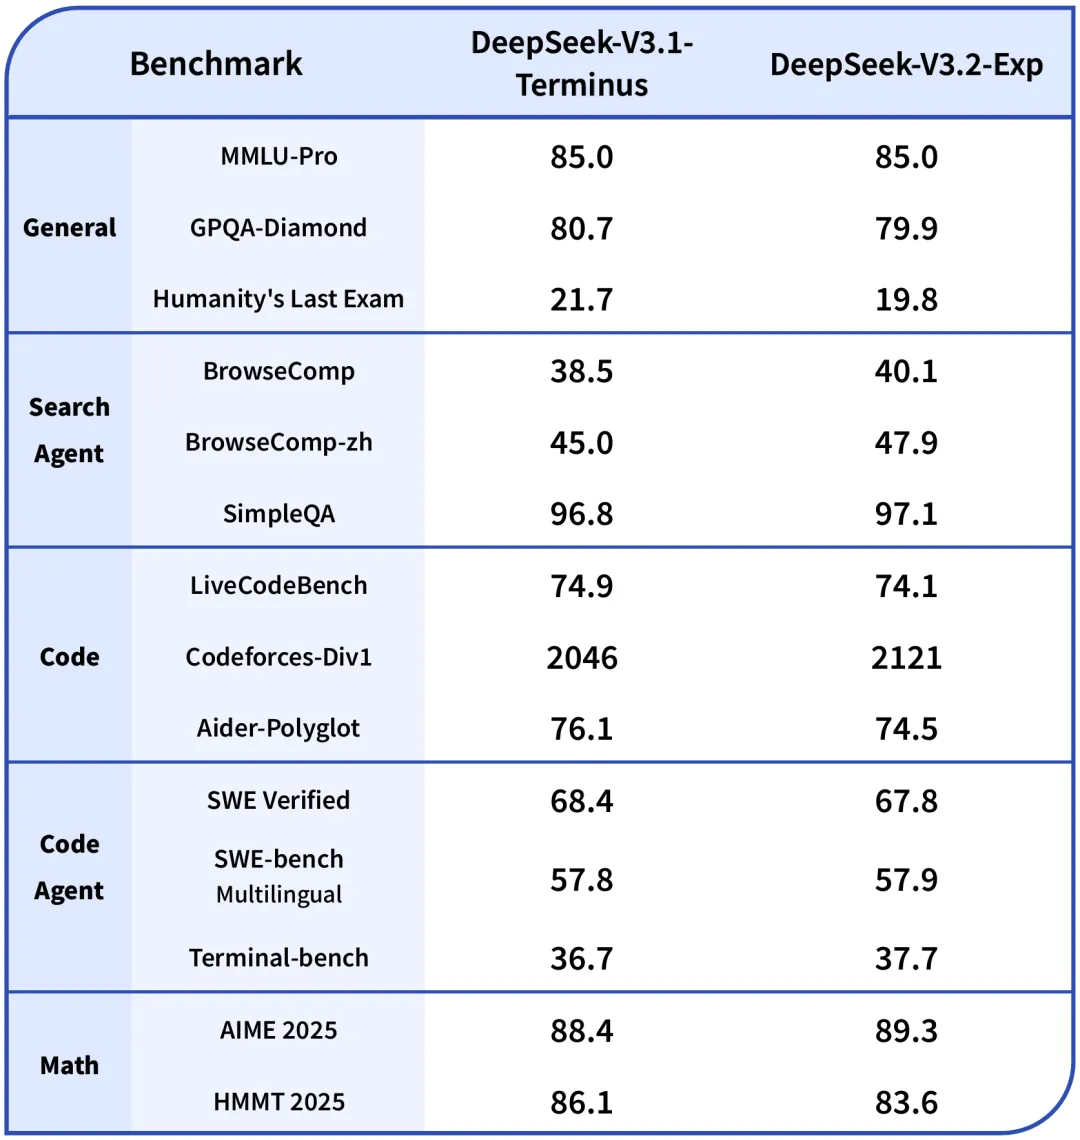
| DeepSeek-V3.2-Exp29 Sep 2025 · DeepSeek | 74.1% | Introducing DeepSeek-V3.2-Expreasoning mode without tools; problems from Aug 2024 to May 2025Source image | |
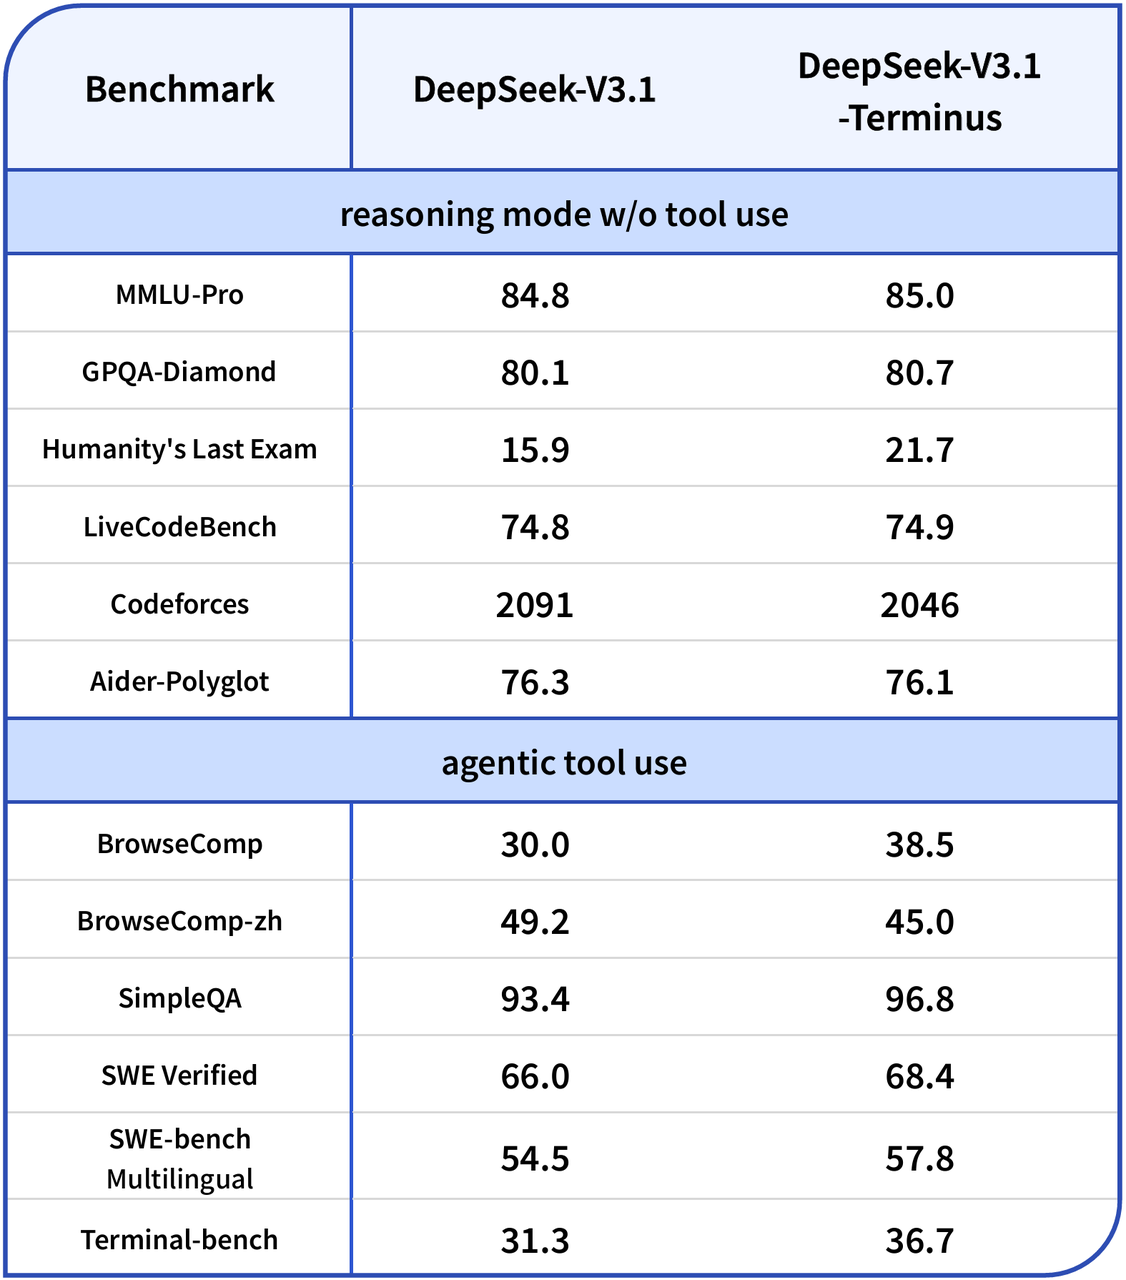
| DeepSeek-V3.1-Terminus22 Sep 2025 · DeepSeek | 74.9% | DeepSeek-V3.1-Terminusreasoning mode without tools; problems from Aug 2024 to May 2025Source image | |
| LongCat-Flash-Thinking22 Sep 2025 · Meituan | 79.4% | LongCat-Flash-Thinking 正式发布,更强、更专业,保持极速!average of 4 runs; problems from Aug 2024 to May 2025 | |
| DeepSeek-V3.121 Aug 2025 · DeepSeek | 56.4% | deepseek-ai/DeepSeek-V3.1 model cardnon-thinking mode; problems from Aug 2024 to May 2025Our capture | CheckedA person checked this number against its source on 29 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
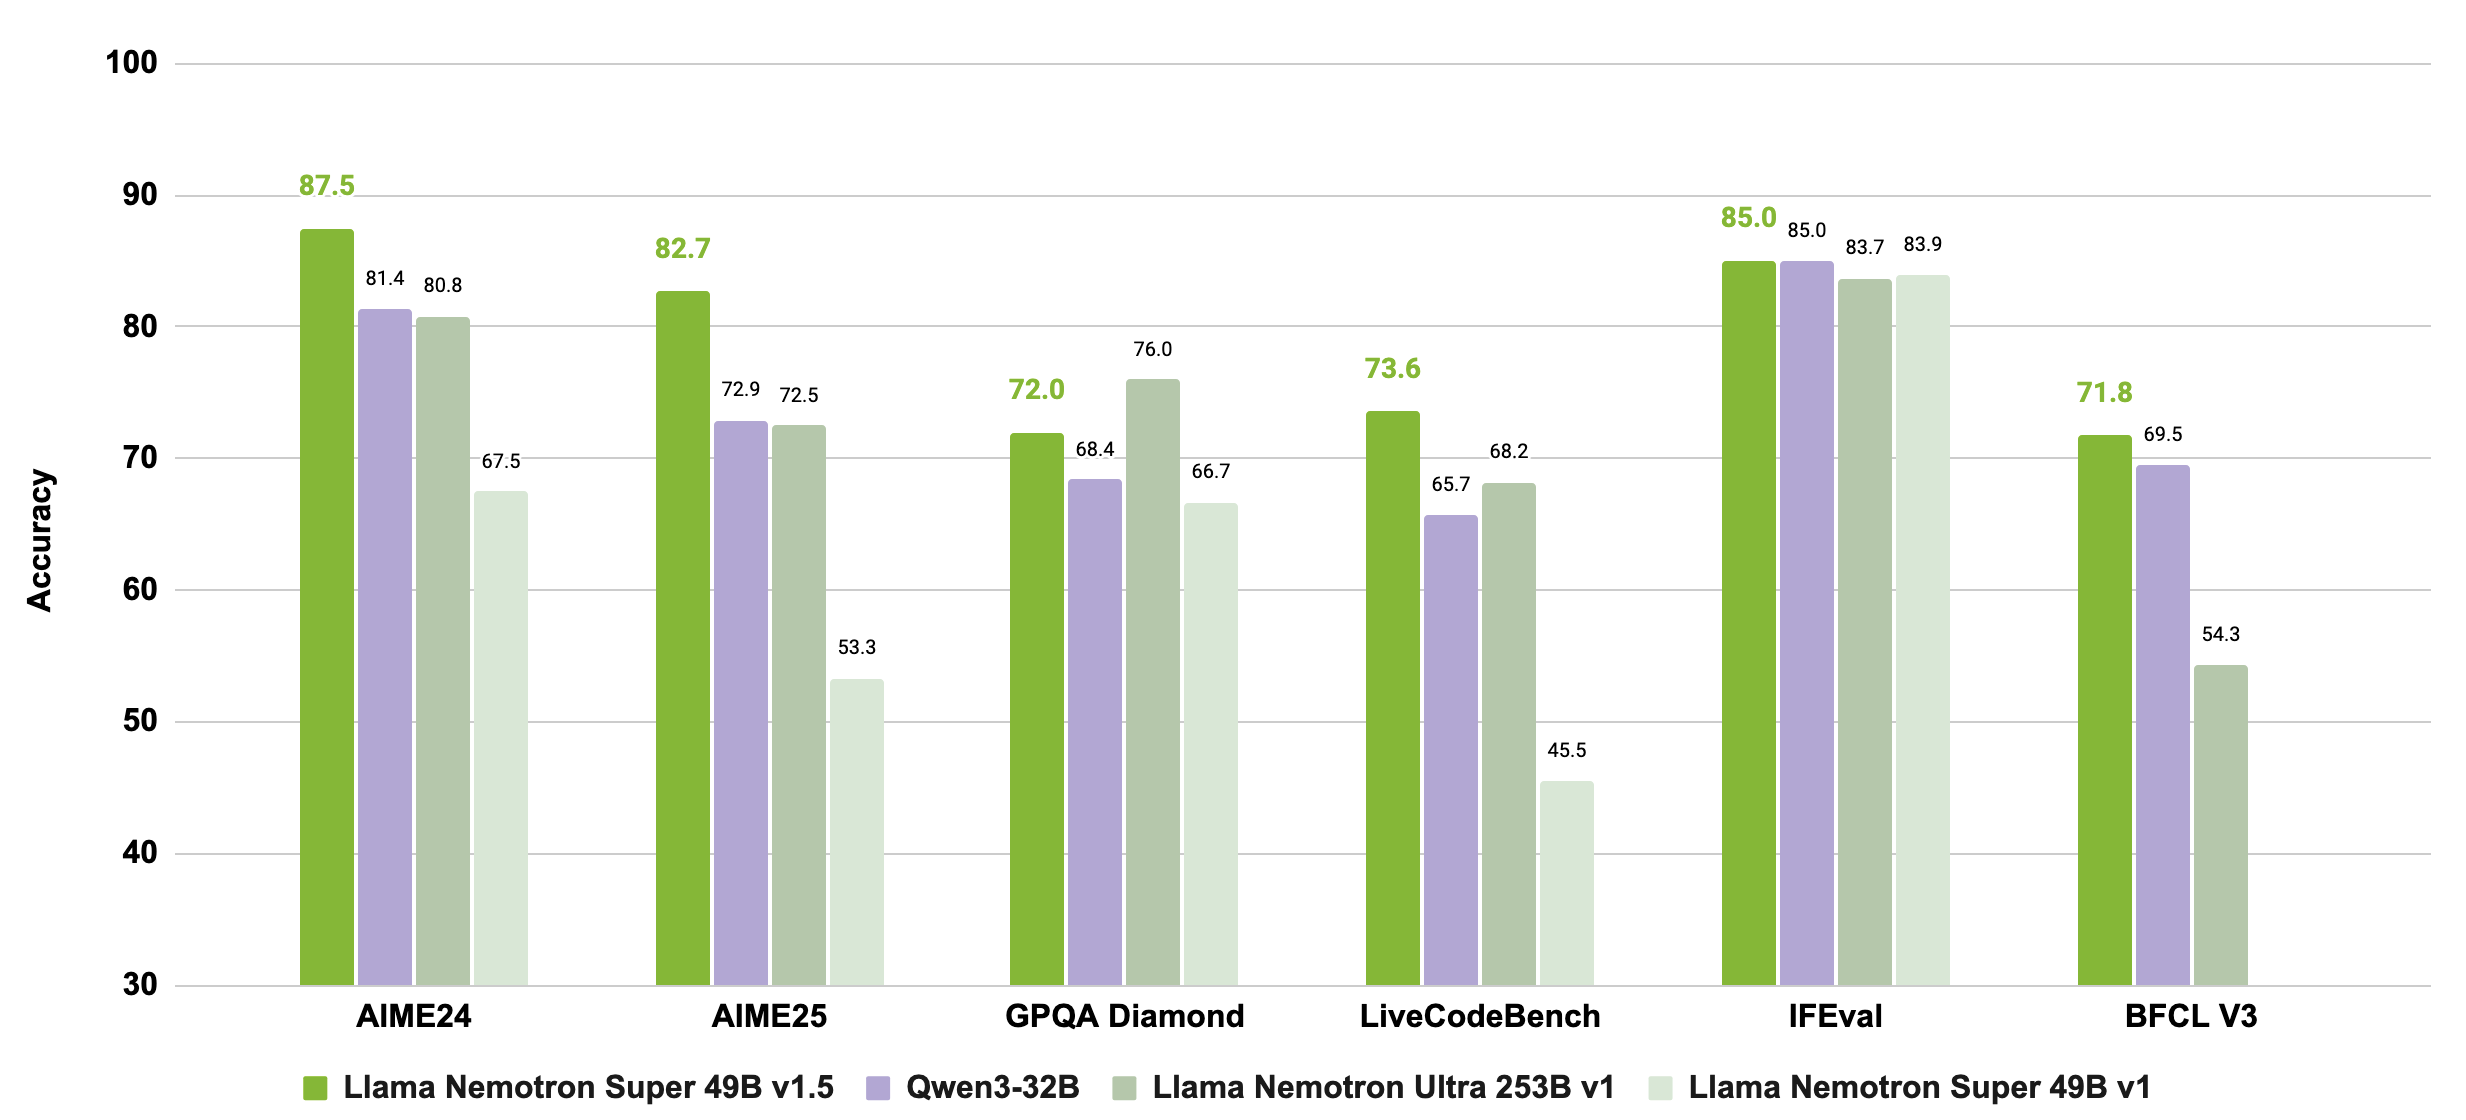
| Llama Nemotron Super 49B v1.529 Jul 2025 · NVIDIA | 73.6% | Build More Accurate and Efficient AI Agents with the New NVIDIA Llama Nemotron Super v1.5problems from Oct 2024 to Feb 2025Source image | CorroboratedThe same number is printed in 1 other lab document: 1 |
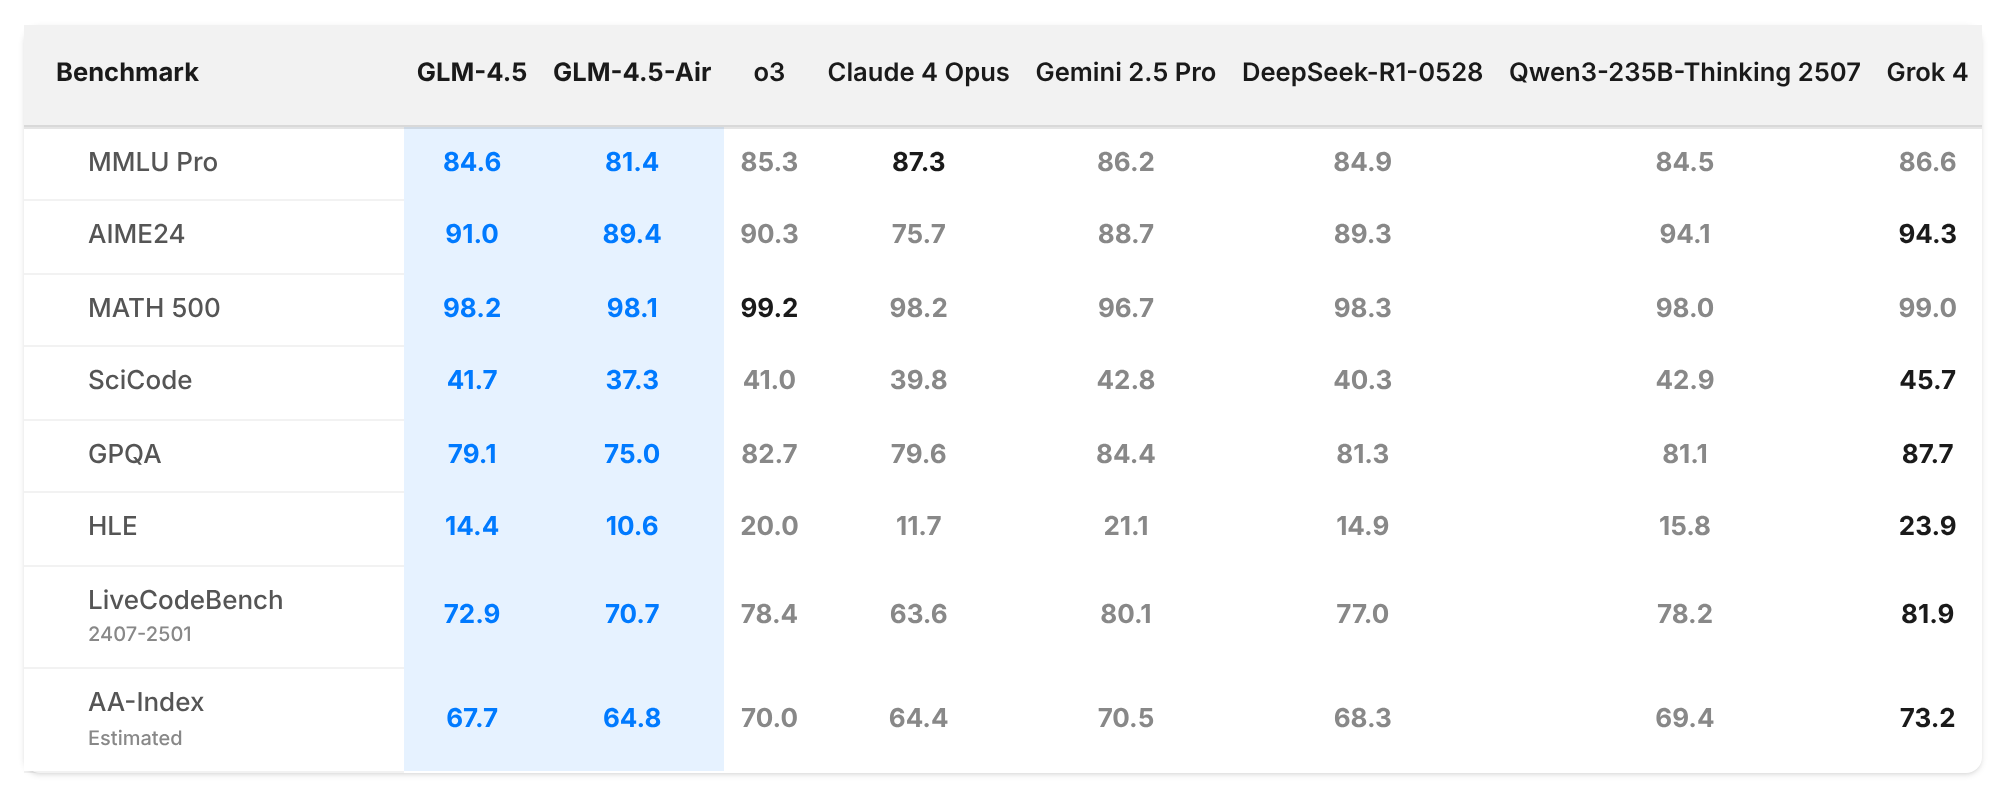
| GLM-4.528 Jul 2025 · Z.ai | 72.9% | GLM-4.5: Reasoning, Coding, and Agentic Abililtiesthinking mode; problems from Jul 2024 to Jan 2025Our capture | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| GLM-4.5-Air28 Jul 2025 · Z.ai | 70.7% | GLM-4.5: Reasoning, Coding, and Agentic Abililtiesthinking mode; problems from Jul 2024 to Jan 2025Our capture | |
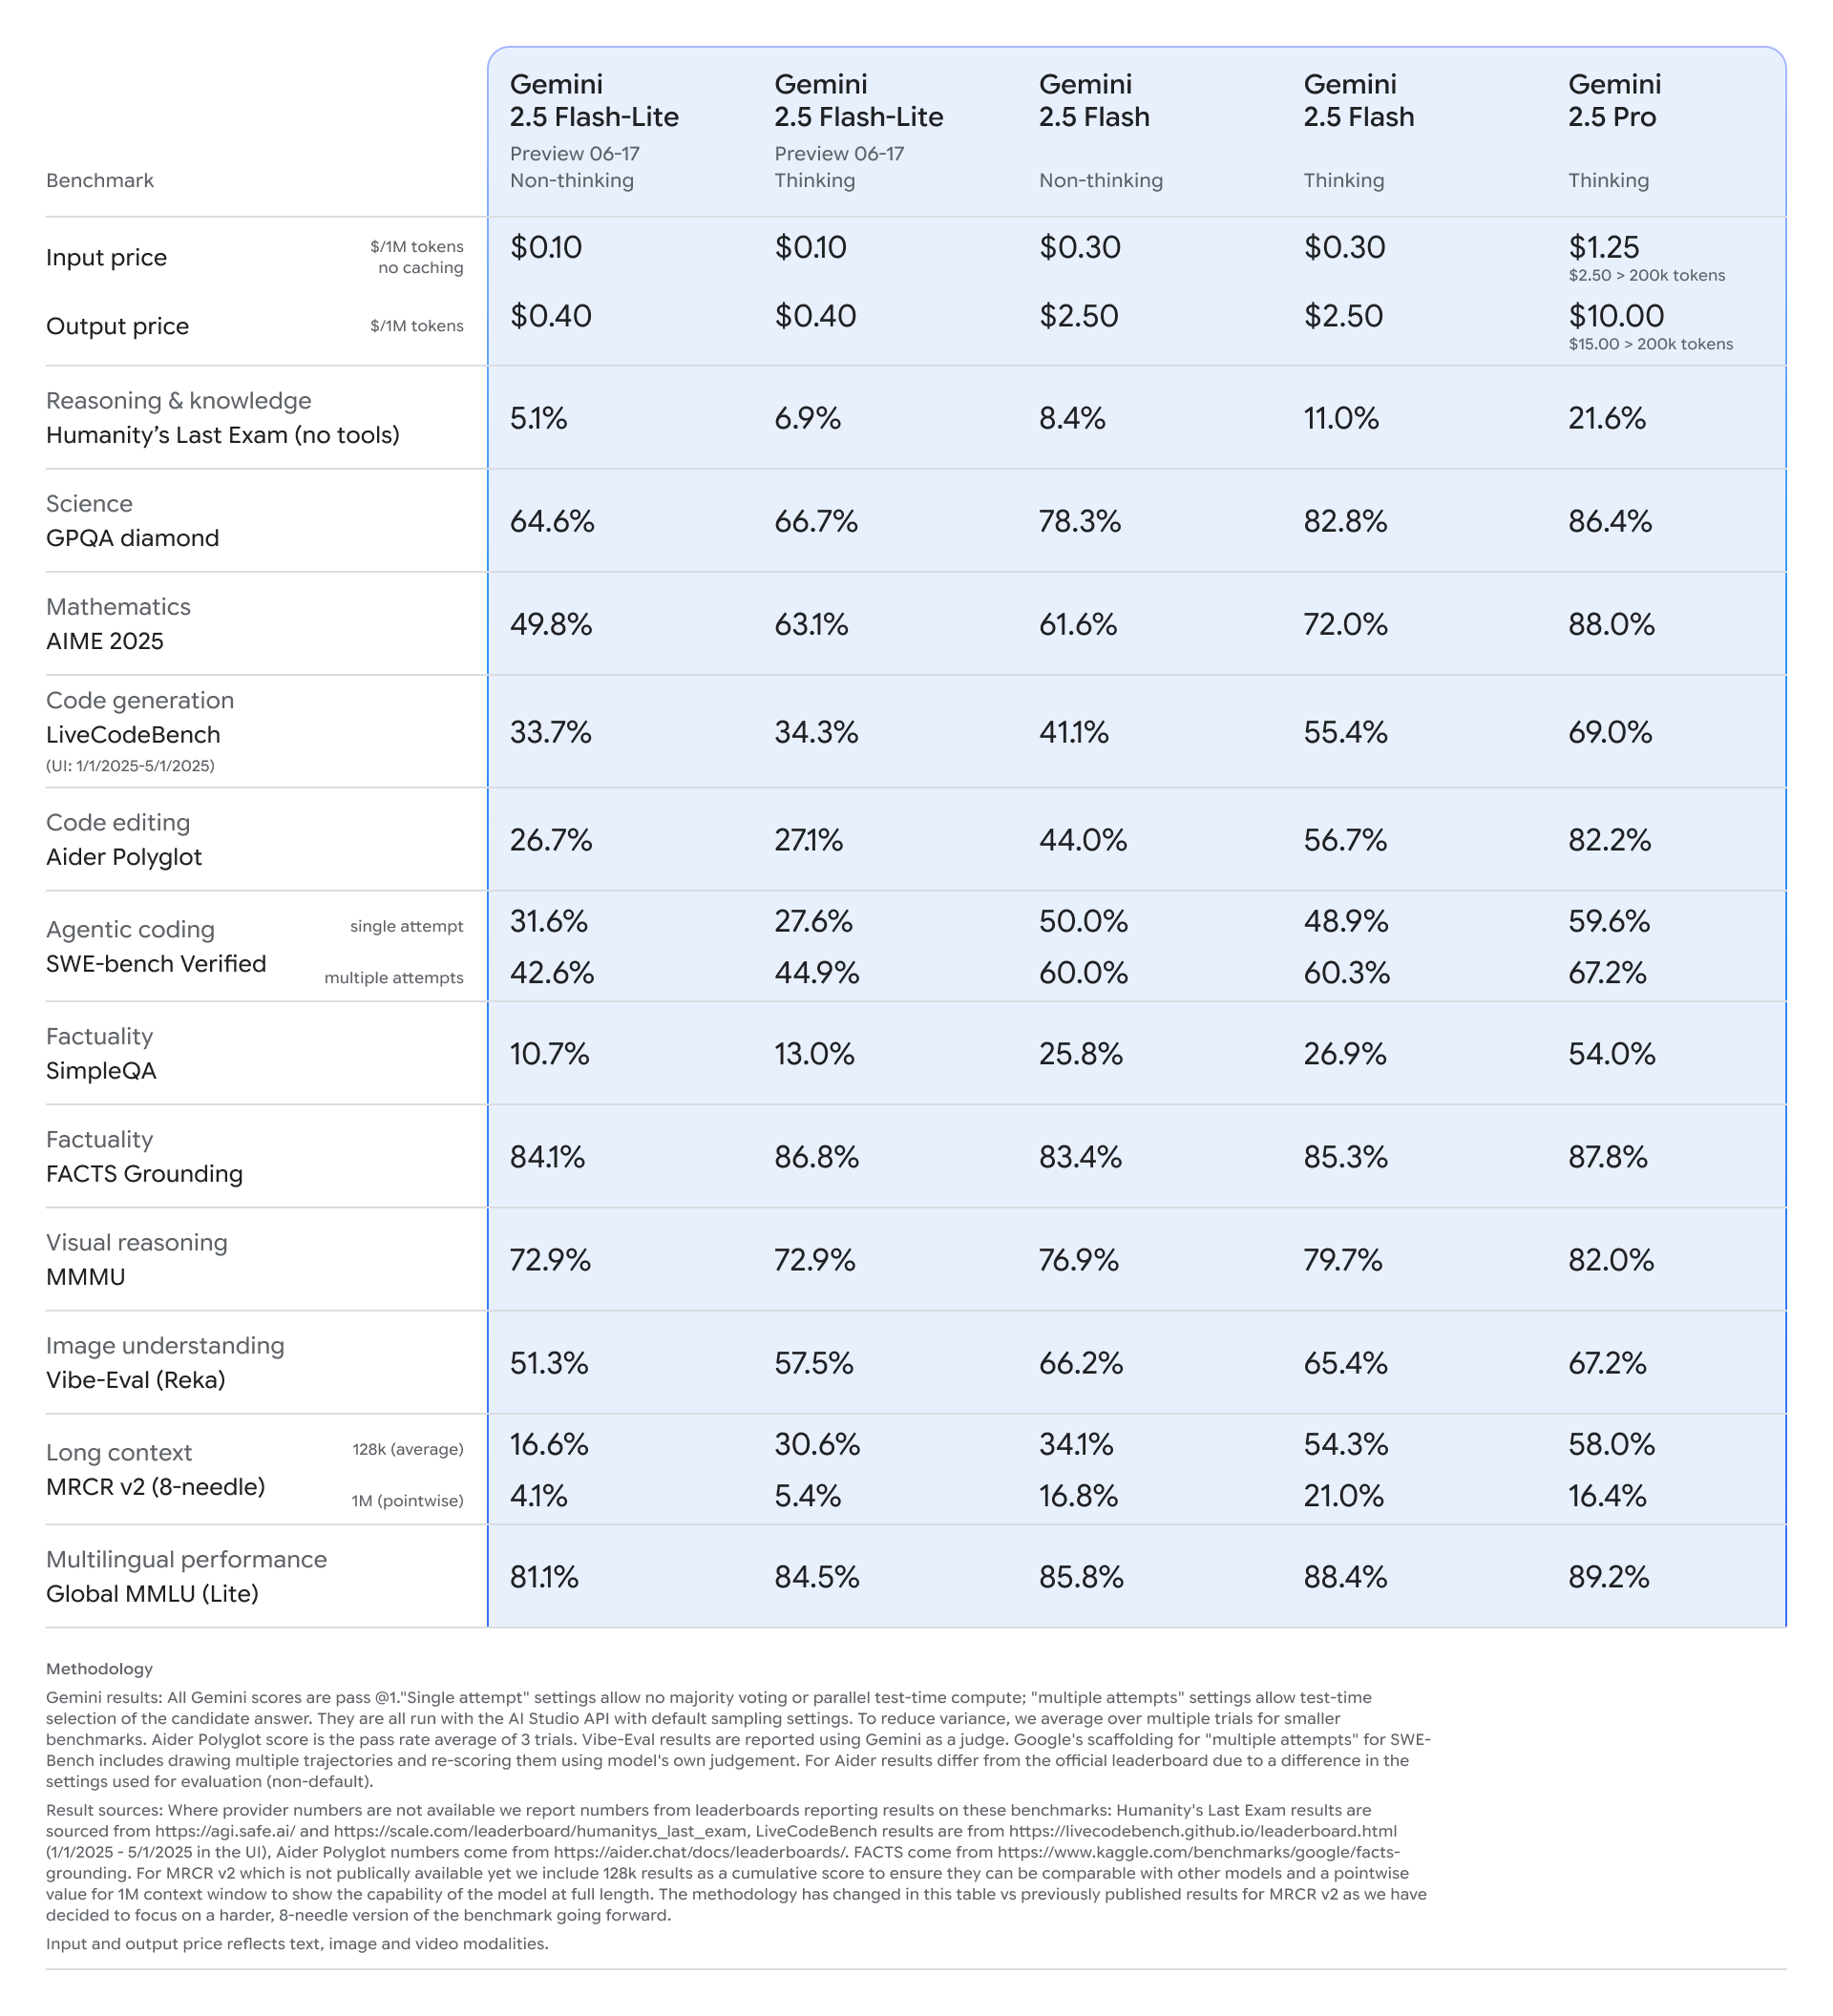
| Gemini 2.5 Flash-Lite17 Jun 2025 · Google | 34.3% | We’re expanding our Gemini 2.5 family of modelsthinking; pass@1; problems from 1/1/2025 to 5/1/2025Source image | CheckedA person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Gemini 2.5 Flash-Lite17 Jun 2025 · Google | 33.7% | We’re expanding our Gemini 2.5 family of modelsnon-thinking; pass@1; problems from 1/1/2025 to 5/1/2025; another report, not chartedSource image | CheckedA person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
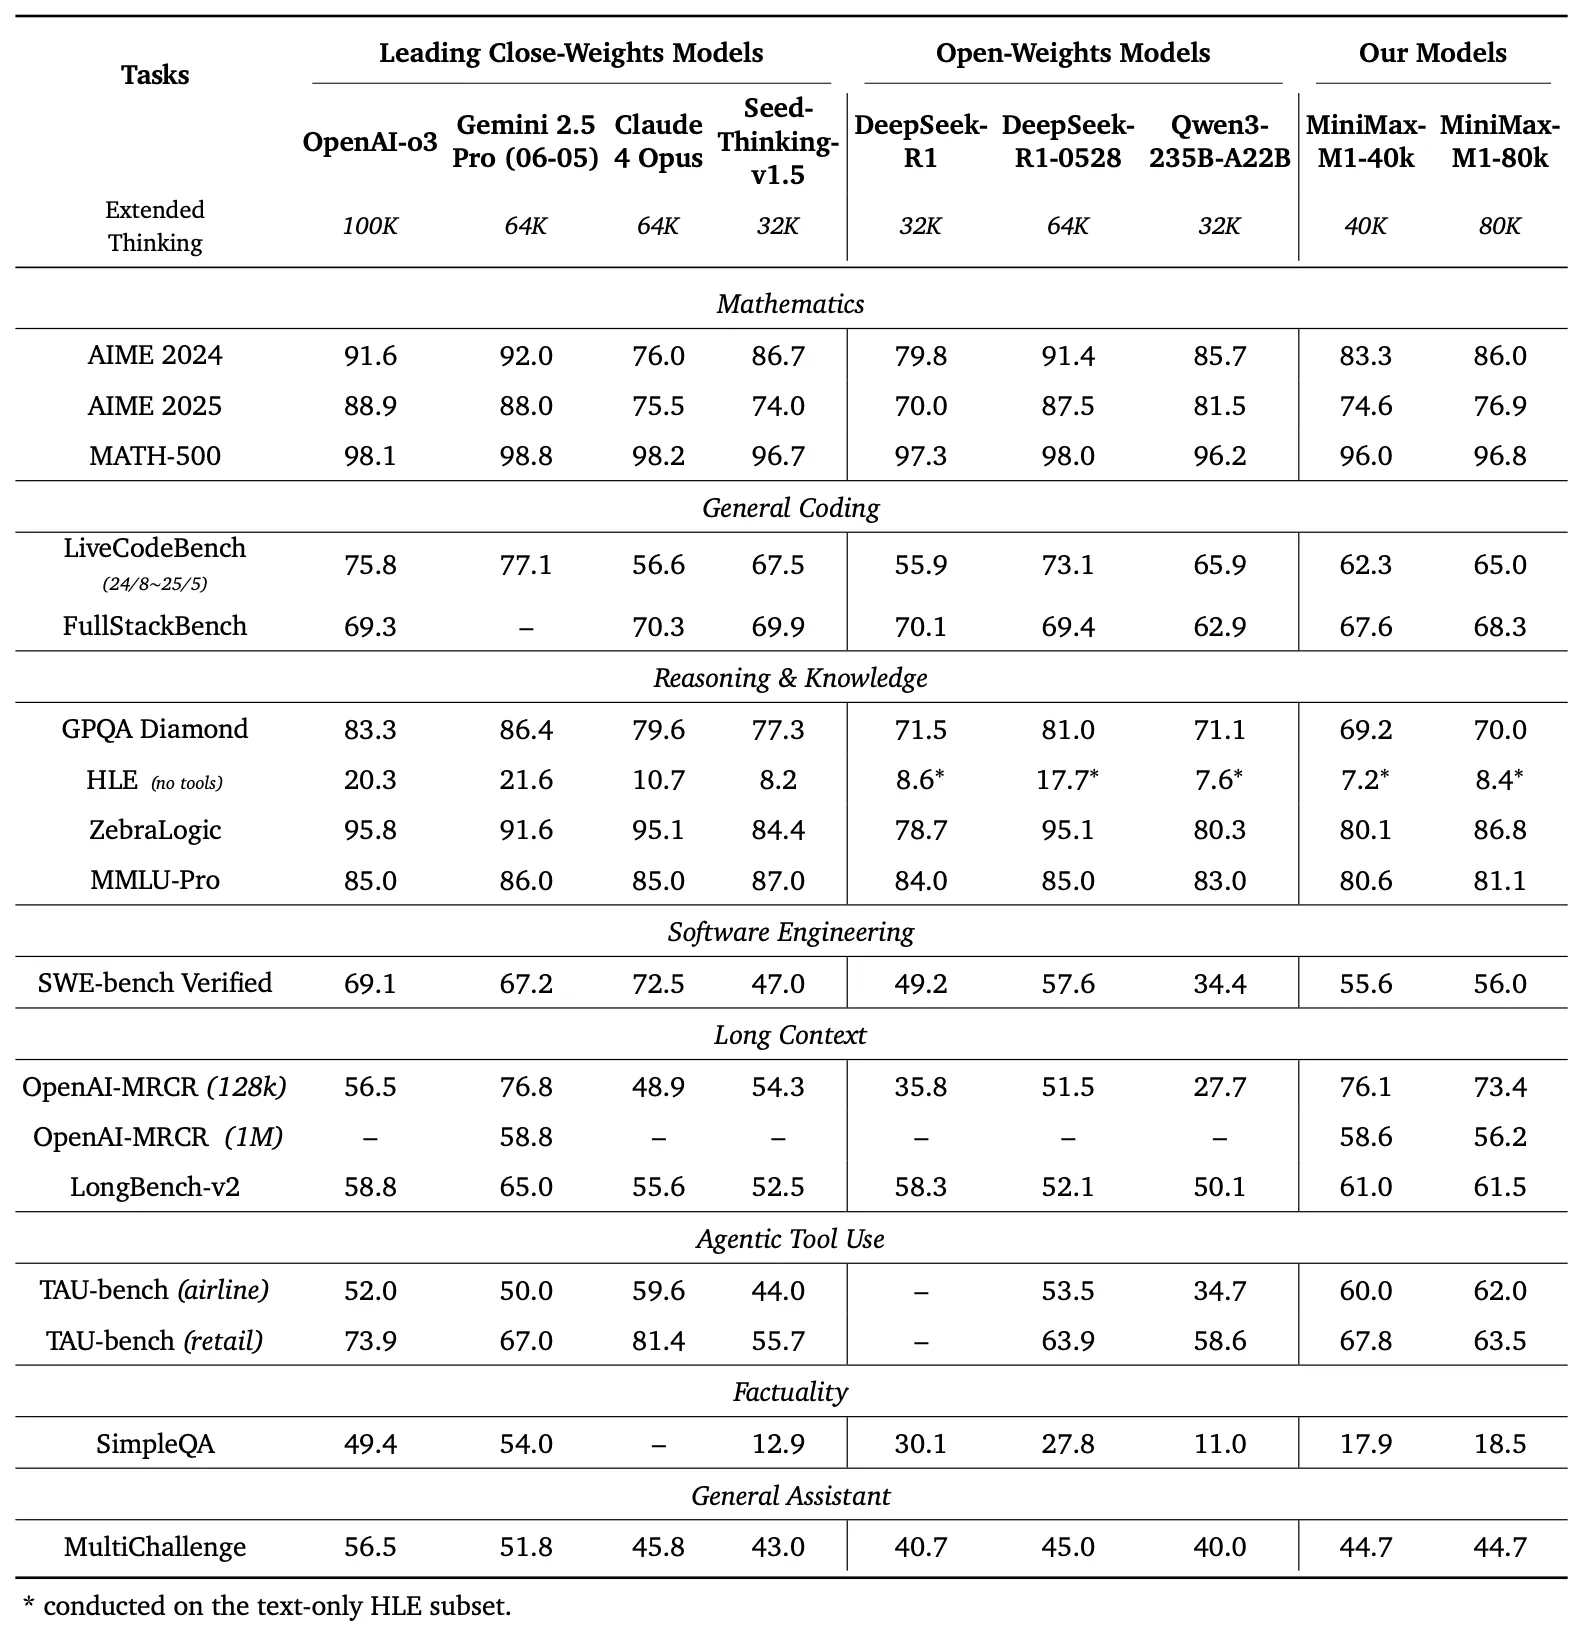
| MiniMax-M116 Jun 2025 · MiniMax | 65.0% | MiniMax-M1, the World's First Open-Source, Large-Scale, Hybrid-Attention Reasoning ModelMiniMax-M1-80k, 80K thinking budget; problems from Aug 2024 to May 2025Source image | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| MiniMax-M116 Jun 2025 · MiniMax | 62.3% | MiniMax-M1, the World's First Open-Source, Large-Scale, Hybrid-Attention Reasoning ModelMiniMax-M1-40k, 40K thinking budget; problems from Aug 2024 to May 2025; another report, not chartedSource image | |
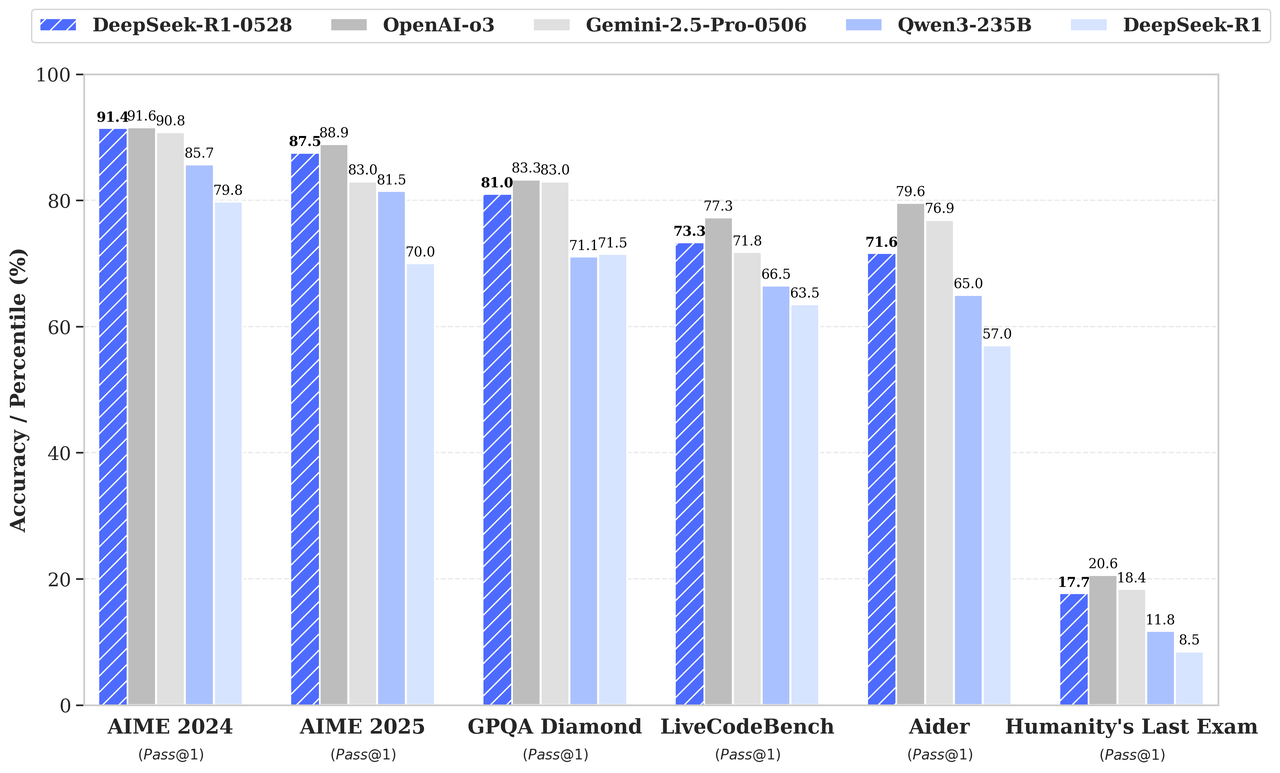
| DeepSeek-R1-052828 May 2025 · DeepSeek | 73.3% | DeepSeek-R1-0528 Releaseproblems from Aug 2024 to May 2025; averaged over 16 samplesSource image | |
| Gemini 2.5 Flash17 Apr 2025 · Google | 55.4% | We’re expanding our Gemini 2.5 family of modelsthinking; pass@1; problems from 1/1/2025 to 5/1/2025; reported laterSource image | CheckedA person checked this number against its source on 29 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Gemini 2.5 Flash17 Apr 2025 · Google | 41.1% | We’re expanding our Gemini 2.5 family of modelsnon-thinking; pass@1; problems from 1/1/2025 to 5/1/2025; reported later; another report, not chartedSource image | CheckedA person checked this number against its source on 29 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Gemini 2.5 Flash17 Apr 2025 · Google | 59.3% | Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next Generation Agentic Capabilitiespass@1; single attempt; problems from 1/1/2025 to 5/1/2025; reported later; another report, not charted | CheckedA person checked this number against its source on 29 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
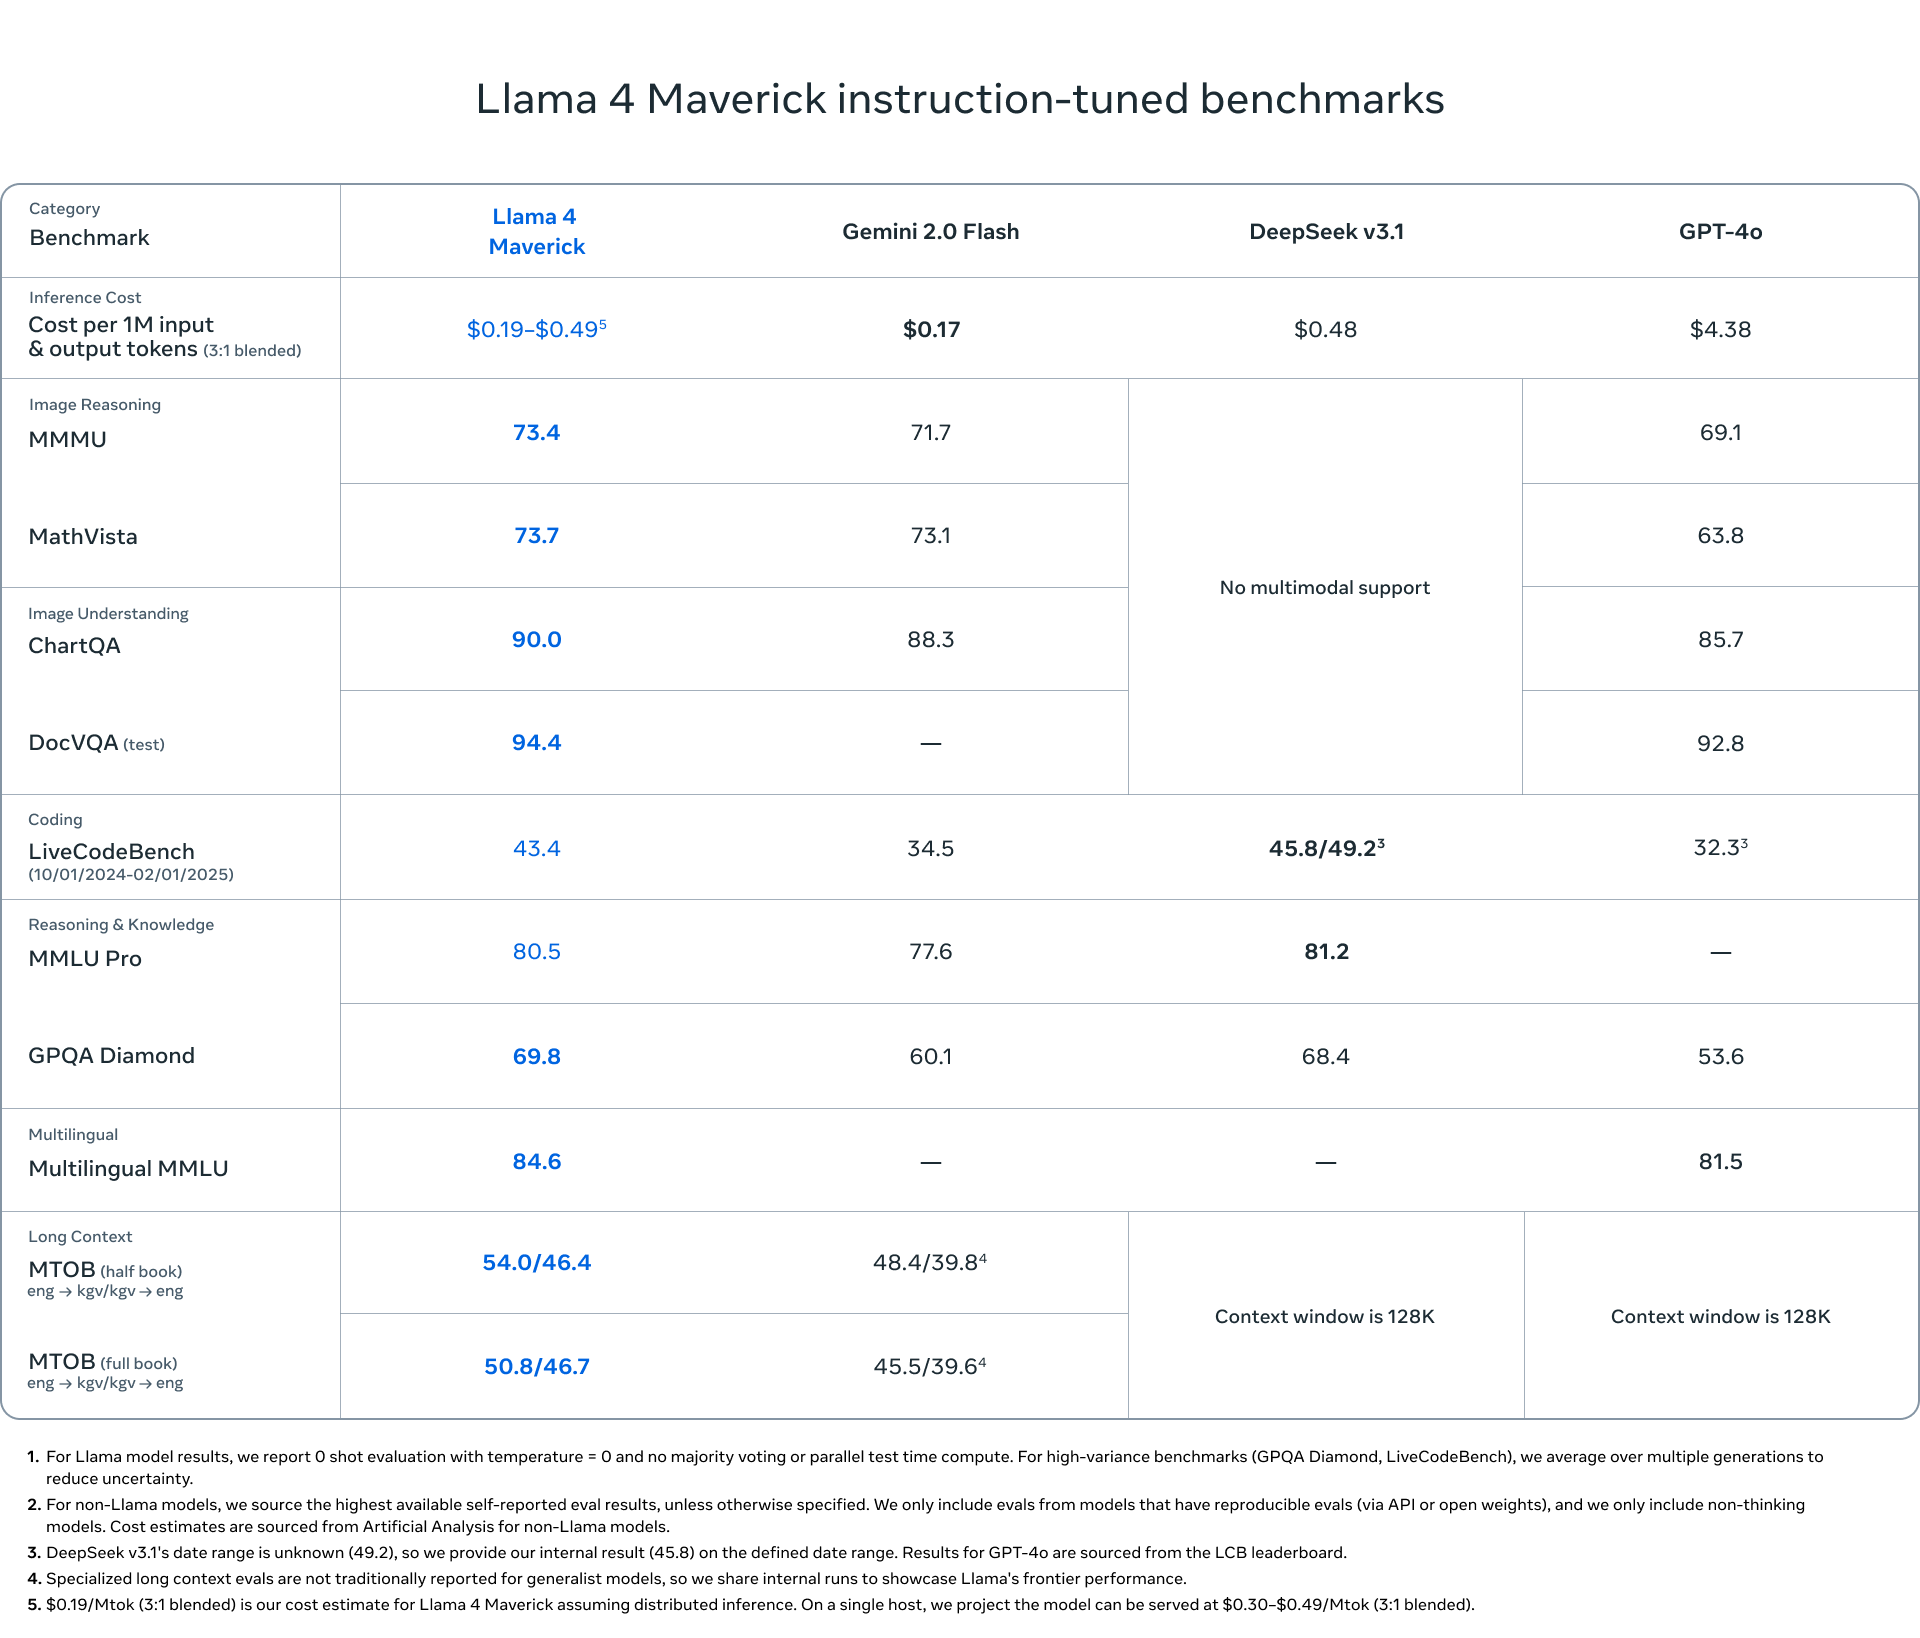
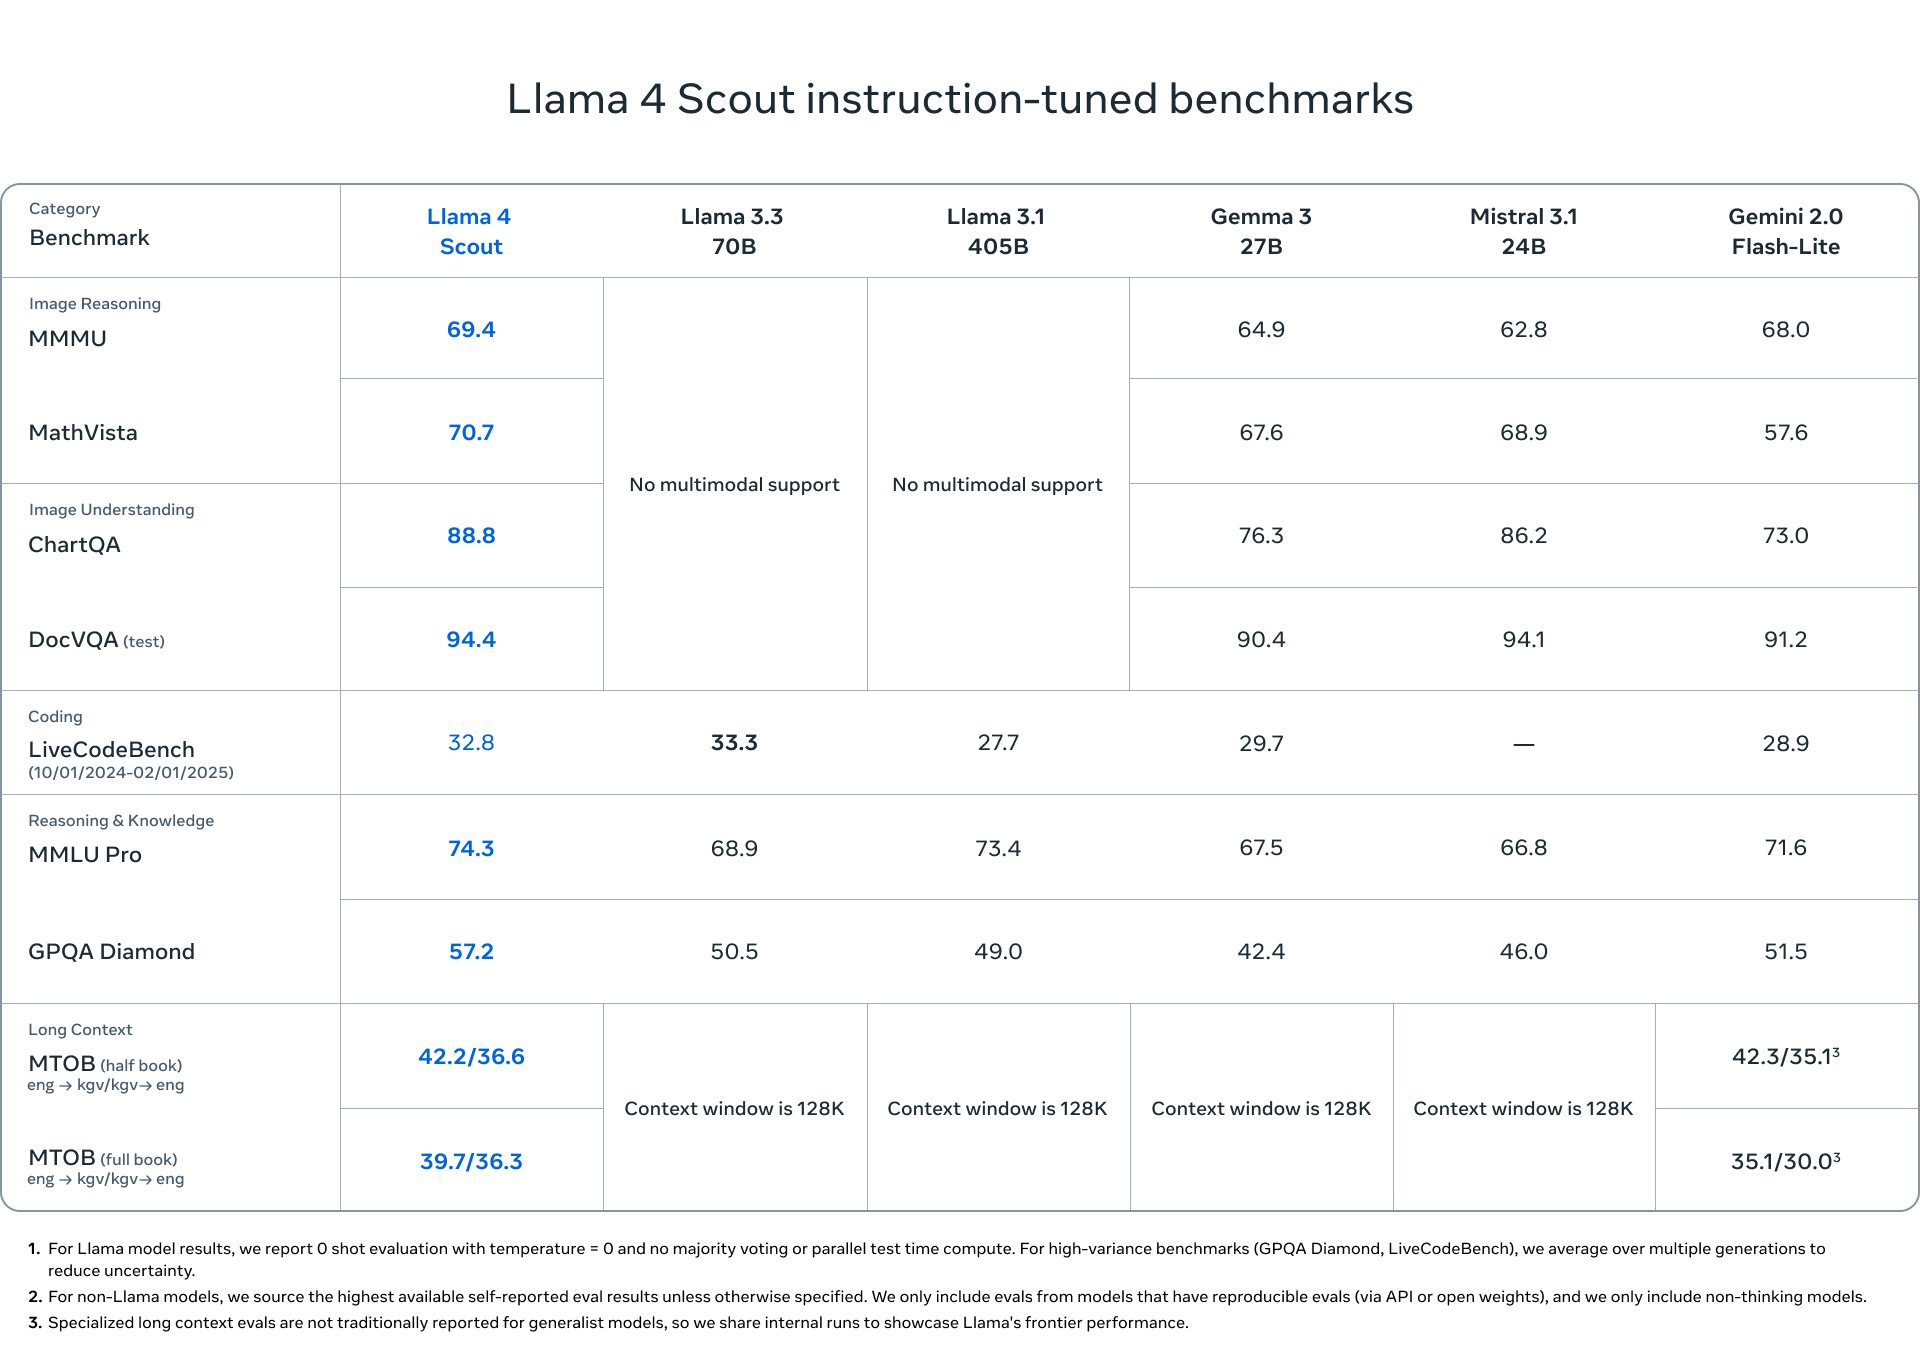
| Llama 4 Maverick5 Apr 2025 · Meta | 43.4% | The Llama 4 herd: The beginning of a new era of natively multimodal AI innovationproblems from Oct 2024 to Feb 2025; 0-shot; averaged over multiple generationsSource image | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Llama 4 Scout5 Apr 2025 · Meta | 32.8% | The Llama 4 herd: The beginning of a new era of natively multimodal AI innovationproblems from Oct 2024 to Feb 2025; 0-shot; averaged over multiple generationsSource image | |
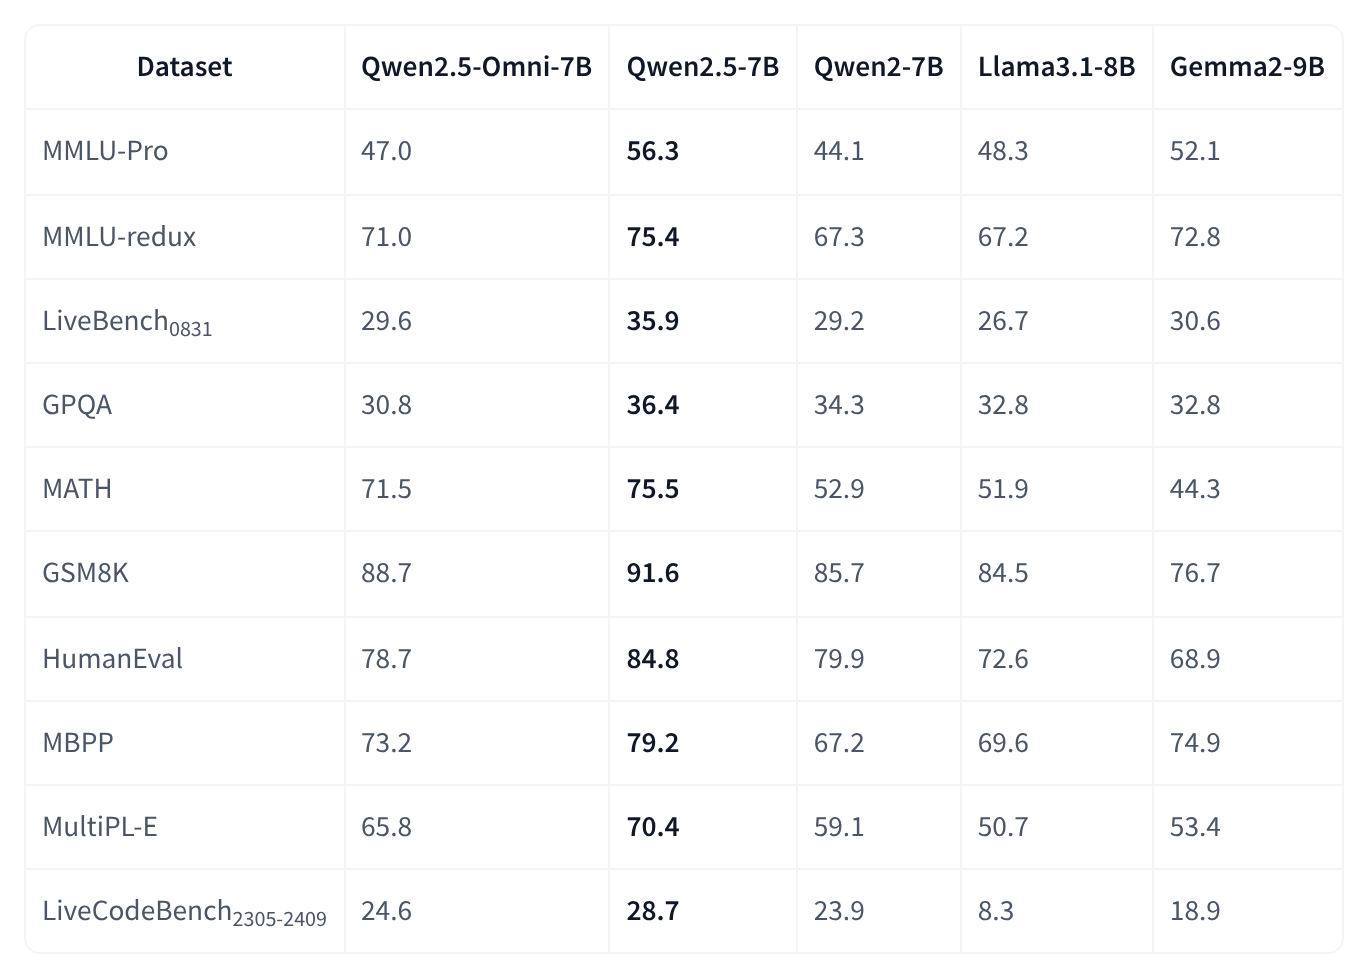
| Qwen2.5-Omni27 Mar 2025 · Alibaba | 24.6% | Qwen/Qwen2.5-Omni-7B model card (launch-day revision)problems from May 2023 to Sep 2024Our capture | CheckedA person checked this number against its source on 28 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Gemini 2.5 Pro25 Mar 2025 · Google | 69.0% | We’re expanding our Gemini 2.5 family of modelsthinking; pass@1; problems from 1/1/2025 to 5/1/2025; reported laterSource image | CorroboratedThe same number is printed in 1 other lab document: 1 |
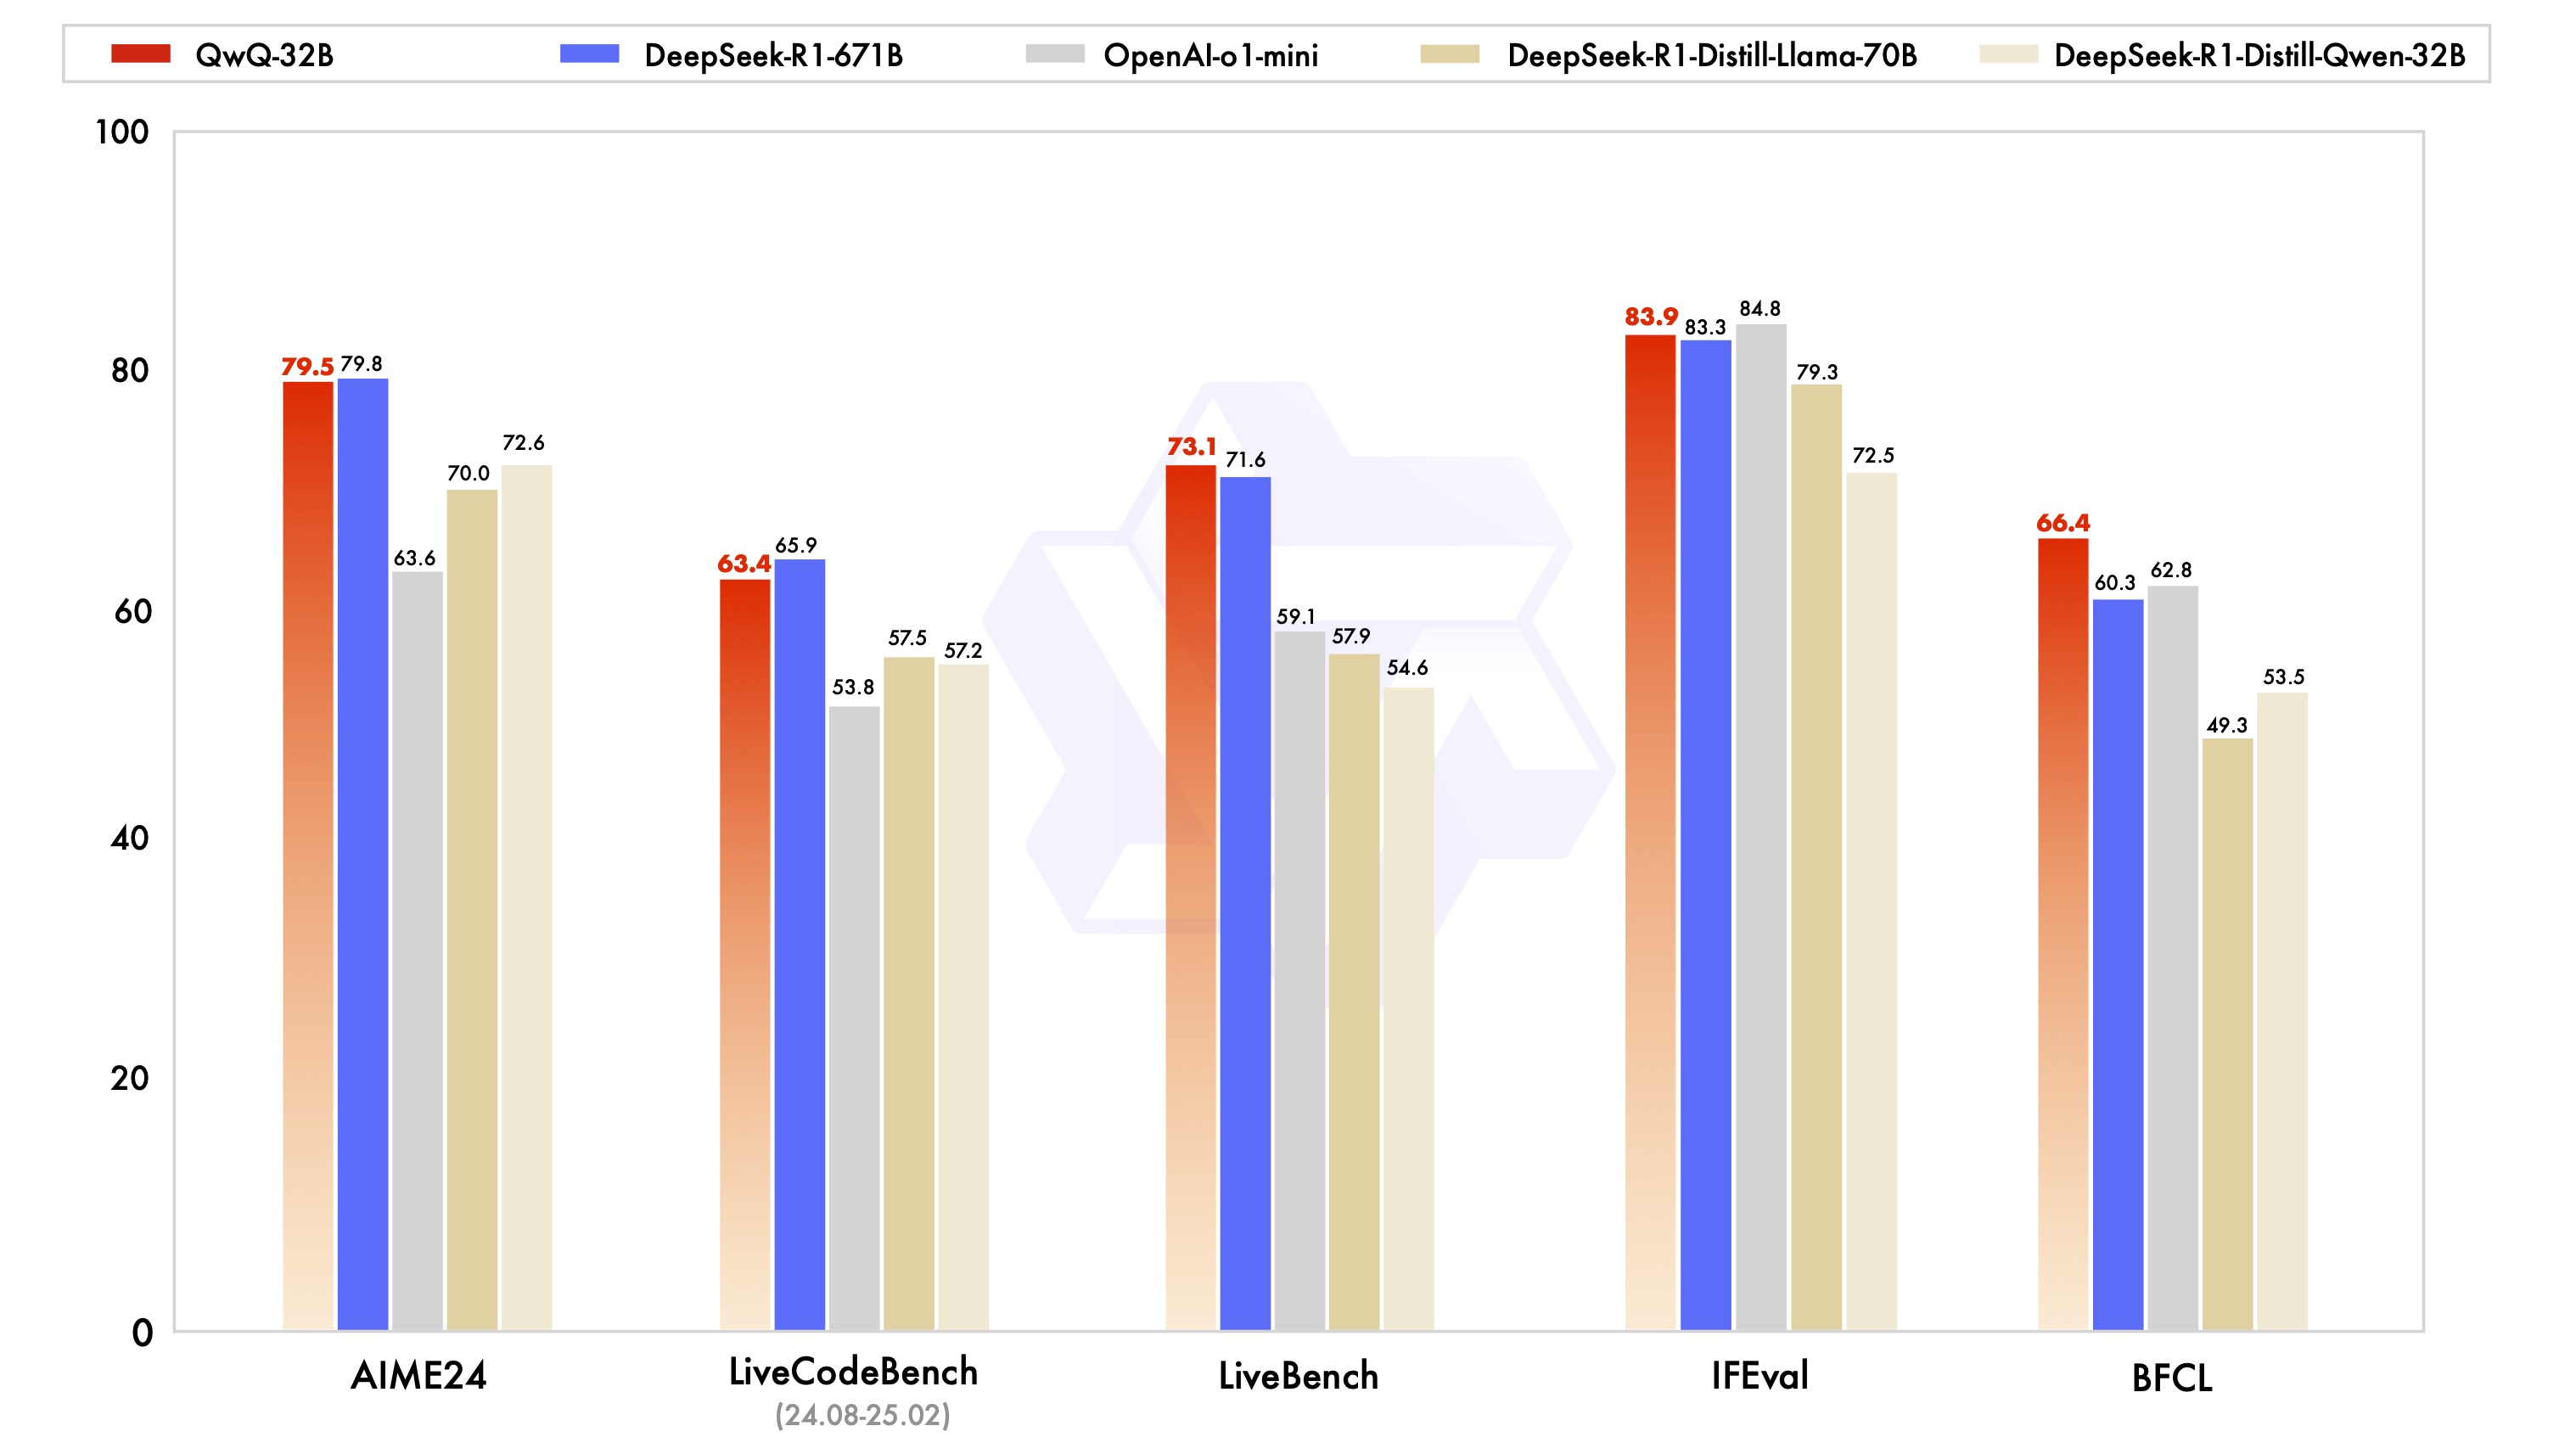
| QwQ-32B6 Mar 2025 · Alibaba | 63.4% | QwQ-32B: Embracing the Power of Reinforcement Learningproblems from Aug 2024 to Feb 2025Source image | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
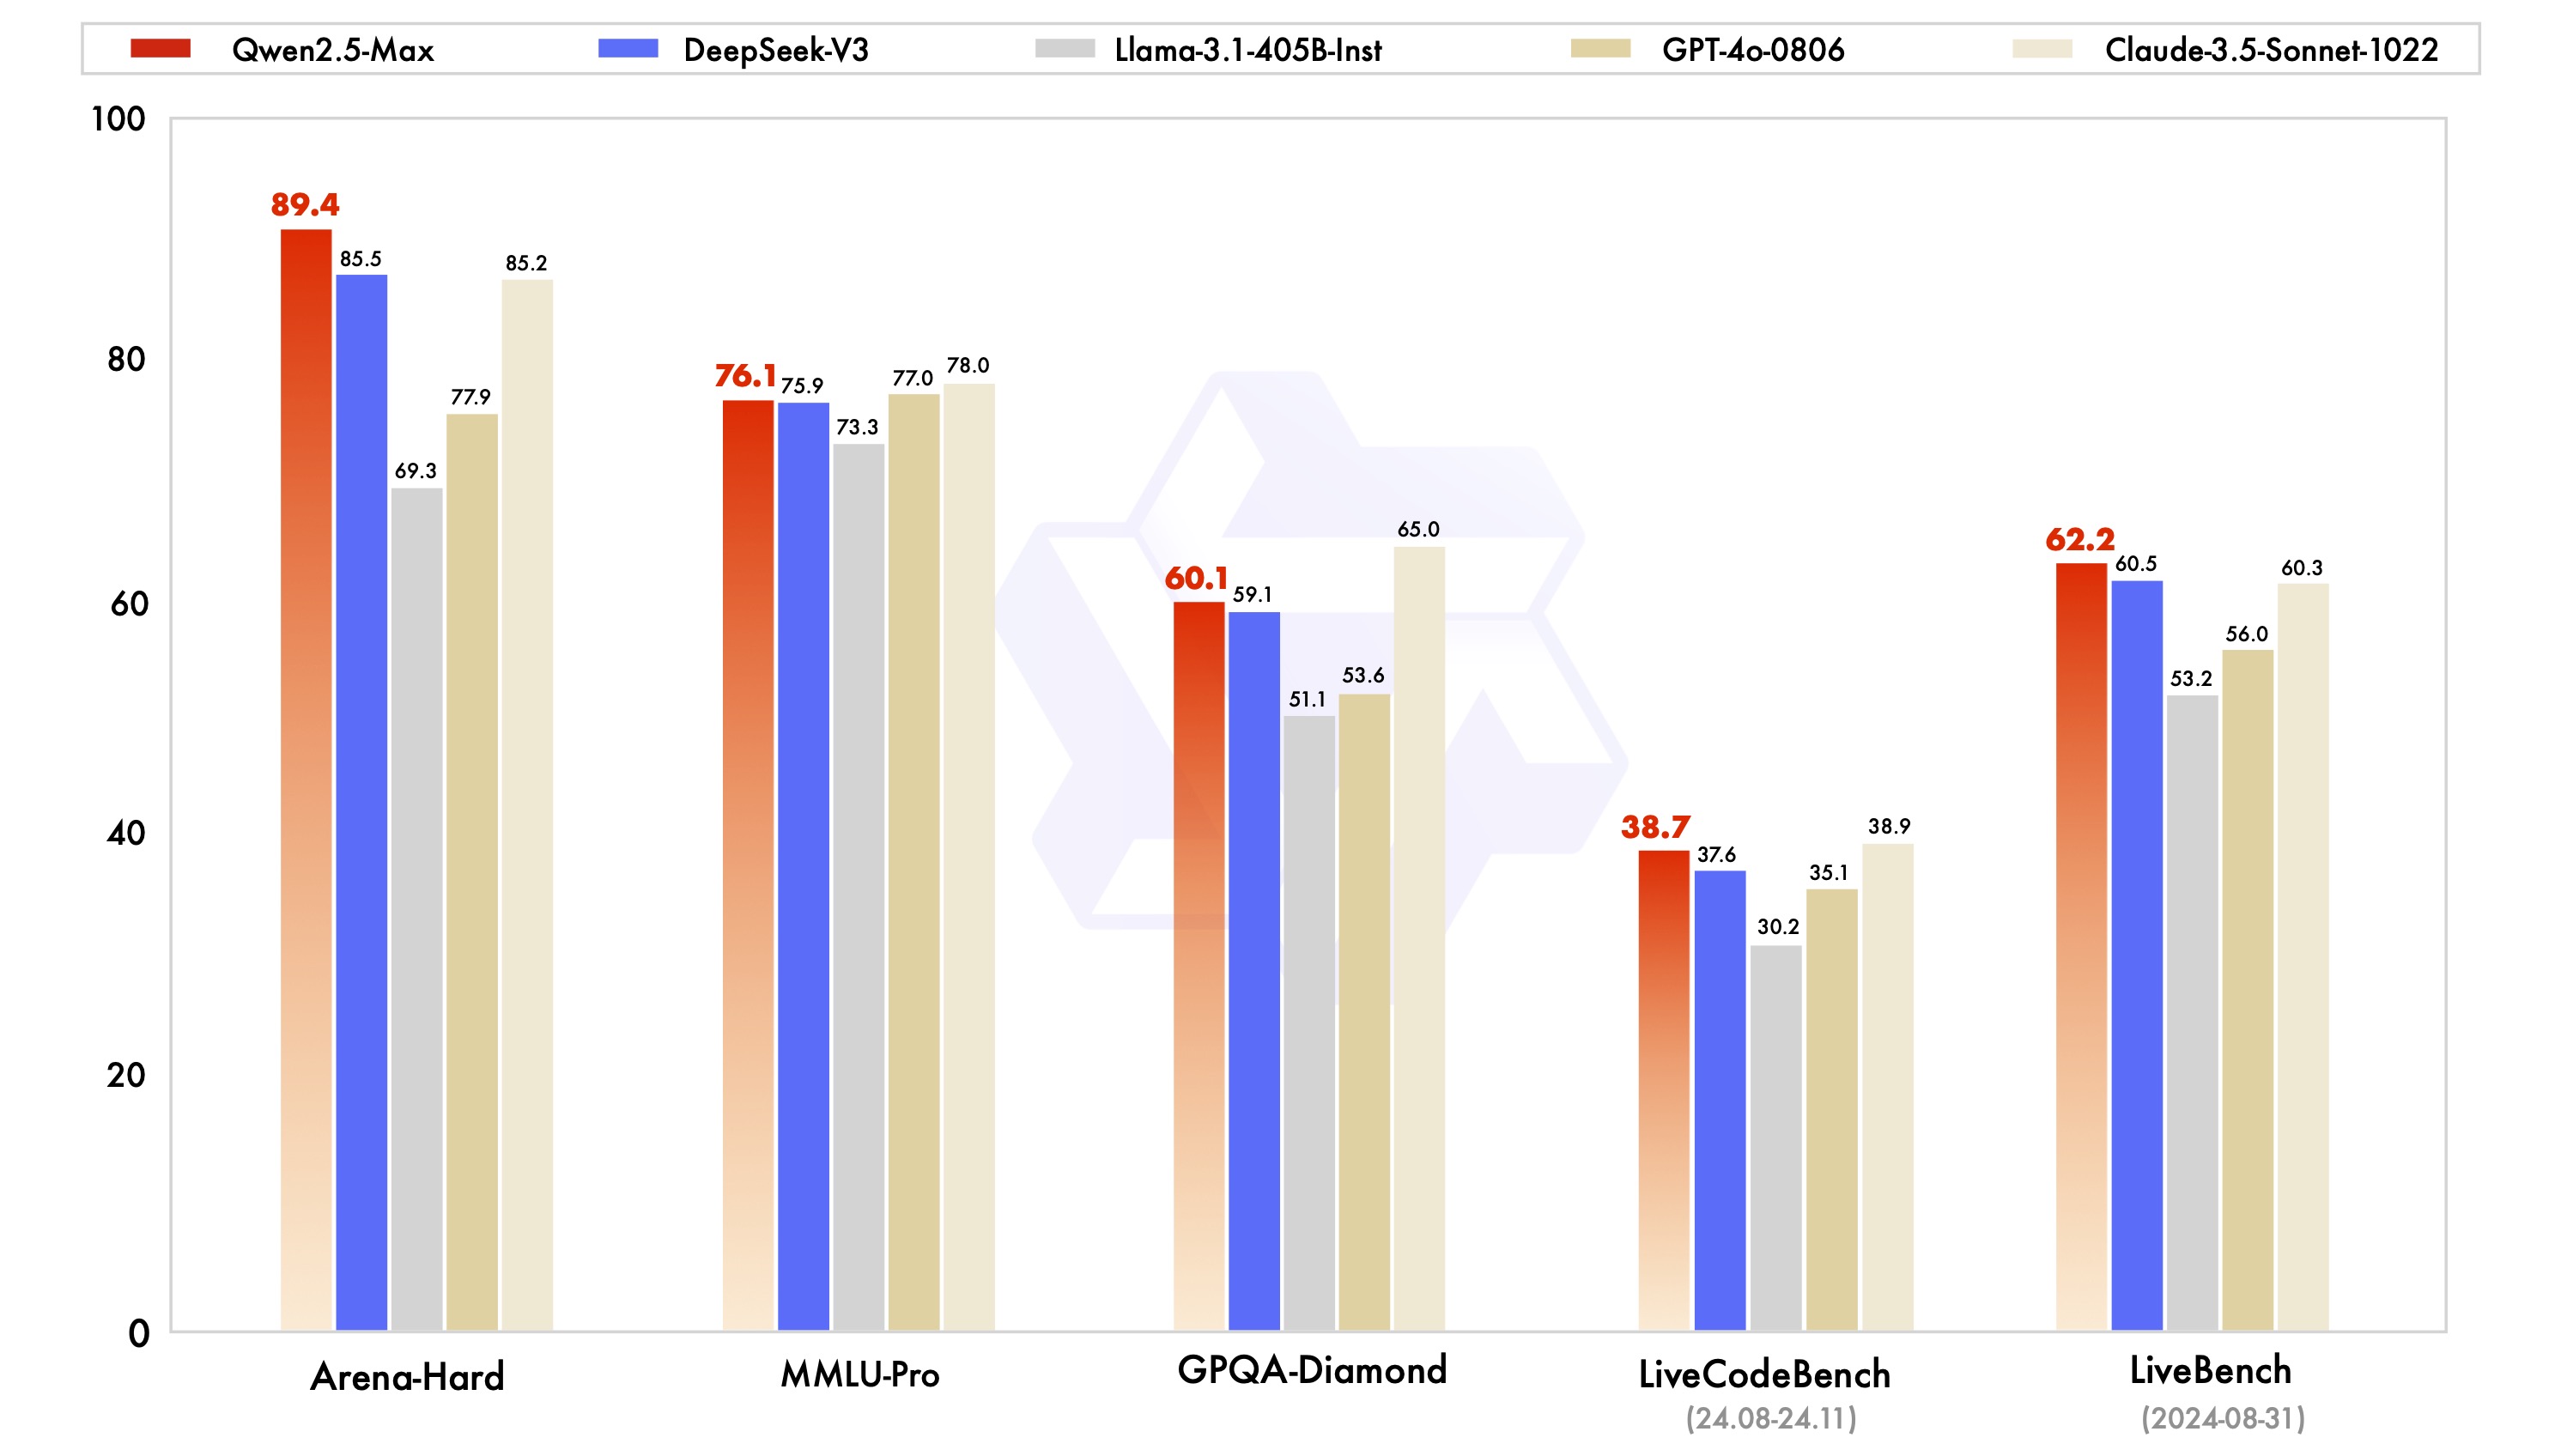
| Qwen2.5-Max28 Jan 2025 · Alibaba | 38.7% | Qwen2.5-Max: Exploring the Intelligence of Large-scale MoE Modelinstruct model; problems from Aug to Nov 2024Source image | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
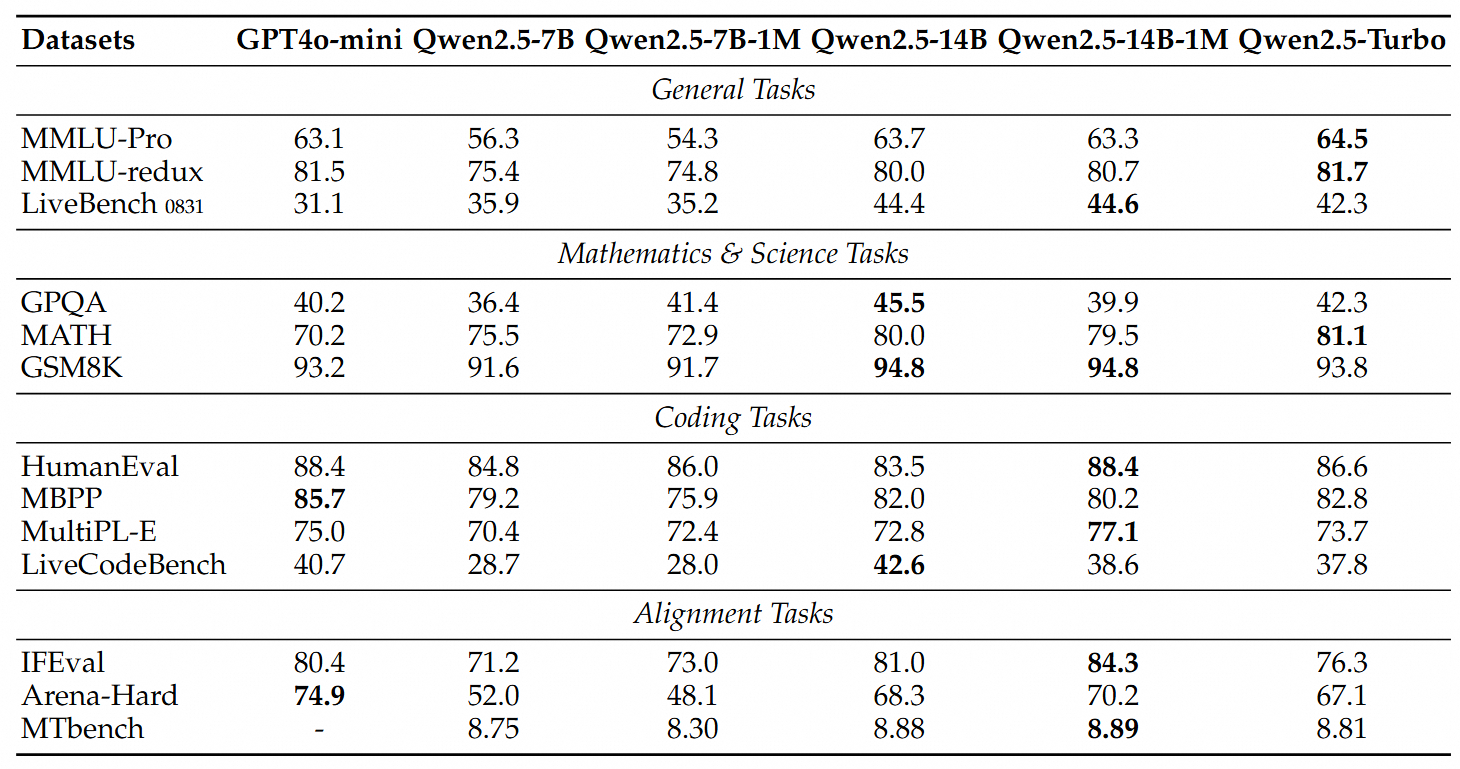
| Qwen2.5-14B-Instruct-1M27 Jan 2025 · Alibaba | 38.6% | Qwen2.5-1M: Deploy Your Own Qwen with Context Length up to 1M Tokensproblems from May 2023 to Sep 2024Source image | CheckedA person checked this number against its source on 28 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| DeepSeek-R120 Jan 2025 · DeepSeek | 65.9% | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learningproblems from Aug 2024 to Jan 2025; chain-of-thought; 32K output limit | CorroboratedThe same number is printed in 1 other lab document: 1 |
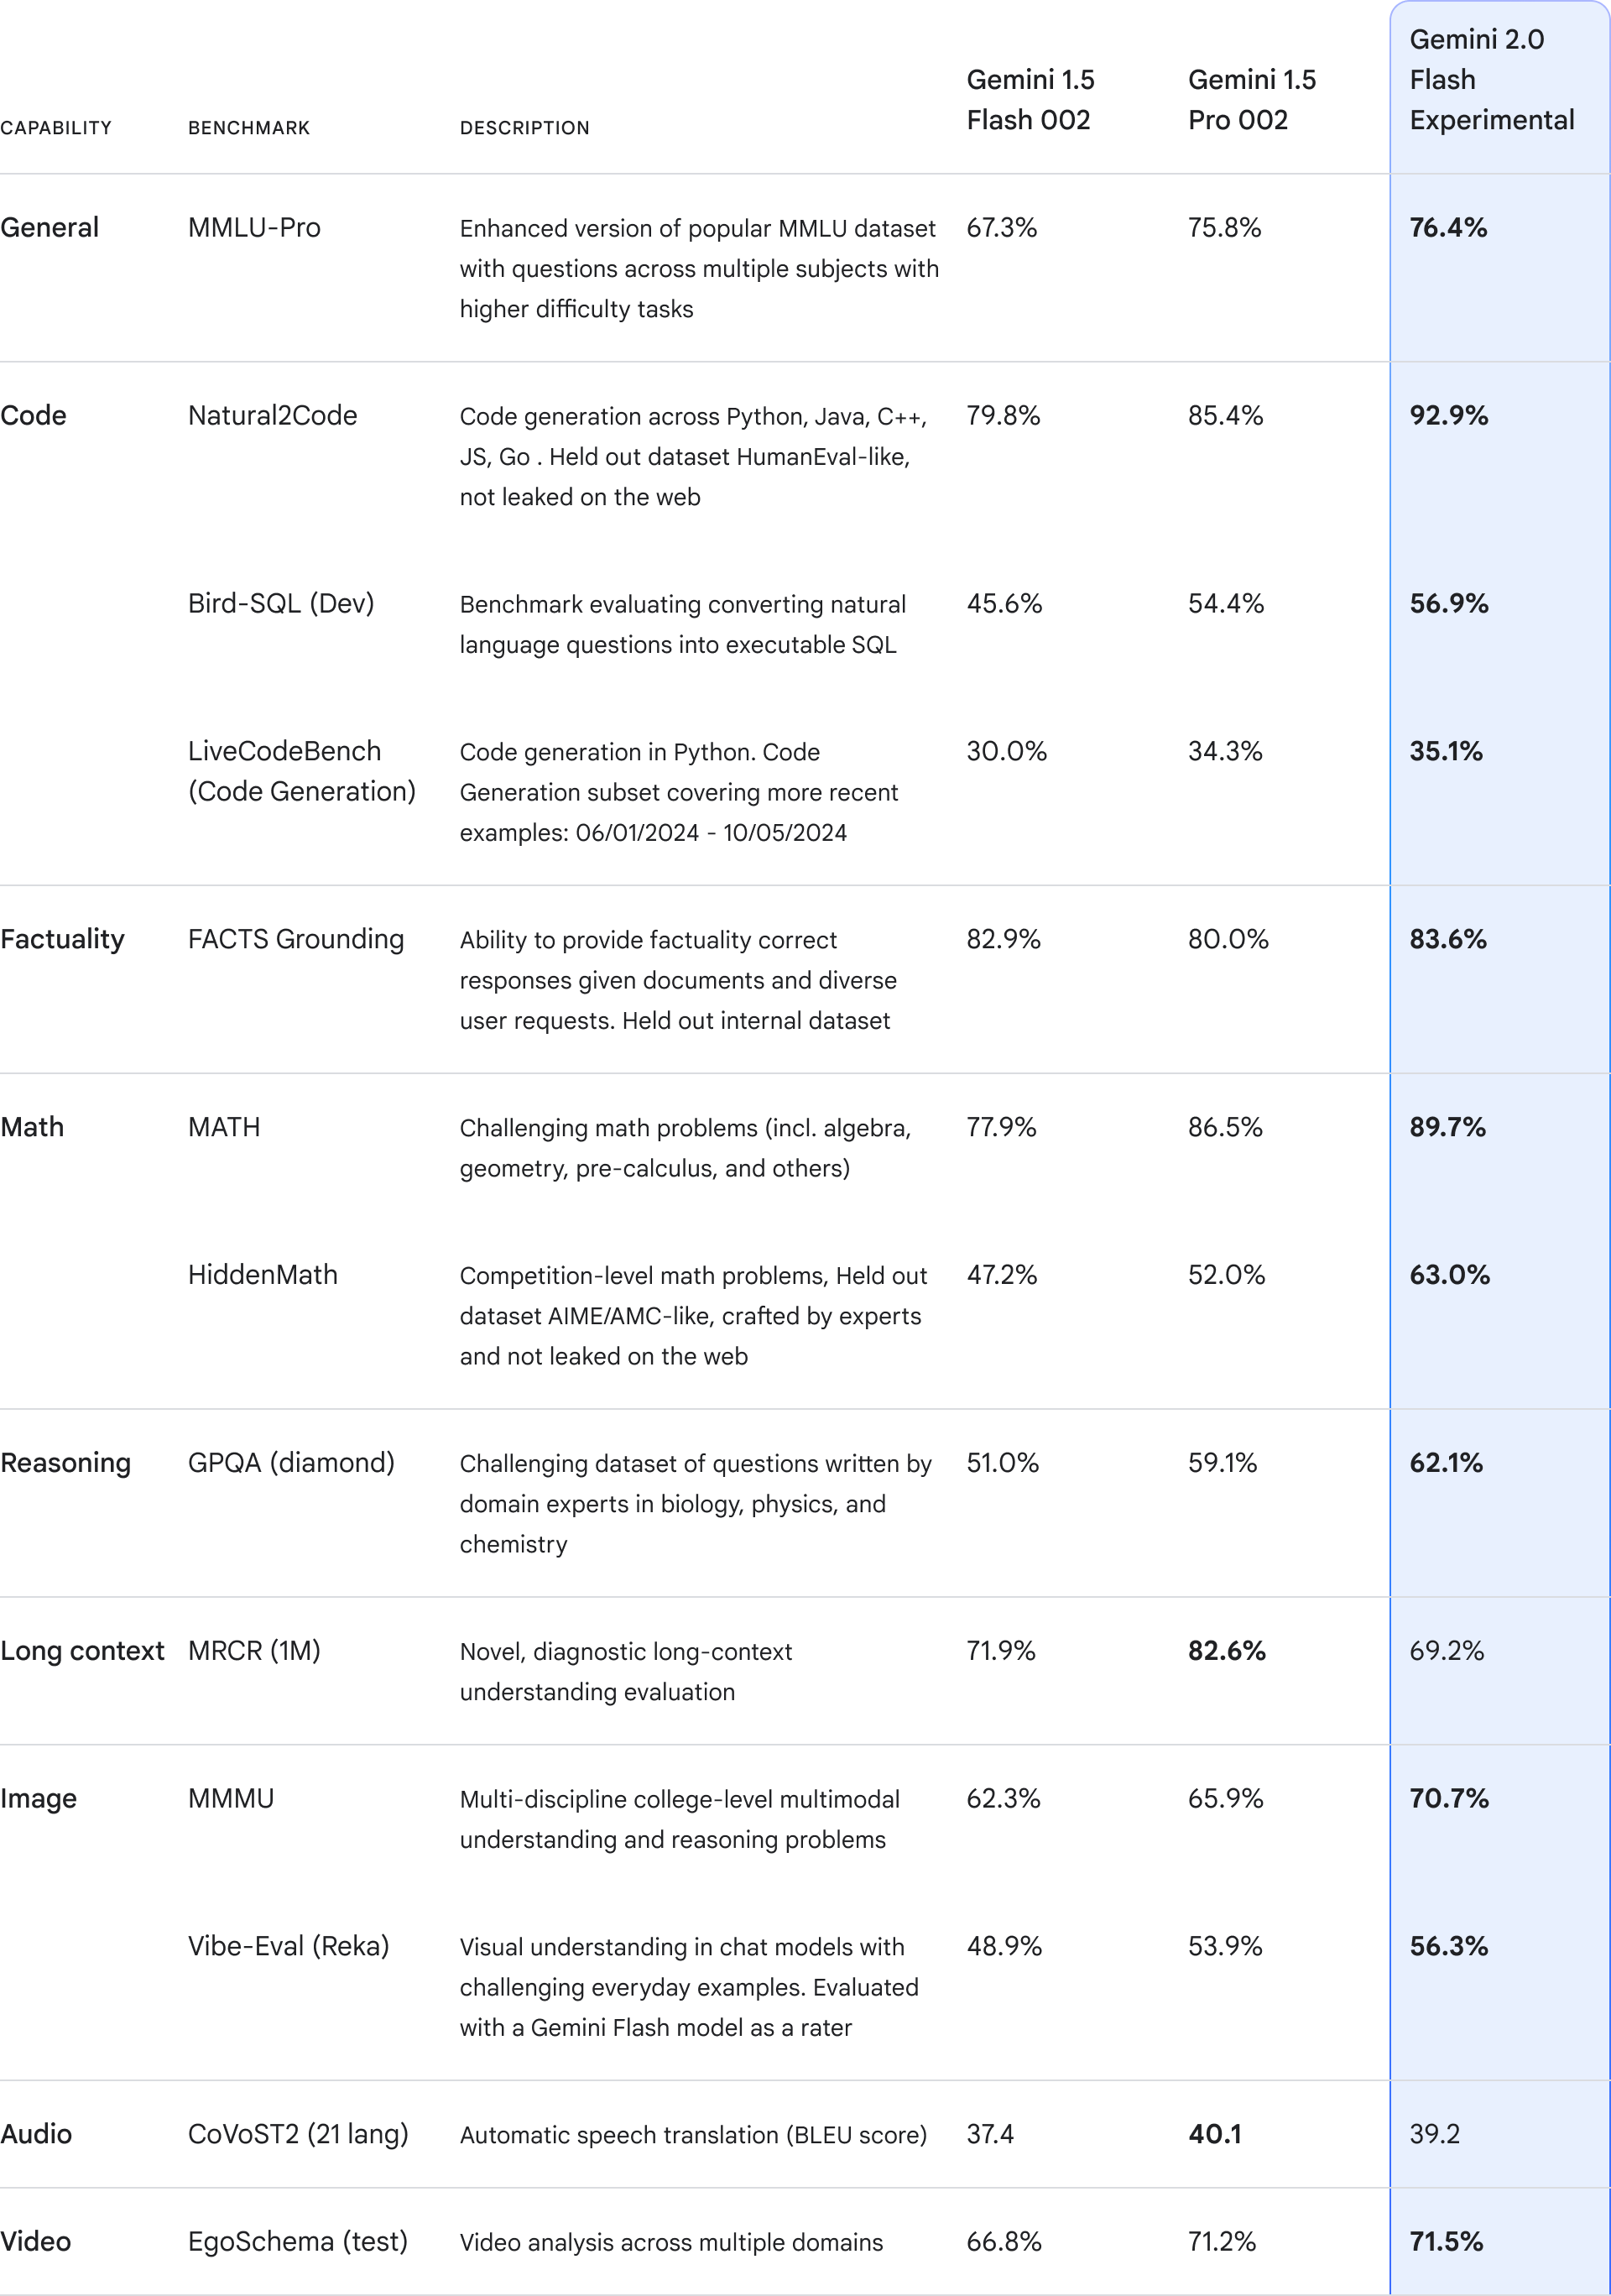
| Gemini 2.0 Flash11 Dec 2024 · Google | 35.1% | Introducing Gemini 2.0: our new AI model for the agentic eraexperimental version; code generation subset; problems from 06/01/2024 to 10/05/2024Source image | CheckedA person checked this number against its source on 29 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Llama 3.1 405B23 Jul 2024 · Meta | 27.7% | The Llama 4 herd: The beginning of a new era of natively multimodal AI innovationproblems from Oct 2024 to Feb 2025; 0-shot; averaged over multiple generations; reported laterSource image | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |