AIME 2025
- OpenAI
- Anthropic
- DeepSeek
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| GPT-5.211 Dec 2025 · OpenAI | 100.0% | Introducing GPT-5.2Row label prints '(no tools)'. The same value is printed again in the detailed math/science table (row 'AIME 2025 (no tools)', column 'GPT-5.2 Thinking'; GPT-5.2 Pro also 100.0% there). The fetched page text was truncated, so footnotes without a % sign are not visible in the extract. | Yes |
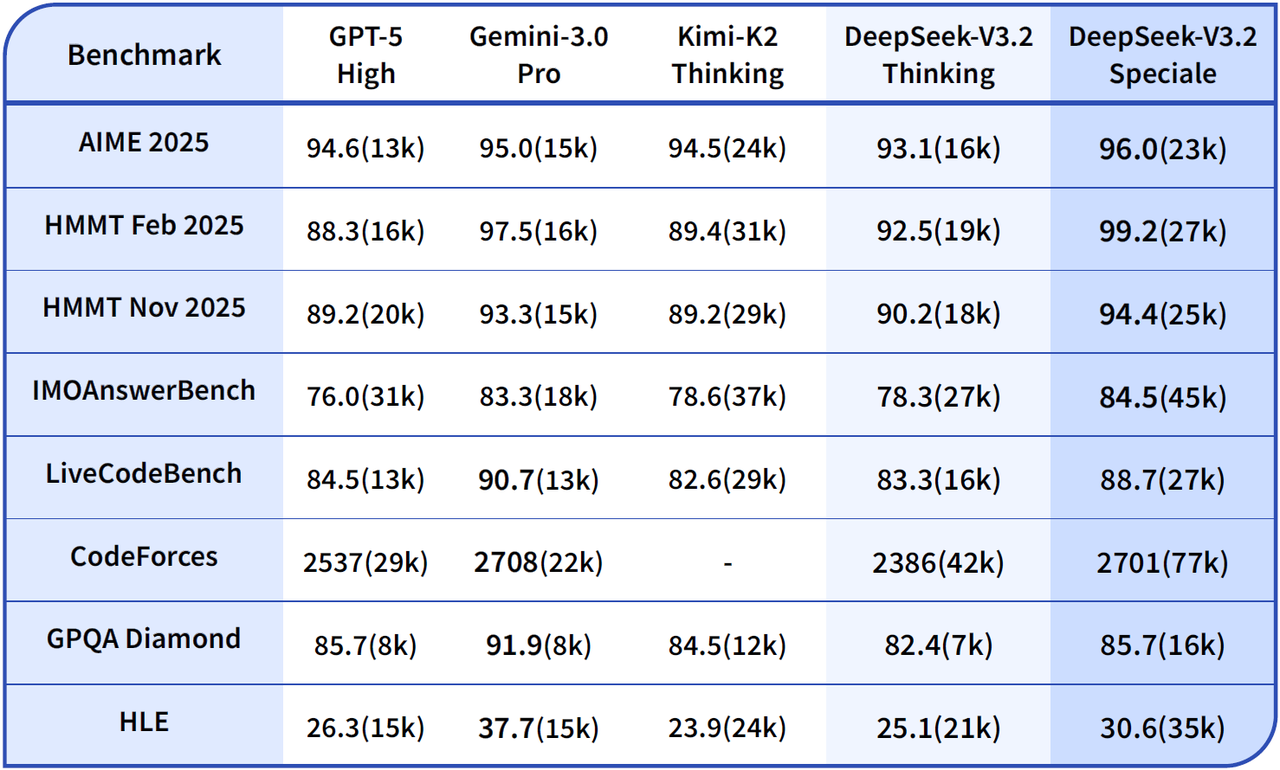
| DeepSeek-V3.21 Dec 2025 · DeepSeek | 93.1% | DeepSeek-V3.2 ReleaseCell prints score with output tokens in parentheses (16k = tokens); score 93.1. No tools printed. The Speciale column (96.0) is a different model. Cell prints "93.1(16k)": 16k is the output token count.Source image | Yes |
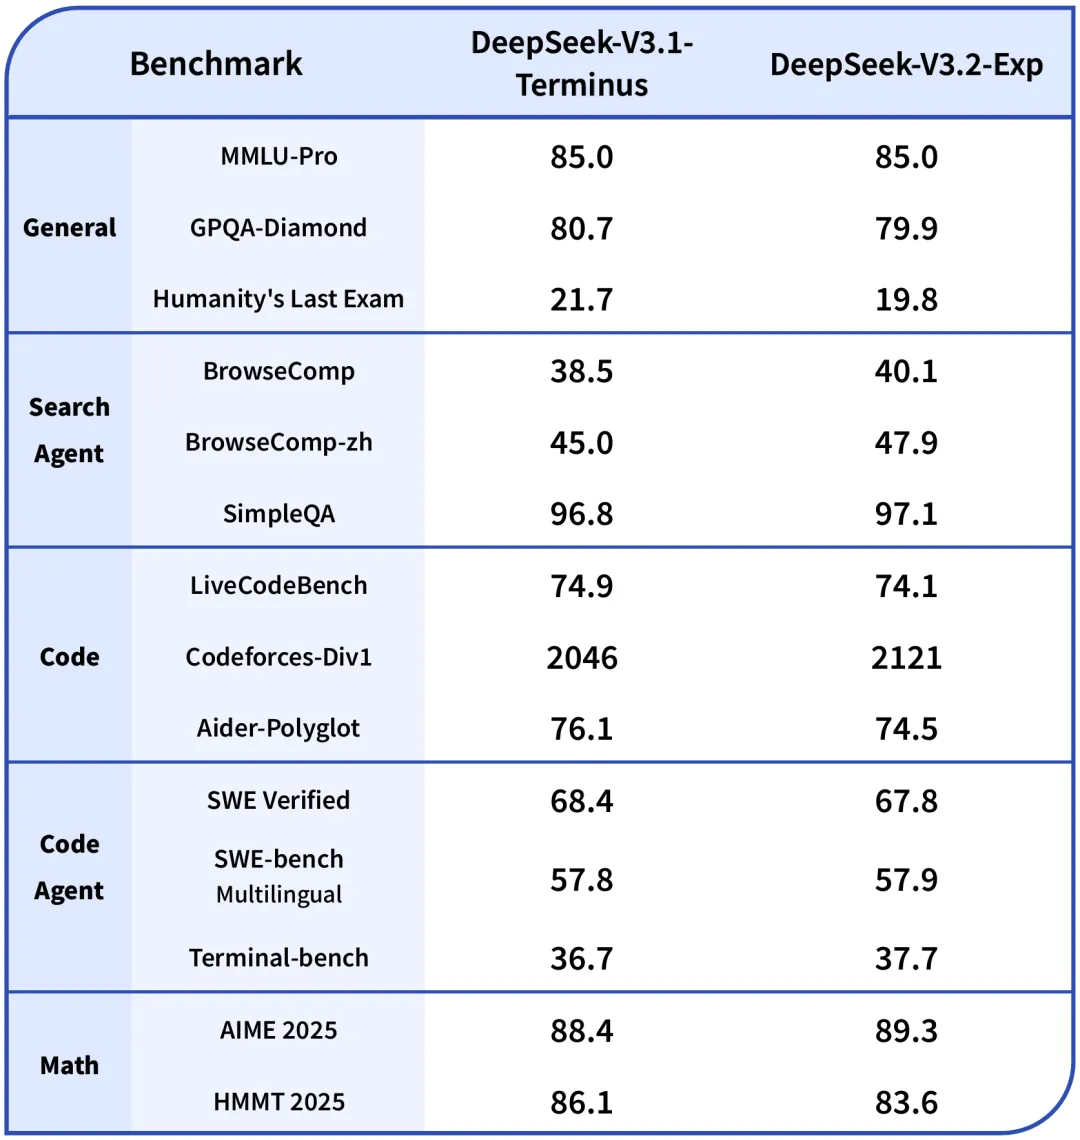
| DeepSeek-V3.2-Exp29 Sep 2025 · DeepSeek | 89.3% | Introducing DeepSeek-V3.2-ExpNo tools or metric printed; no-tools by default.Source image | Yes |
| GPT-57 Aug 2025 · OpenAI | 94.6% | Introducing GPT-5Sentence in the text. The same value is the 'With thinking' segment of the 'GPT-5 (no tools)' bar in the AIME 2025 chart below it (screenshot part 3, kb:/api/images/97). Chart y-axis 'Accuracy, pass@1'. | Yes |
| GPT-57 Aug 2025 · OpenAI | 61.9% | Introducing GPT-5another report, not charted; Read from the full-page screenshot (shots.jsonl part 3, image 97; the bar's x-axis label is at the top of part 4, kb:/api/images/98, sha256 f036431e418305f0b45d54e5179176b075413da4a646a81867a80b28bd140ddb). Chart y-axis 'Accuracy, pass@1'; legend: dark = With thinking, light = Without thinking; stacked bar, value label on each segment. Footnote under the chart: '*AIME results with tools should not be compared directly to the performance of models without tool access; they are an example of how effectively GPT-5 leverages available tools.' This is the without-thinking value; the with-thinking value of the same bar is 94.6% (primary row). Read from a full-page screenshot of the post (para-kb image /api/images/97), as openai.com is bot-walled. | Yes |
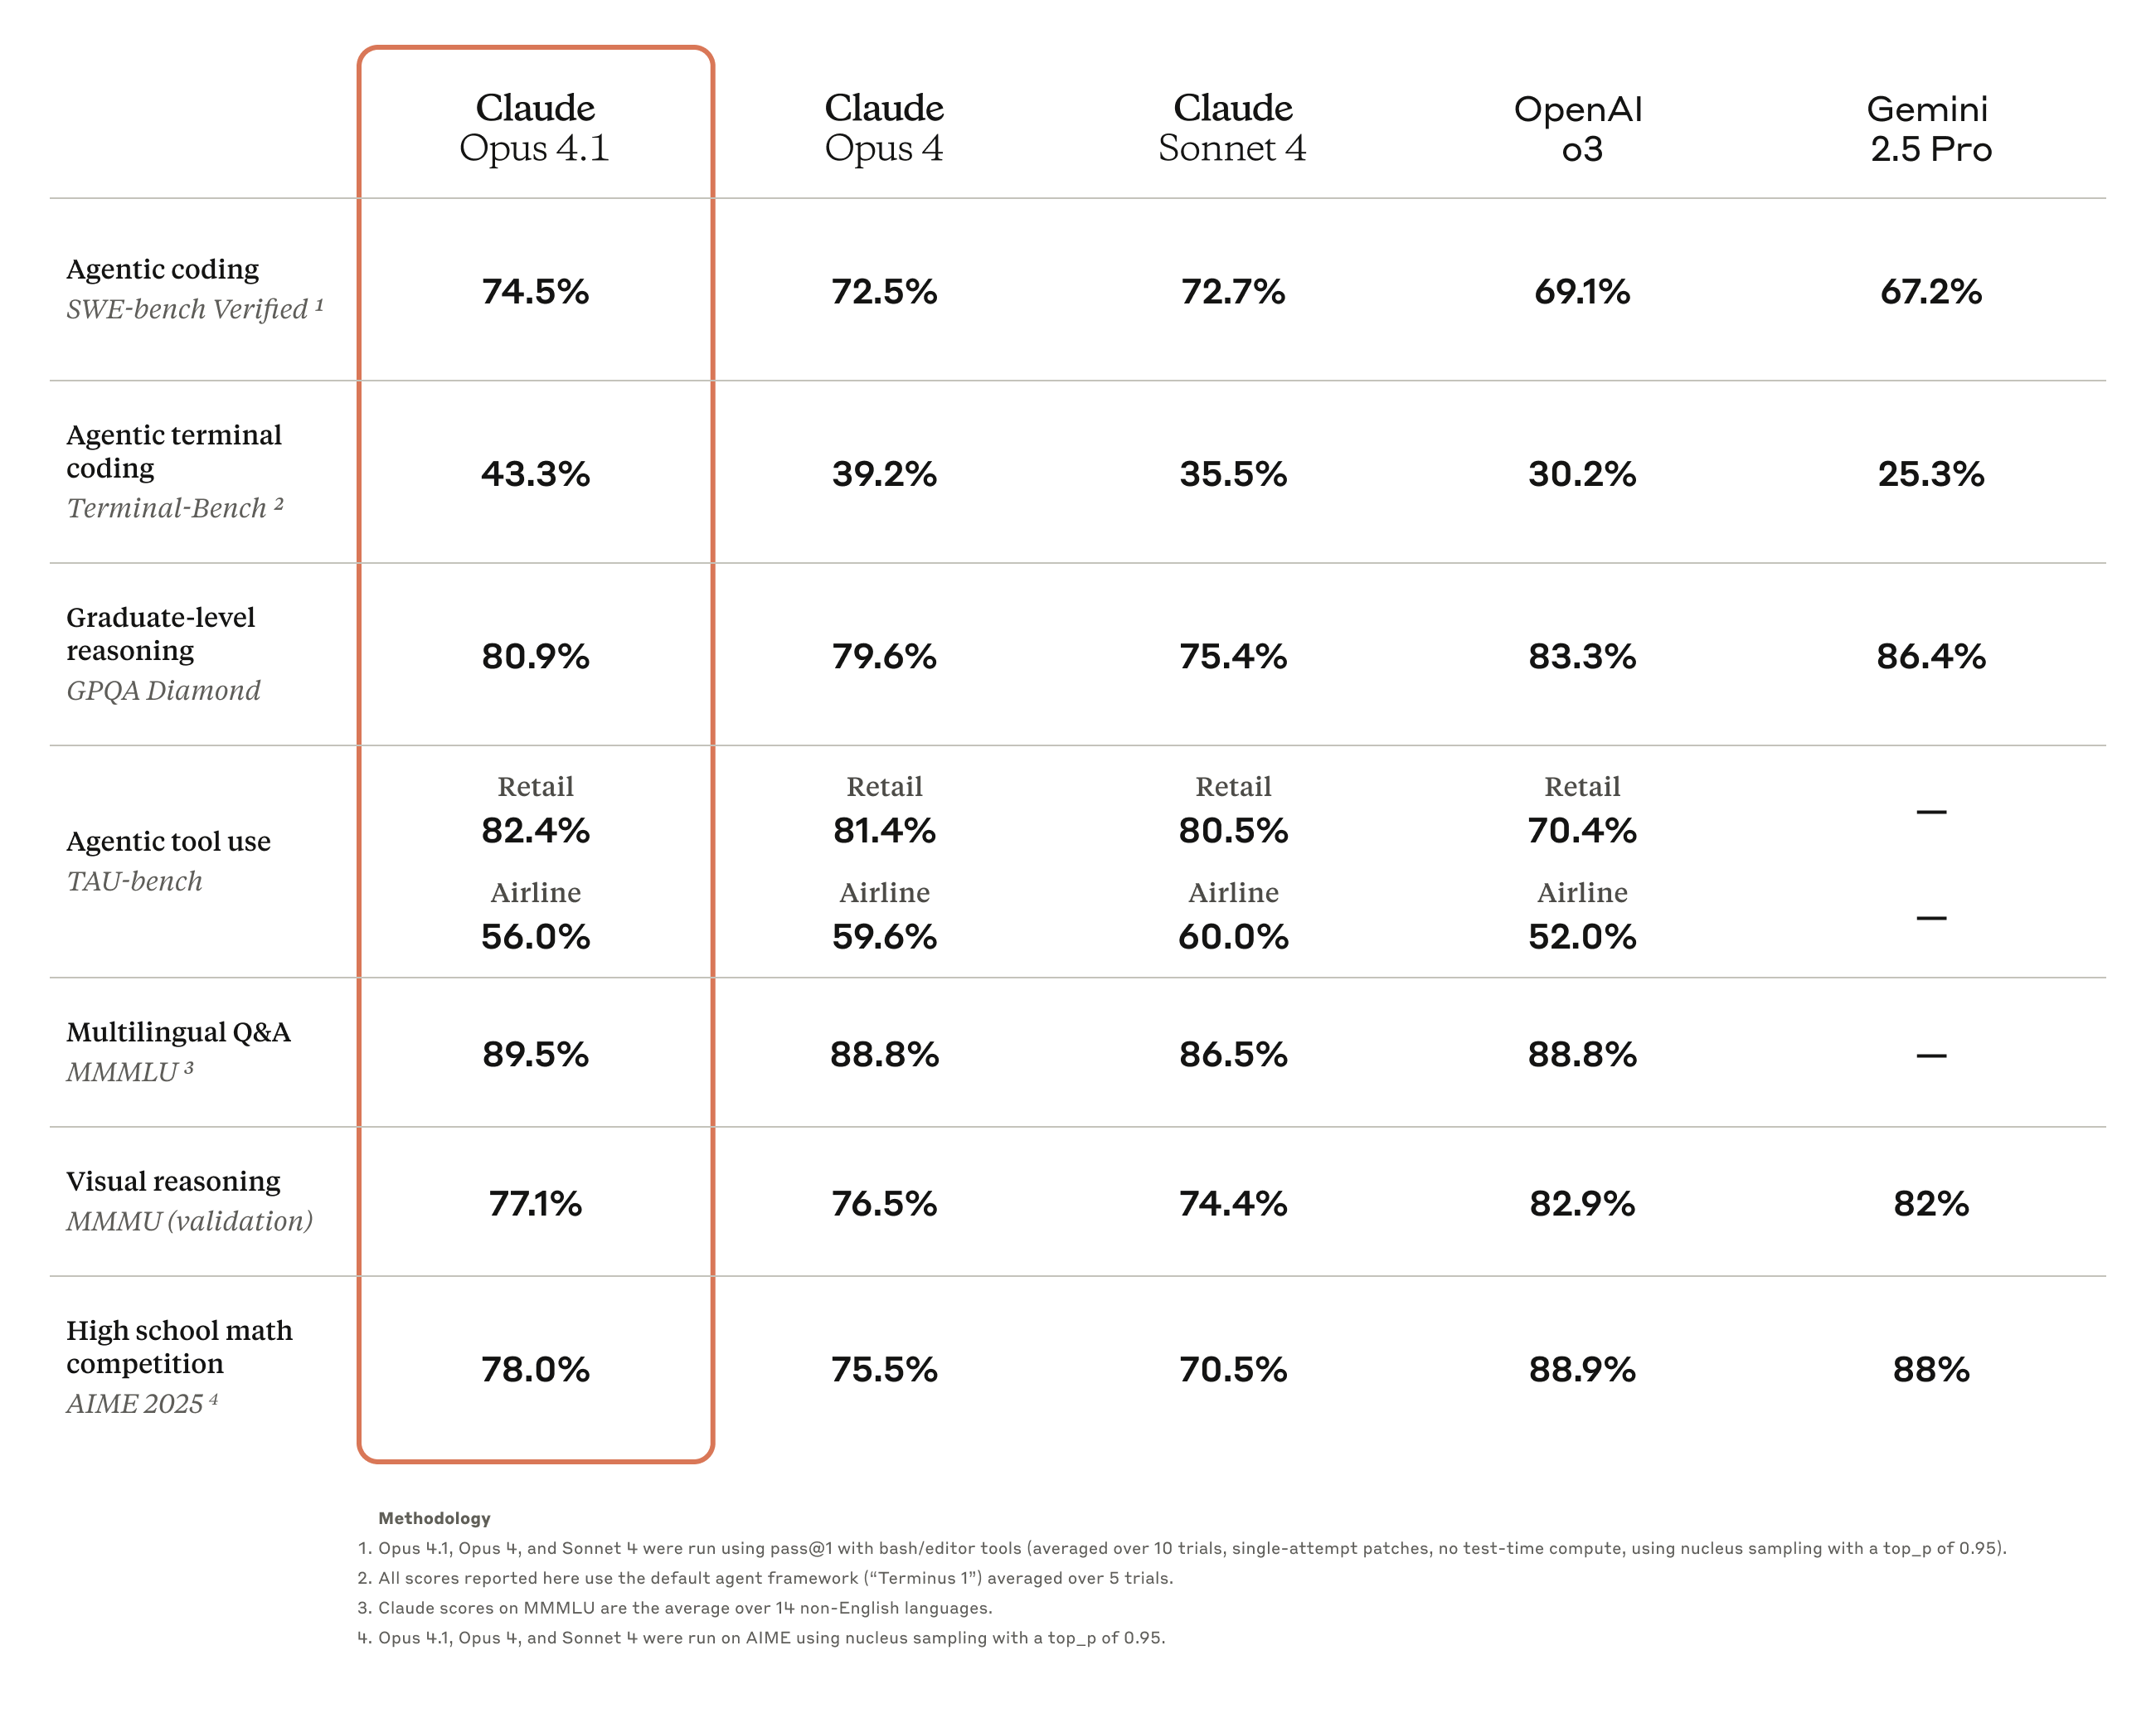
| Claude Opus 4.15 Aug 2025 · Anthropic | 78.0% | Claude Opus 4.1Extended thinking up to 64K tokens (appendix); footnote 4: nucleus sampling, top_p 0.95.Source image | Yes |
| Claude Opus 422 May 2025 · Anthropic | 75.5% | Introducing Claude 4Extended thinking (up to 64K tokens) per appendix; footnote 4: nucleus sampling, top_p 0.95. No tools stated. | Yes |
| Claude Opus 422 May 2025 · Anthropic | 90.0% | Introducing Claude 4parallel test-time compute; Footnote 5: parallel test-time compute with internal scoring model. Extended thinking up to 64K. | Yes |
| Claude Opus 422 May 2025 · Anthropic | 33.9% | Introducing Claude 4another report, not charted; Without extended thinking. Printed as 'AIME' (the table row is AIME 2025). | Yes |
| OpenAI o316 Apr 2025 · OpenAI | 88.9% | Introducing OpenAI o3 and o4-miniRead from the full-page screenshot (shots.jsonl part 2) of the HTML bar chart; value label above the bar. Post note under the chart set: 'All models are evaluated at high reasoning effort settings, similar to variants like o4-mini-high in ChatGPT.' Printed without % (y-axis 'Accuracy (%)'). A cost-vs-score image (o3-o4_AIME2025.png, 'AIME 2025, no tools' vs estimated inference cost, o3 low/medium/high) has no value labels and is not recorded. Read from a full-page screenshot of the post (para-kb image /api/images/79), as openai.com is bot-walled. | Yes |
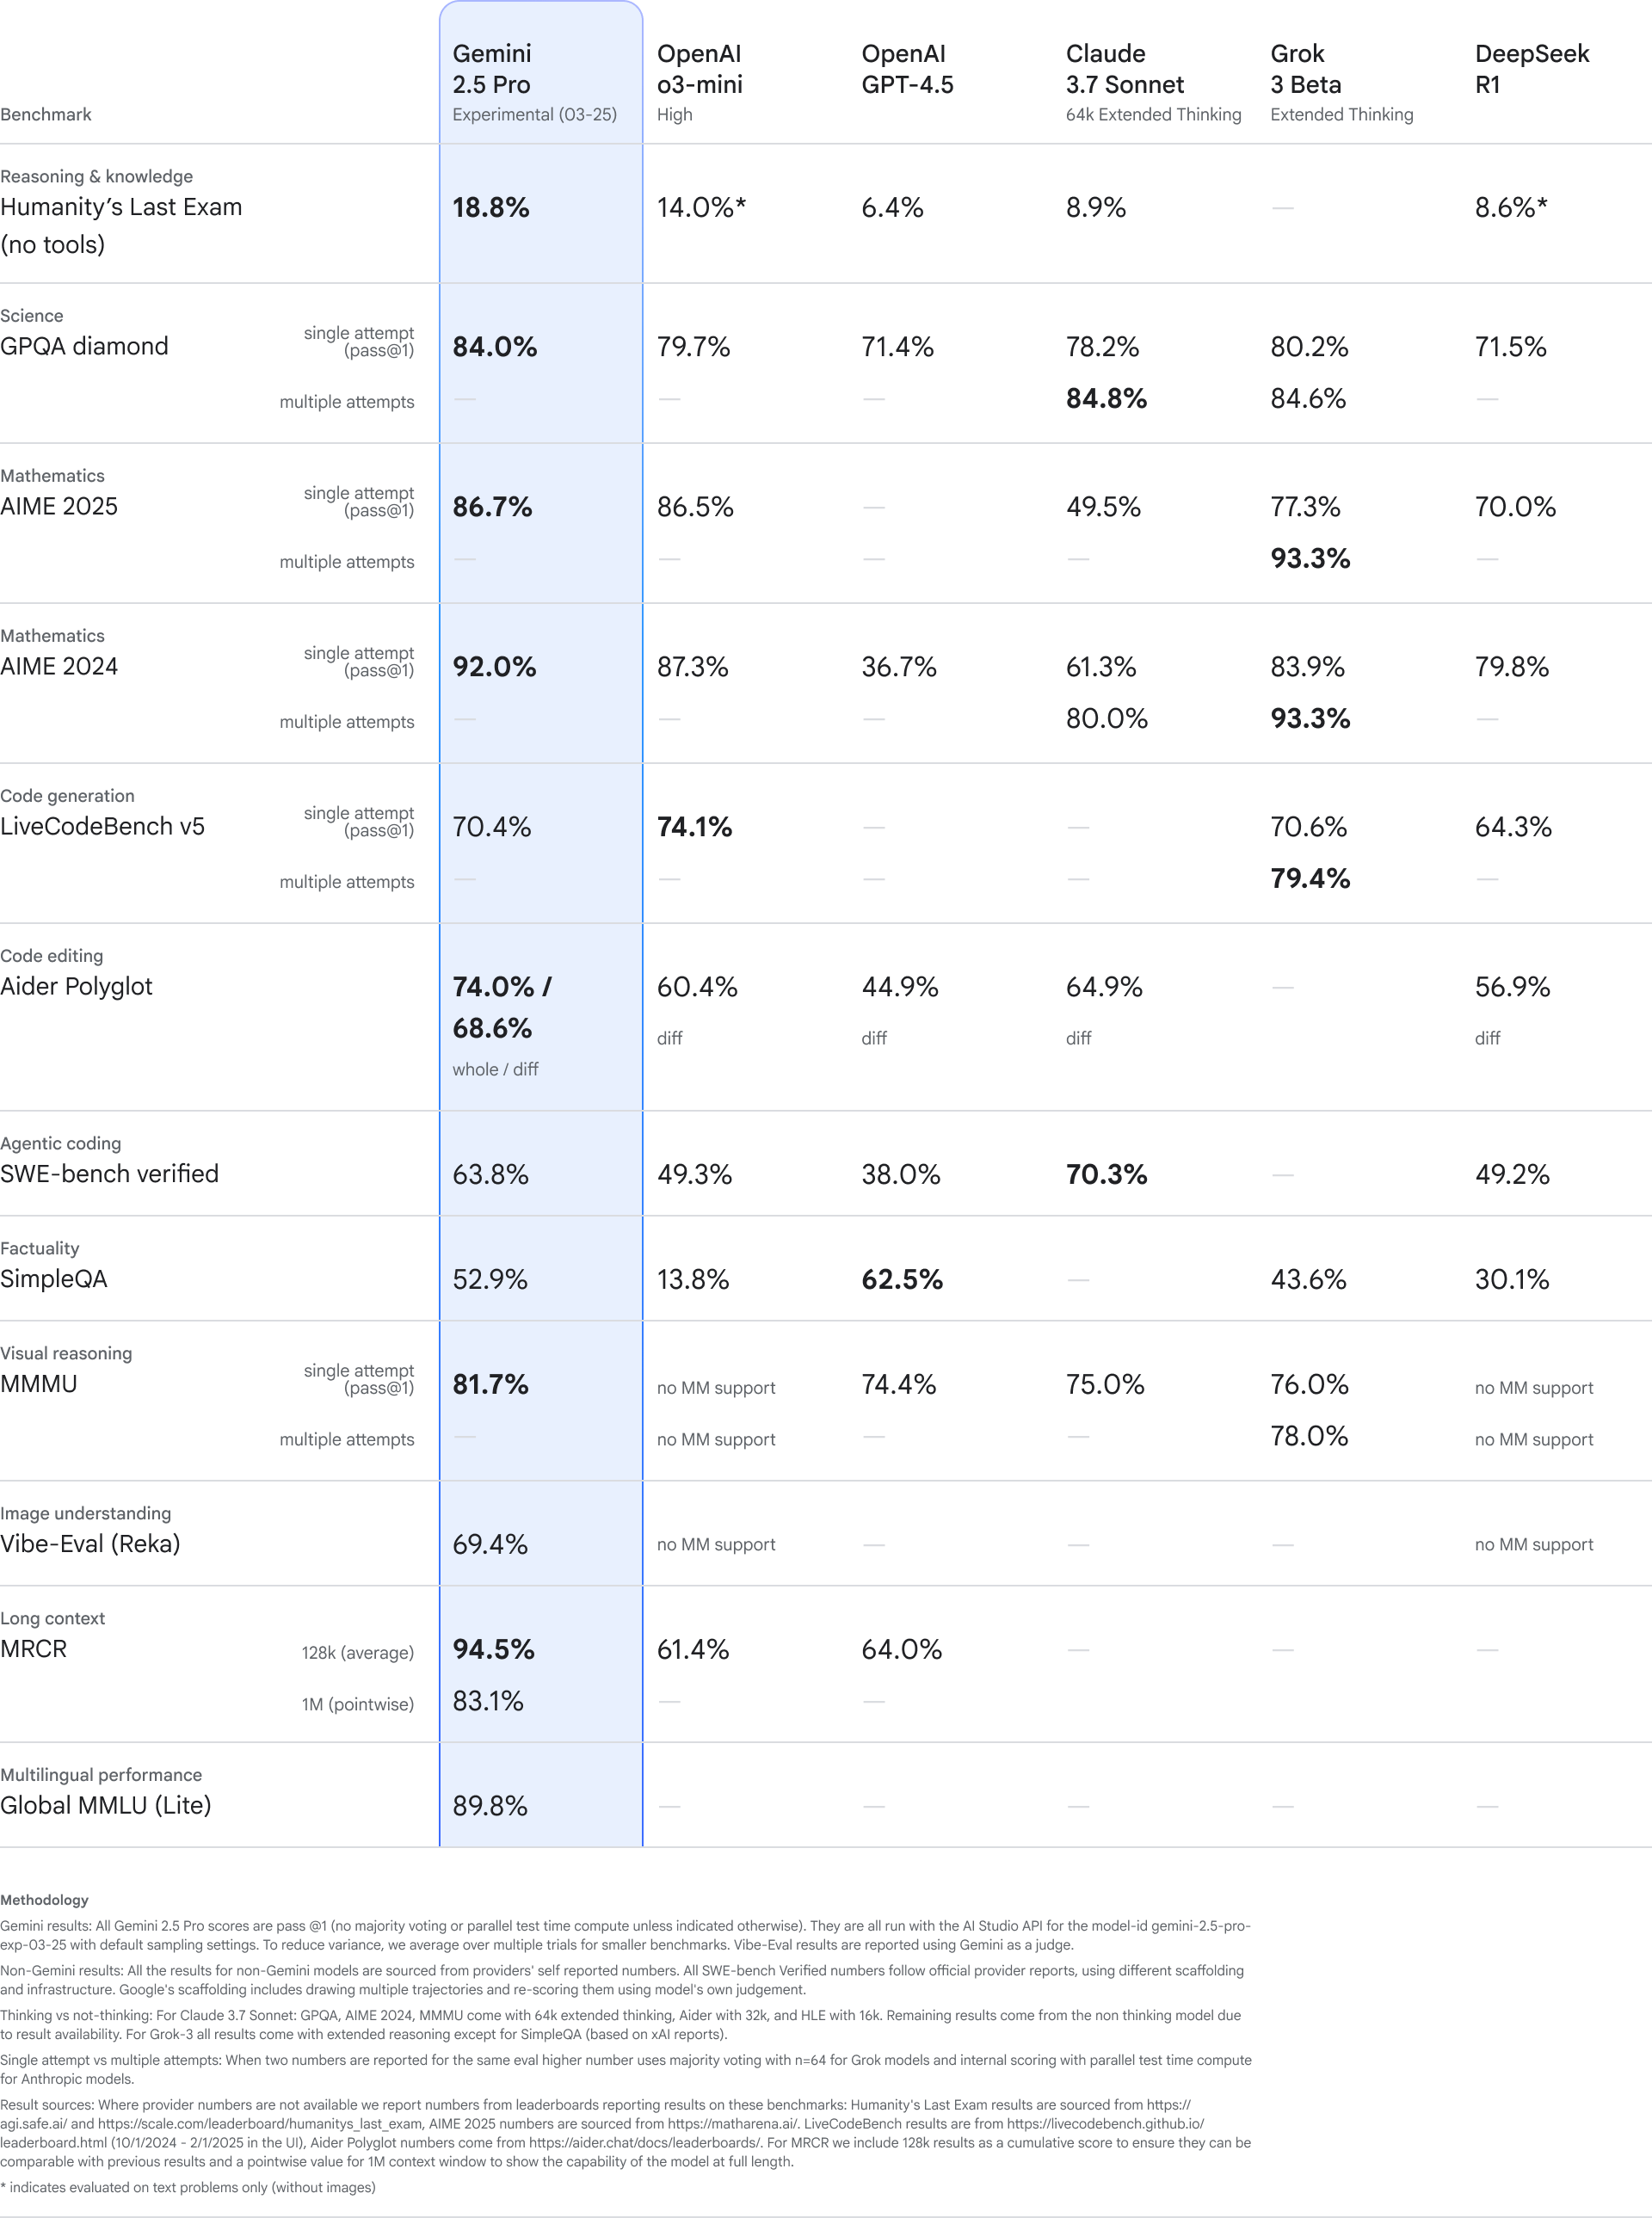
| Gemini 2.5 Pro25 Mar 2025 · Google | 86.7% | Gemini 2.5: Our most intelligent AI modelMethodology under the table: all Gemini 2.5 Pro scores are pass@1 (no majority voting or parallel test-time compute), run via AI Studio API model gemini-2.5-pro-exp-03-25 with default sampling, averaged over multiple trials for smaller benchmarks. No tools printed. The 'multiple attempts' sub-row is a dash for Gemini.Source image | Yes |
Benchmark
maa.orgHigher is better
Mathematical Association of AmericaIntroduced 12 Feb 2025