AIME 2024
- OpenAI
- Anthropic
- DeepSeek
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| OpenAI o316 Apr 2025 · OpenAI | 91.6% | Introducing OpenAI o3 and o4-miniRead from the full-page screenshot (shots.jsonl part 2) of the HTML bar chart; value label above the bar. Post note under the chart set: 'All models are evaluated at high reasoning effort settings, similar to variants like o4-mini-high in ChatGPT.' Printed without % (y-axis 'Accuracy (%)'). Read from a full-page screenshot of the post (para-kb image /api/images/79), as openai.com is bot-walled. | Yes |
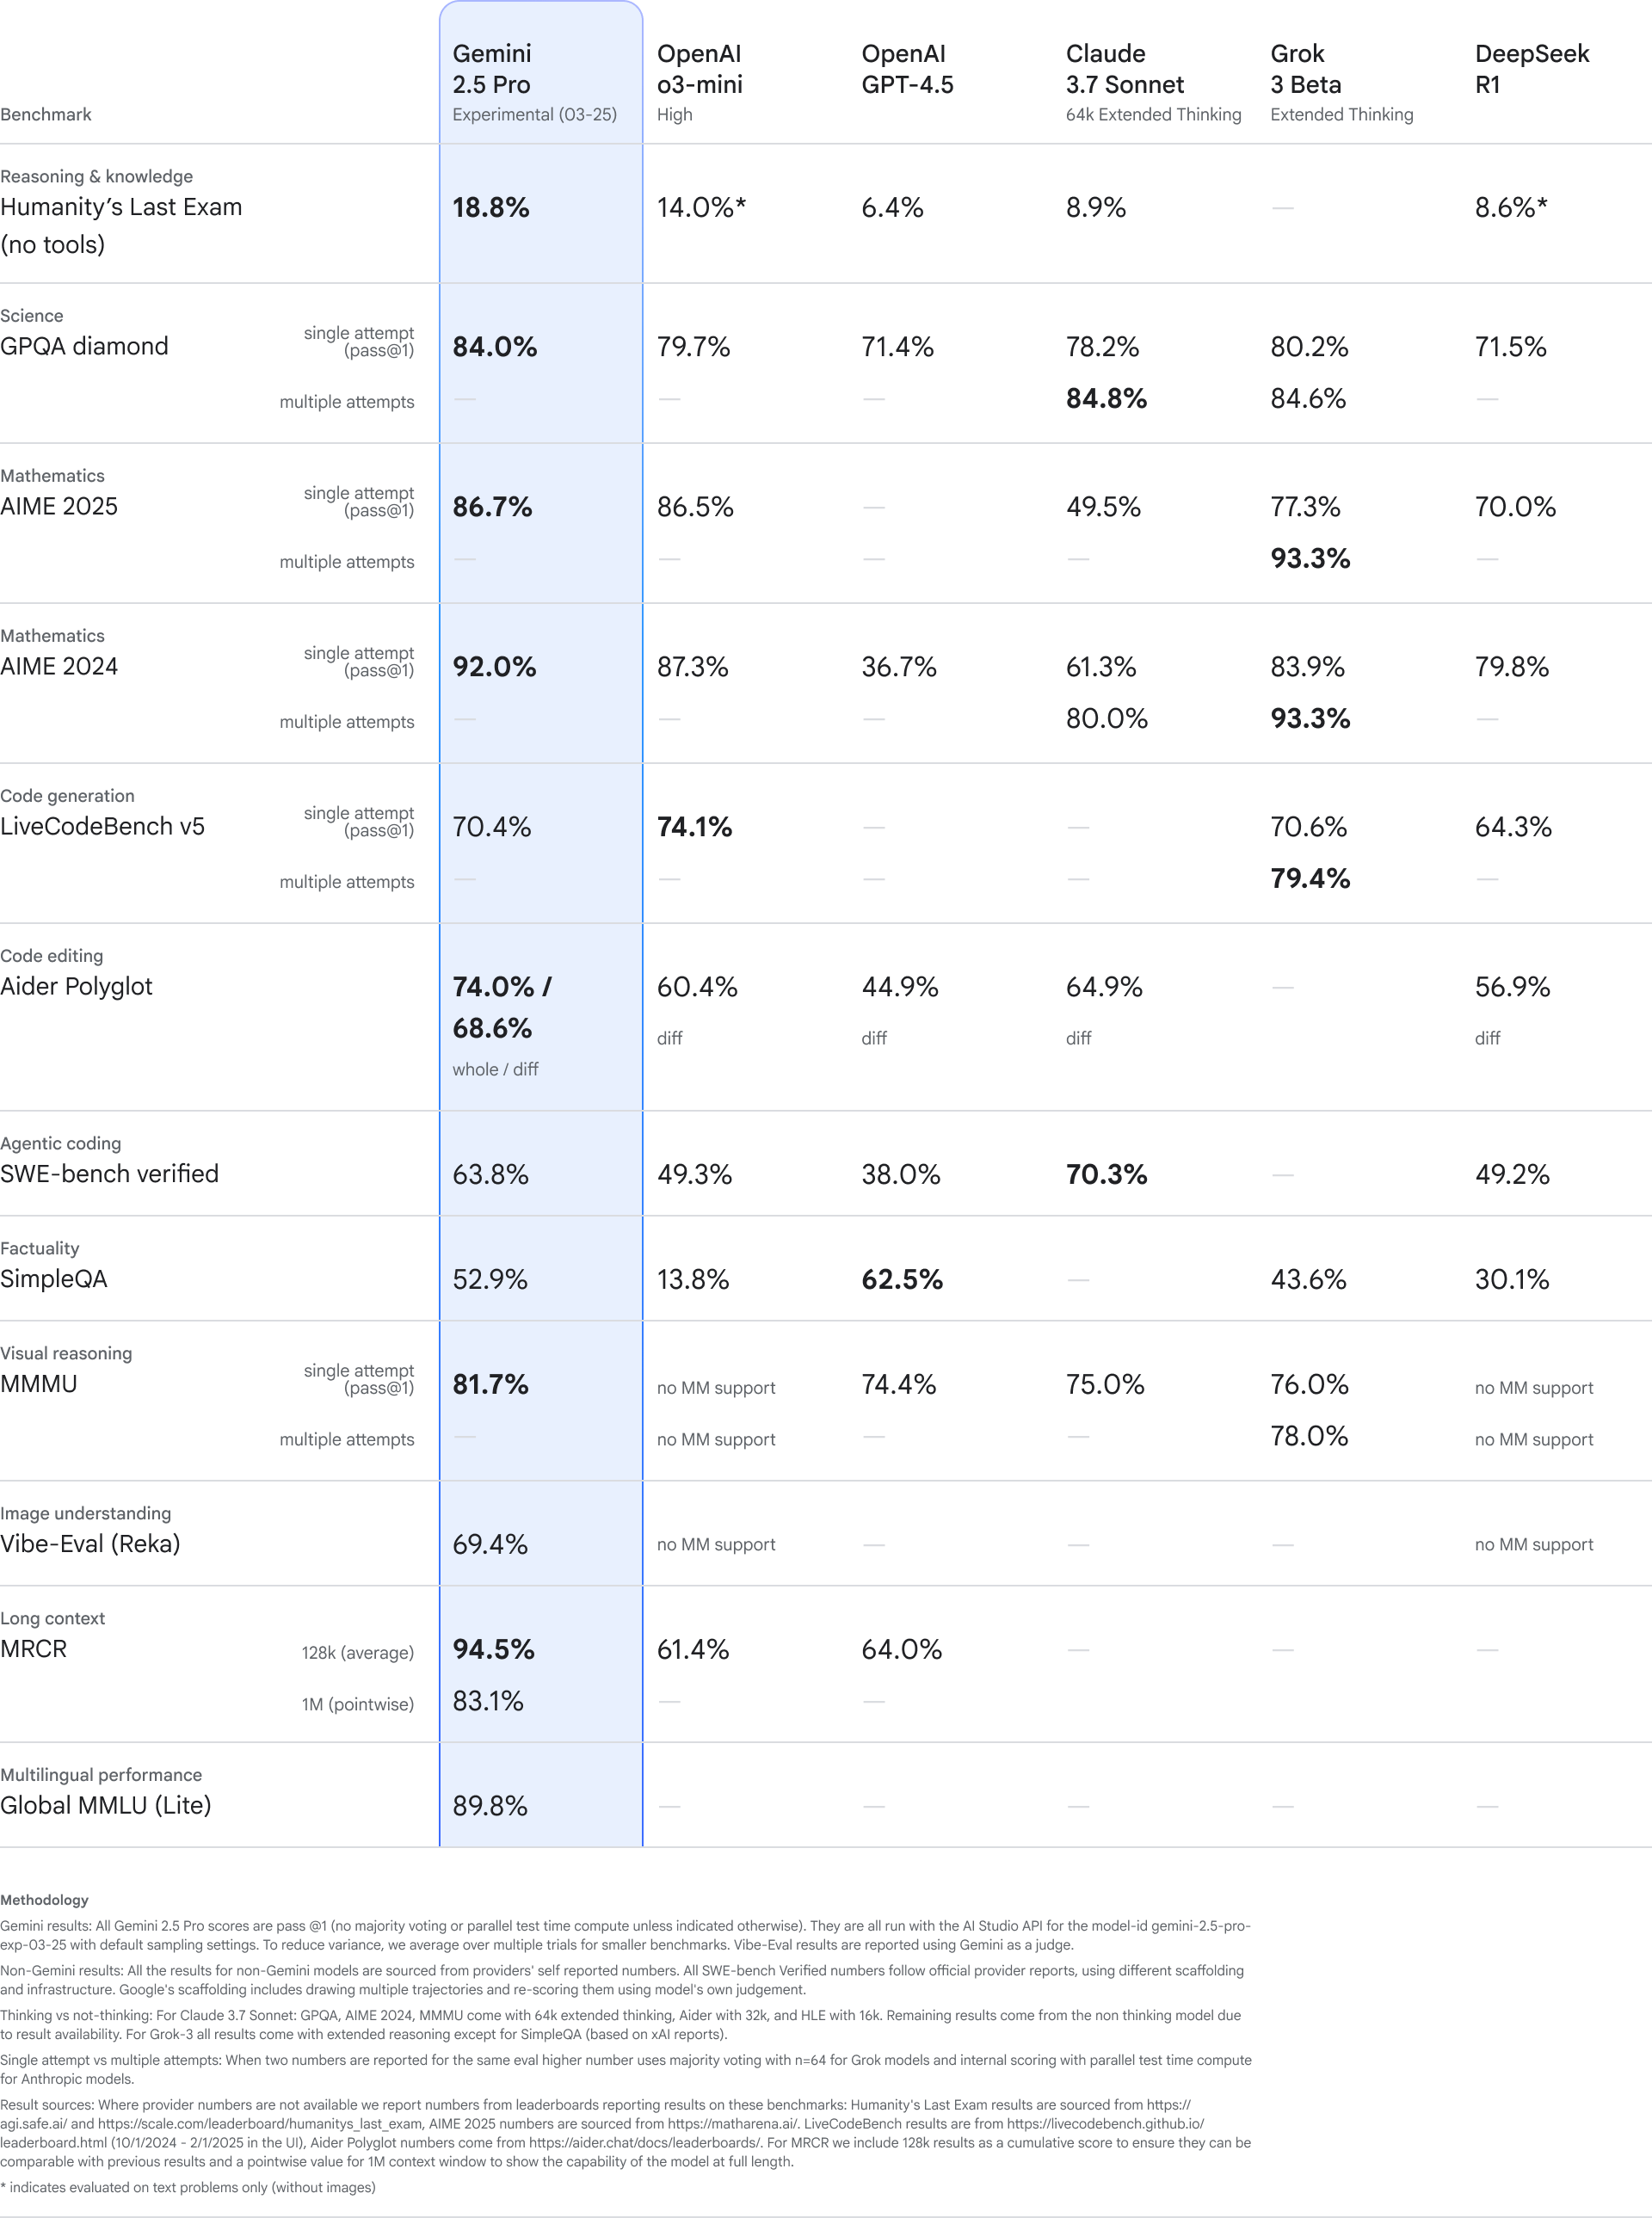
| Gemini 2.5 Pro25 Mar 2025 · Google | 92.0% | Gemini 2.5: Our most intelligent AI modelMethodology under the table: all Gemini 2.5 Pro scores are pass@1 (no majority voting or parallel test-time compute), run via AI Studio API model gemini-2.5-pro-exp-03-25 with default sampling, averaged over multiple trials for smaller benchmarks. No tools printed. The 'multiple attempts' sub-row is a dash for Gemini. The hero chart image does not show AIME 2024.Source image | Yes |
| GPT-4.527 Feb 2025 · OpenAI | 36.7% | Introducing GPT-4.5HTML table; the post prints no tools setting for this row (GPT-4.5 is a non-reasoning model and the table has no tool notes; the '*' footnote marks only the SWE rows), so no-tools is assumed. The fetched page text was truncated, so footnotes without a % sign are not visible in the extract. | Yes |
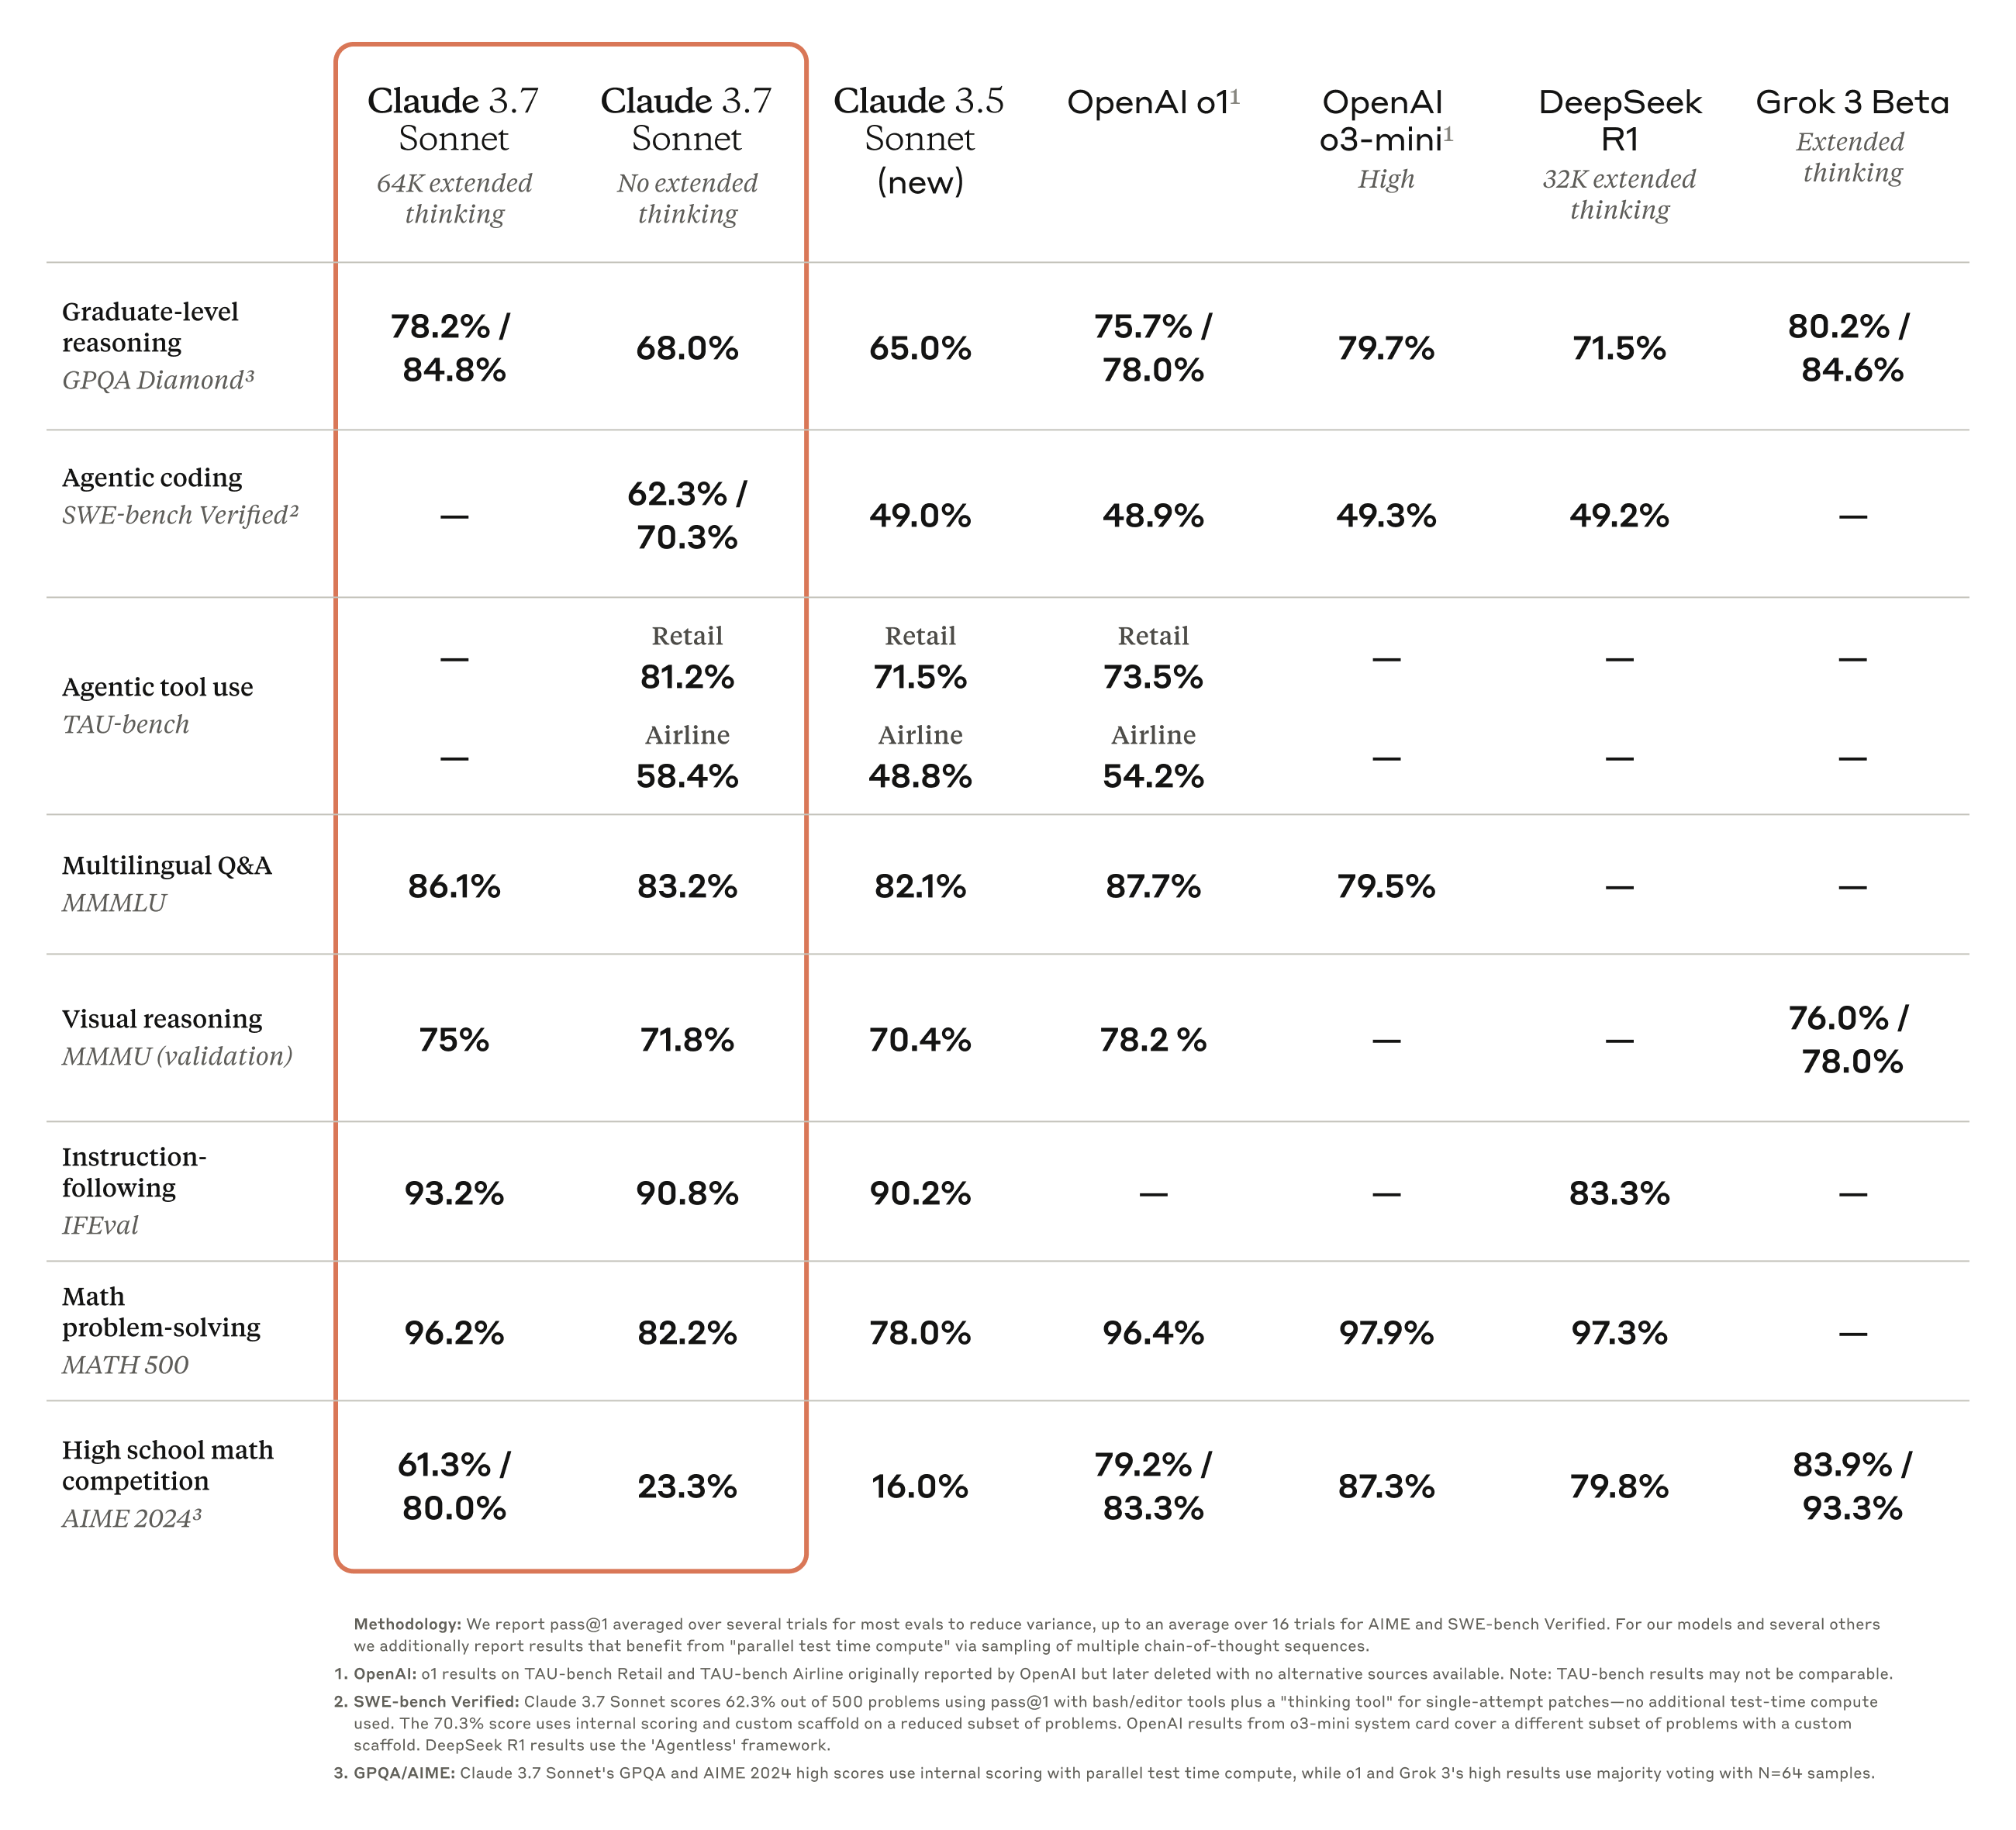
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 61.3% | Claude 3.7 Sonnet and Claude Code64K extended thinking; pass@1 averaged over up to 16 trials. Chosen as primary over the no-extended-thinking column (both are own, non-parallel); flag if the other should be primary.Source image | Yes |
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 80.0% | Claude 3.7 Sonnet and Claude Codeparallel test-time compute; 64K extended thinking. Footnote 3: high score uses internal scoring with parallel test-time compute. Methodology: pass@1 averaged over up to 16 trials for AIME.Source image | Yes |
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 23.3% | Claude 3.7 Sonnet and Claude Codeanother report, not charted; No extended thinking; pass@1 averaged over up to 16 trials.Source image | Yes |
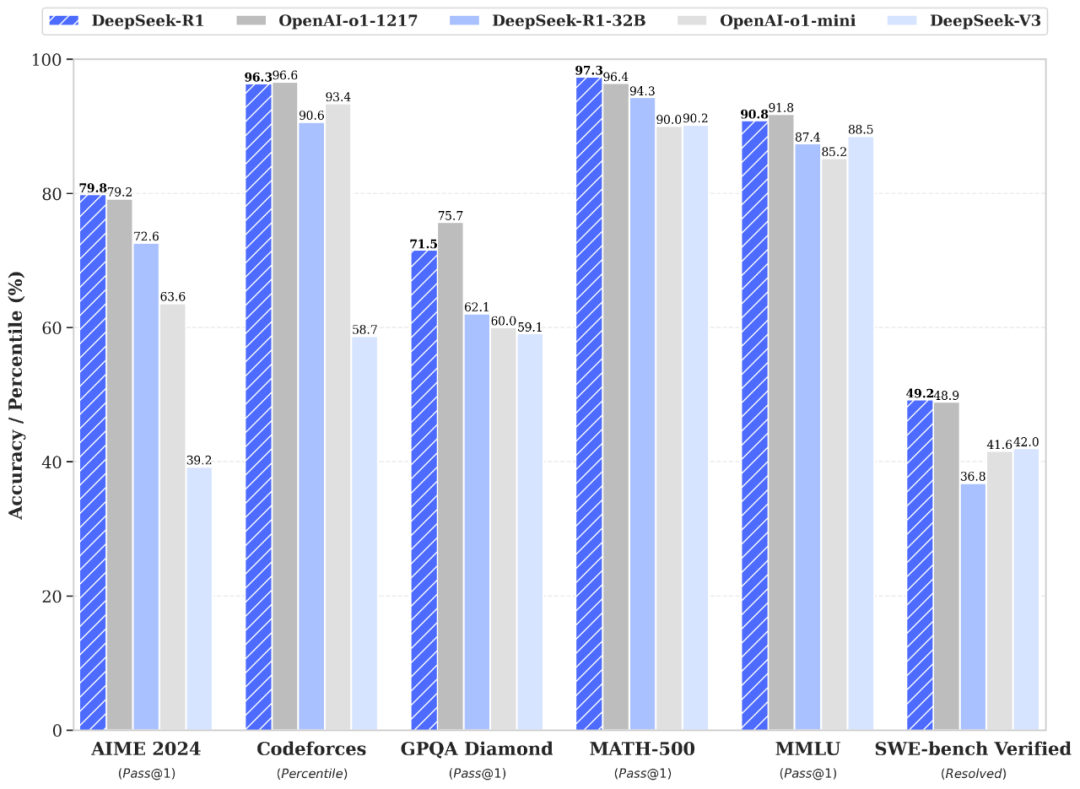
| DeepSeek-R120 Jan 2025 · DeepSeek | 79.8% | DeepSeek-R1 ReleasePass@1; post states no tool use either way, so no-tools by default. The distill table image prints AIME 2024 pass@1/cons@64 only for the distilled models and competitors, not for DeepSeek-R1.Source image | Yes |
Benchmark
maa.orgHigher is better
Mathematical Association of AmericaIntroduced 7 Feb 2024