o4-mini
Announced on openai.com
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
| Humanity's Last ExamNo tools · high reasoning effort | 14.28% | |
| Humanity's Last ExamWith tools · high reasoning effort; Python and browsing; known cheating domains blocked; attempts a monitor flags count as wrong | 17.70% | CheckedA person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Verifiedhigh reasoning effort; 477 of the 500 verified tasks; 256K context | 68.1% | |
| GPQA Diamondhigh reasoning effort; no tools | 81.4% | |
| BrowseComphigh reasoning effort; Python and browsing | 28.3% | CheckedA person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
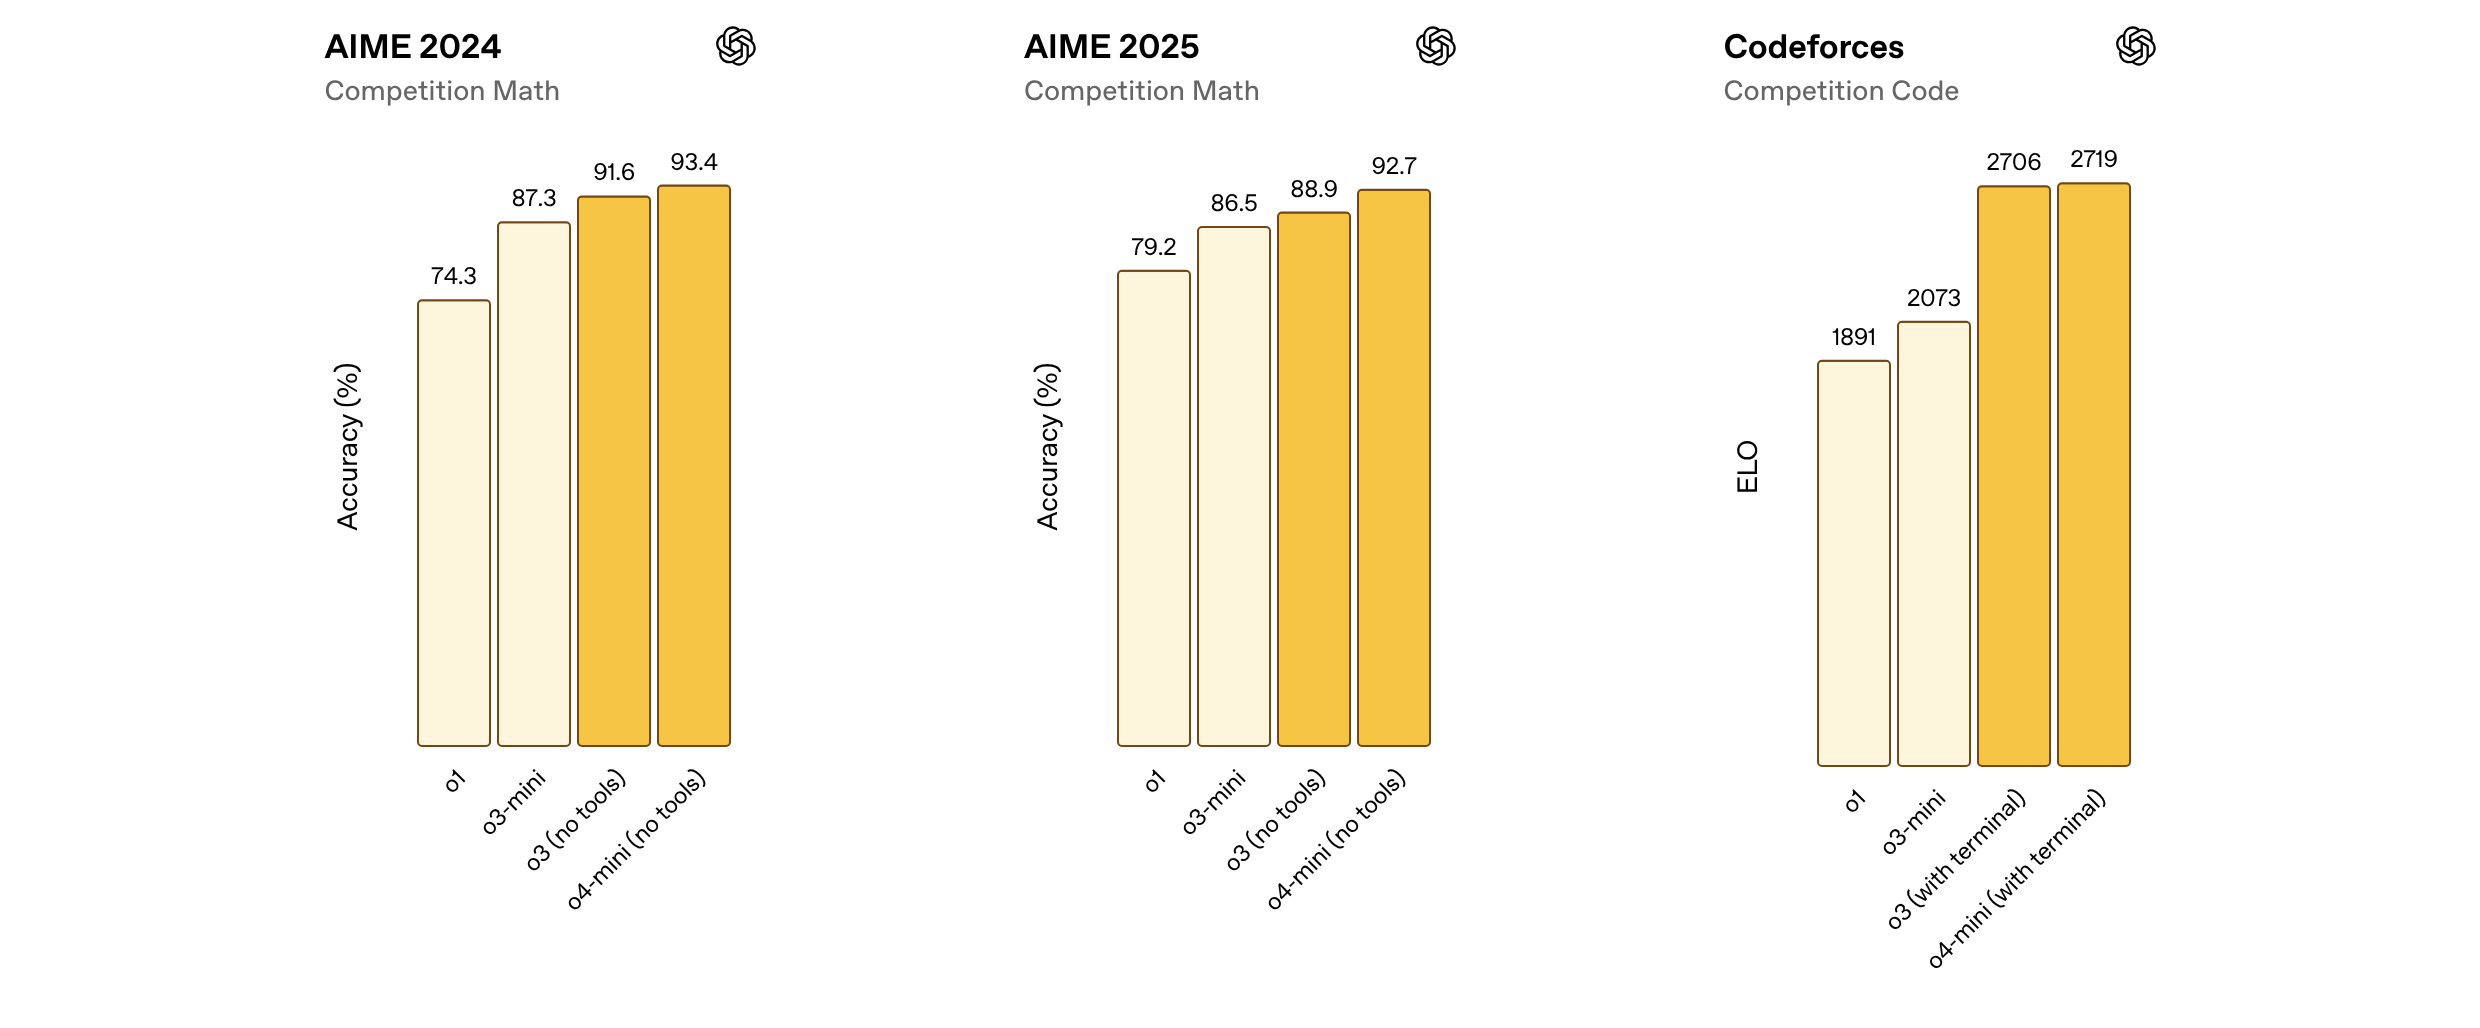
| AIME 2024No tools · high reasoning effort | 93.4% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| AIME 2025No tools · high reasoning effort | 92.7% | |
| AIME 2025With tools · Python interpreter; pass@1; OpenAI says not to compare with-tools scores to models without tools | 99.5% | CheckedA person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Python interpreter; majority vote over 8 samples · parallel test-time compute | 100% | CheckedA person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by OpenAI
- Introducing OpenAI o3 and o4-miniopenai.com · 16 Apr 2025
Our capture of the source 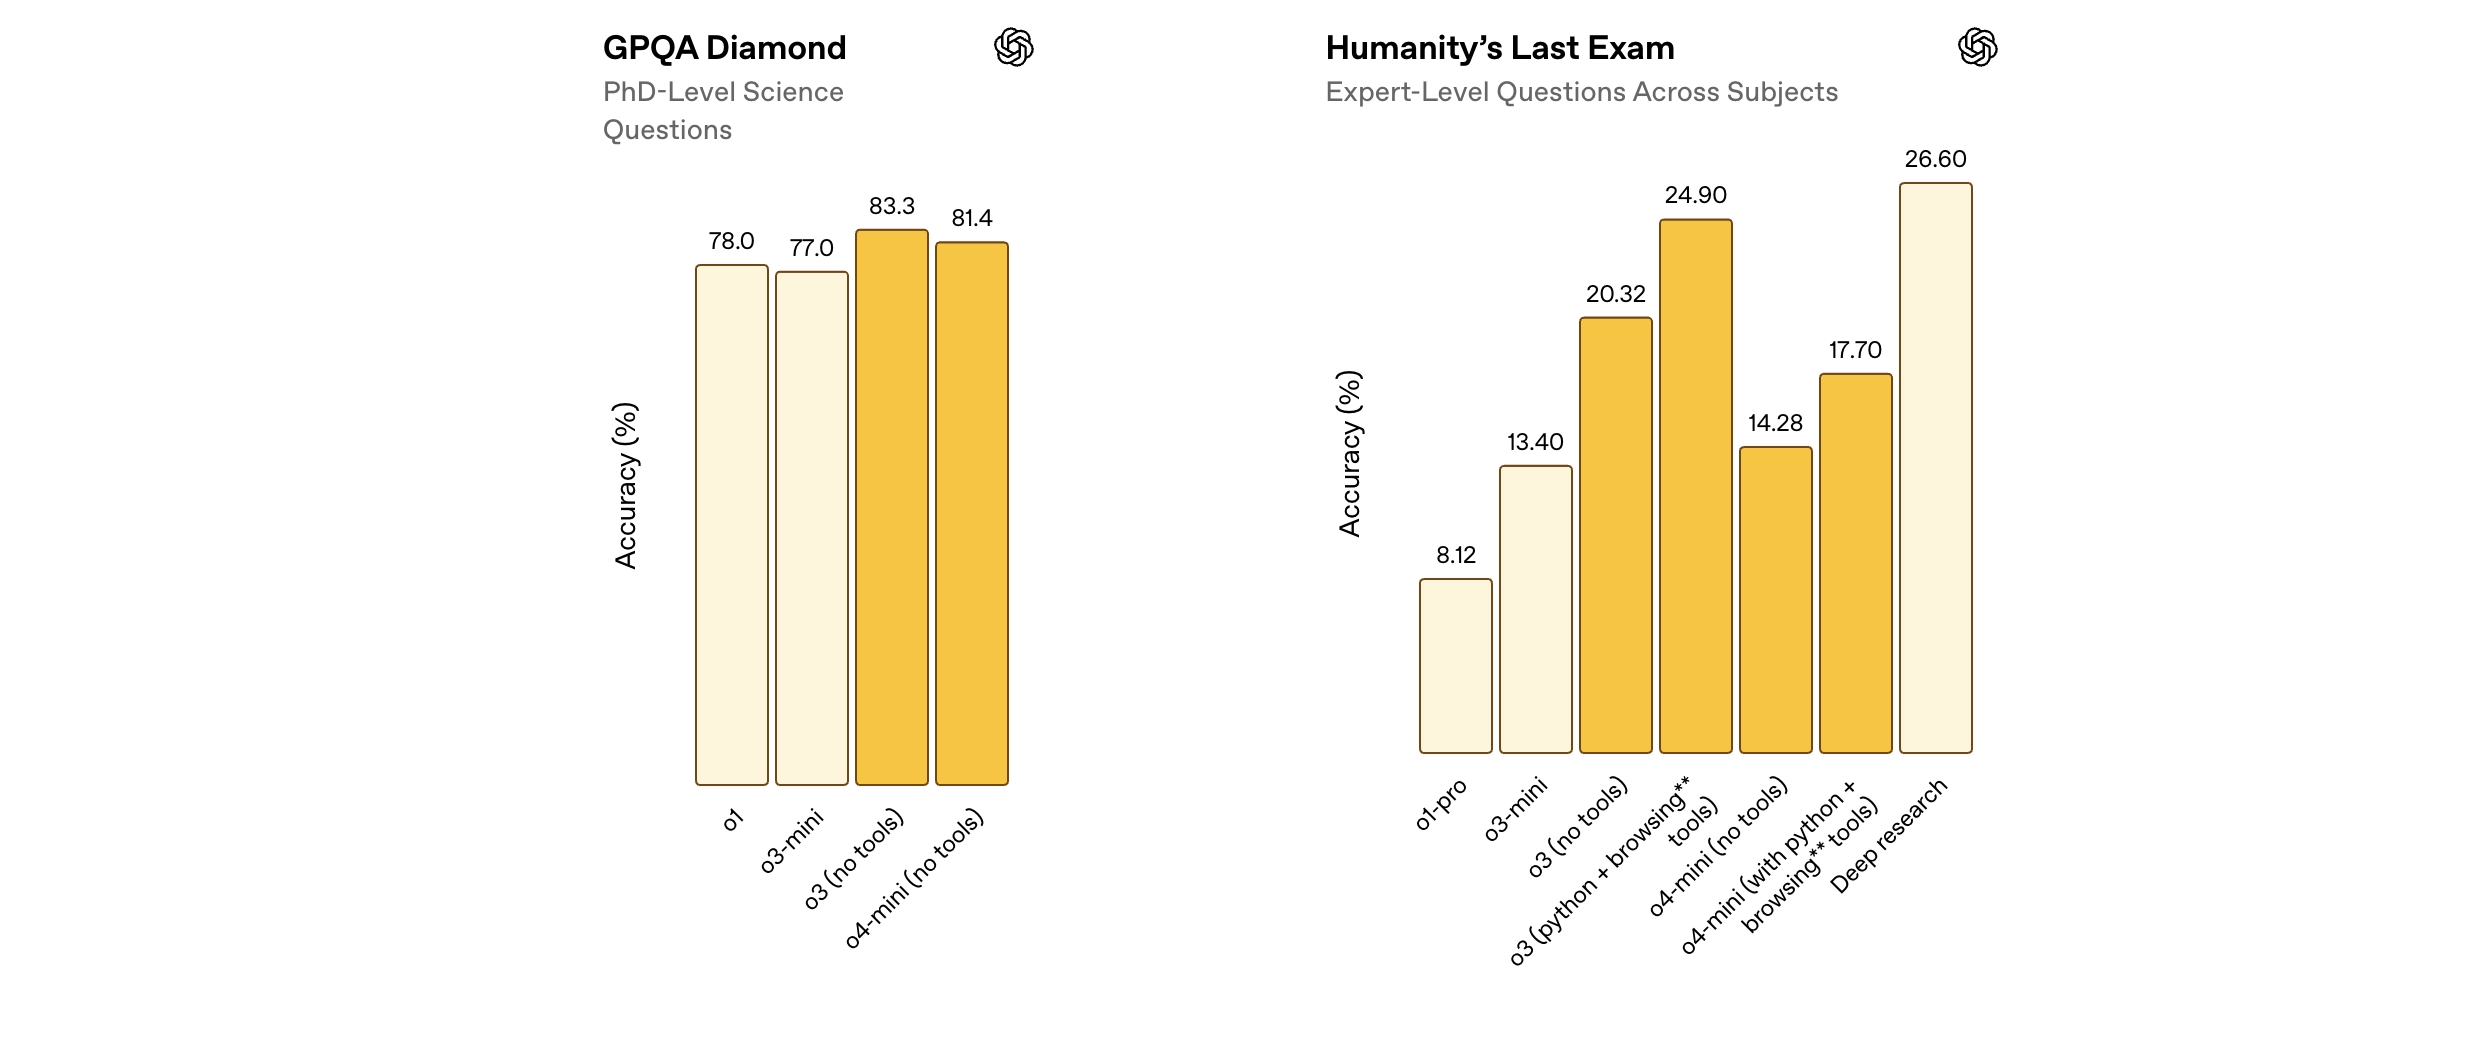
Our capture of the source 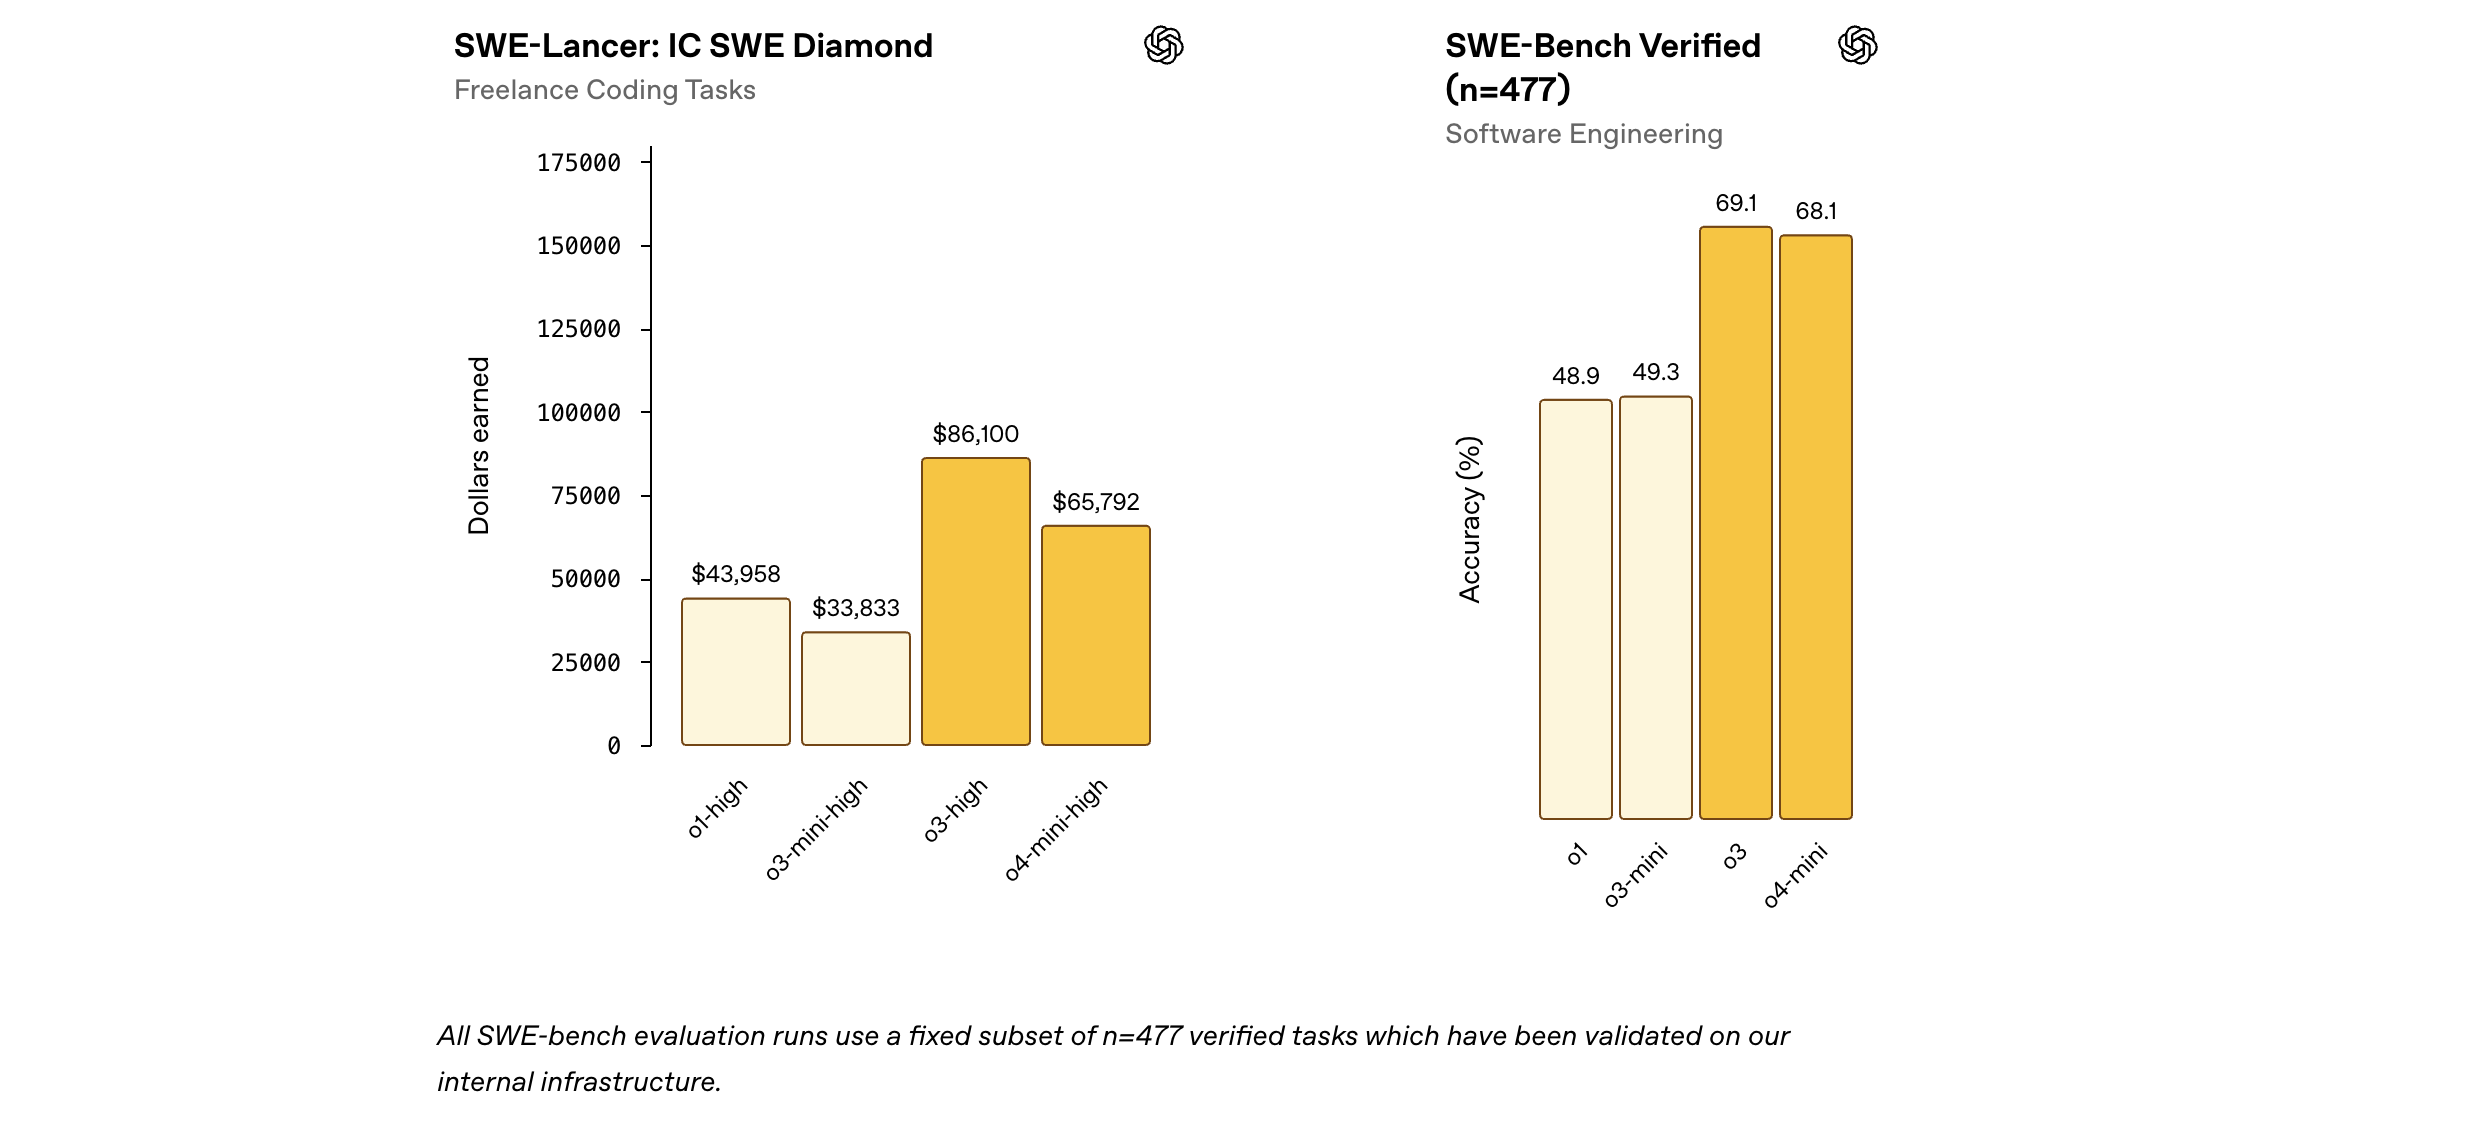
Our capture of the source 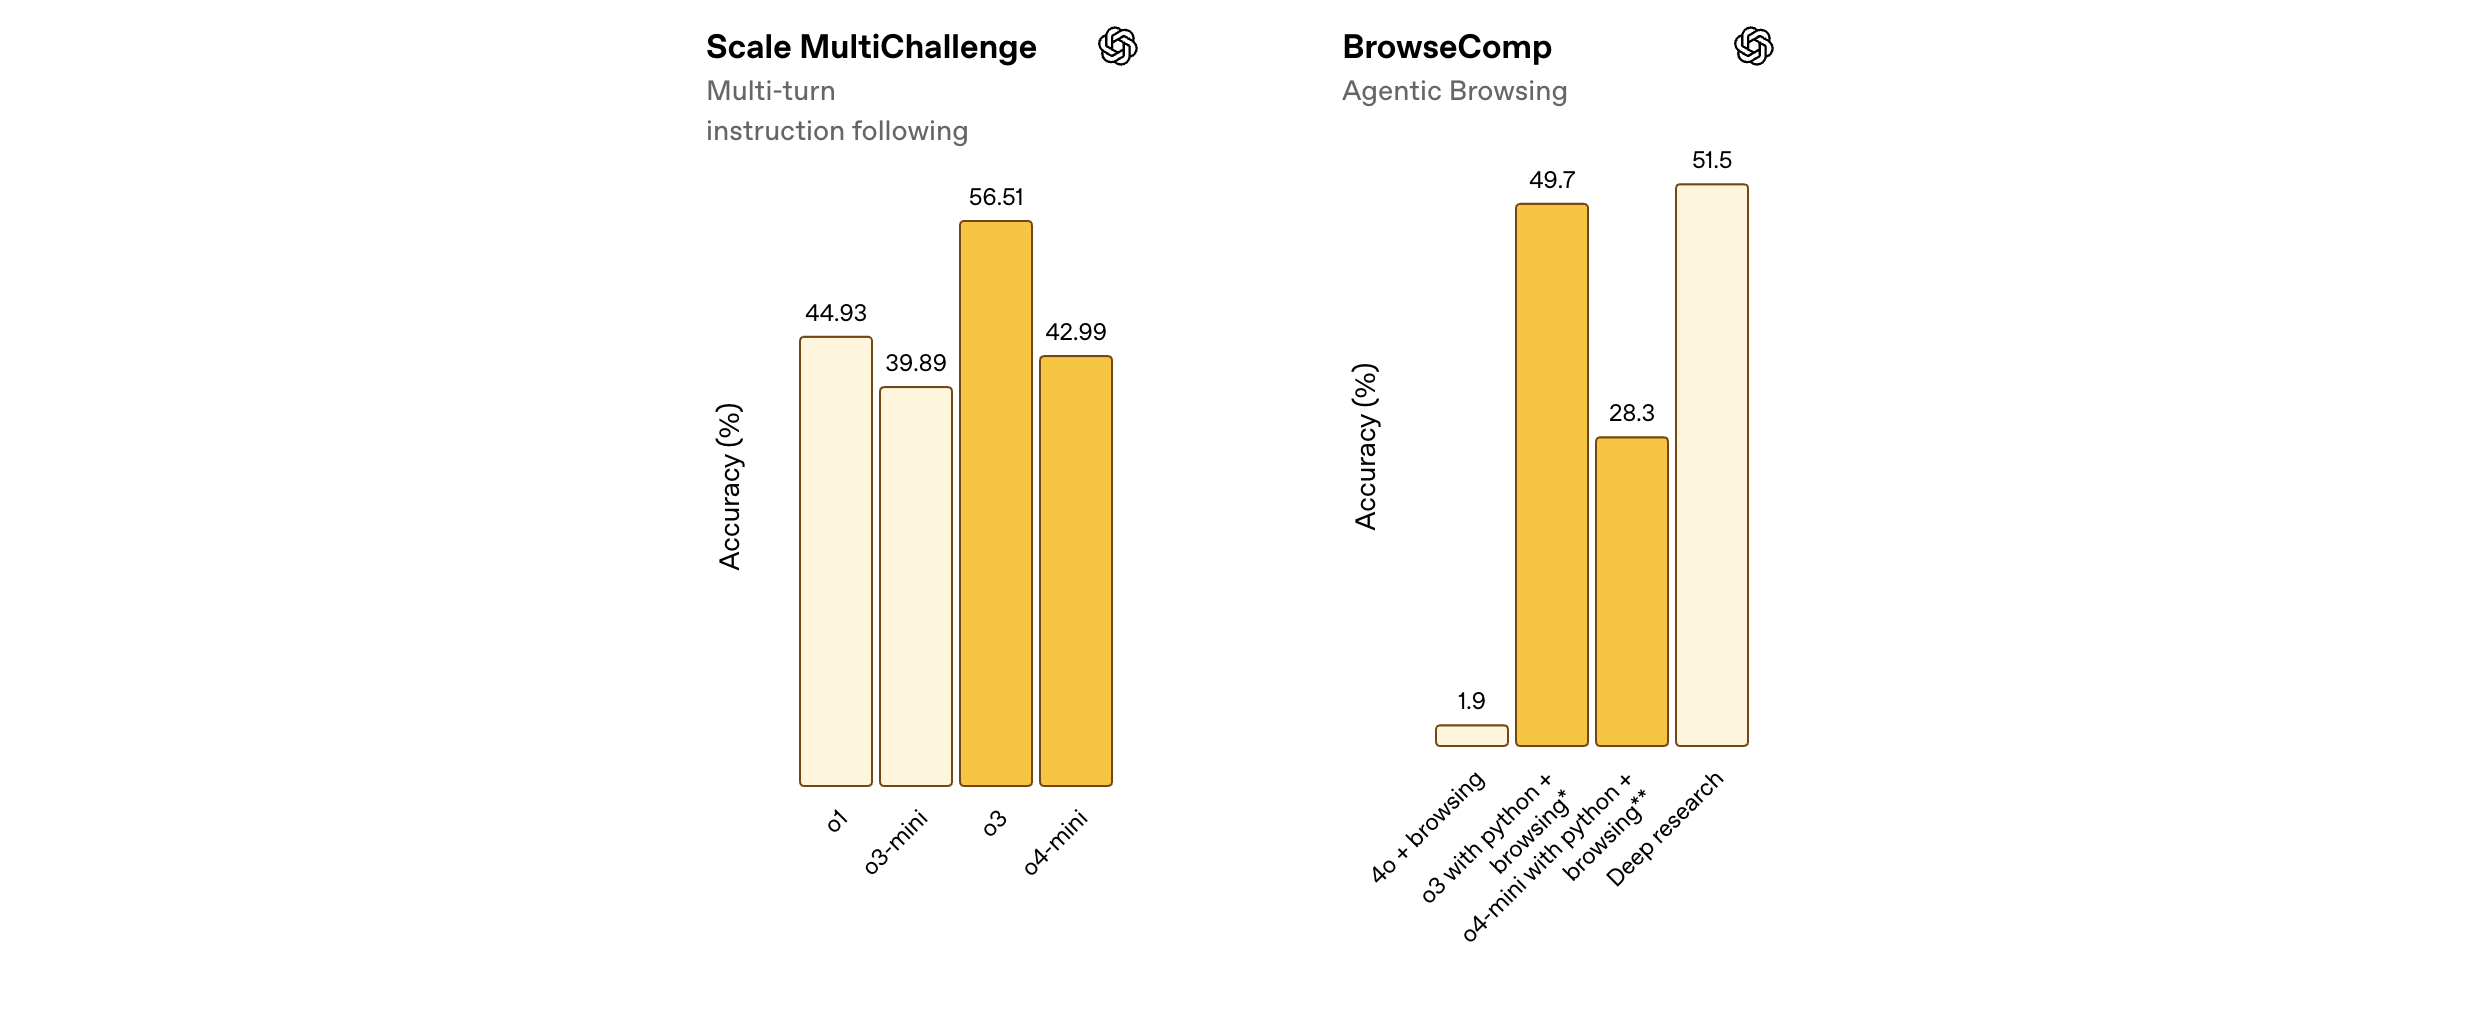
Our capture of the source