BrowseComp
- OpenAI
- Anthropic
- DeepSeek
- Moonshot AI
- MiniMax
- Reported in a later post or card
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| GPT-6 Astra3 Sep 2026 · OpenAI | 91.5% | GPT-6 Astra: A new generation of intelligencePro and Ultra variants are separate columns, not recorded | Not yet |
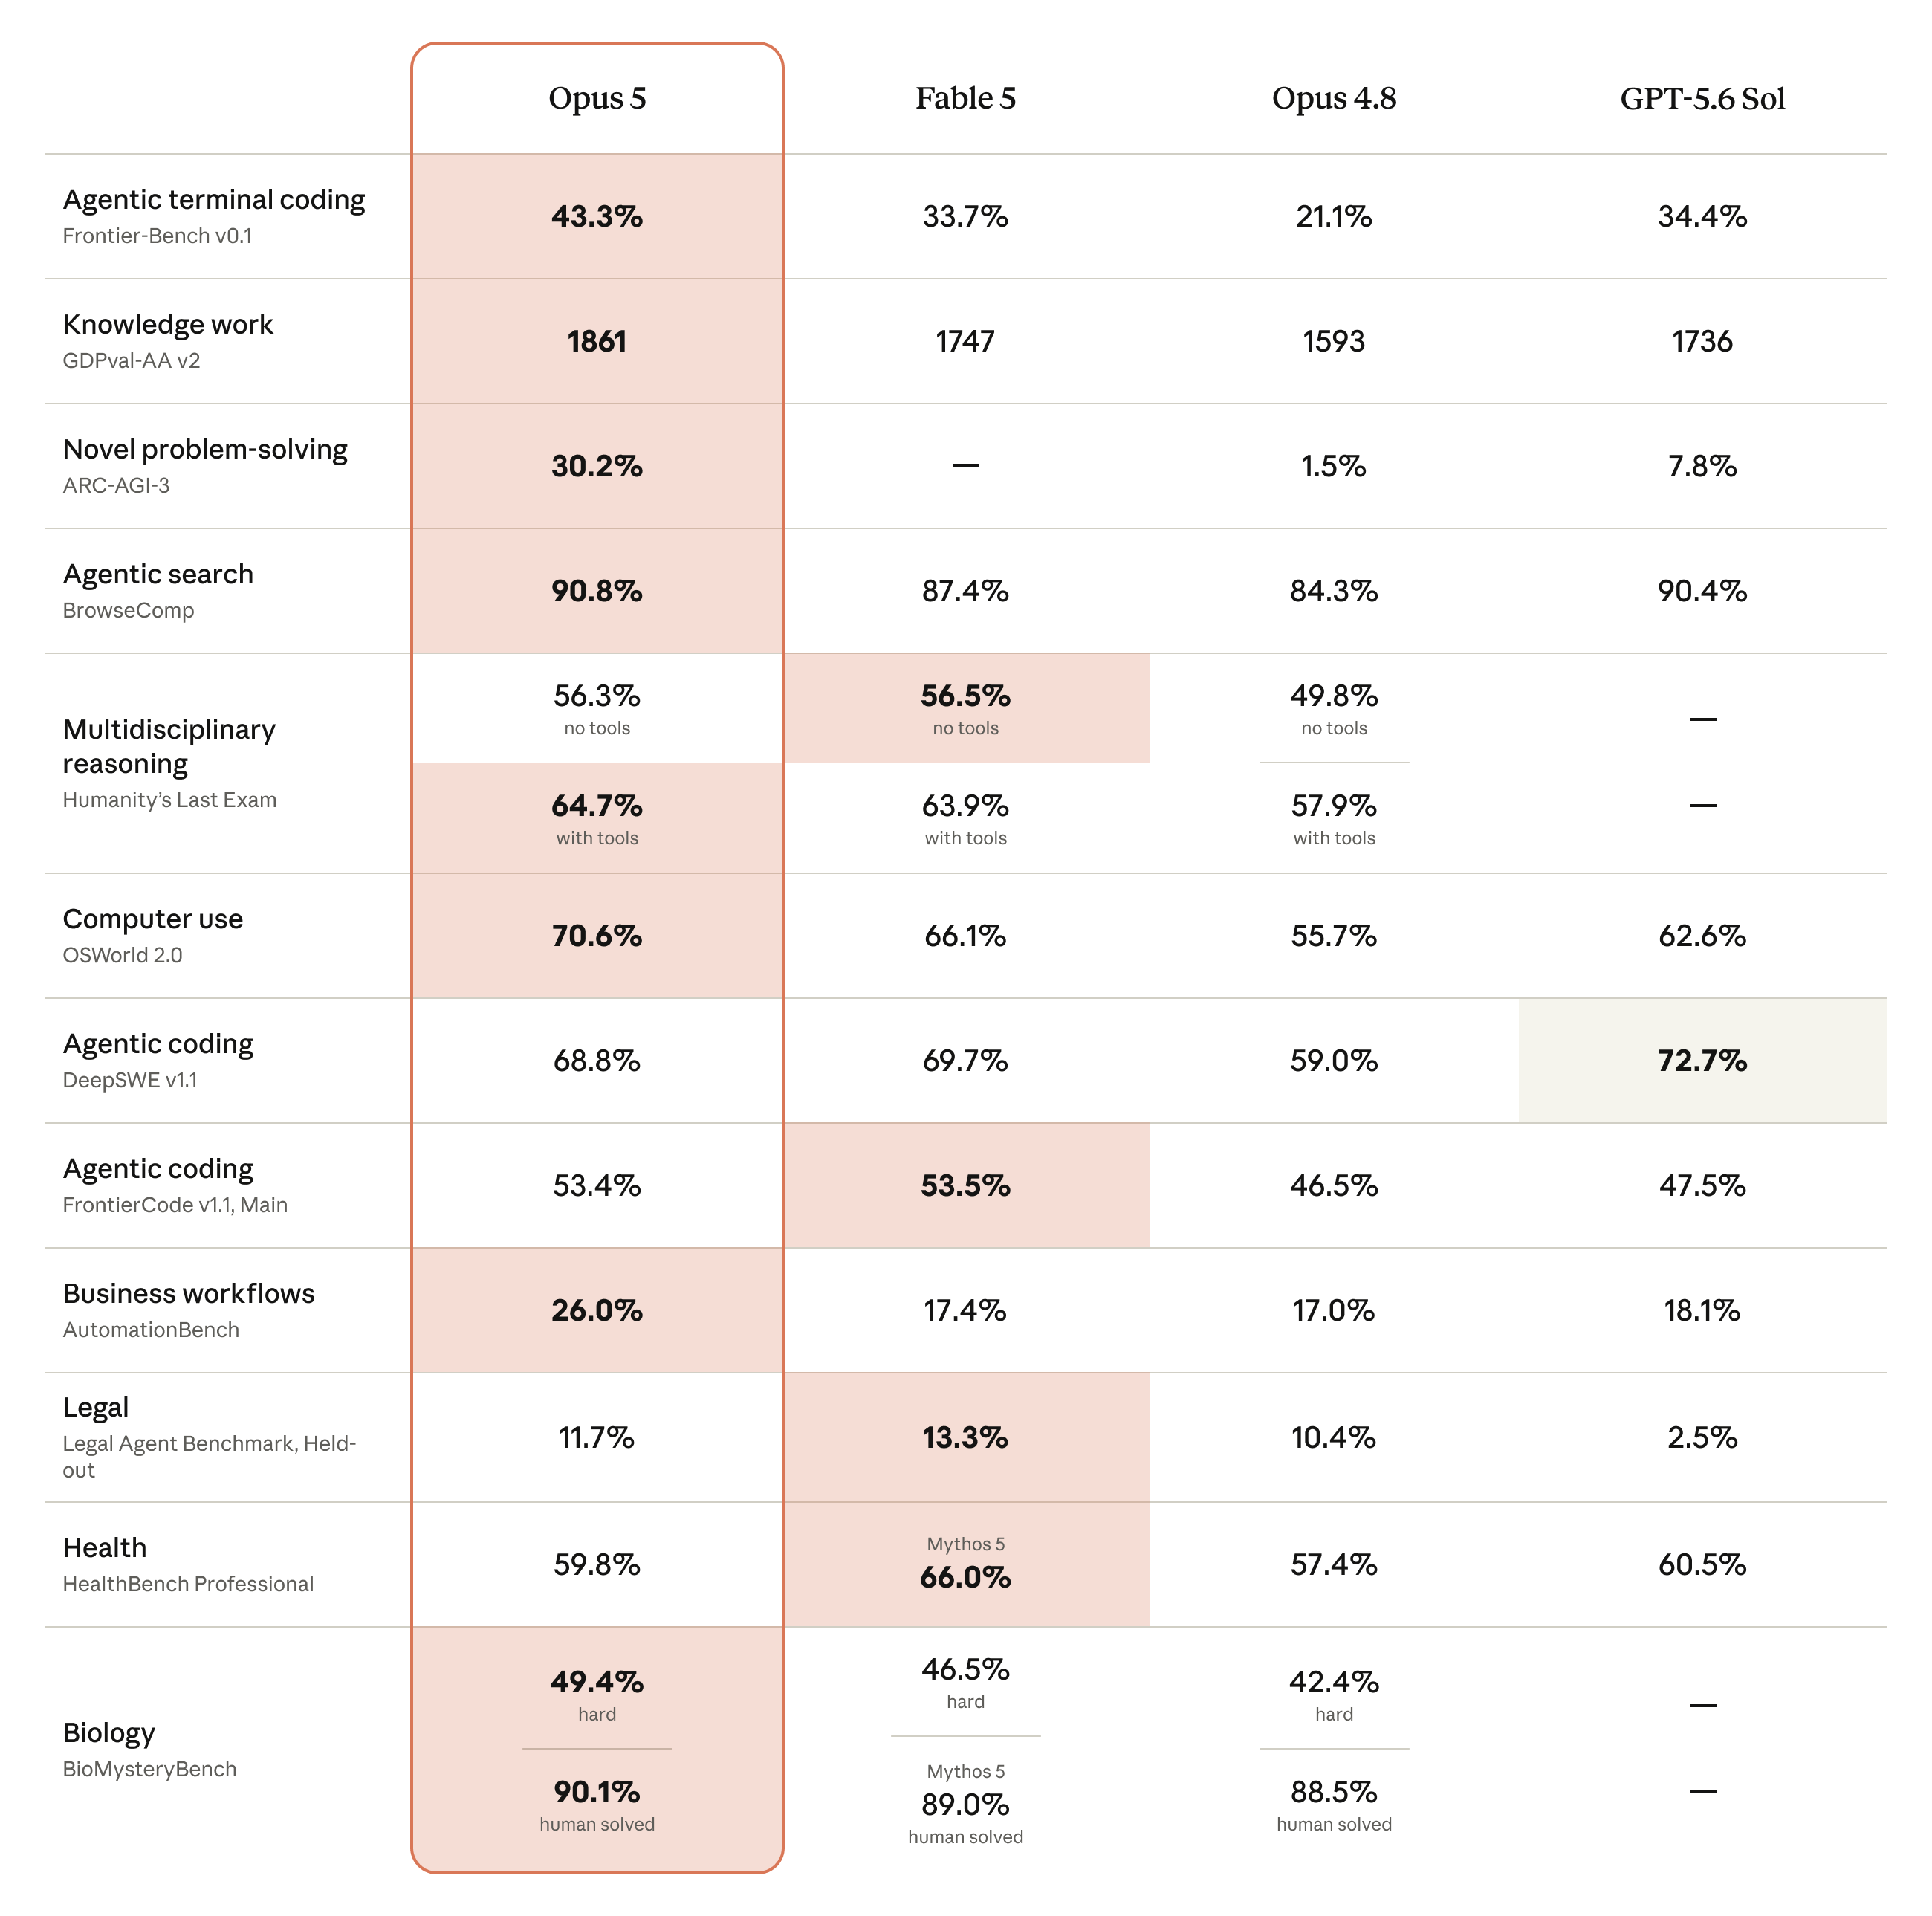
| Claude Opus 524 Jul 2026 · Anthropic | 90.8% | Introducing Claude Opus 5context compaction triggered at 200k tokens (card 8.10.2); the card's summary table prints the same valueSource image | Not yet |
| Kimi K316 Jul 2026 · Moonshot AI | 91.2% | Kimi K3: Open Frontier Intelligencecontext compaction as in the Claude model cards, triggered at 300K tokens (footnote 'BrowseComp'); reasoning effort max | Not yet |
| Kimi K316 Jul 2026 · Moonshot AI | 90.4% | Kimi K3: Open Frontier Intelligenceanother report, not charted; 1M-token context window, no context management | Not yet |
| GPT-5.6 Sol9 Jul 2026 · OpenAI | 90.4% | GPT-5.6: Frontier intelligence that scales with your ambitionPro and Ultra variants are separate columns, not recorded | Not yet |
| Claude Sonnet 530 Jun 2026 · Anthropic | 84.7% | Claude Sonnet 5 System Cardadaptive thinking, max effort, 10M-token limit with context compaction triggered at 200k (Table 8.1.A caption). The post shows only an effort-level curve without values | Not yet |
| Claude Fable 59 Jun 2026 · Anthropic | 87.4% | Introducing Claude Opus 5reported later; Fable 5's own post has no BrowseComp row and its card prints '-' for Fable 5; the Opus 5 card's summary table prints the same valueSource image | Not yet |
| Claude Mythos 59 Jun 2026 · Anthropic | 88.0% | Claude Fable 5 and Claude Mythos 5 System Cardsingle-agent; adaptive thinking, max effort, 10M-token limit, compaction at 200k tokens (8.14.2). The launch post's table has no BrowseComp row | Not yet |
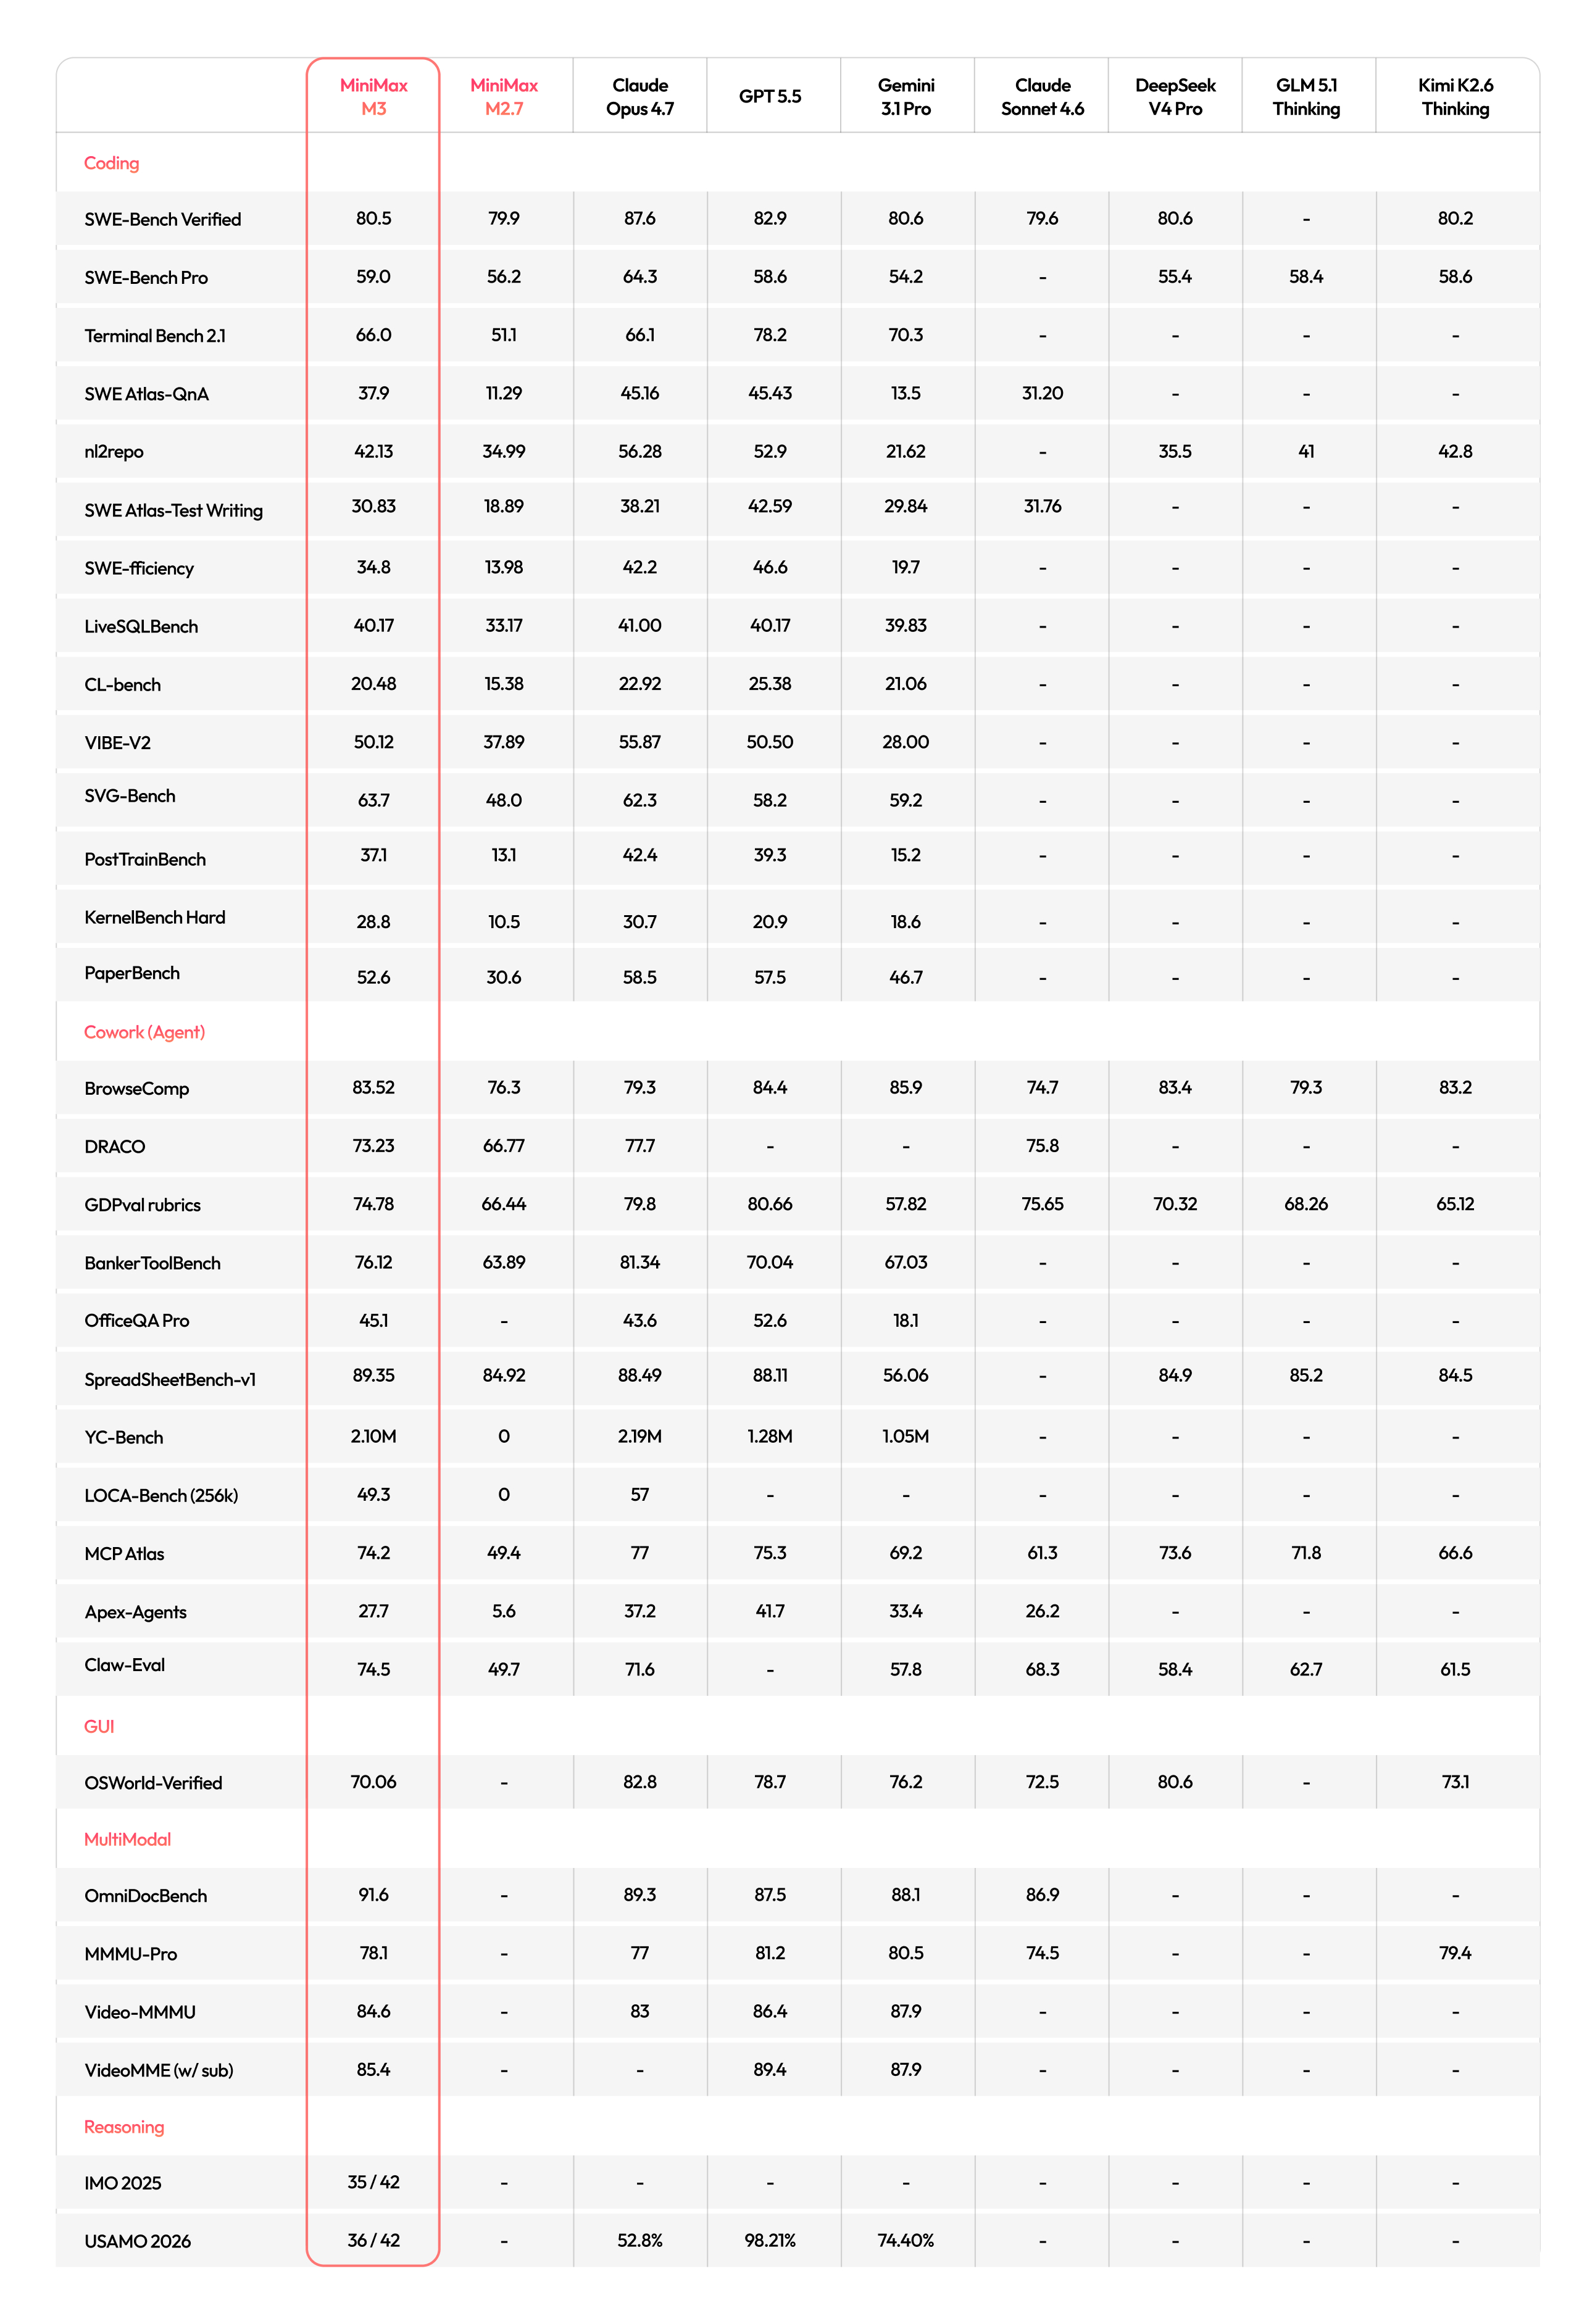
| MiniMax M31 Jun 2026 · MiniMax | 83.52% | MiniMax M3: Frontier Coding, 1M Context, Native Multimodality — All in One ModelWebExplorer agent framework; when token usage exceeds 64K, all history is discarded (evaluation notes)Source image | Not yet |
| Claude Opus 4.828 May 2026 · Anthropic | 84.3% | Claude Opus 4.8 System Cardsingle-agent; adaptive thinking, max effort, 10M-token limit, context compaction triggered at 200k tokens (8.10.2). The Opus 4.8 post's table has no BrowseComp row | Not yet |
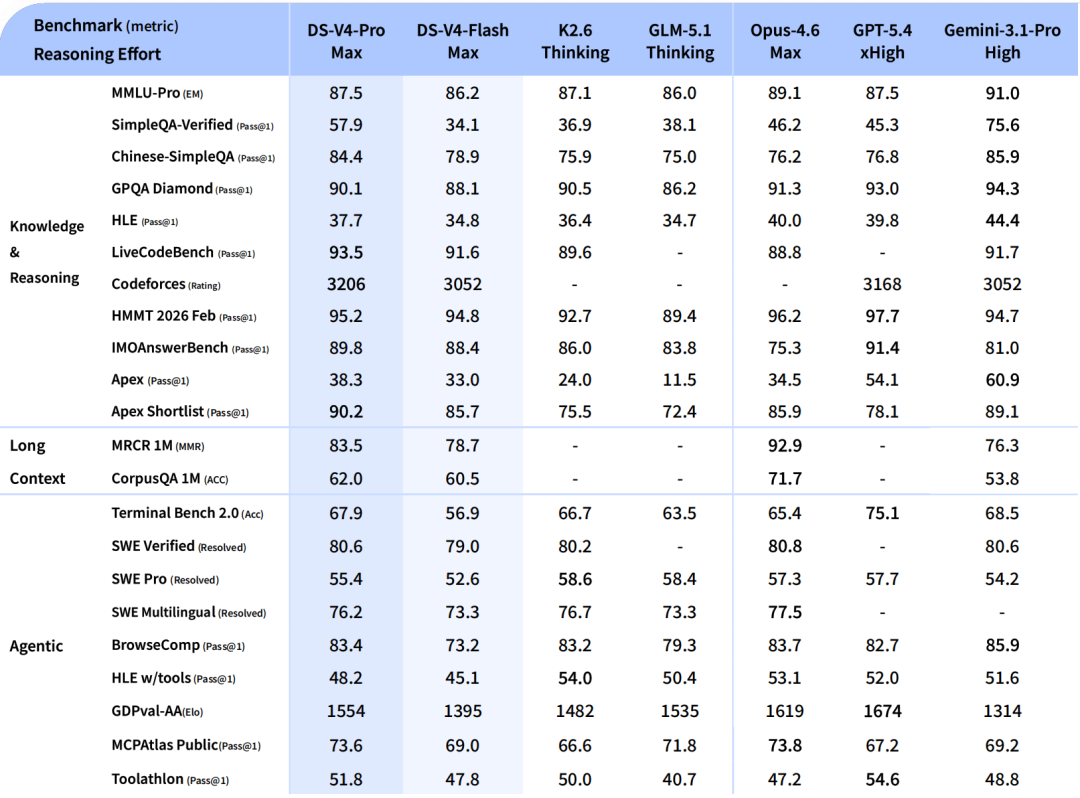
| DeepSeek-V4-Pro24 Apr 2026 · DeepSeek | 83.4% | DeepSeek V4 Preview ReleaseMax reasoning effort; context management not statedSource image | Not yet |
| GPT-5.523 Apr 2026 · OpenAI | 84.4% | Introducing GPT-5.5Pro and Ultra variants are separate columns, not recorded | Not yet |
| Kimi K2.620 Apr 2026 · Moonshot AI | 83.2% | Kimi K2.6: Advancing Open-Source Codingcontext management, discard-all strategy as for Kimi K2.5 and DeepSeek-V3.2 (footnote 3) | Not yet |
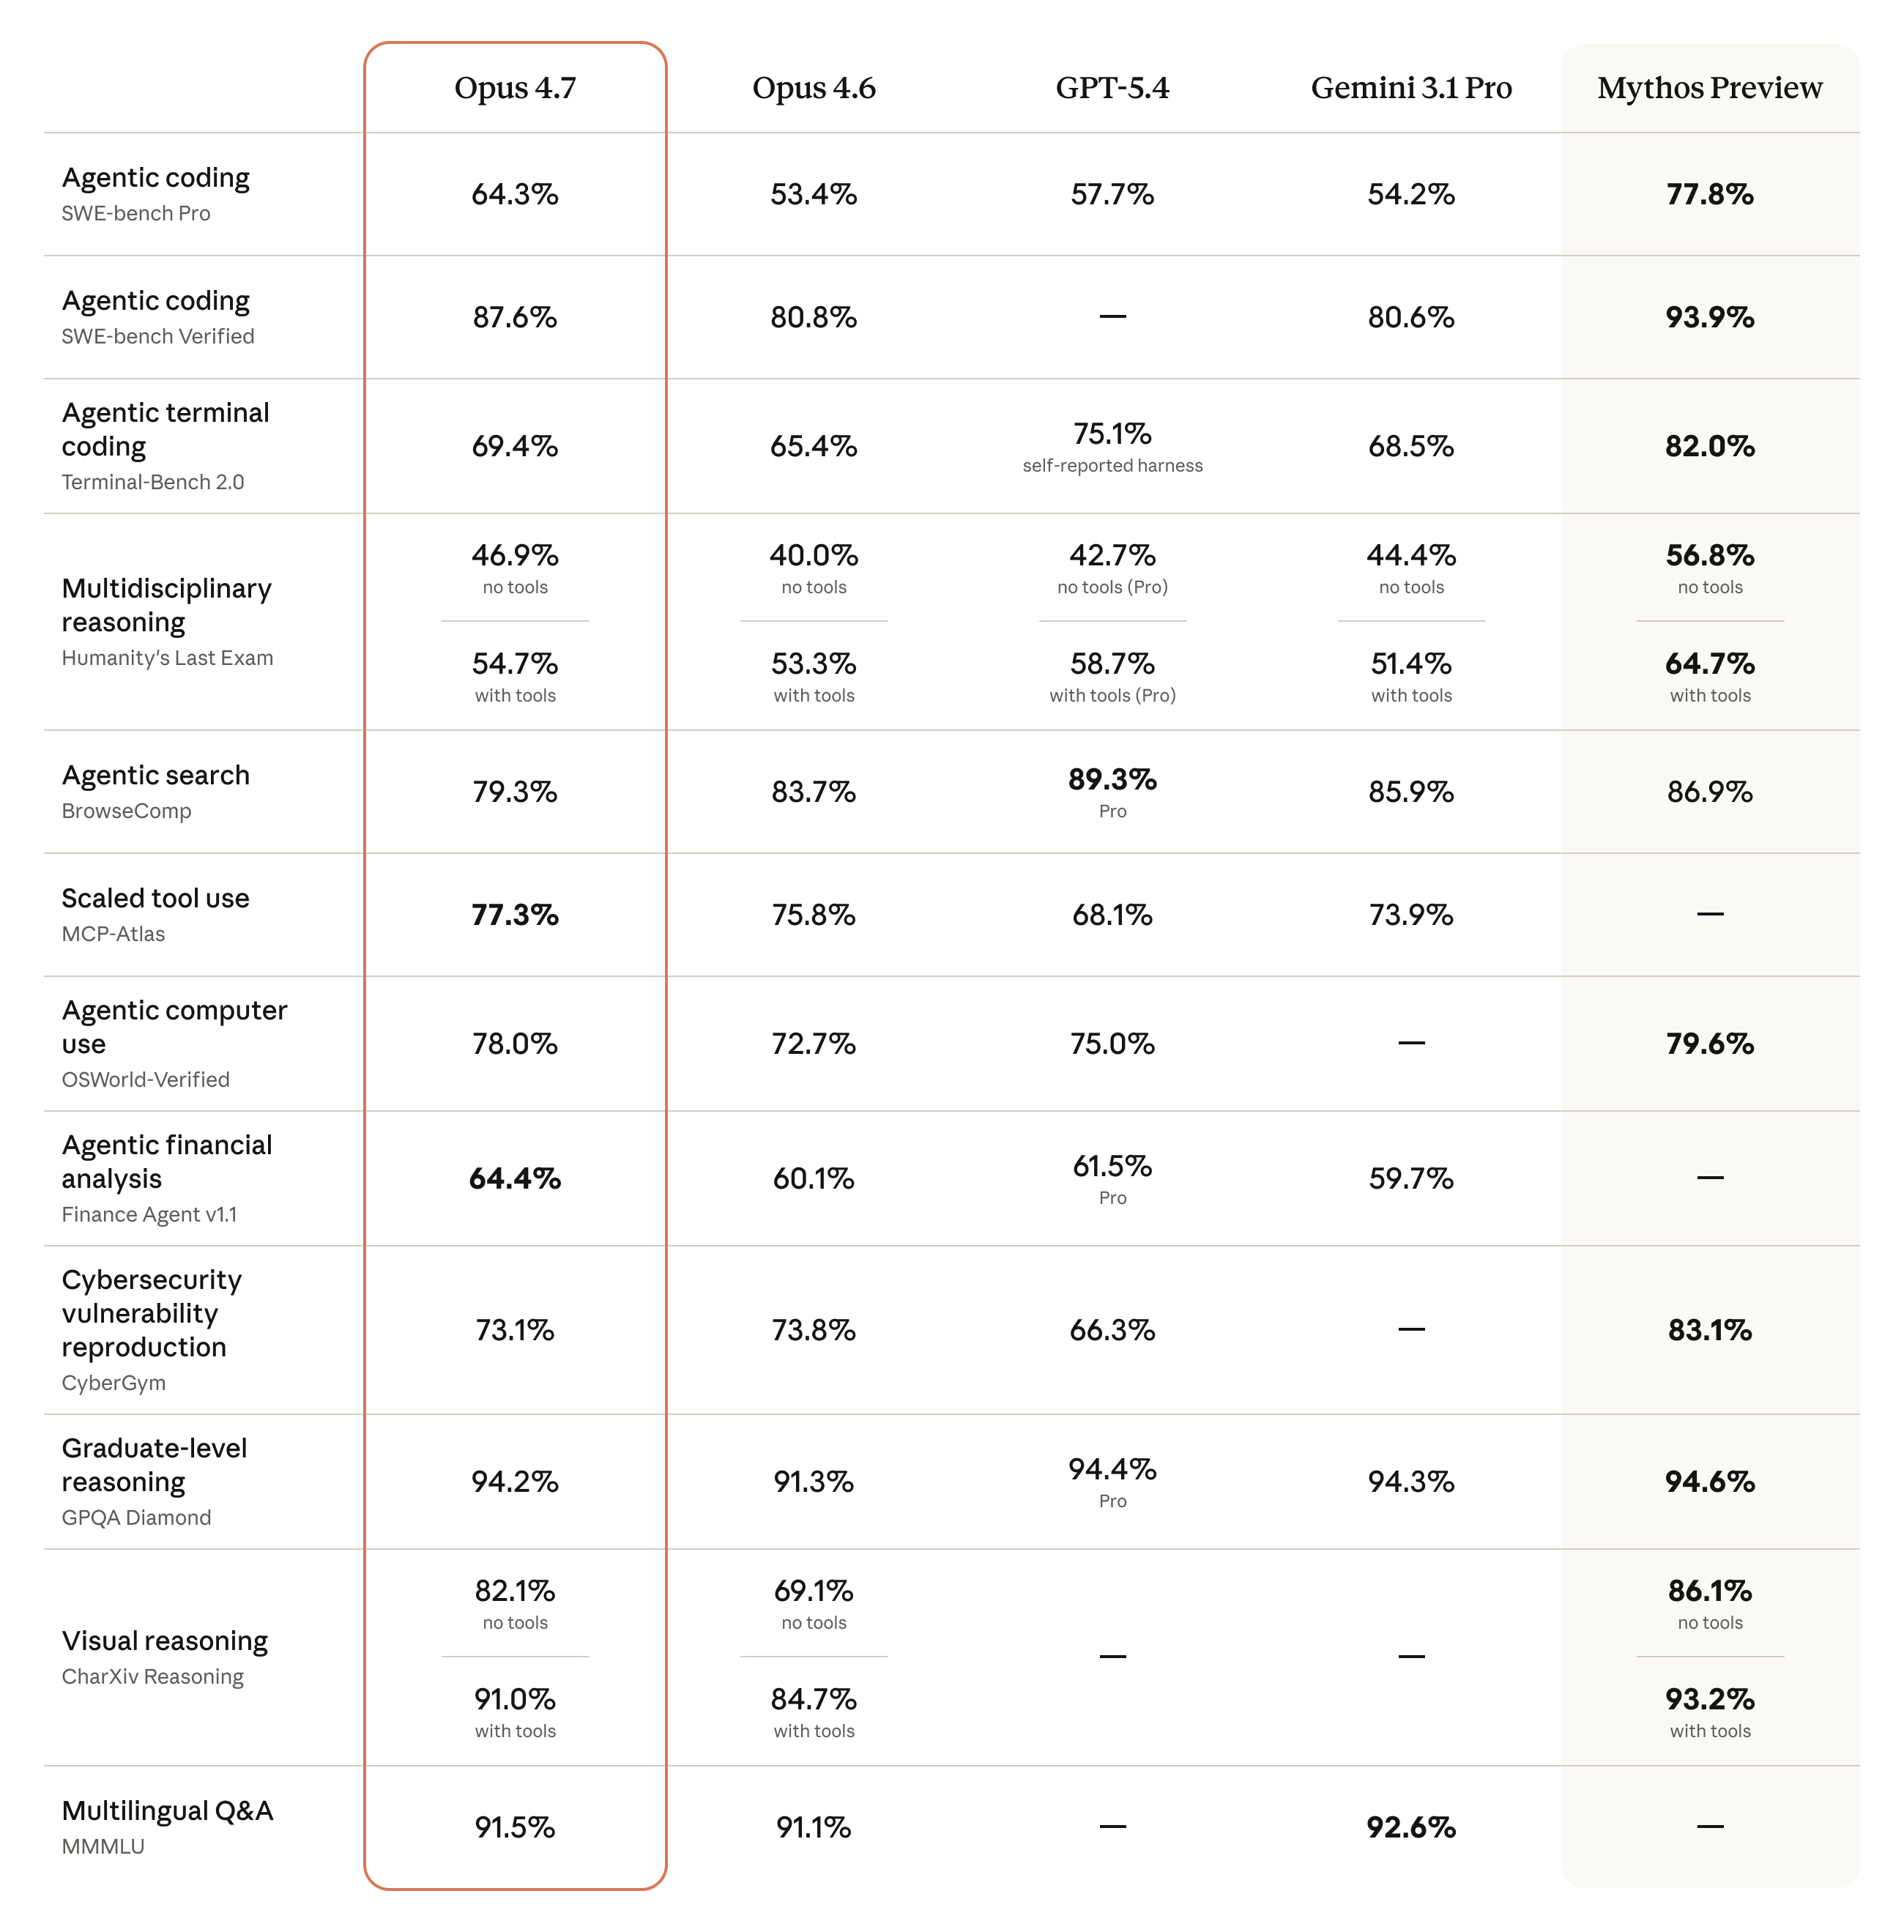
| Claude Opus 4.716 Apr 2026 · Anthropic | 79.3% | Introducing Claude Opus 4.7system card 8.8.2: thinking off, max effort, 10M token limit, context compaction triggered at 200k tokensSource image | Not yet |
| Claude Opus 4.716 Apr 2026 · Anthropic | 79.8% | Claude Opus 4.8 System Cardreported later; another report, not charted; re-run: footnote 27 'Changes to the Opus 4.7 BrowseComp score are due to a new blocklist, context compaction at 200k tokens and using adaptive thinking.' | Not yet |
| Claude Mythos Preview7 Apr 2026 · Anthropic | 86.9% | Introducing Claude Opus 4.7reported later; the Mythos Preview post links no system card and prints no BrowseComp; Opus 4.7 post is the earliest reportSource image | Not yet |
| Claude Mythos Preview7 Apr 2026 · Anthropic | 87.9% | Claude Fable 5 and Claude Mythos 5 System Cardreported later; another report, not charted | Not yet |
| GPT-5.45 Mar 2026 · OpenAI | 82.7% | Introducing GPT-5.4Pro and Ultra variants are separate columns, not recorded | Not yet |
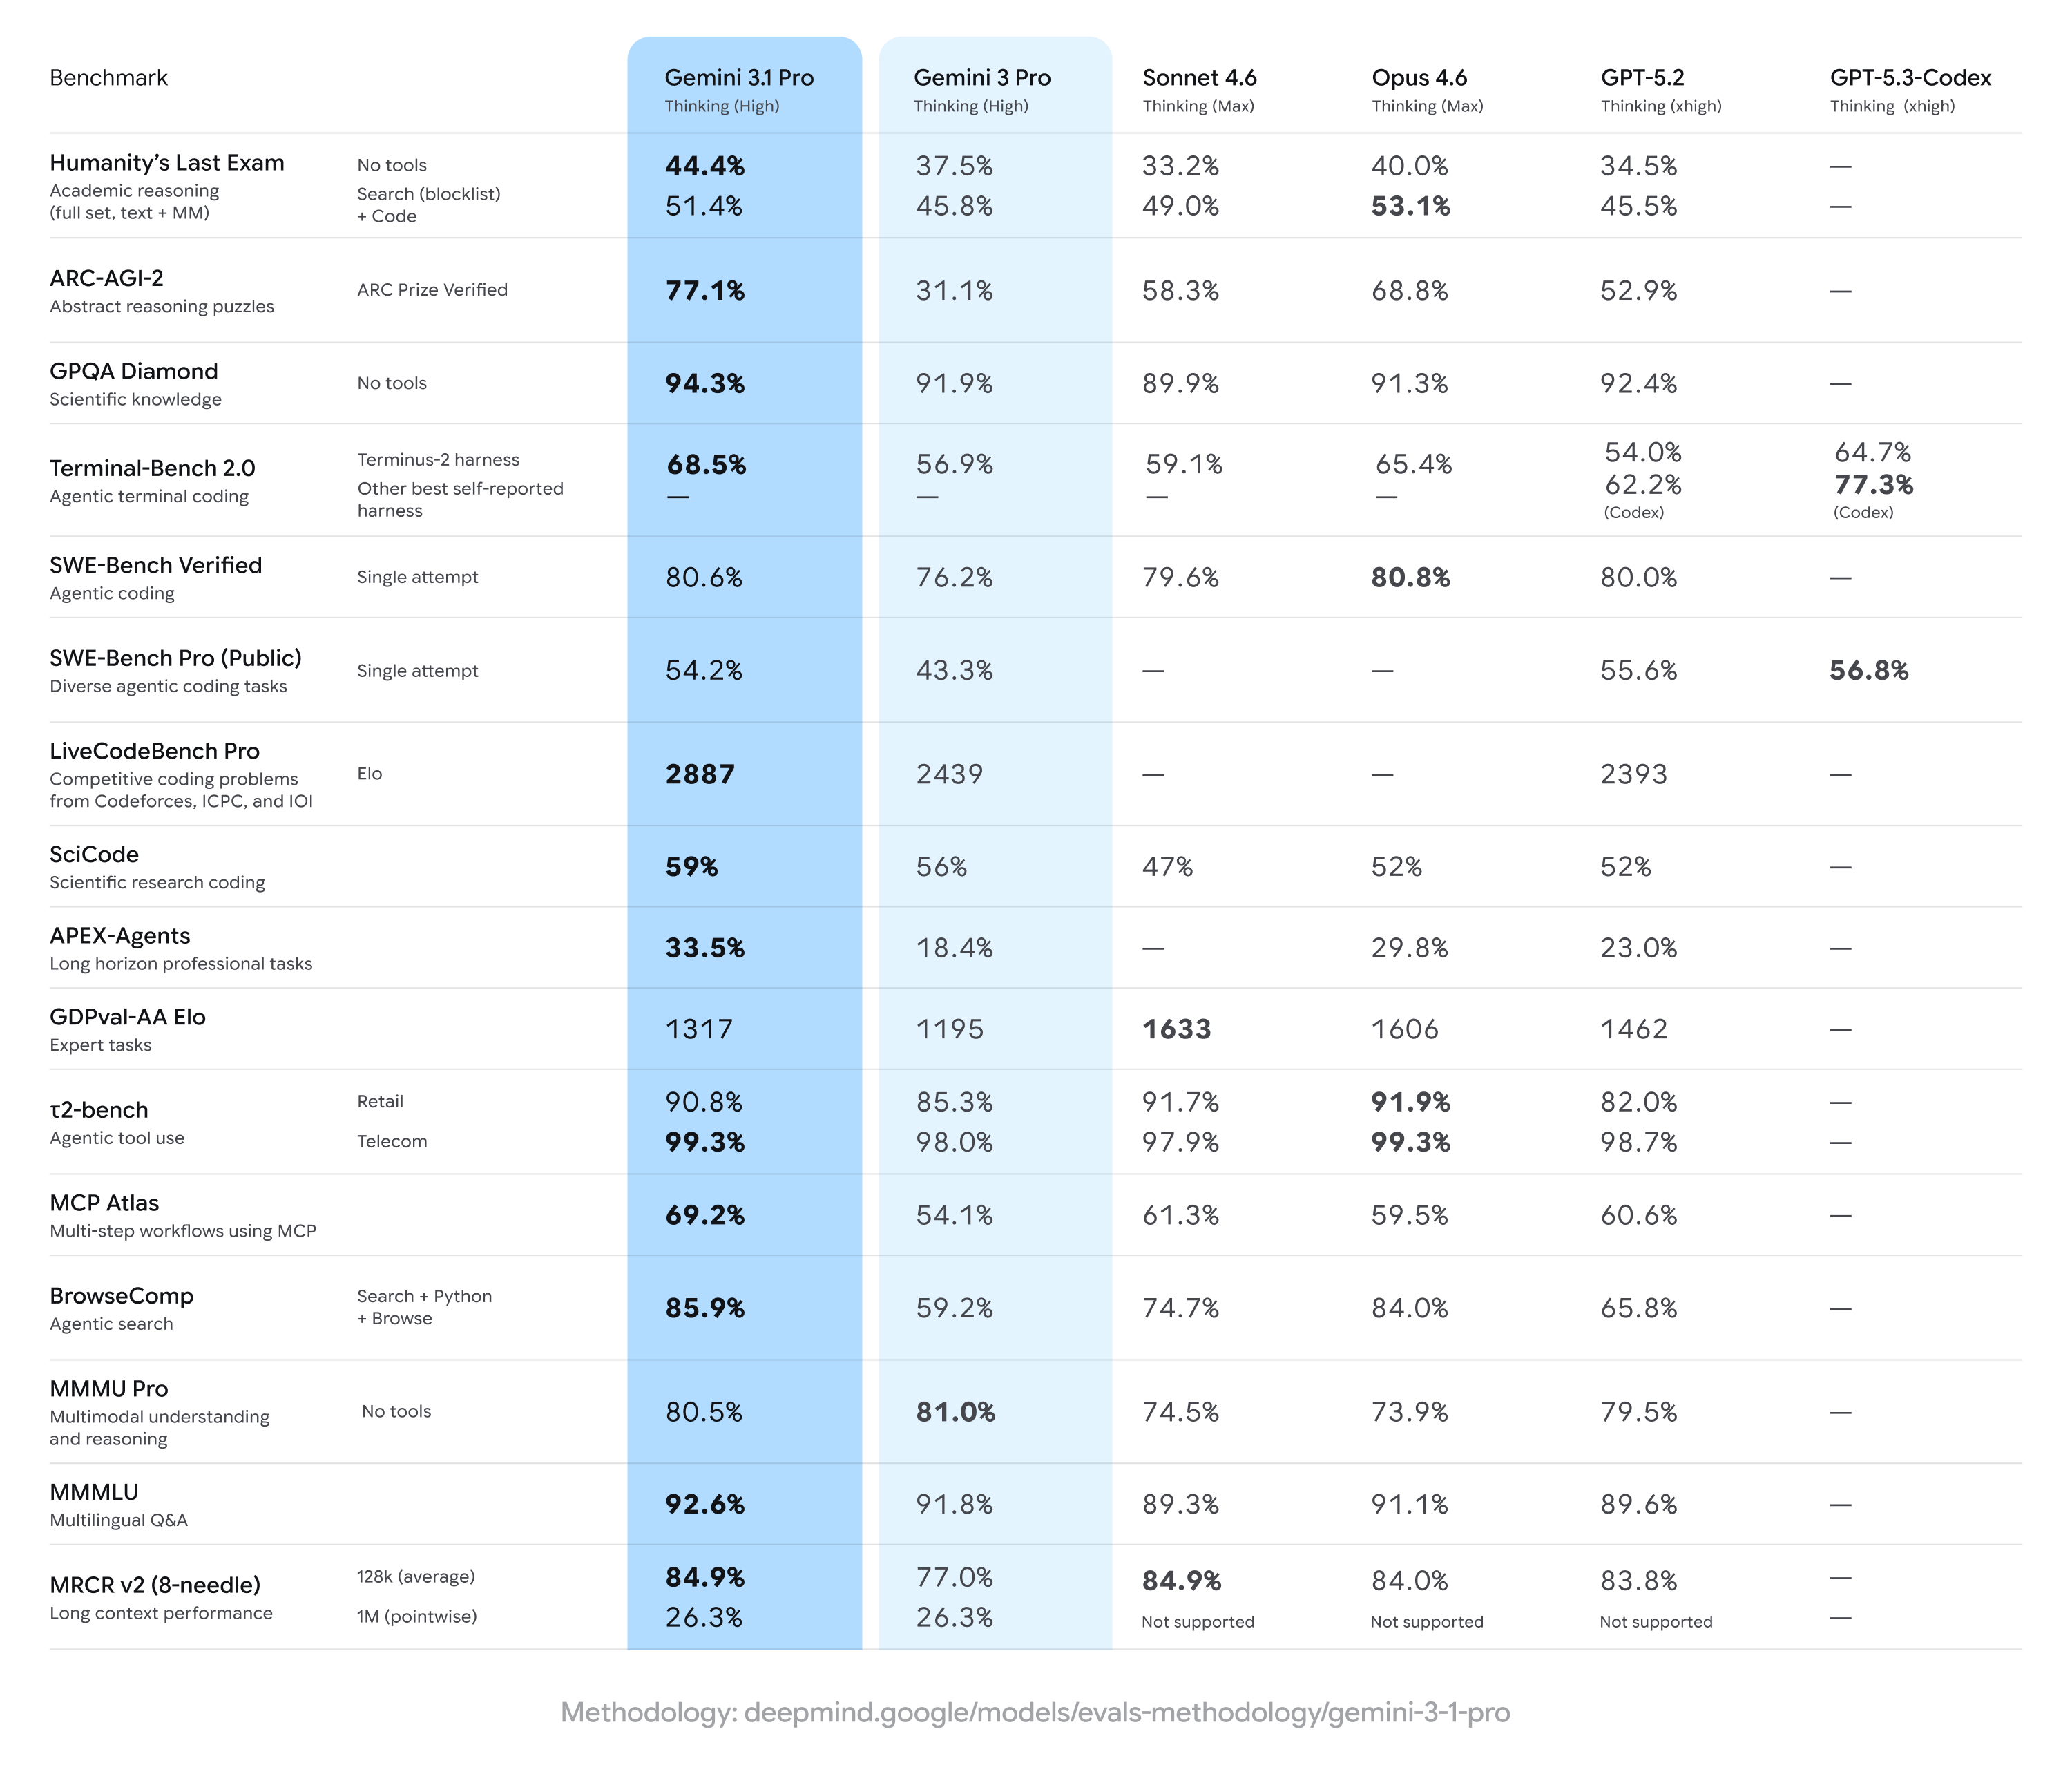
| Gemini 3.1 Pro19 Feb 2026 · Google | 85.9% | Gemini 3.1 Pro: A smarter model for your most complex tasksThinking (High); search + Python + browseSource image | Not yet |
| MiniMax M2.512 Feb 2026 · MiniMax | 76.3% | MiniMax M2.5: Built for Real-World Productivity.with context management: WebExplorer agent framework; when token usage exceeds 30% of the maximum context, all history is discarded (evaluation notes) | Not yet |
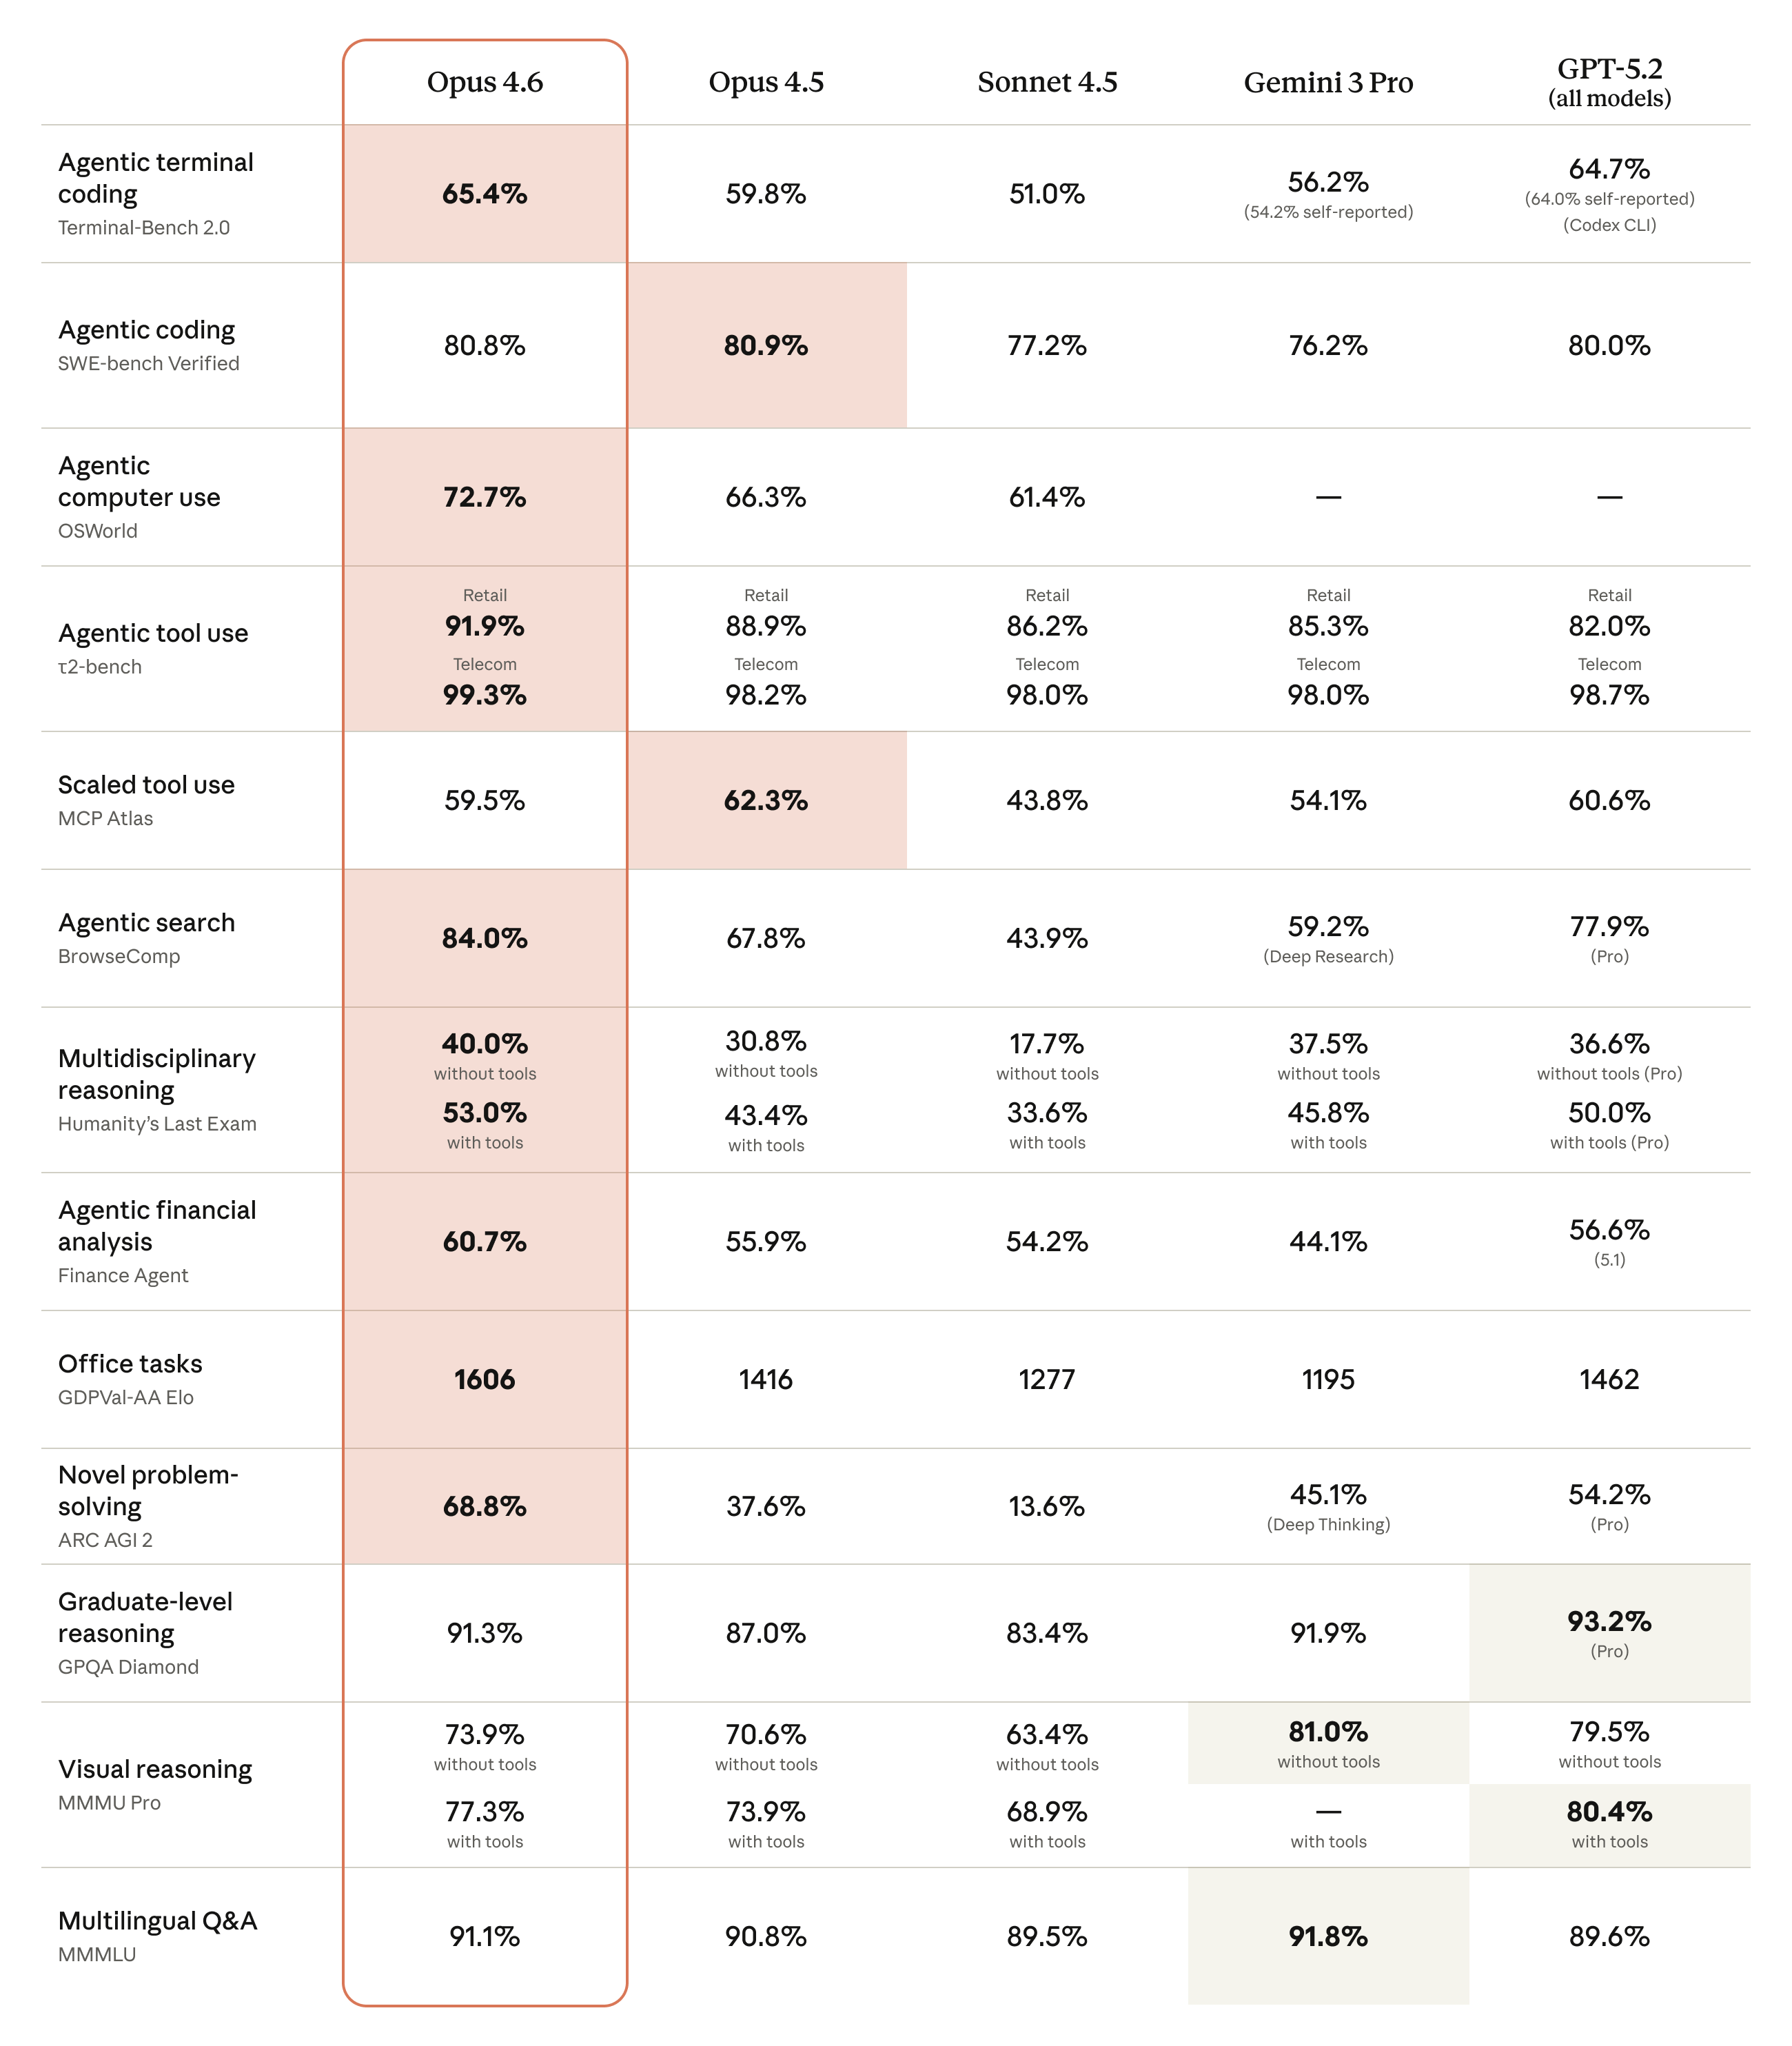
| Claude Opus 4.65 Feb 2026 · Anthropic | 84.0% | Claude Opus 4.6web search, web fetch, programmatic tool calling, context compaction triggered at 50k tokens up to 10M total tokens, max effort, no thinking (footnote)Source image | Not yet |
| Claude Opus 4.65 Feb 2026 · Anthropic | 83.7% | Claude Opus 4.6 System Cardanother report, not charted; card updated March 6, 2026 after an improved cheating-detection pipeline (changelog: 83.97% -> 83.73%); thinking disabled, compaction at 50k up to 10M tokens, max effort | Not yet |
| Kimi K2.527 Jan 2026 · Moonshot AI | 74.9% | Kimi K2.5: Visual Agentic Intelligencewith context management, discard-all strategy (footnote 3); the headline chart at the top of the post shows this figure | Not yet |
| Kimi K2.527 Jan 2026 · Moonshot AI | 60.6% | Kimi K2.5: Visual Agentic Intelligenceanother report, not charted; no context management: tasks exceeding the context length counted as failed | Not yet |
| GPT-5.211 Dec 2025 · OpenAI | 65.8% | Introducing GPT-5.2Pro and Ultra variants are separate columns, not recorded | Not yet |
| Claude Opus 4.524 Nov 2025 · Anthropic | 67.8% | Claude Opus 4.6reported later; Opus 4.5's own post and card report only BrowseComp-Plus (a different benchmark); the Opus 4.6 system card (Figure 2.21.1.A) prints the same valueSource image | Not yet |
| Gemini 3 Pro18 Nov 2025 · Google | 59.2% | Gemini 3.1 Pro: A smarter model for your most complex tasksreported later; Gemini 3 Pro's own post prints no BrowseComp; earliest Google report. Anthropic's Opus 4.6 table labels the same 59.2% as Gemini 3 Pro '(Deep Research)'Source image | Not yet |
| Kimi K2 Thinking6 Nov 2025 · Moonshot AI | 60.2% | Introducing Kimi K2 Thinkingsearch, code-interpreter and web-browsing tools; up to 300 steps, 24k reasoning tokens per step; context management hides all previous tool outputs when input exceeds 256k (footnote 4e); Hugging Face blocked | Not yet |
| Claude Sonnet 4.529 Sep 2025 · Anthropic | 43.9% | Claude Opus 4.6reported later; Sonnet 4.5's own post and system card print no BrowseComp; the Opus 4.6 system card (Figure 2.21.1.A) prints the same valueSource image | Not yet |
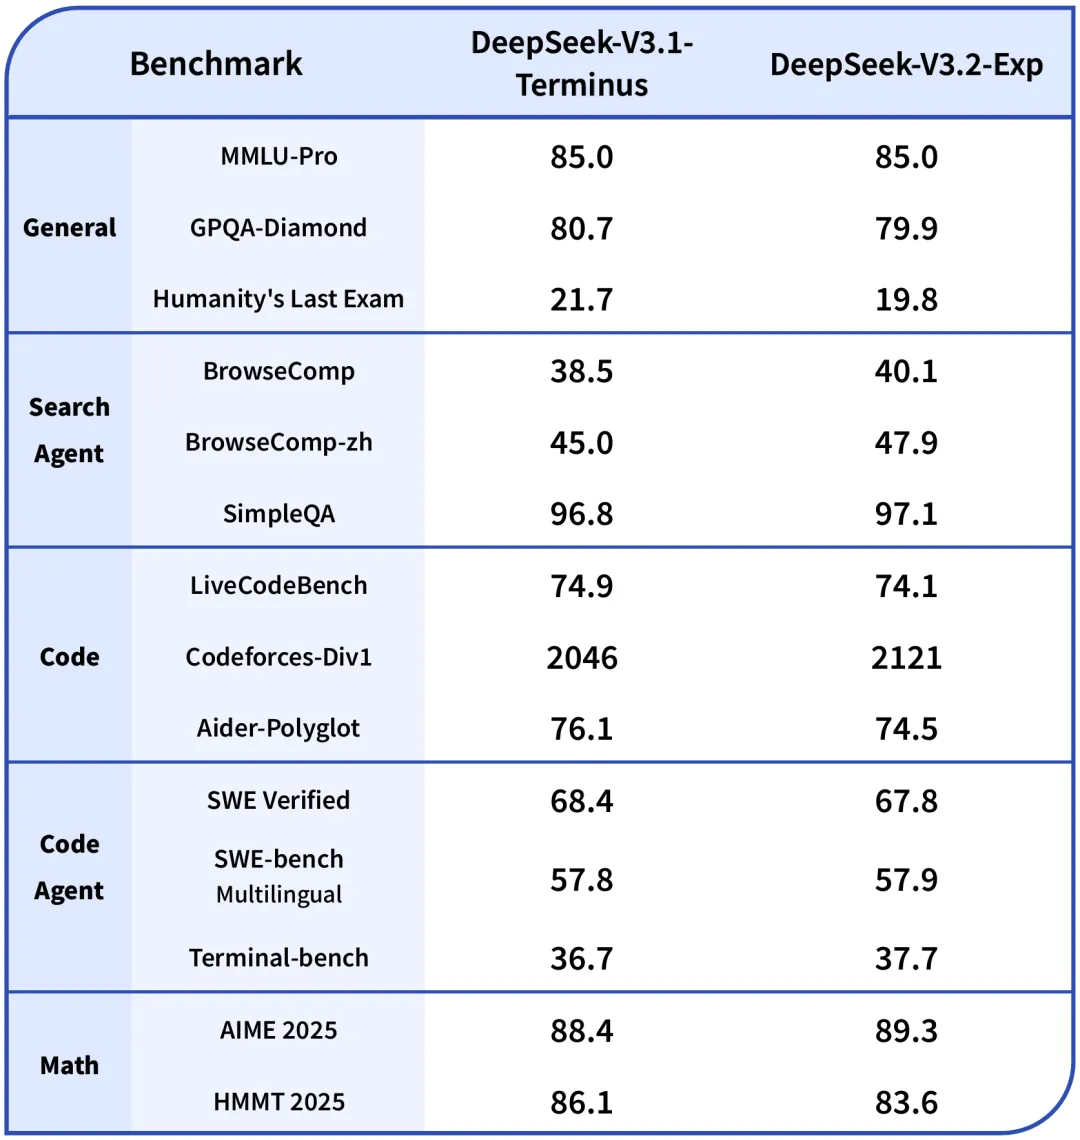
| DeepSeek-V3.2-Exp29 Sep 2025 · DeepSeek | 40.1% | Introducing DeepSeek-V3.2-ExpSource image | Not yet |
Benchmark
openai.comHigher is better