Qwen3-Max-Thinking
- Made by
- Alibaba
- Released
- Announced in
- Pushing Qwen3-Max-Thinking Beyond its Limitsqwen.ai
- Event
- Qwen3-Max-Thinking
- API record
- /api/v1/models/qwen3-max-thinking
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
| Humanity's Last ExamNo tools · text-only subset | 30.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| heavy mode: test-time scaling over parallel trajectories; text-only subset · parallel test-time compute | 36.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Humanity's Last ExamWith tools · text-only subset; with search, HLE-related websites blocked | 49.8% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| heavy mode: test-time scaling over parallel trajectories; with search · parallel test-time compute | 58.3% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Verified | 75.3% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| GPQA Diamondwithout test-time scaling | 87.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| heavy mode: multi-round test-time scaling over parallel trajectories · parallel test-time compute | 92.8% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
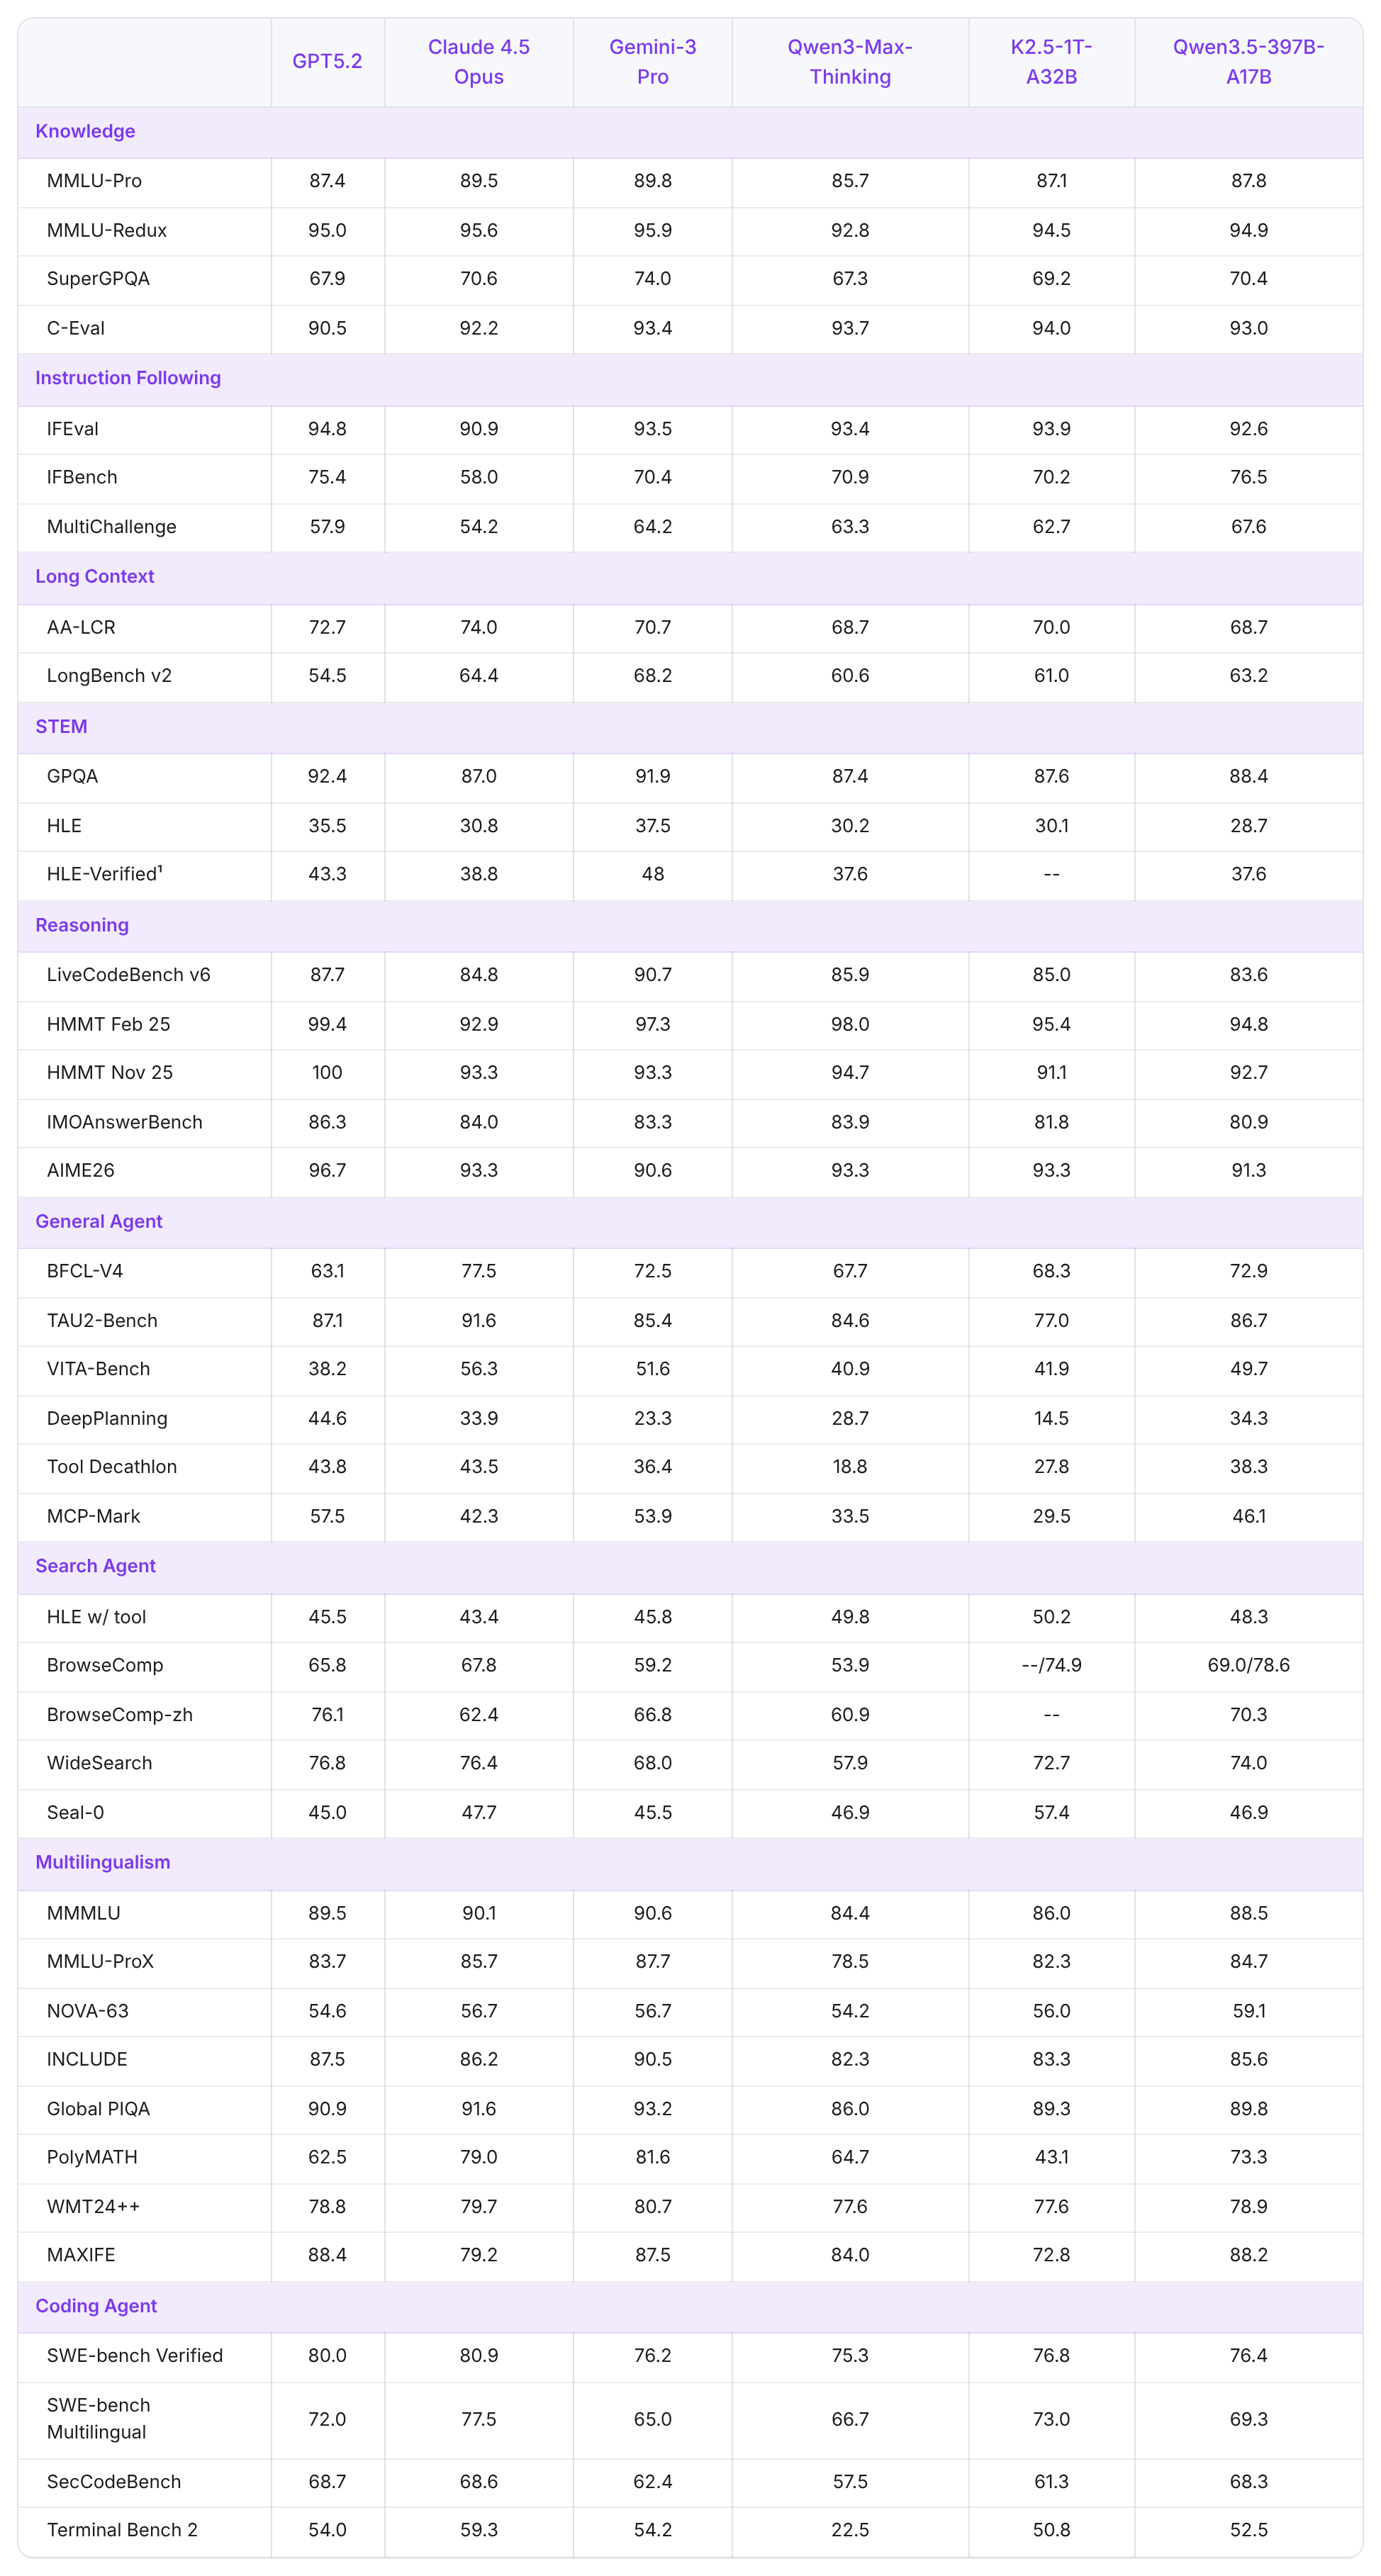
| BrowseCompsearch agent; context folding at 256K tokens · reported later, in Qwen3.5: Towards Native Multimodal Agents | 53.9% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 2.0reported later, in Qwen3.5: Towards Native Multimodal Agents | 22.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| MMLU-Pro | 85.7% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| HMMT February 2025No tools | 98.0% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| LiveCodeBenchLiveCodeBench v6, problems from Feb to May 2025 | 85.9% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| heavy mode: test-time scaling over parallel trajectories · parallel test-time compute | 91.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by Alibaba
- Pushing Qwen3-Max-Thinking Beyond its Limitsqwen.ai · 26 Jan 2026
Original image 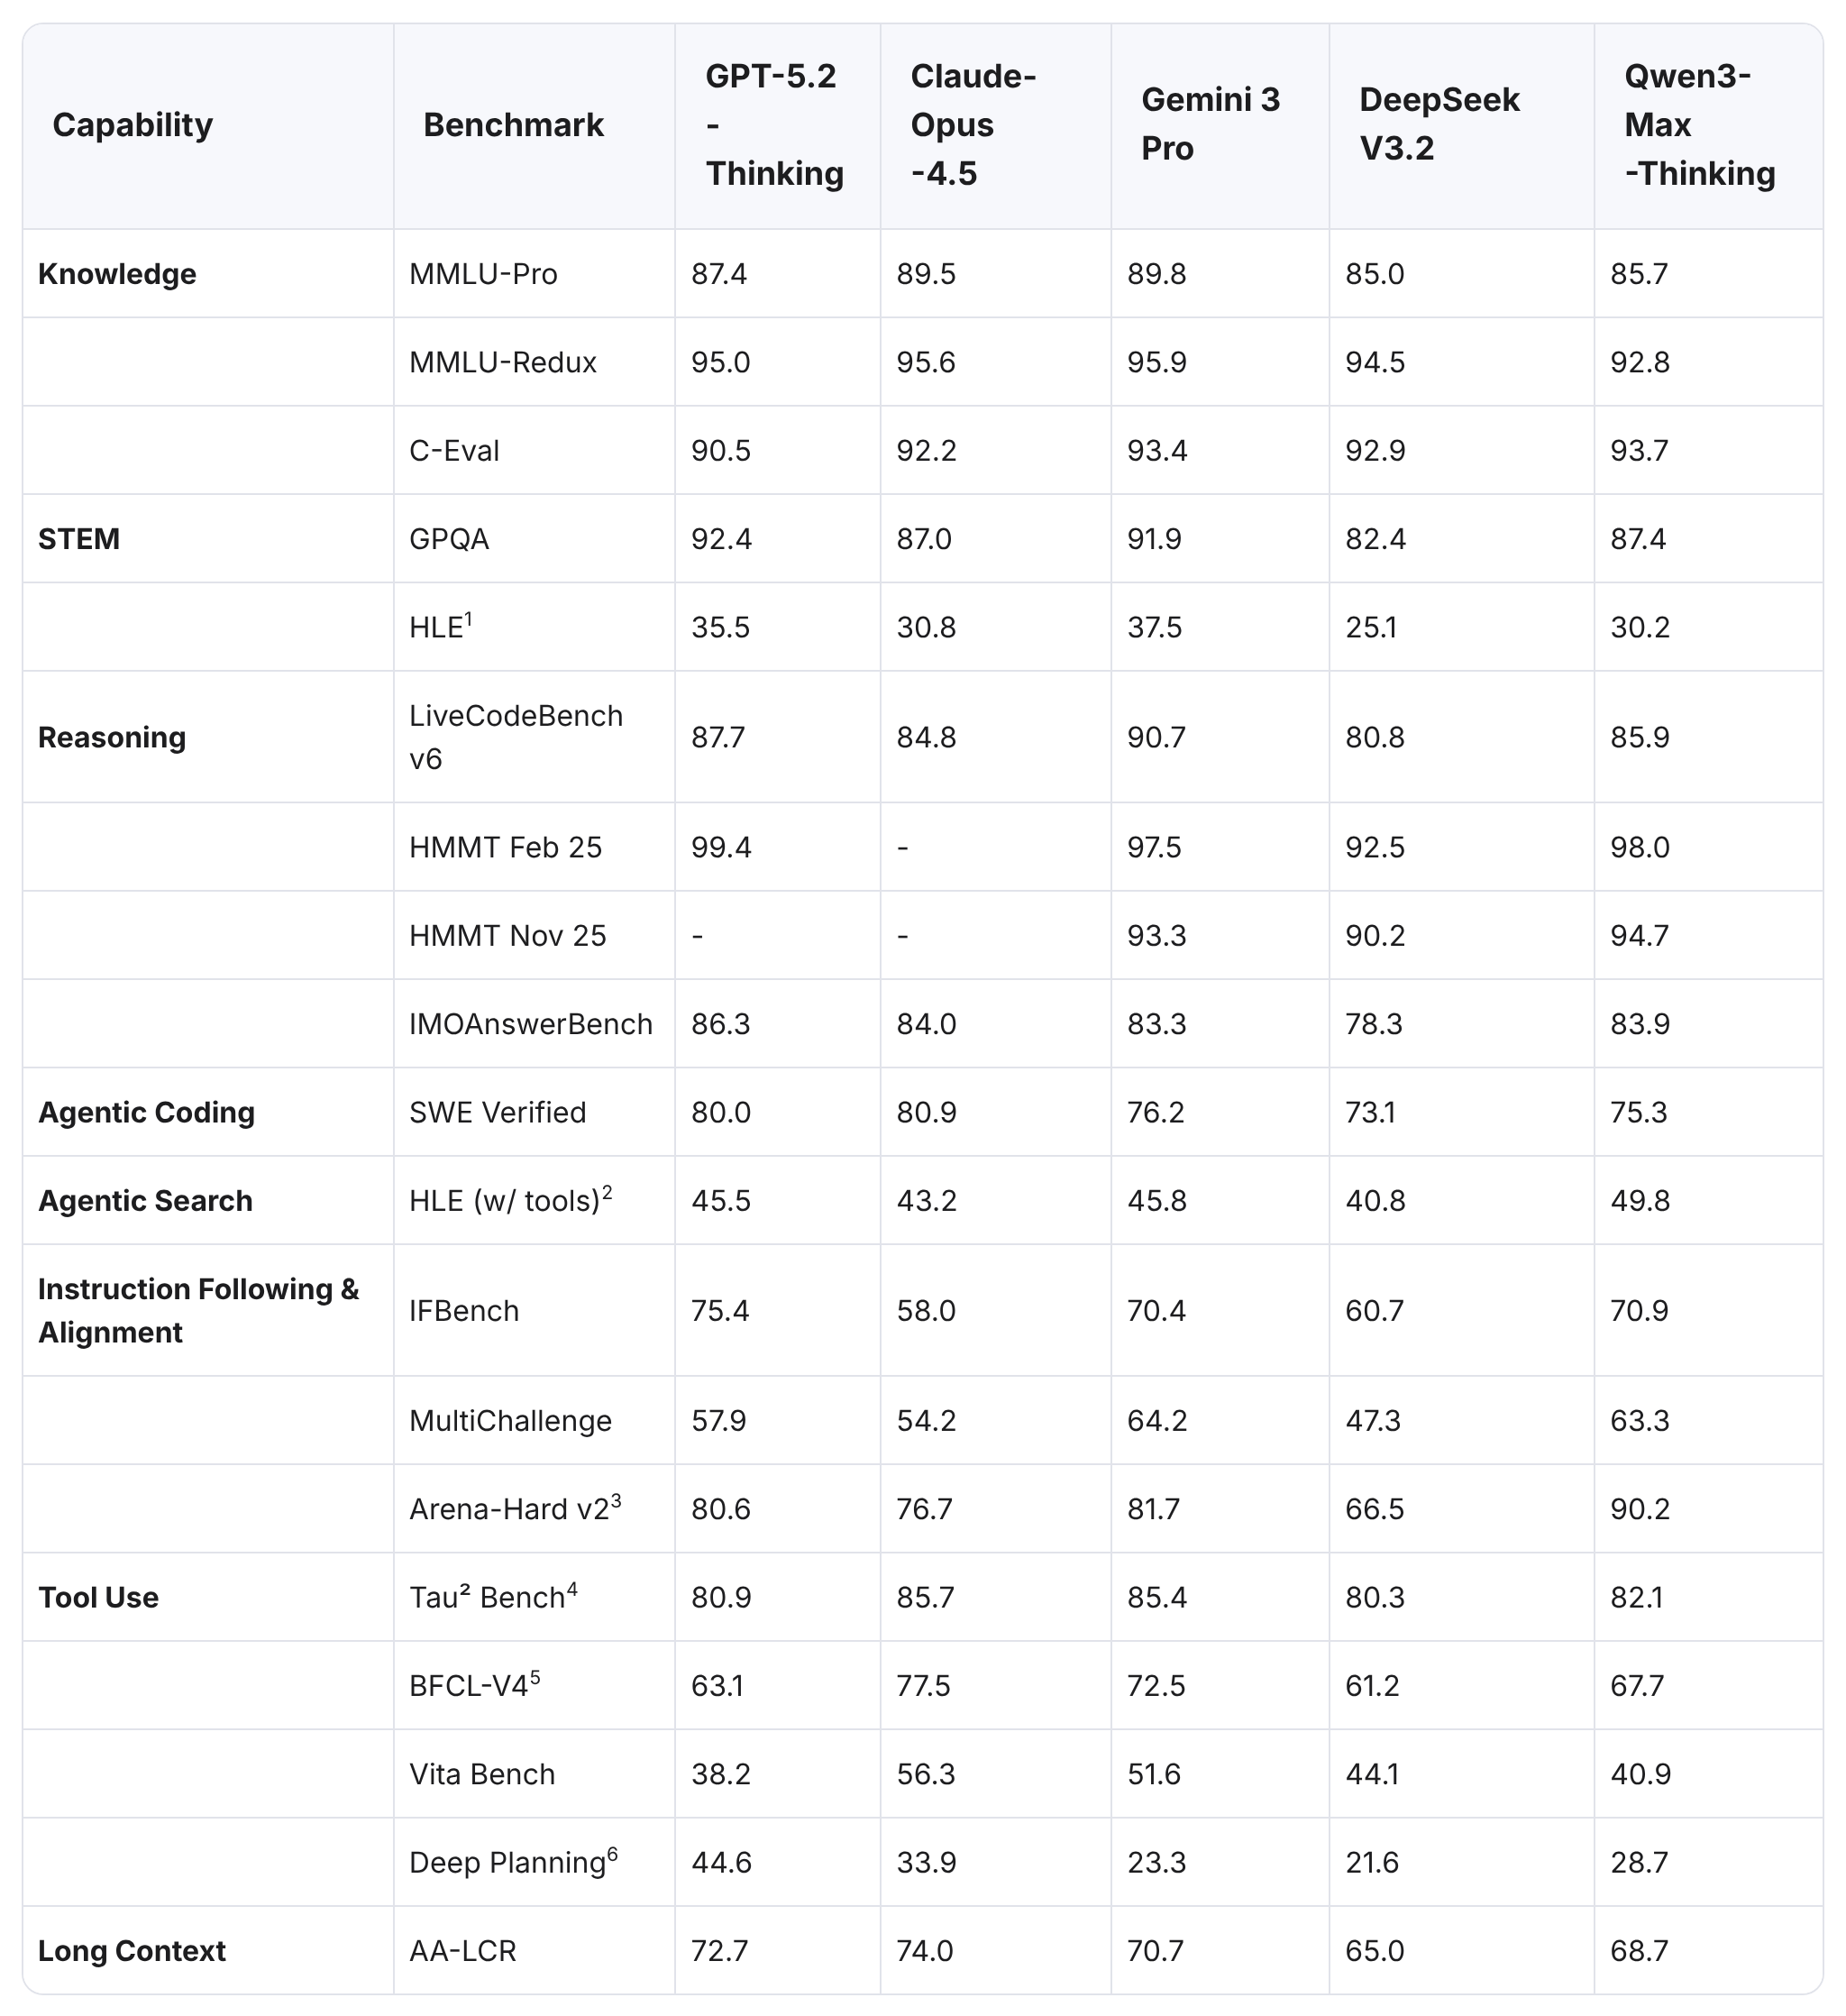
Our capture of the source - Qwen3.5: Towards Native Multimodal Agentsqwen.ai · 16 Feb 2026
Our capture of the source