Humanity's Last Exam
Created by Center for AI Safety and Scale AI, 23 Jan 2025 · Higher is better · Website
- OpenAI
- Other labs
- Reported in a later post or card
Results
| Model | Score | Source |
|---|---|---|
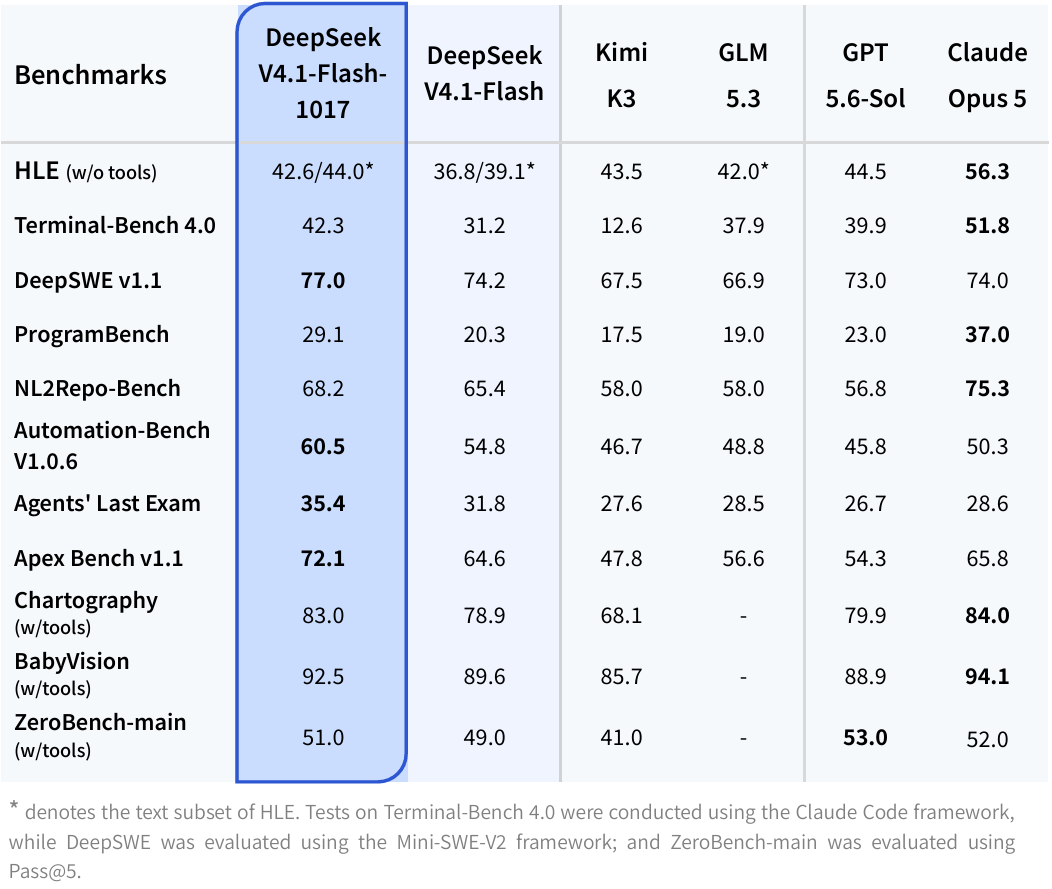
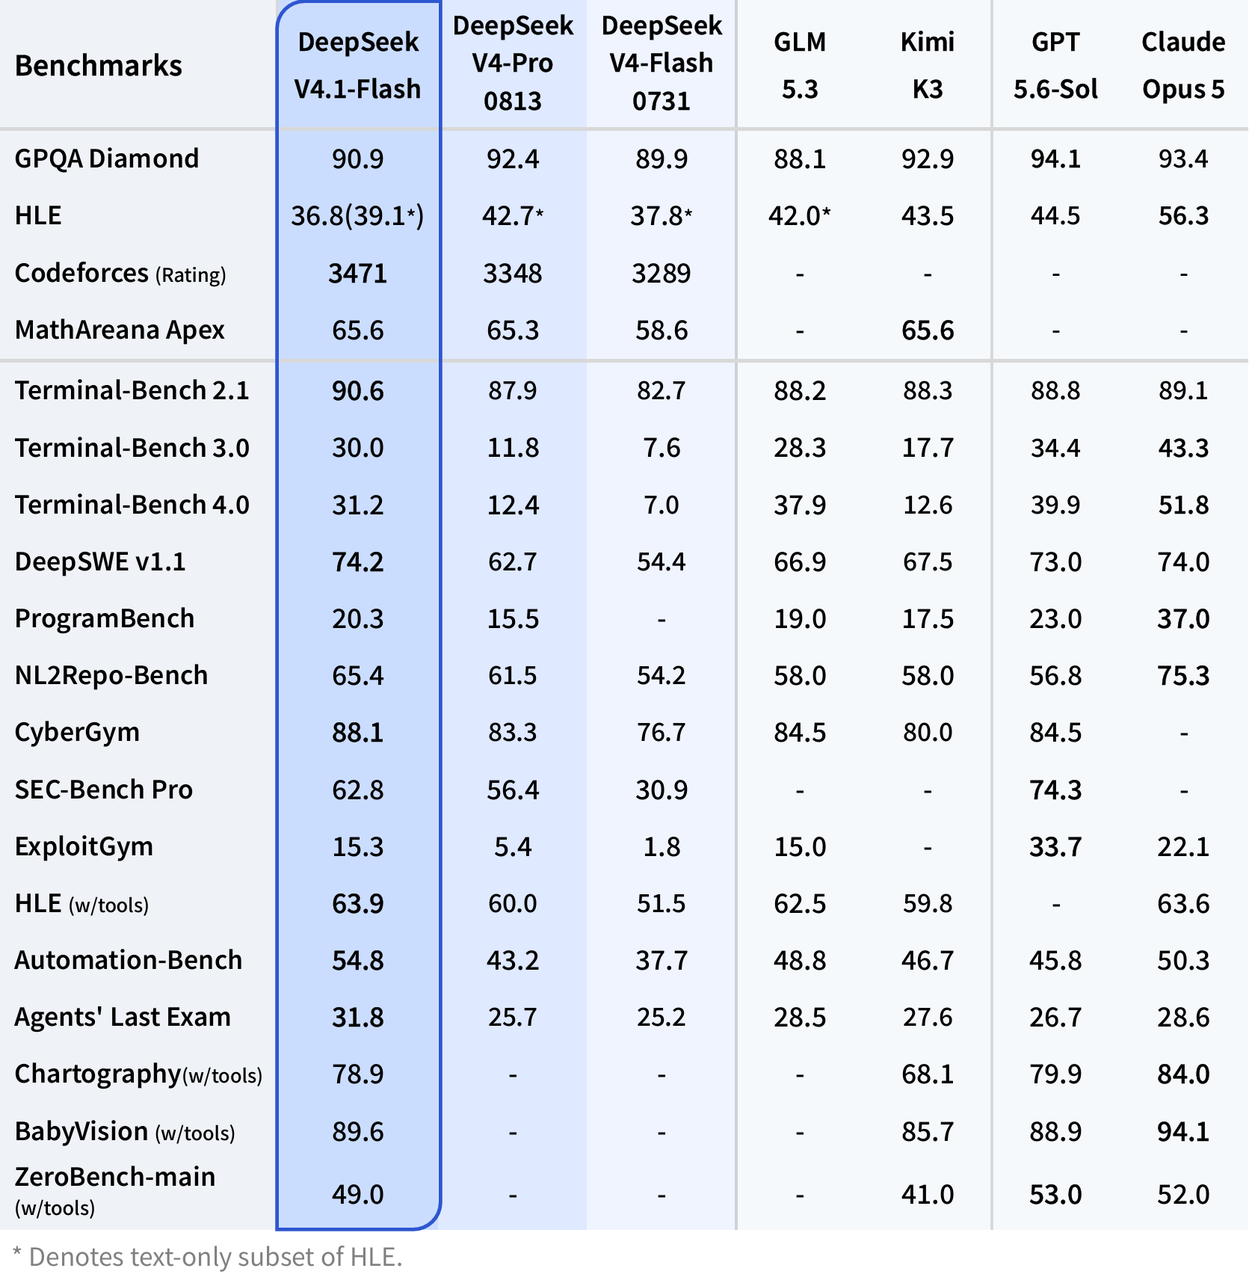
| DeepSeek-V4.1-Flash-101717 Oct 2026 · DeepSeek | 44.0% | DeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made RealCorroborated The same number is printed in 1 other lab document: 1text-only subsetSource image |
| MiniMax M3.1 Flash19 Oct 2026 · MiniMax | 43.4% | MiniMax M3.1 Flash: Redefining Agent Performance and CostChecked A person checked this number against its source on 26 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.text-only subsetSource image |
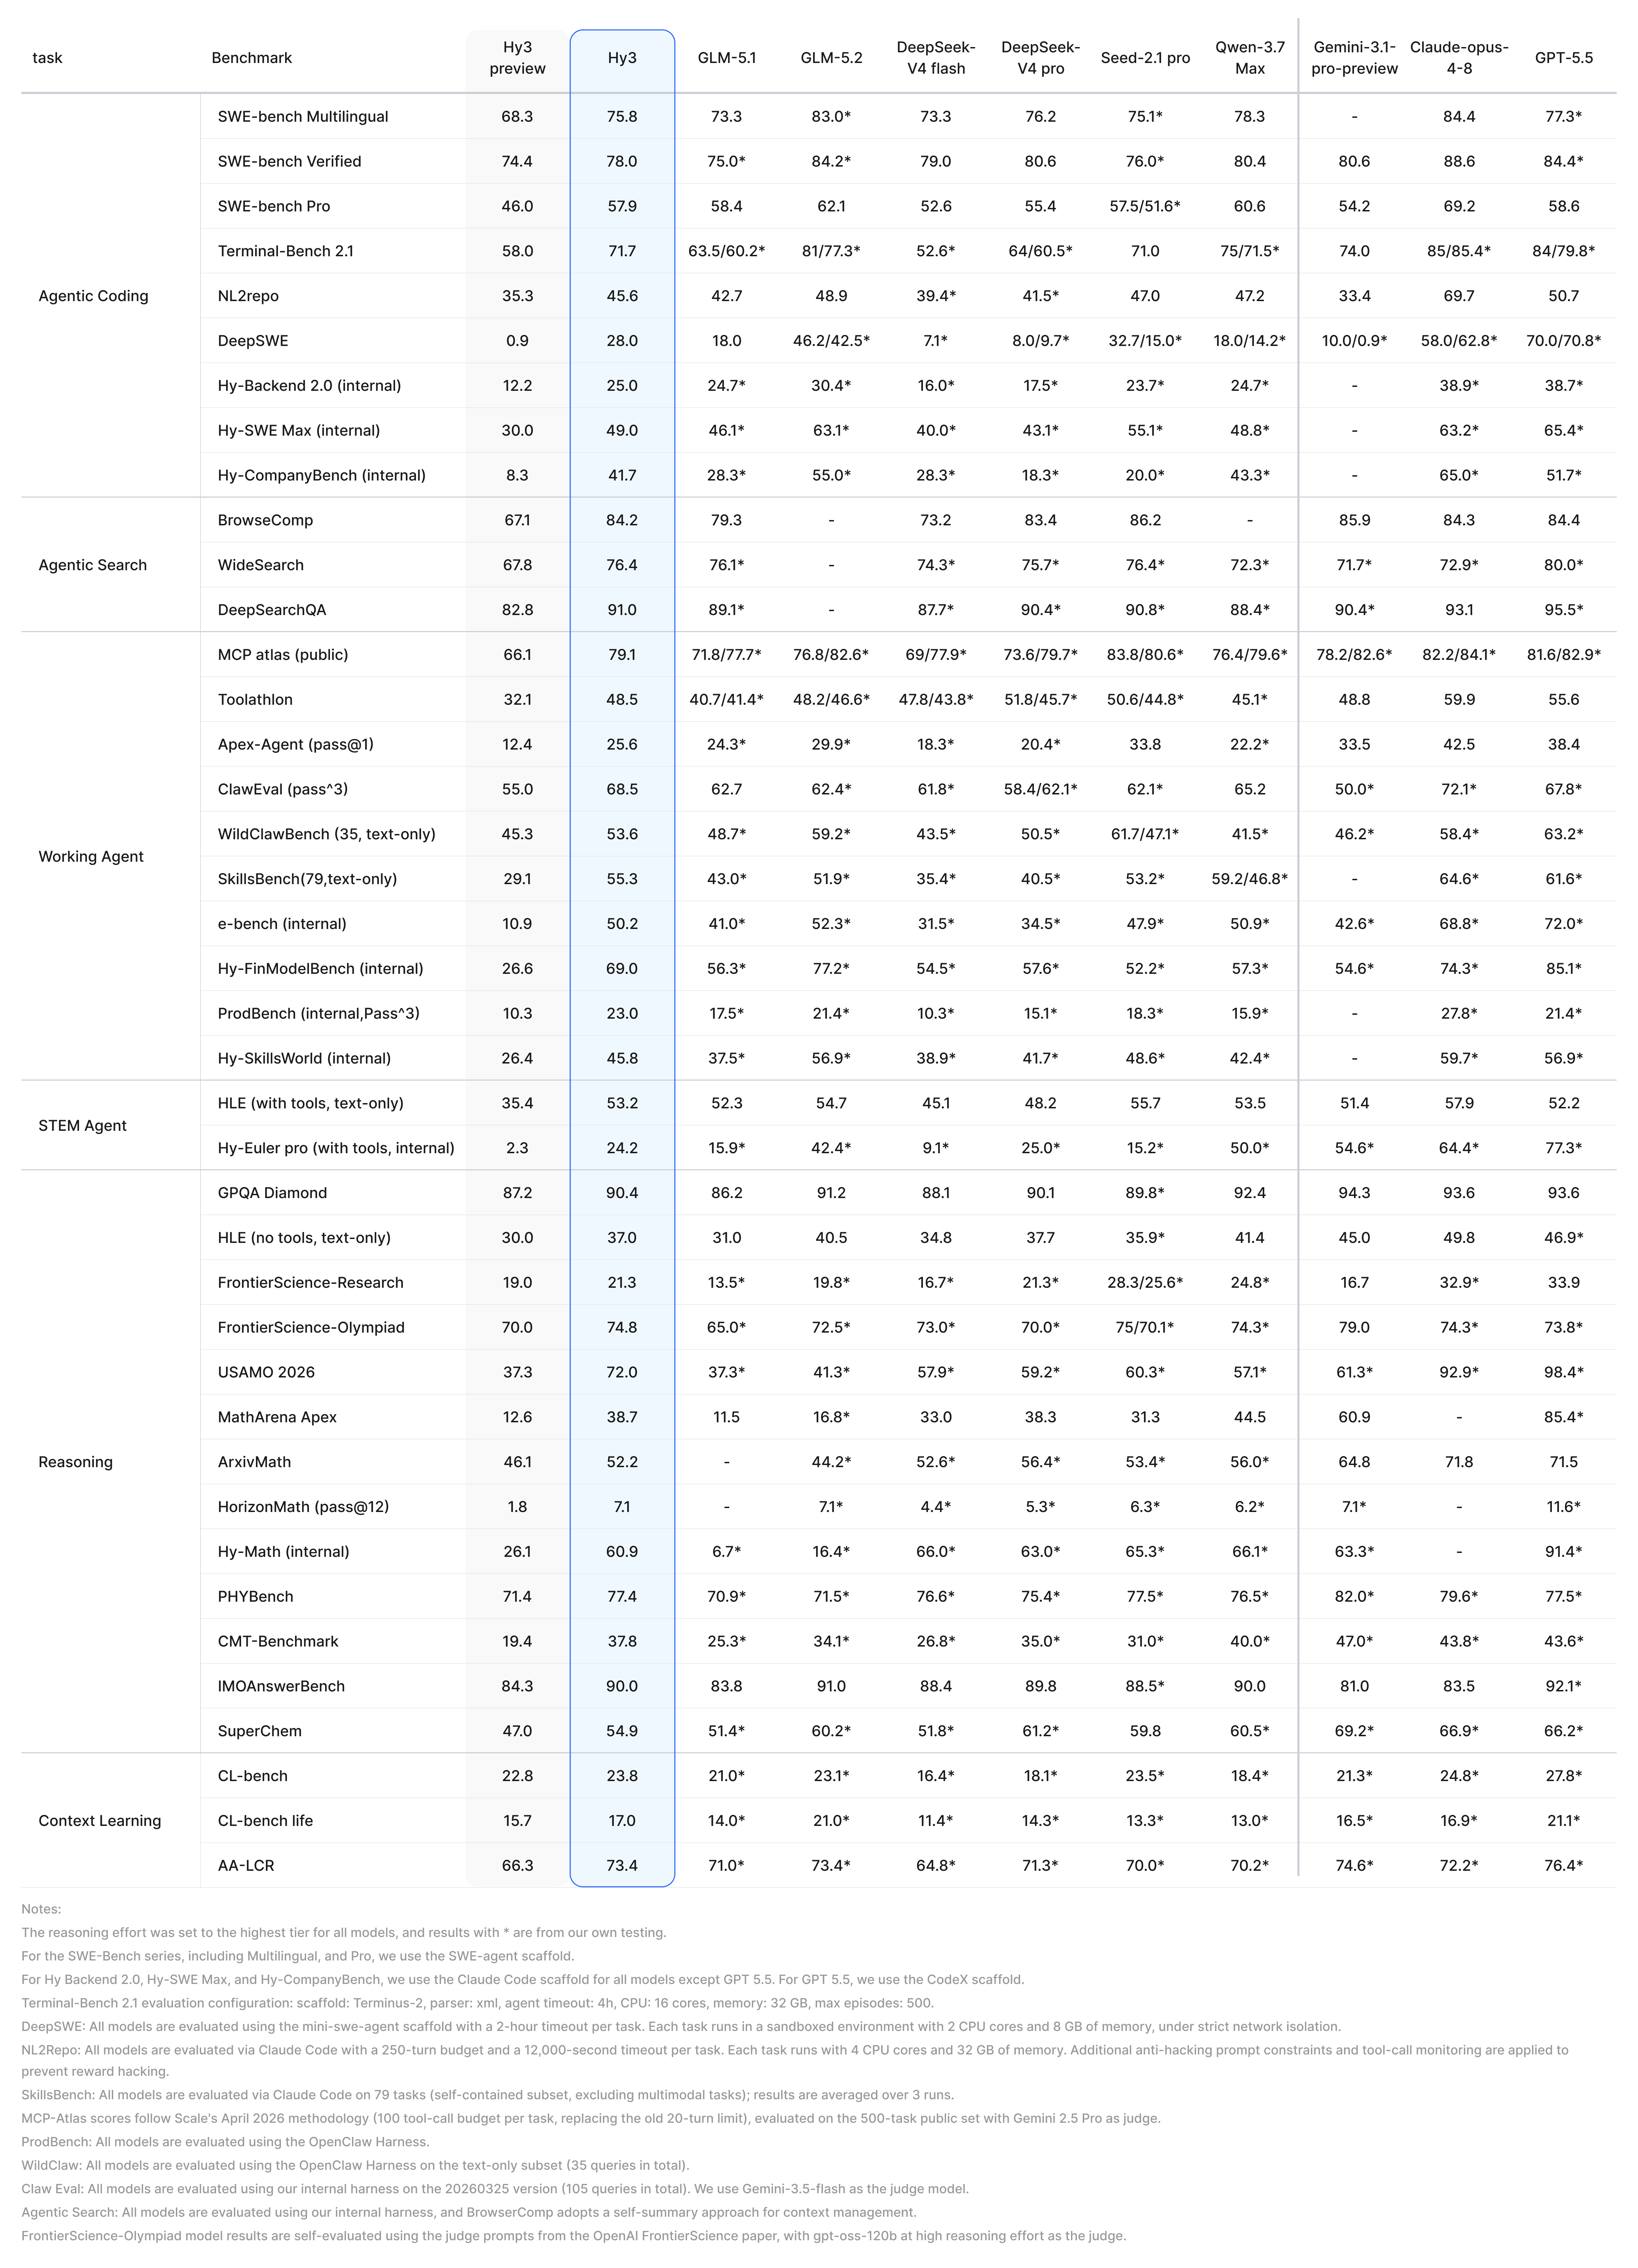
| Hy4 preview28 Aug 2026 · Tencent | 43.4% | Introducing Hy4 previewCorroborated The same number is printed in 1 other lab document: 1text-only subset; highest reasoning settingSource image |
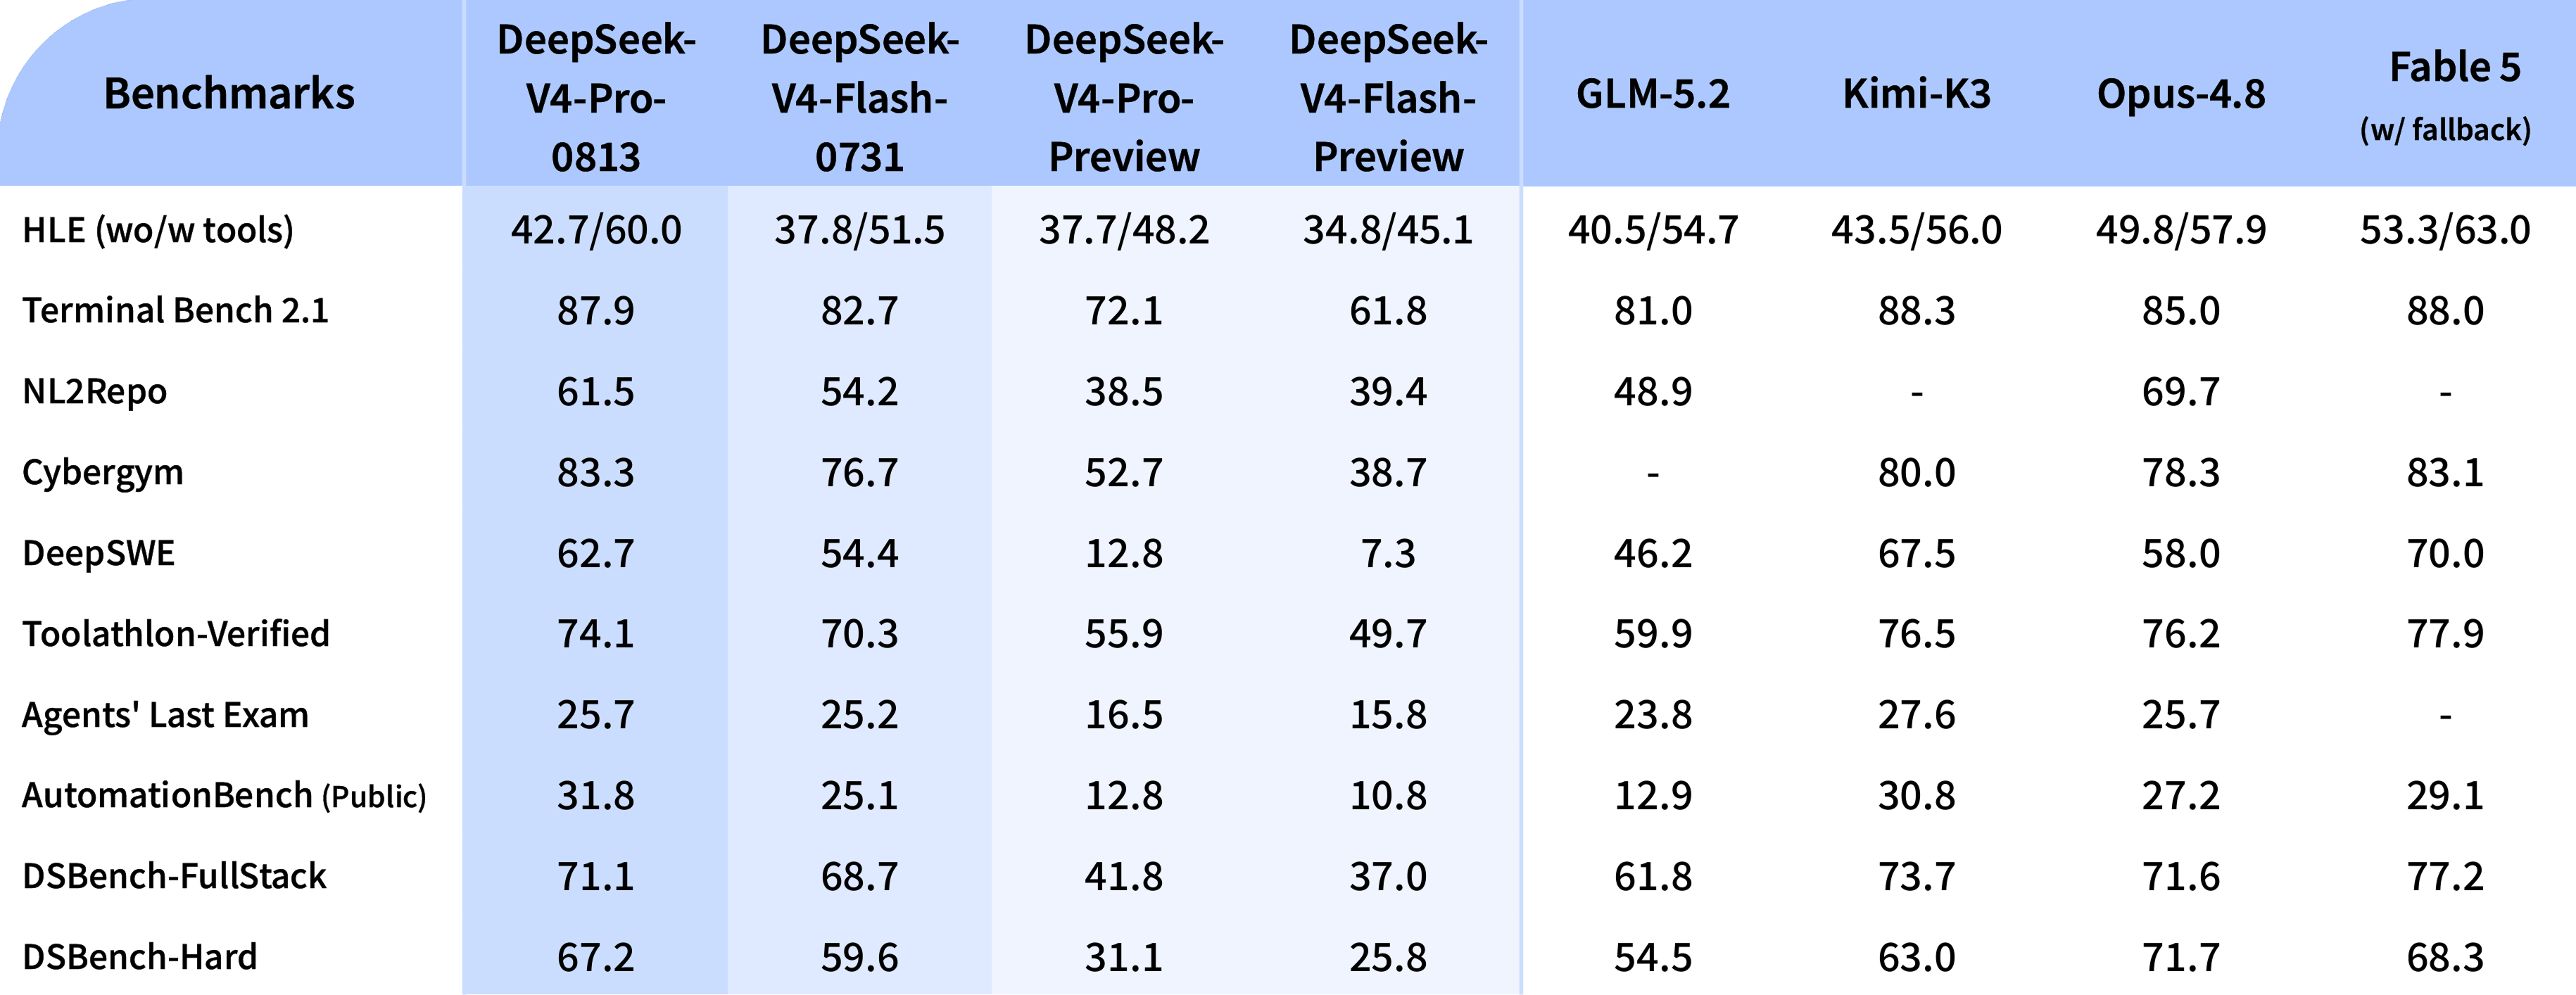
| DeepSeek-V4-Pro-081313 Aug 2026 · DeepSeek | 42.7% | DeepSeek-V4-Pro GA ReleaseCorroborated The same number is printed in 2 other lab documents: 1 2Source image |
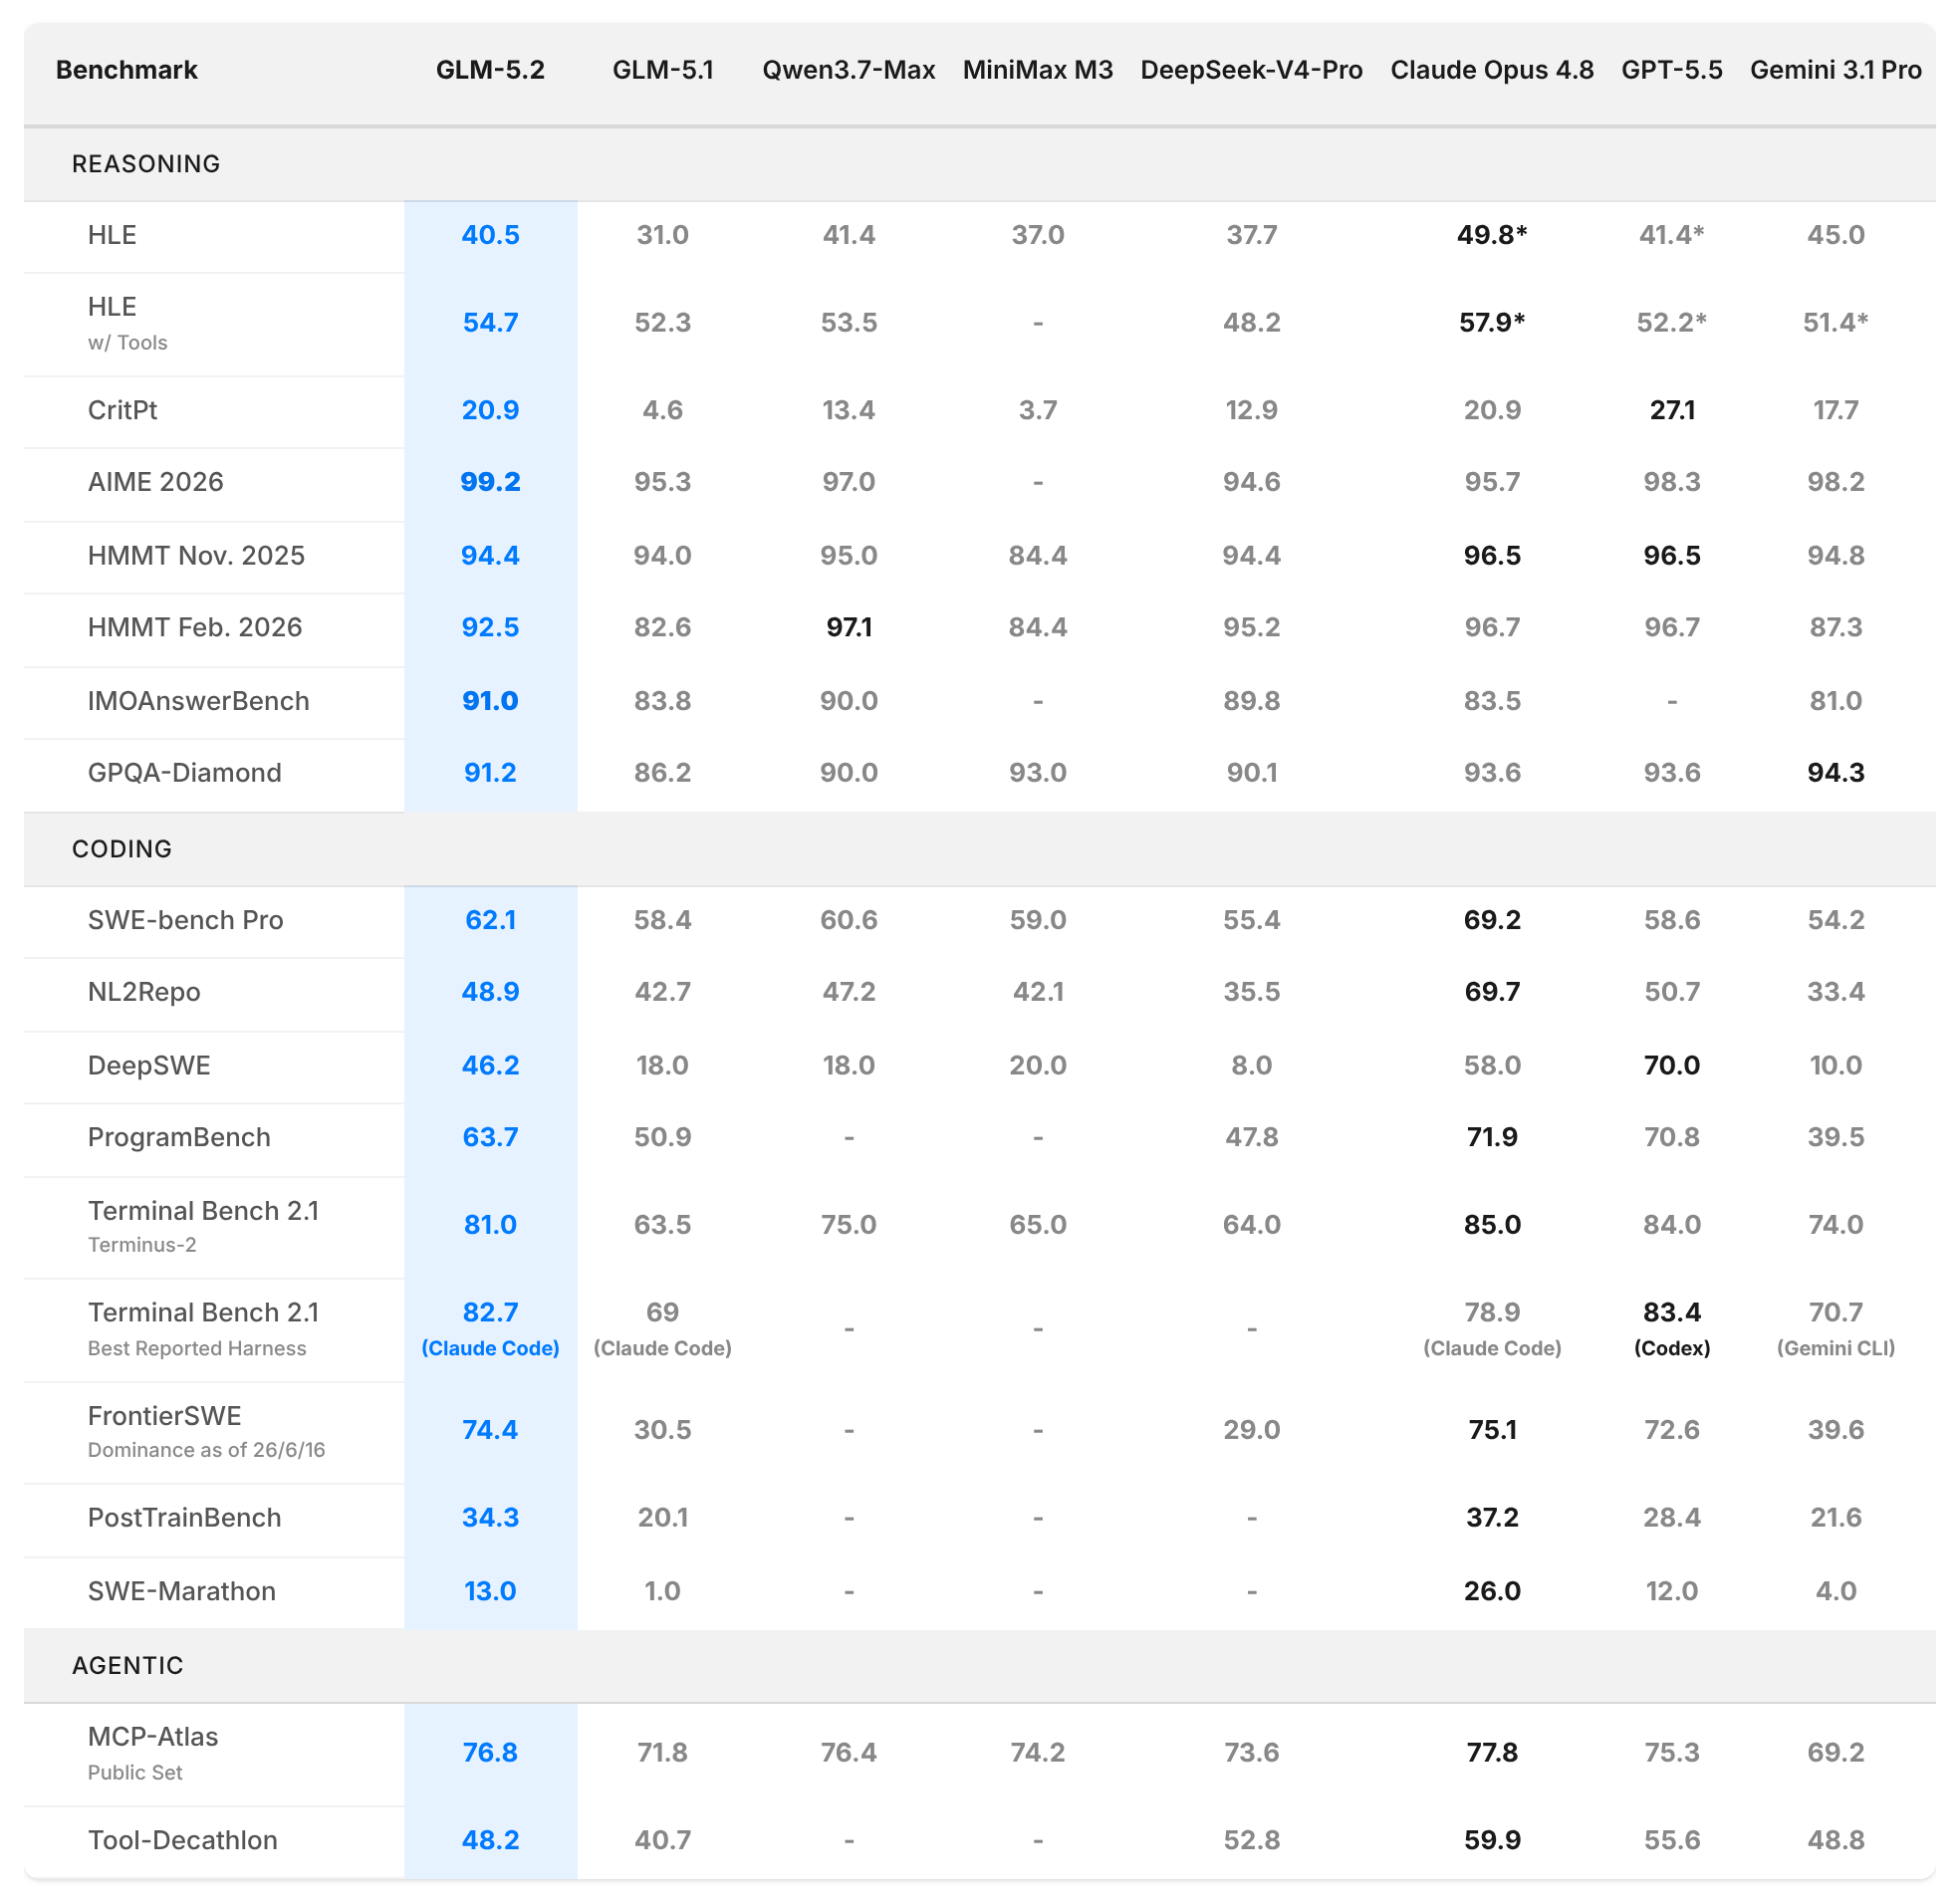
| GLM-5.216 Jun 2026 · Z.ai | 40.5% | GLM-5.2: Built for Long-Horizon TasksChecked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.text-only subset; GPT-5.5 judge; up to 163,840 output tokensOur capture |
| DeepSeek-V4.1-Flash10 Sep 2026 · DeepSeek | 39.1% | DeepSeek-V4.1-Flash: Smarter, Faster, More EfficientCorroborated The same number is printed in 2 other lab documents: 1 2text-only subsetSource image |
| Hy36 Jul 2026 · Tencent | 37.0% | Introducing Hy3Corroborated The same number is printed in 1 other lab document: 1text-only subset; highest reasoning settingSource image |
| Hy36 Jul 2026 · Tencent | 30.0% | Introducing Hy3Corroborated The same number is printed in 3 other lab documents: 1 2 3Hy3 preview, re-evaluated at Hy3 launch; text-only subset; highest reasoning setting; another report, not chartedSource image |
| Hy36 Jul 2026 · Tencent | 34.4% | Introducing Hy4 previewChecked A person checked this number against its source on 7 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.re-evaluated at Hy4 preview launch; text-only subset; highest reasoning setting; reported later; another report, not chartedSource image |
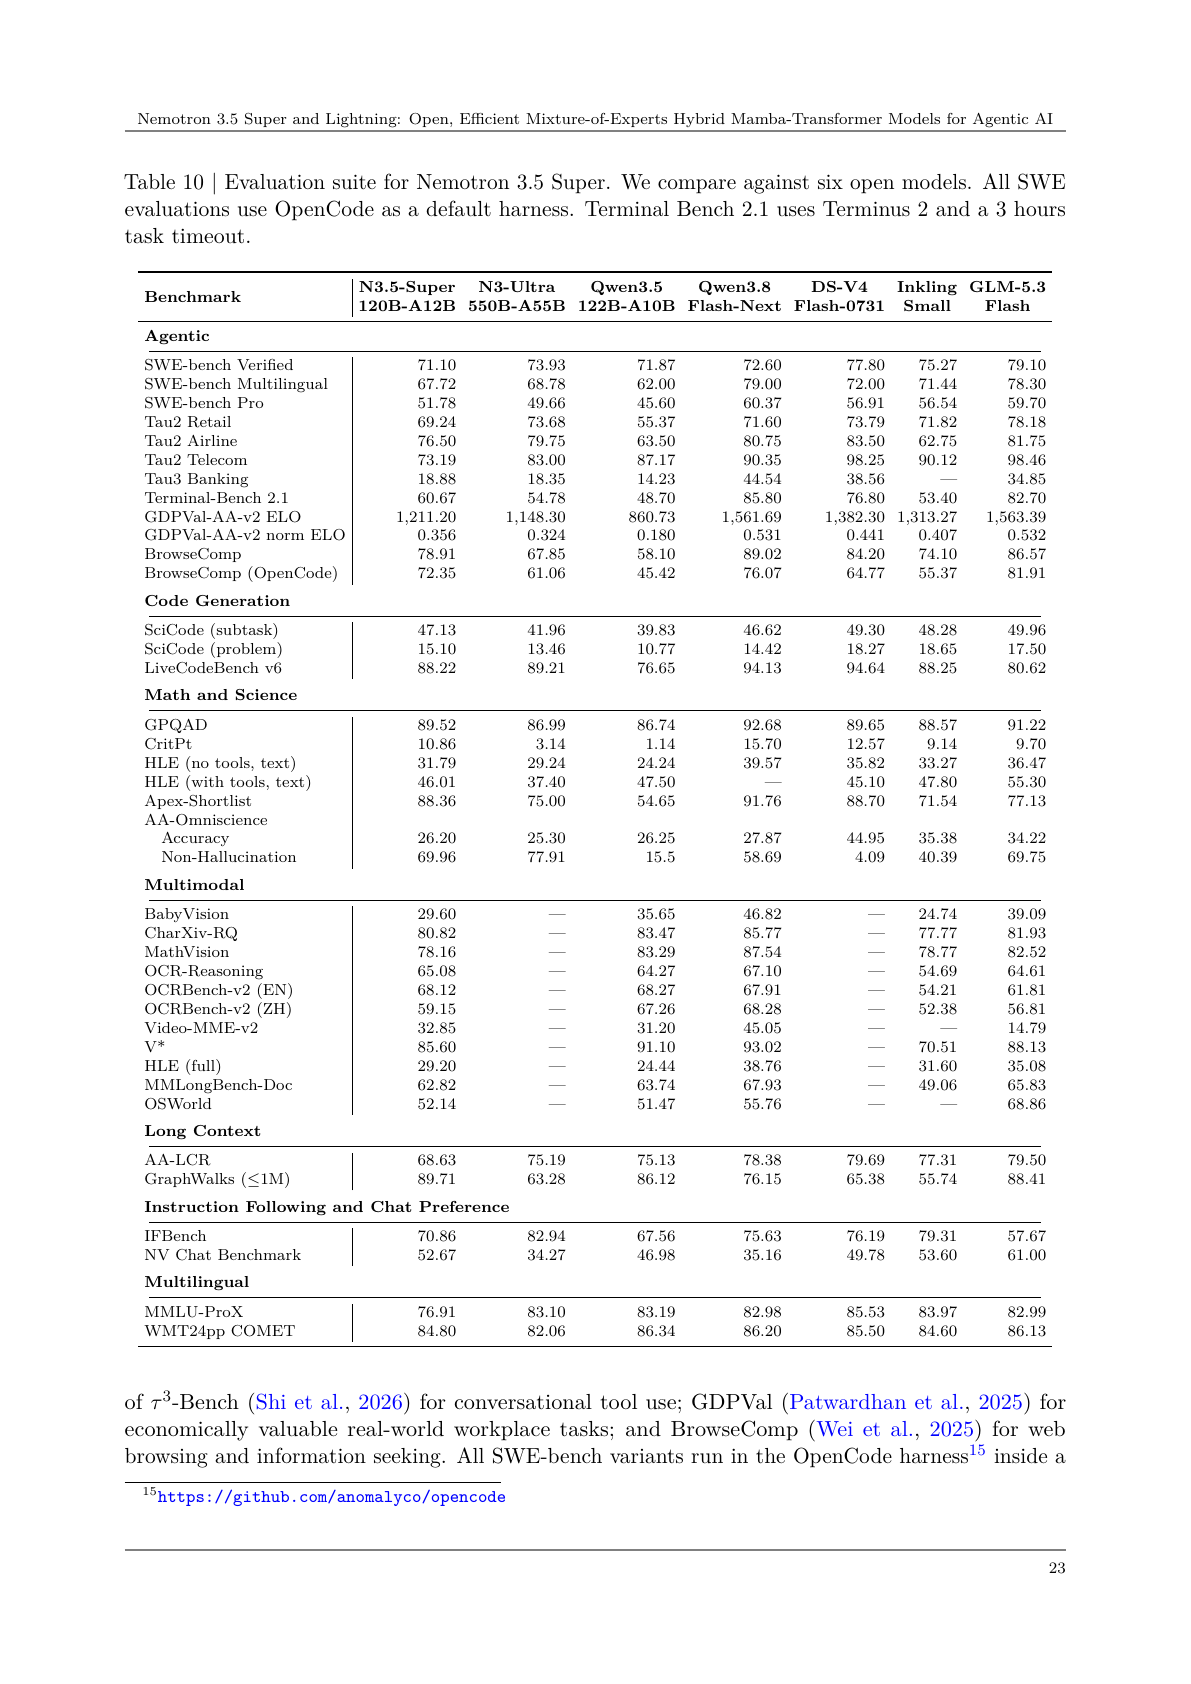
| Nemotron 3.5 Super VL 120B-A12B15 Oct 2026 · NVIDIA | 31.79% | Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AICorroborated The same number is printed in 3 other lab documents: 1 2 3text-only subset; GPT-5.6 Luna judgeOur capture |
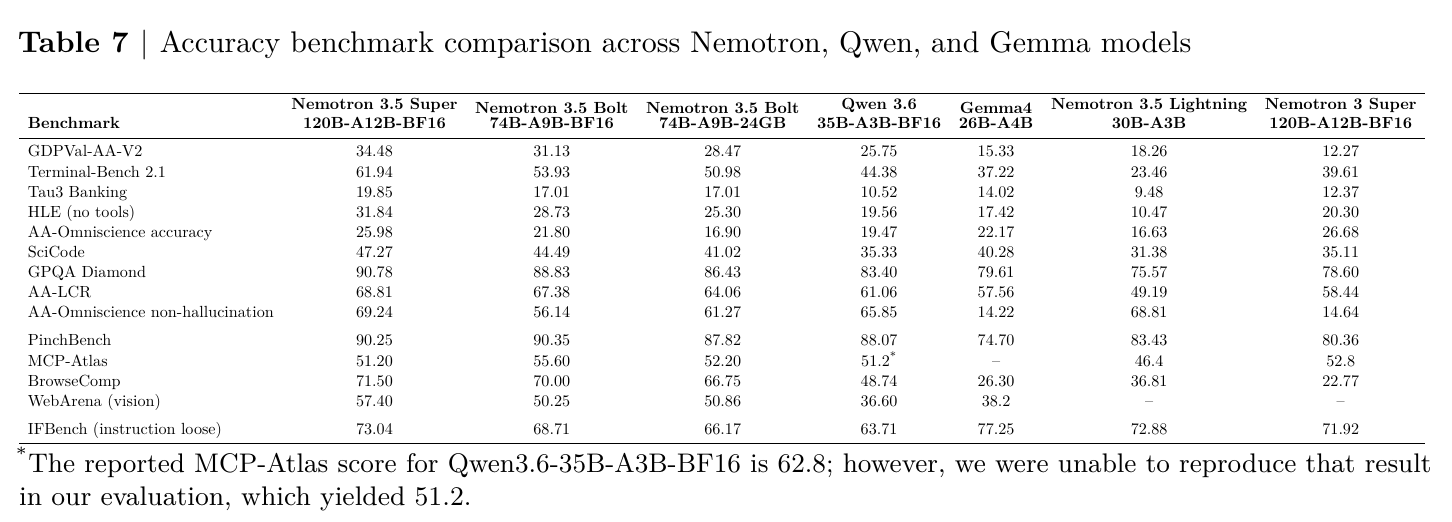
| Nemotron 3.5 Super VL 120B-A12B15 Oct 2026 · NVIDIA | 31.84% | Nemotron 3.5 Bolt 74B-A9B 24GB: A Hybrid Vision-Language Model for Local AICorroborated The same number is printed in 1 other lab document: 1another report, not chartedOur capture |
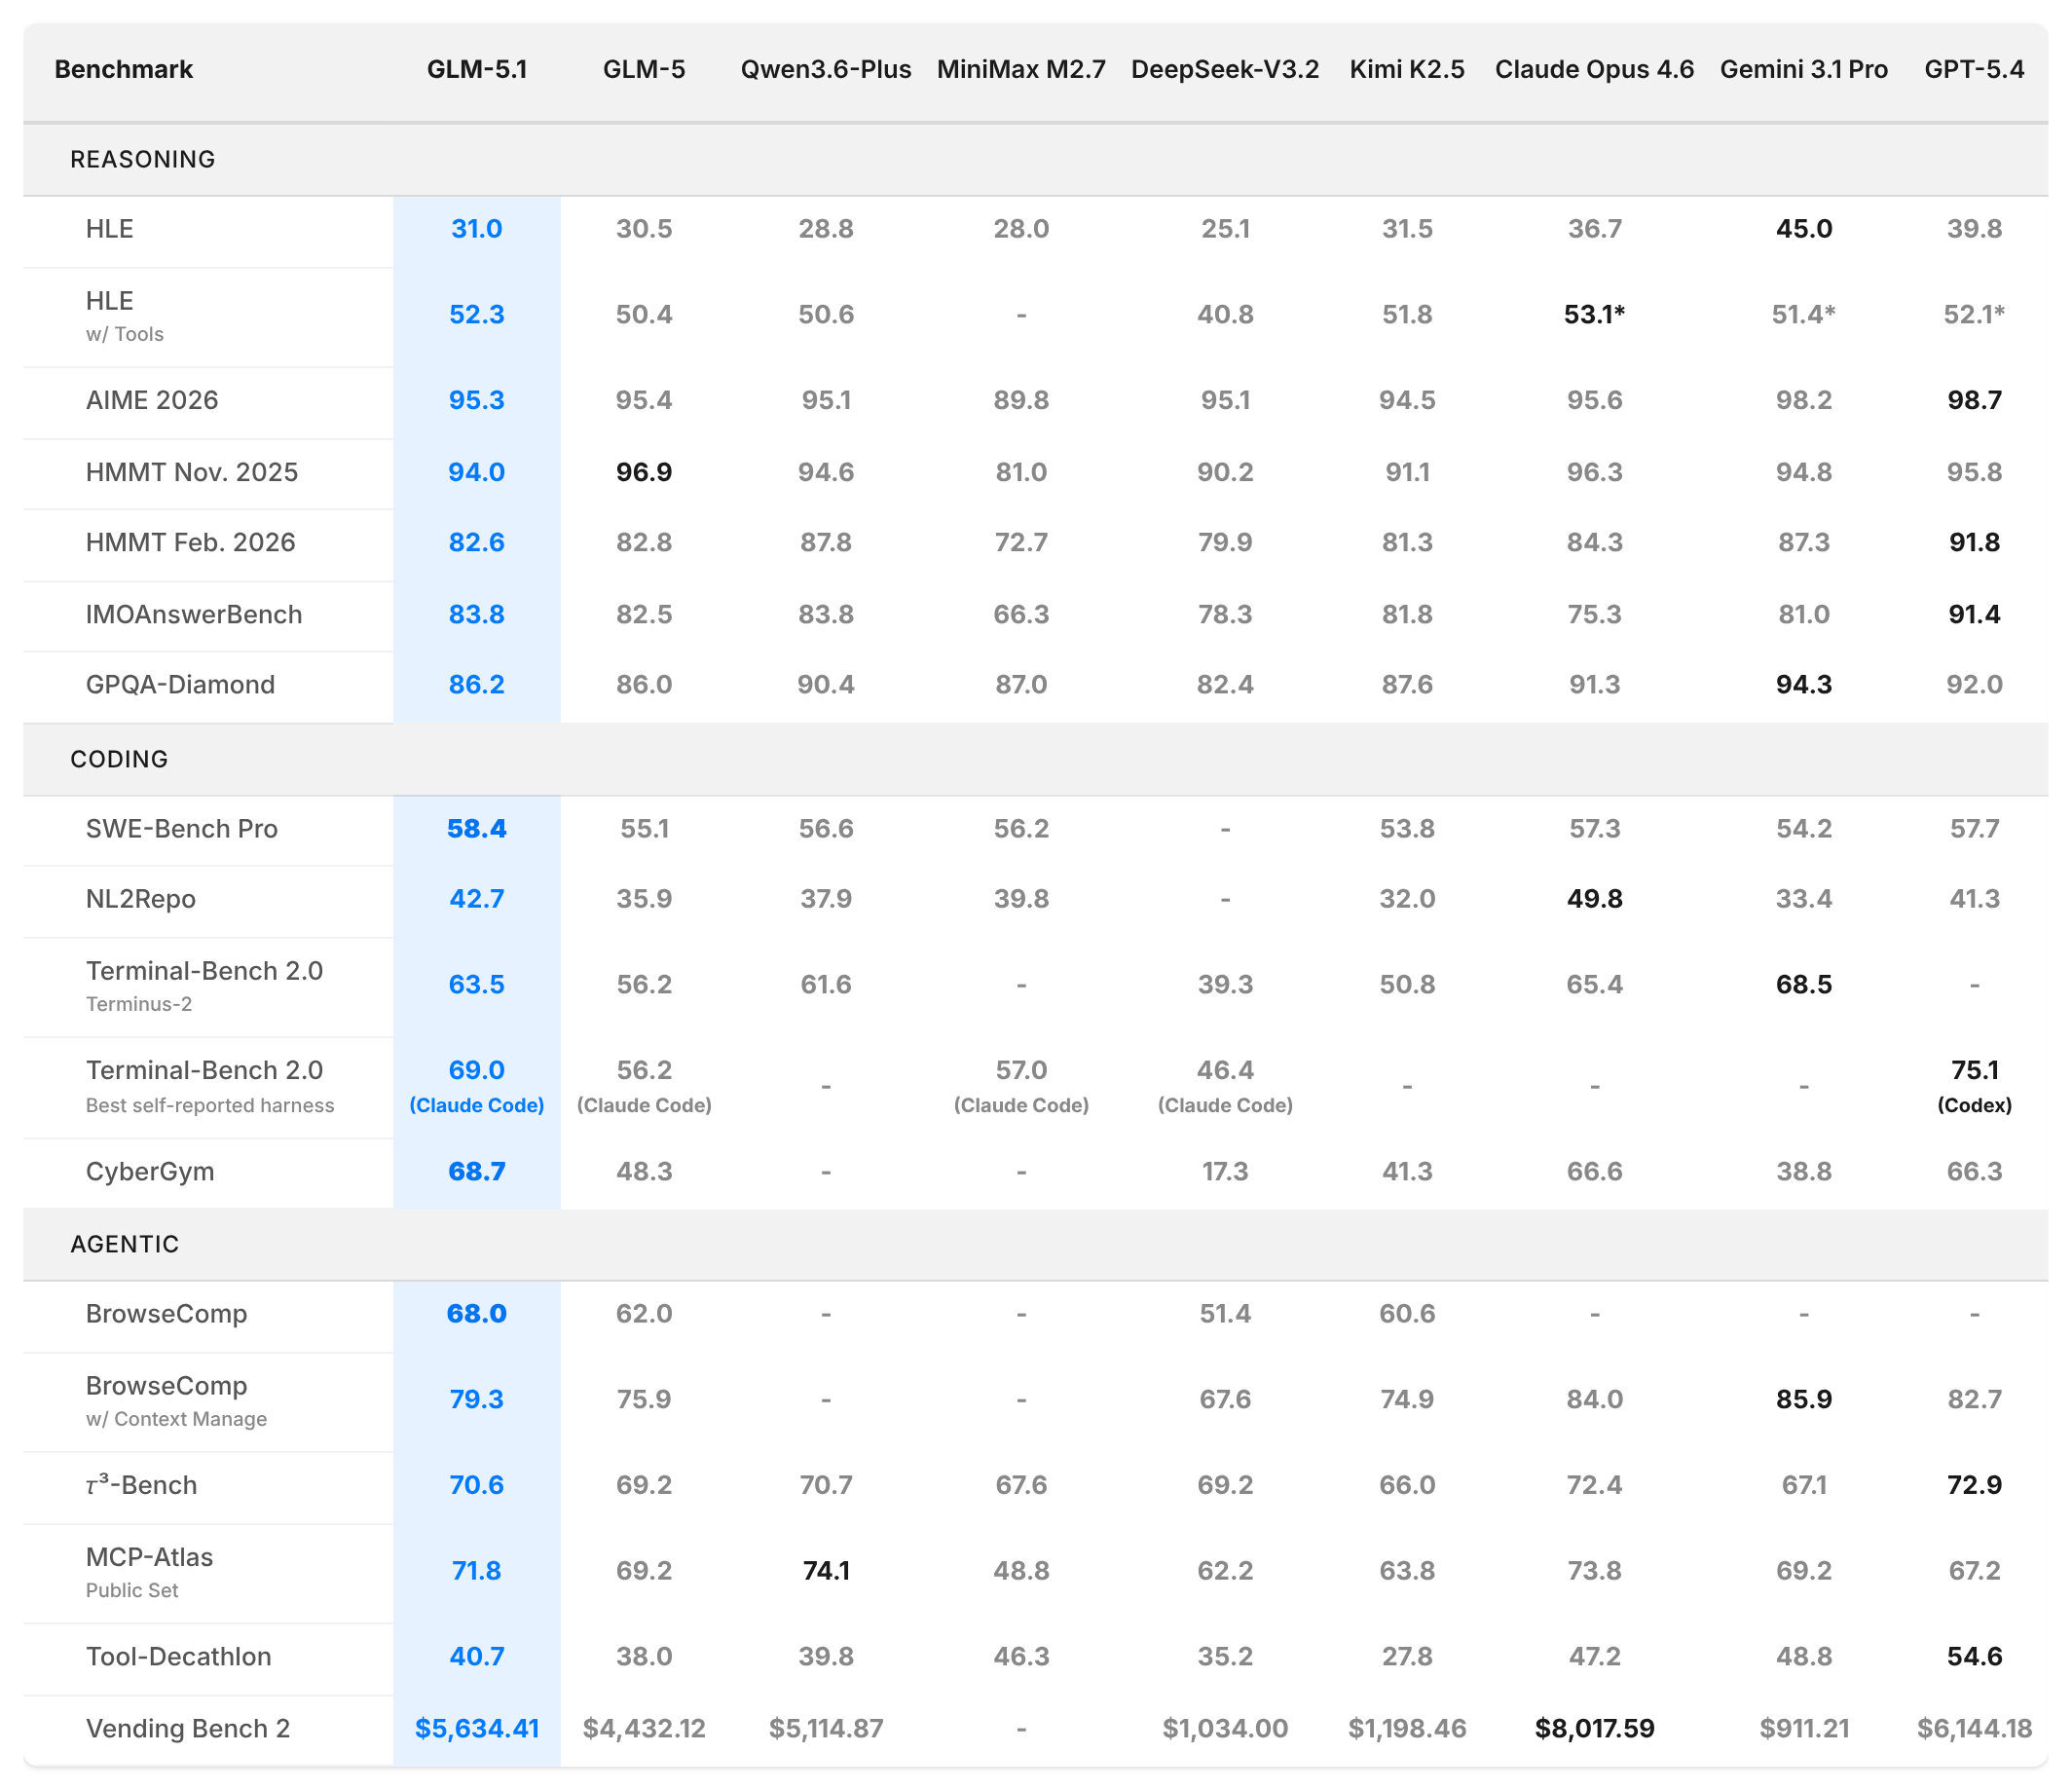
| GLM-5.17 Apr 2026 · Z.ai | 31.0% | GLM-5.1: Towards Long-Horizon TasksChecked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.Corroborated The same number is printed in 1 other lab document: 1text-only subset; GPT-5.2 judge; up to 163,840 output tokensOur capture |
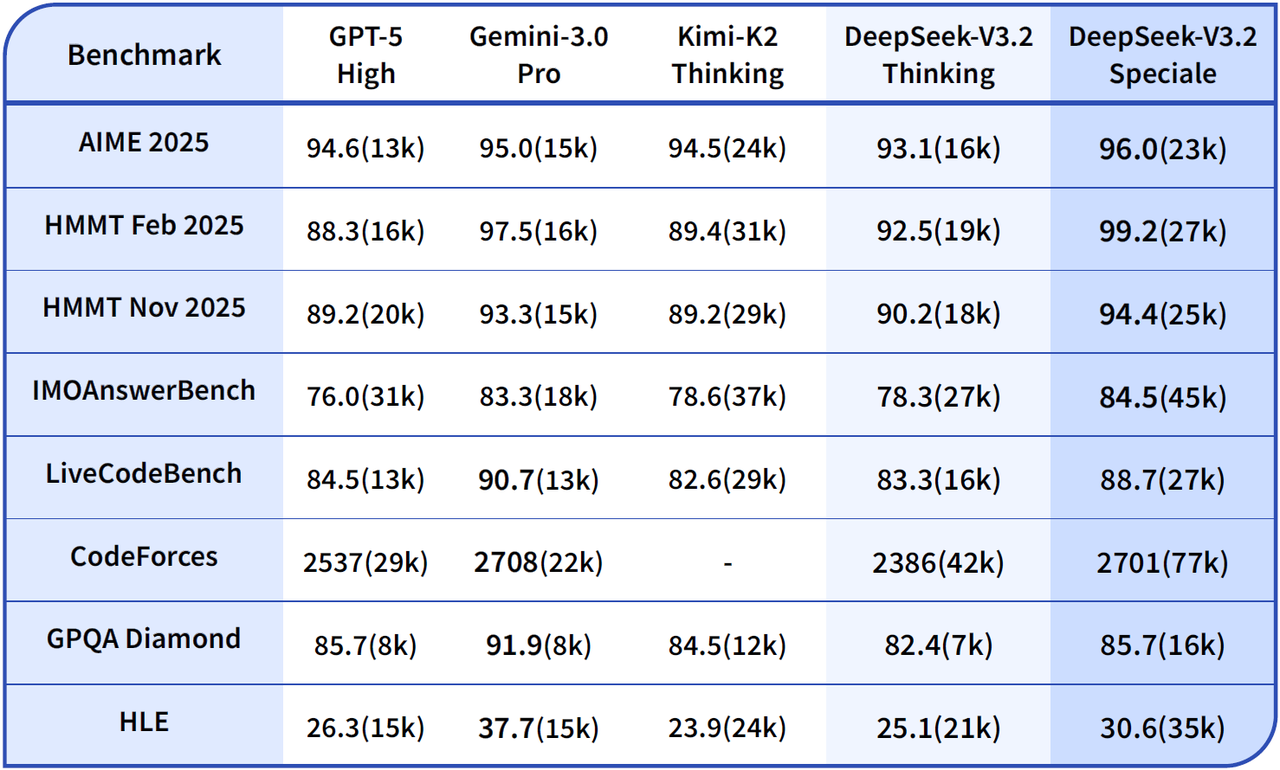
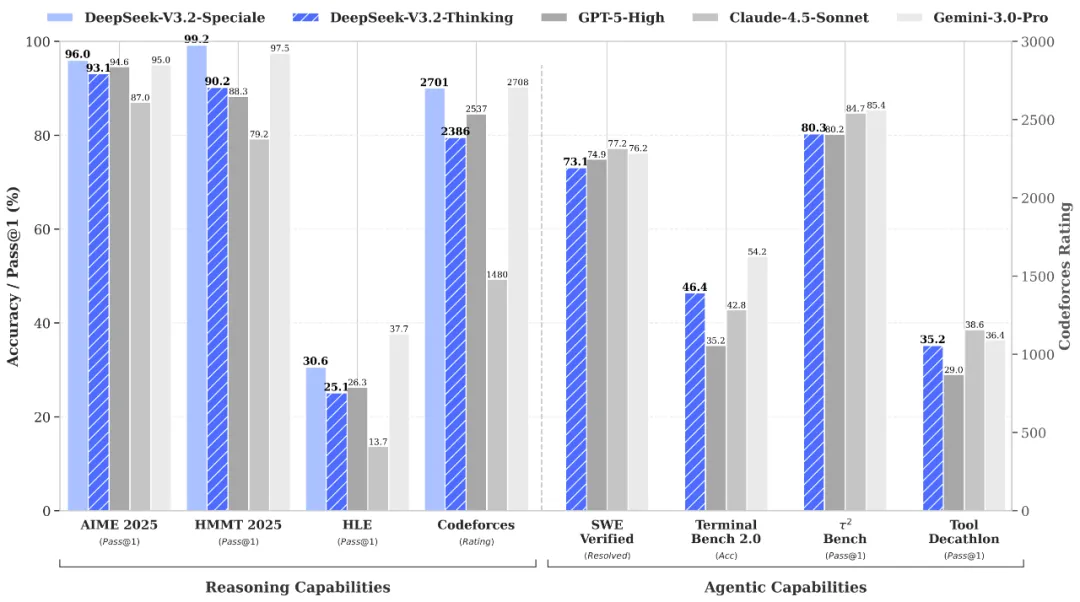
| DeepSeek-V3.2-Speciale1 Dec 2025 · DeepSeek | 30.6% | DeepSeek-V3.2 ReleaseCorroborated The same number is printed in 2 other lab documents: 1 235K output tokens; full or text-only set not statedSource image |
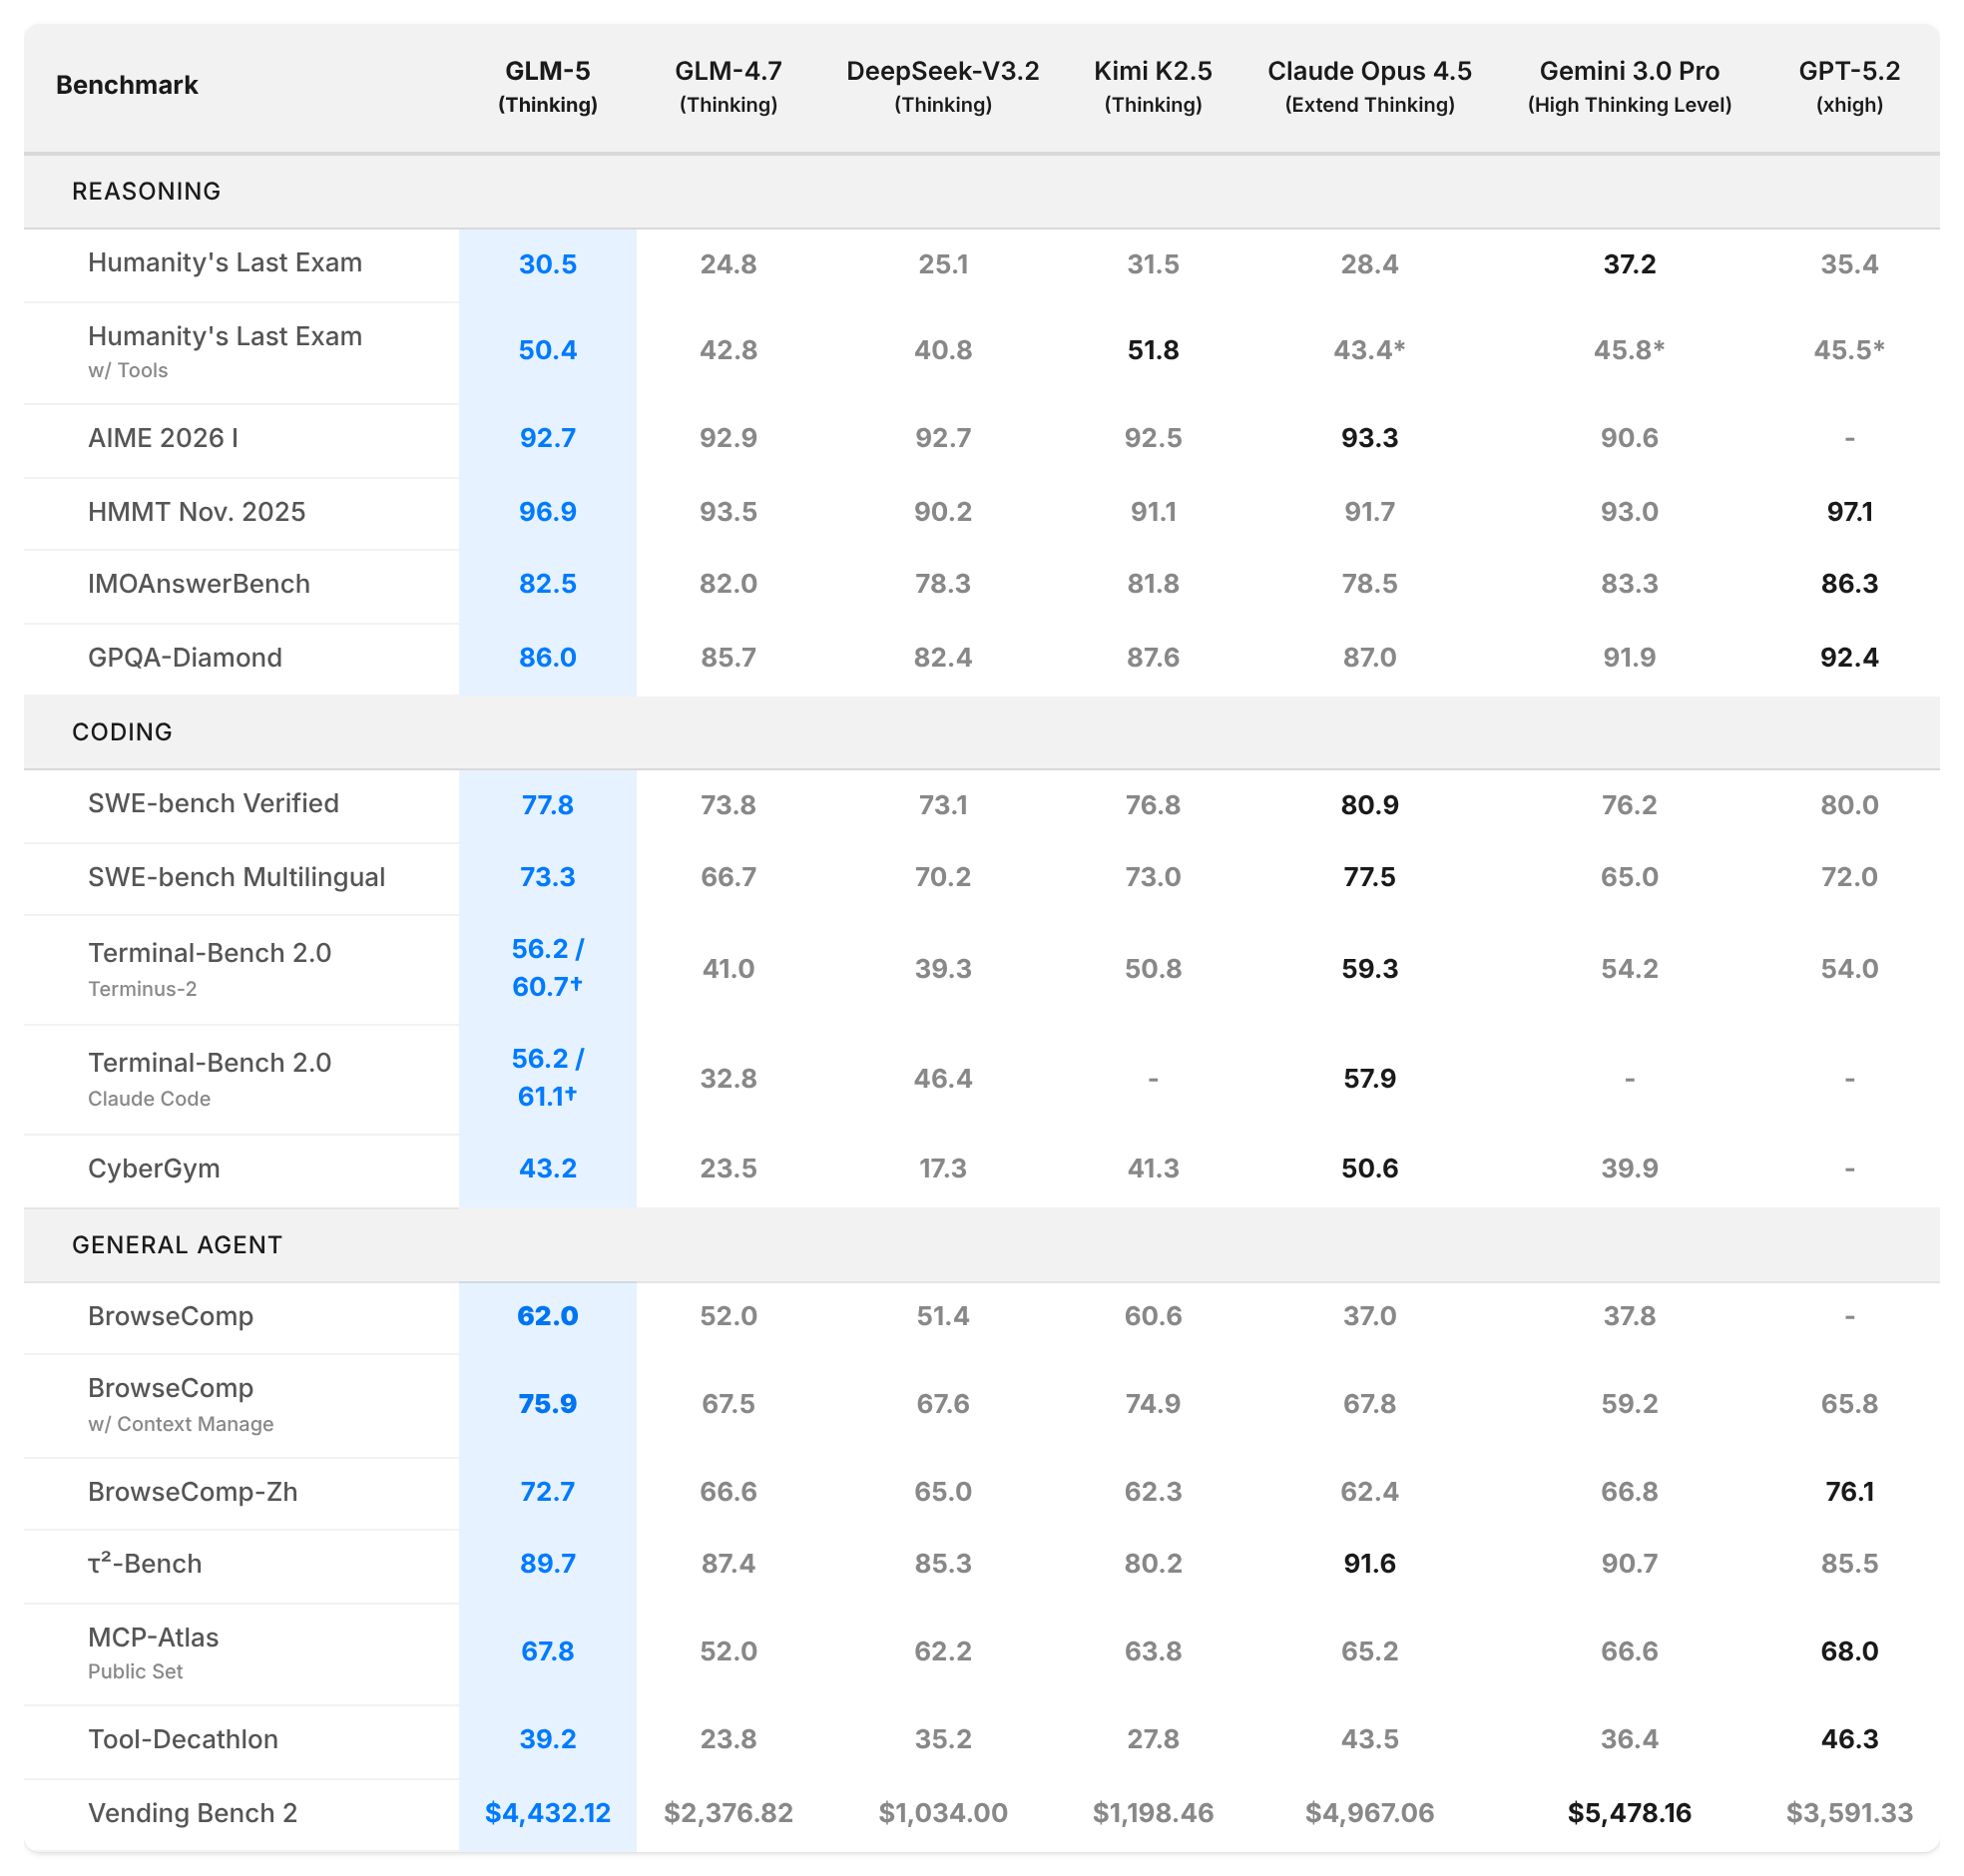
| GLM-512 Feb 2026 · Z.ai | 30.5% | GLM-5: From Vibe Coding to Agentic EngineeringChecked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.text-only subset; GPT-5.2 judge; up to 131,072 output tokensOur capture |
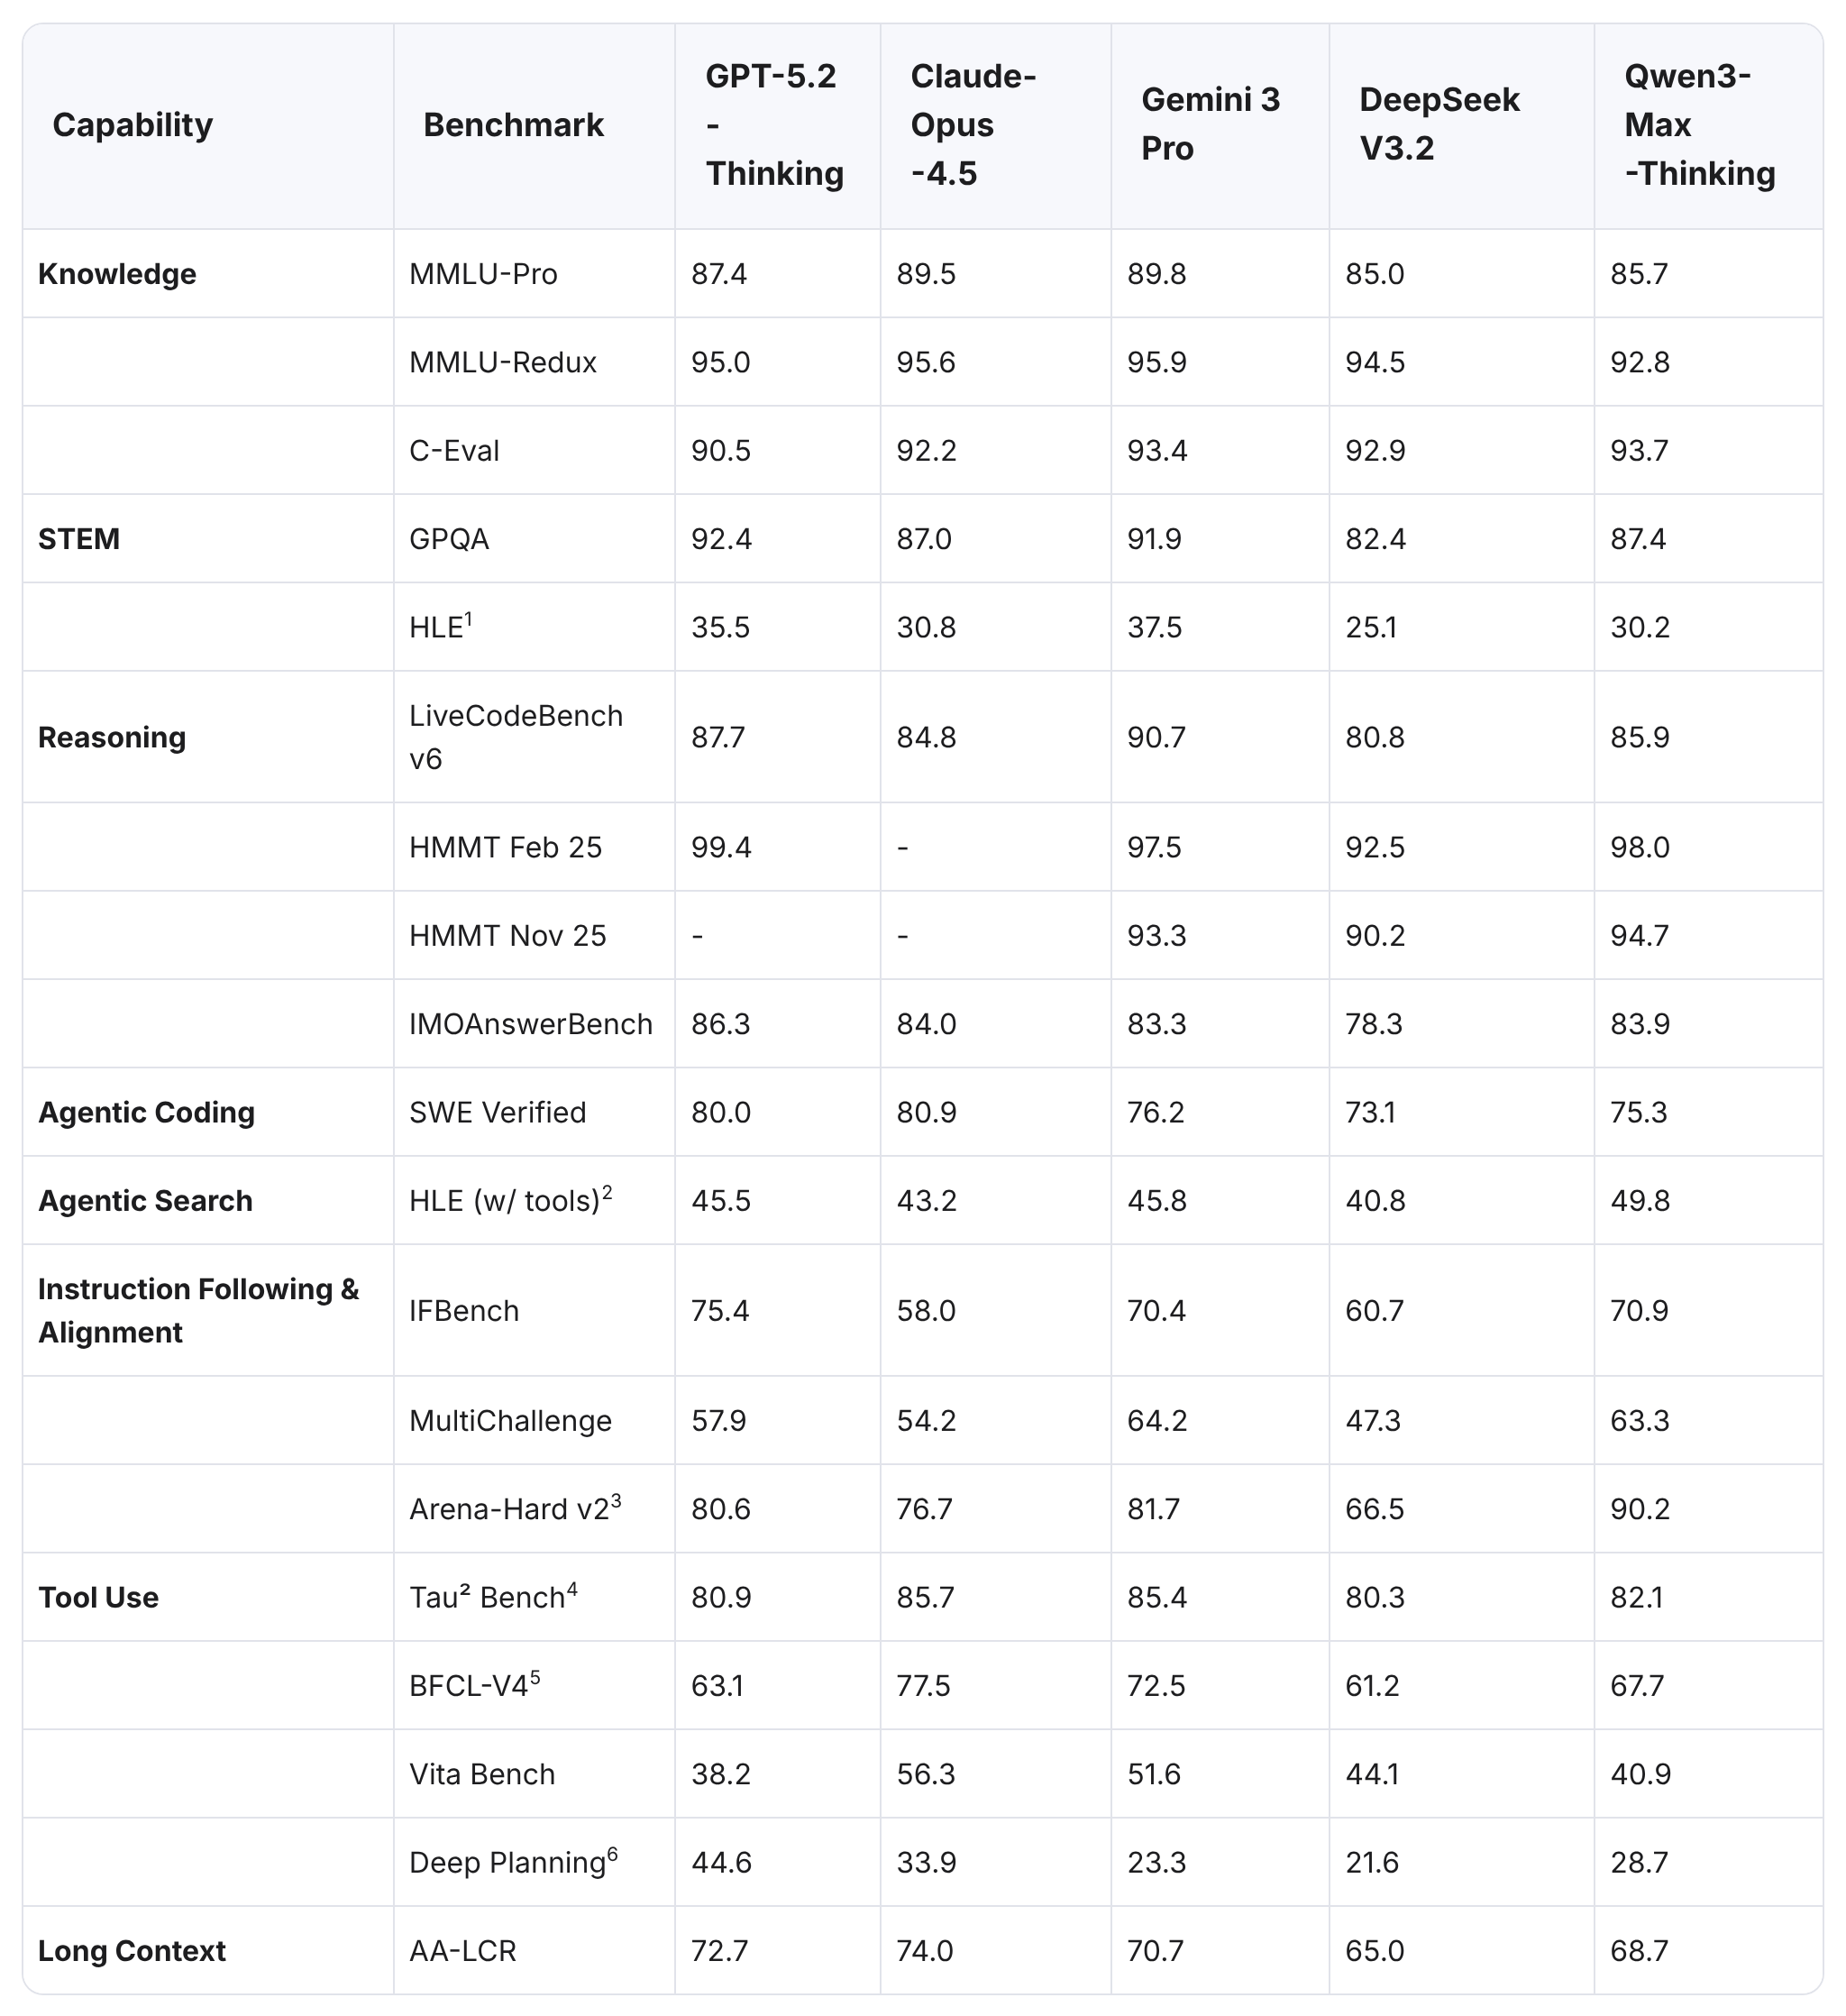
| Qwen3-Max-Thinking26 Jan 2026 · Alibaba | 30.2% | Pushing Qwen3-Max-Thinking Beyond its LimitsChecked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.text-only subsetOur capture |
| Nemotron 3 Ultra 550B-A55B4 Jun 2026 · NVIDIA | 29.24% | Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AICorroborated The same number is printed in 2 other lab documents: 1 2text-only subset; GPT-5.6 Luna judge; reported laterOur capture |
| Nemotron 3.5 Bolt15 Oct 2026 · NVIDIA | 28.73% | Nemotron 3.5 Bolt 74B-A9B 24GB: A Hybrid Vision-Language Model for Local AICorroborated The same number is printed in 1 other lab document: 1BF16 weights |
| Nemotron 3.5 Bolt15 Oct 2026 · NVIDIA | 25.30% | Nemotron 3.5 Bolt 74B-A9B 24GB: A Hybrid Vision-Language Model for Local AICorroborated The same number is printed in 1 other lab document: 124GB build with 2-bit (IQ2) weights; another report, not charted |
| DeepSeek-V3.21 Dec 2025 · DeepSeek | 25.1% | DeepSeek-V3.2 ReleaseChecked A person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.Corroborated The same number is printed in 2 other lab documents: 1 2thinking mode; 21K output tokens; full or text-only set not statedSource image |
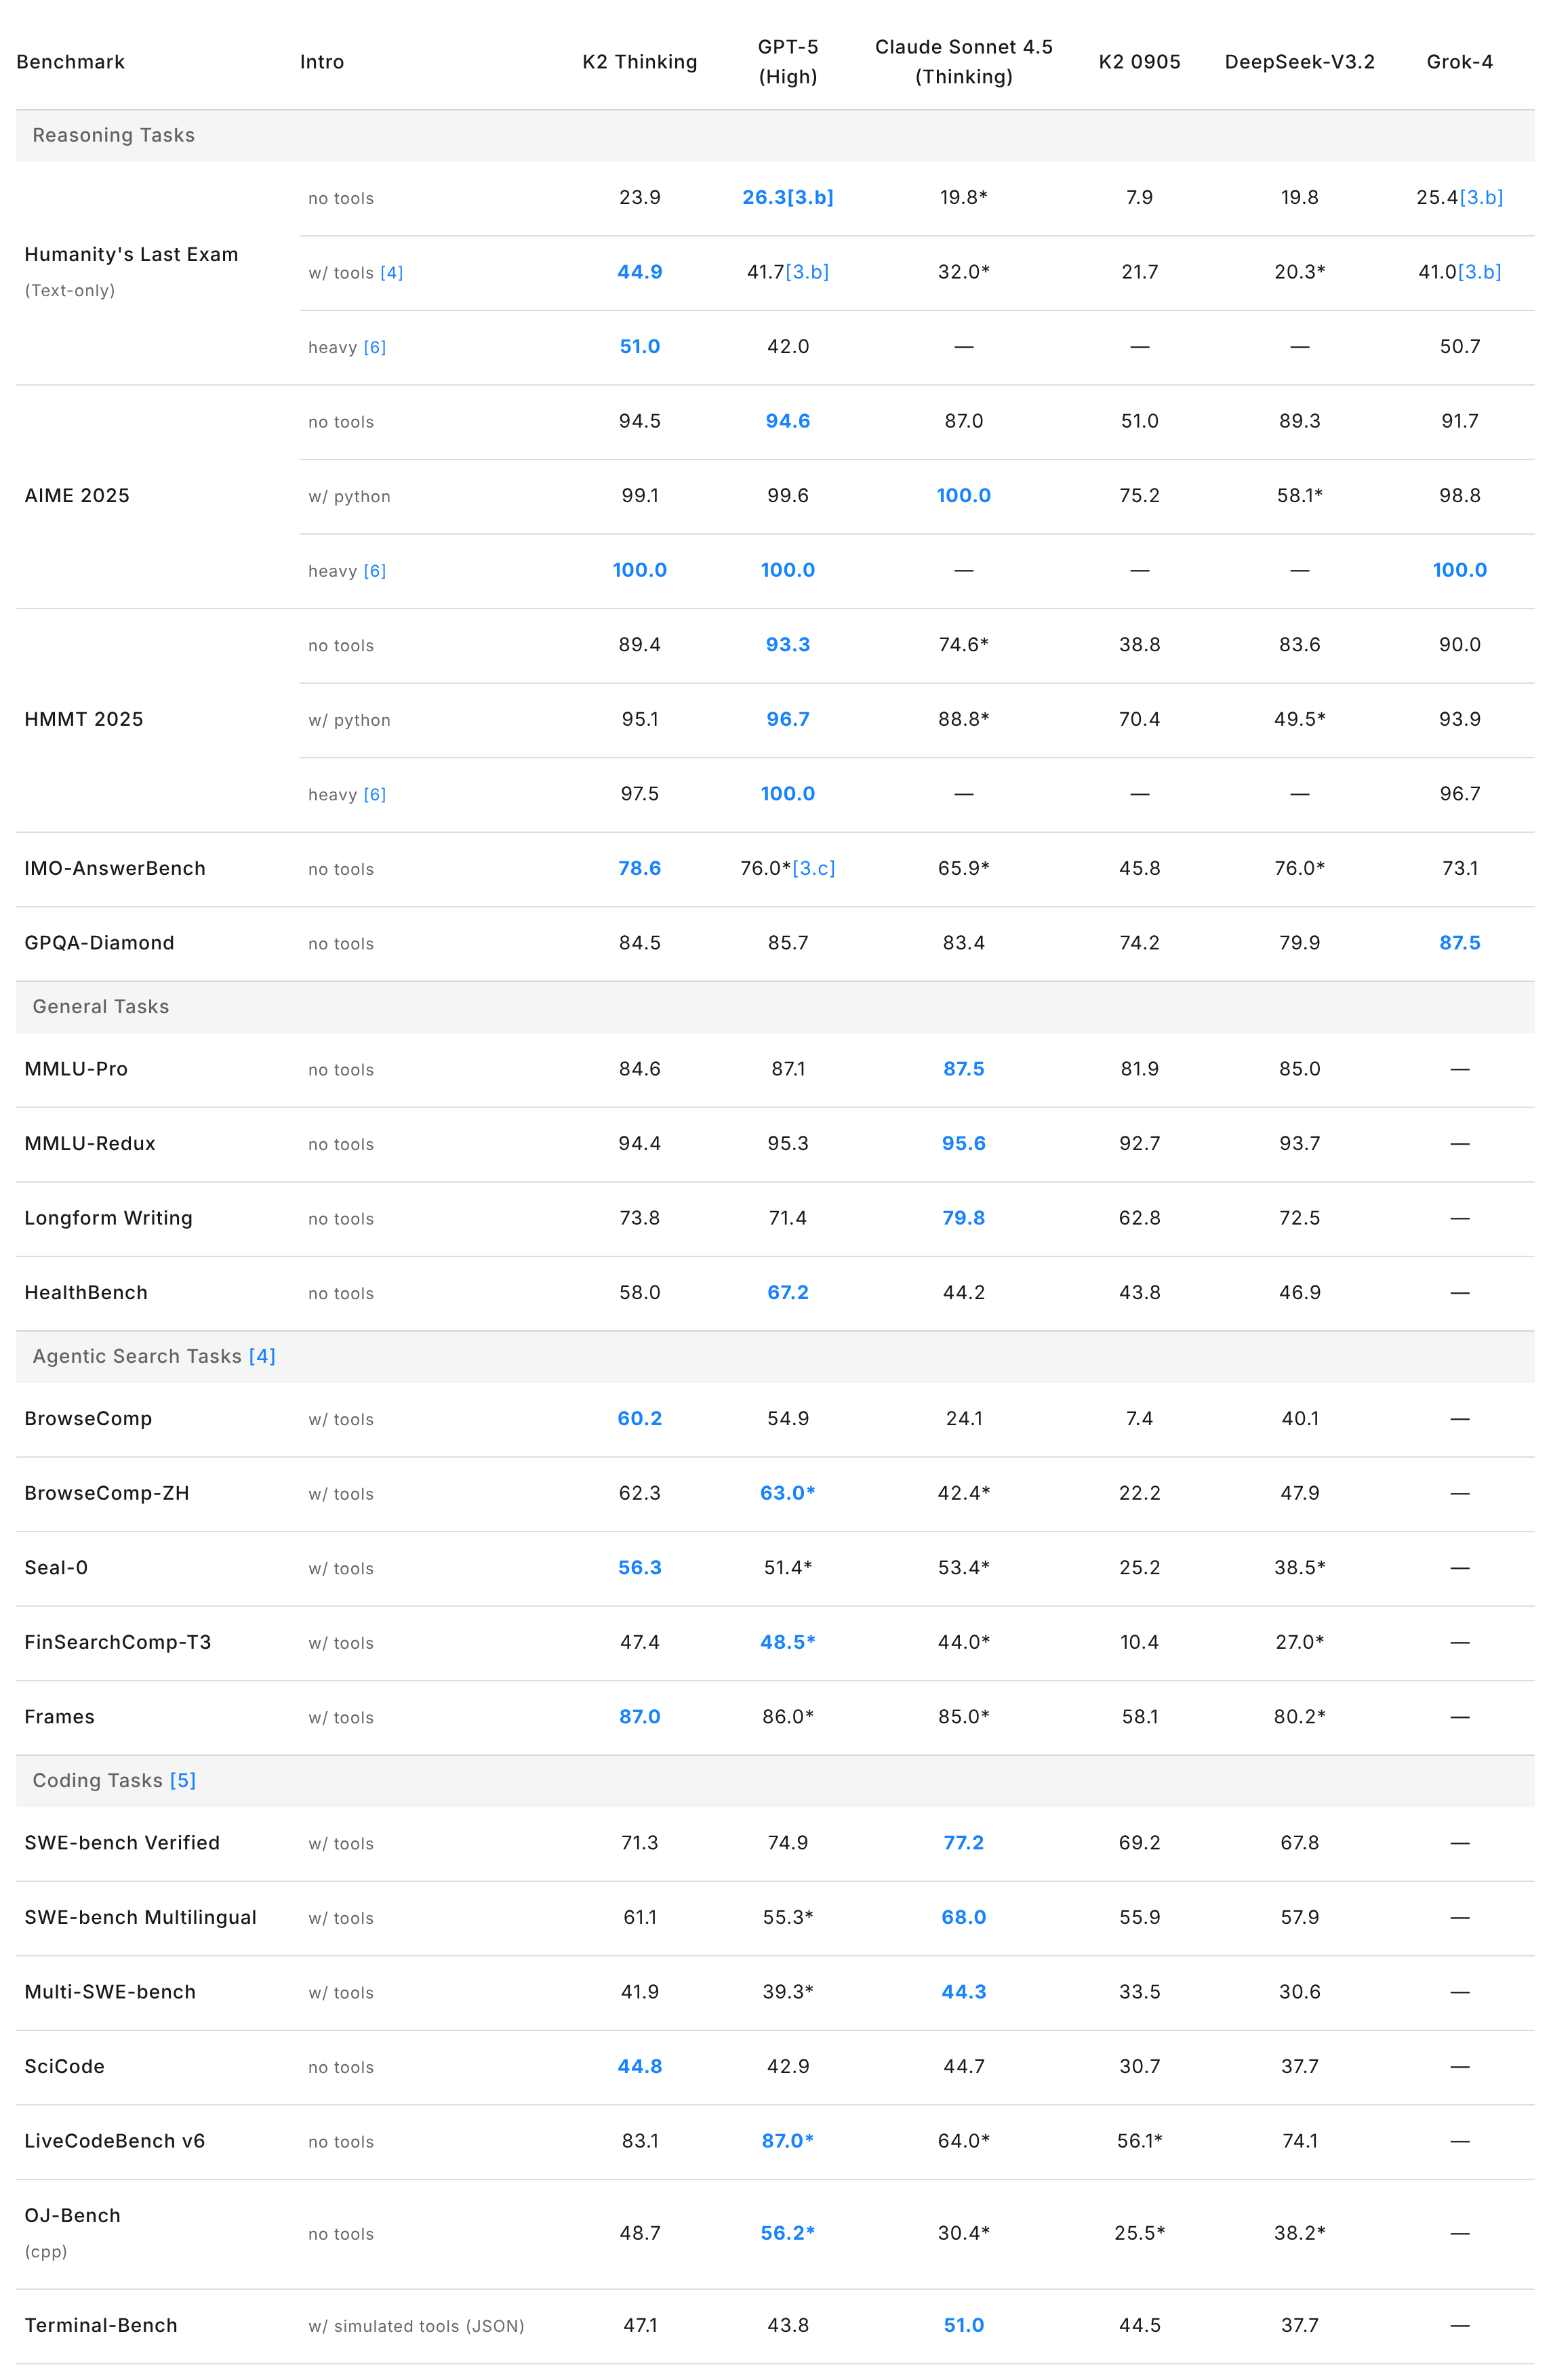
| Kimi K2 Thinking6 Nov 2025 · Moonshot AI | 23.9% | Introducing Kimi K2 ThinkingChecked A person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.Corroborated The same number is printed in 2 other lab documents: 1 2text-only subset; 96K thinking-token budget; INT4 precisionOur capture |
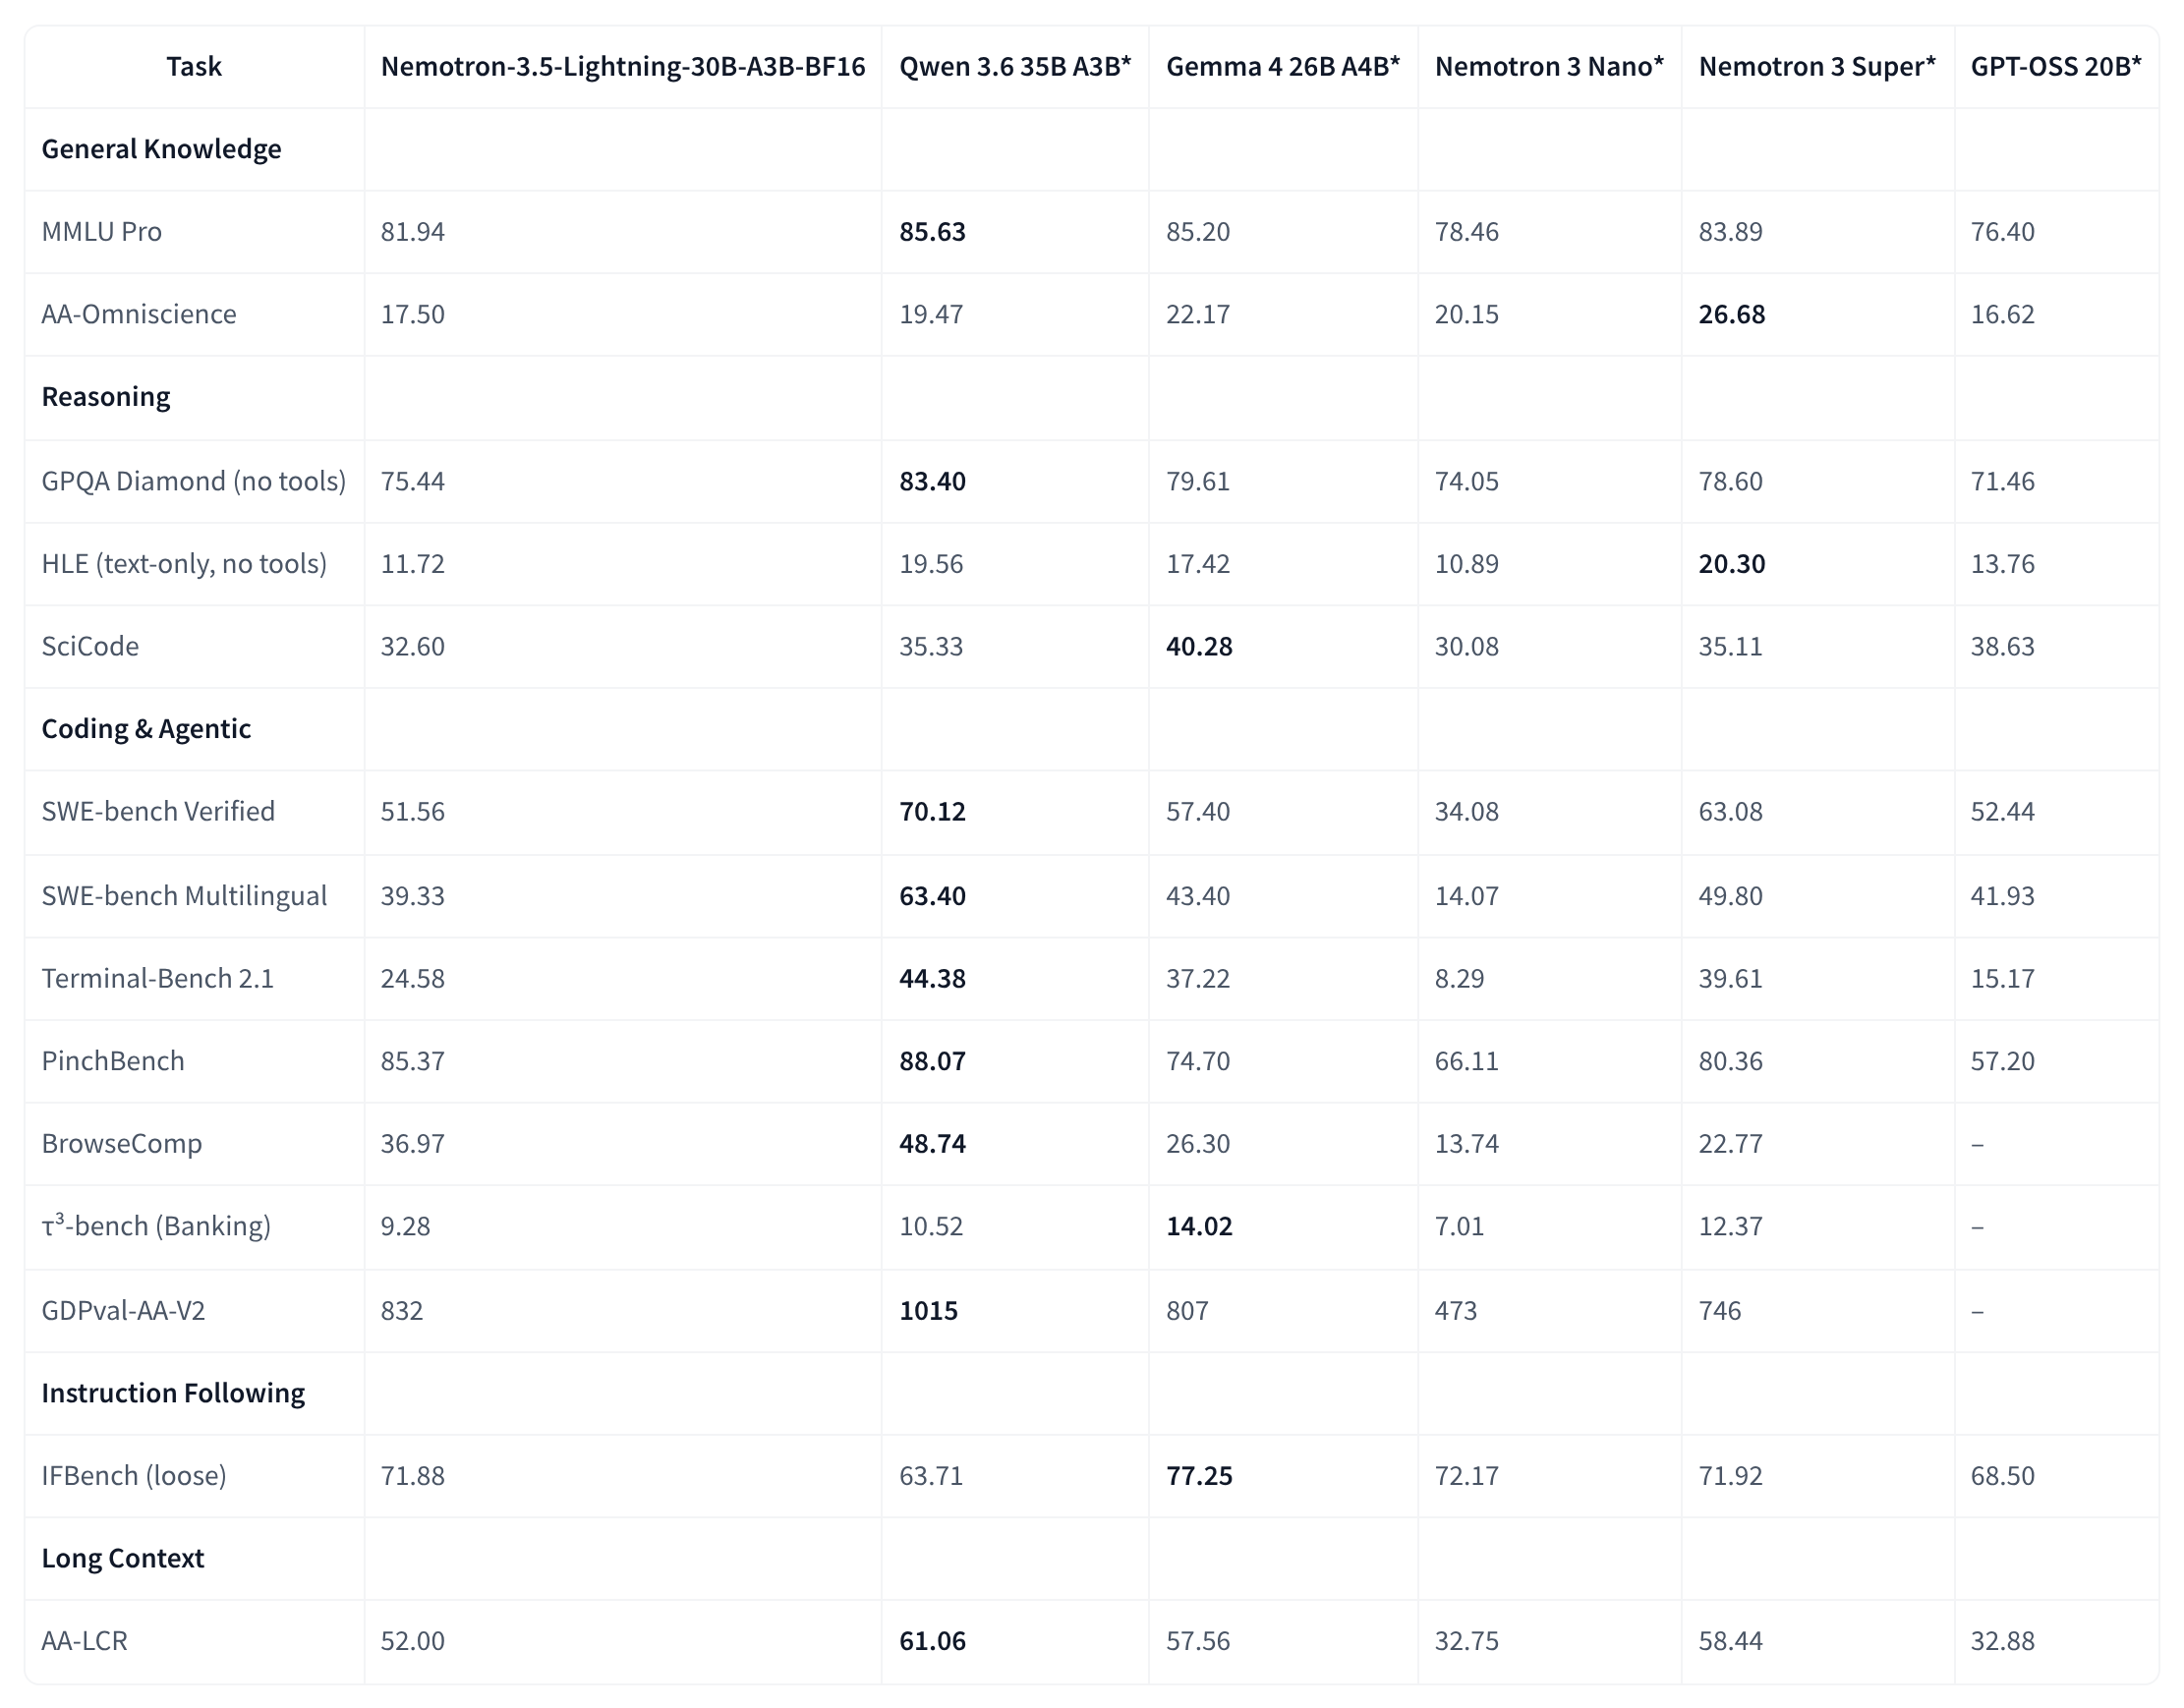
| Nemotron 3 Super 120B-A12B11 Mar 2026 · NVIDIA | 20.30% | Nemotron 3.5 Bolt 74B-A9B 24GB: A Hybrid Vision-Language Model for Local AICorroborated The same number is printed in 1 other lab document: 1reported laterOur capture |
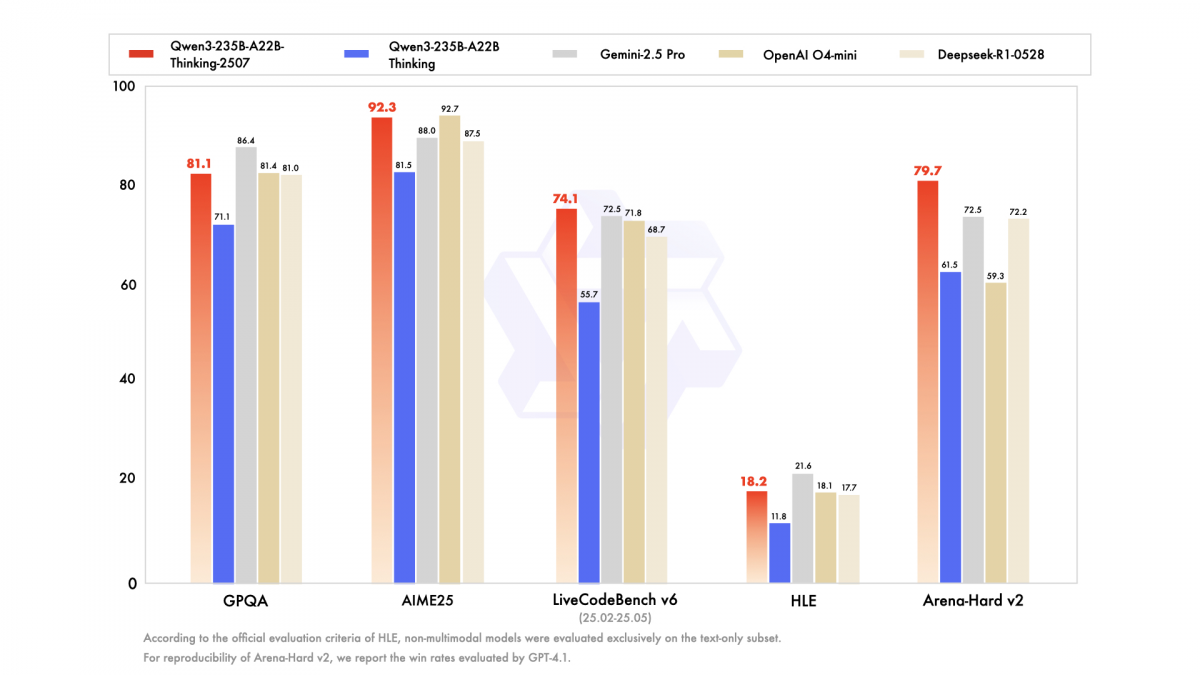
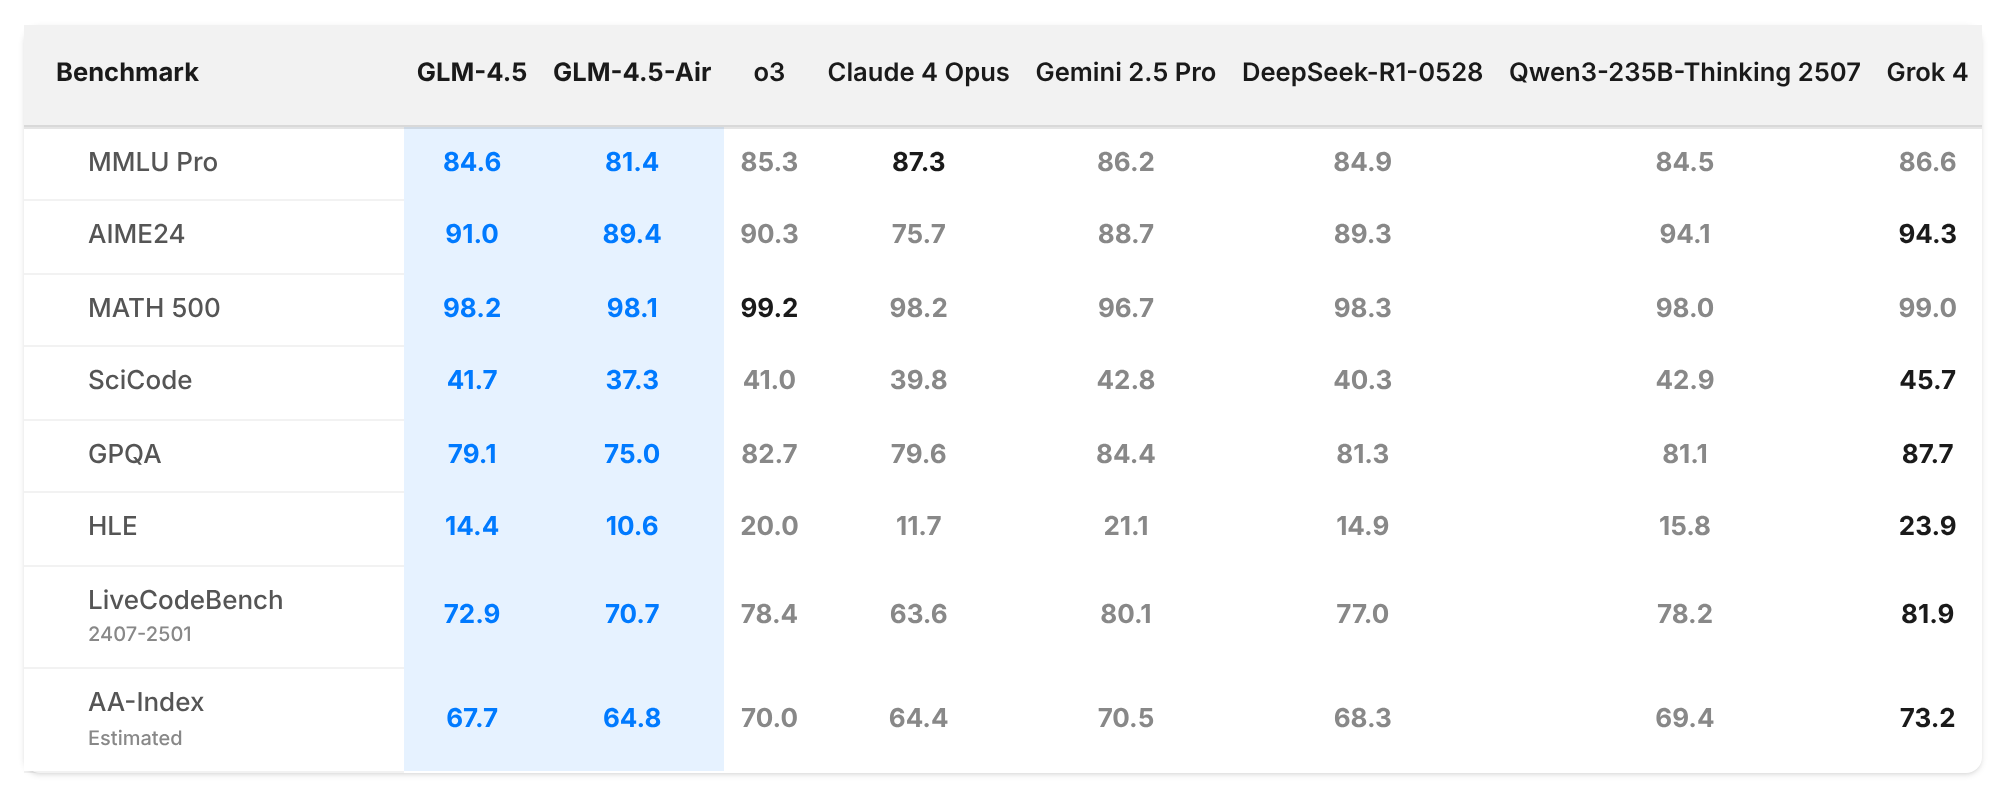
| Qwen3-235B-A22B-Thinking-250725 Jul 2025 · Alibaba | 18.2% | Alibaba Unveils New Qwen3 Models for Coding, Complexing Reasoning and Machine TranslationCorroborated The same number is printed in 1 other lab document: 1text-only subsetSource image |
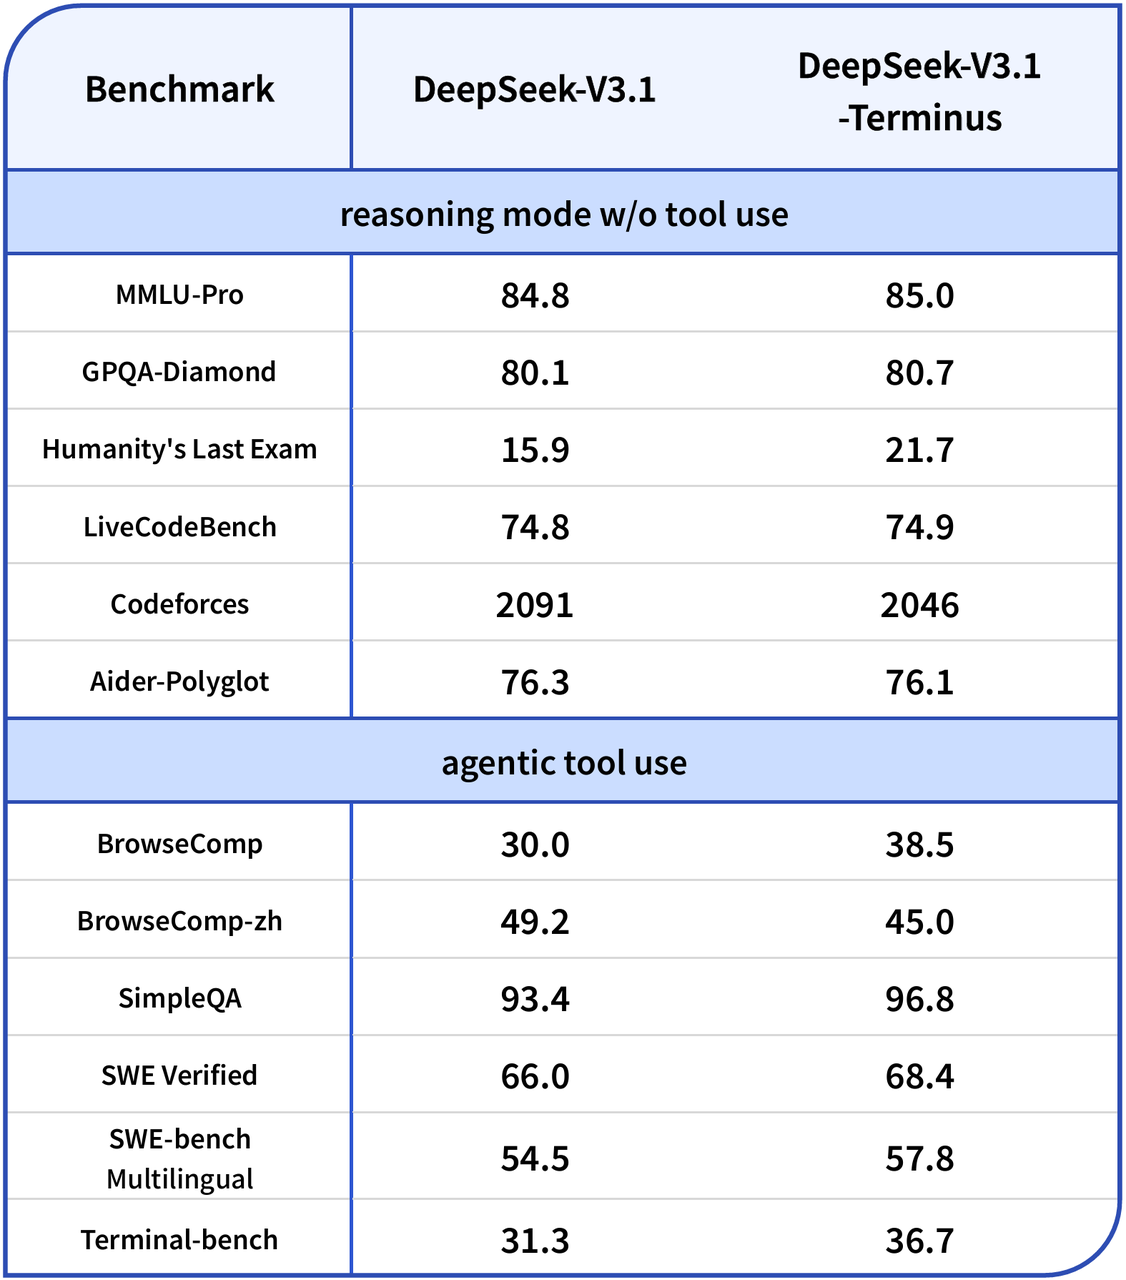
| DeepSeek-V3.121 Aug 2025 · DeepSeek | 15.9% | DeepSeek-V3.1-TerminusCorroborated The same number is printed in 2 other lab documents: 1 2reasoning mode; full or text-only set not stated; reported laterSource image |
| GLM-4.528 Jul 2025 · Z.ai | 14.4% | GLM-4.5: Reasoning, Coding, and Agentic AbililtiesChecked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.Corroborated The same number is printed in 1 other lab document: 1thinking mode; text-only questions; GPT-4o judgeOur capture |
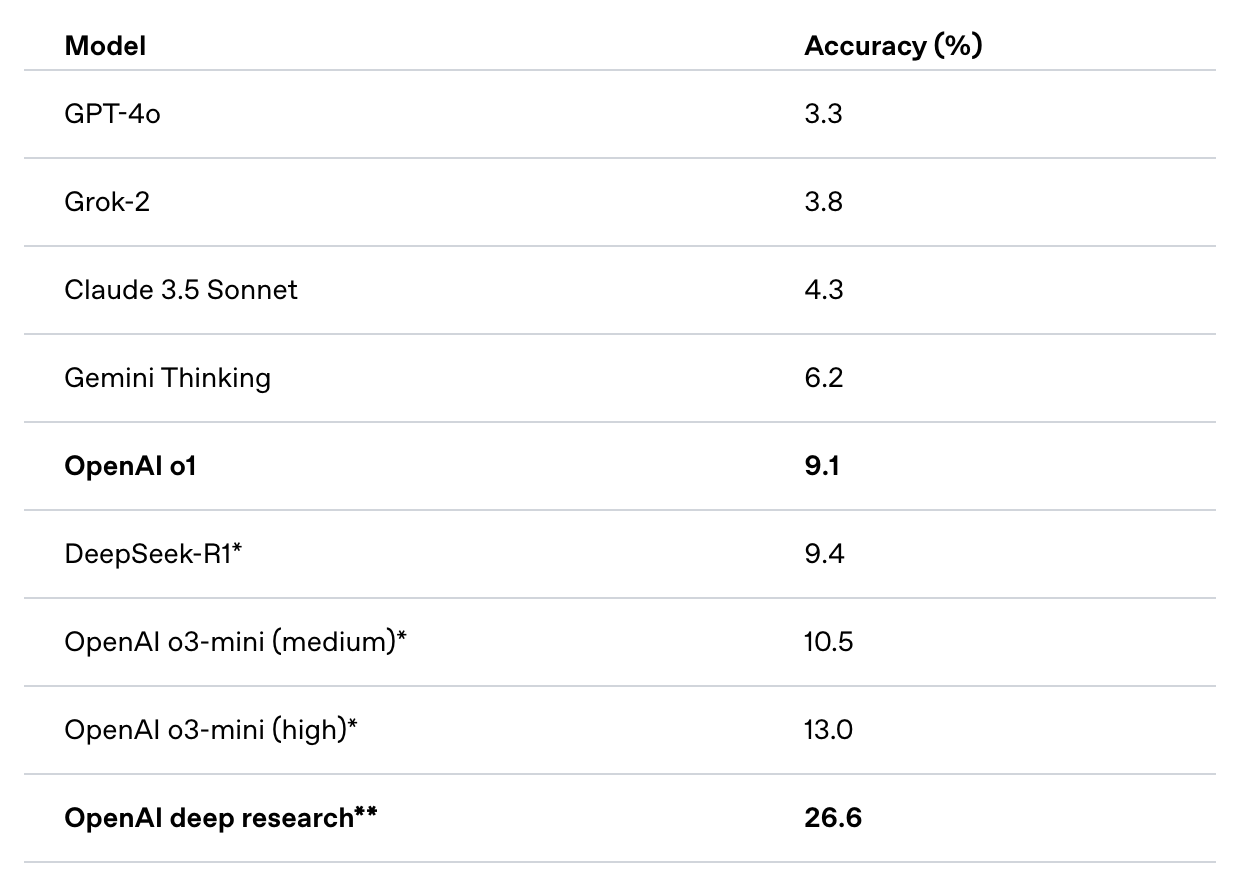
| o3-mini31 Jan 2025 · OpenAI | 13.0% | Introducing deep researchChecked A person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.high reasoning effort; reported laterOur capture |
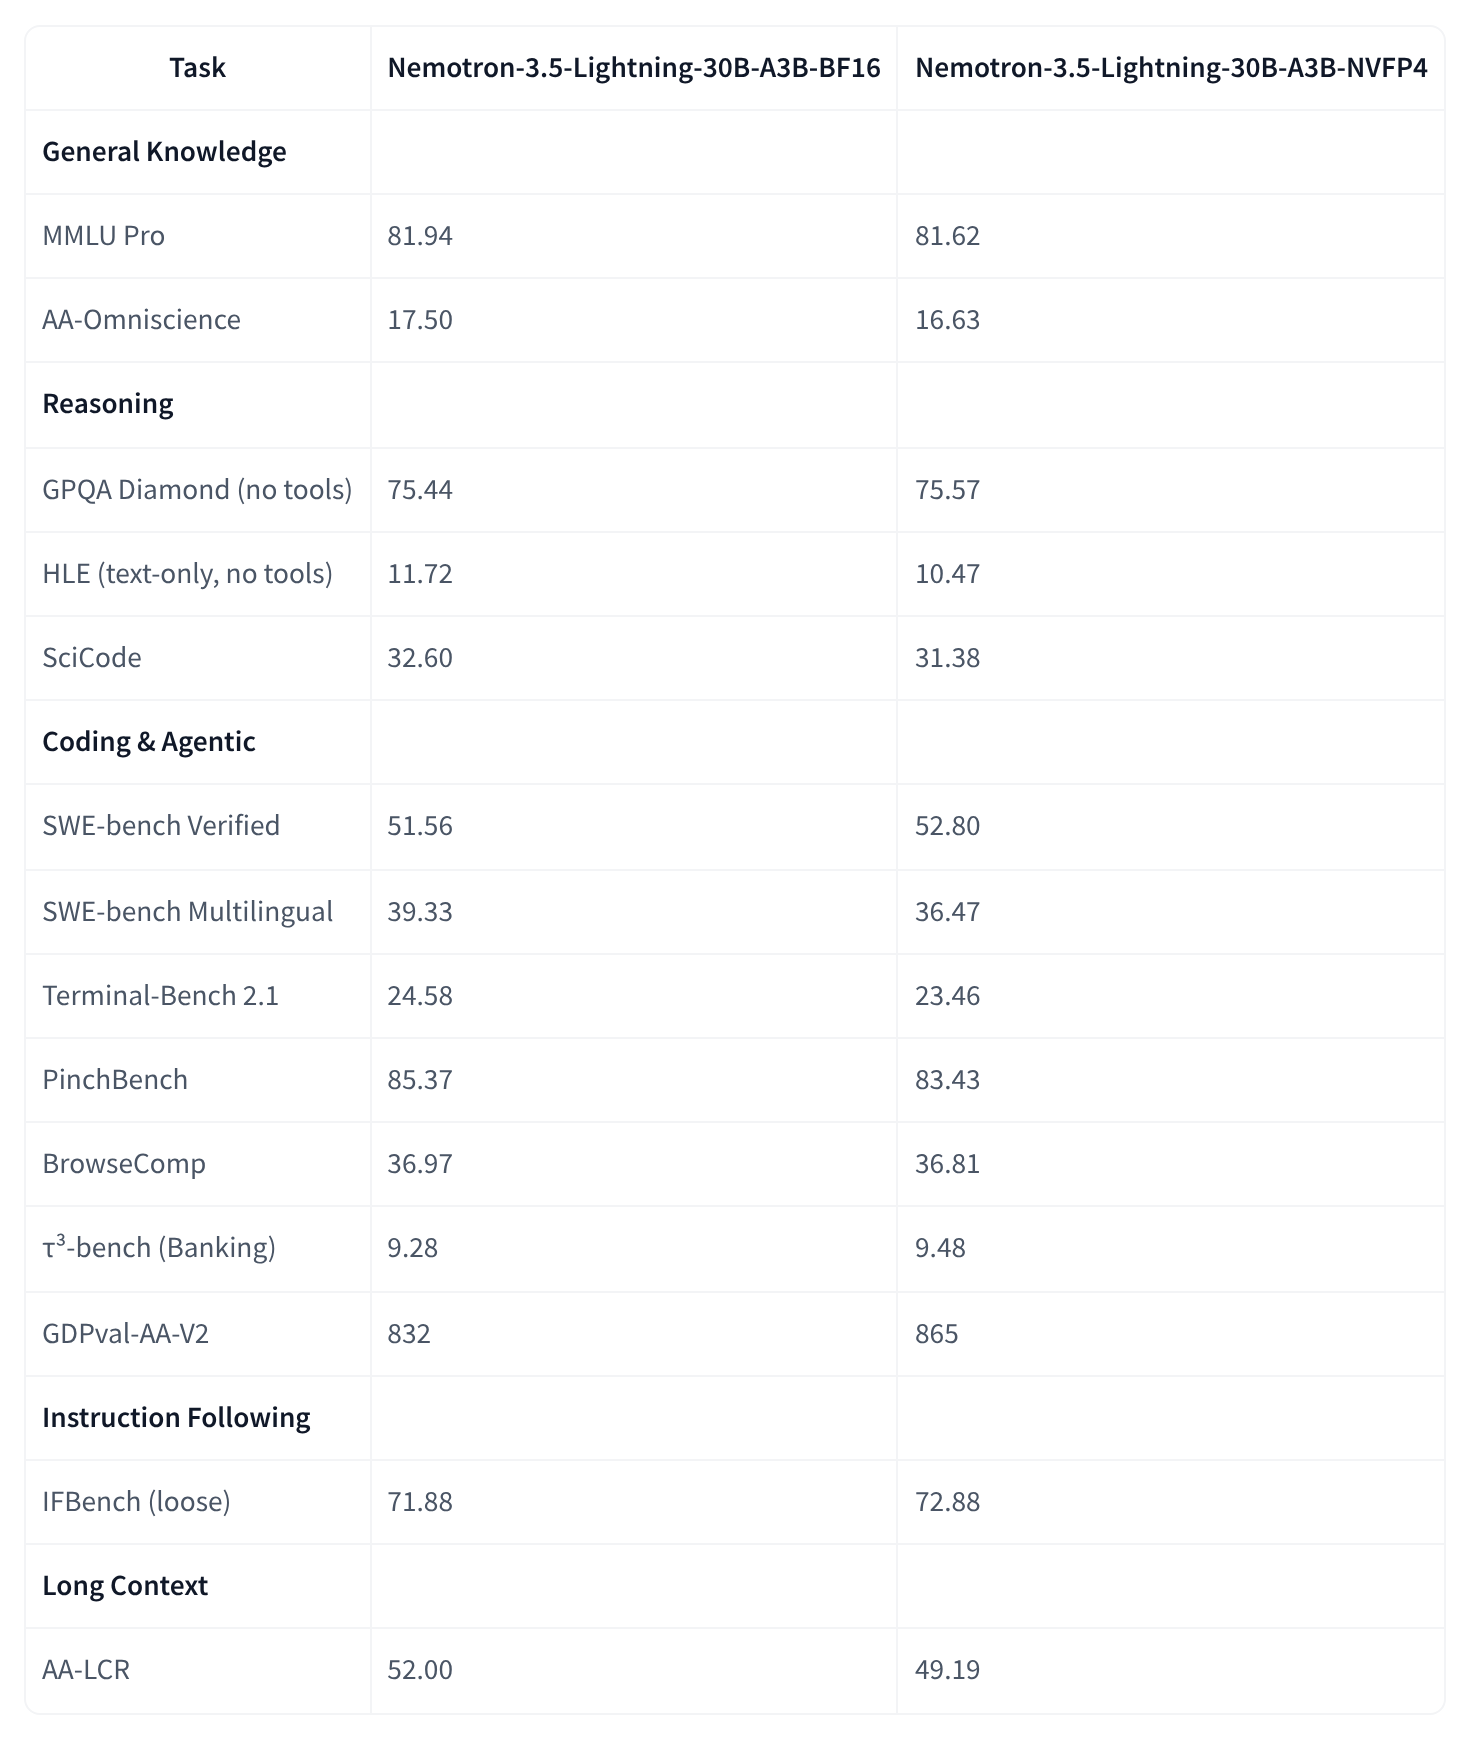
| Nemotron 3.5 Lightning 30B-A3B11 Aug 2026 · NVIDIA | 11.72% | nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 model card (launch-day revision)Checked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.Corroborated The same number is printed in 1 other lab document: 1text-only subsetOur capture |
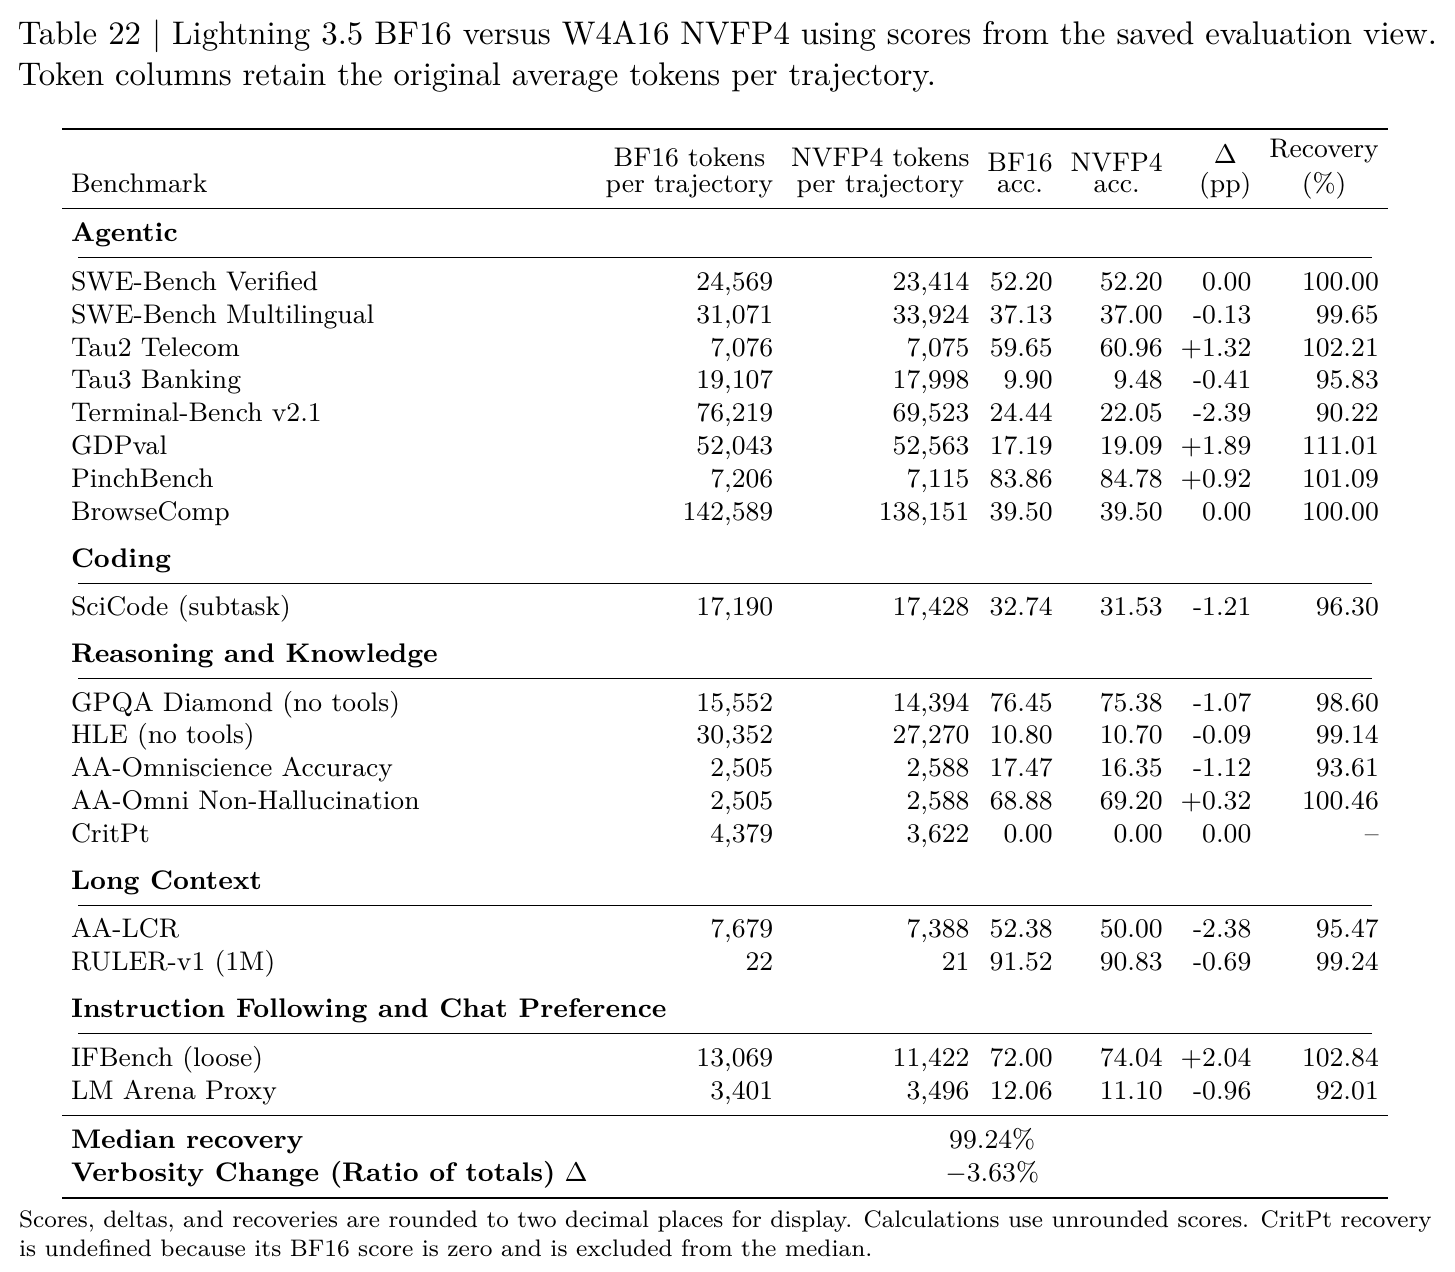
| Nemotron 3.5 Lightning 30B-A3B11 Aug 2026 · NVIDIA | 10.80% | Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AICorroborated The same number is printed in 1 other lab document: 1average of 2 runs; reported later; another report, not chartedOur capture |
| Nemotron 3 Nano 30B-A3B15 Dec 2025 · NVIDIA | 10.89% | nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16 model card (revision of 2026-08-11)Checked A person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.later re-run; text-only subset; reported laterOur capture |
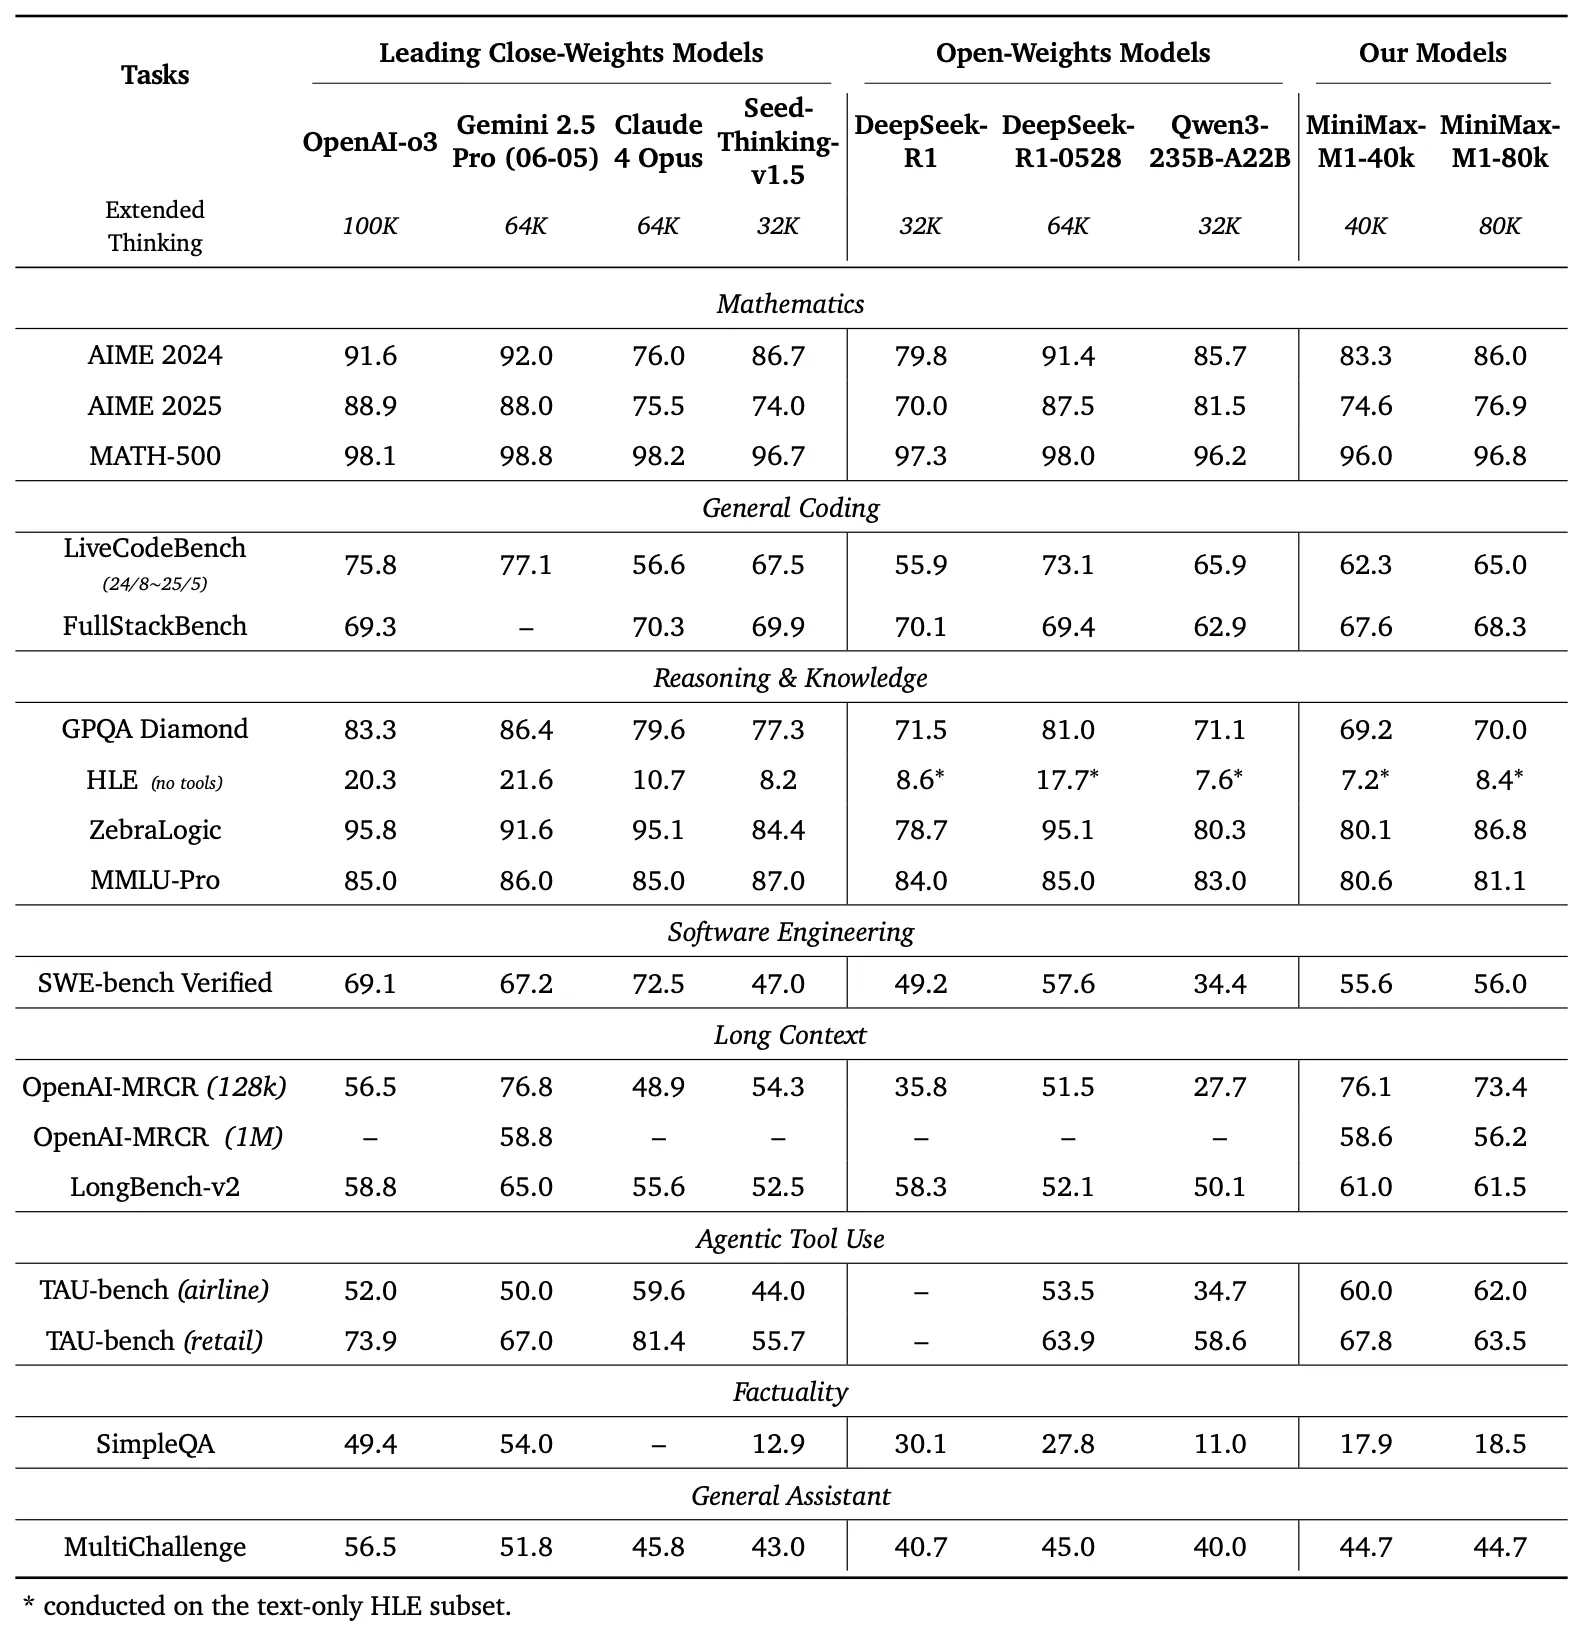
| MiniMax-M116 Jun 2025 · MiniMax | 8.4% | MiniMax-M1, the World's First Open-Source, Large-Scale, Hybrid-Attention Reasoning ModelChecked A person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.MiniMax-M1-80k, 80K thinking budget; text-only subsetSource image |