GLM-5
- Made by
- Z.ai
- Released
- Announced in
- GLM-5: From Vibe Coding to Agentic Engineeringz.ai
- Event
- GLM-5
- API record
- /api/v1/models/glm-5
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
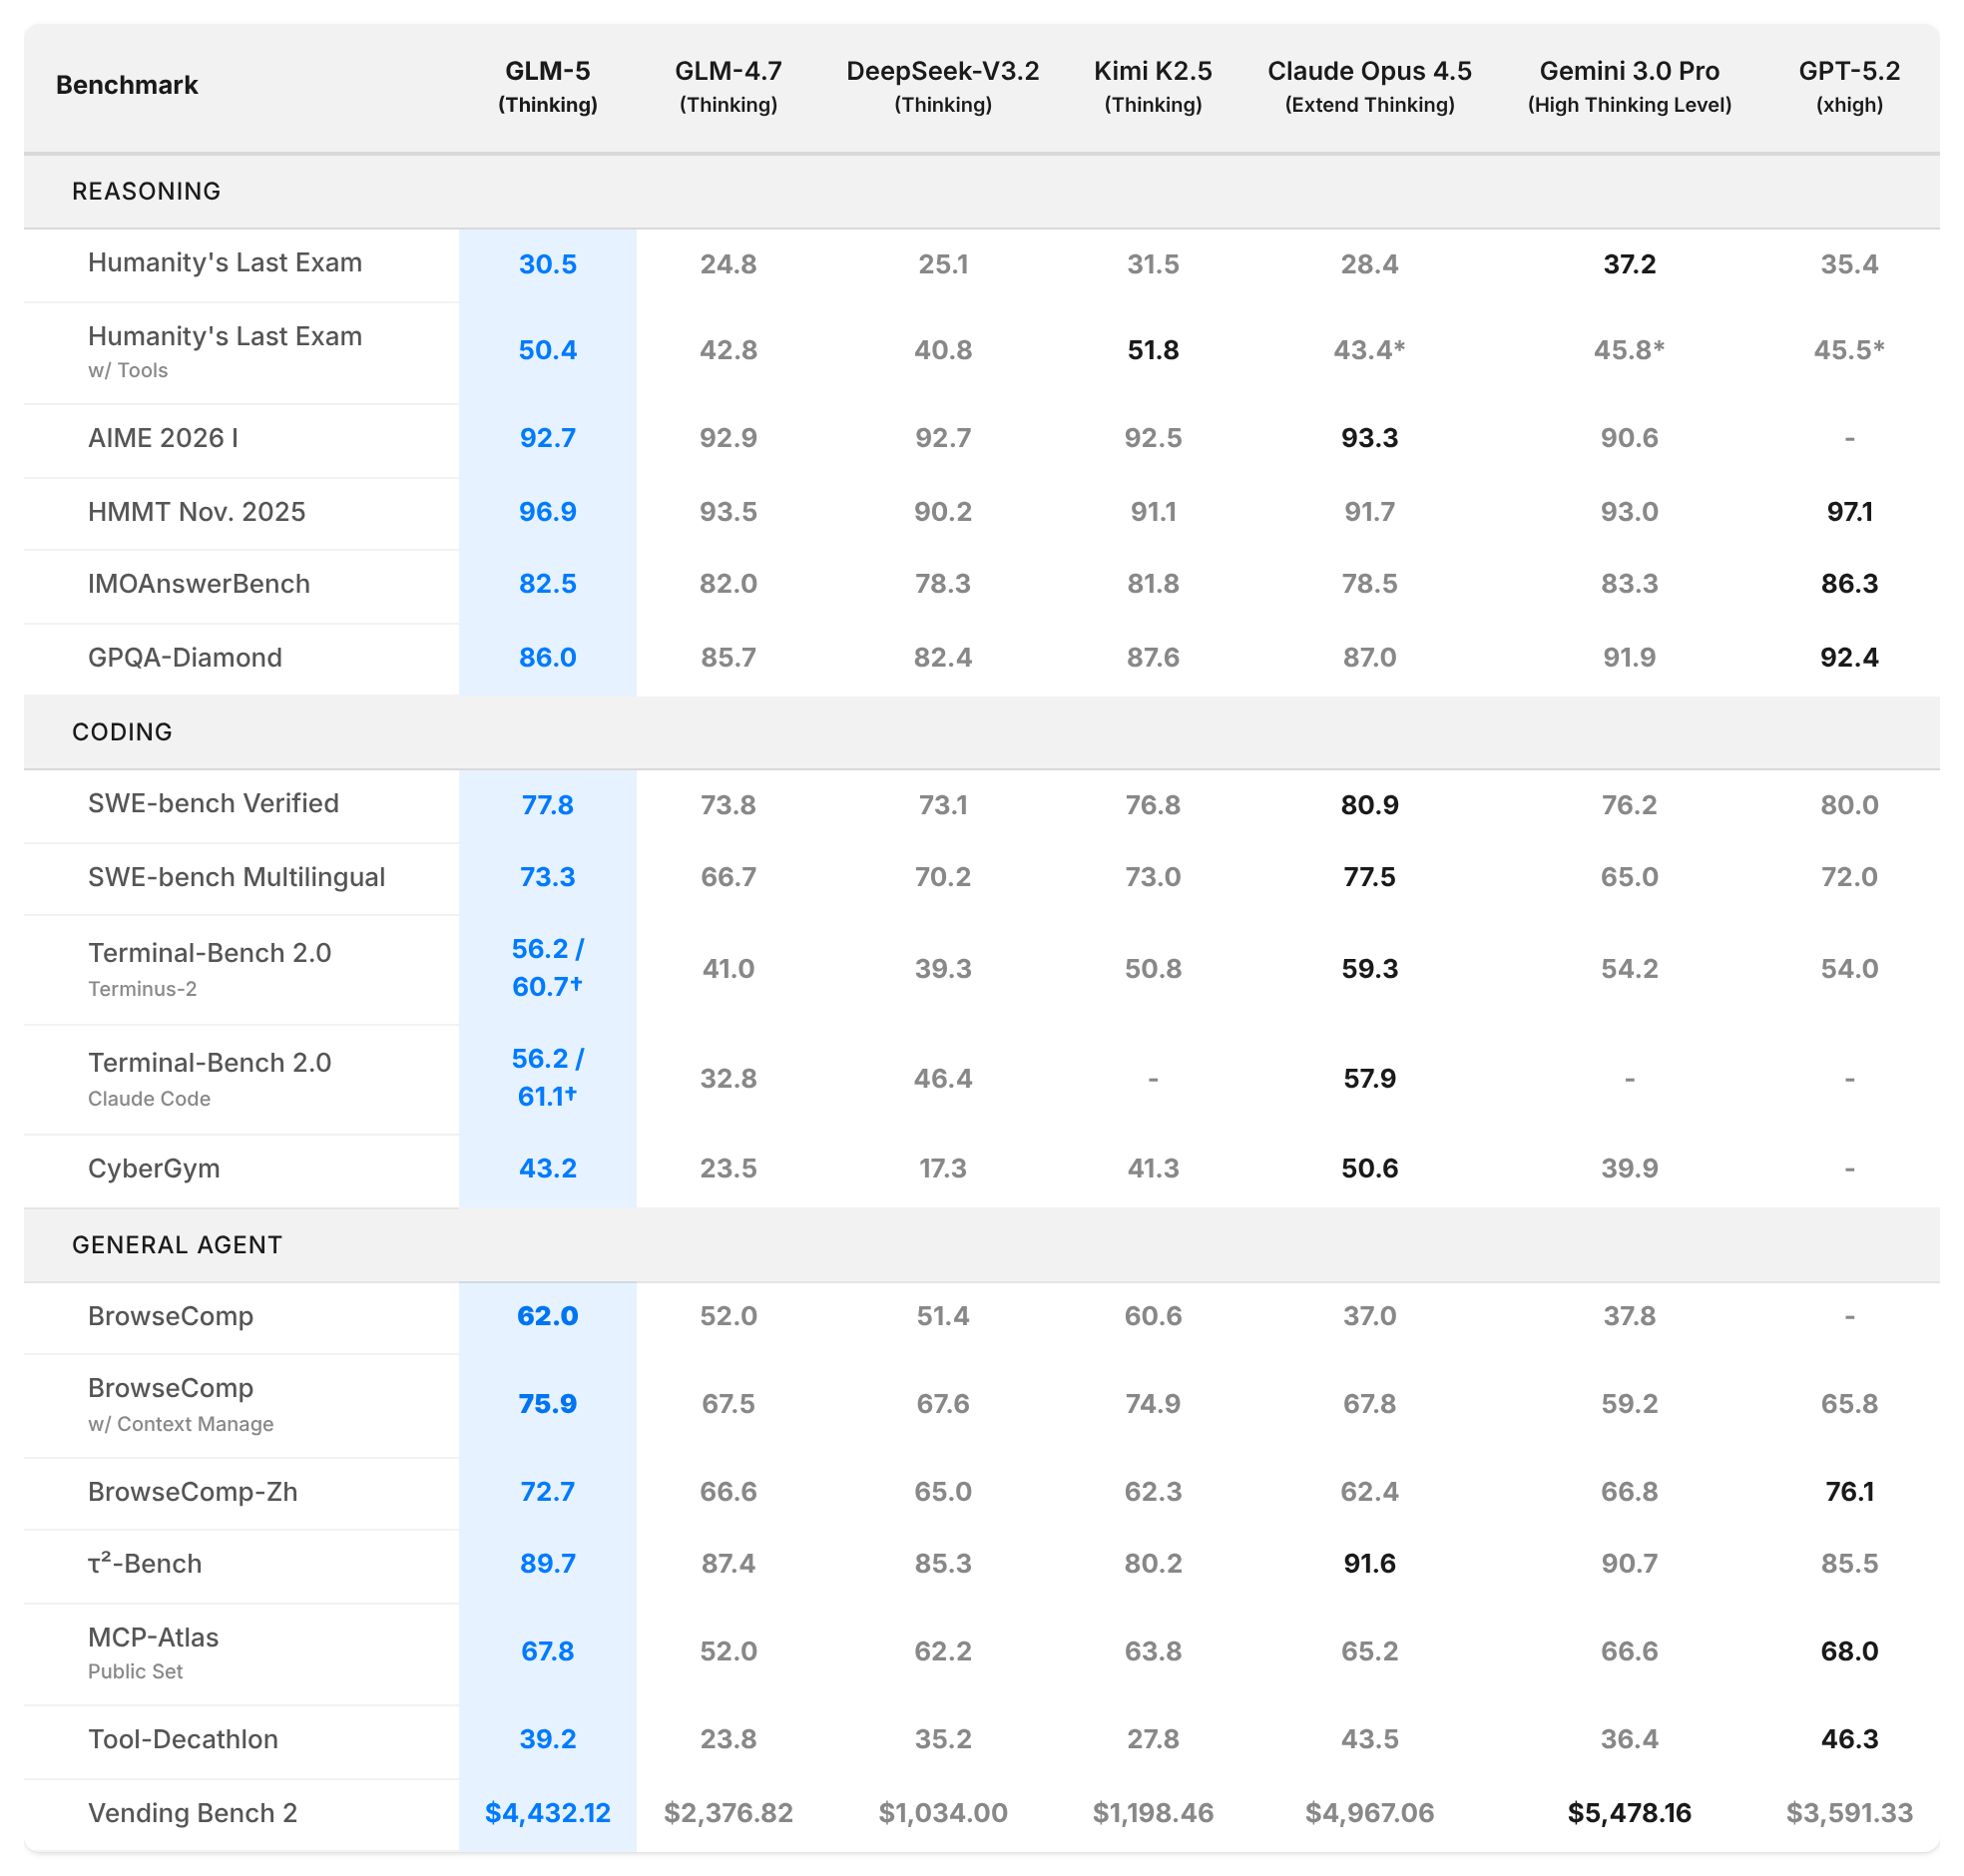
| Humanity's Last ExamNo tools · text-only subset; GPT-5.2 judge; up to 131,072 output tokens | 30.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Humanity's Last ExamWith tools · text-only subset; GPT-5.2 judge; 202,752-token context | 50.4% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| SWE-bench VerifiedOpenHands with a tailored prompt; 200K context | 77.8% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
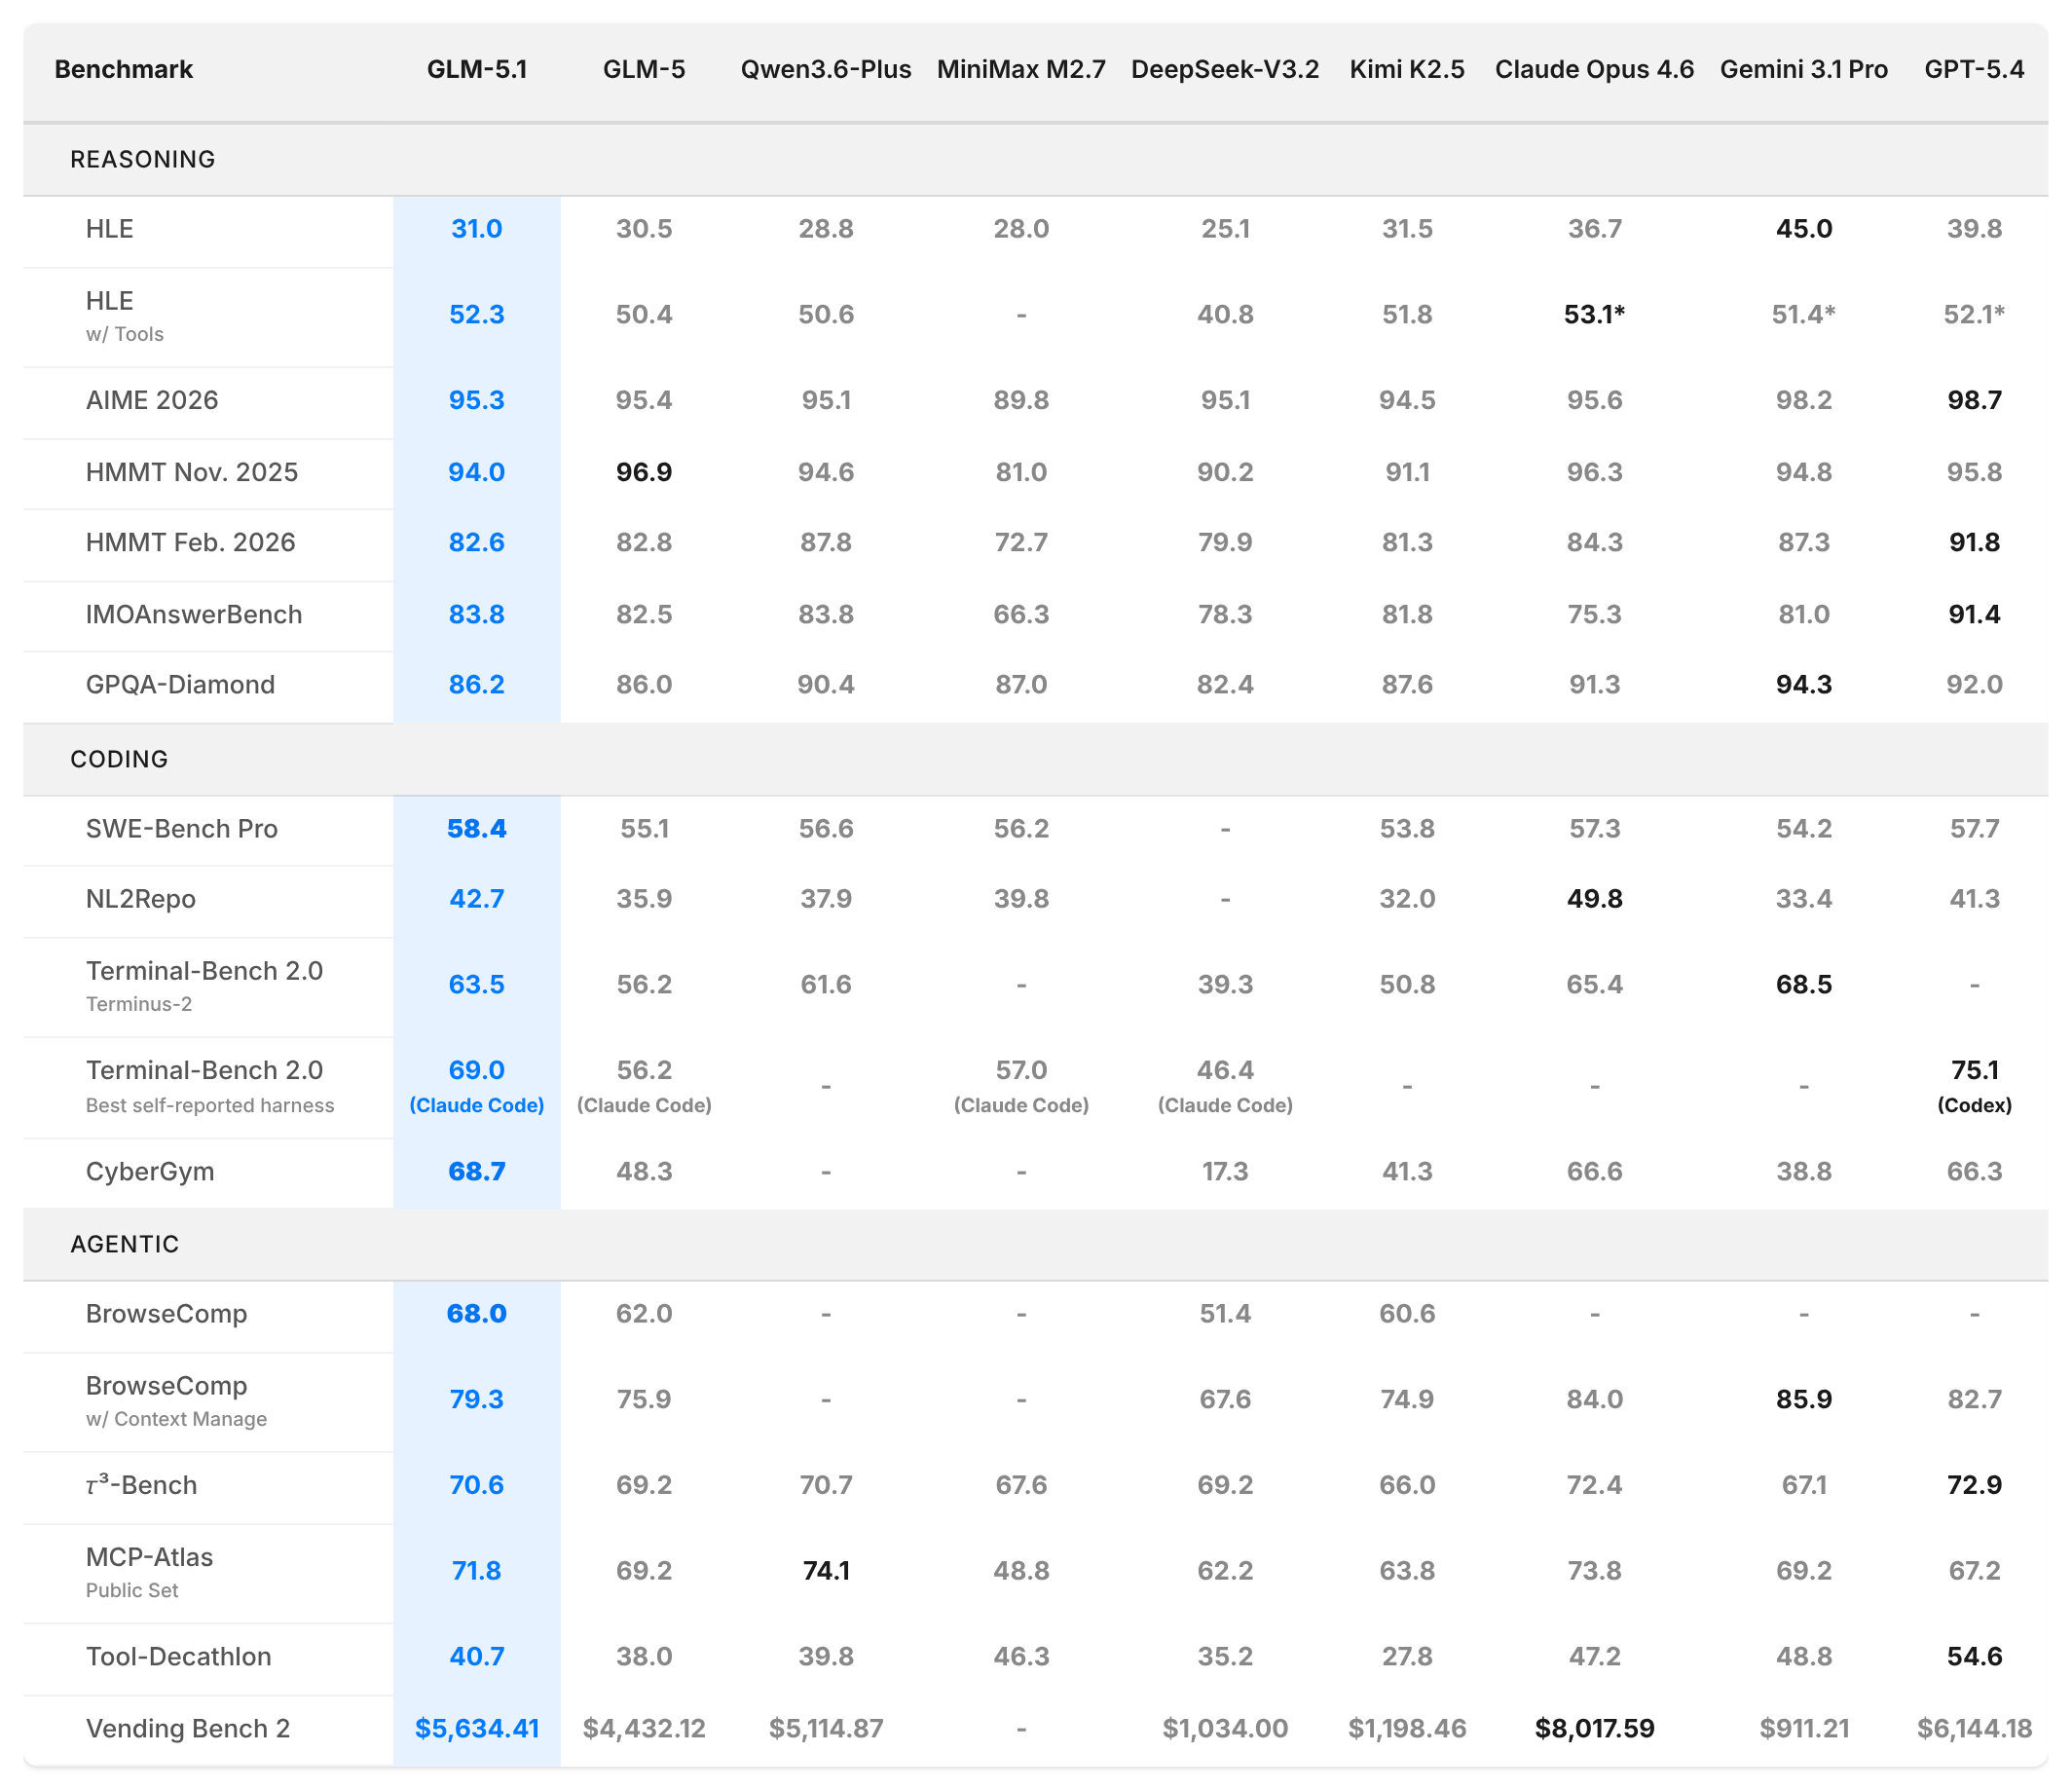
| SWE-bench ProOpenHands with a tailored prompt · reported later, in GLM-5.1: Towards Long-Horizon Tasks · The source doesn't say whether this is the public or the commercial set | 55.1% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| GPQA Diamondup to 131,072 output tokens | 86.0% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| BrowseCompwithout context management: keeps the last 5 turns | 62.0% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| with context management, discard-all strategy | 75.9% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| Terminal-Bench 2.0Terminus 2 harness; 2h timeout; 128K context (60.7 on Z.ai's verified version of the benchmark) | 56.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Claude Code harness, thinking; no time limit; averaged over 5 runs (61.1 on Z.ai's verified version of the benchmark) | 56.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| MCP Atlas500-task public set; thinking mode; 10-minute timeout per task; Gemini 3 Pro judge | 67.8% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| 500-task public set; Gemini 3 Pro judge · reported later, in GLM-5.1: Towards Long-Horizon Tasks | 69.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by Z.ai
- GLM-5: From Vibe Coding to Agentic Engineeringz.ai · 12 Feb 2026
Our capture of the source - GLM-5.1: Towards Long-Horizon Tasksz.ai · 7 Apr 2026
Our capture of the source