Frontier Log

The Harness Is Part of the Score

How a model's score on an agentic coding benchmark changes with the agent harness it runs in, from the labs' own per-harness reports.
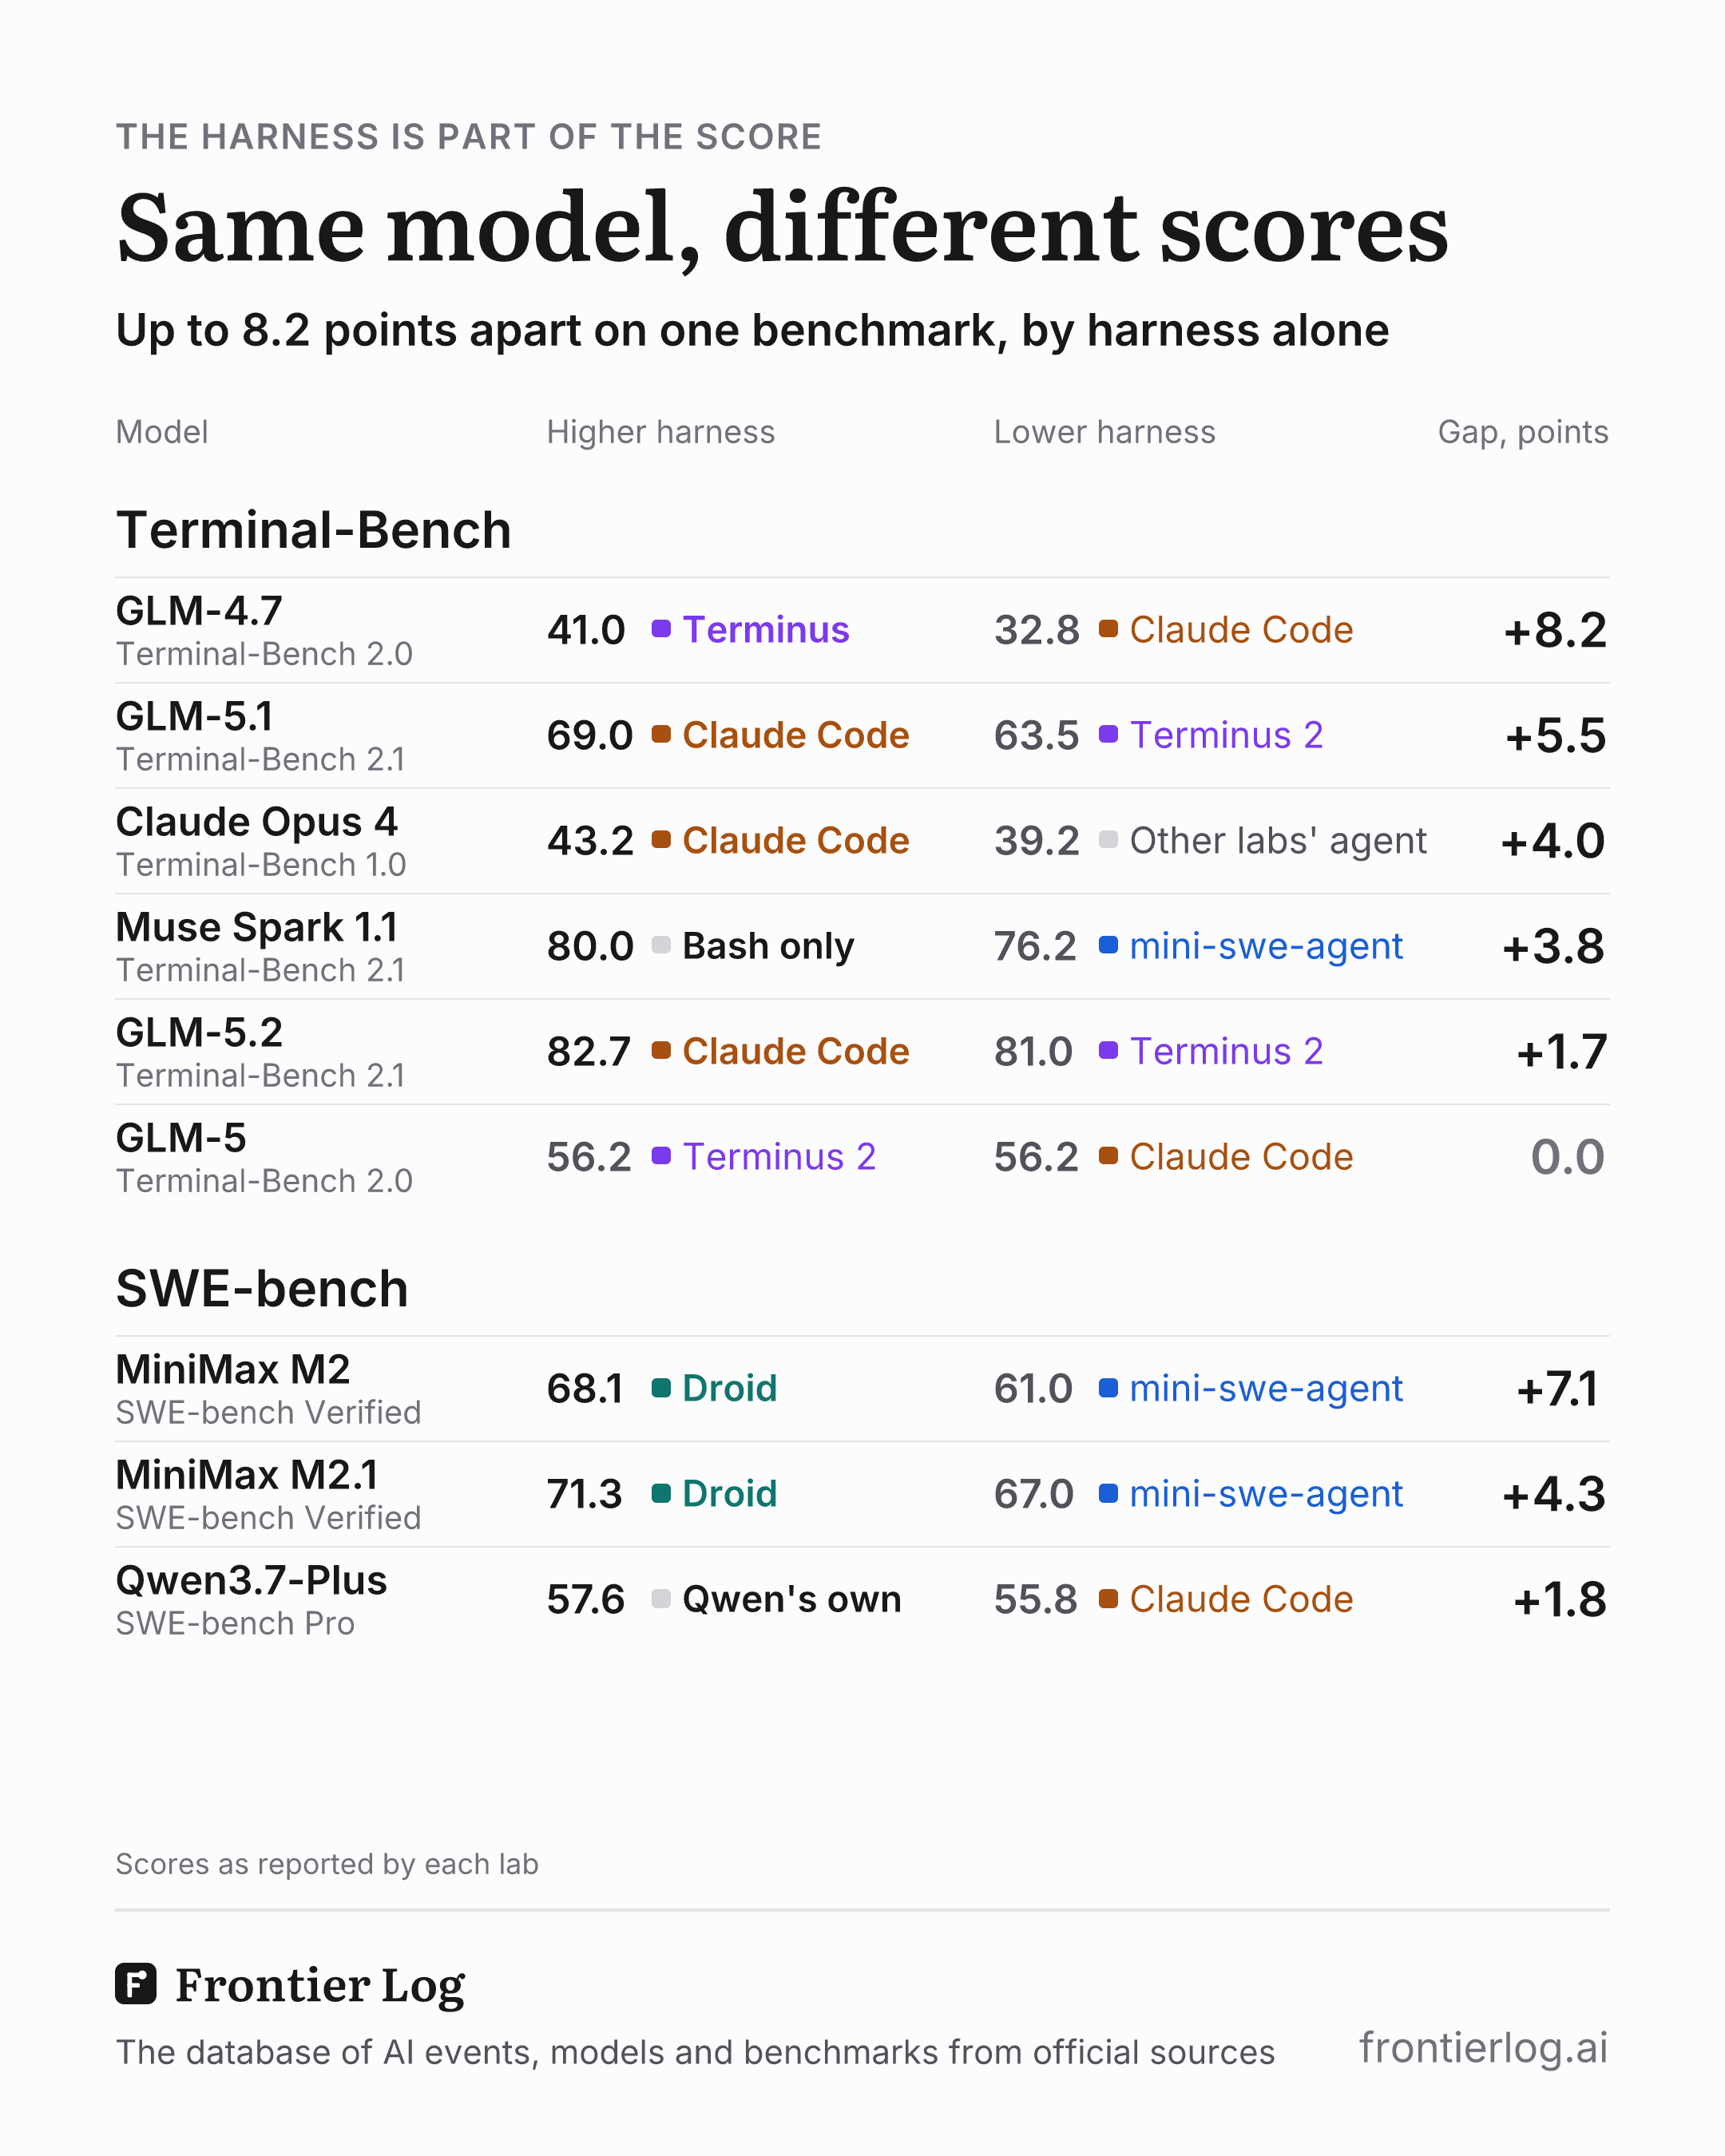
Nine models whose labs report one benchmark under two harnesses, in two sections, widest gap first, with Claude Code, mini-swe-agent, Terminus and Droid each in its own colour. Terminal-Bench: GLM-4.7 on 2.0 (Terminus 41.0, Claude Code 32.8, 8.2 points), GLM-5.1 on 2.1 (Claude Code 69.0, Terminus 2 63.5, 5.5), Claude Opus 4 on 1.0 (Claude Code 43.2, the agent used for other labs' models 39.2, 4.0), Muse Spark 1.1 on 2.1 (bash only 80.0, mini-swe-agent 76.2, 3.8), GLM-5.2 on 2.1 (Claude Code 82.7, Terminus 2 81.0, 1.7), GLM-5 on 2.0 (56.2 in both). SWE-bench: MiniMax M2 on Verified (Droid 68.1, mini-swe-agent 61.0, 7.1), MiniMax M2.1 on Verified (Droid 71.3, mini-swe-agent 67.0, 4.3), Qwen3.7-Plus on Pro (Qwen's own harness 57.6, Claude Code 55.8, 1.8).

Same model, different scores

Up to 8.2 points apart on one benchmark, by harness alone

Other labs report the same model under two harnesses, with gaps from none (GLM-5, Terminal-Bench 2.0) to 8.2 points (GLM-4.7). The same pair can swap order: Claude Code trails Terminus for GLM-4.7, ties it for GLM-5 and leads it for GLM-5.1 and GLM-5.2.
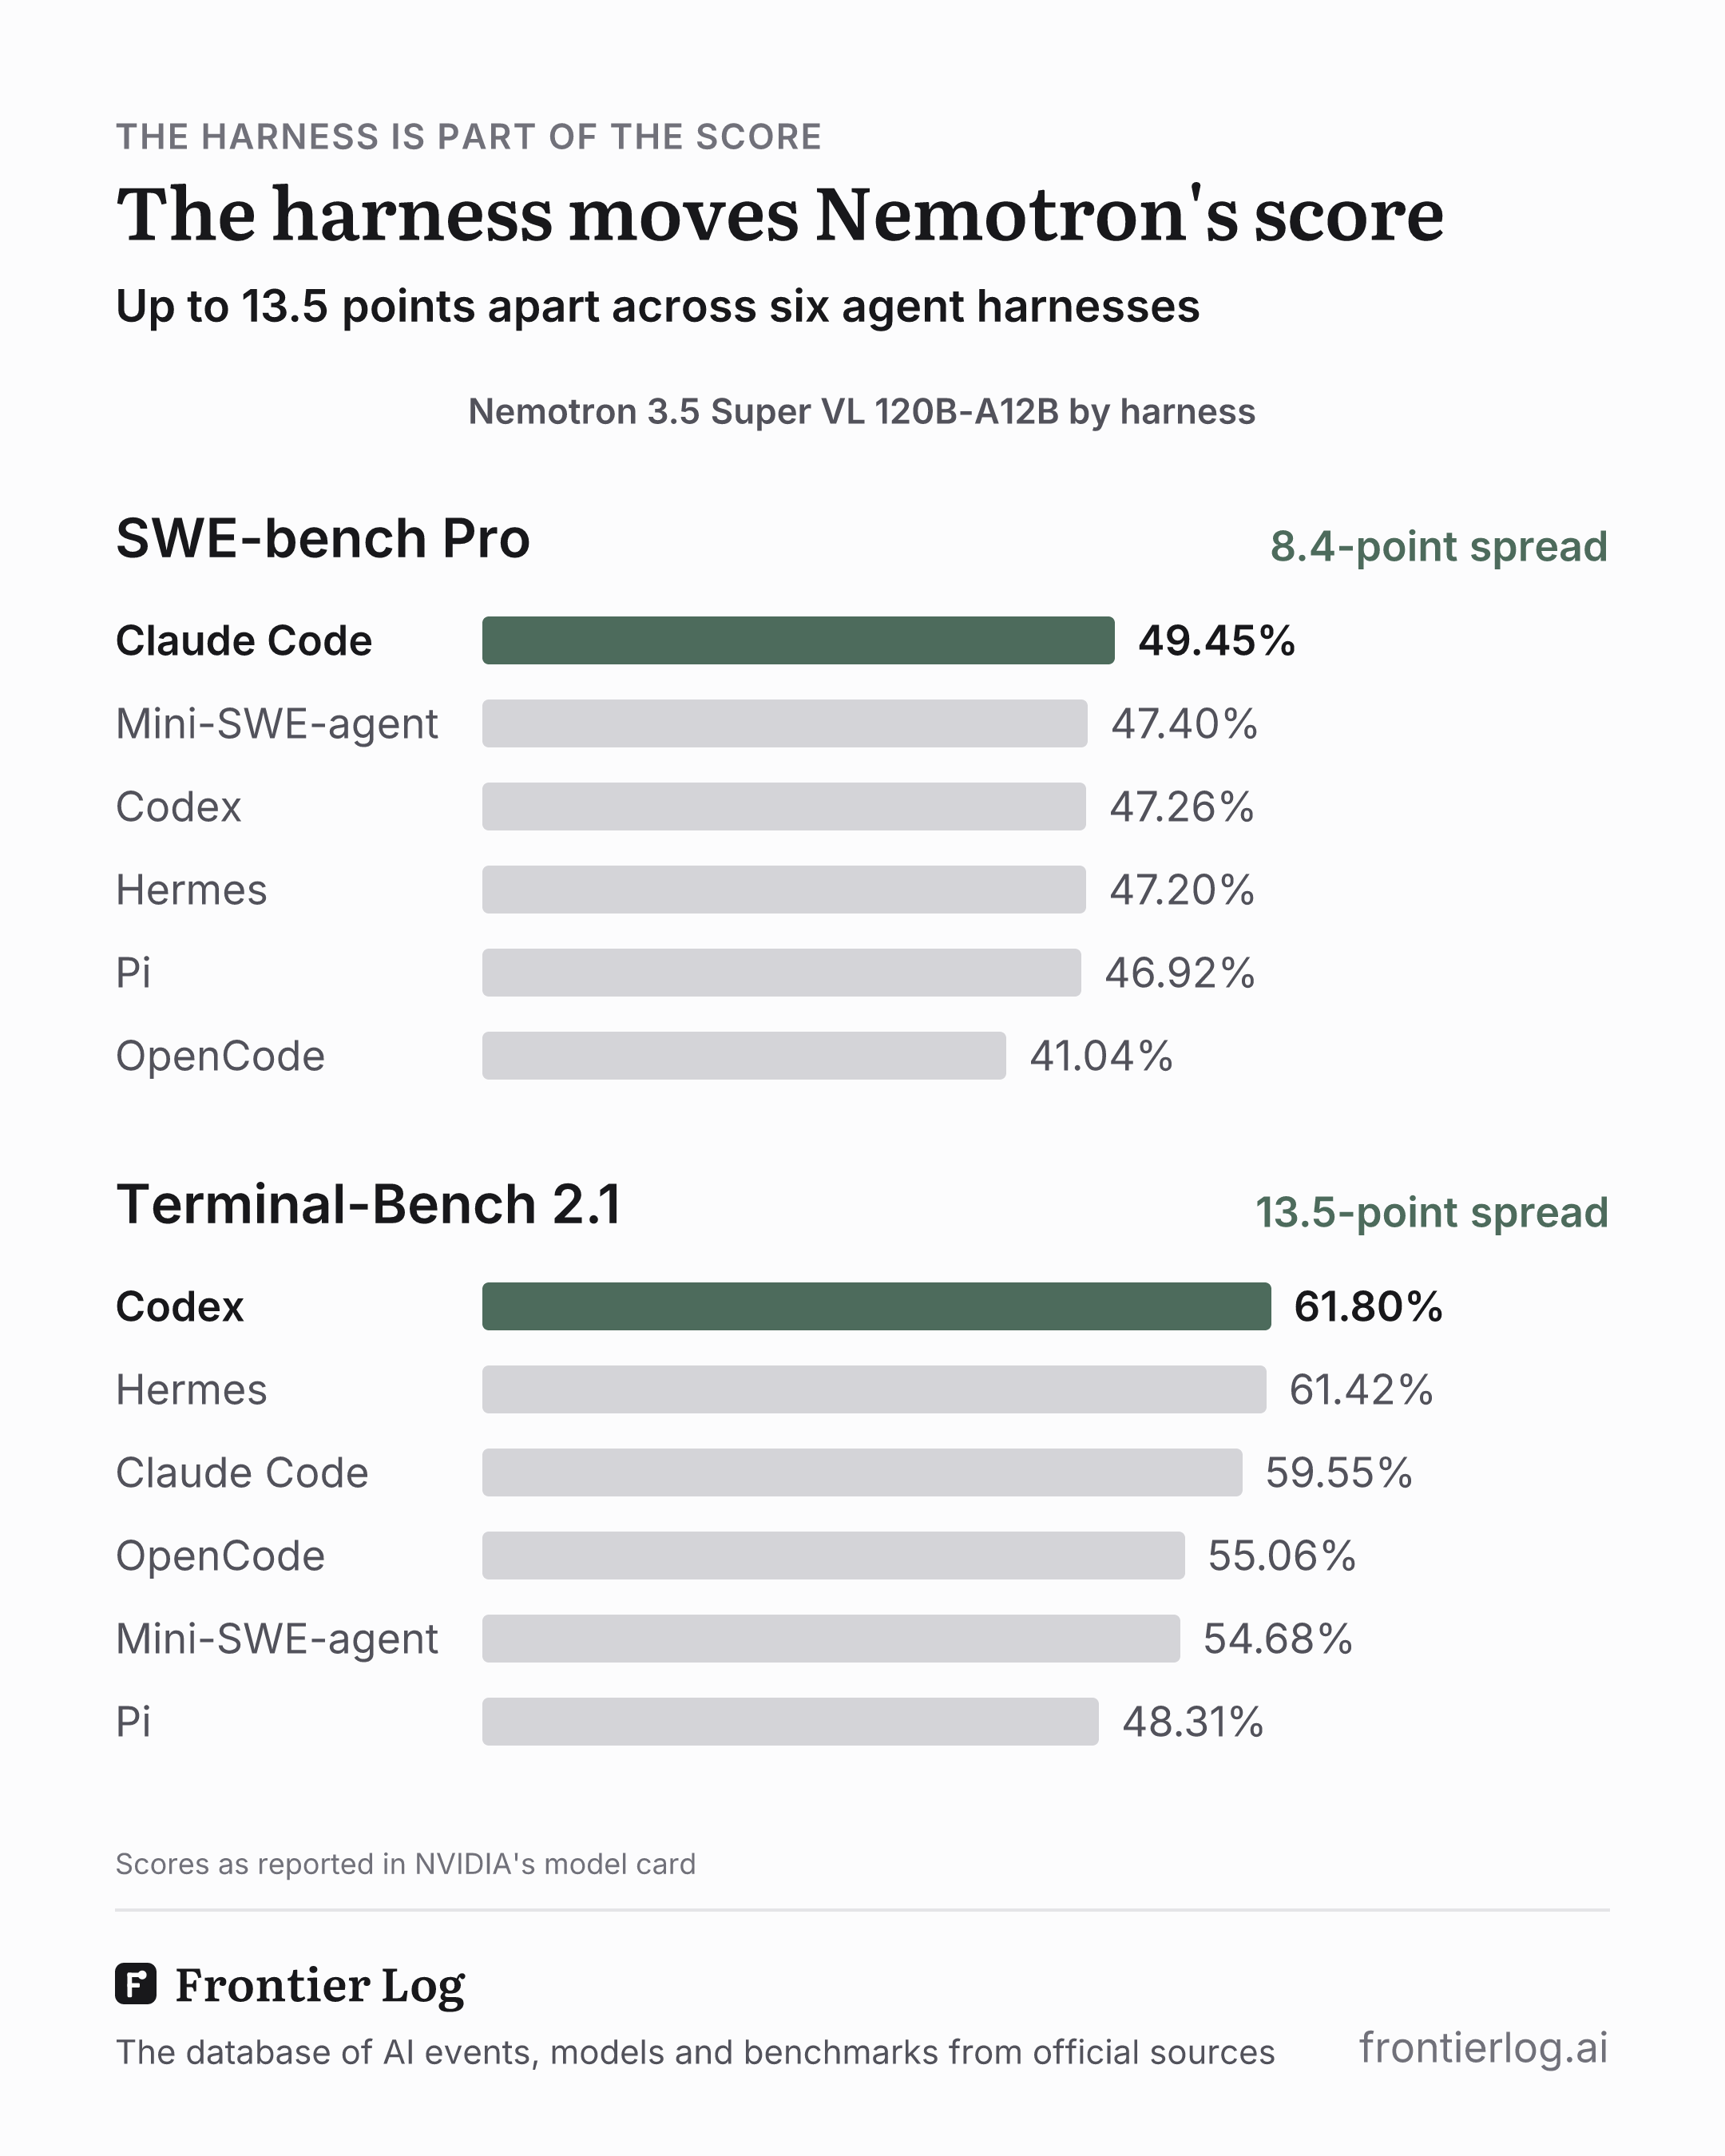
Nemotron 3.5 Super VL 120B-A12B's scores in six agent harnesses, from NVIDIA's model card. SWE-bench Pro: Claude Code 49.45%, Mini-SWE-agent 47.40%, Codex 47.26%, Hermes 47.20%, Pi 46.92%, OpenCode 41.04%, an 8.4-point spread. Terminal-Bench 2.1: Codex 61.80%, Hermes 61.42%, Claude Code 59.55%, OpenCode 55.06%, Mini-SWE-agent 54.68%, Pi 48.31%, a 13.5-point spread.

The harness moves Nemotron's score

Up to 13.5 points apart across six agent harnesses

NVIDIA ran Nemotron 3.5 Super in six agent harnesses: the harness moves its score by 8.4 points on SWE-bench Pro and 13.5 on Terminal-Bench 2.1. No harness is best on both: Claude Code leads on SWE-bench Pro, Codex on Terminal-Bench 2.1.
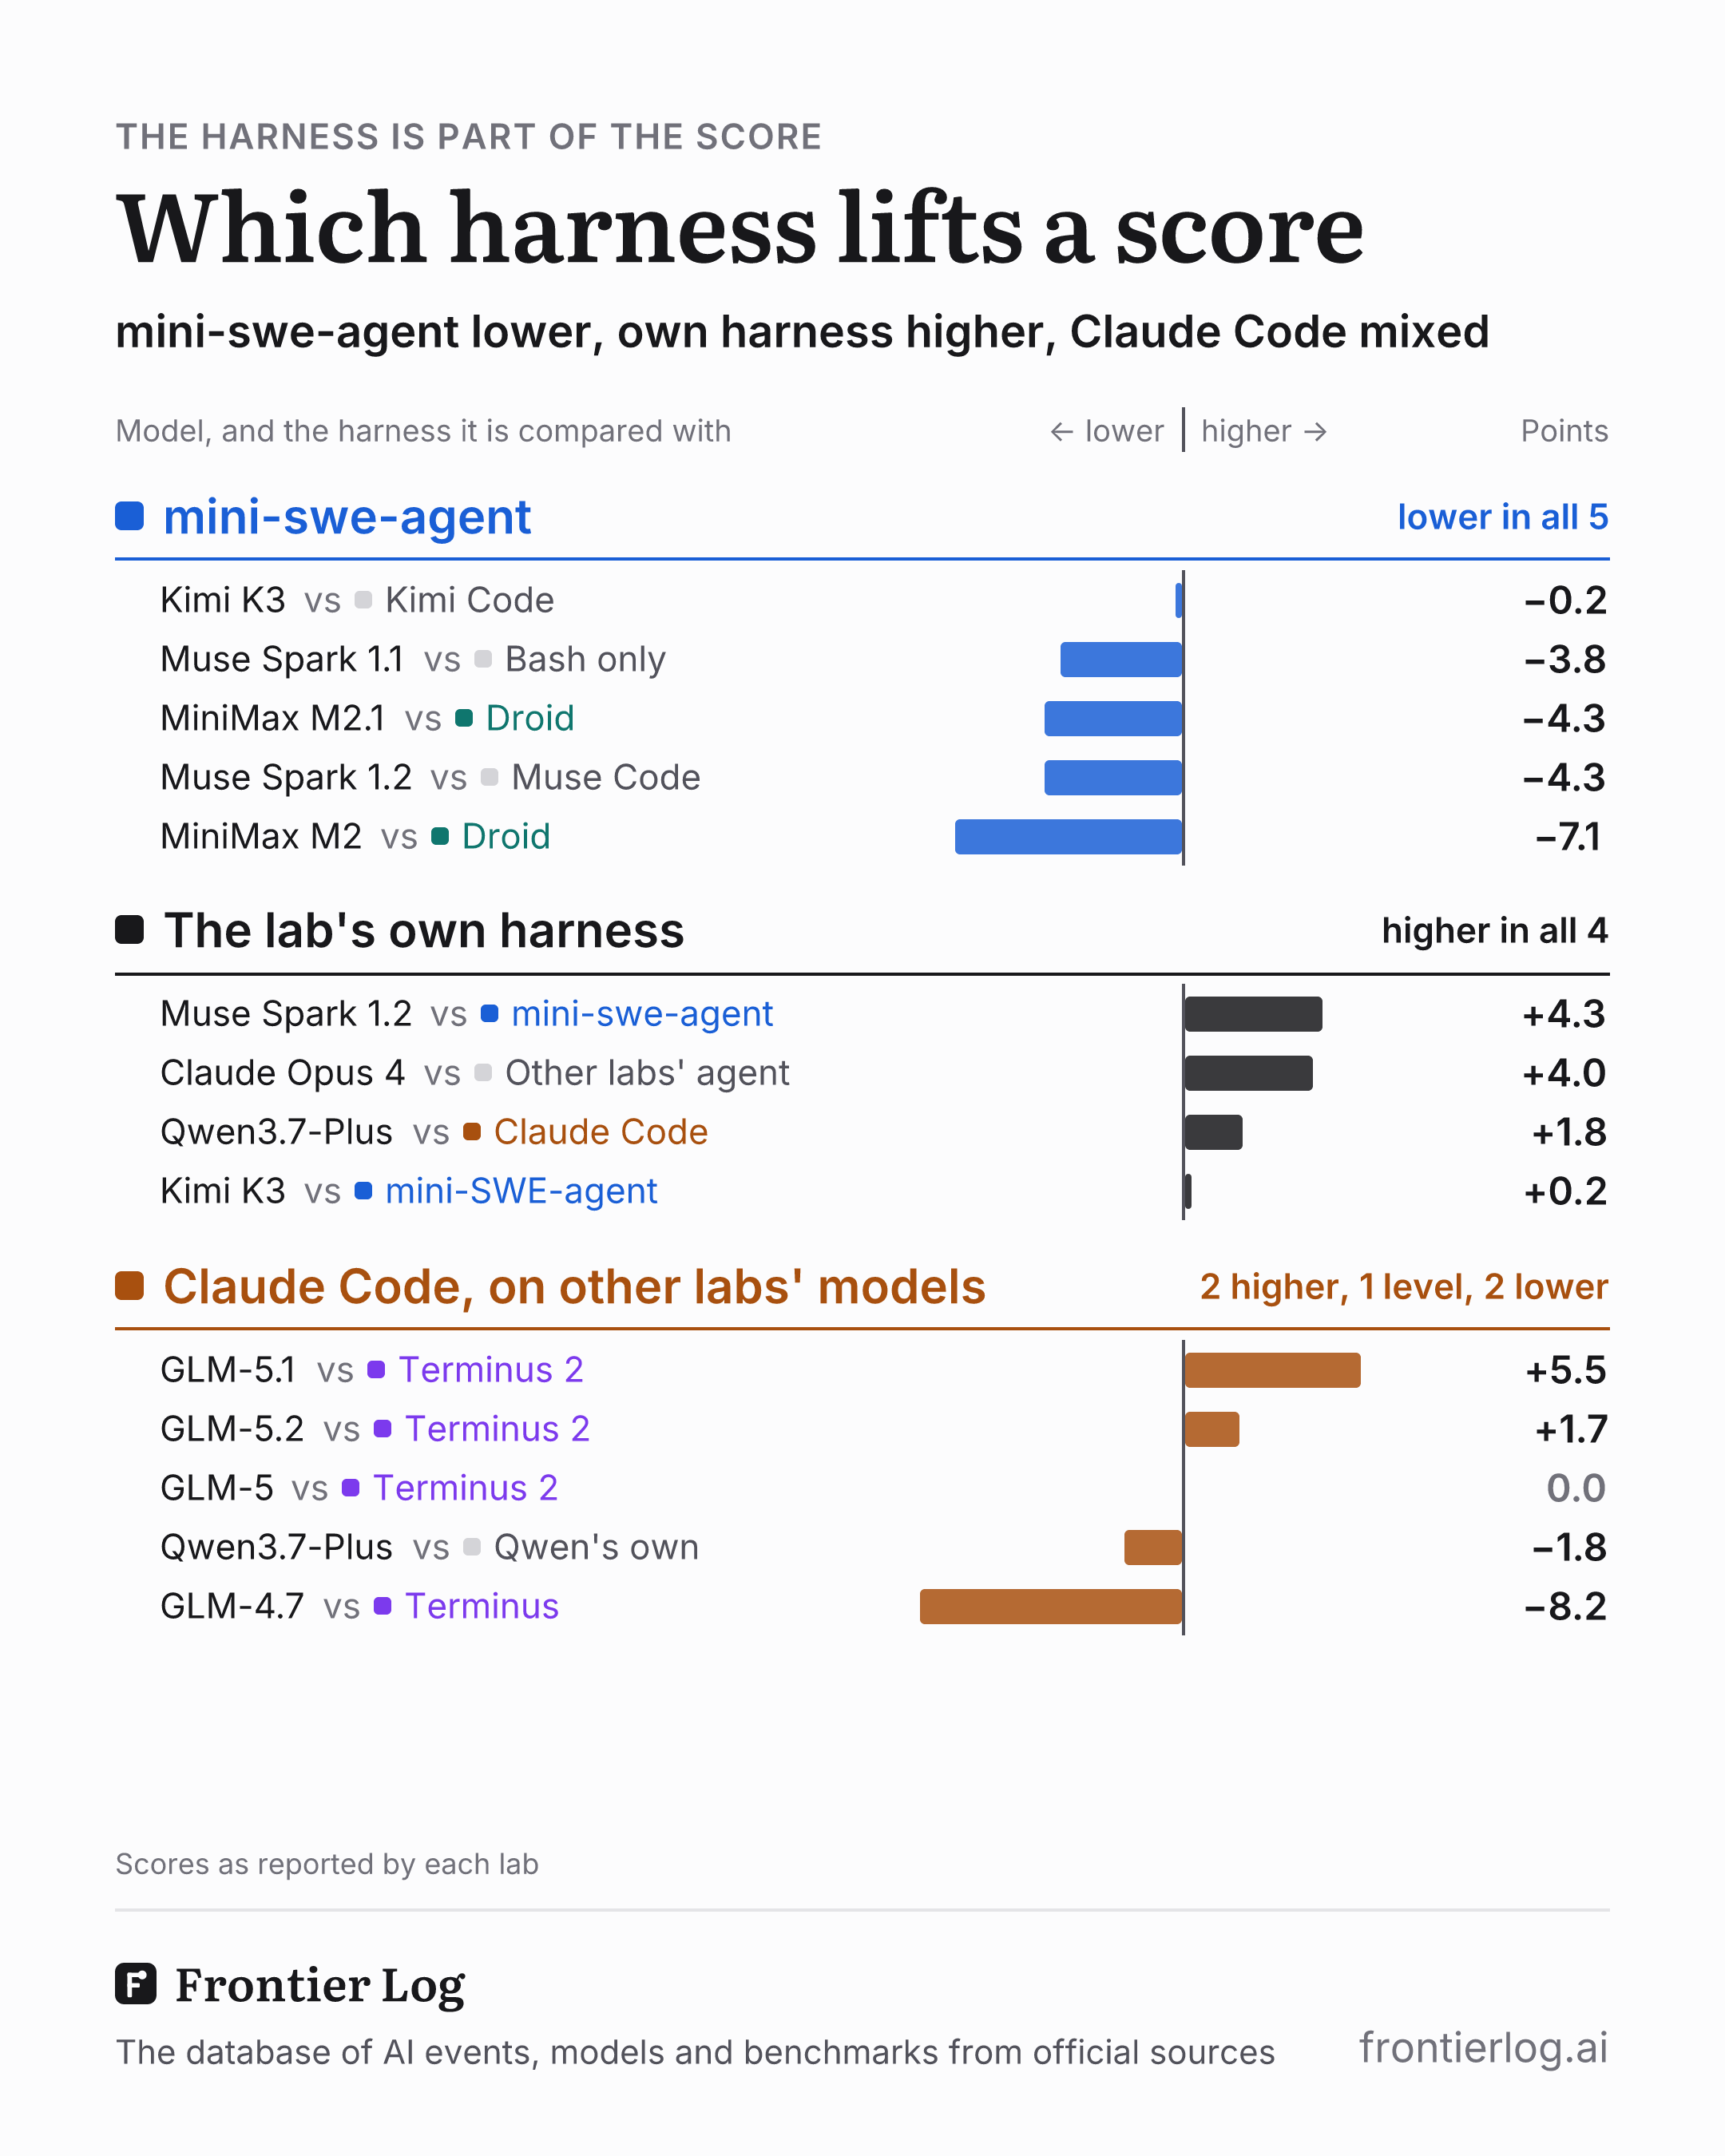
Each harness's score minus the same model's score on the same benchmark in the other harness its lab reported. mini-swe-agent: Kimi K3 vs Kimi Code −0.2, Muse Spark 1.1 vs bash only −3.8, MiniMax M2.1 vs Droid −4.3, Muse Spark 1.2 vs Muse Code −4.3, MiniMax M2 vs Droid −7.1. The lab's own harness: Muse Spark 1.2 vs mini-swe-agent +4.3, Claude Opus 4 vs the agent used for other labs' models +4.0, Qwen3.7-Plus vs Claude Code +1.8, Kimi K3 vs mini-SWE-agent +0.2. Claude Code on other labs' models: GLM-5.1 vs Terminus 2 +5.5, GLM-5.2 vs Terminus 2 +1.7, GLM-5 vs Terminus 2 0.0, Qwen3.7-Plus vs Qwen's own −1.8, GLM-4.7 vs Terminus −8.2.

Which harness lifts a score

mini-swe-agent lower, own harness higher, Claude Code mixed

mini-swe-agent scored lower every time, by 0.2 to 7.1 points, and a lab's own harness higher every time, by 0.2 to 4.3, while Claude Code on other labs' models went both ways. Each pair is a different model and benchmark, so this shows direction, not a fixed effect.

Nemotron 3.5 Super: SWE-bench Pro by harness

ModelScoreSources
Nemotron 3.5 Super VL and BoltClaude Code49.45%Announcement'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'Claude Code' bar
Nemotron 3.5 Super VL and BoltMini-SWE-agent47.40%Announcement'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'Mini-SWE agent' bar
Nemotron 3.5 Super VL and BoltCodex47.26%Announcement'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'Codex' bar
Nemotron 3.5 Super VL and BoltHermes47.20%Announcement'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'Hermes' bar
Nemotron 3.5 Super VL and BoltPi46.92%Announcement'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'Pi' bar
Nemotron 3.5 Super VL and BoltOpenCode41.04%Announcement'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'OpenCode' bar

Nemotron 3.5 Super: Terminal-Bench 2.1 by harness

ModelScoreSources
Nemotron 3.5 Super VL and BoltCodex61.80%Announcement'Agentic Coding Benchmarks' image, 'Terminal-Bench 2.1' panel, value label of the 'Codex' bar
Nemotron 3.5 Super VL and BoltHermes61.42%Announcement'Agentic Coding Benchmarks' image, 'Terminal-Bench 2.1' panel, value label of the 'Hermes' bar
Nemotron 3.5 Super VL and BoltClaude Code59.55%Announcement'Agentic Coding Benchmarks' image, 'Terminal-Bench 2.1' panel, value label of the 'Claude Code' bar
Nemotron 3.5 Super VL and BoltOpenCode55.06%Announcement'Agentic Coding Benchmarks' image, 'Terminal-Bench 2.1' panel, value label of the 'OpenCode' bar
Nemotron 3.5 Super VL and BoltMini-SWE-agent54.68%Announcement'Agentic Coding Benchmarks' image, 'Terminal-Bench 2.1' panel, value label of the 'Mini-SWE agent' bar
Nemotron 3.5 Super VL and BoltPi48.31%Announcement'Agentic Coding Benchmarks' image, 'Terminal-Bench 2.1' panel, value label of the 'Pi' bar

SWE-bench Verified by harness

ModelScoreSources
MiniMax M2Droid68.1%Announcement'Benchmarks' section, second (agent frameworks and specialized benchmarks) table image, row 'SWE-bench Verified (Droid)', column 'MiniMax-M2'
MiniMax M2mini-swe-agent61.0%Announcement'Benchmarks' section, second (agent frameworks and specialized benchmarks) table image, row 'SWE-bench Verified (mini-swe-agent)', column 'MiniMax-M2'
MiniMax M2.1Droid71.3%Announcement'Benchmarks' section, second (agent frameworks and specialized benchmarks) table image, row 'SWE-bench Verified (Droid)', column 'MiniMax-M2.1'
MiniMax M2.1mini-swe-agent67.0%Announcement'Benchmarks' section, second (agent frameworks and specialized benchmarks) table image, row 'SWE-bench Verified (mini-swe-agent)', column 'MiniMax-M2.1'

SWE-bench Pro by harness

ModelScoreSources
Qwen3.7-PlusQwen's own57.6%Announcementlanguage benchmark table (first table), Coding Agent block, row 'SWE-Pro', column 'Qwen3.7-Plus'Run on the lab's own corrected version of the public set
Qwen3.7-PlusClaude Code55.8%Announcementlater report: Qwen3.8-Flash-Next post, Language table (first table), row 'Agentic coding / SWE-bench Pro', column 'Qwen3.7-Plus'Run on the lab's own corrected version of the public set

Terminal-Bench 1.0 by harness

ModelScoreSources
Claude 4 (Opus 4 and Sonnet 4)Claude Code43.2%Announcementmain benchmark table (HTML drawn by script), row 'Agentic terminal coding / Terminal-bench', column 'Claude Opus 4', first number of the cell
Claude 4 (Opus 4 and Sonnet 4)Other labs' agent39.2%Announcementmethodology footnote 2 under the main table

Terminal-Bench 2.0 by harness

ModelScoreSources
GLM-4.7Terminus41.0%Announcementbenchmark table, row 'Terminal Bench 2.0', column 'GLM-4.7'
GLM-4.7Claude Code32.8%Announcementbenchmark table, row 'Terminal-Bench 2.0 Claude Code', column 'GLM-4.7 (Thinking)'
GLM-5Terminus 256.2%Announcementbenchmark table, row 'Terminal-Bench 2.0 Terminus-2', column 'GLM-5 (Thinking)'
GLM-5Claude Code56.2%Announcementbenchmark table, row 'Terminal-Bench 2.0 Claude Code', column 'GLM-5 (Thinking)'

Terminal-Bench 2.1 by harness

ModelScoreSources
GLM-5.1Terminus 263.5%Announcement'Full Benchmark Table', row 'Terminal Bench 2.1 Terminus-2', column 'GLM-5.1'
GLM-5.1Claude Code69%Announcement'Full Benchmark Table', row 'Terminal Bench 2.1 Best Reported Harness', column 'GLM-5.1'
GLM-5.2Terminus 281.0%Announcement'Full Benchmark Table', row 'Terminal Bench 2.1 Terminus-2', column 'GLM-5.2'
GLM-5.2Claude Code82.7%Announcement'Full Benchmark Table', row 'Terminal Bench 2.1 Best Reported Harness', column 'GLM-5.2'
Muse Spark 1.1Bash only80.0%Announcementbenchmark table (image), row 'Terminal-Bench 2.1', column 'Muse Spark 1.1'
Muse Spark 1.1mini-swe-agent76.2%Announcementbar chart 'Terminal-Bench 2.1' (image, Coding tab), value label above the bar 'Muse Spark 1.1, mini-swe-agent'

DeepSWE v1.1 by harness

ModelScoreSources
Kimi K3Kimi Code67.5%Announcement'Full Benchmark Table', row 'DeepSWE' (Coding), column 'Kimi K3 (max)'
Kimi K3mini-SWE-agent67.3%AnnouncementFootnotes, 'Coding benchmarks', the 'DeepSWE.' note (score on the official DeepSWE leaderboard with the mini-SWE-agent harness)
Muse Spark 1.2 and Muse CodeMuse Code59.3%Announcementbar chart 'DeepSWE 1.1' (image, Coding tab), value label above the bar 'Muse Spark 1.2, Muse Code'
Muse Spark 1.2 and Muse Codemini-swe-agent55.0%AnnouncementMuse Spark 1.3 scorecard (image), row 'DeepSWE v1.1', column 'Muse Spark 1.2 (xhigh)'

Tags

Nemotron 3.5 Super VL and Bolt on the timeline