SWE-bench Verified
- OpenAI
- Anthropic
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
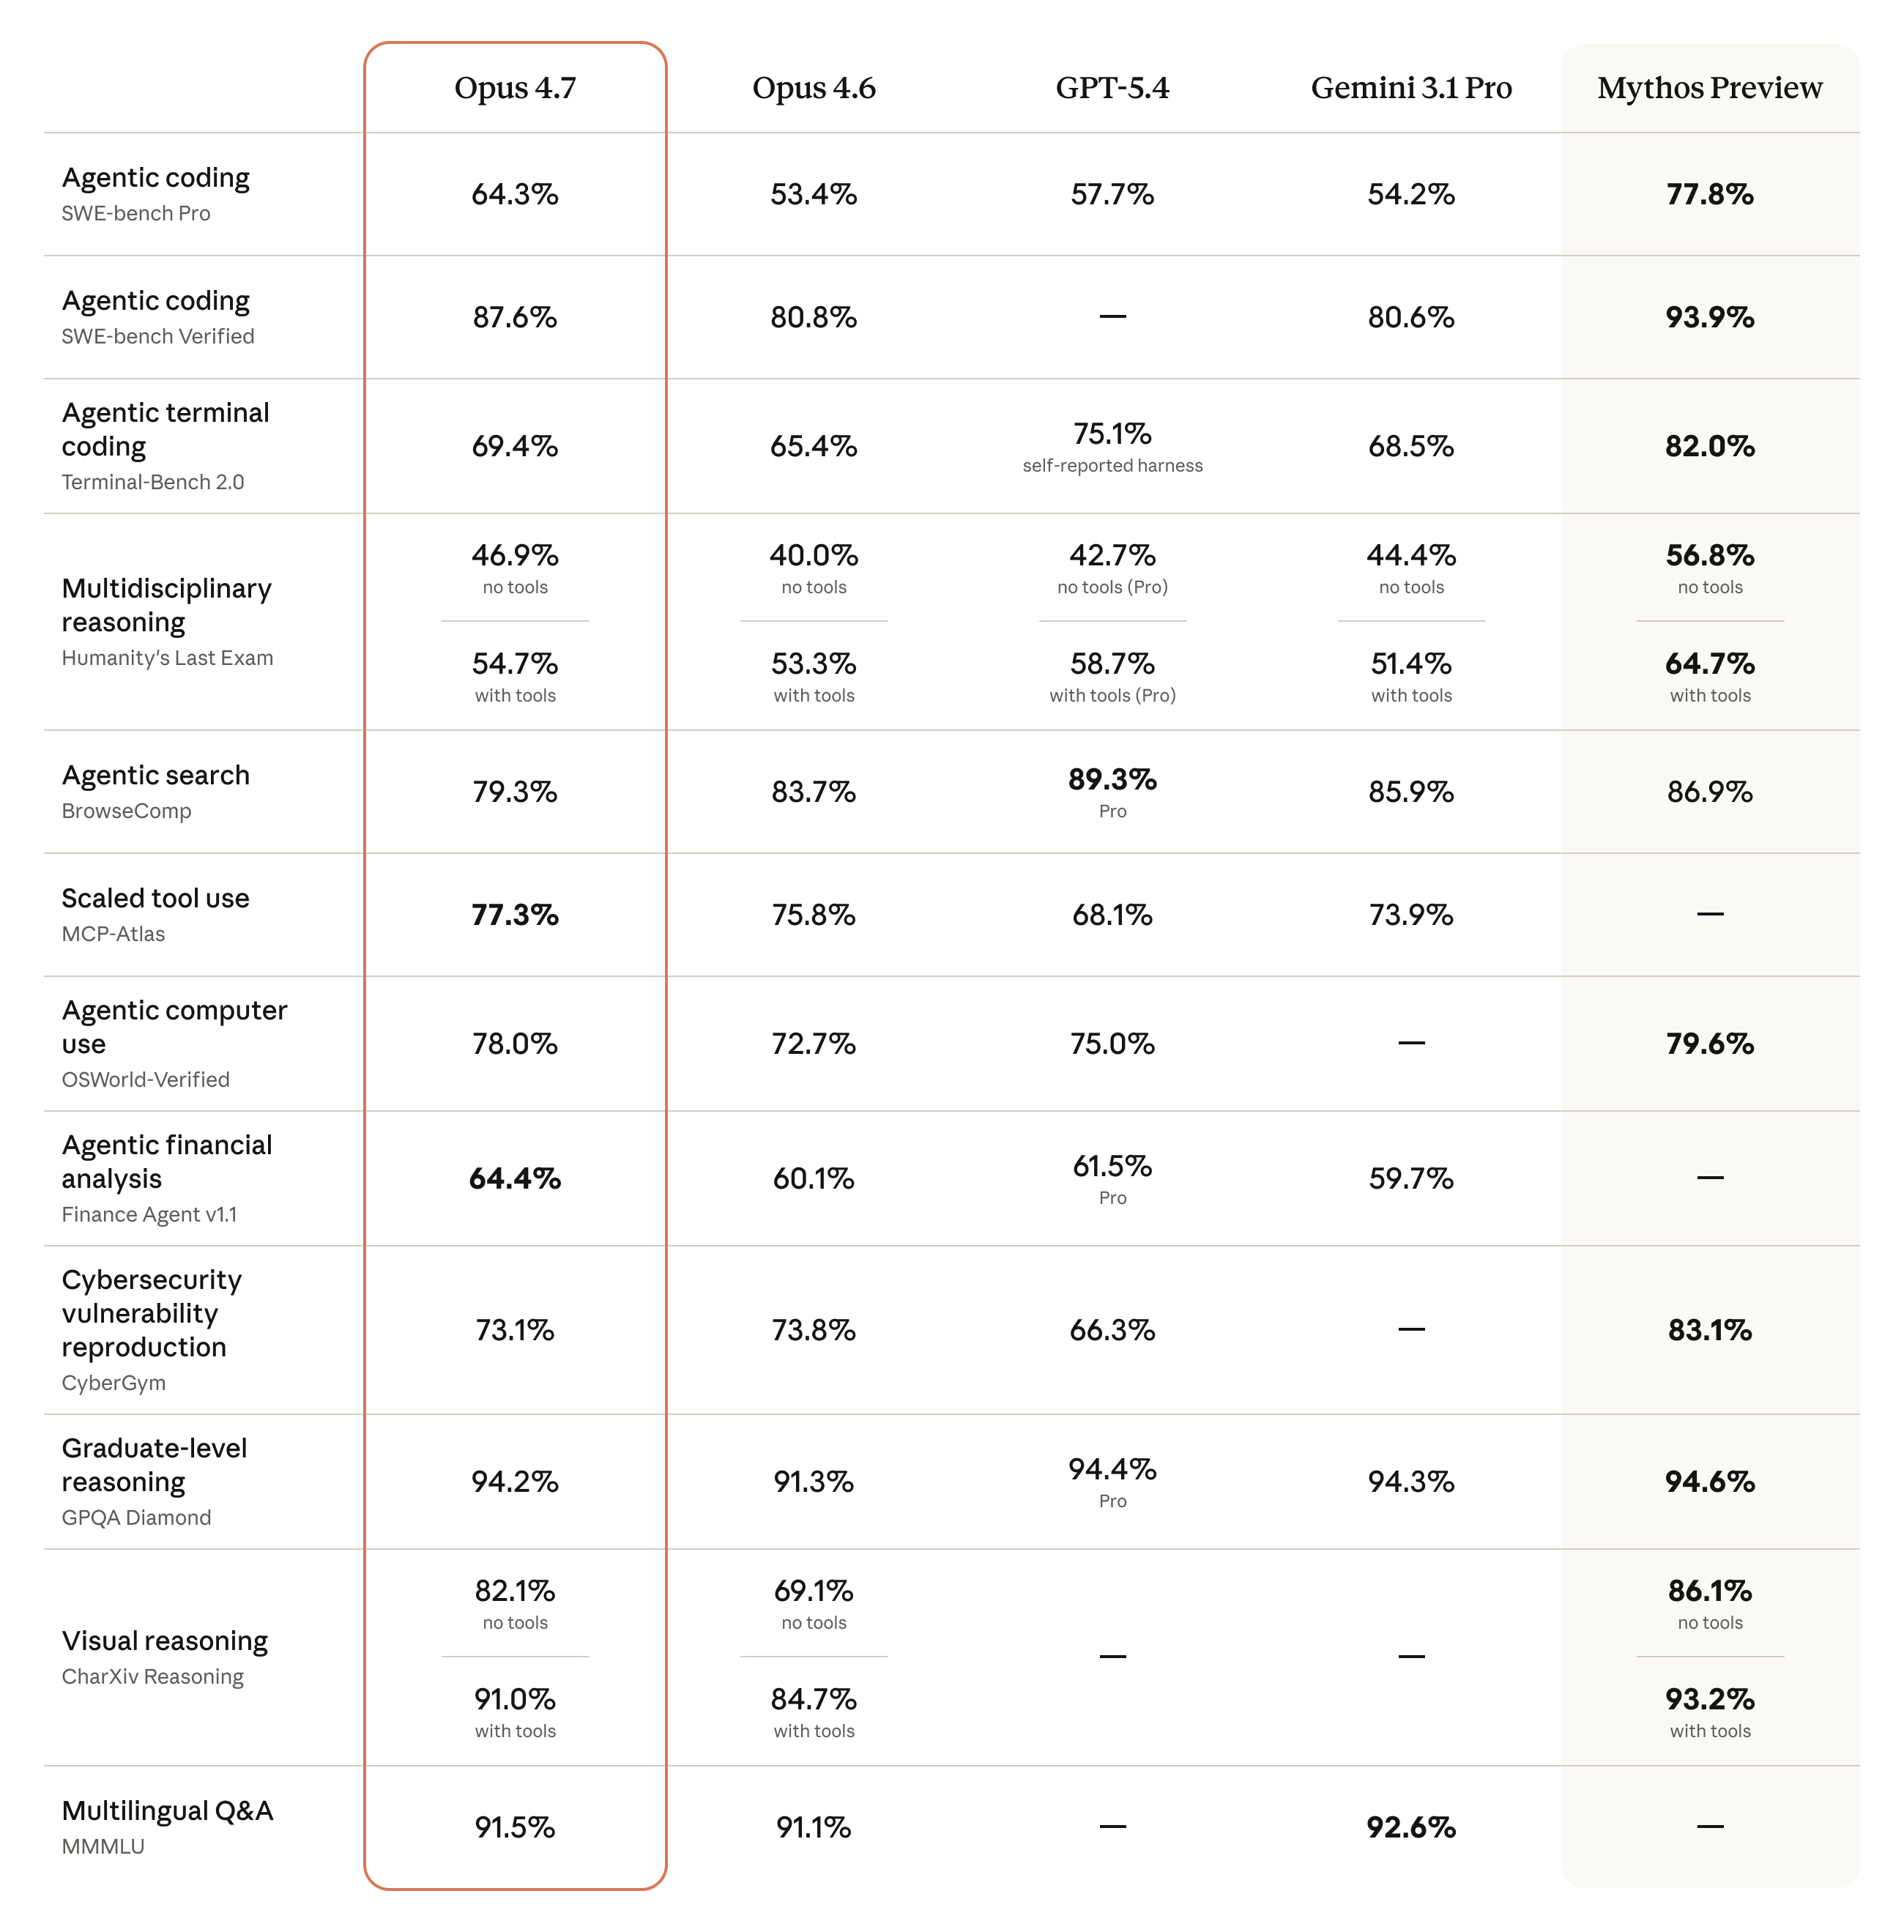
| Claude Opus 4.716 Apr 2026 · Anthropic | 87.6% | Introducing Claude Opus 4.7Source image | Not yet |
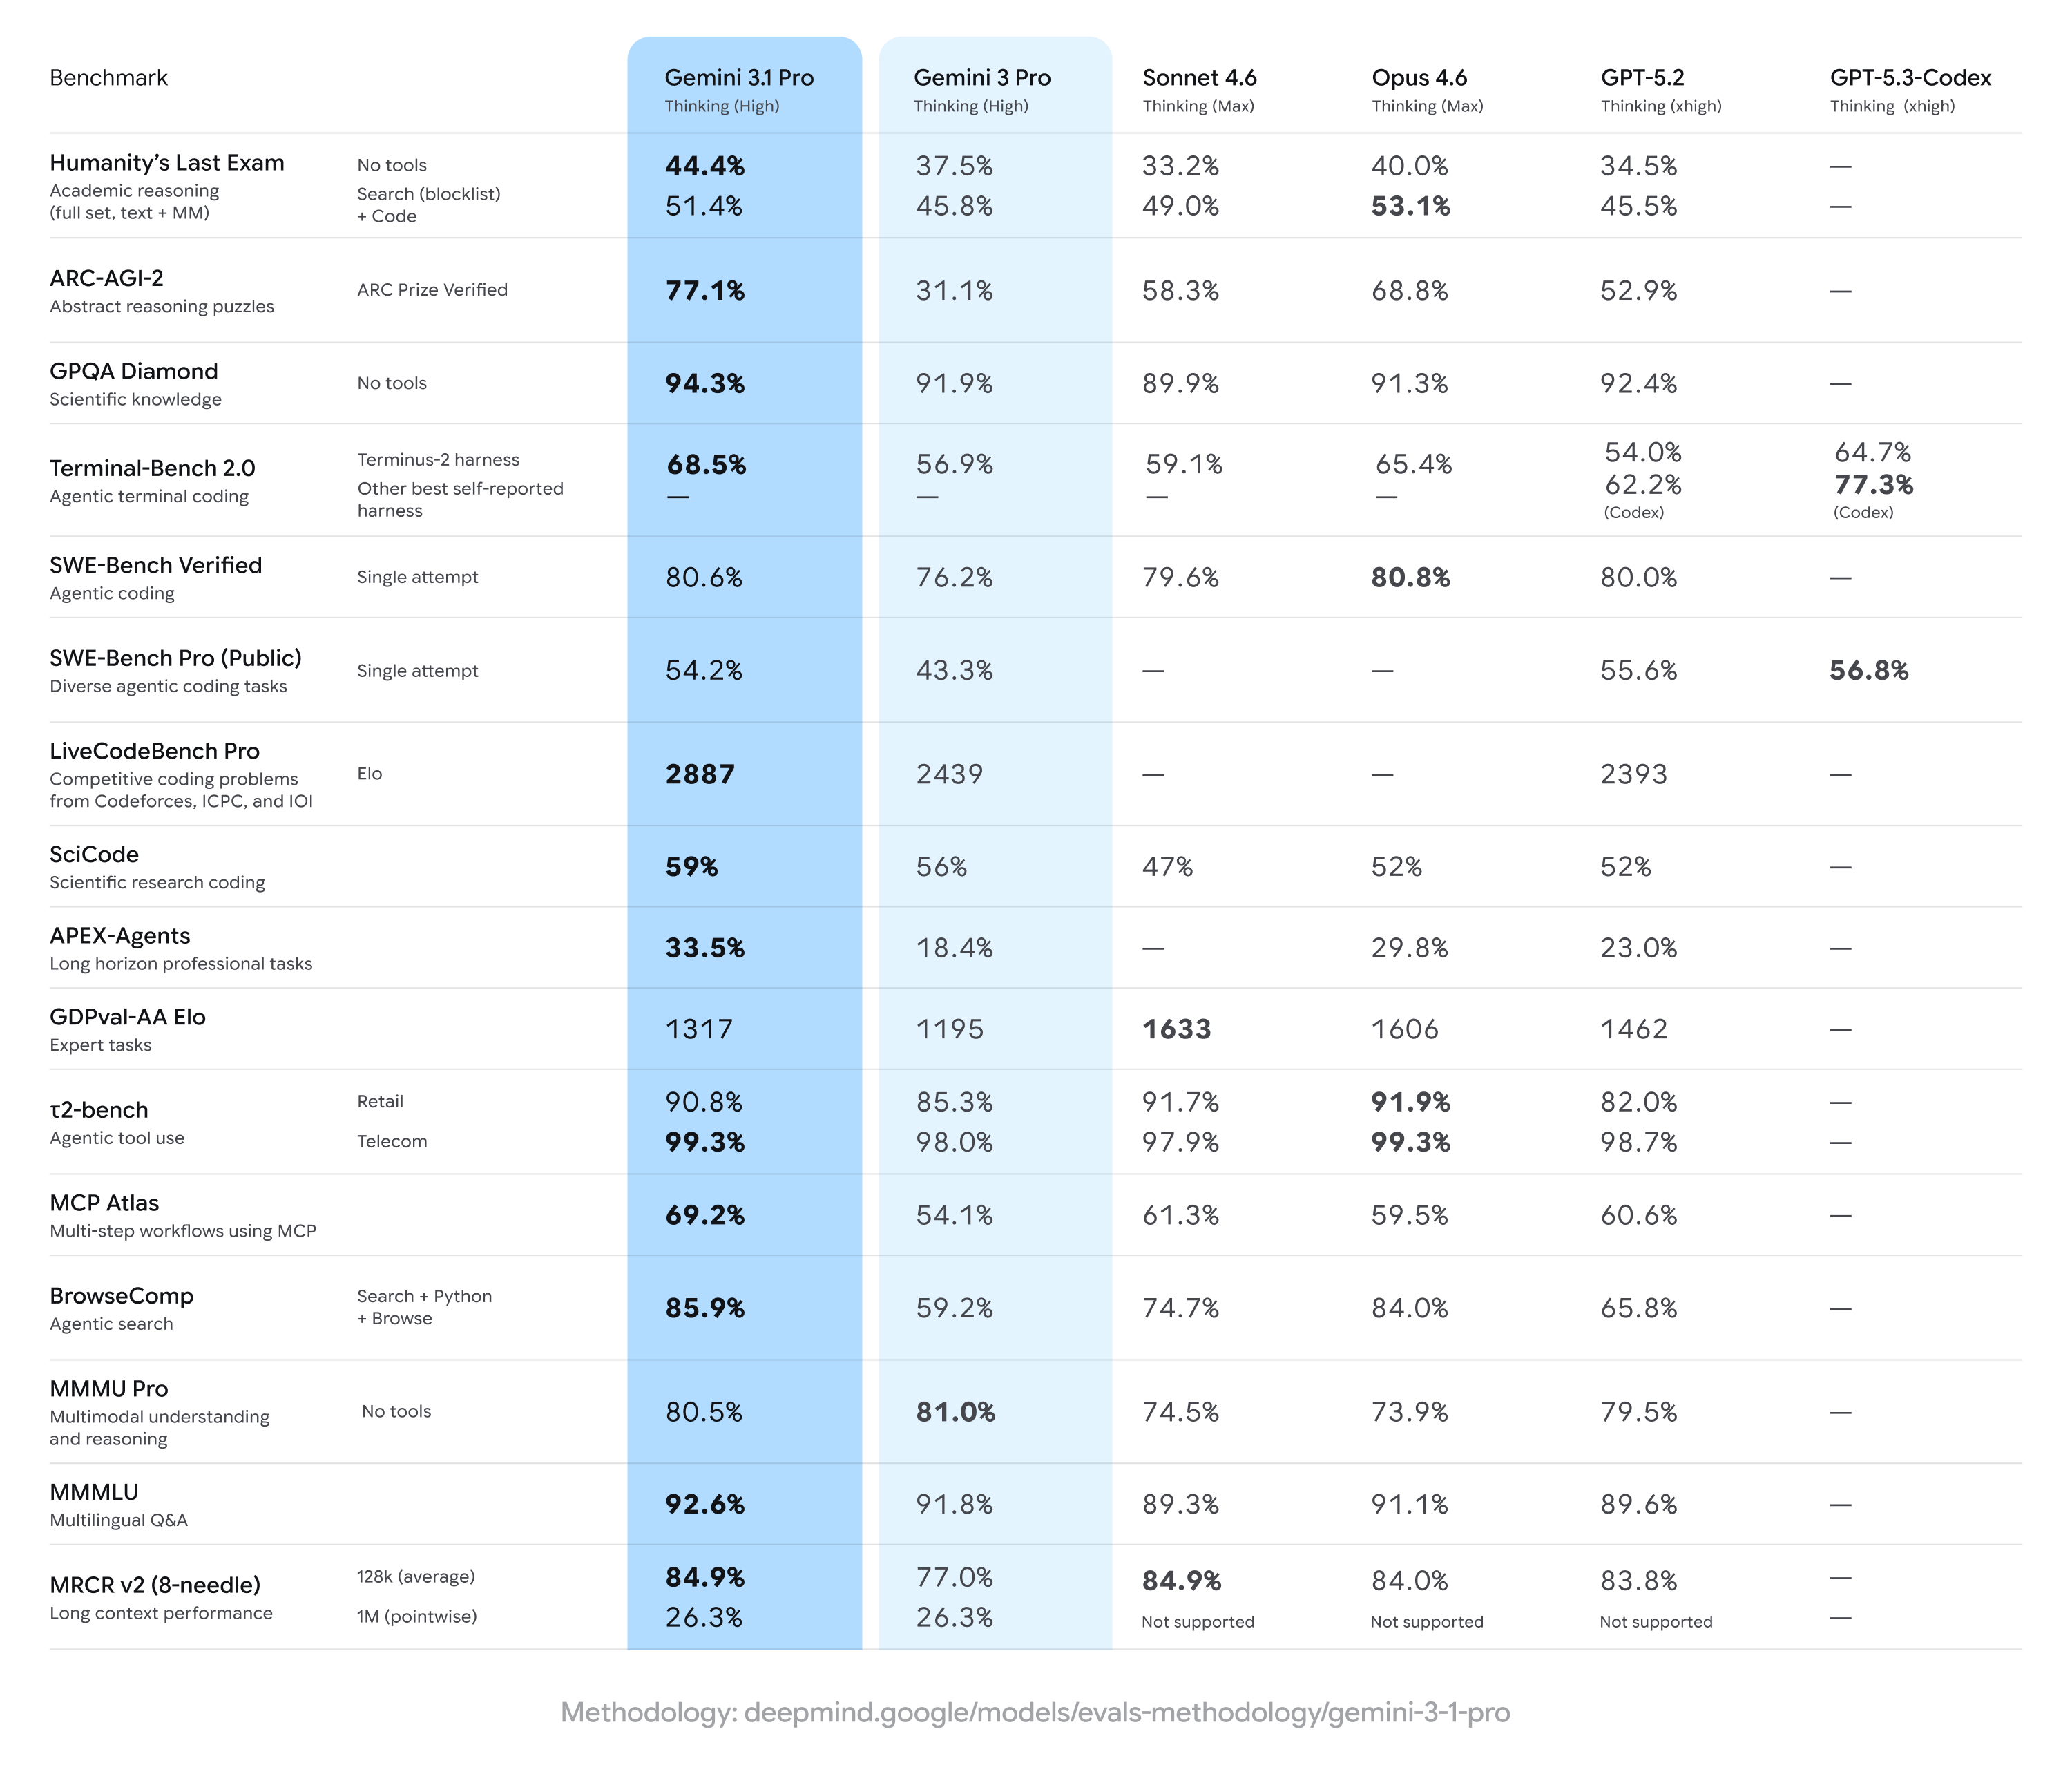
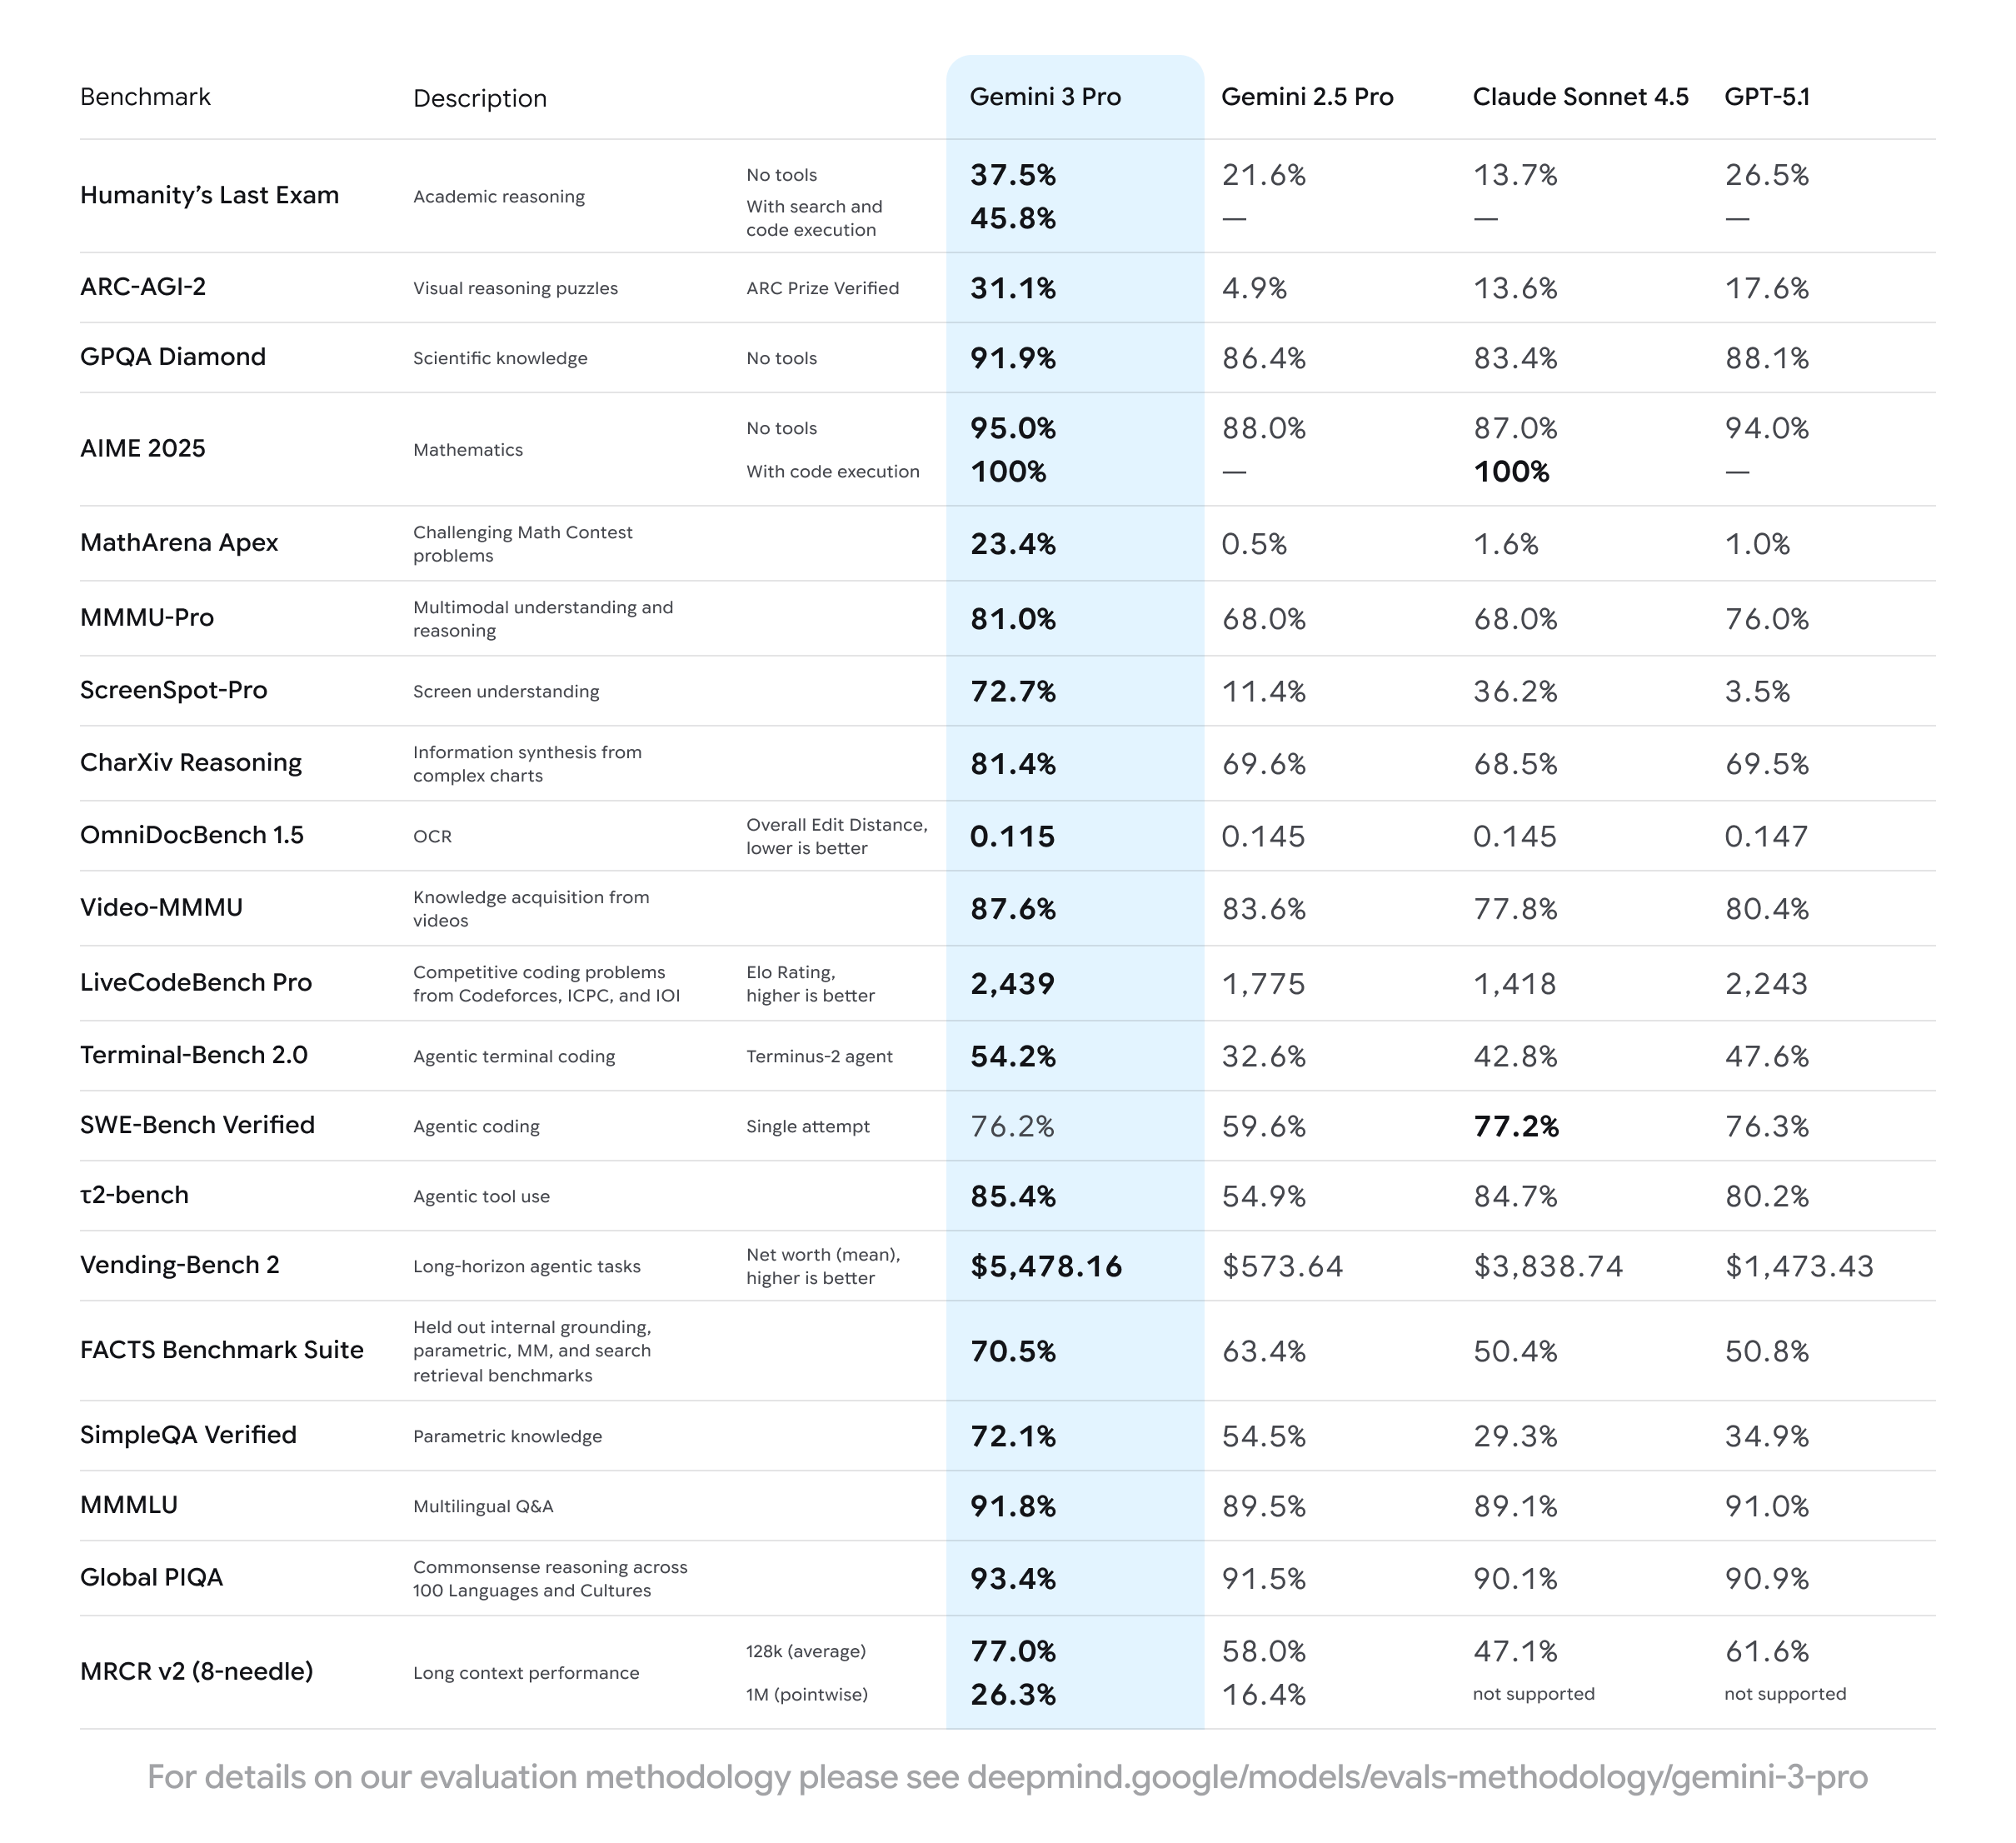
| Gemini 3.1 Pro19 Feb 2026 · Google | 80.6% | Gemini 3.1 Pro: A smarter model for your most complex taskssingle attempt; Thinking (High)Source image | Not yet |
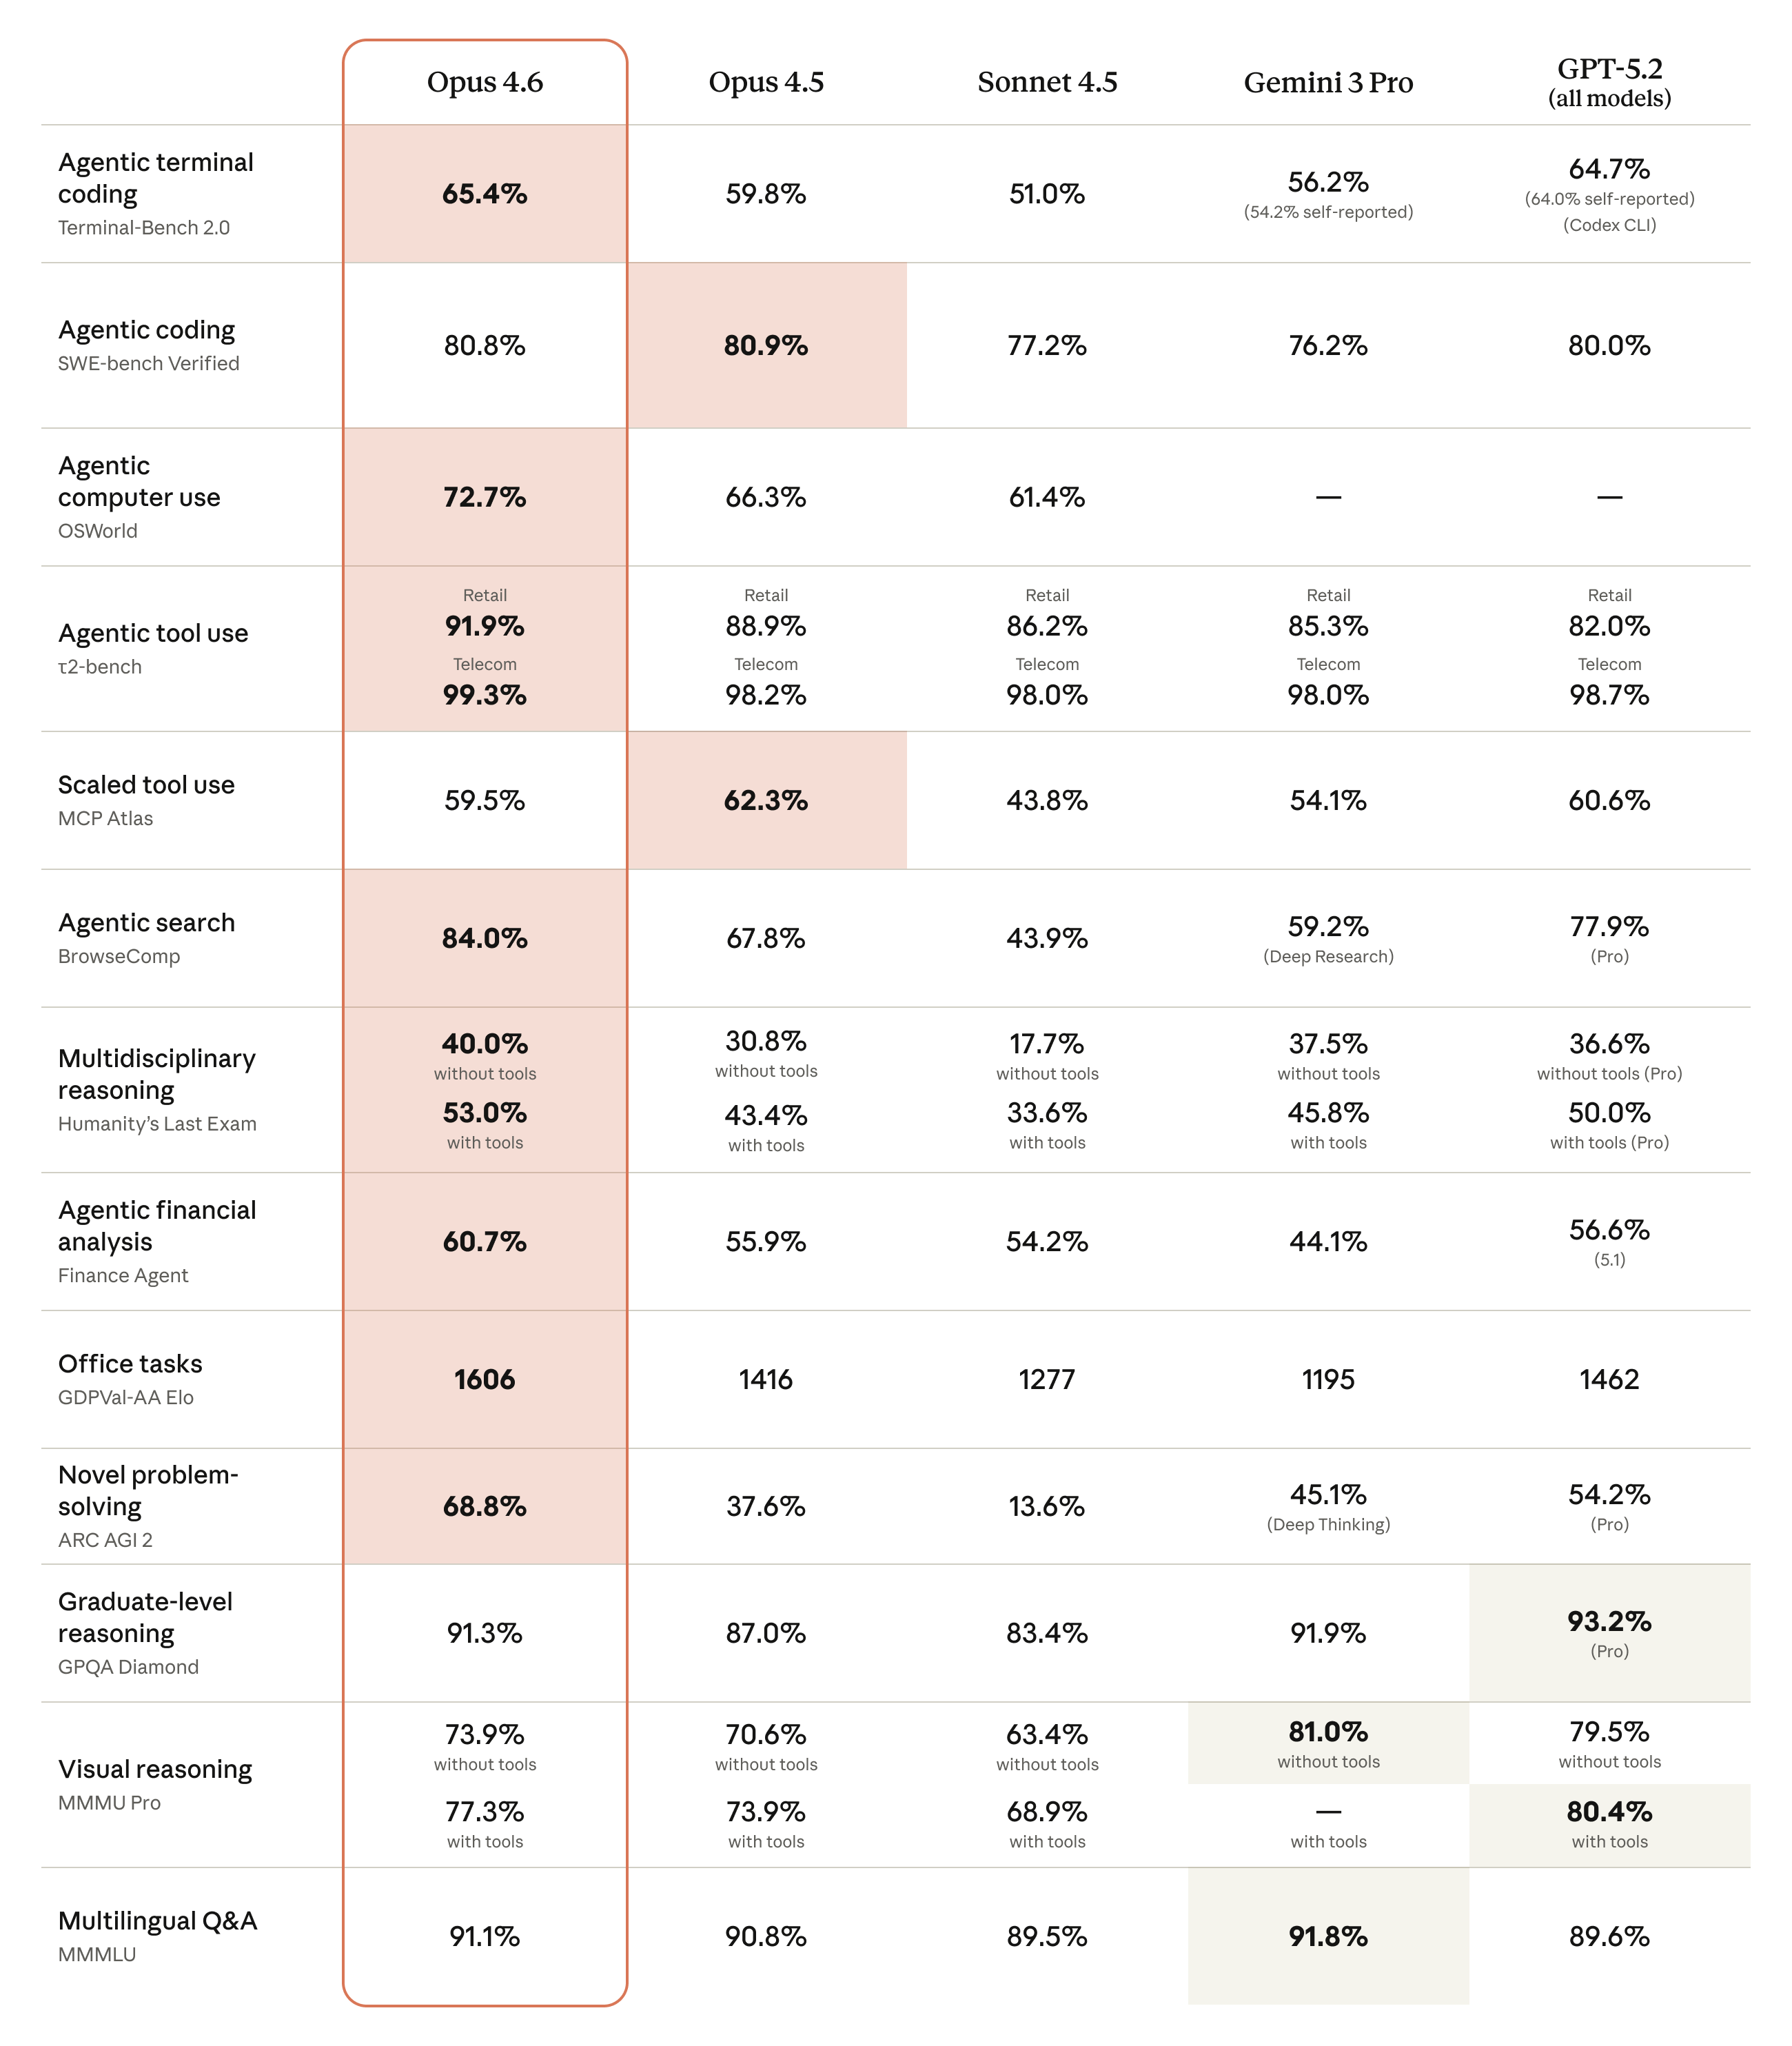
| Claude Opus 4.65 Feb 2026 · Anthropic | 80.8% | Claude Opus 4.6averaged over 25 trials (footnote)Source image | Not yet |
| GPT-5.211 Dec 2025 · OpenAI | 80.0% | Introducing GPT-5.2 | Not yet |
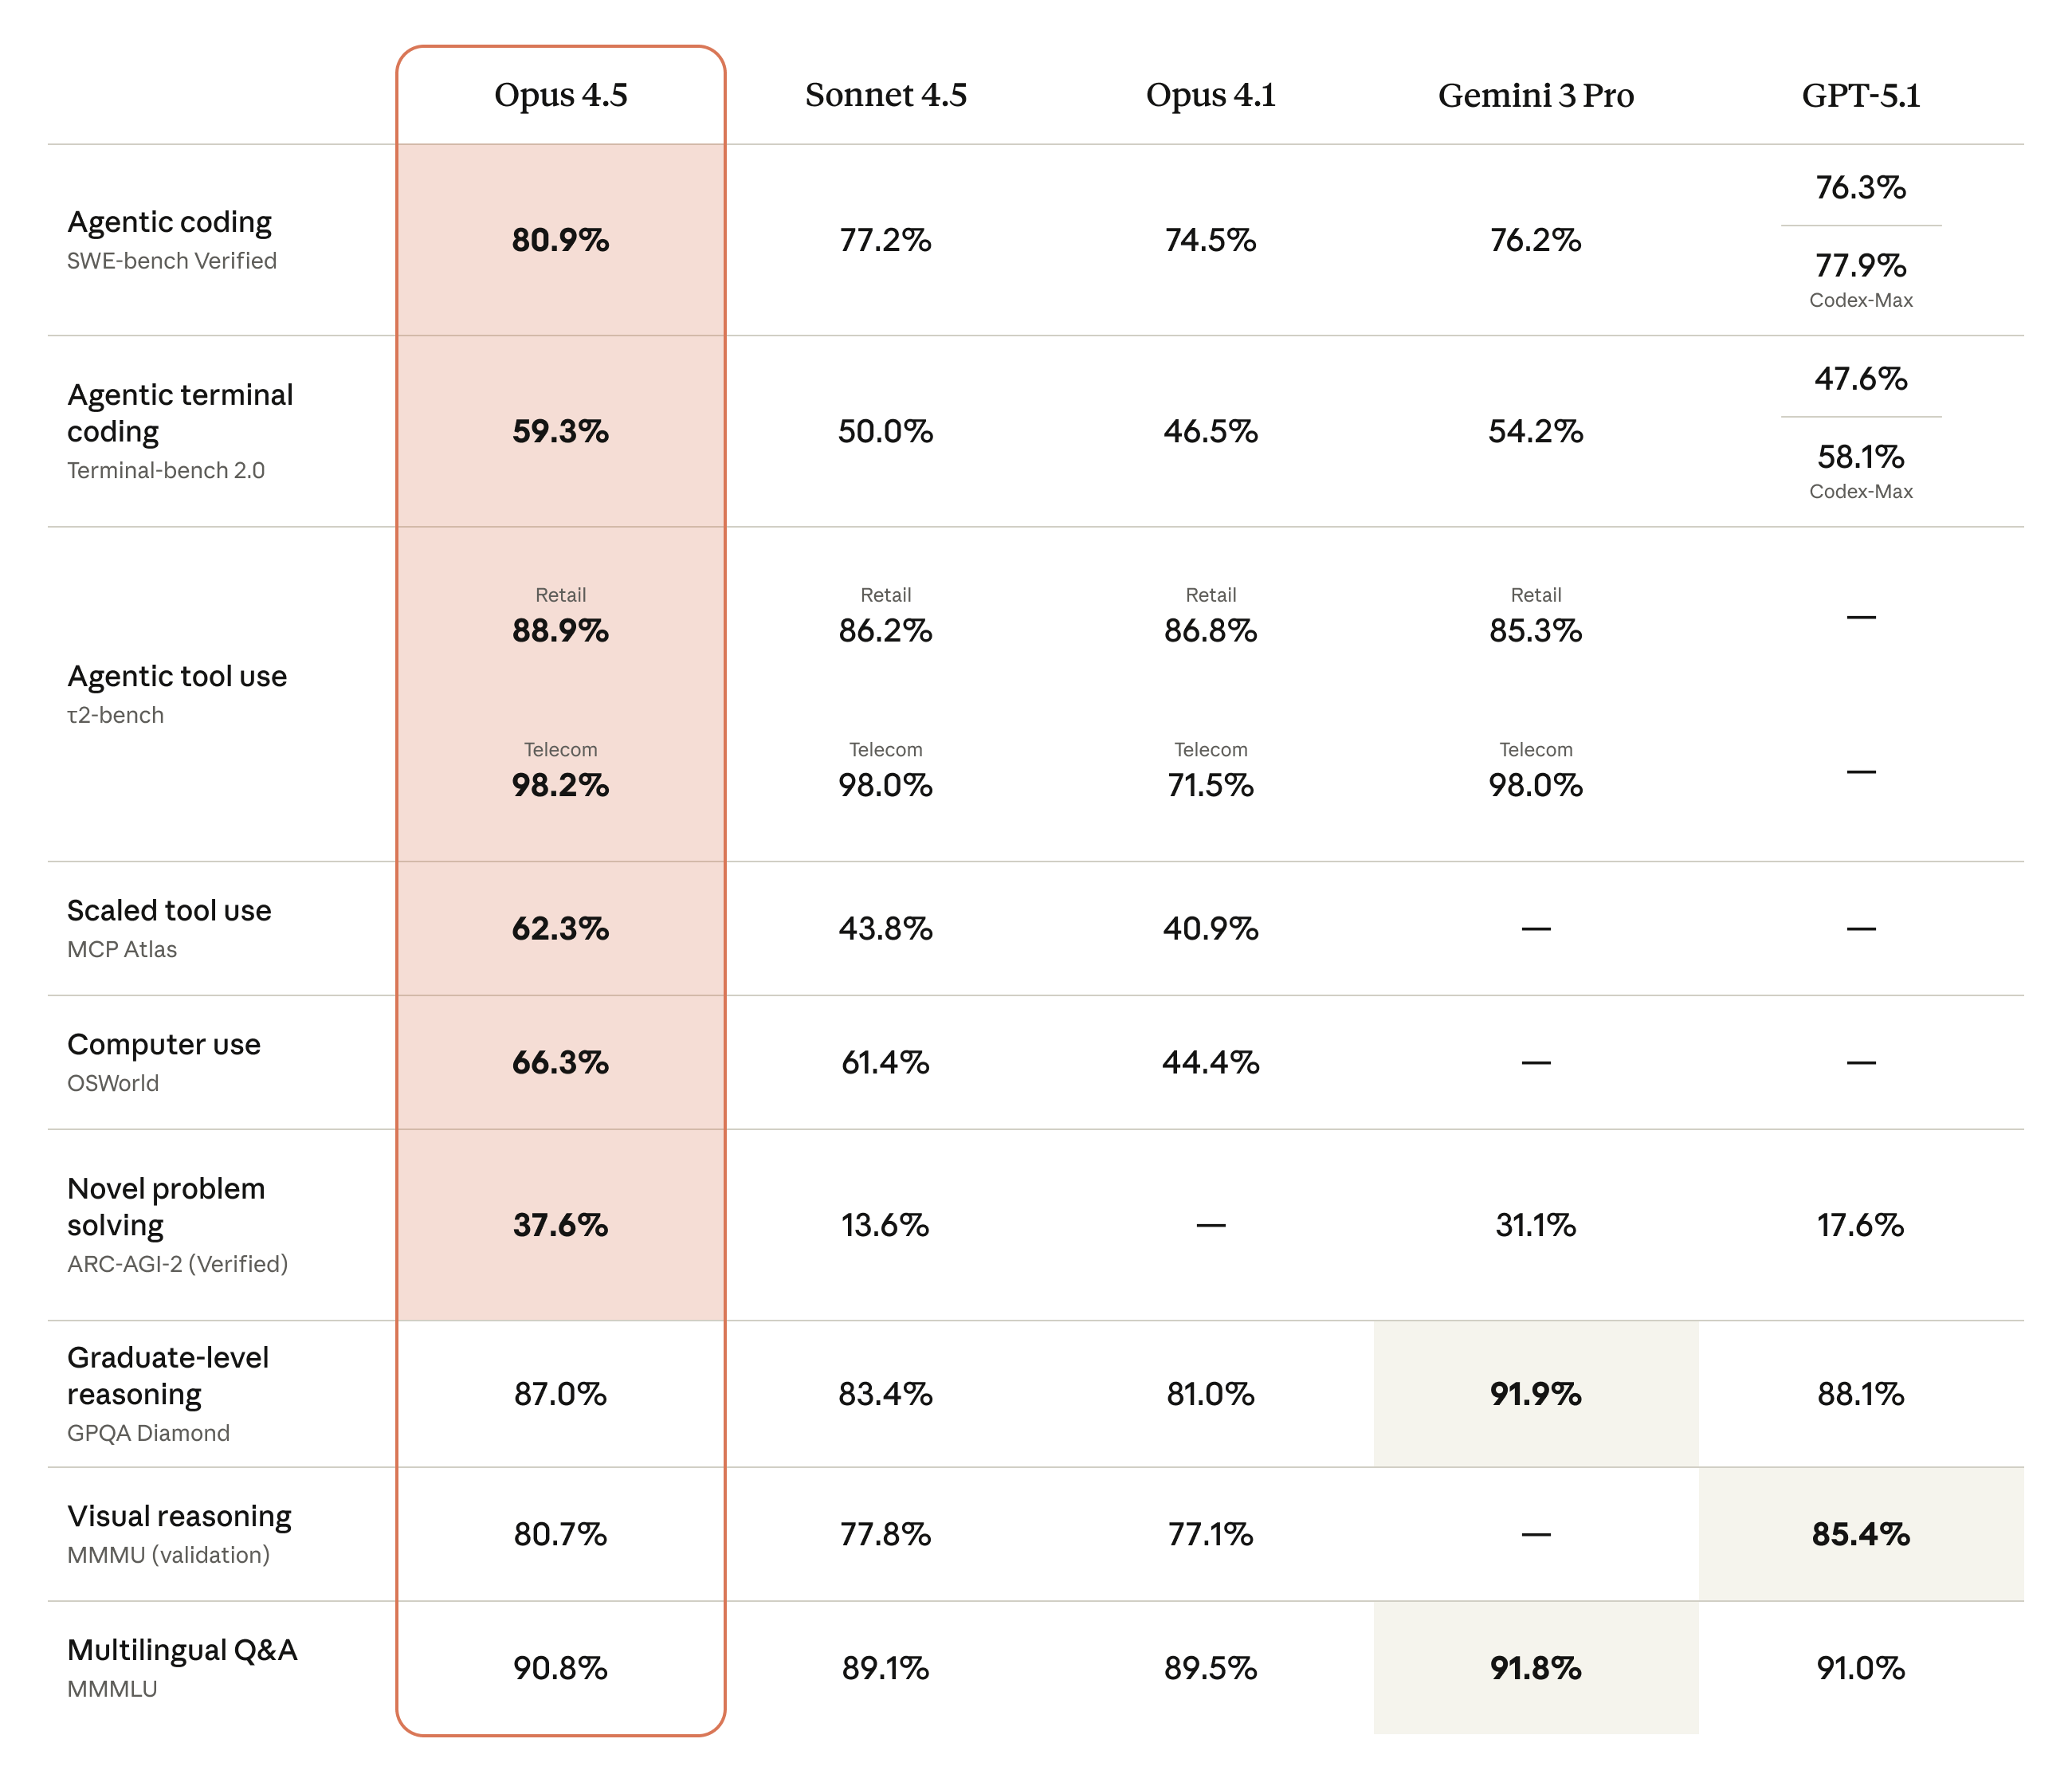
| Claude Opus 4.524 Nov 2025 · Anthropic | 80.9% | Introducing Claude Opus 4.5no thinking budget, default effort (high), averaged over 5 trials (methodology)Source image | Not yet |
| Gemini 3 Pro18 Nov 2025 · Google | 76.2% | Start building with Gemini 3single attemptSource image | Not yet |
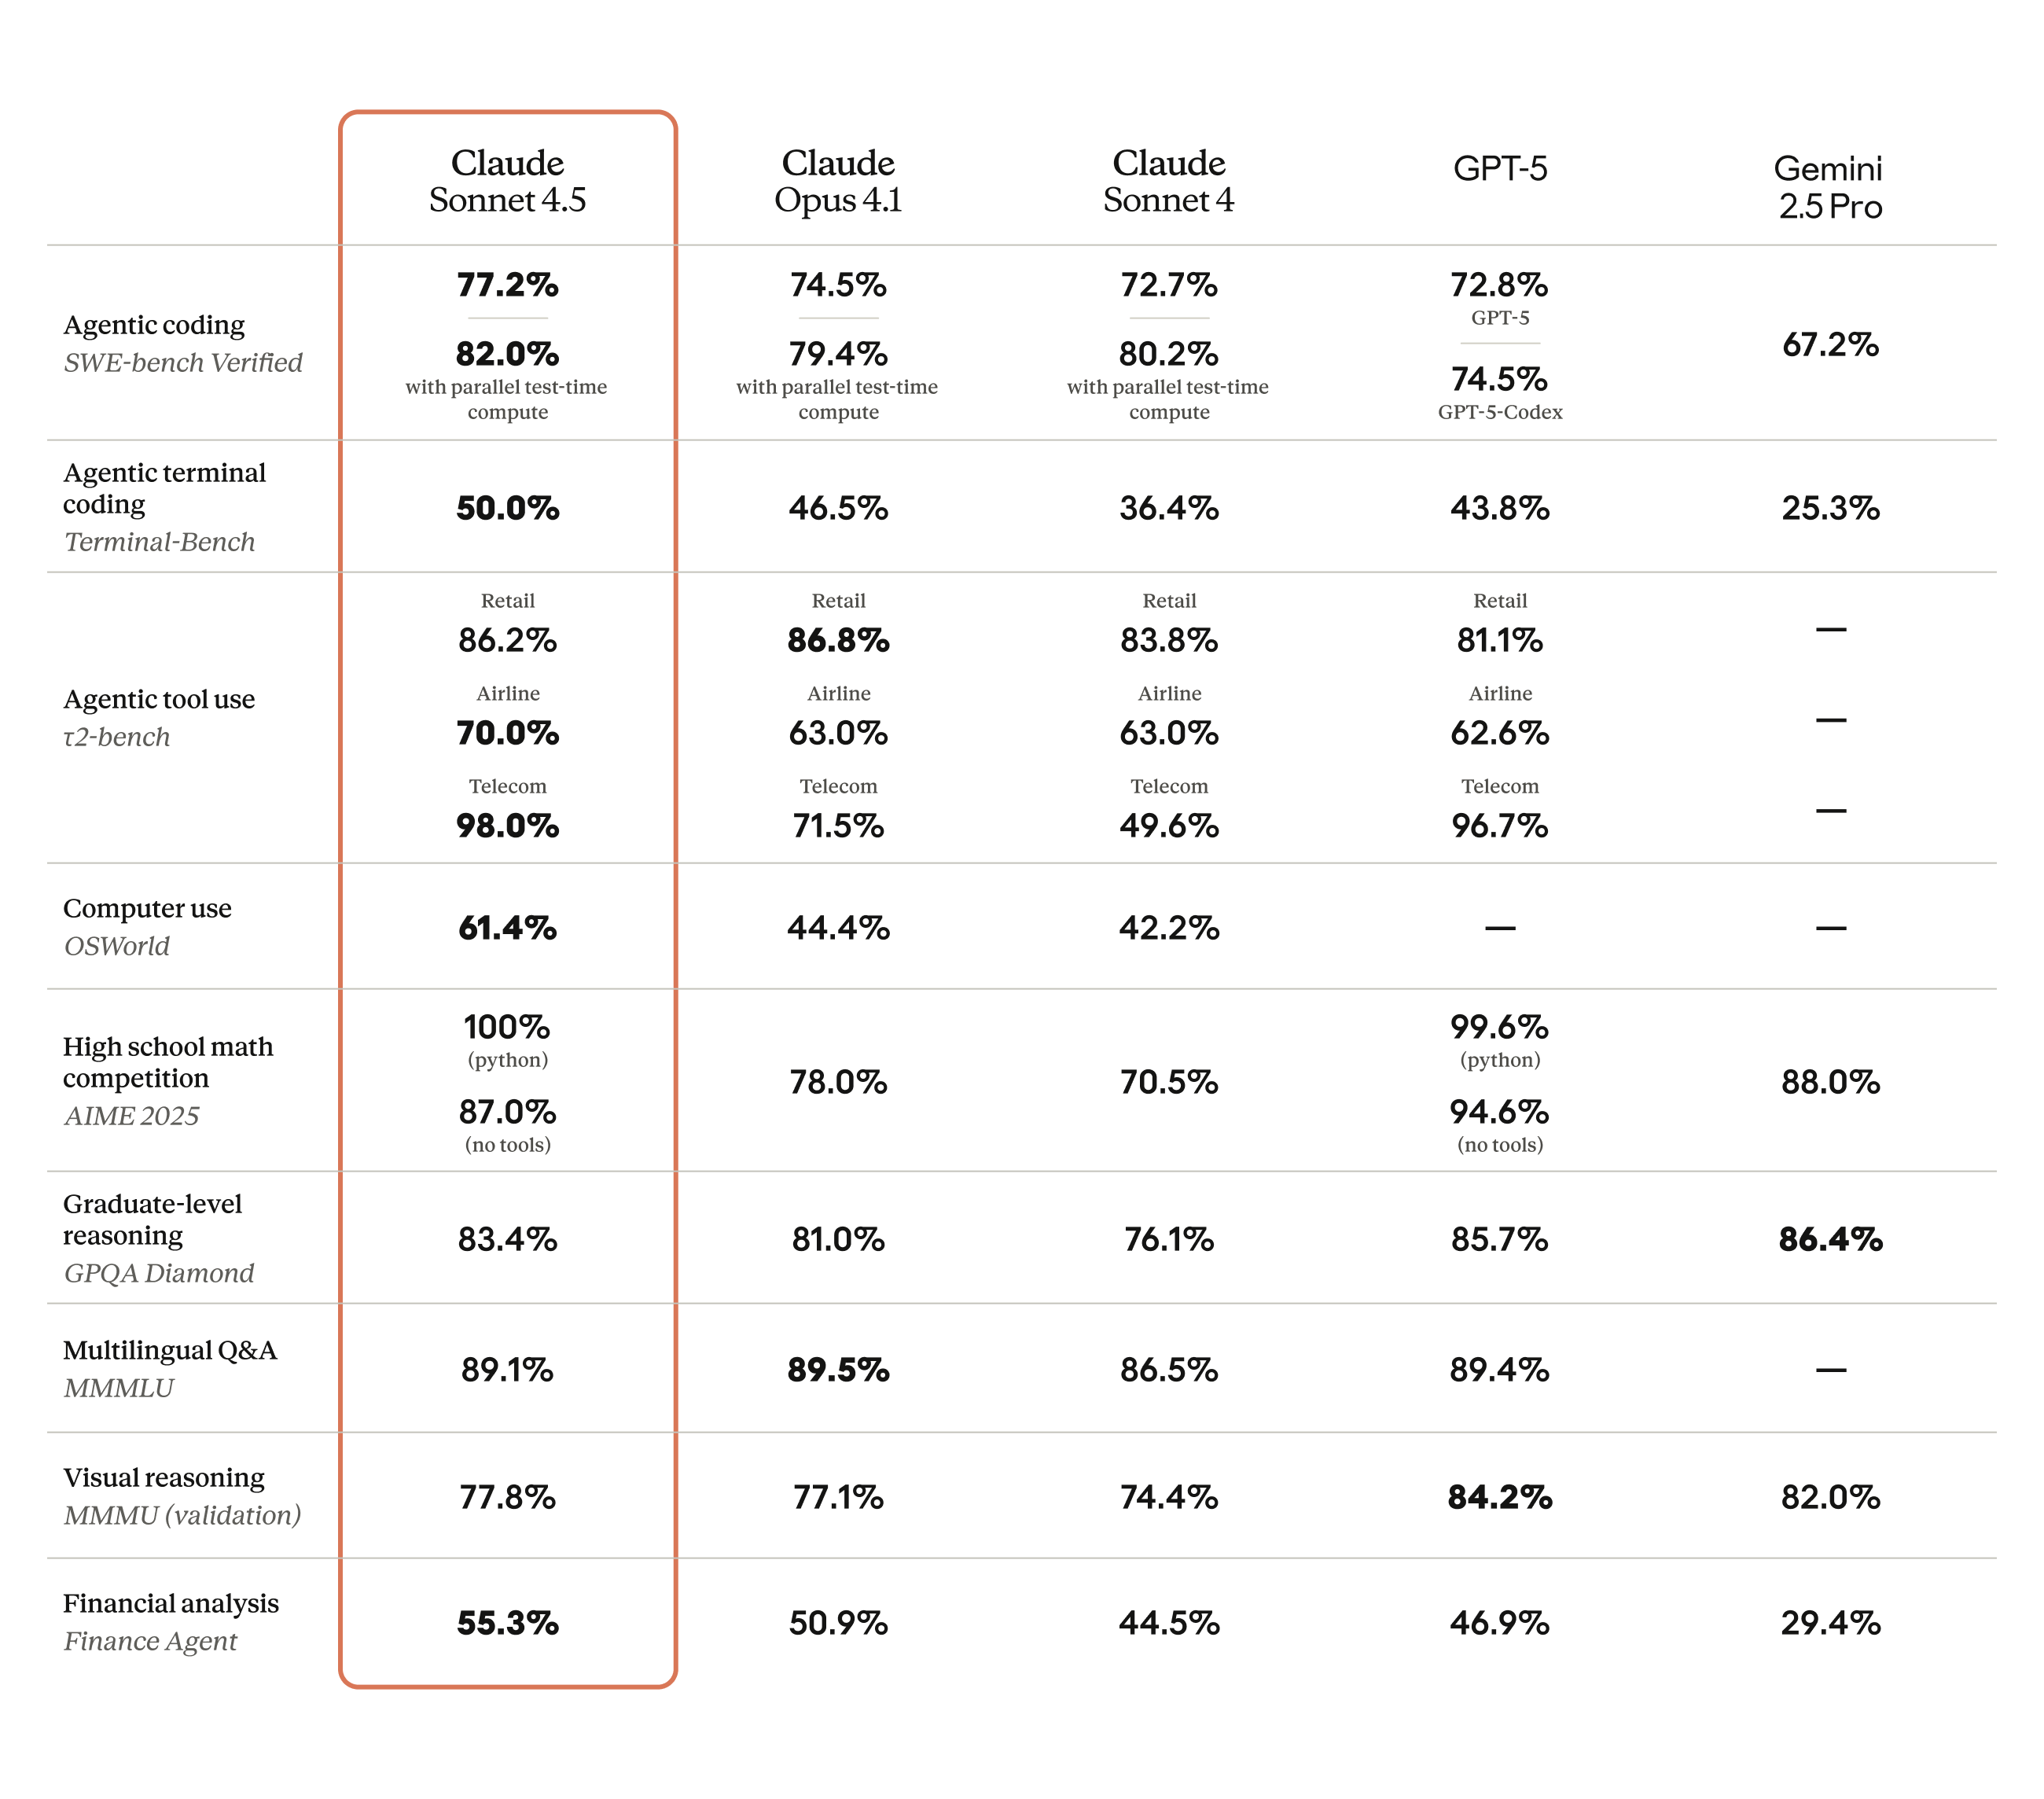
| Claude Sonnet 4.529 Sep 2025 · Anthropic | 77.2% | Introducing Claude Sonnet 4.5bash and file-editing tools, averaged over 10 trials, no test-time compute, 200K thinking budget (methodology)Source image | Not yet |
| Claude Sonnet 4.529 Sep 2025 · Anthropic | 82.0% | Introducing Claude Sonnet 4.5parallel test-time compute; with parallel test-time computeSource image | Not yet |
| GPT-57 Aug 2025 · OpenAI | 74.9% | Introducing GPT-5 | Not yet |
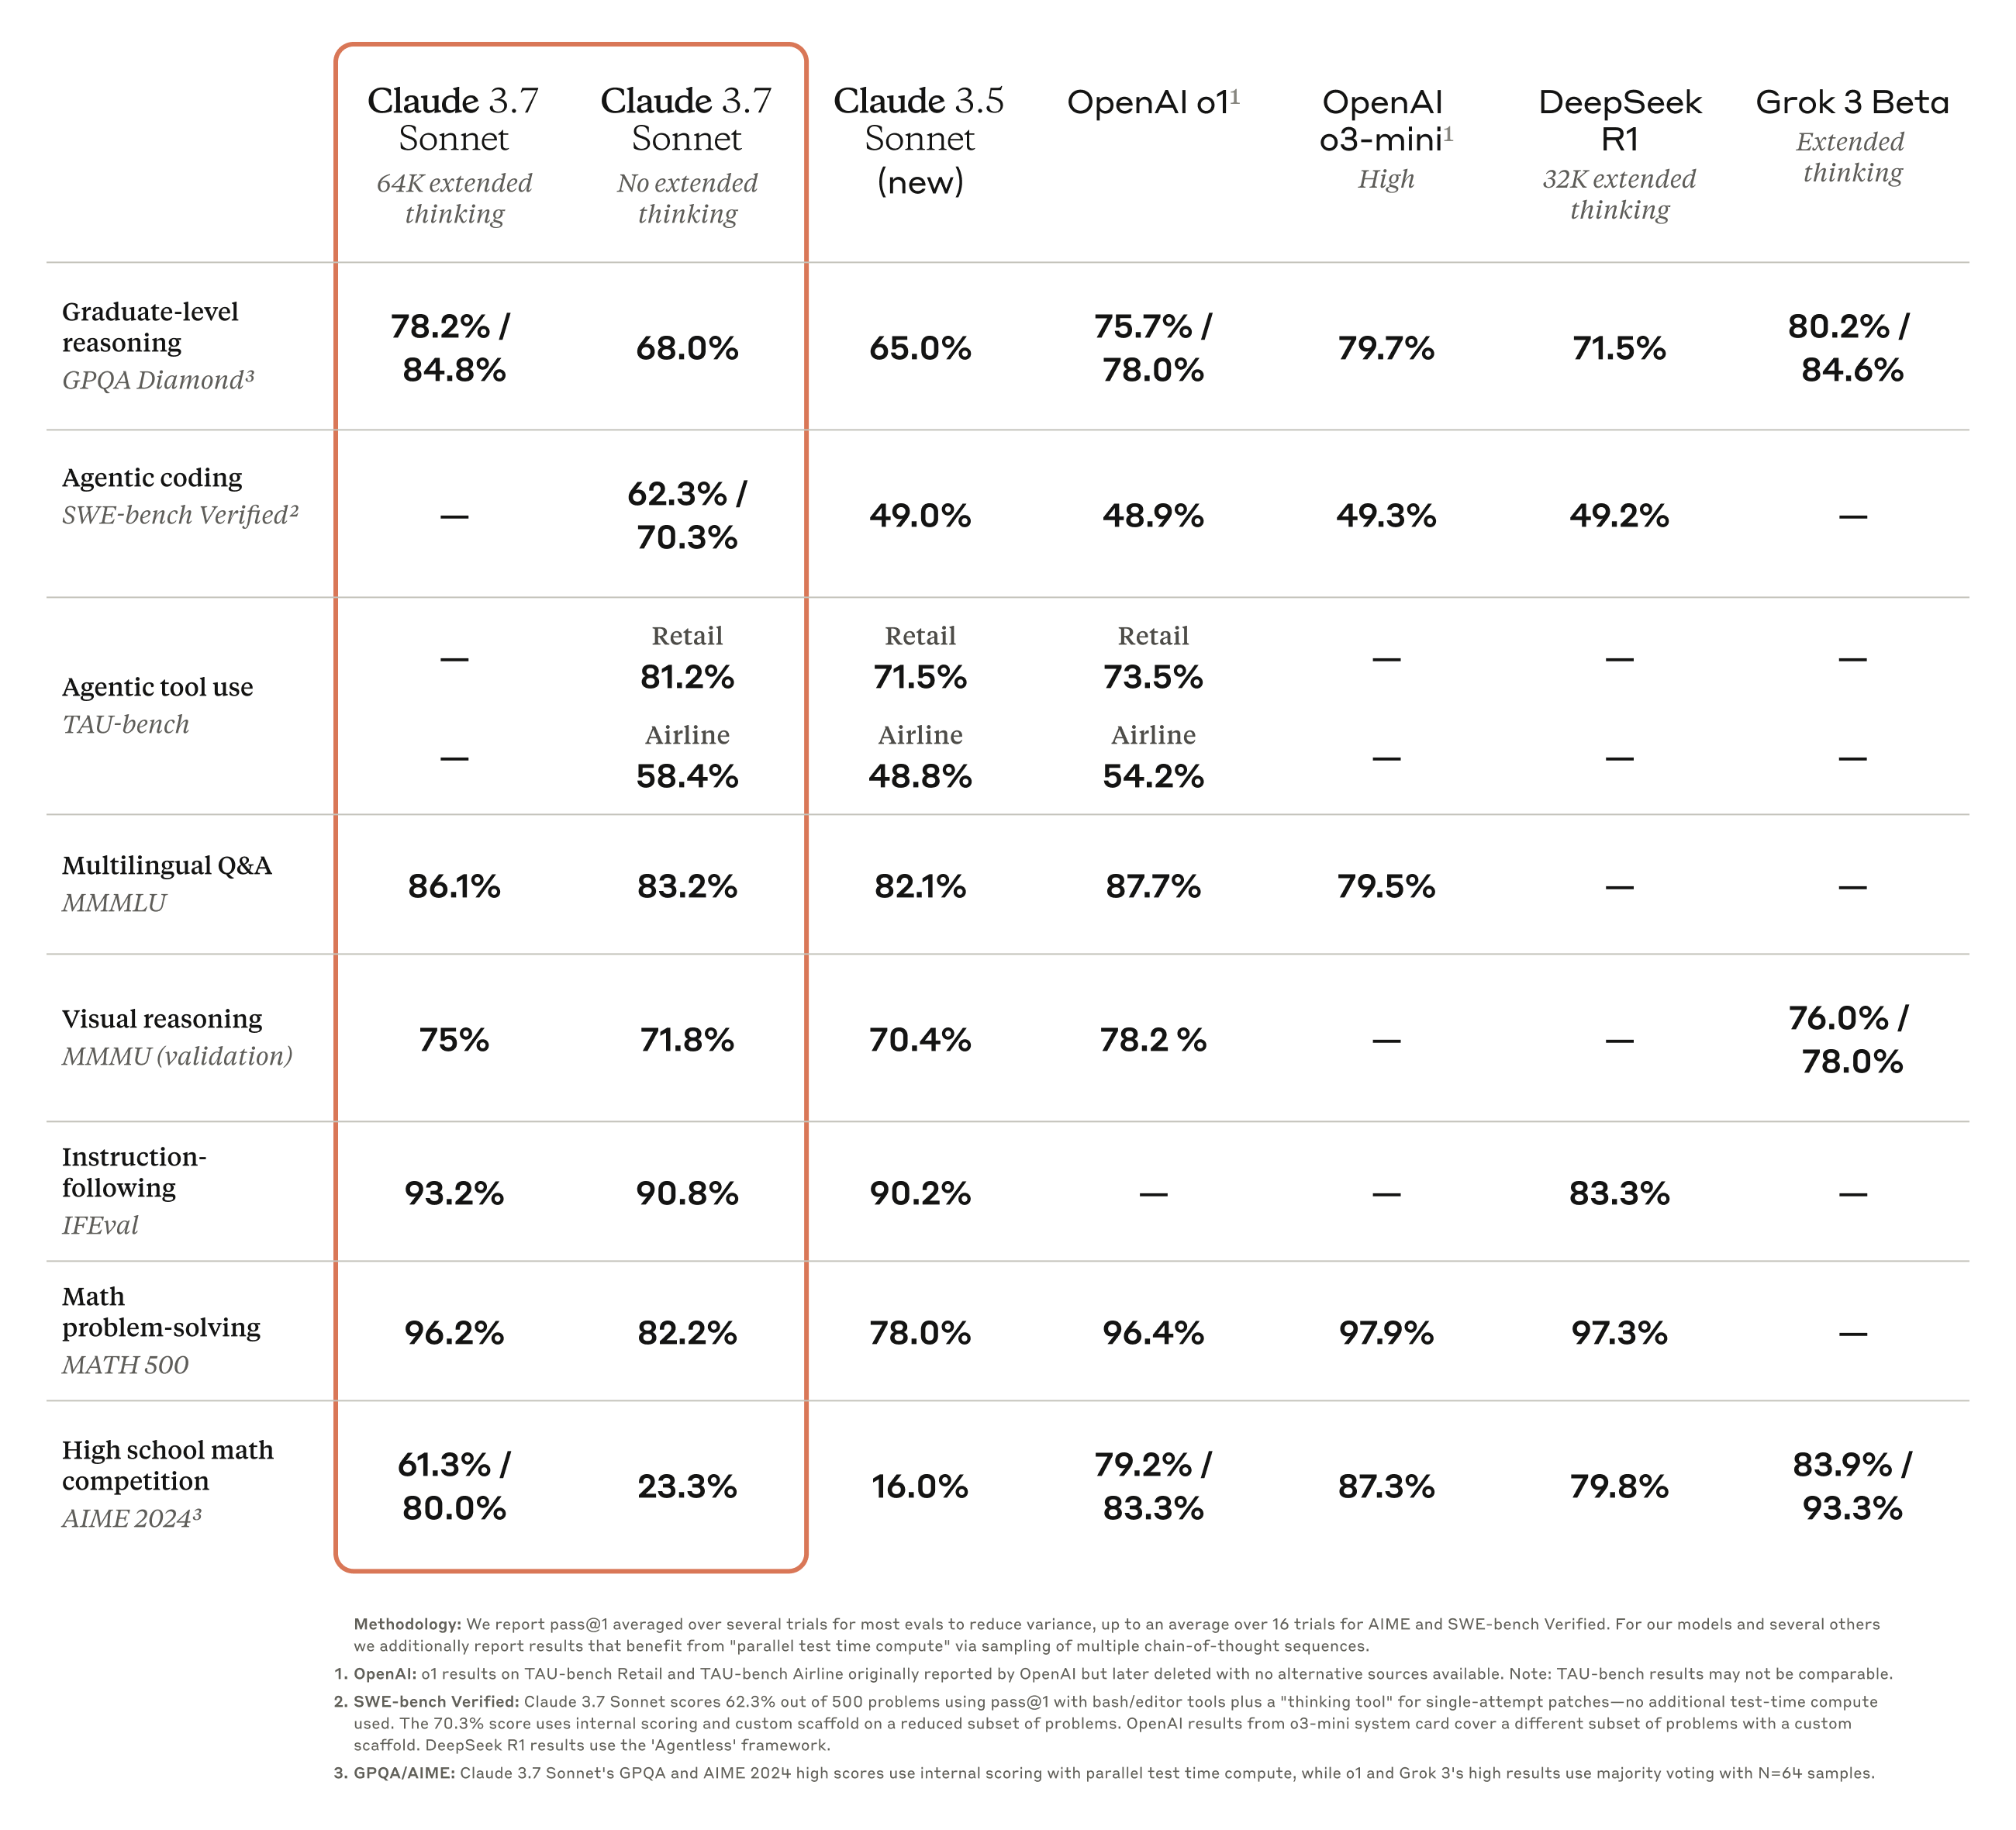
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 62.3% | Claude 3.7 Sonnet and Claude Codepass@1 with bash/editor tools plus a 'thinking tool', averaged over 16 trials (footnote 2)Source image | Yes |
| Claude 3.7 Sonnet24 Feb 2025 · Anthropic | 70.3% | Claude 3.7 Sonnet and Claude Codeparallel test-time compute; internal scoring and custom scaffold on a reduced subset of problems (footnote 2)Source image | Yes |
Benchmark
swebench.comHigher is better