Claude Opus 4.5
- Made by
- Anthropic
- Released
- Announced in
- Introducing Claude Opus 4.5anthropic.com
- Event
- Claude Opus 4.5
- API record
- /api/v1/models/claude-opus-4-5
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
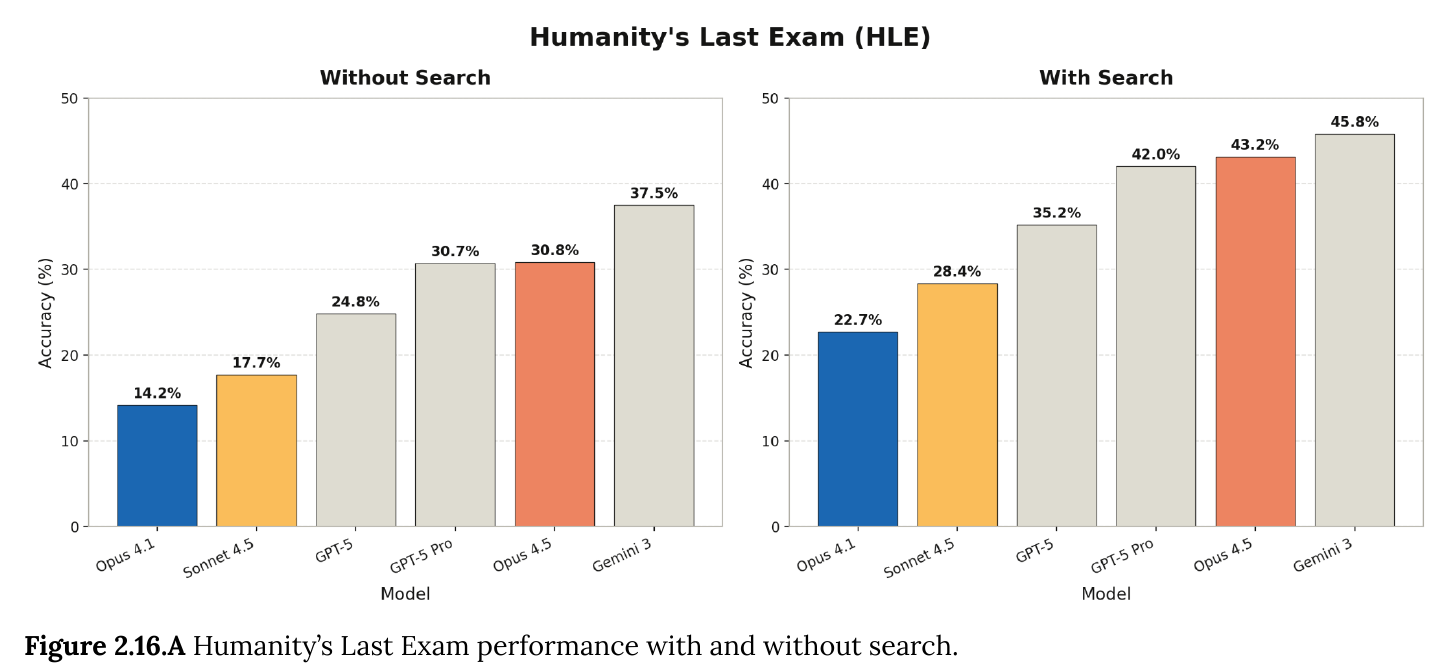
| Humanity's Last ExamNo tools · reasoning only; Claude Sonnet 4.5 as grader | 30.8% | CheckedA person checked this number against its source on 16 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Humanity's Last ExamWith tools · web search, web fetch and code execution, no reasoning; Claude Sonnet 4.5 as grader | 43.2% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
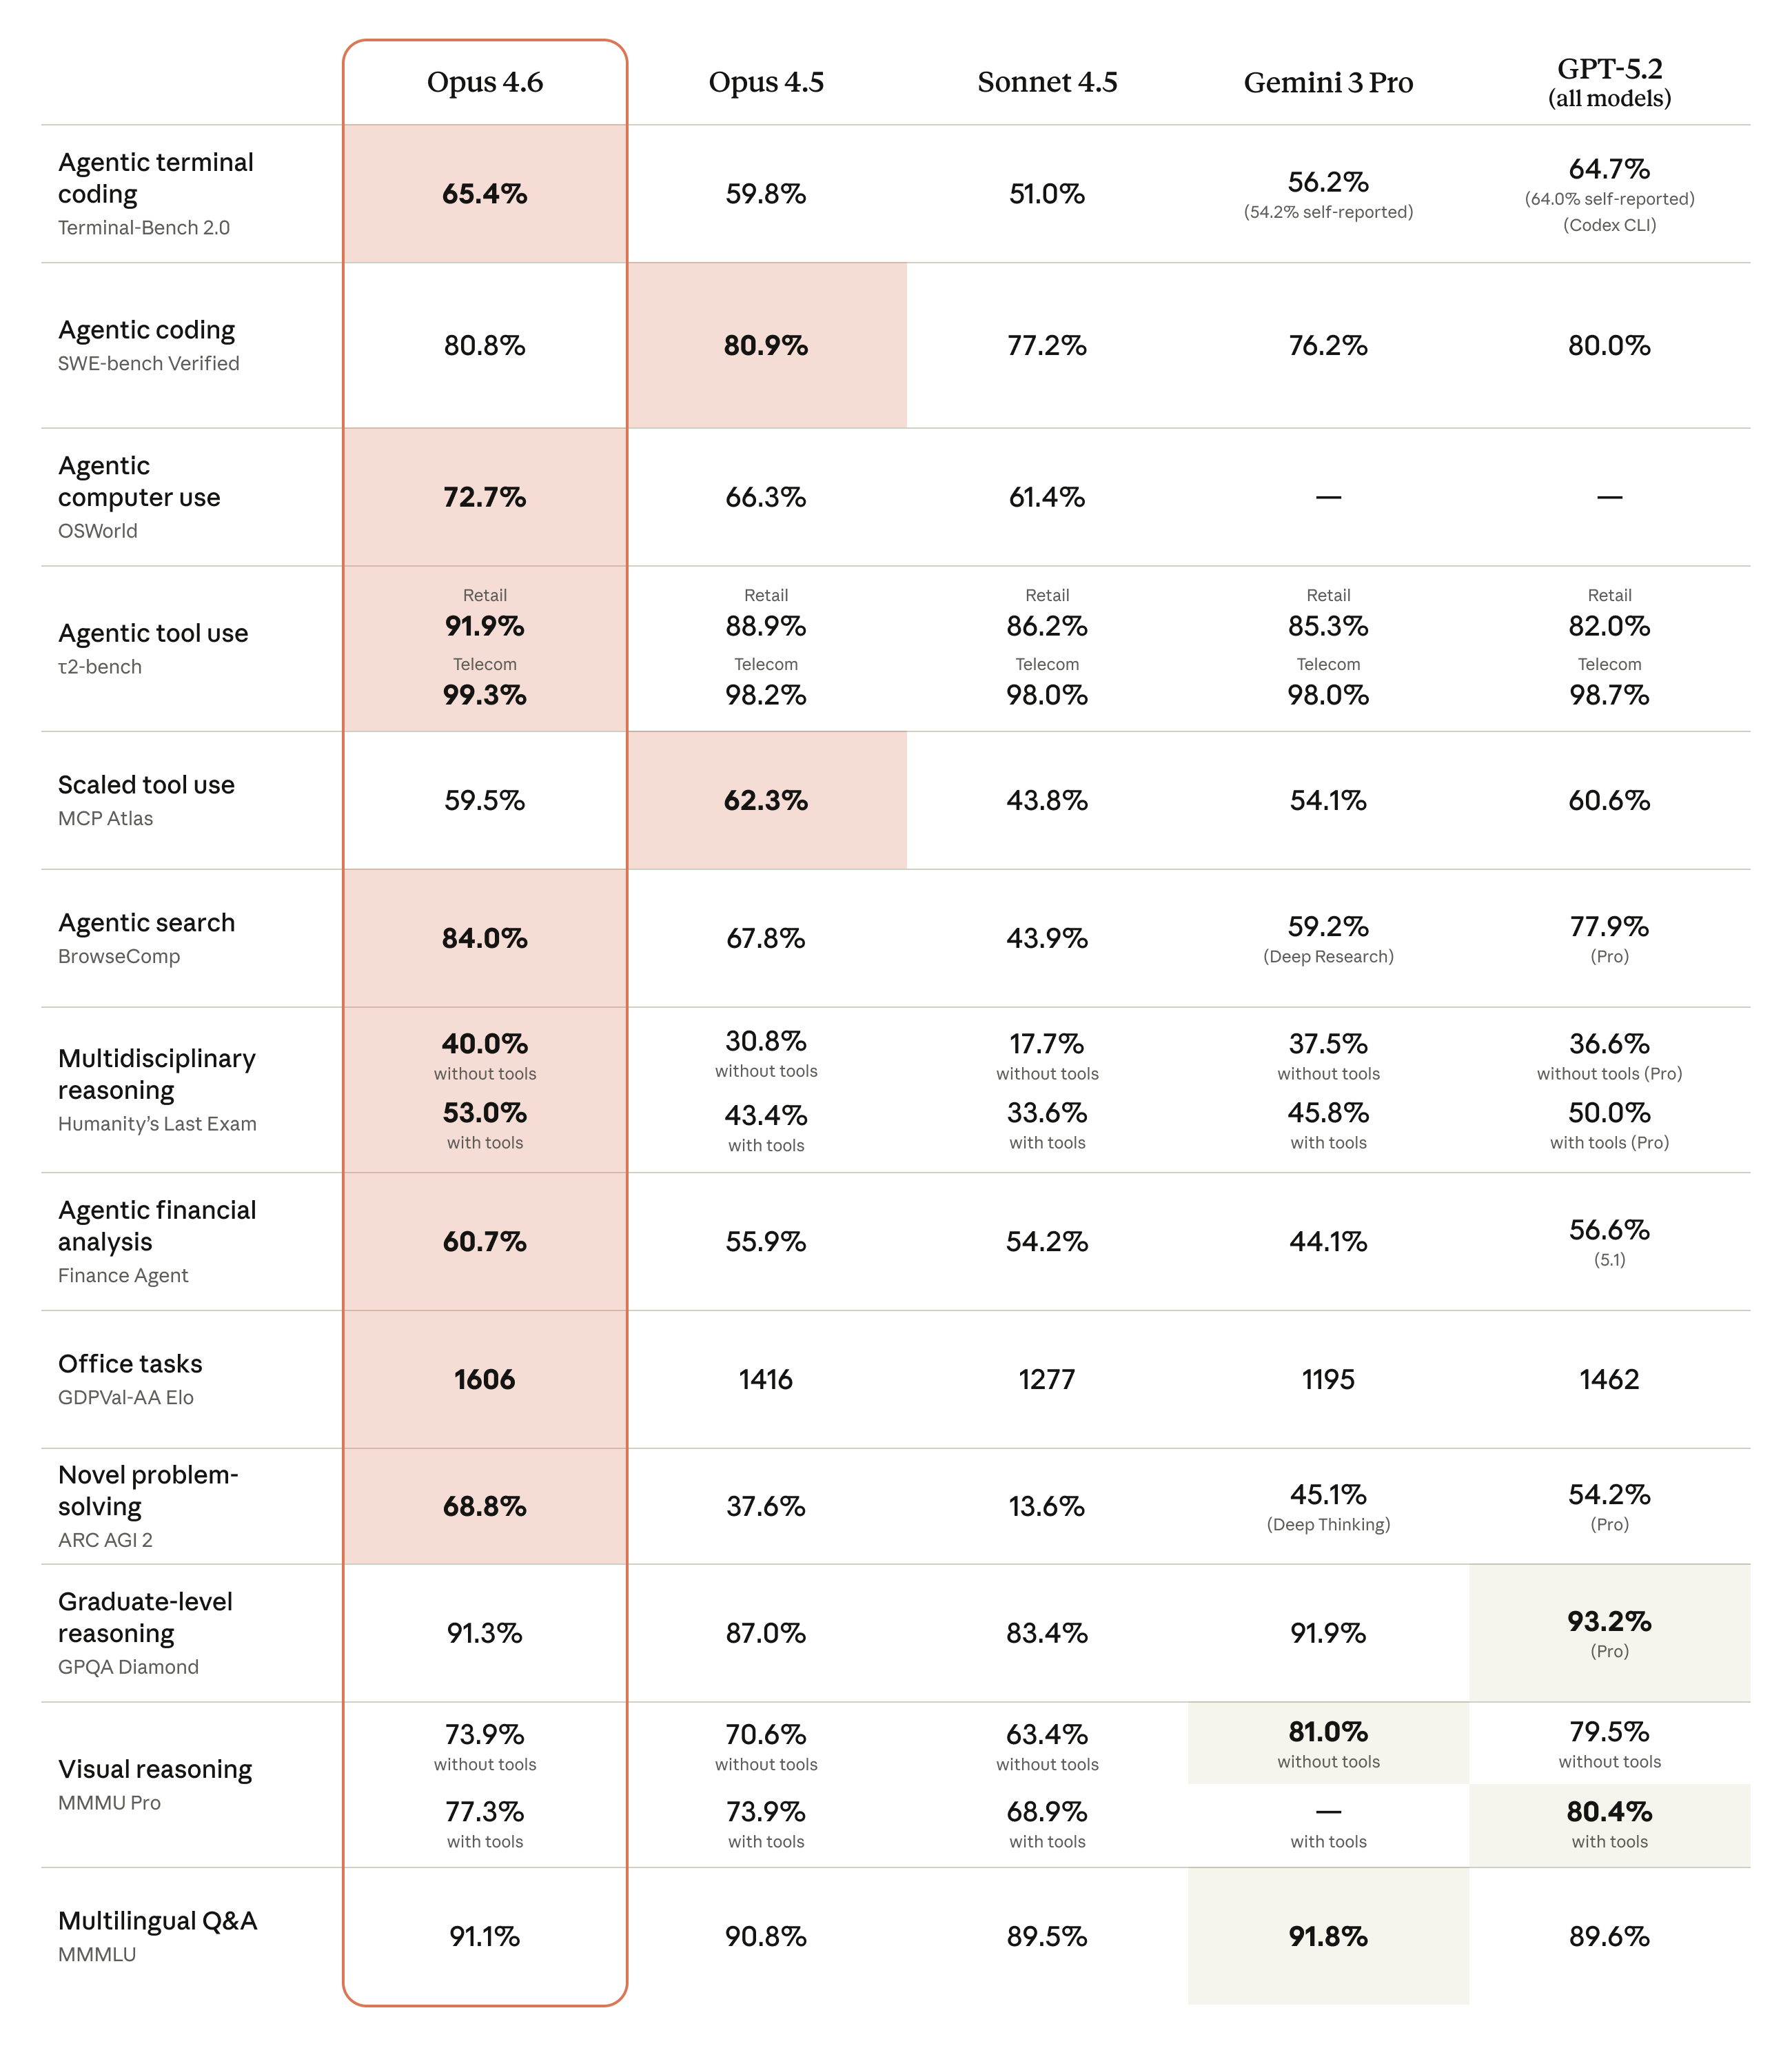
| web search, web fetch, code execution, programmatic tool calling; compaction at 50K up to 3M tokens; max effort, adaptive thinking · reported later, in Claude Opus 4.6 | 43.4% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
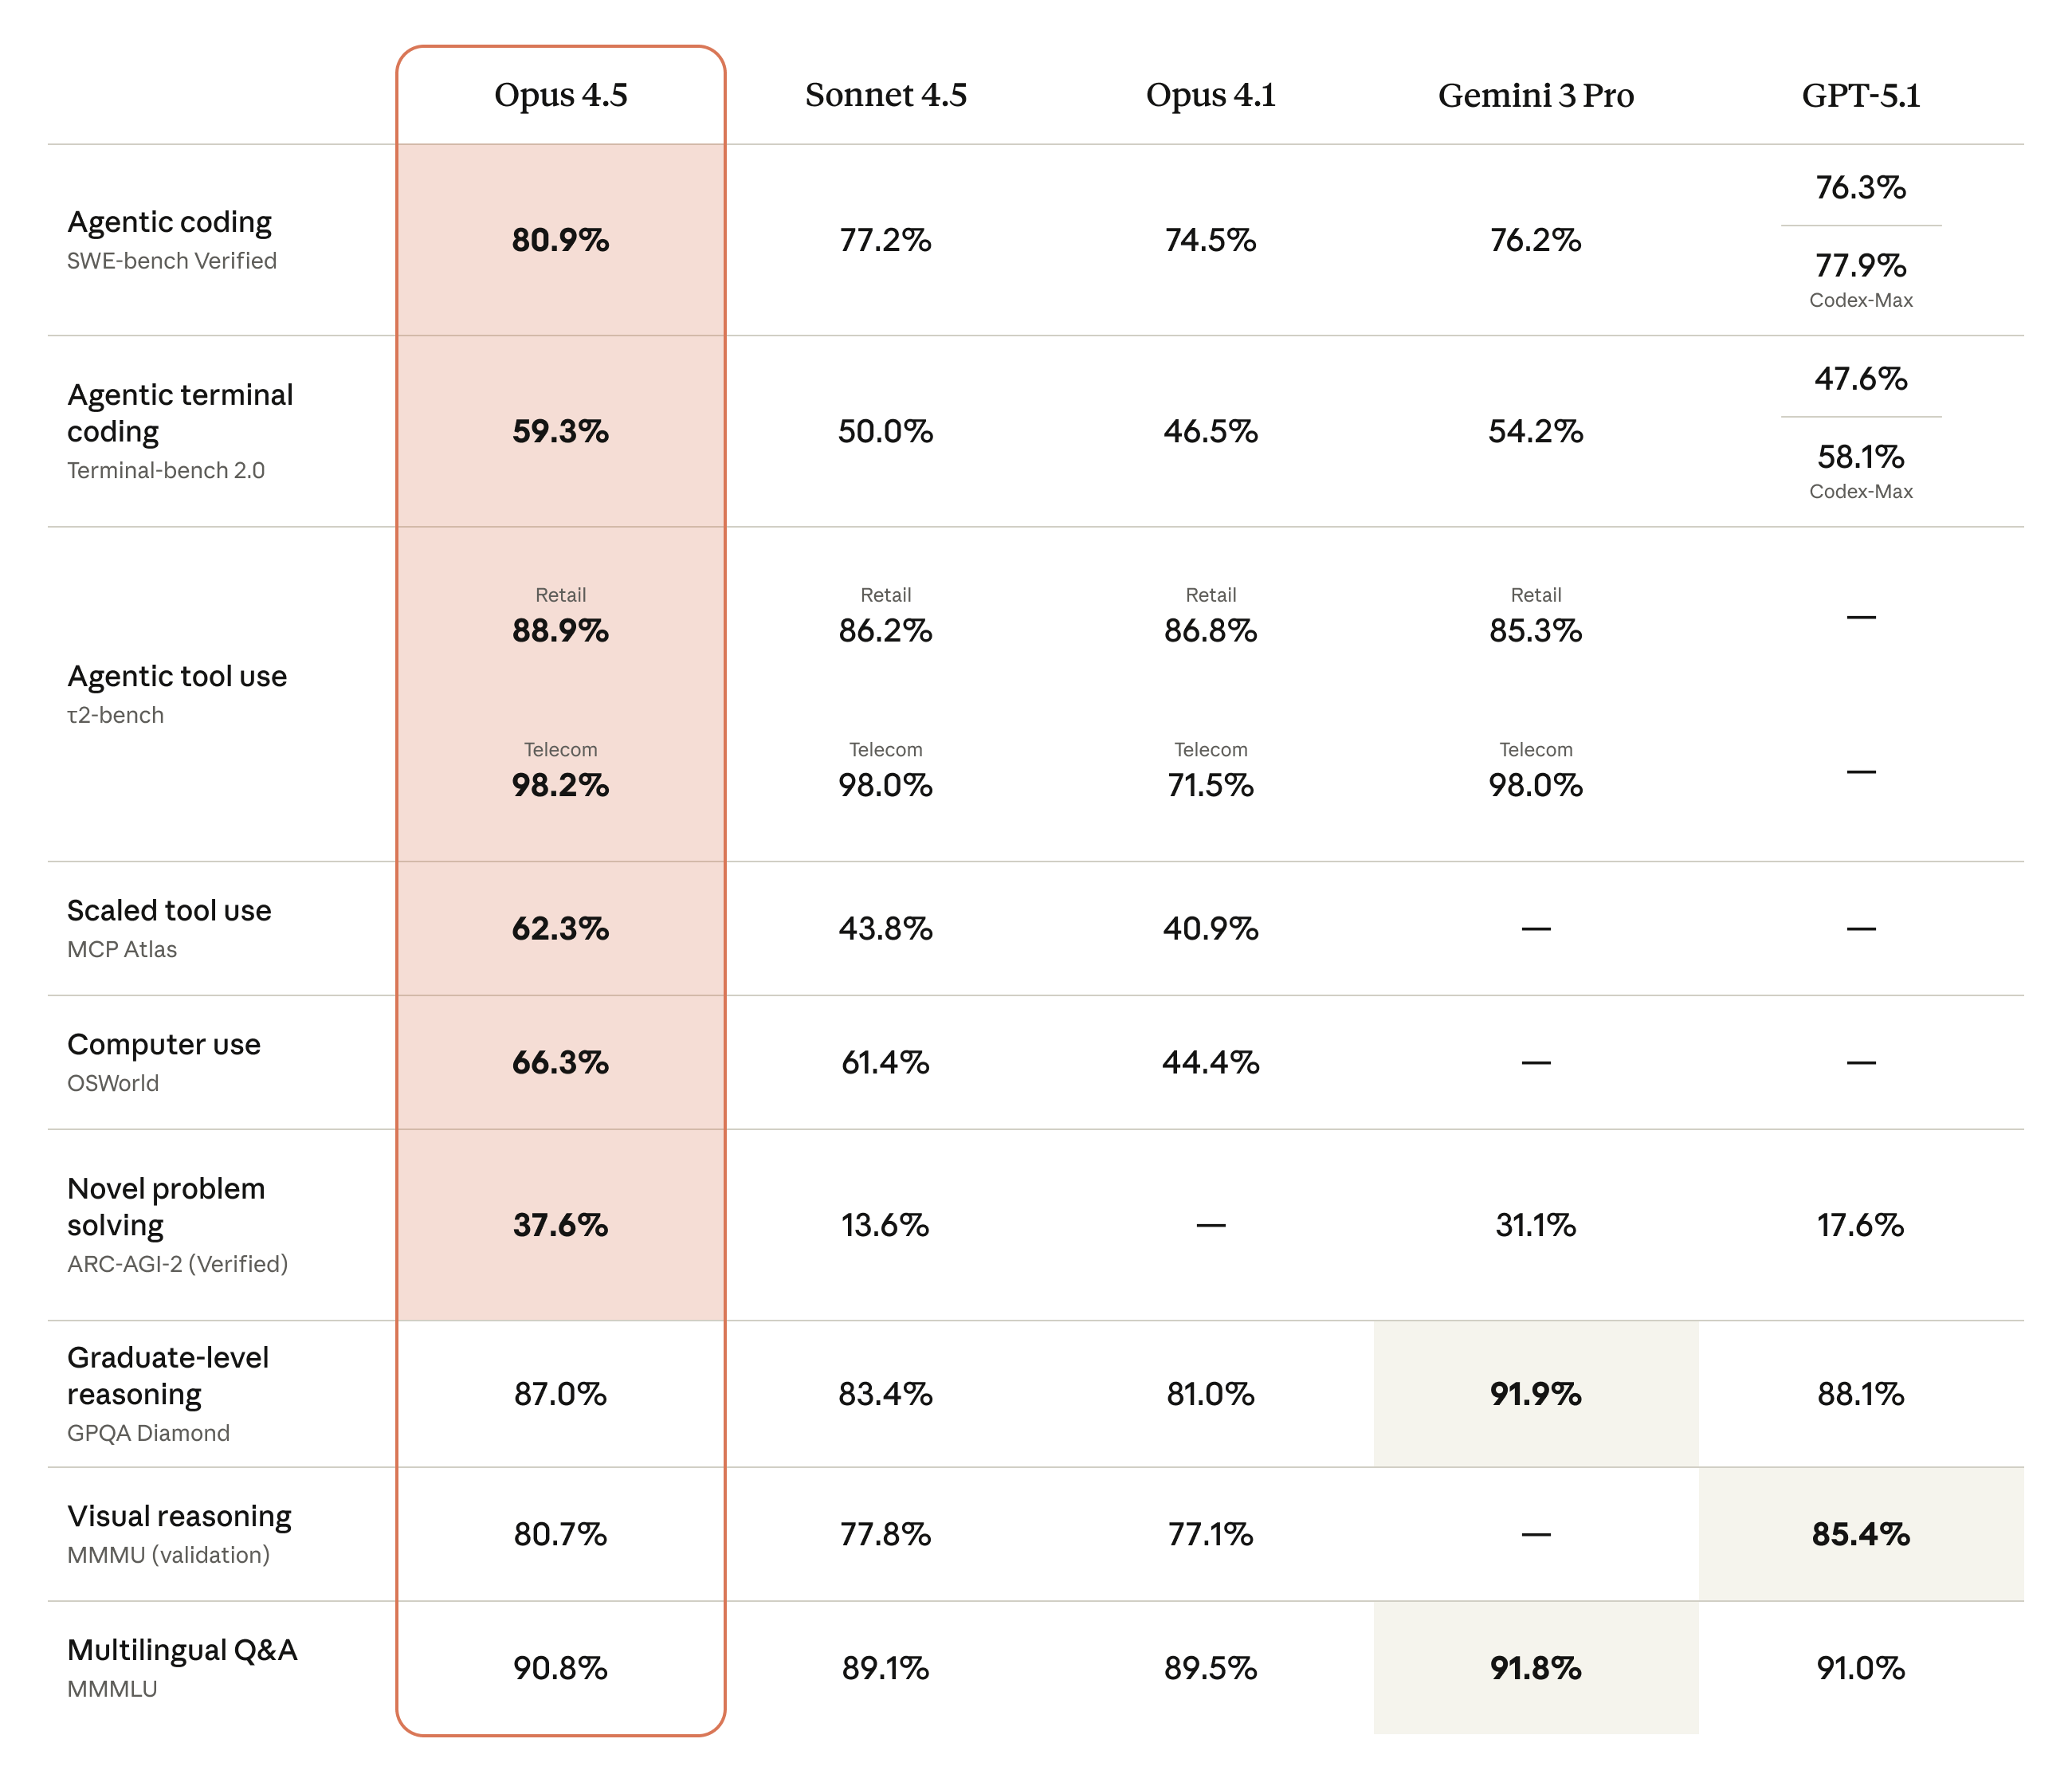
| SWE-bench Verifiedno thinking budget, high effort; averaged over 5 trials | 80.9% | CheckedA person checked this number against its source on 16 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Prono thinking; average of 5 trials · The source doesn't say whether this is the public or the commercial set | 52.0% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| 64K thinking budget; average of 5 trials · The source doesn't say whether this is the public or the commercial set | 51.60% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| GPQA Diamond64K thinking budget, high effort; averaged over 5 trials | 87.0% | CheckedA person checked this number against its source on 16 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| BrowseCompreported later, in Claude Opus 4.6 | 67.8% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| ARC-AGI-264K thinking budget, high effort; averaged over 5 trials | 37.6% | CheckedA person checked this number against its source on 16 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 2.0128K thinking budget, high effort; averaged over 5 trials | 59.3% | CheckedA person checked this number against its source on 16 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| reported later, in Claude Opus 4.6 System Card | 59.8% |
Sources
Reported by Anthropic
- Claude Opus 4.5 System Cardanthropic.com · 24 Nov 2025
Our capture of page 32 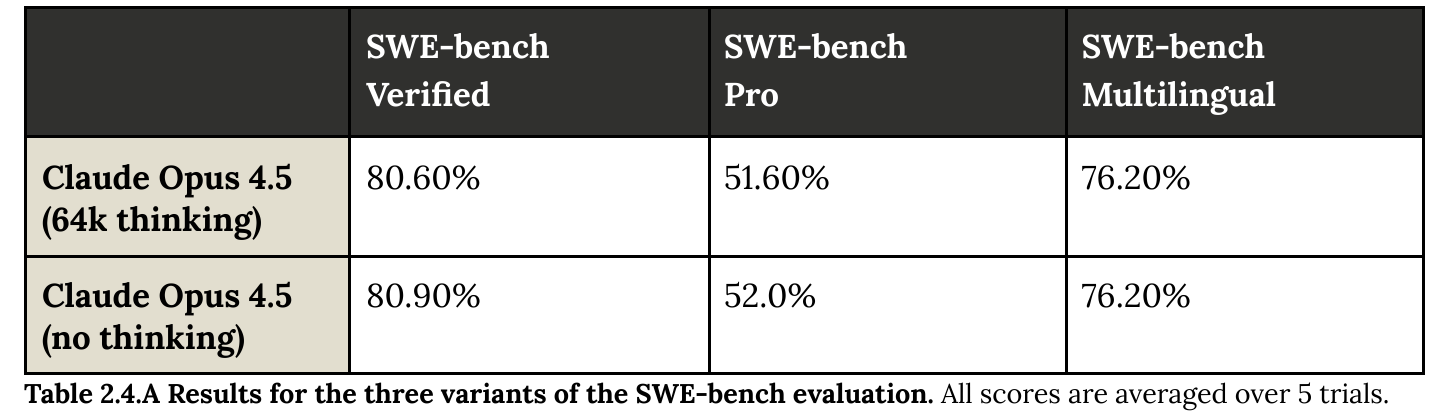
Our capture of page 20 - Introducing Claude Opus 4.5anthropic.com · 24 Nov 2025
Original image - Claude Opus 4.6 System Cardanthropic.com · 5 Feb 2026
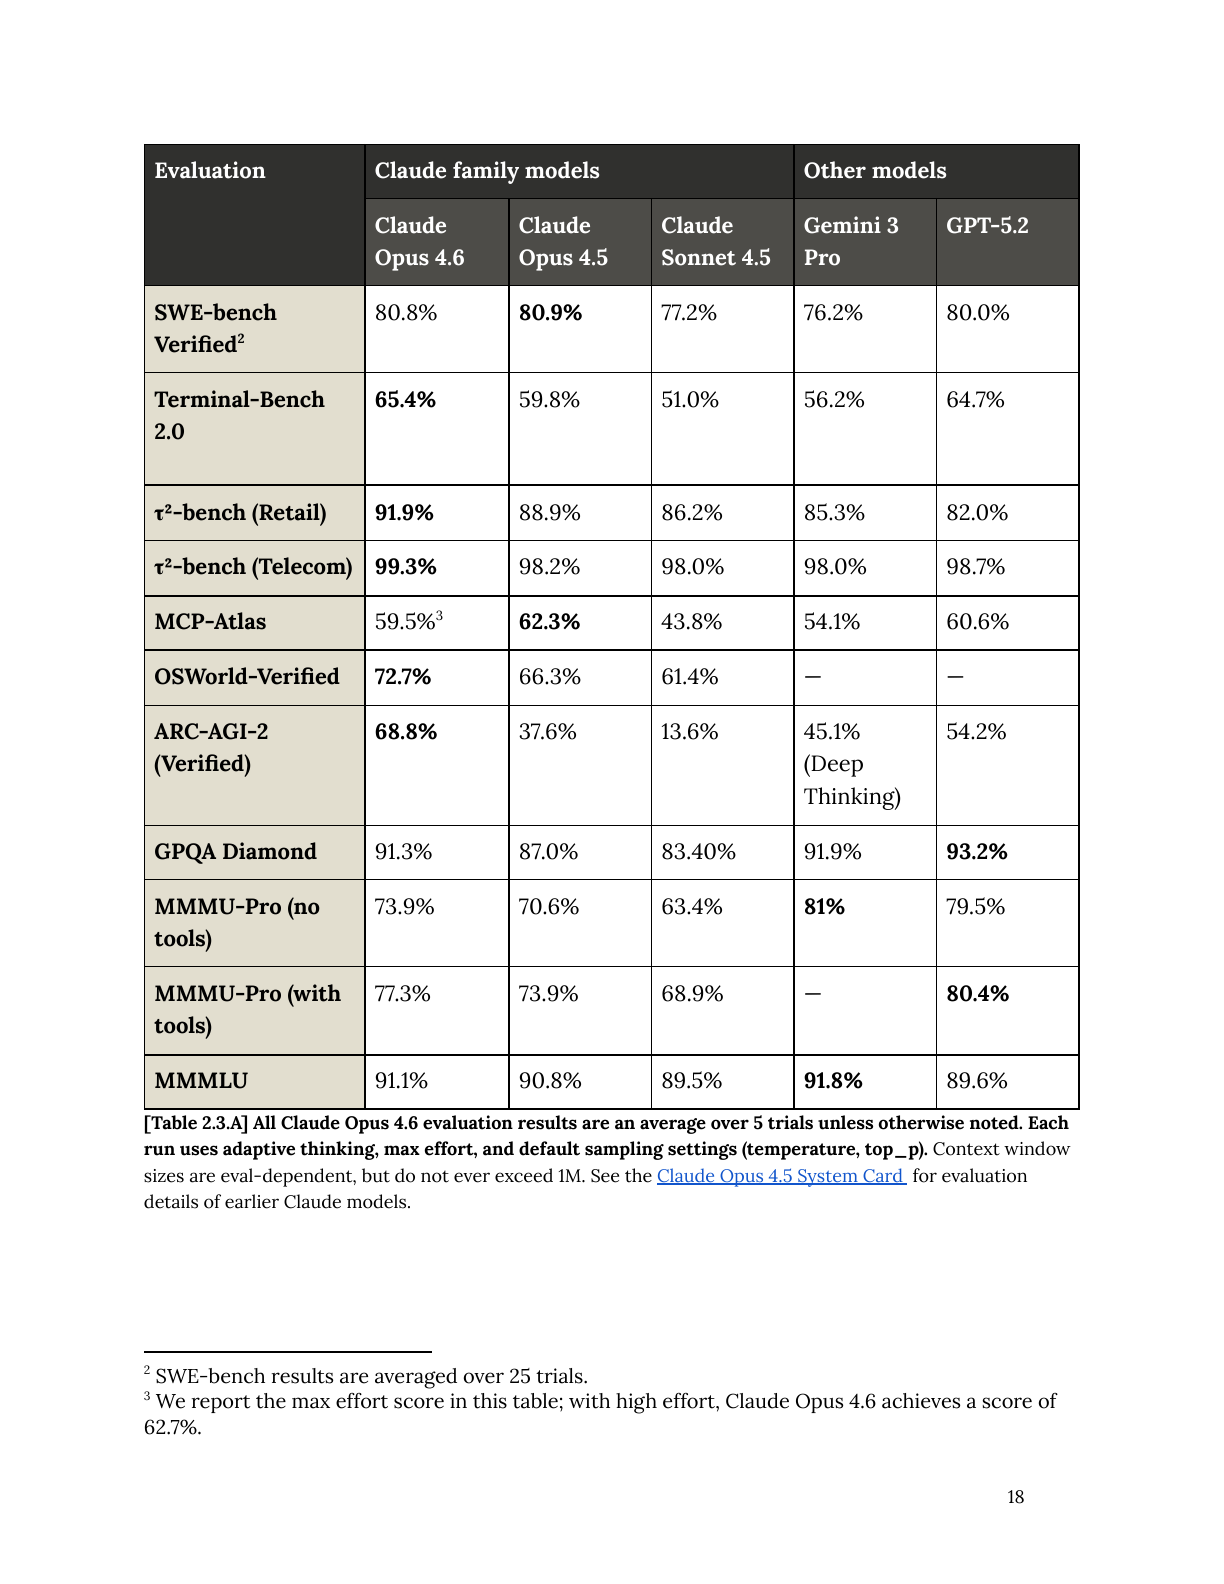
Our capture of page 18 - Claude Opus 4.6anthropic.com · 5 Feb 2026
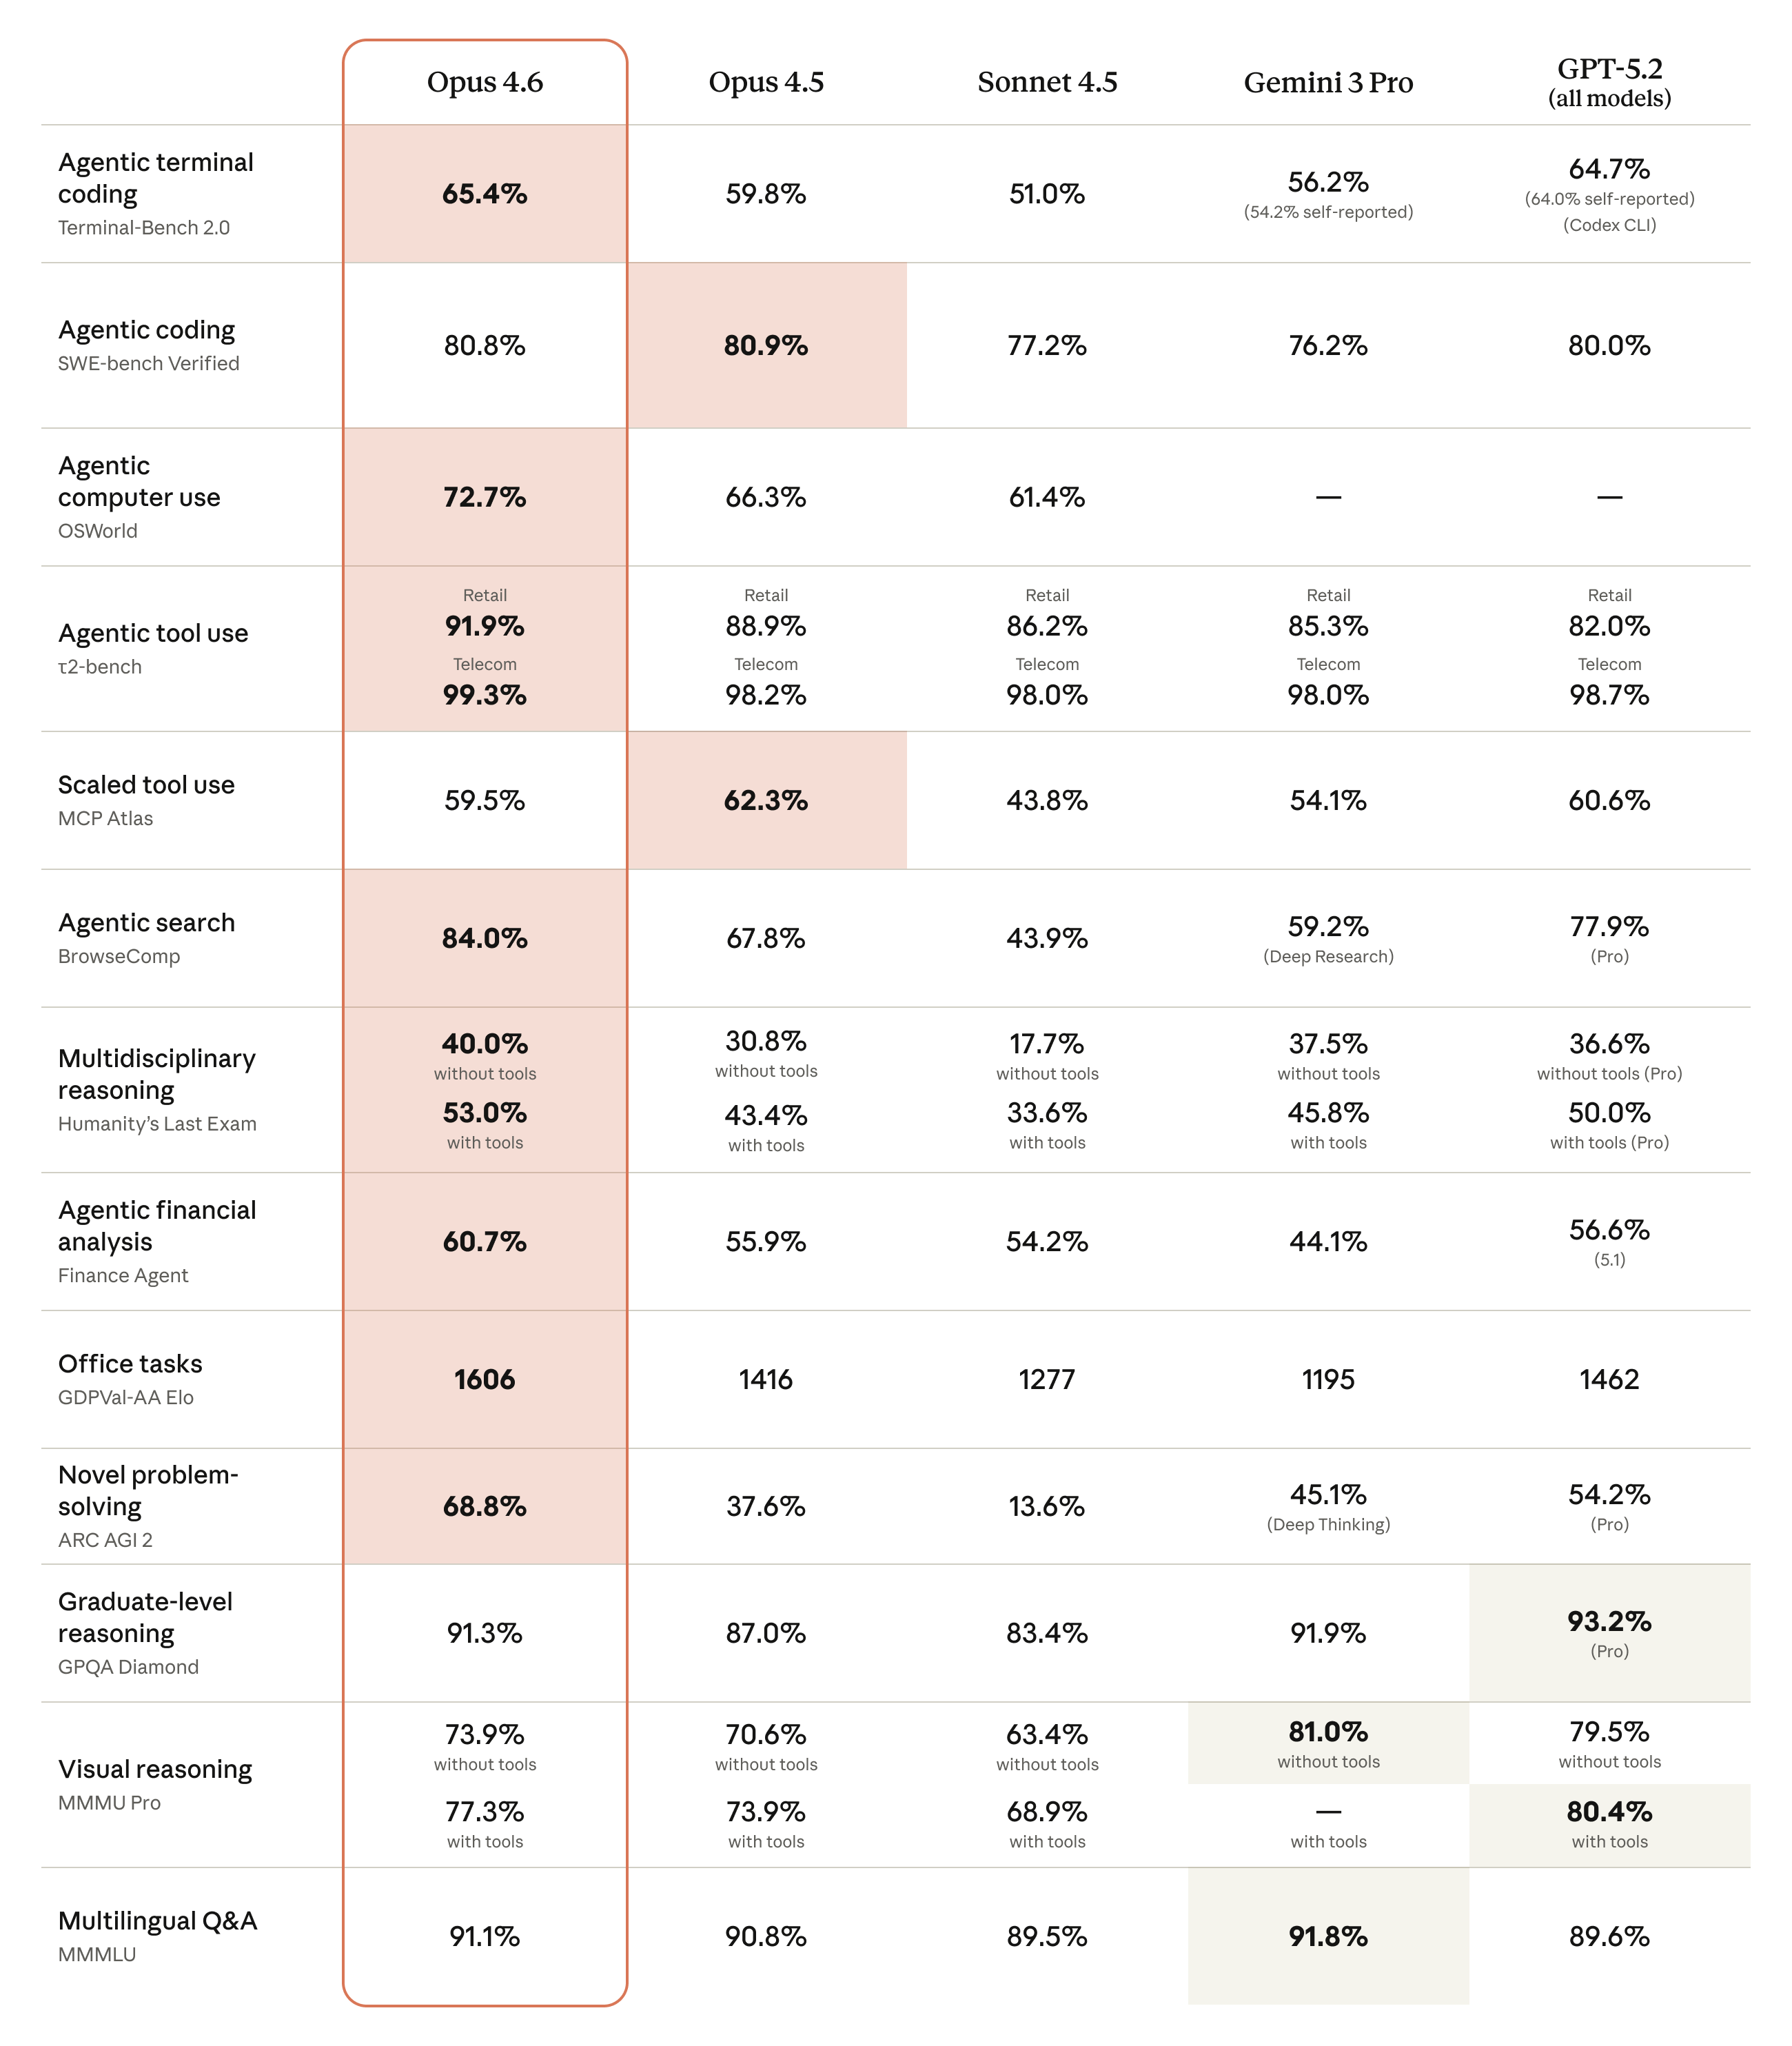
Original image