ARC-AGI-2
- OpenAI
- Anthropic
- Reported in a later post or card
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| Claude Opus 4.716 Apr 2026 · Anthropic | 75.83% | Claude Opus 4.7 System Cardmax thinking (section 8.11) | Not yet |
| GPT-5.45 Mar 2026 · OpenAI | 73.3% | Introducing GPT-5.4ARC-AGI-2 (Verified) | Not yet |
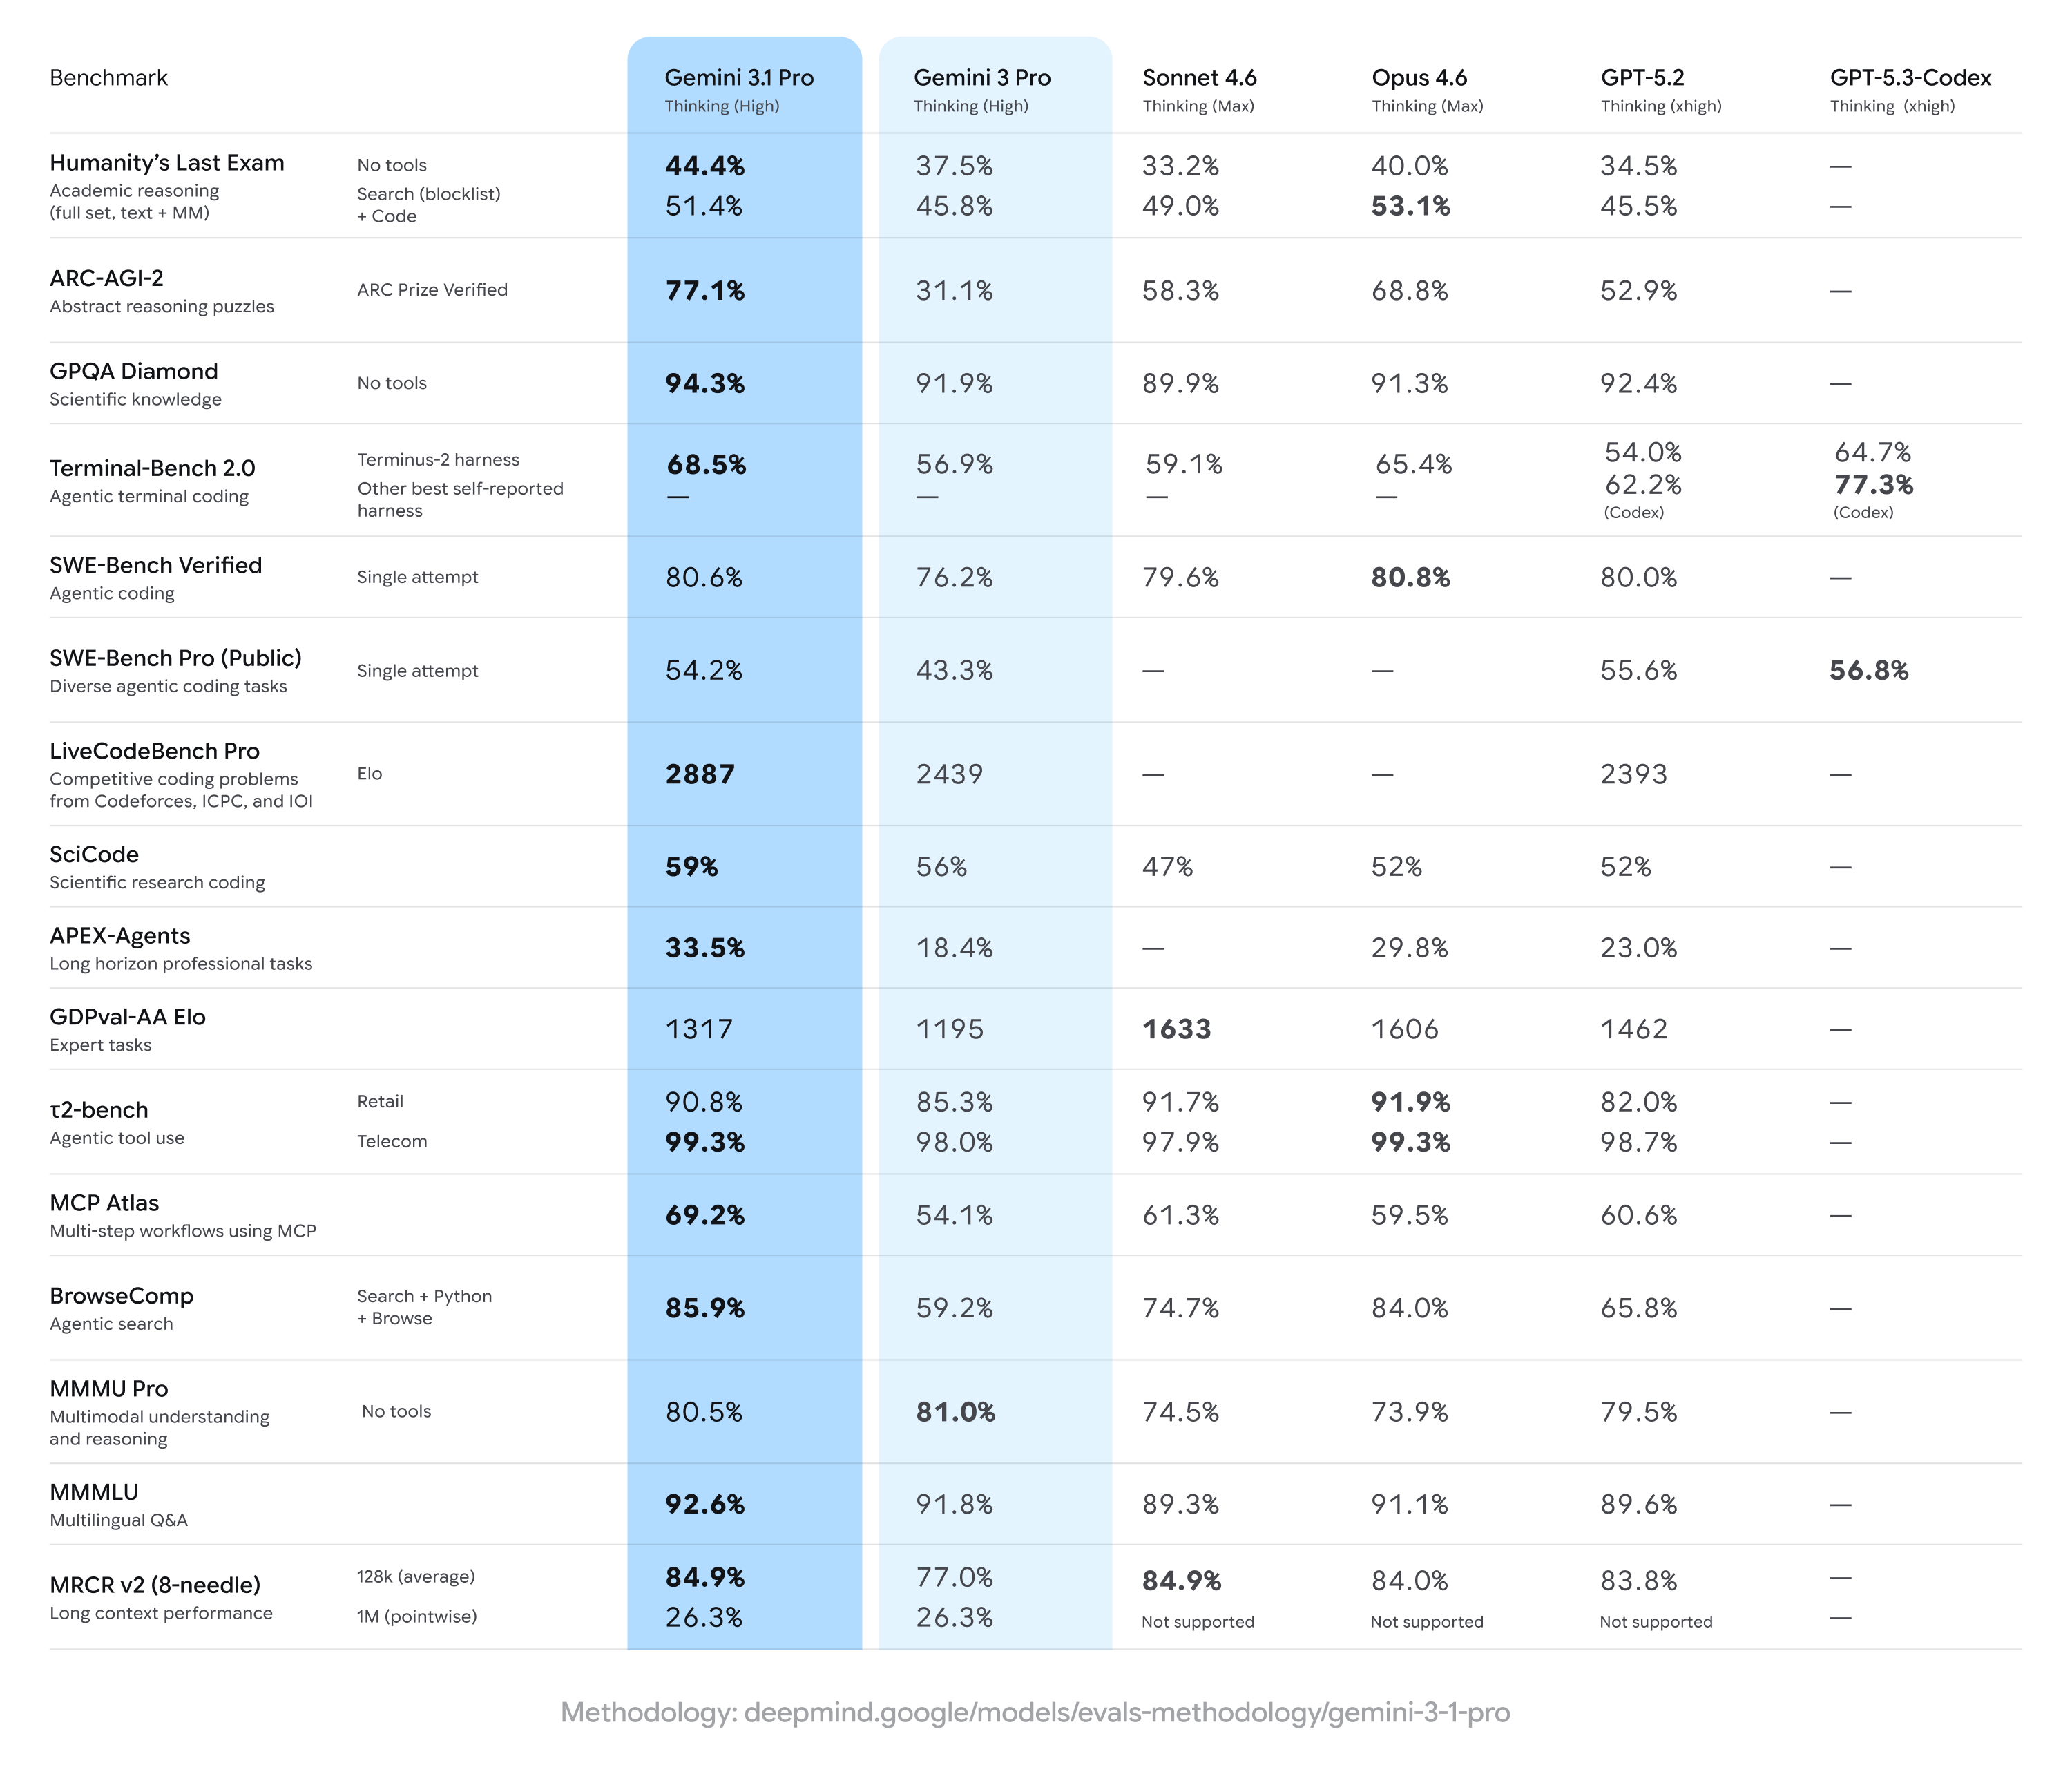
| Gemini 3.1 Pro19 Feb 2026 · Google | 77.1% | Gemini 3.1 Pro: A smarter model for your most complex tasksARC Prize Verified; Thinking (High)Source image | Not yet |
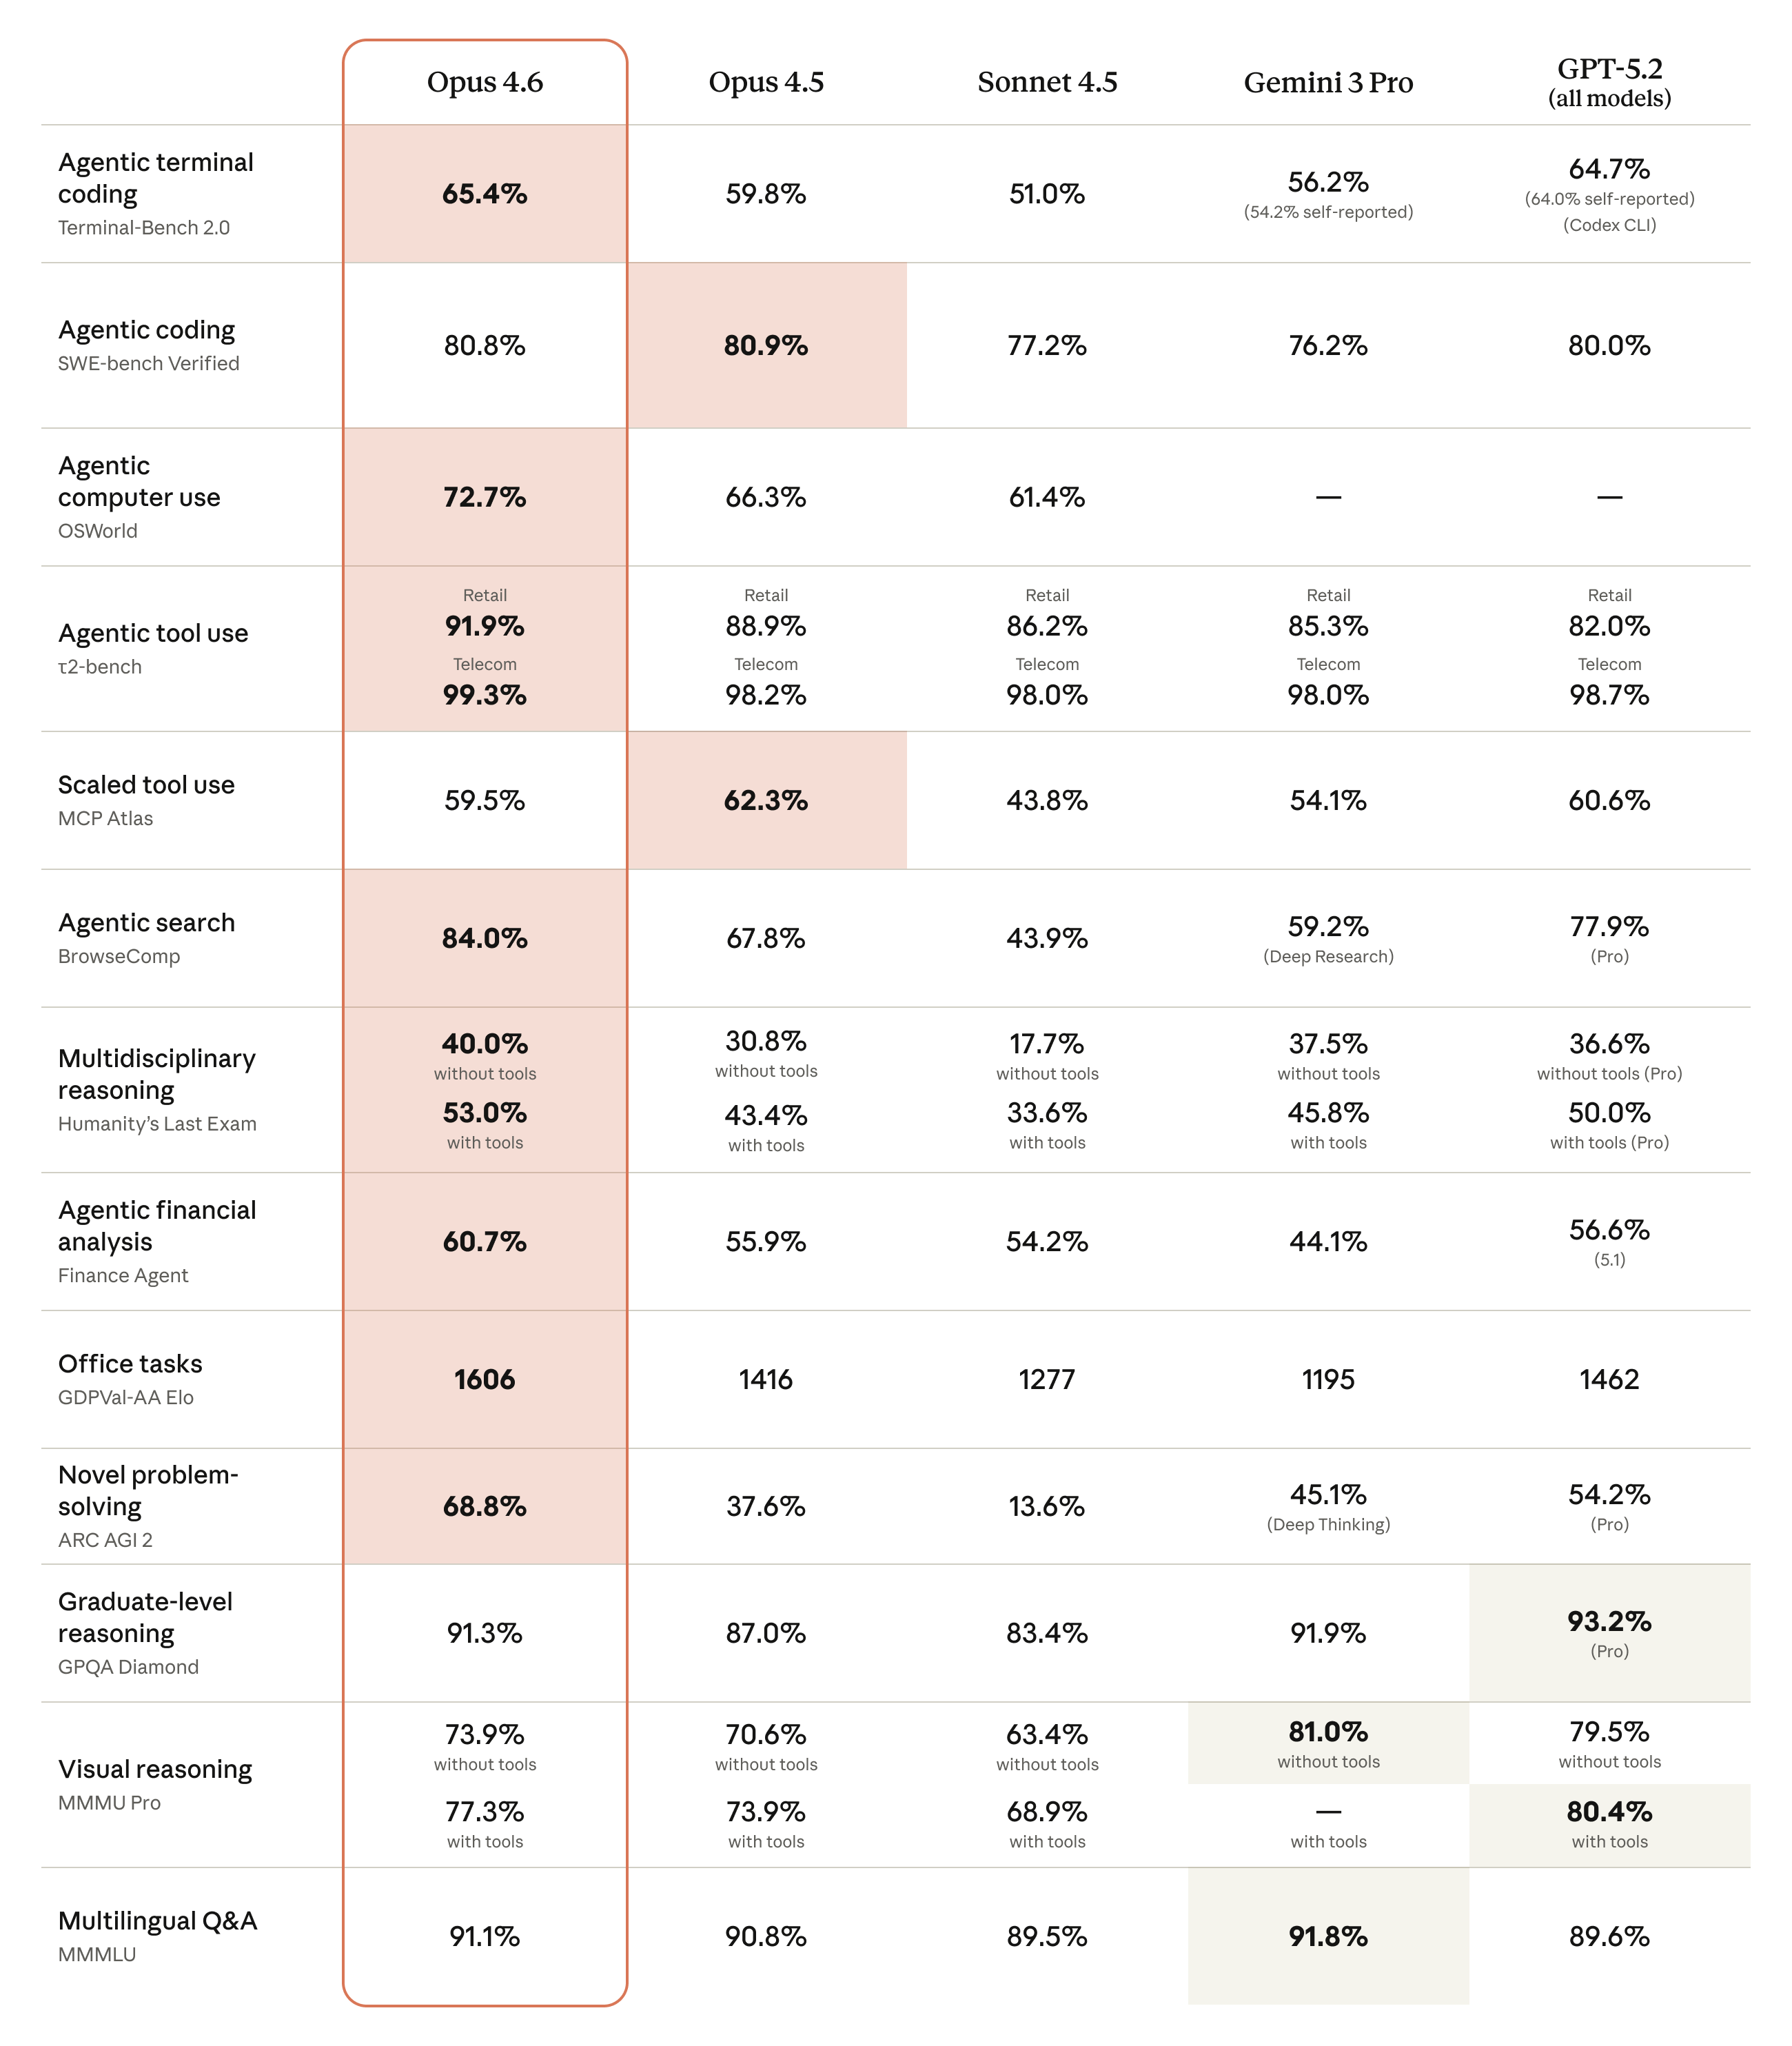
| Claude Opus 4.65 Feb 2026 · Anthropic | 68.8% | Claude Opus 4.6max effort and a 120k thinking budget (footnote)Source image | Not yet |
| Claude Opus 4.65 Feb 2026 · Anthropic | 69.17% | Claude Opus 4.6 System Cardanother report, not charted; as reported by the ARC Prize Foundation, 120k thinking tokens and high effort, private dataset | Not yet |
| GPT-5.211 Dec 2025 · OpenAI | 52.9% | Introducing GPT-5.2ARC-AGI-2 (Verified) | Not yet |
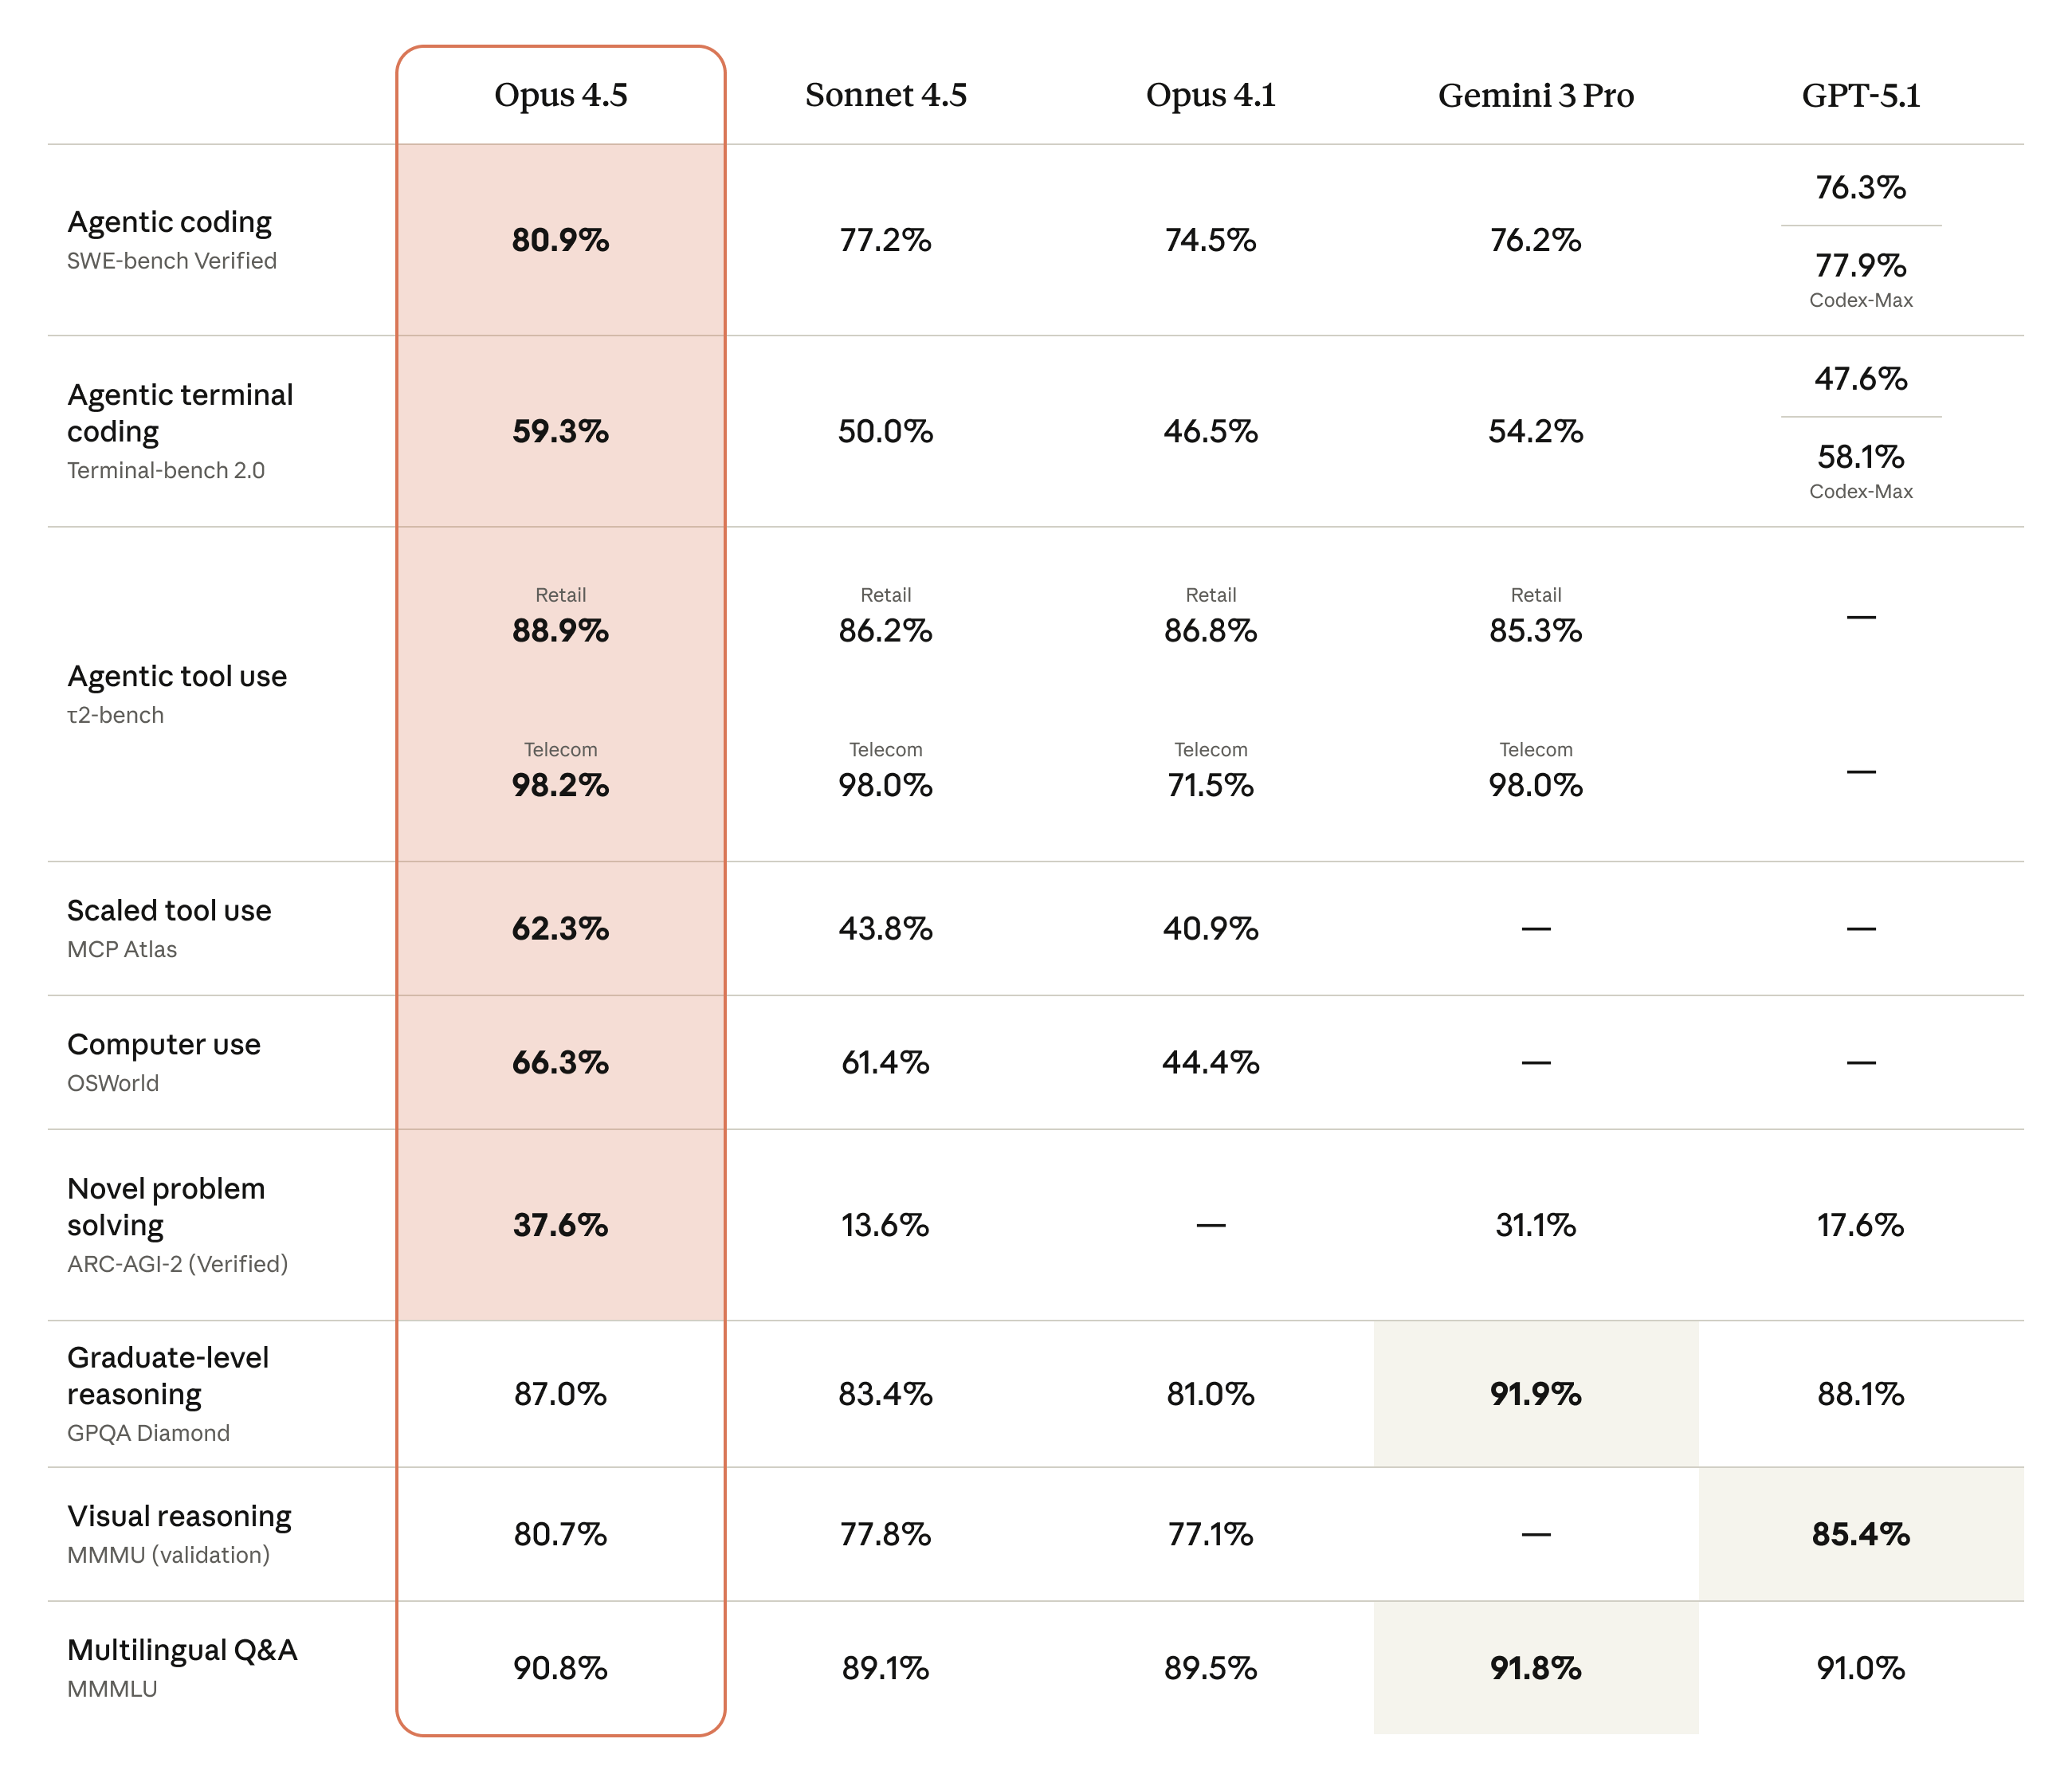
| Claude Opus 4.524 Nov 2025 · Anthropic | 37.6% | Introducing Claude Opus 4.564K thinking budget, default effort (high), averaged over 5 trials (methodology)Source image | Not yet |
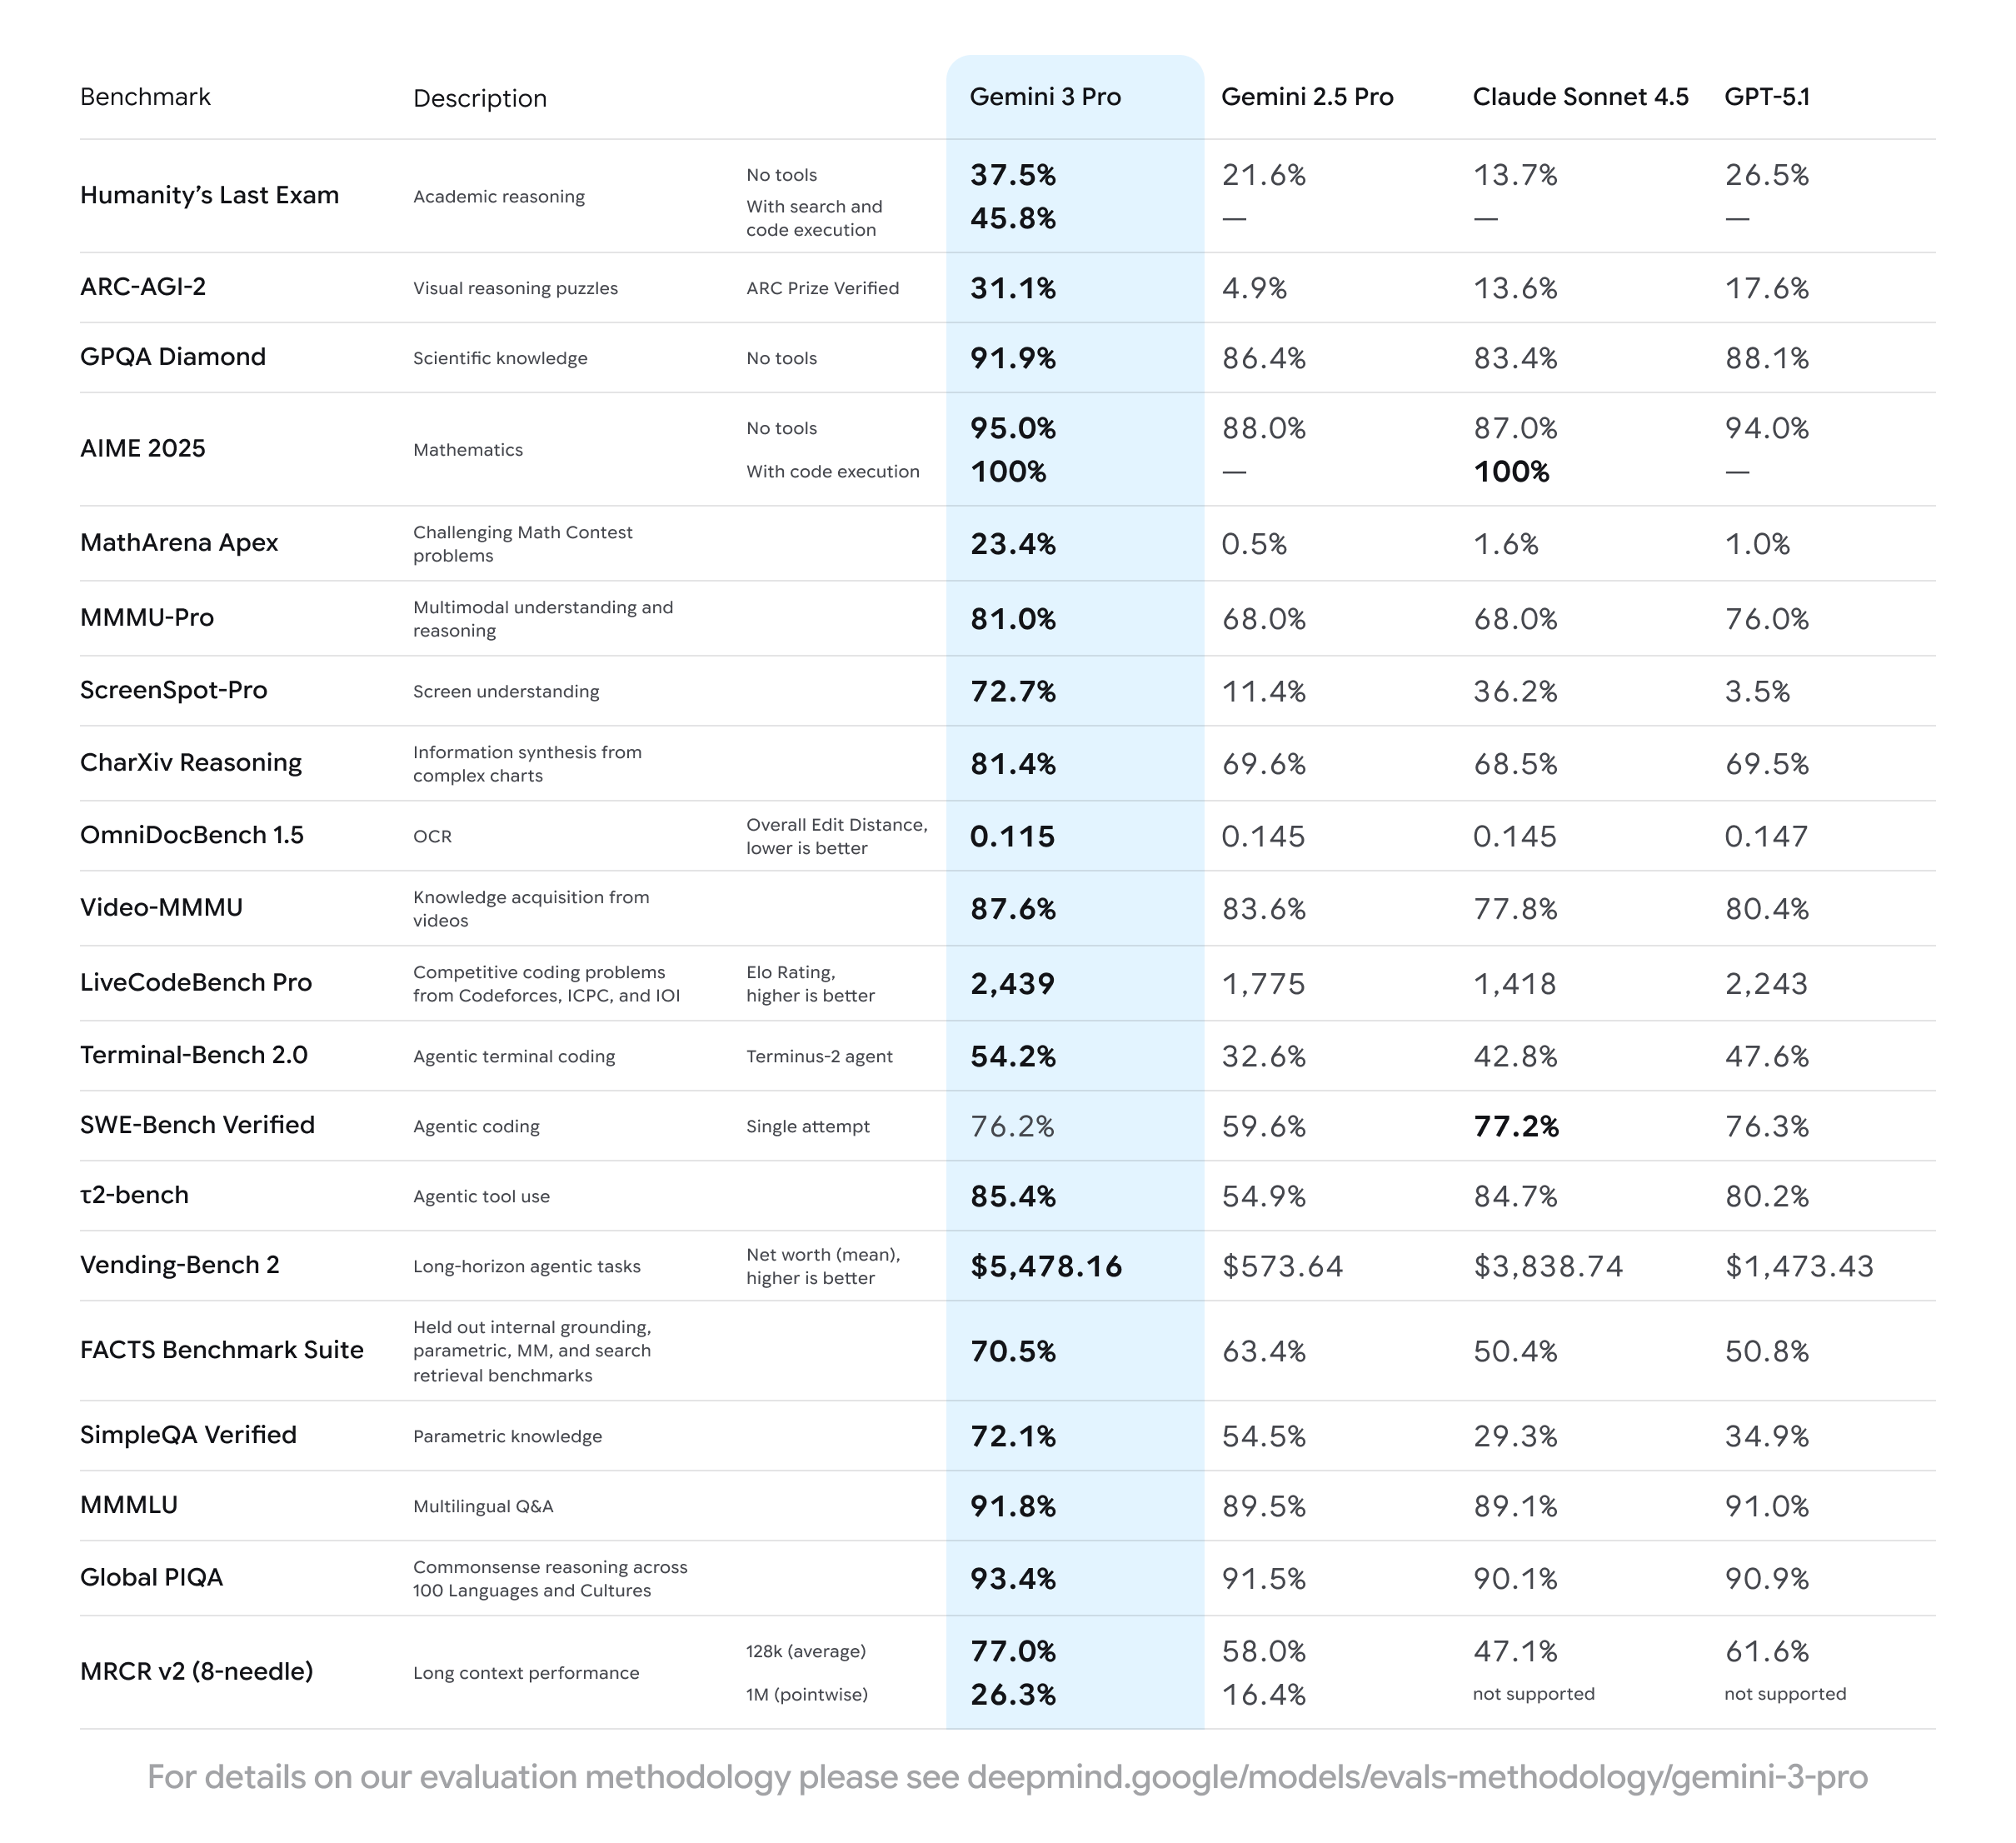
| Gemini 3 Pro18 Nov 2025 · Google | 31.1% | Start building with Gemini 3ARC Prize VerifiedSource image | Not yet |
| Claude Sonnet 4.529 Sep 2025 · Anthropic | 13.6% | Introducing Claude Opus 4.5reported laterSource image | Not yet |
Benchmark
arcprize.orgHigher is better