ARC-AGI-3
- OpenAI
- Anthropic
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| GPT-6 Astra3 Sep 2026 · OpenAI | 99.9% | GPT-6 Astra: A new generation of intelligenceCell prints '99.9% 1': footnote 1 marker dropped; footnote text not in the extracted page (text truncated). Same value in the intro: 'Astra also saturates ARC-AGI-3 with a 99.9% score'. The post also says Astra 'surpassed our human action-efficiency baseline on 96% of levels' (a different measure, not recorded). | Yes |
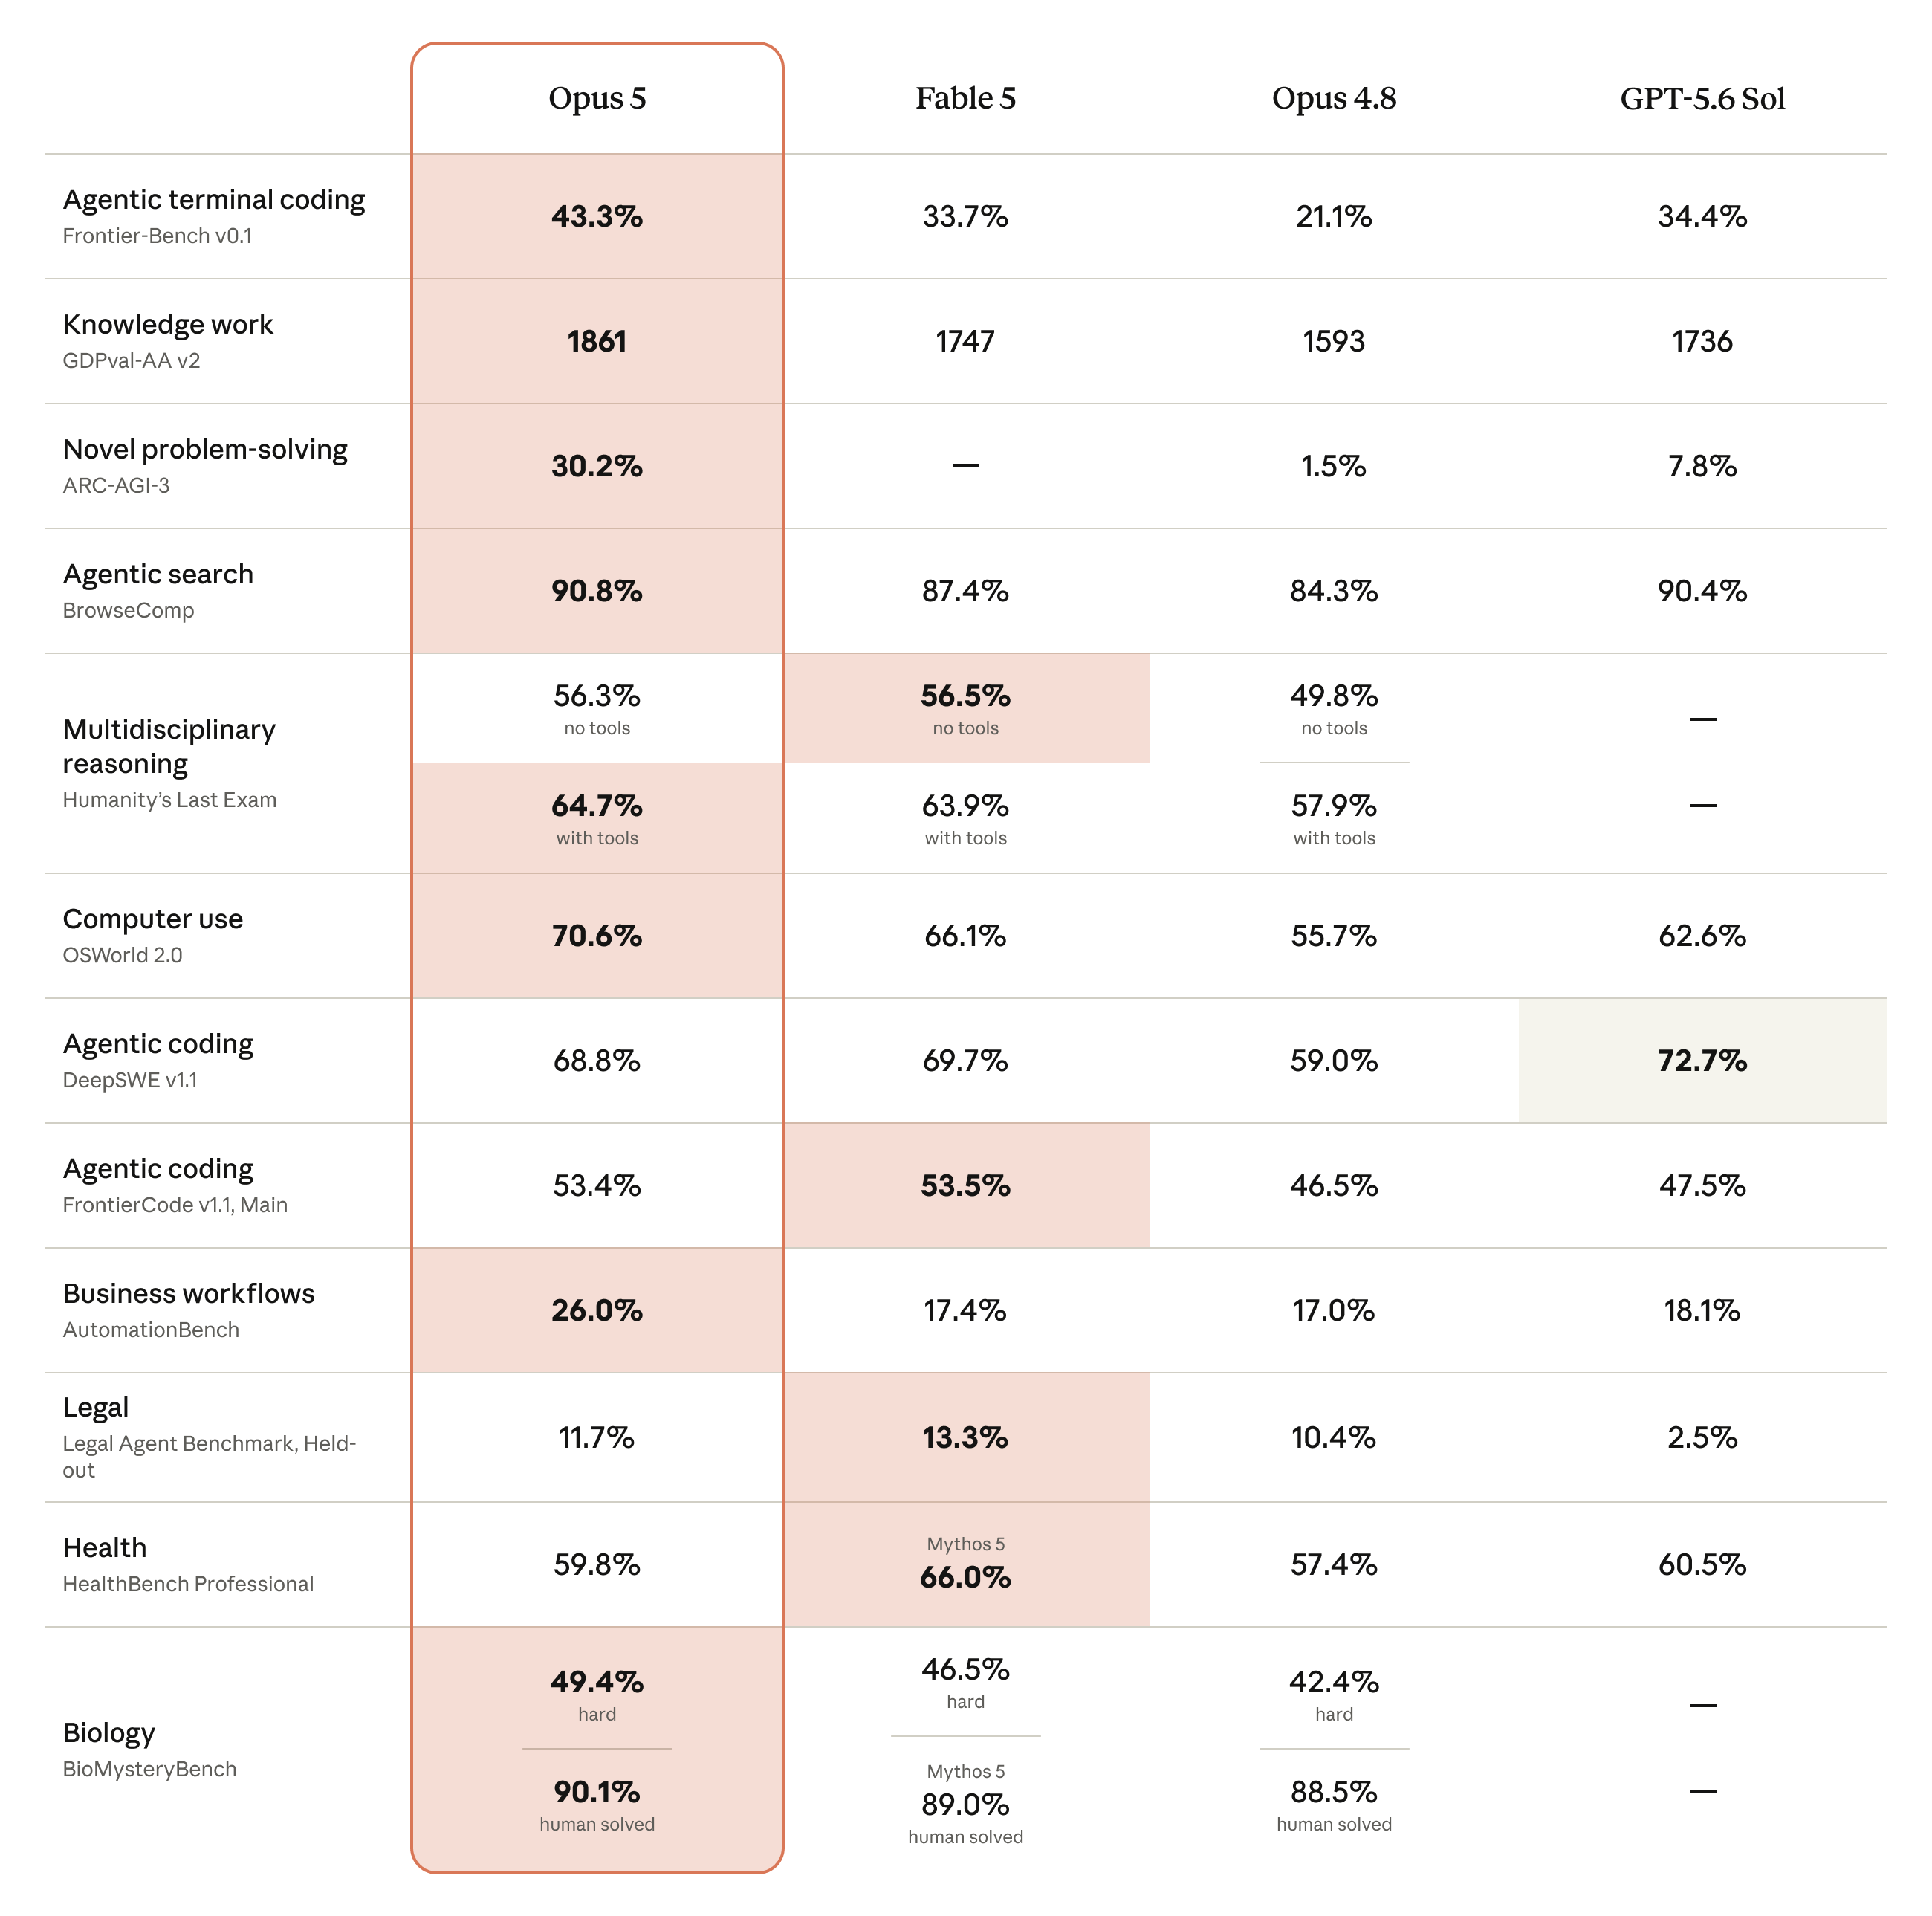
| Claude Opus 524 Jul 2026 · Anthropic | 30.2% | Introducing Claude Opus 5Effort not stated for the table; the 'Novel problem-solving by cost' chart (b5e071ba...png) labels the Opus 5 point 'Opus 5 (high)' with no value. Text: 'Opus 5's score is three times as high as the next-best model'.Source image | Yes |
| GPT-5.6 Sol9 Jul 2026 · OpenAI | 7.78% | GPT-5.6: Frontier intelligence that scales with your ambitionRow carries footnote 7 (superscript dropped); the footnote's text is not in the extracted page (text truncated). The later GPT-6 Astra post prints 7.8% for GPT-5.6 Sol (a later report). | Yes |
Benchmark
arcprize.orgHigher is better
ARC Prize FoundationIntroduced 25 Mar 2026