Muse Spark
- Made by
- Meta
- Released
- Announced in
- Introducing Muse Spark: Scaling Towards Personal Superintelligenceai.meta.com
- Event
- Muse Spark
- API record
- /api/v1/models/muse-spark
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
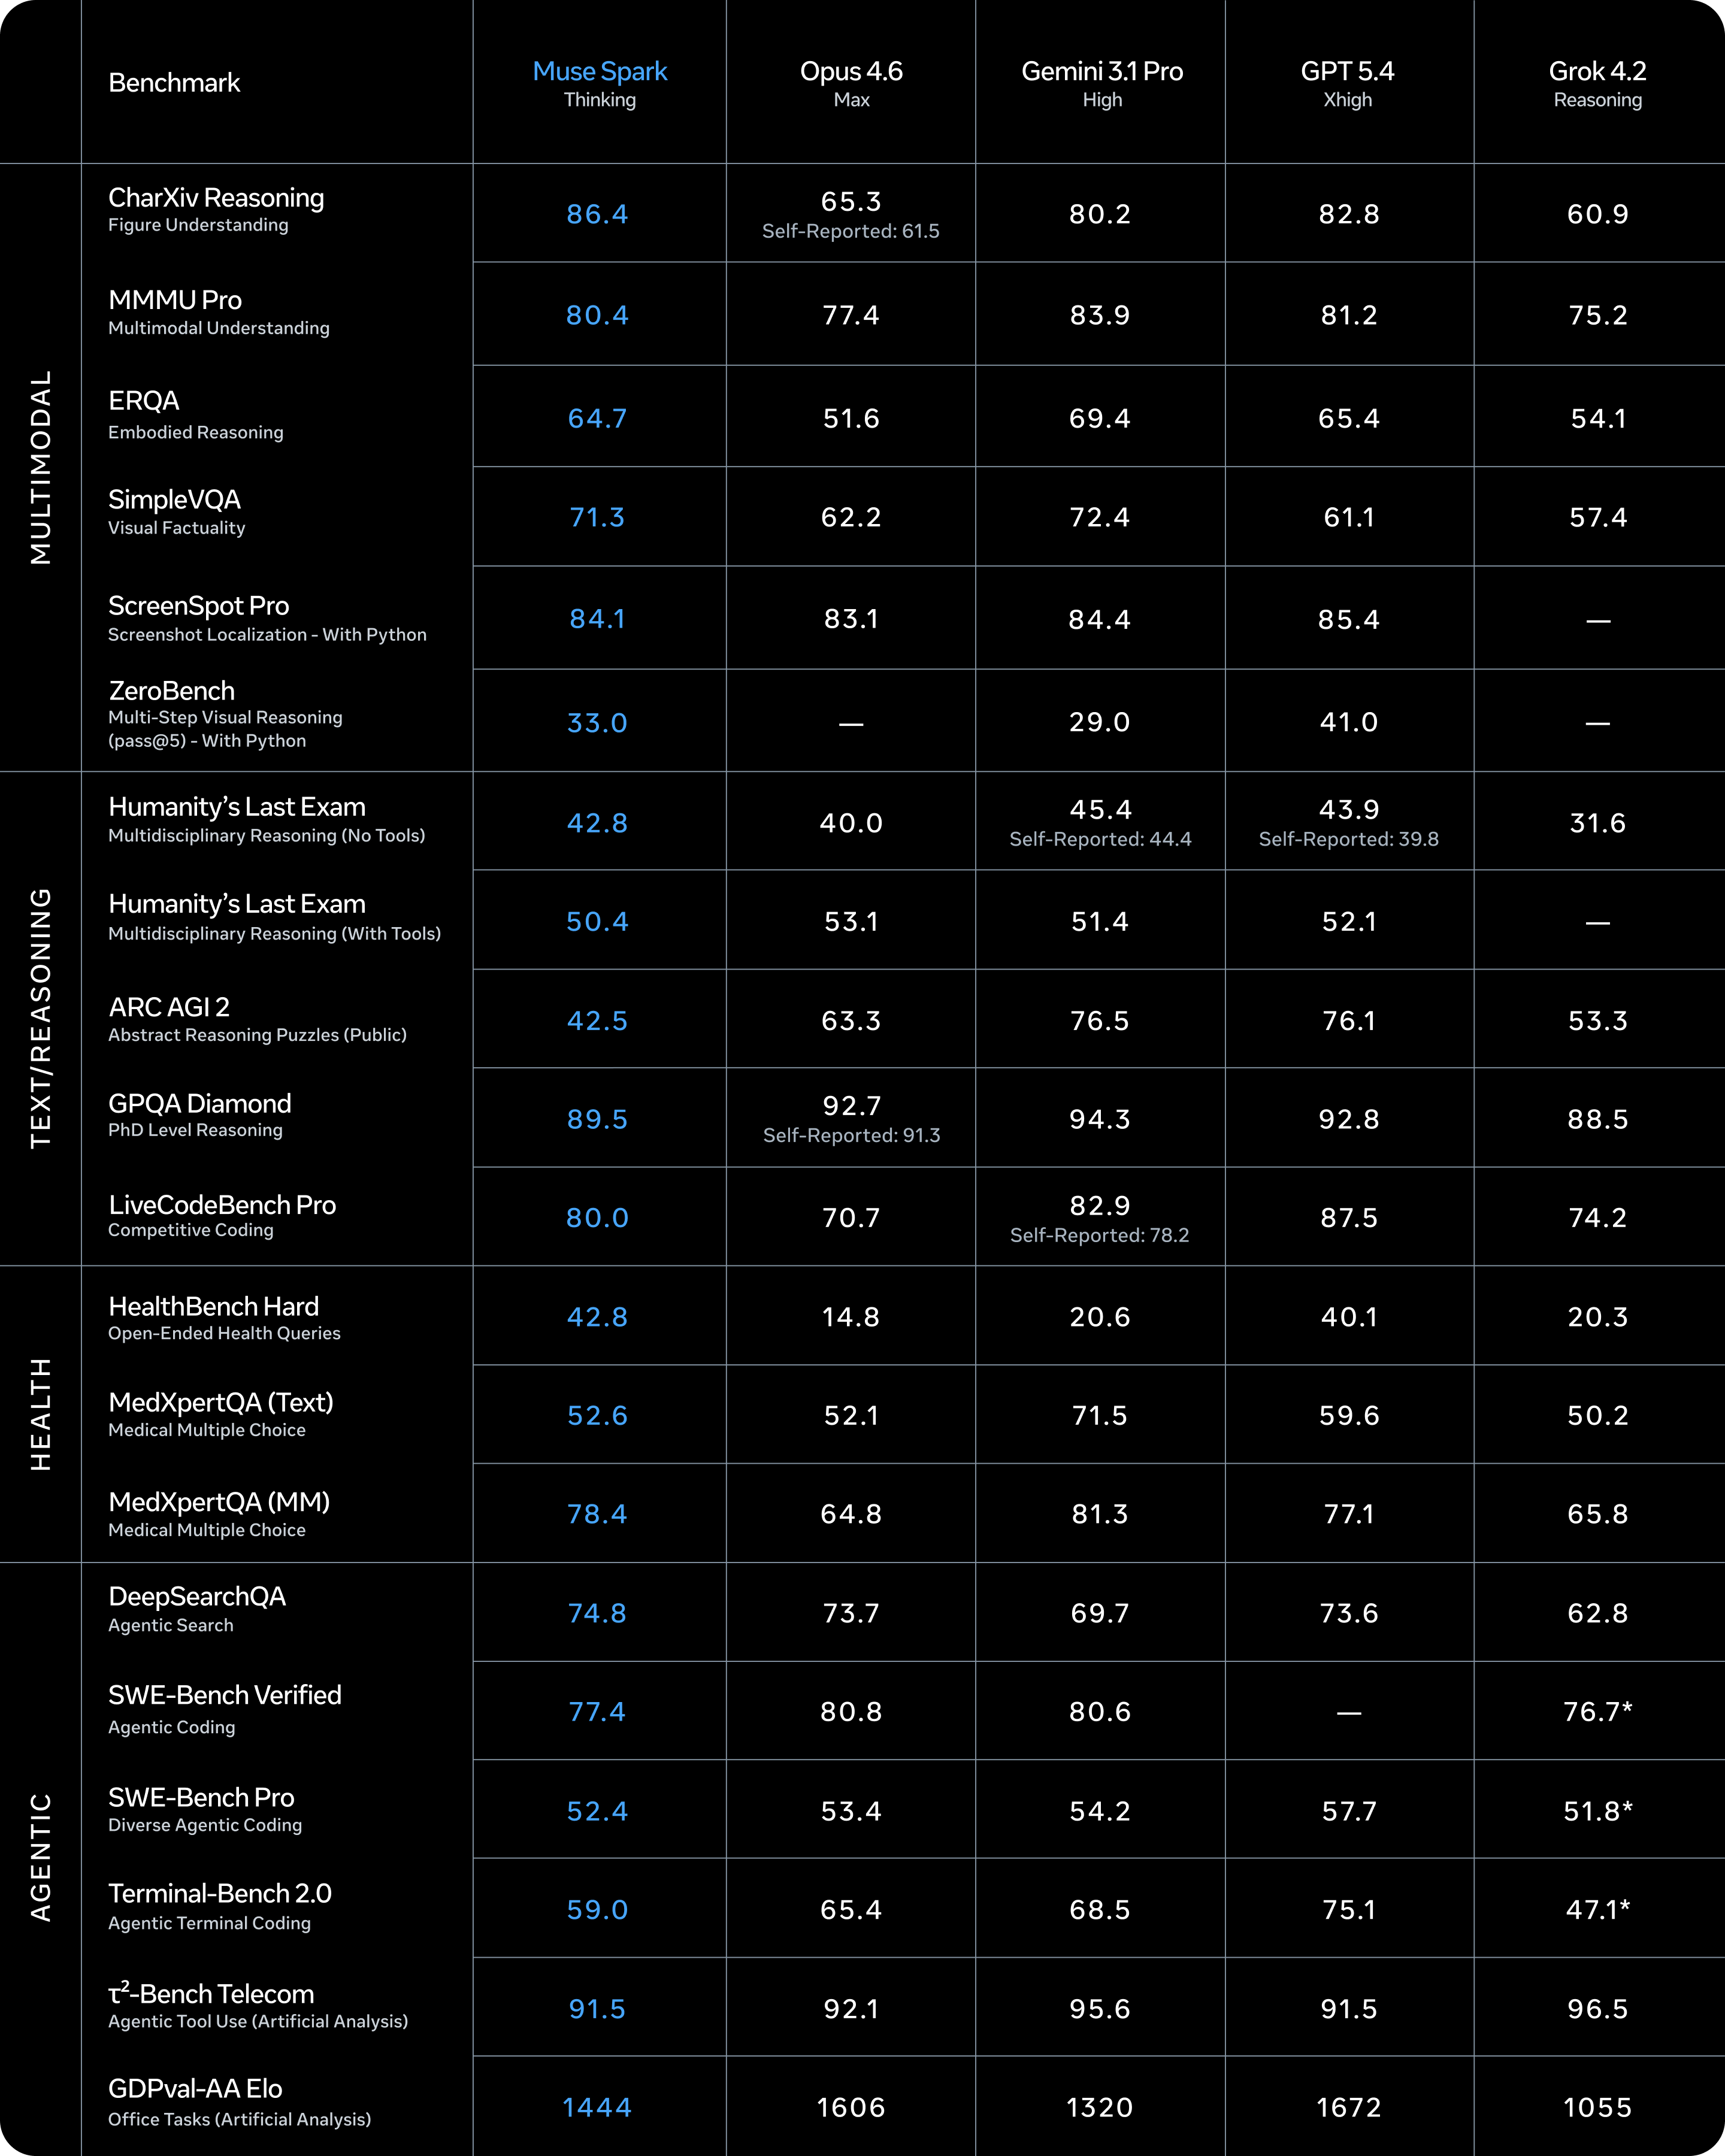
| Humanity's Last ExamNo tools · thinking mode; full 2,500-question set | 42.8% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| contemplating mode: multiple agents reasoning in parallel, refined and aggregated · parallel test-time compute | 50.2% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Humanity's Last ExamWith tools · thinking mode; bash and browser tools | 50.4% | |
| contemplating mode: multiple agents reasoning in parallel; bash and browser tools · parallel test-time compute | 58.4% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Verifiedthinking mode; bash and file-edit tools; averaged over 15 attempts; tests fixed in 5 tasks | 77.4% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Prothinking mode; public set; bash and file-edit tools; averaged over 4 attempts | 52.4% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
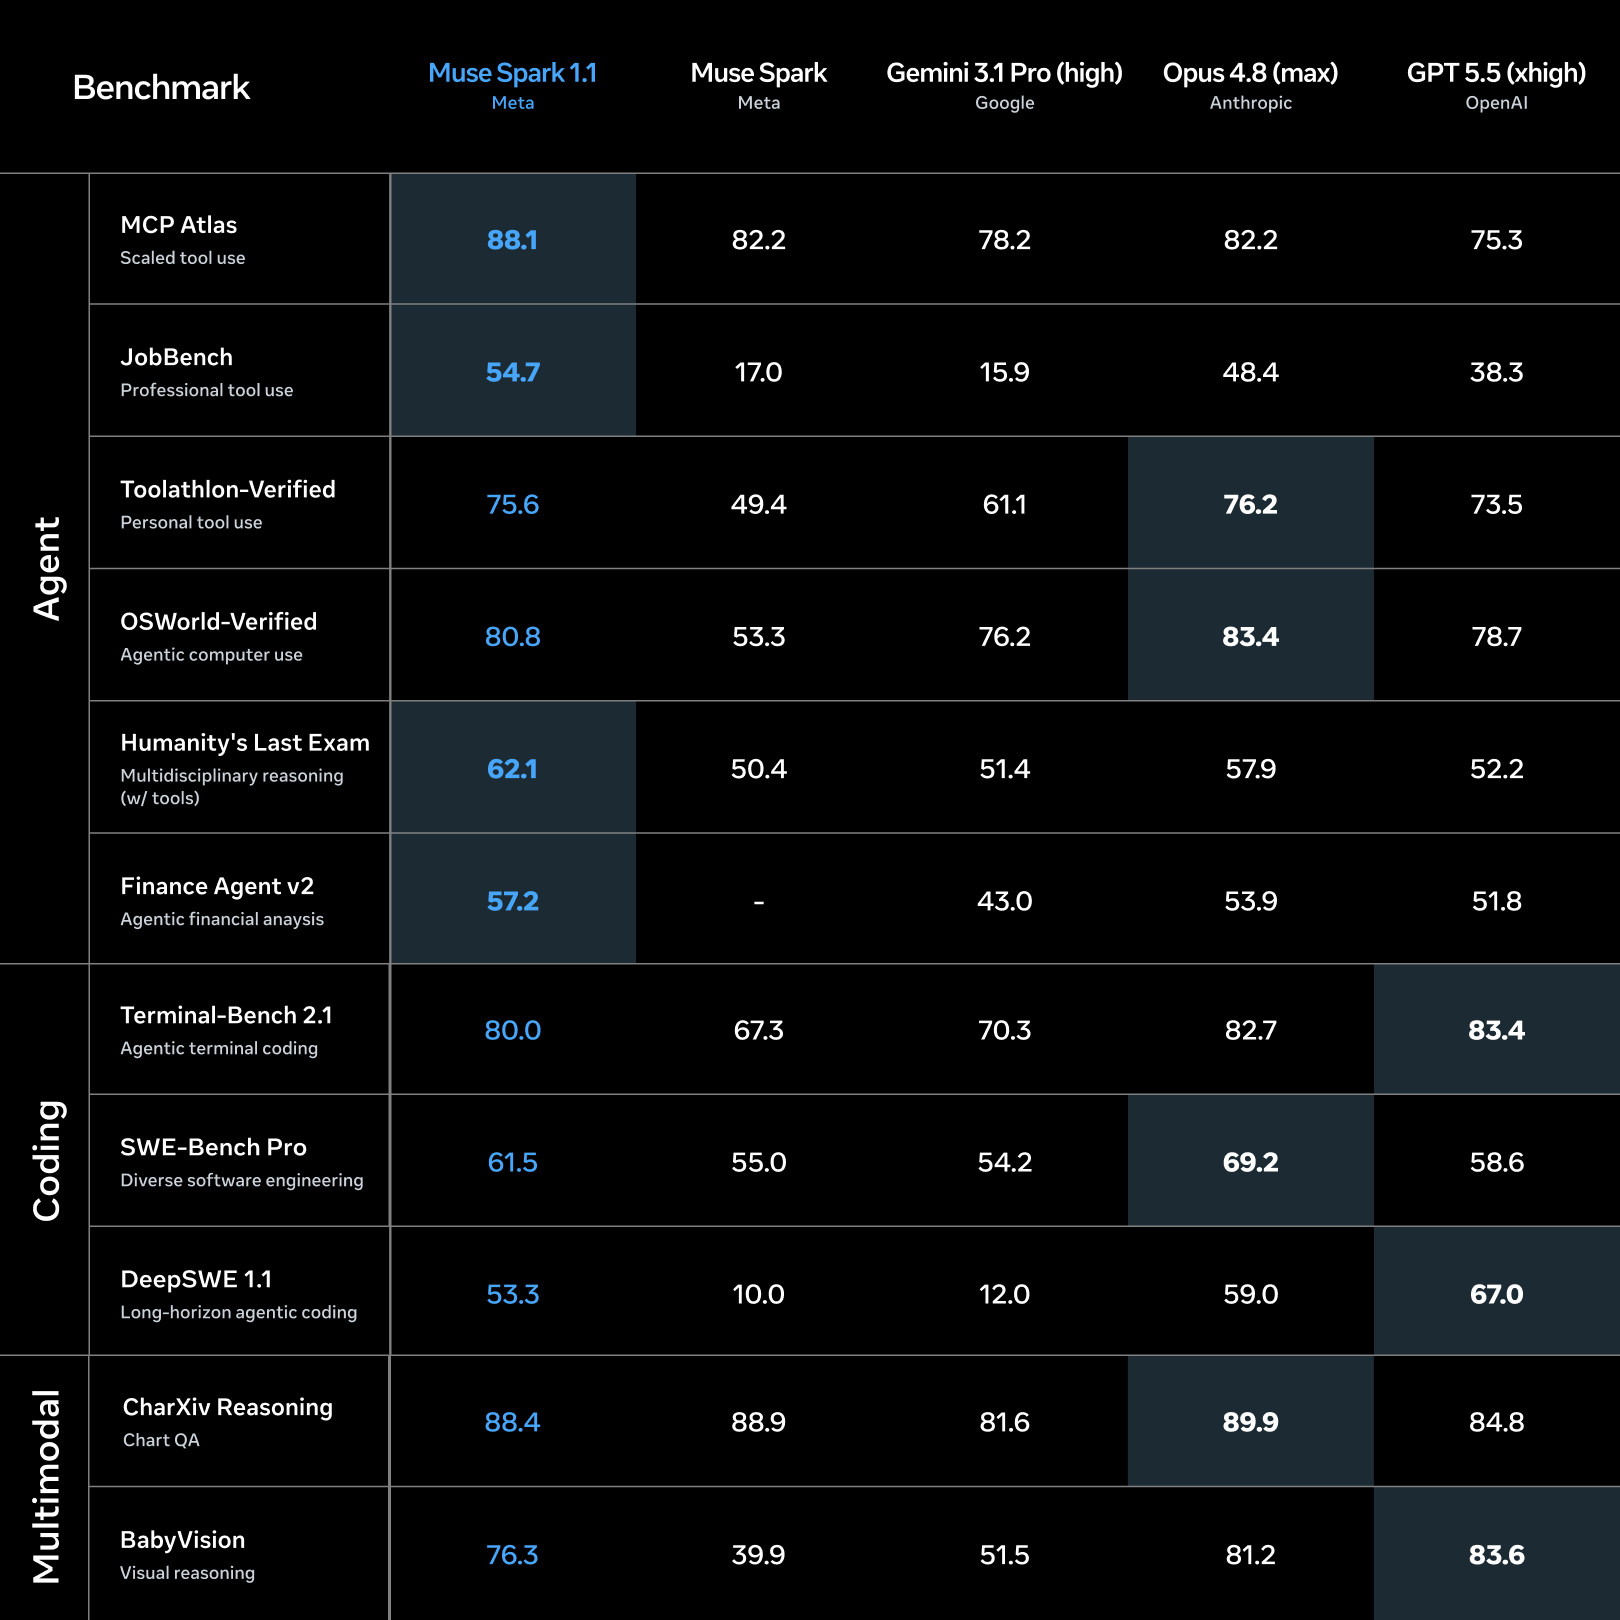
| reported later, in Introducing Muse Spark 1.1 | 55.0% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| GPQA Diamondthinking mode; averaged over 4 runs | 89.5% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| ARC-AGI-2thinking mode; public set | 42.5% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 2.0thinking mode; bash-only harness; averaged over 15 attempts; one task test script fixed | 59.0% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| DeepSWE v1.1reported later, in Introducing Muse Spark 1.1 | 10.0% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| Terminal-Bench 2.1reported later, in Introducing Muse Spark 1.1 | 67.3% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| OSWorld-Verifiedreported later, in Introducing Muse Spark 1.1 | 53.3% | CorroboratedThe same number is printed in 1 other lab document: 1 |
| MCP Atlasrun by Scale AI · reported later, in Introducing Muse Spark 1.1 | 82.2% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by Meta
- Introducing Muse Spark: Scaling Towards Personal Superintelligenceai.meta.com · 8 Apr 2026
Original image 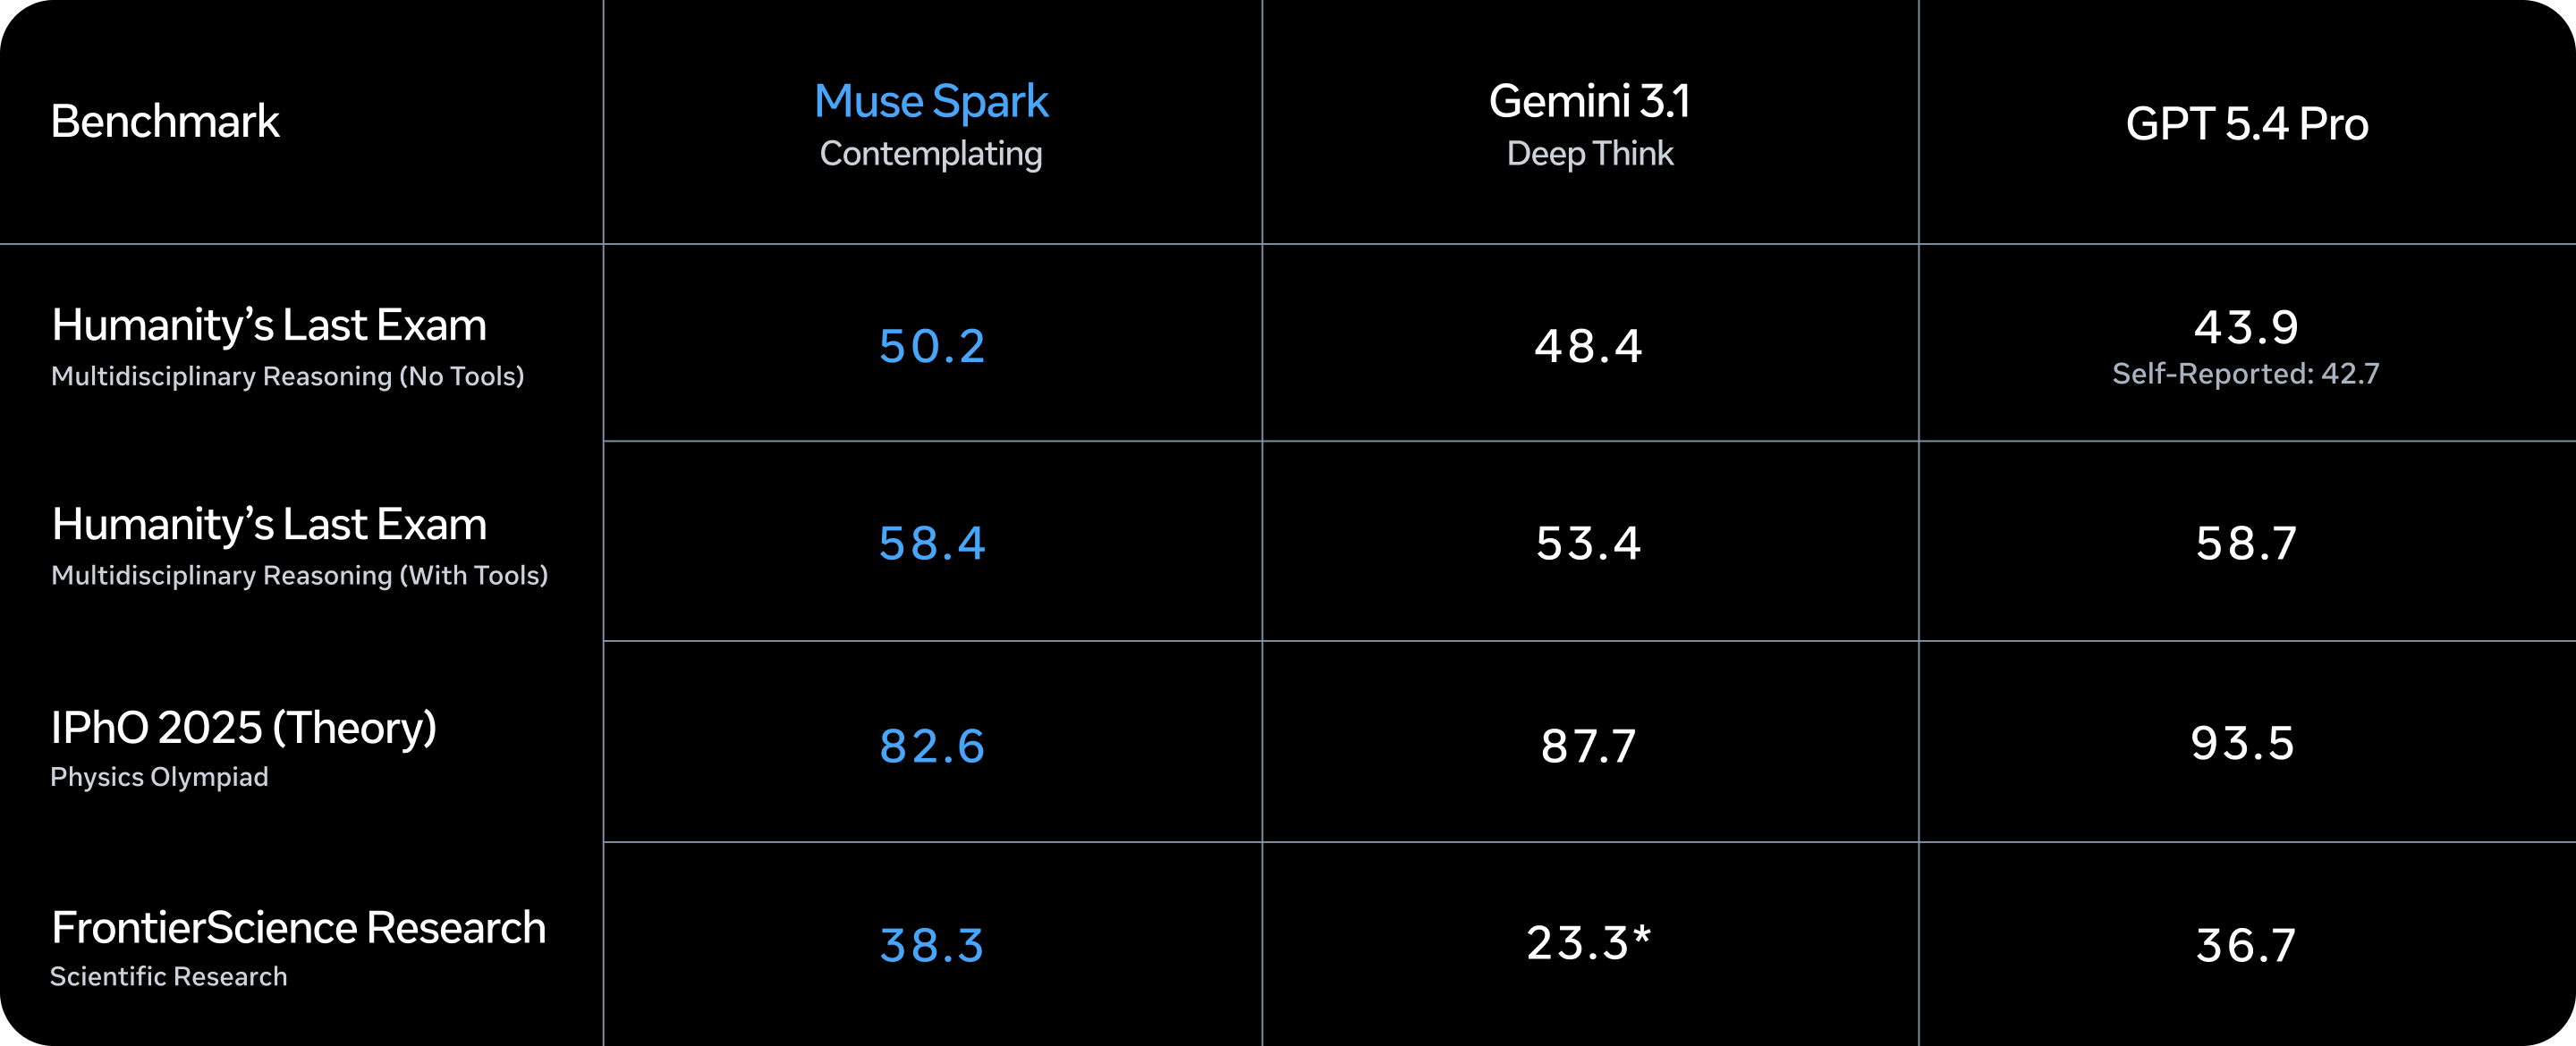
Original image - Introducing Muse Spark 1.1ai.meta.com · 9 Jul 2026
Original image

