OSWorld-Verified
- OpenAI
- Anthropic
- Alibaba
Results
| Model | Score | Source | Human-verified |
|---|---|---|---|
| Qwen3.8-Max3 Aug 2026 · Alibaba | 86.1% | Qwen3.8-Max: A New Bar for Coding and CoworkNo harness footnote for this row. | Yes |
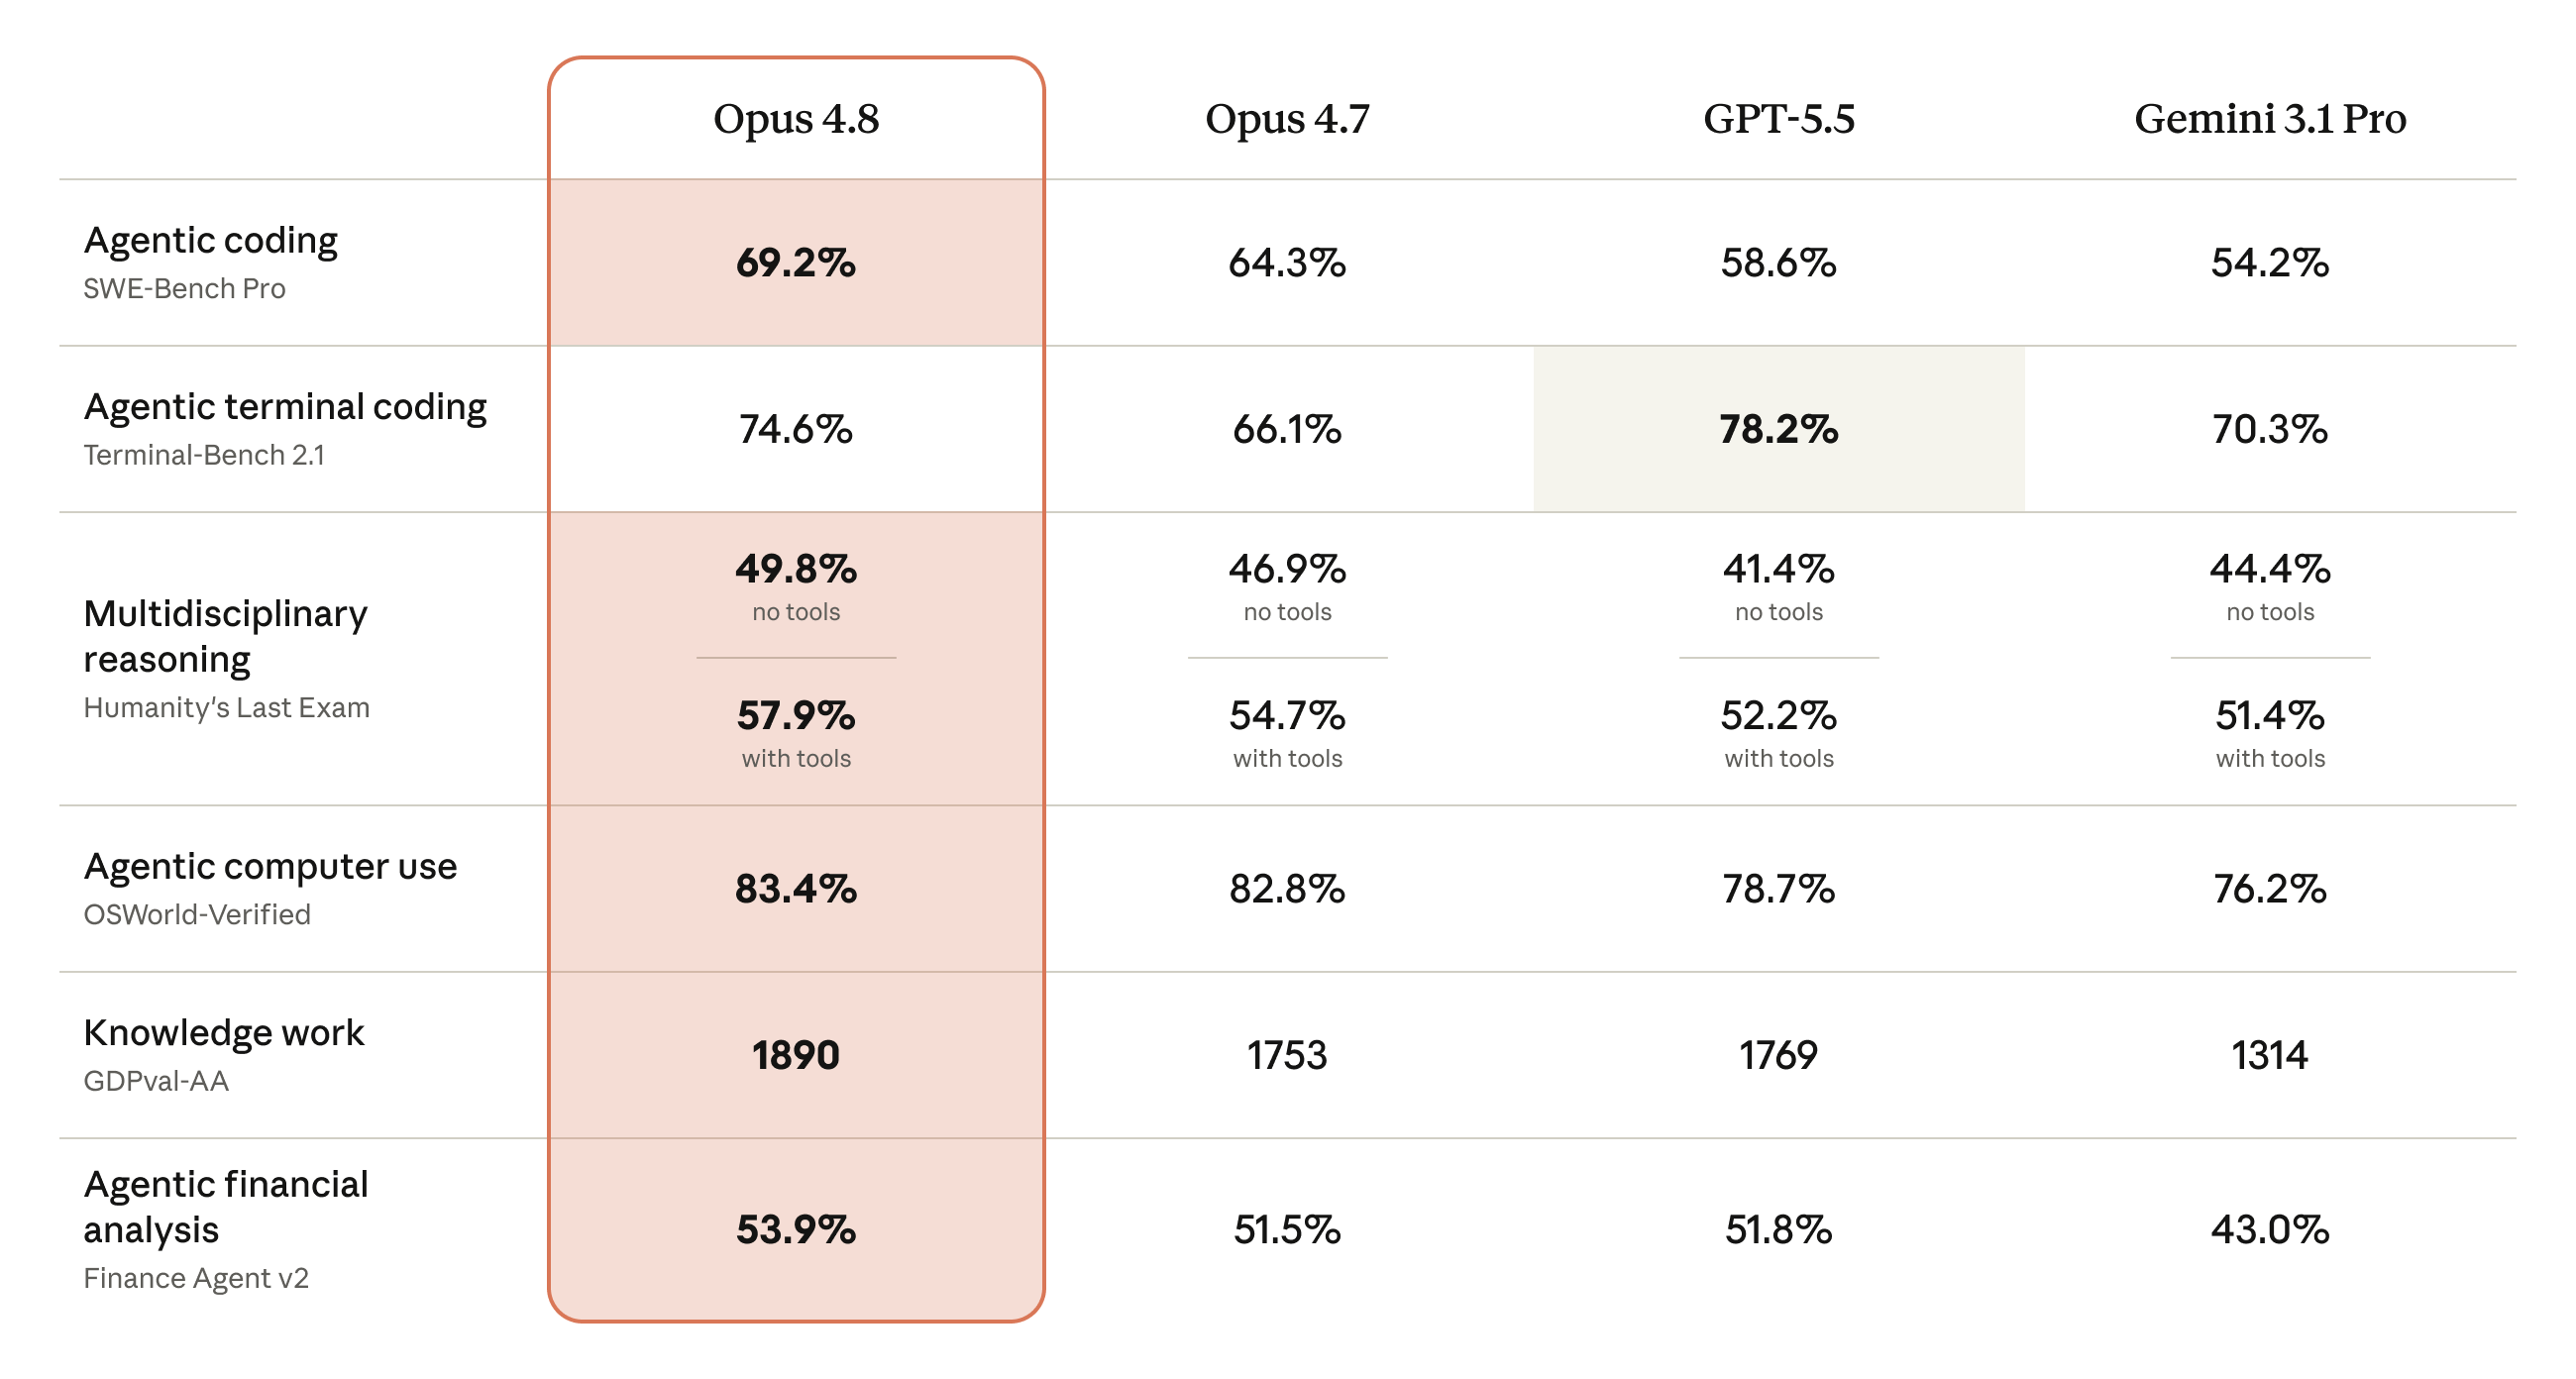
| Claude Opus 4.828 May 2026 · Anthropic | 83.4% | Introducing Claude Opus 4.8Footnote: Anthropic changed how it runs OSWorld-Verified (details in the system card); scores may not be comparable with earlier Anthropic OSWorld-Verified numbers.Source image | Yes |
| GPT-5.523 Apr 2026 · OpenAI | 78.7% | Introducing GPT-5.5Repeated in the computer-use detail table and in the text ('which measures whether a model can operate real computer environments on its own, it reaches 78.7%'). The fetched page text was truncated, so footnotes without a % sign are not visible in the extract. | Yes |
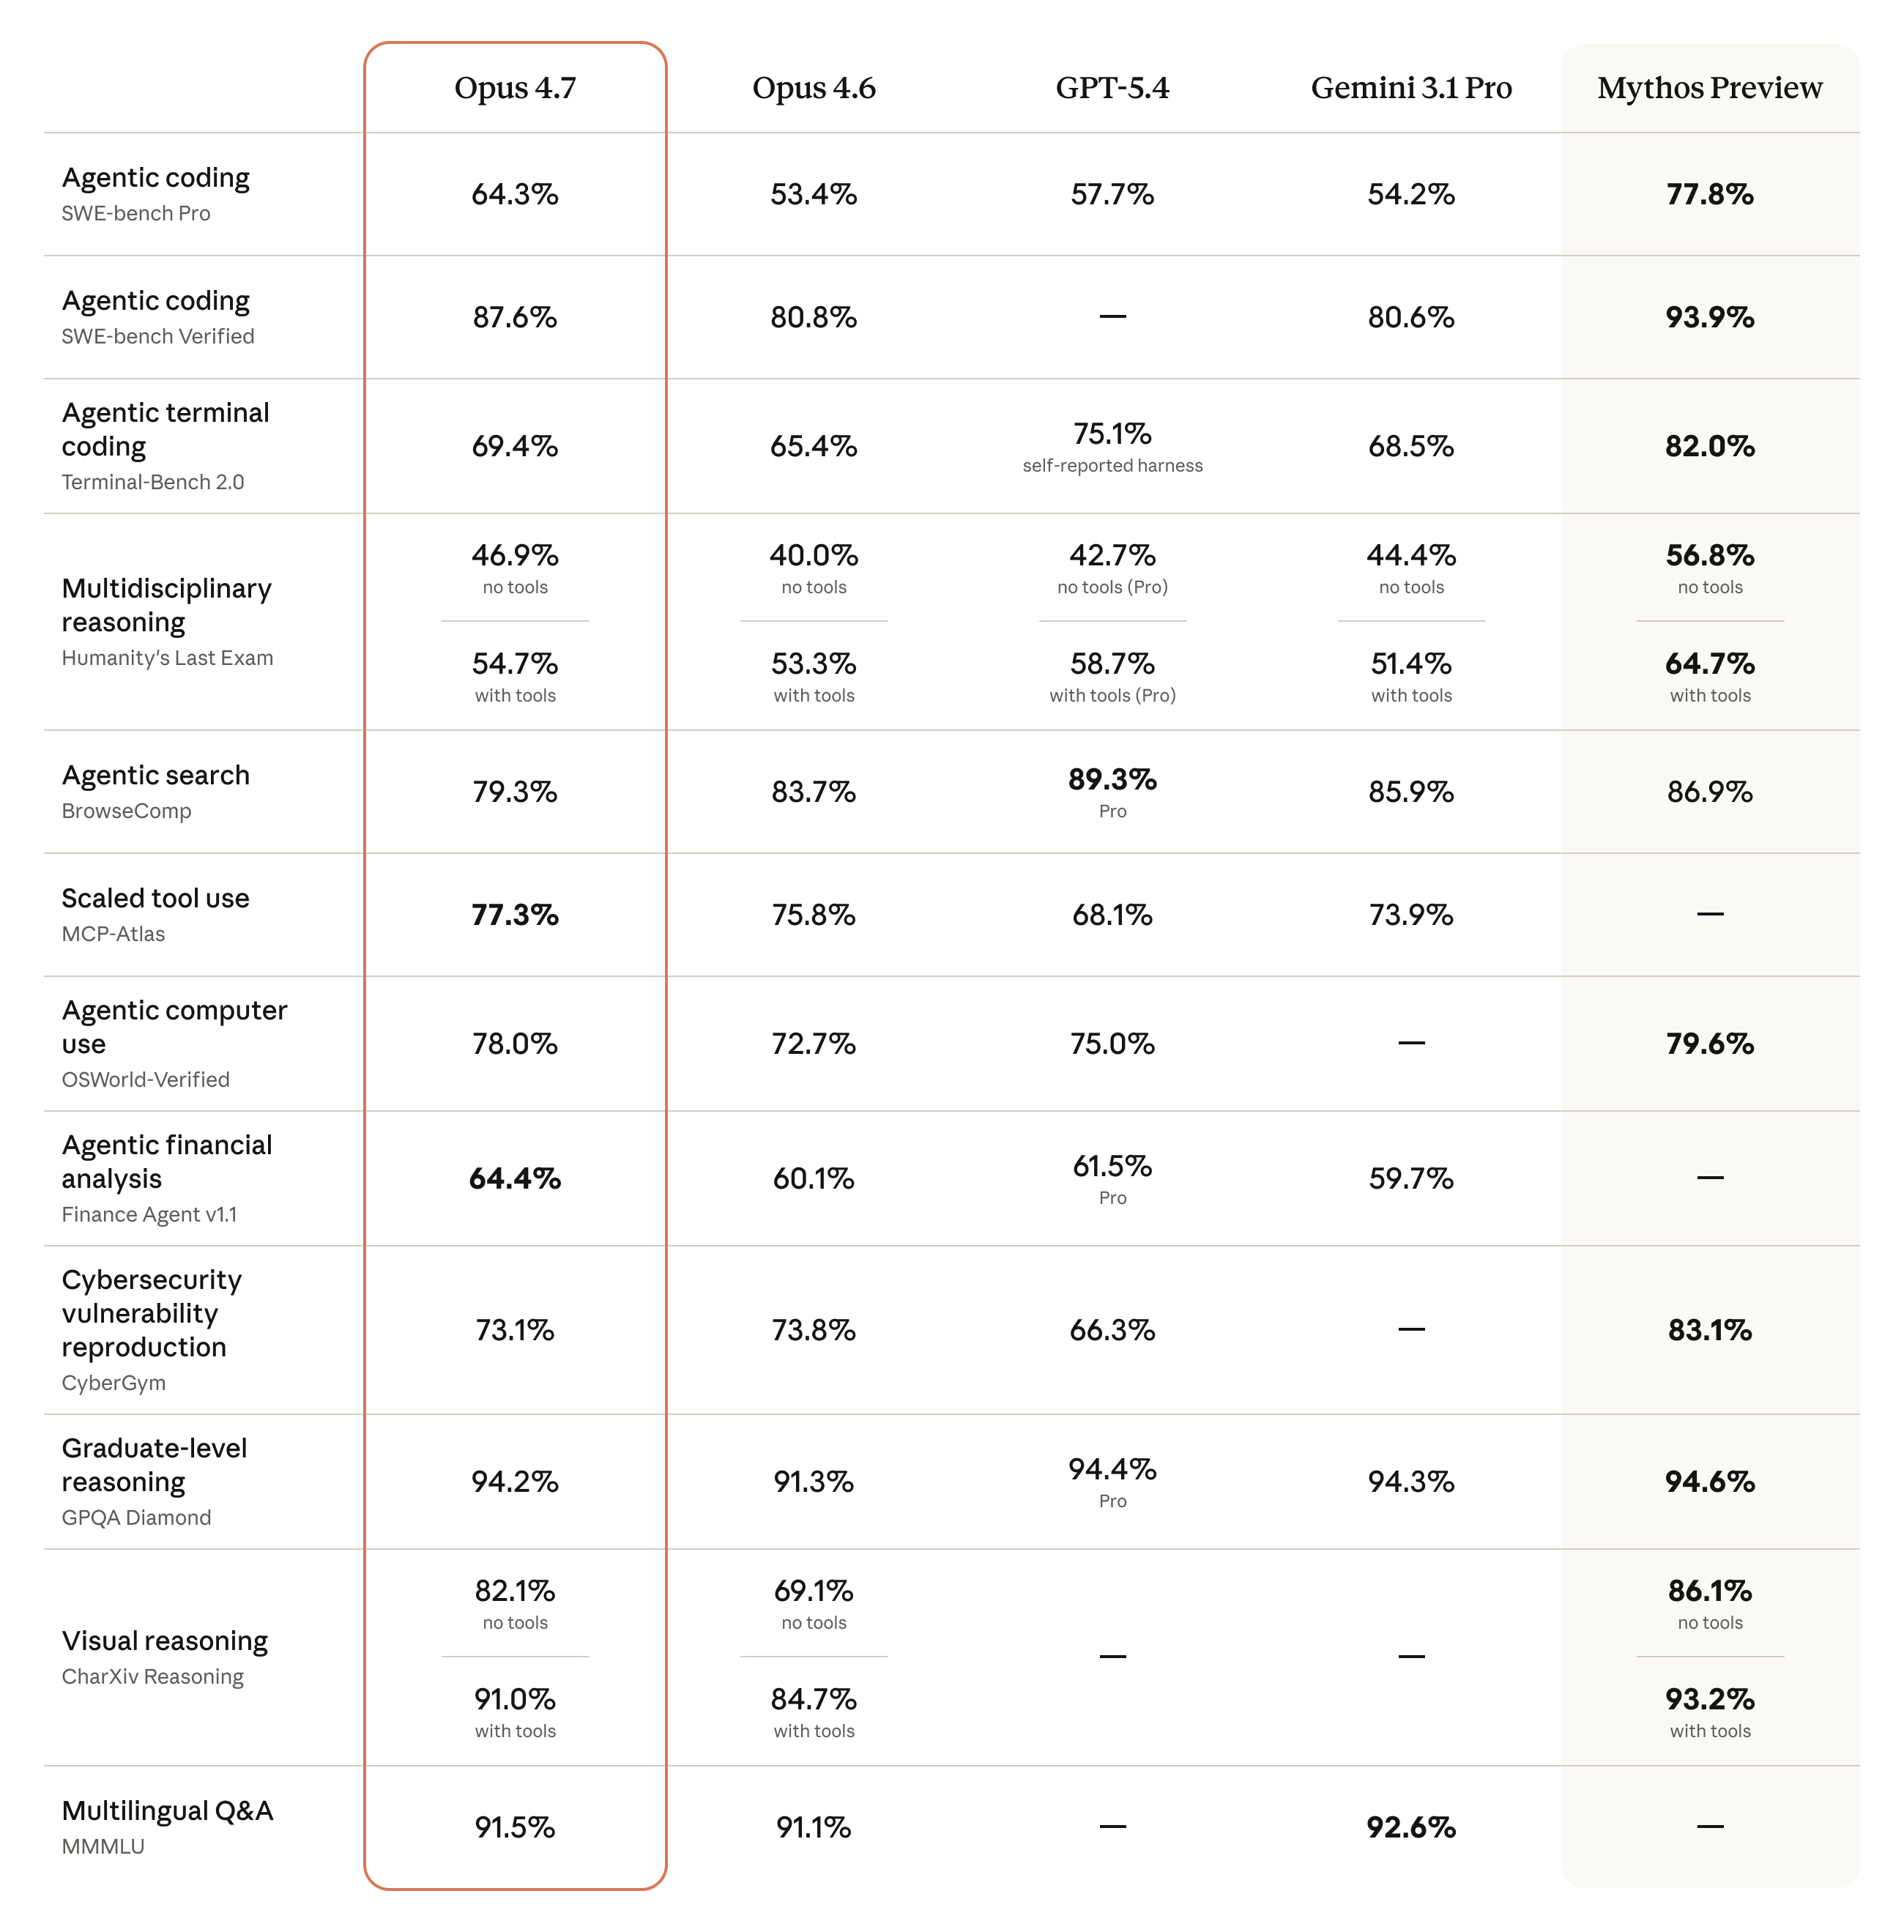
| Claude Opus 4.716 Apr 2026 · Anthropic | 78.0% | Introducing Claude Opus 4.7No harness or effort note for OSWorld in the footnotes. Later report: the Opus 4.8 post's footnote says the OSWorld-Verified method changed and restates Opus 4.7 at 82.3% (its table prints 82.8% for Opus 4.7); not recorded here.Source image | Yes |
| GPT-5.45 Mar 2026 · OpenAI | 75.0% | Introducing GPT-5.4Repeated in the computer-use/vision detail table (row 'OSWorld-Verified', column 'GPT‑5.4'). The '*' footnote on that row belongs to GPT-5.3-Codex's 74.0%. The fetched page text was truncated, so footnotes without a % sign are not visible in the extract. | Yes |
Benchmark
osworld-v1.xlang.aiHigher is better
XLANG LabIntroduced 28 Jul 2025