Kimi K2.5
- Made by
- Moonshot AI
- Released
- Announced in
- Kimi K2.5: Visual Agentic Intelligencekimi.ai
- Event
- Kimi K2.5
- API record
- /api/v1/models/kimi-k2-5
Benchmark results
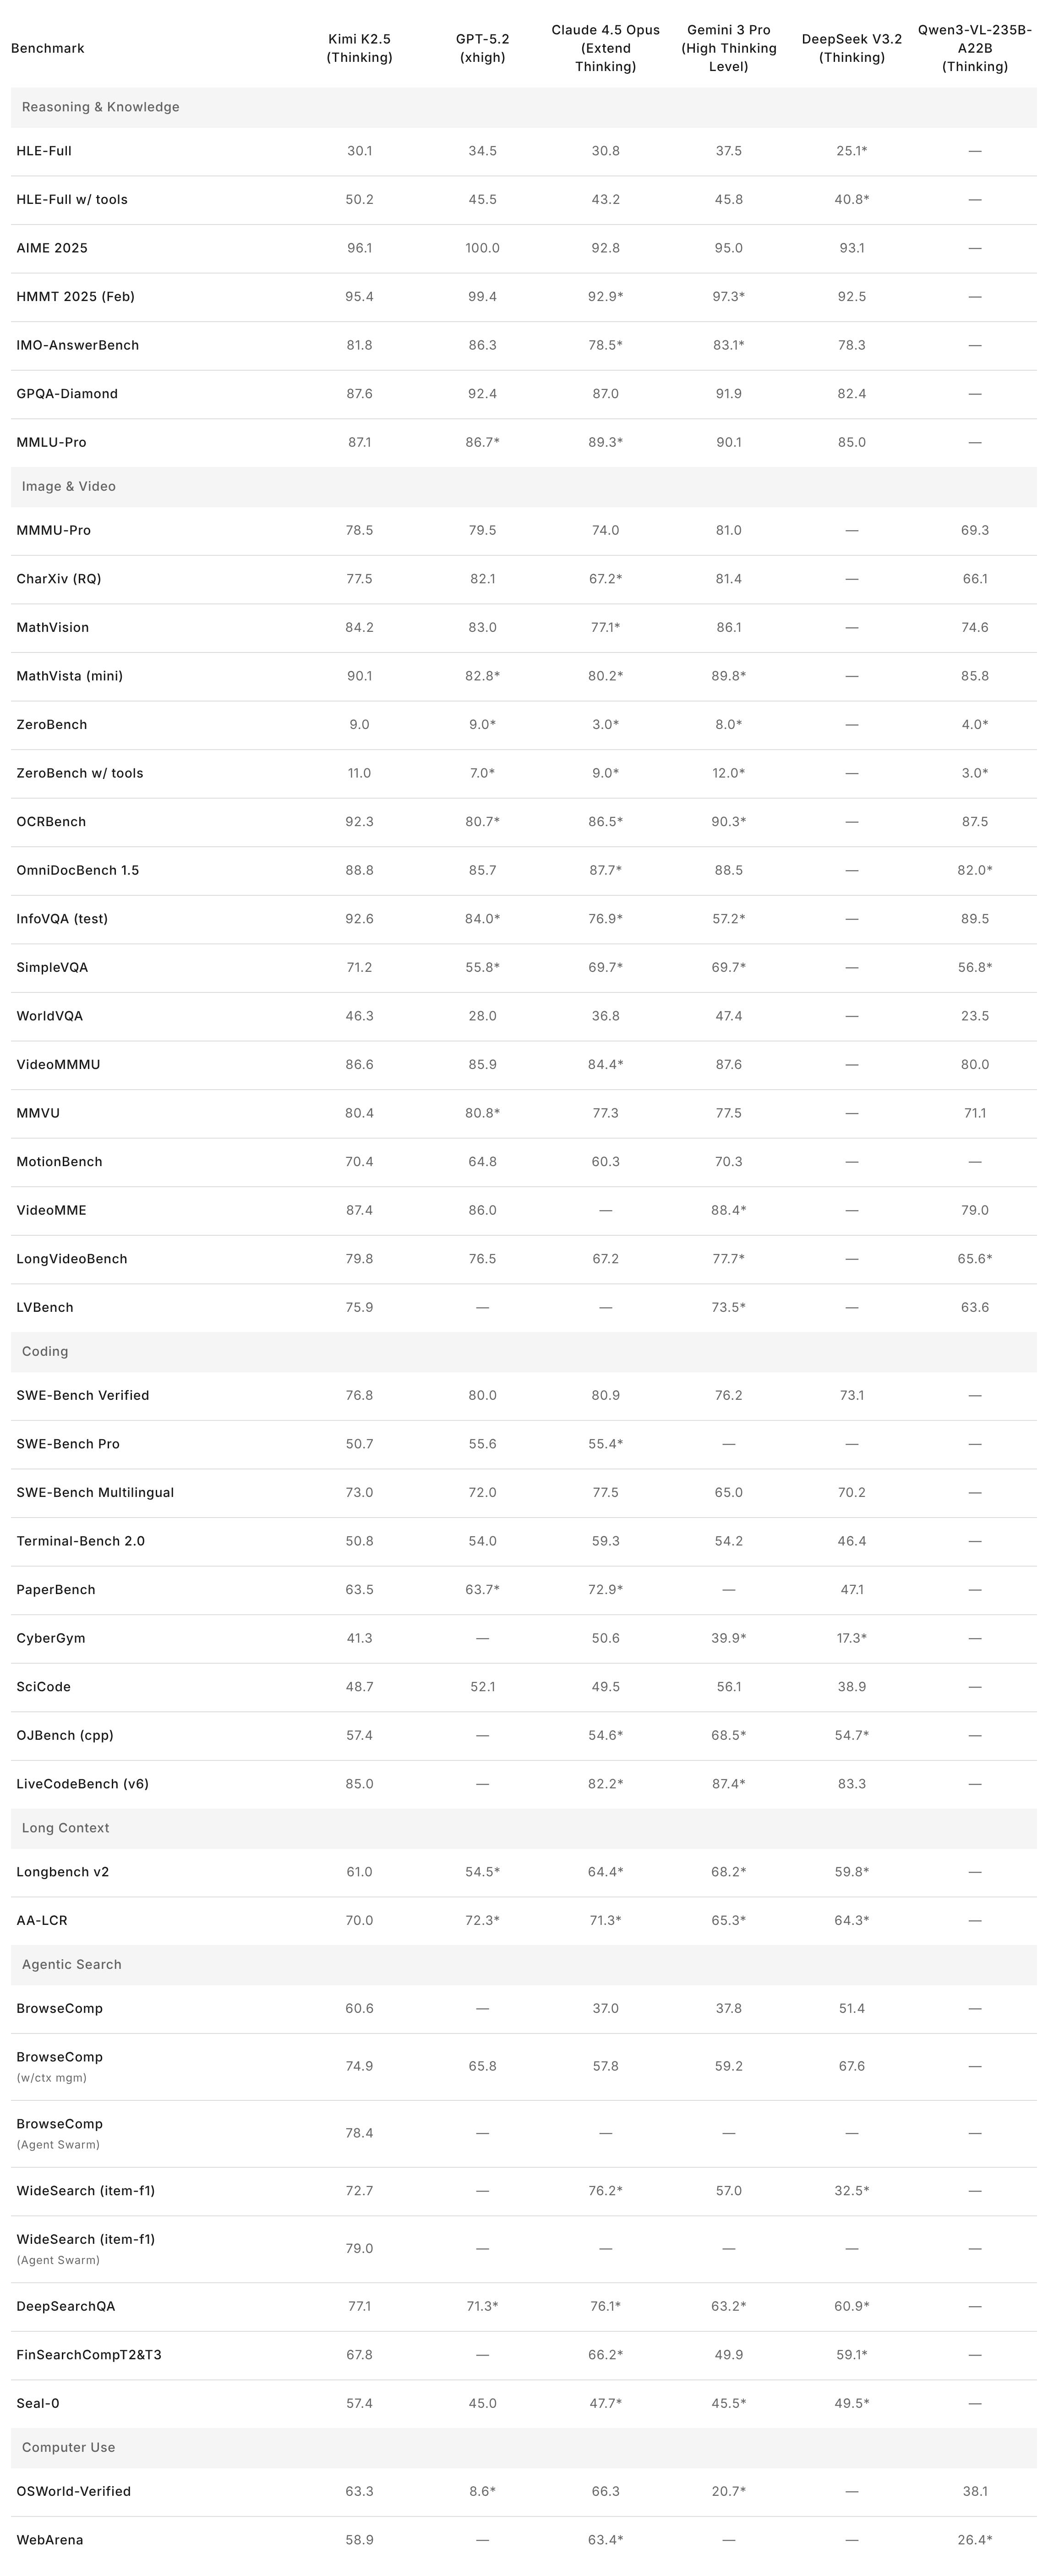
| Benchmark | Score | Source check |
|---|---|---|
| Humanity's Last ExamNo tools · full set, text and image (31.5 text-only); 96K-token completion budget | 30.1% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| Humanity's Last ExamWith tools · full set, text and image (51.8 text-only); search, code and browsing tools; Hugging Face blocked | 50.2% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Verified | 76.8% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| SWE-bench Proin-house minimal-tool harness; non-thinking mode; average of 5 runs · The source doesn't say whether this is the public or the commercial set | 50.7% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| GPQA Diamondthinking mode; 96K-token completion budget; average of 8 runs | 87.6% | CheckedA person checked this number against its source on 20 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| BrowseCompwith context management, discard-all strategy | 74.9% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| no context management: tasks past the context length count as failed | 60.6% | CheckedA person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by Moonshot AI
- Kimi K2.5: Visual Agentic Intelligencekimi.ai · 27 Jan 2026
Our capture of the source