Meta's Muse Models Climbed to the Top of DeepSWE in Six Months
Meta's Muse models went from 10.0% to 79.0% on DeepSWE v1.1 between April and October 2026, passing every other lab's reported score on Sep 2.
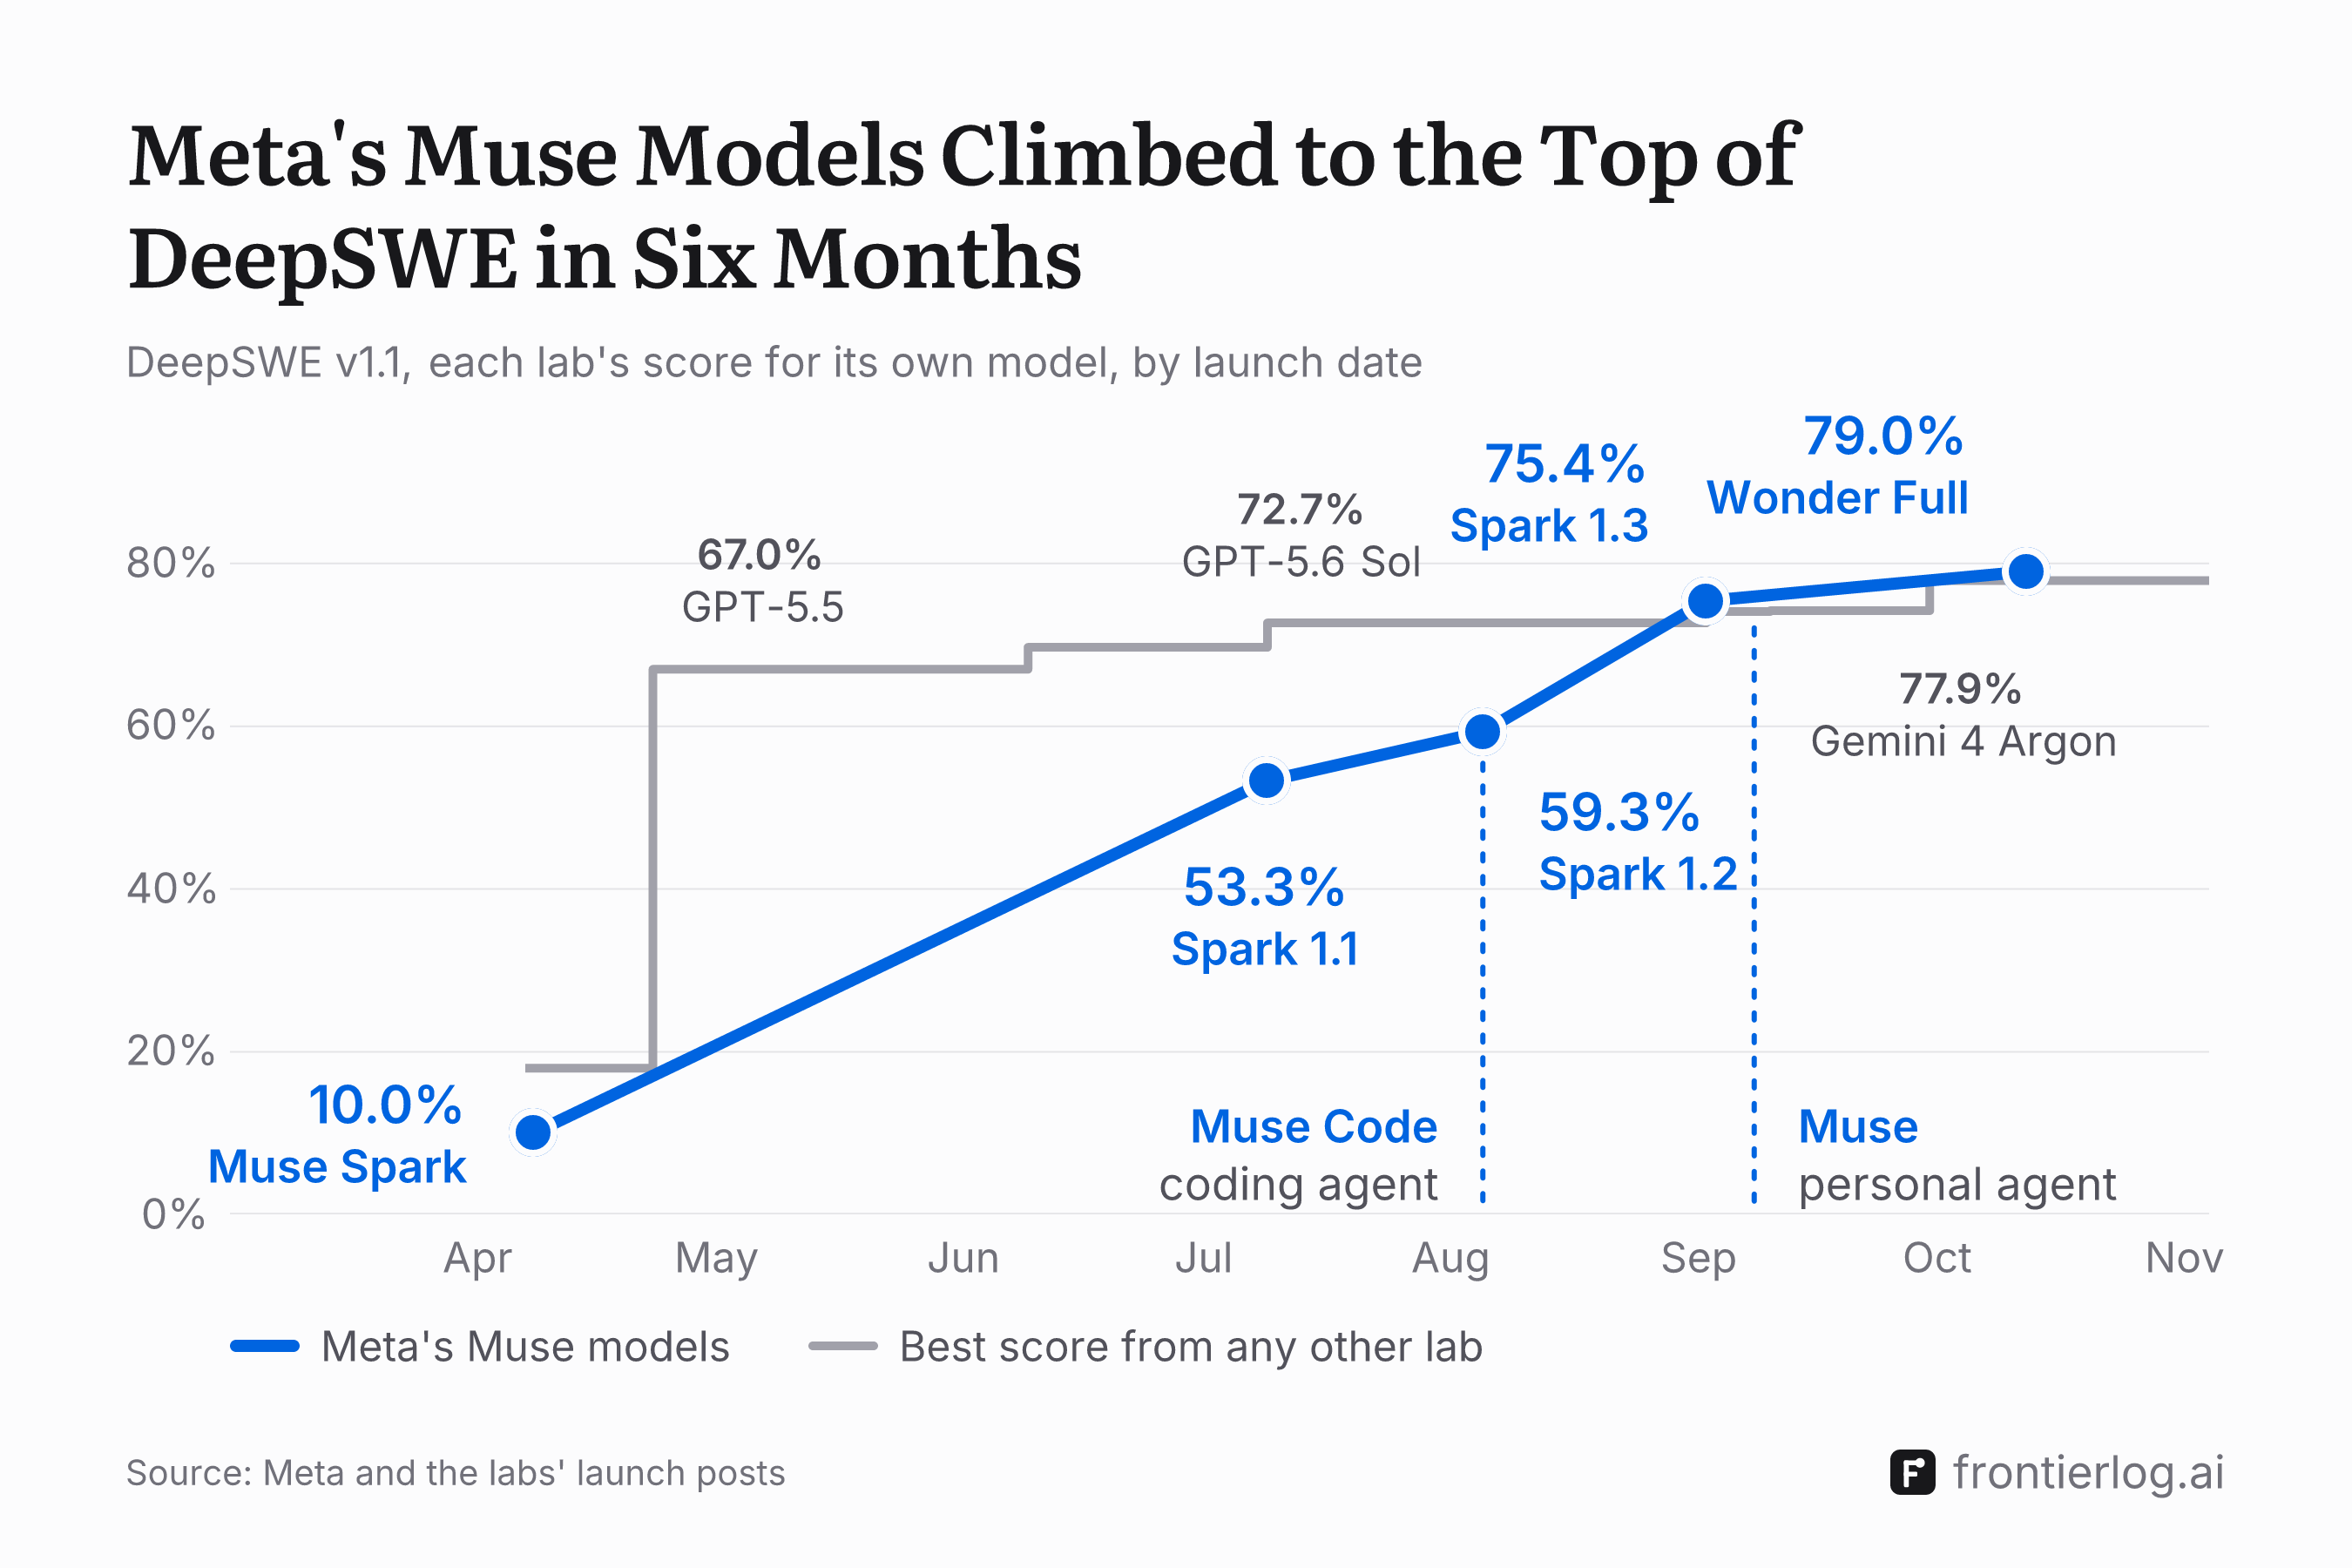
Meta's Muse models went from 10.0% to 79.0% on DeepSWE v1.1, a long-horizon coding benchmark, in the six months after Meta Superintelligence Labs launched Muse Spark, the first of its Muse models, on Apr 8, 2026. On Sep 2, Muse Spark 1.3 scored above every score another lab had reported for its own model. Between those launches, Meta released two agents: Muse Code for coding and Muse, a personal agent.
From 10% to 59% in four months
Meta reported Muse Spark's 10.0% in its Muse Spark 1.1 post on Jul 9, where Muse Spark 1.1 scored 53.3%. OpenAI launched GPT-5.6 Sol the same day and reported 72.7%, above every other lab's model launched by then.
On Aug 5, Meta launched Muse Spark 1.2 and Muse Code, a terminal coding agent in beta. Muse Spark 1.2 scored 59.3% running in Muse Code. Meta took Muse Code out of beta on Aug 31.
Ahead of the other labs on Sep 2
Muse Spark 1.3 scored 75.4% at max effort on Sep 2. Google reported 73.7% for Gemini 3.8 Flash the same day. In its own comparison table, Meta put GPT-5.6 Sol at 73.0% and Claude Opus 5 at 74.0%, both at max effort.
Six days later, on Sep 8, Meta launched Muse, "a secure, private personal AI agent" in the Muse app and WhatsApp, which Meta said is powered by Muse Spark. It began rolling out in the US.
Google's Gemini 4 Argon passed Muse Spark 1.3's 75.4% on Sep 30, with 77.9%.
Muse Wonder Full at 79.0%
On Oct 12, Meta launched Muse Wonder and Muse Wonder Full, which scored 78.8% and 79.0% at max effort. As of Nov 4, no other lab has reported a higher DeepSWE v1.1 score for its own model in the posts Frontier Log records.
How the scores compare
Each score is the lab's own report for its own model, with its own harness and effort setting. Meta reported Muse Spark 1.2 at 59.3% in Muse Code at its launch, for example, and at 55.0% at xhigh effort, with no harness named, in its later Muse Spark 1.3 post. Some earlier scores were reported after their models launched: Muse Spark's in Meta's July post, GLM-5.1's 18.0% in Z.ai's GLM-5.2 post on Jun 16, GPT-5.5's 67% in OpenAI's GPT-5.6 post on Jul 9, and Claude Fable 5's 69.7% in Anthropic's Claude Opus 5 post on Jul 24.
Not yet on Datacurve's leaderboard
Datacurve, which makes DeepSWE, runs its own DeepSWE leaderboard. As of Nov 4, the leaderboard was last updated on Sep 22. It lists Muse Spark 1.2 at 55% at xhigh effort, and no Muse Spark 1.3, Muse Wonder or Muse Wonder Full. GPT-6 Astra, Gemini 3.8 Flash and Claude Opus 5 lead there, at 74% each.
DeepSWE v1.1, Meta's Muse models
DeepSWE v1.1, other labs' highest score to date
DeepSWE v1.1, Meta's Muse Spark 1.3 comparison table
| Model | Value | Sources |
|---|---|---|
| GPT-5.6GPT-5.6 Sol (max), as Meta reported it | 73.0% | Announcementscorecard (image), row 'DeepSWE v1.1', column 'GPT 5.6 Sol (max)' |
| Claude Opus 5Claude Opus 5 (max), as Meta reported it | 74.0% | Announcementscorecard (image), row 'DeepSWE v1.1', column 'Opus 5 (max)' |
| Muse Spark 1.2 | 55.0% | AnnouncementMuse Spark 1.3 scorecard (image), row 'DeepSWE v1.1', column 'Muse Spark 1.2 (xhigh)' |
| Muse Spark 1.3 | 75.4% | Announcementscorecard (image), row 'DeepSWE v1.1', column 'Muse Spark 1.3 (max)' |
Sources
- Meta, Apr 8, 2026Introducing Muse Spark: Scaling Towards Personal Superintelligence
- Meta, Jul 9, 2026Introducing Muse Spark 1.1
- Meta, Aug 5, 2026Introducing Muse Code and Muse Spark 1.2
- Meta, Sep 2, 2026Introducing Muse Spark 1.3
- Meta, Oct 12, 2026Muse Wonder: A Frontier Model For Personal & Professional AI Agents
- Meta, Sep 8, 2026Introducing Muse: The World’s First Personal AI Agent Built for Everyone
- Z.ai, Jun 16, 2026GLM-5.2: Built for Long-Horizon Tasks
- Anthropic, Jul 24, 2026Introducing Claude Opus 5
- OpenAI, Jul 9, 2026GPT-5.6: Frontier intelligence that scales with your ambition
- Google, Sep 2, 2026Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Smarter, Faster, More Efficient
- Google, Sep 30, 2026Gemini 4 Argon: our next era of frontier intelligence
- Datacurve, DeepSWE leaderboard, Sep 22, 2026deepswe.datacurve.ai