Benchmark Scores Move After Launch Day
How labs re-report their older models' benchmark scores in later documents, and how far a launch-day score holds.
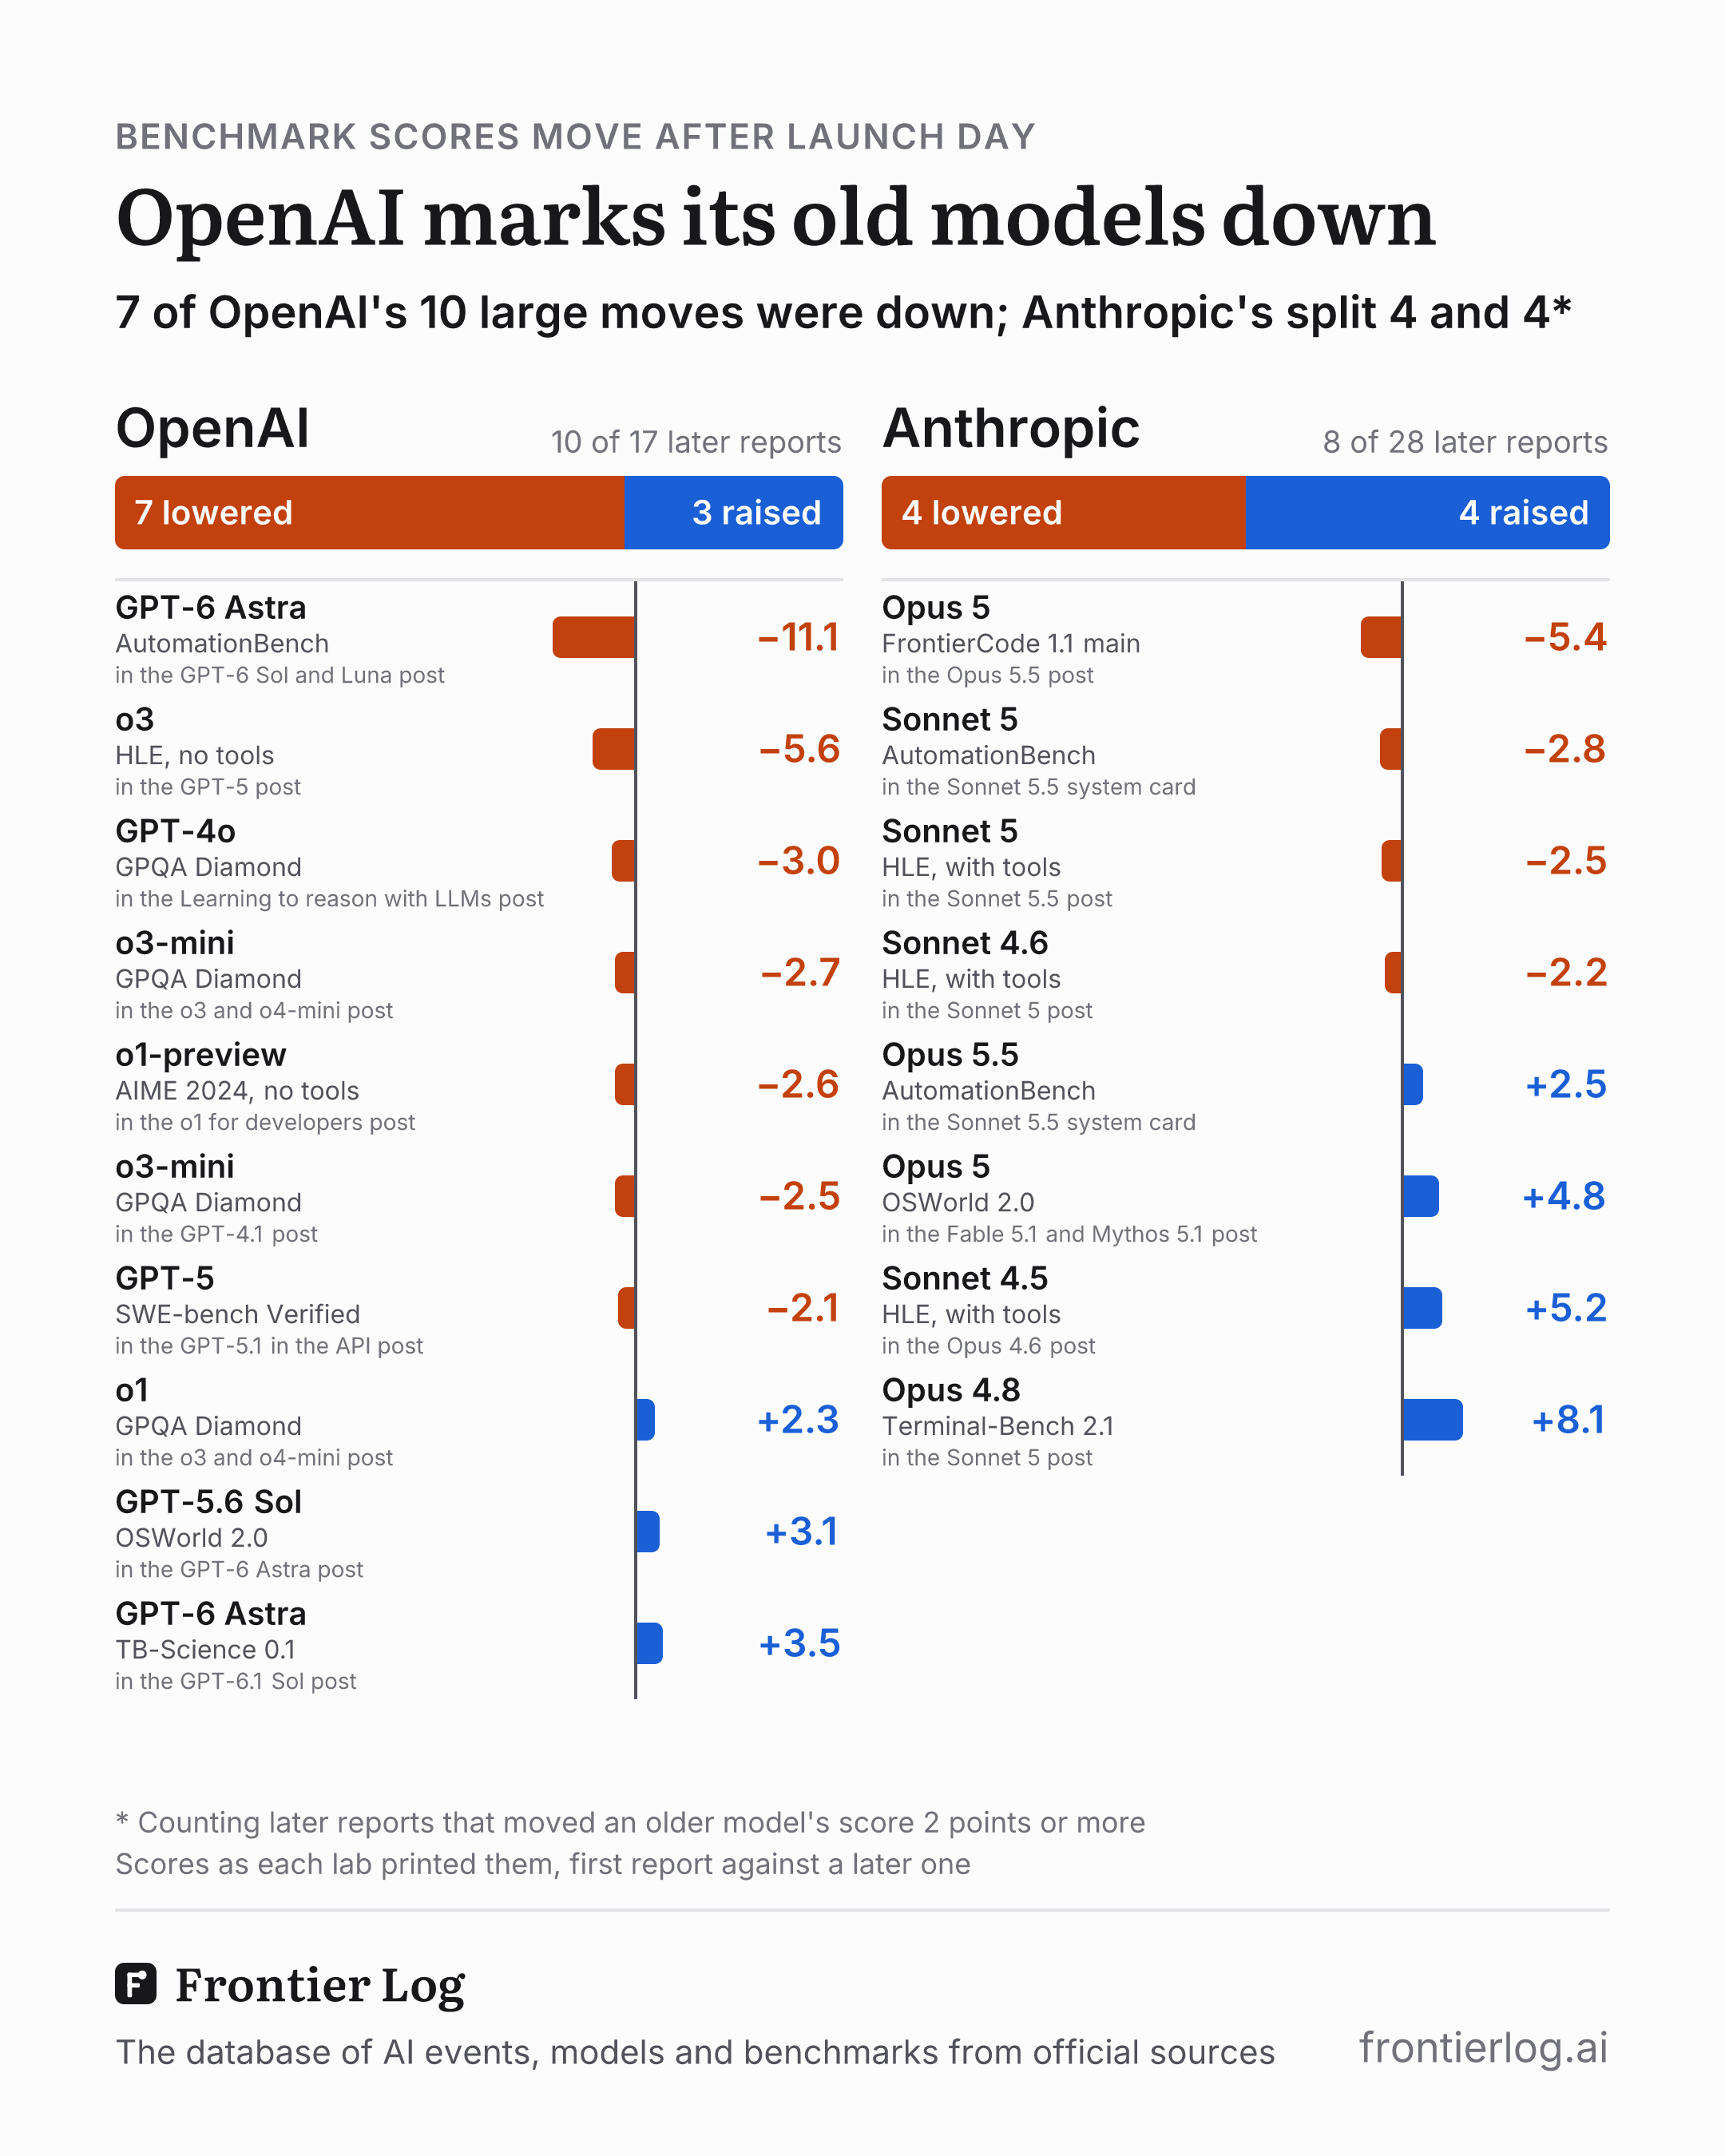
OpenAI marks its old models down
7 of OpenAI's 10 large moves were down; Anthropic's split 4 and 4*
Counting moves of 2 points or more, OpenAI's later reports lowered an older model's score 7 times out of 10, while Anthropic's split 4 and 4. OpenAI's biggest is GPT-6 Astra on AutomationBench, 11.1 points lower in the GPT-6 Sol and Luna post, at low effort.
* Counting later reports that moved an older model's score 2 points or more
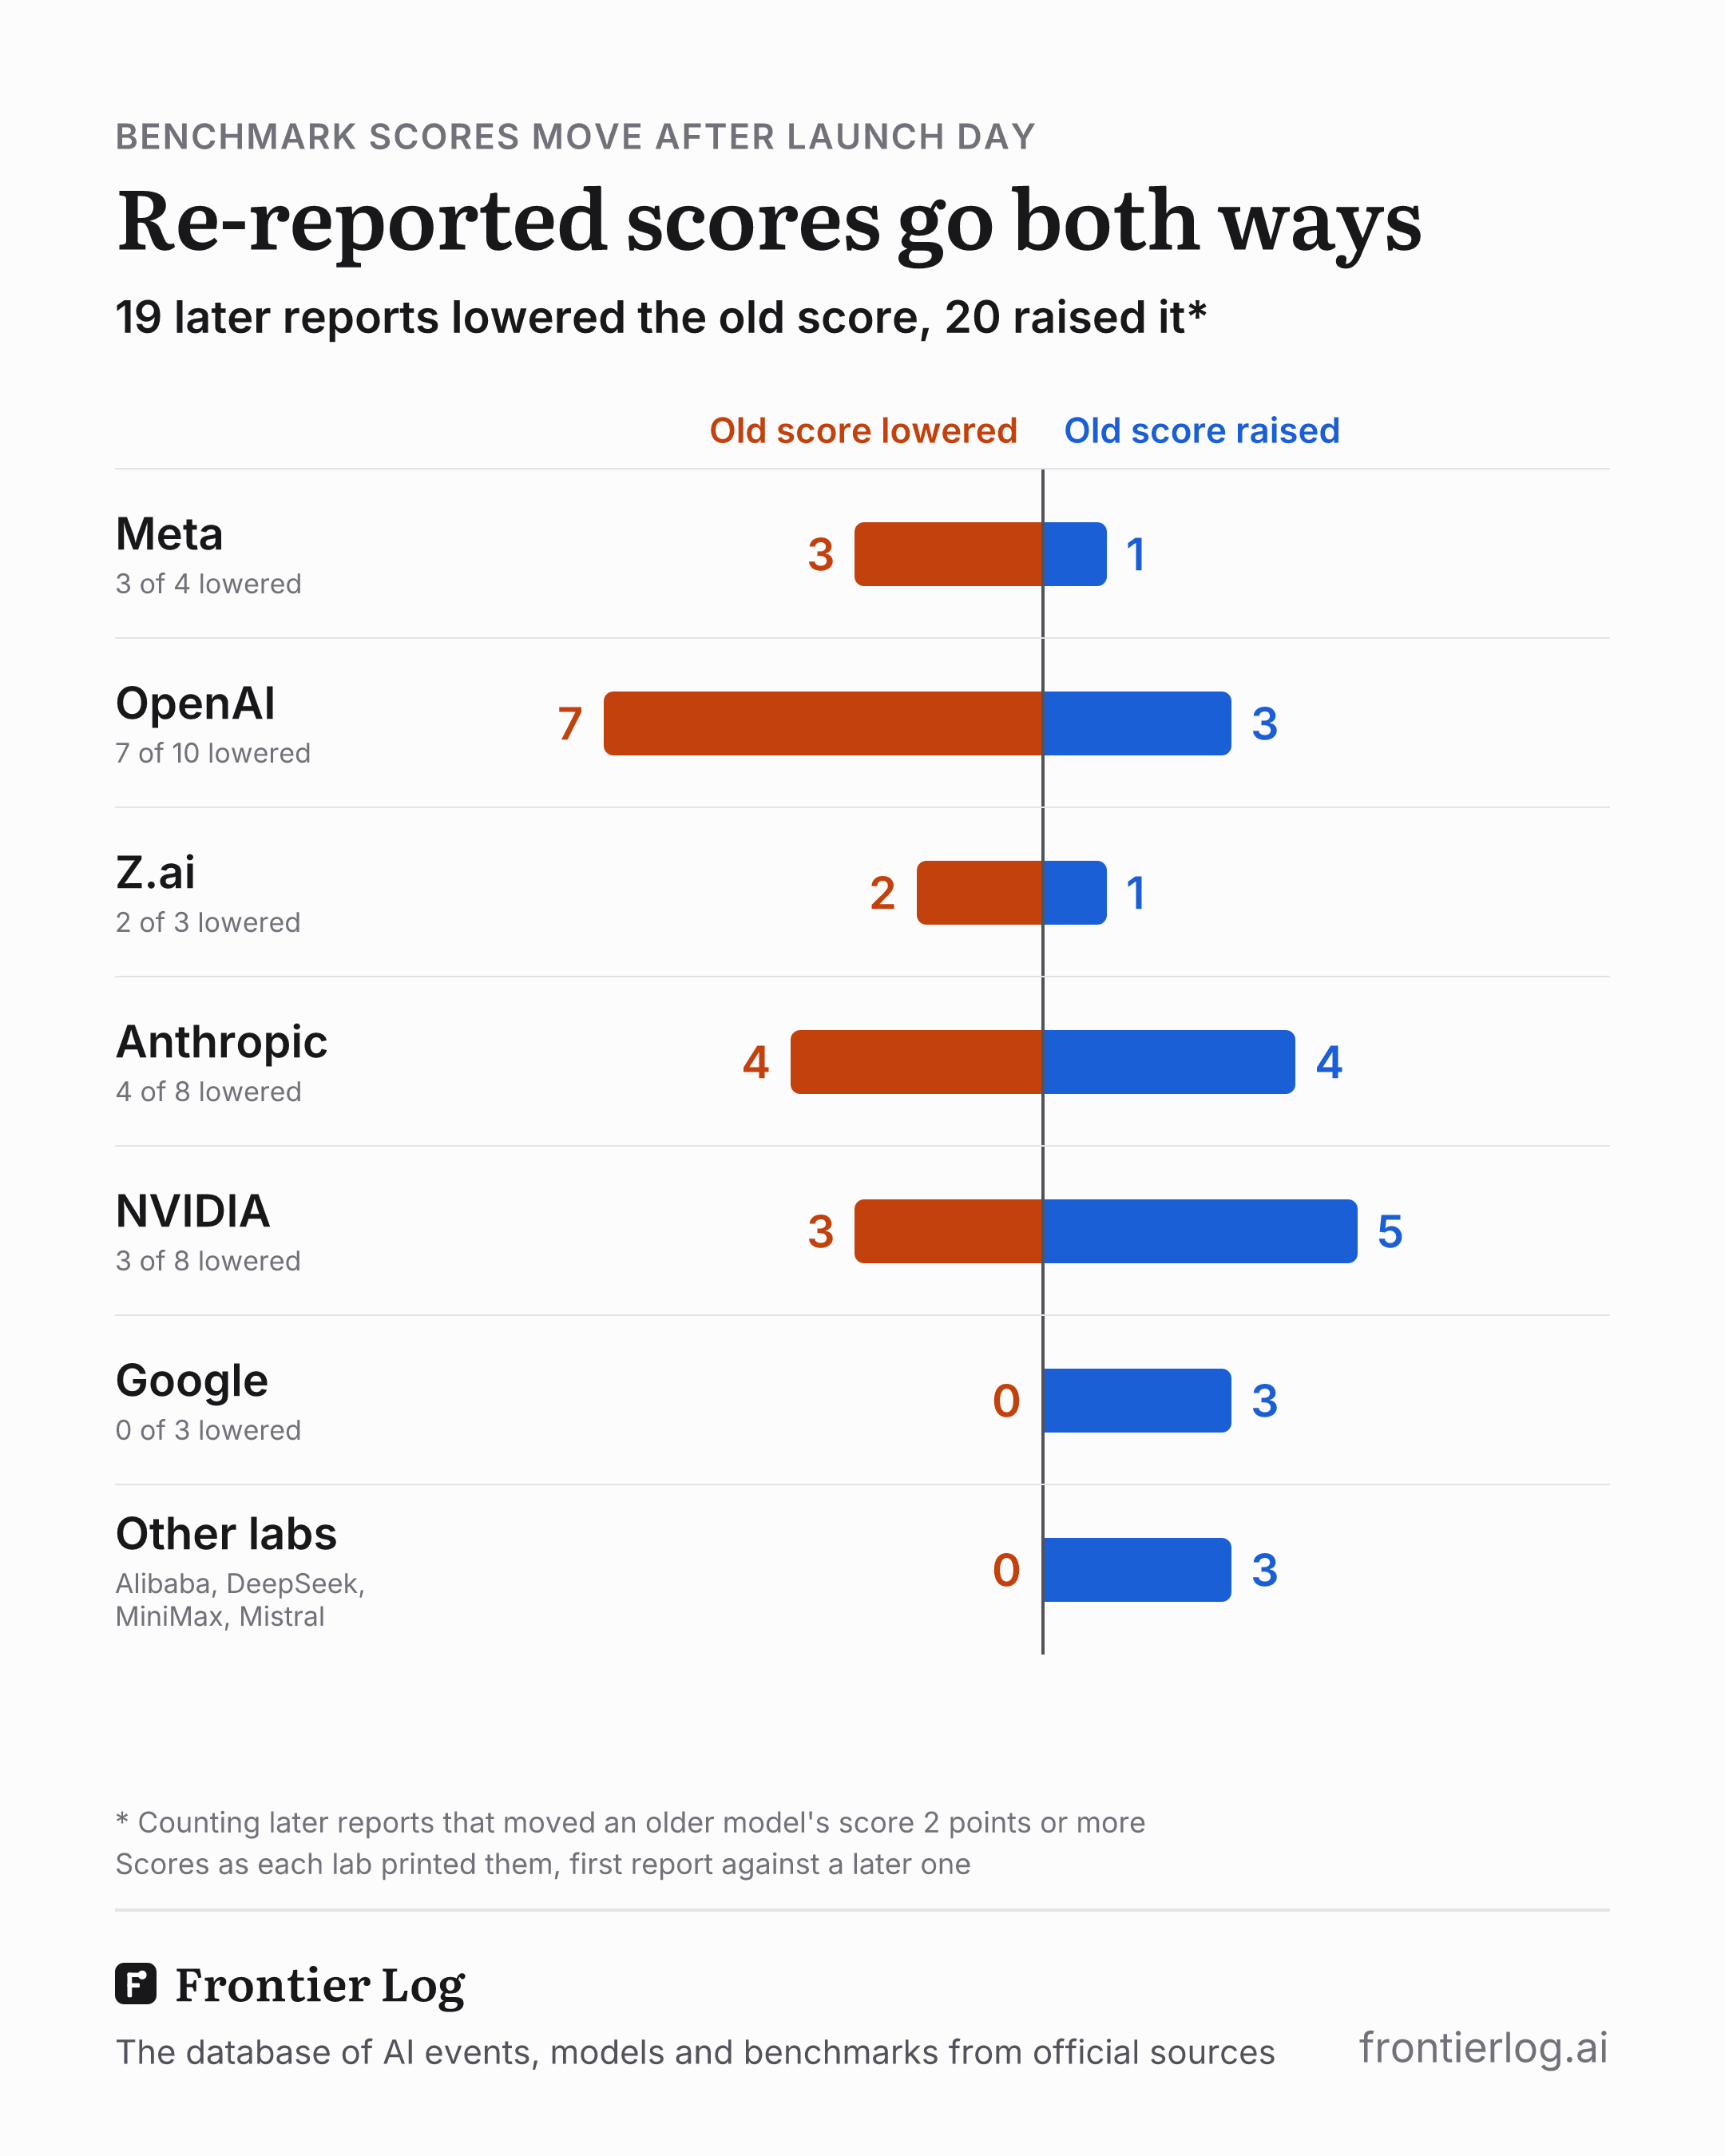
Re-reported scores go both ways
19 later reports lowered the old score, 20 raised it*
Counting moves of 2 points or more, labs re-report older models' scores in both directions: 19 later reports lowered the old score and 20 raised it. OpenAI lowered 7 of its 10 and Meta 3 of 4; NVIDIA, Google and the smaller labs mostly raised theirs.
* Counting later reports that moved an older model's score 2 points or more
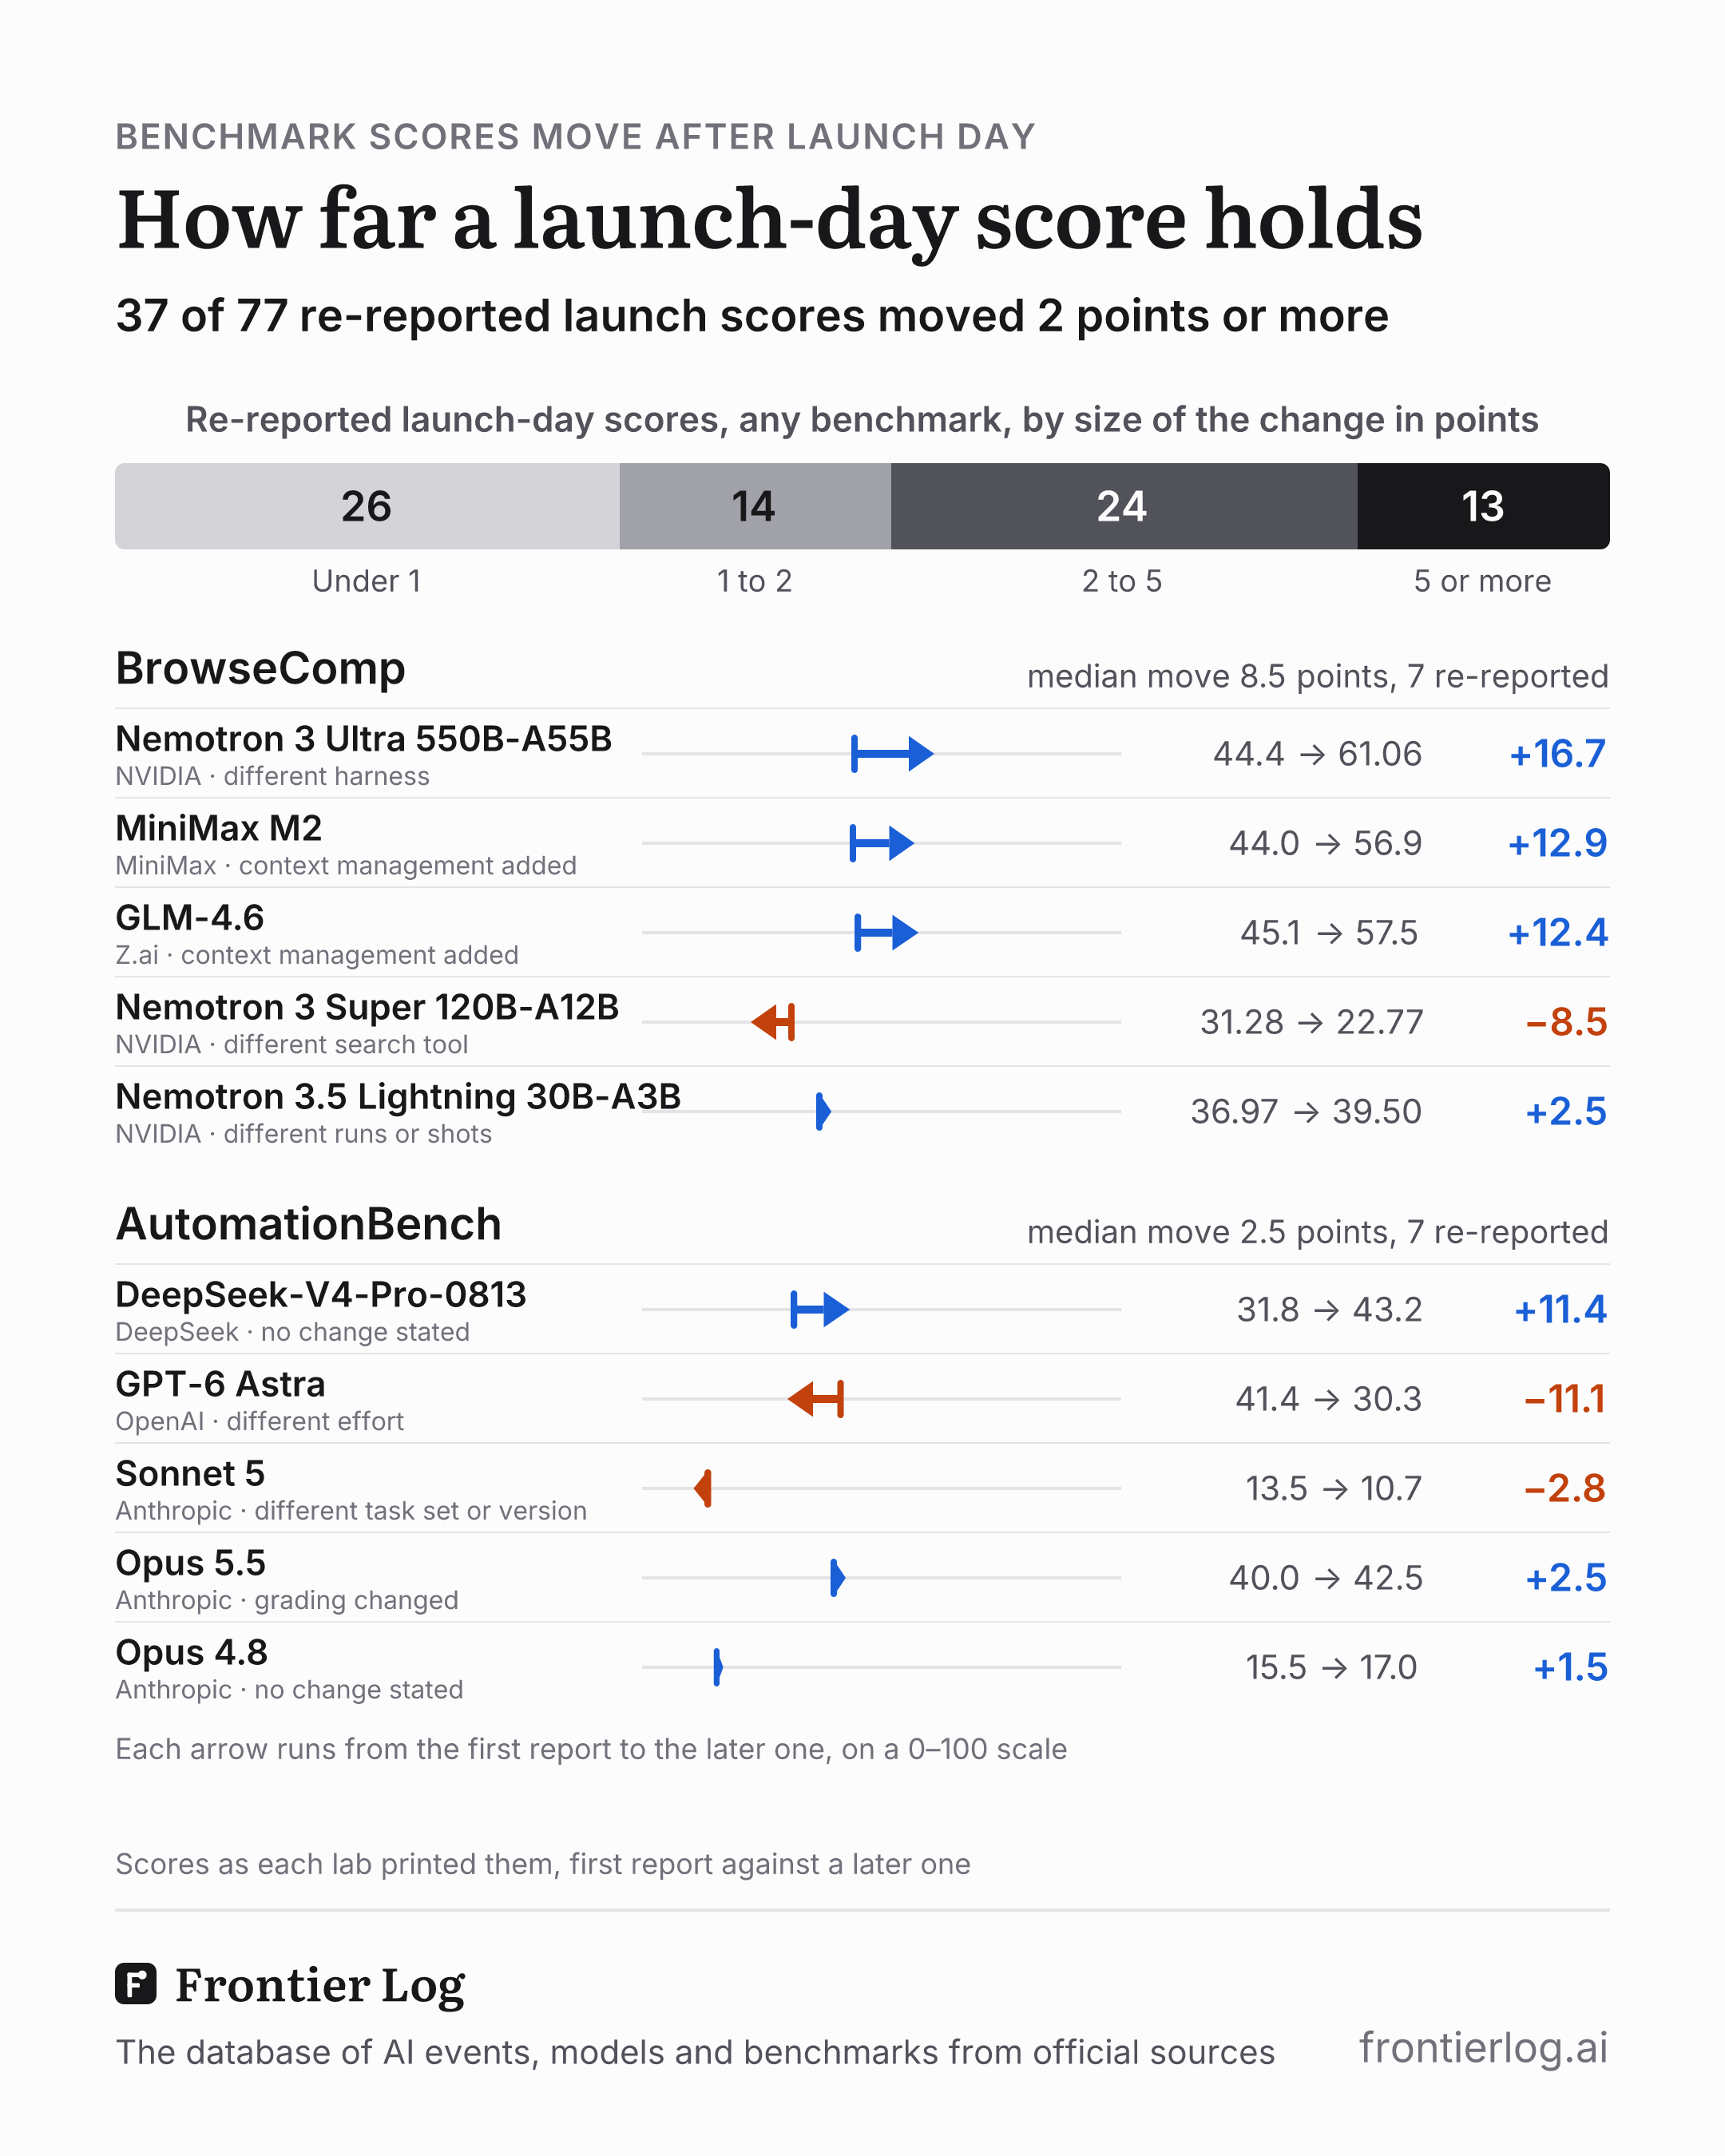
How far a launch-day score holds
37 of 77 re-reported launch scores moved 2 points or more
About half the launch-day scores a lab later printed again moved 2 points or more, and 13 moved 5 or more. BrowseComp moves most, a median 8.5 points, as harnesses and context management change.
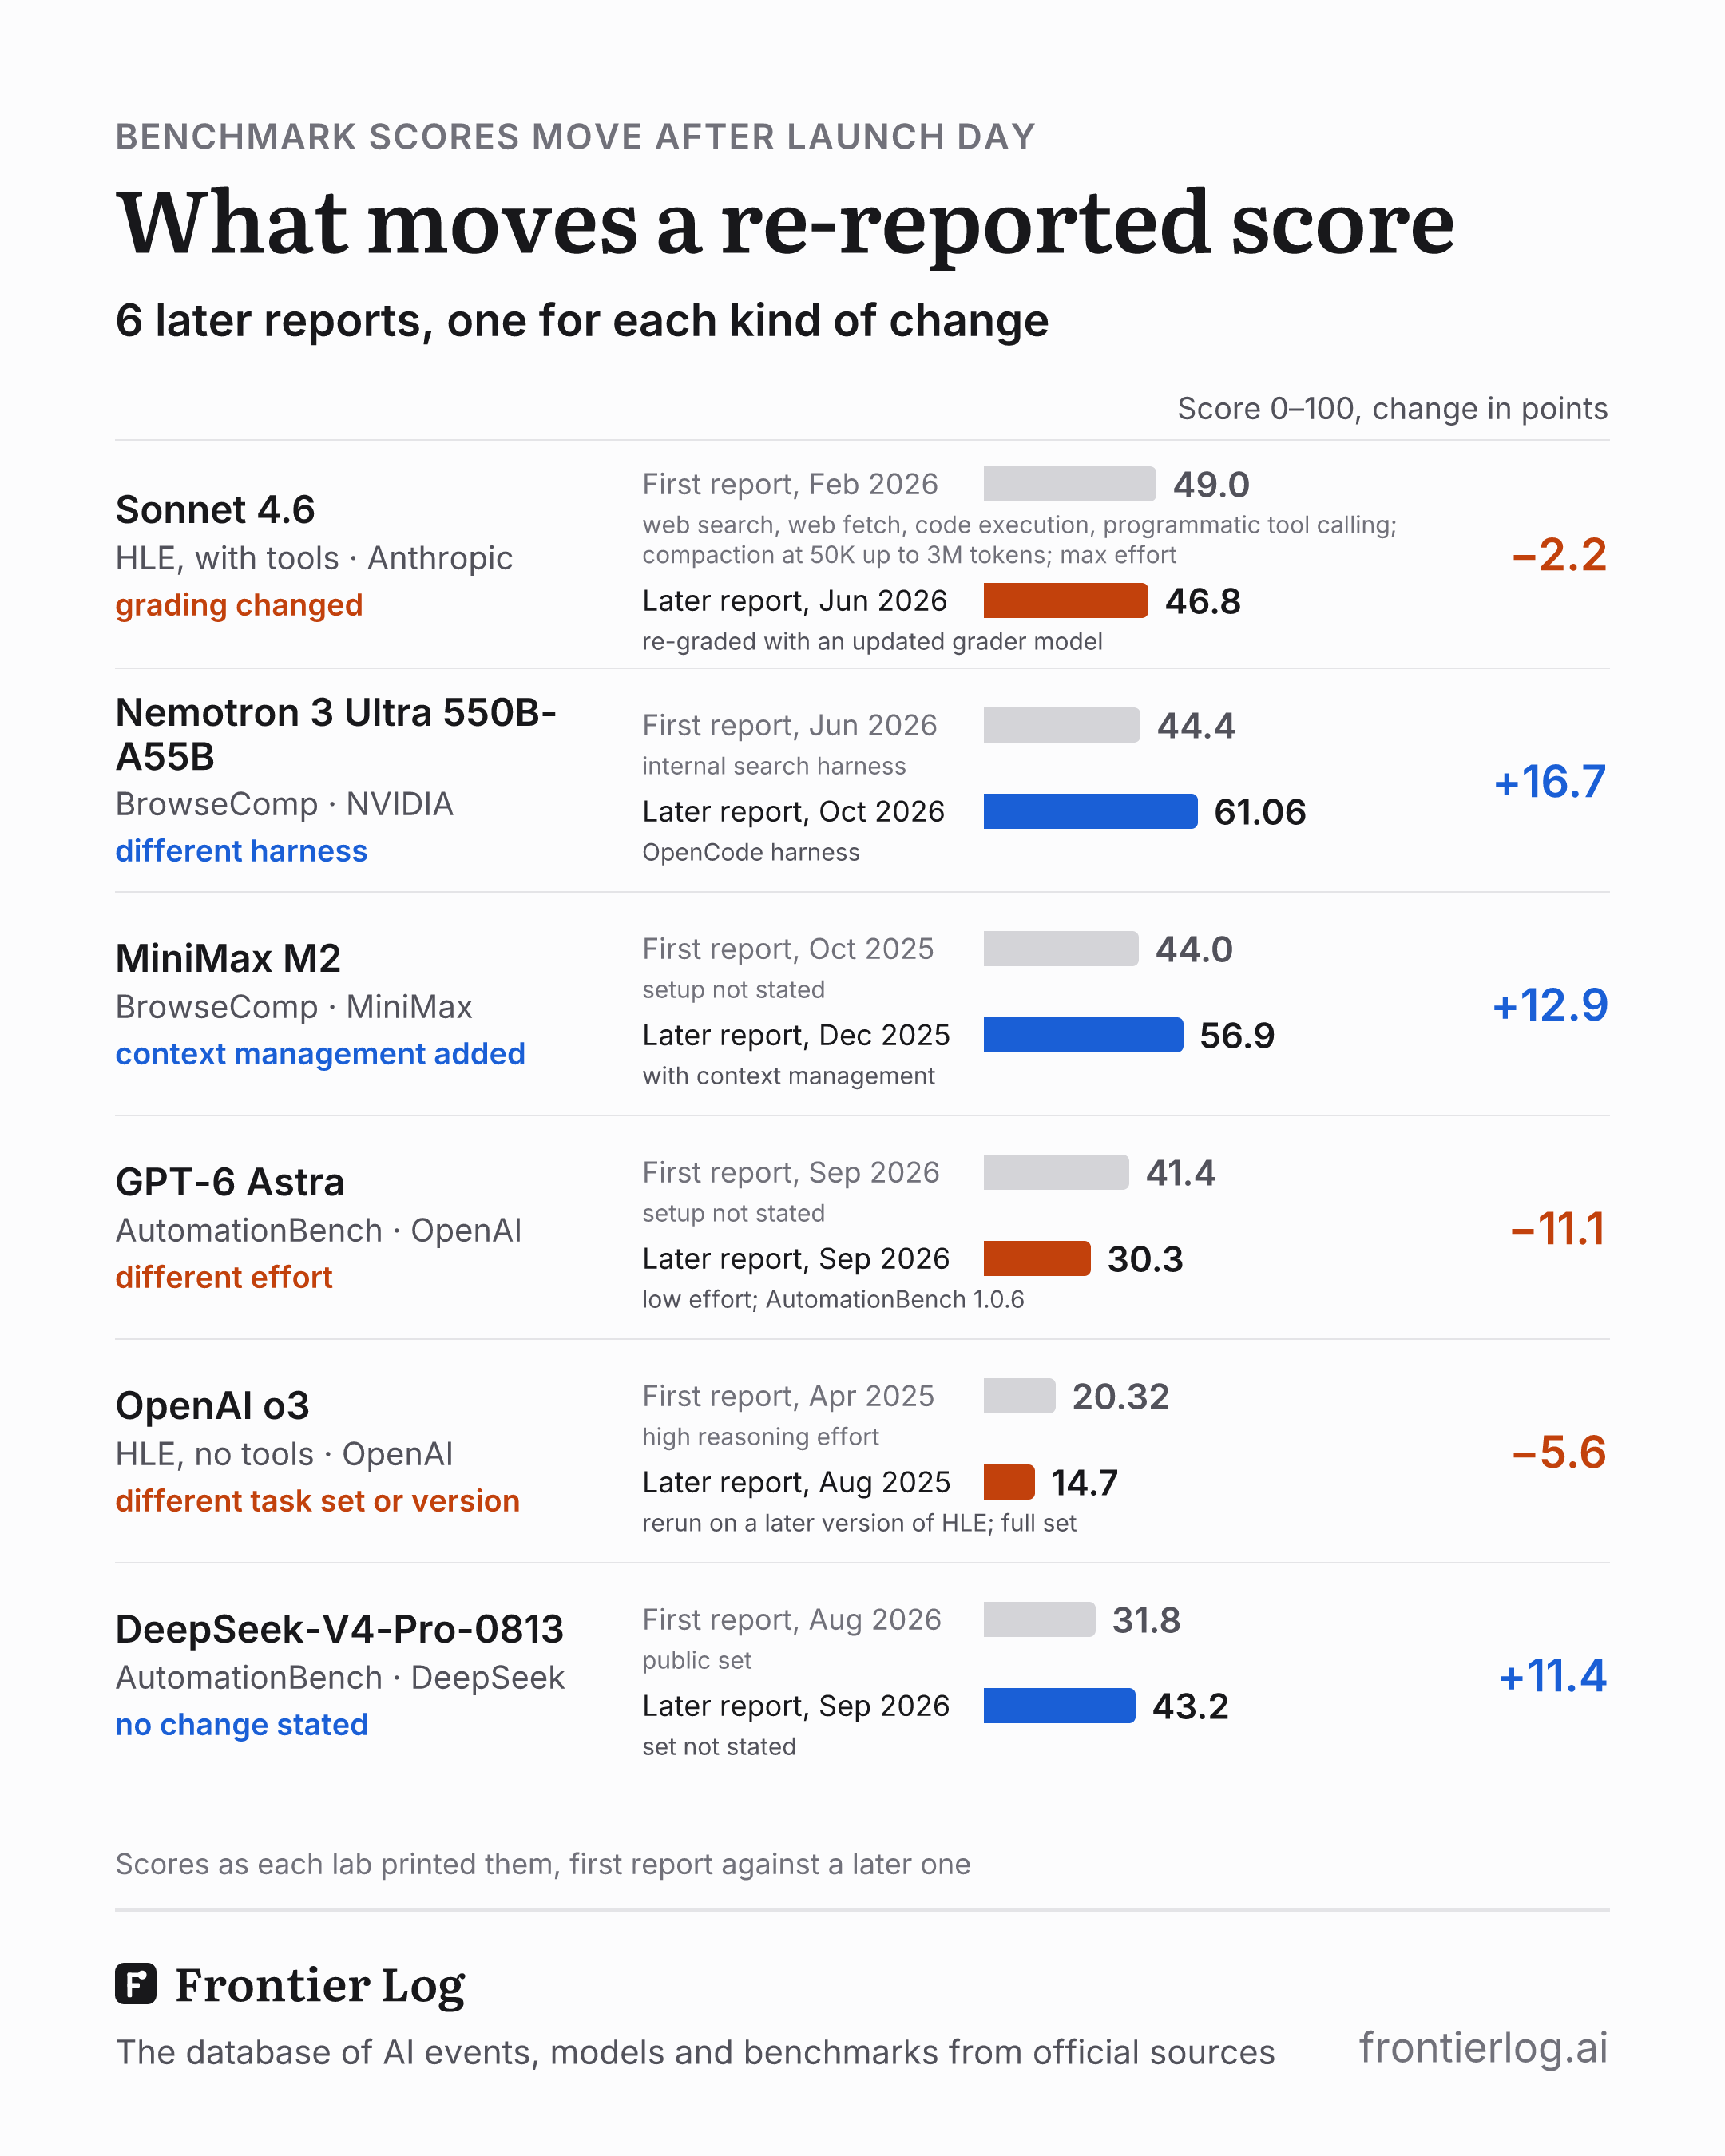
What moves a re-reported score
6 later reports, one for each kind of change
A stated change in setup, from the grader to the harness, context management, effort or task set, can move a re-reported score by 2 to 17 points. DeepSeek's AutomationBench later report, 11.4 points higher, states no change.
AIME 2024, no tools
| Model | Score | Sources |
|---|---|---|
| OpenAI o1First report, Sep 2024. Setup: AIME year and pass@1 not stated | 44.6% | Announcement'Optimized for STEM Reasoning' section, the 'Mathematics:' paragraph under the 'Math Performance vs Inference Cost' chart, the figure in parentheses after 'o1-preview' |
| OpenAI o1Later report, 17 Dec 2024, in the o1 for developers post: no change stated. Setup: pass@1 | 42.0% | Announcementeval table (Category / Eval / o1-2024-12-17 / o1-preview), row 'Math: AIME 2024 (pass @1)', column 'o1-preview' |
AIME 2025, no tools
AutomationBench
| Model | Score | Sources |
|---|---|---|
| Claude Opus 4.8First report, May 2026. Setup: Zapier leaderboard, private held-out set; max effort | 15.5% | AnnouncementSection 8.1, Table 8.1.A (evaluation summary), row 'Automation Bench', column 'Claude Opus 4.8' |
| Claude Opus 4.8Later report, 24 Jul 2026, in the Claude Opus 5 post: no change stated. Setup: Zapier leaderboard, private held-out set; max effort | 17.0% | Announcementbenchmark table (image), row 'Business workflows, AutomationBench', column 'Opus 4.8' |
| Claude Fable 5 and Mythos 5First report, Jun 2026. Setup: Zapier leaderboard, private held-out set; max effort | 17.4% | AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Fable 5' |
| Claude Fable 5 and Mythos 5Later report, 1 Sep 2026, in the Claude Fable 5.1 and Mythos 5.1 post: grading changed. Setup: Zapier leaderboard, private held-out set; tasks blocked by safeguards scored zero | 17.1% | Announcementbenchmark table (HTML), row 'Business workflows, AutomationBench', column 'Fable 5' |
| Claude Sonnet 5First report, Jun 2026. Setup: Zapier leaderboard, private held-out set; max effort | 13.5% | AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Claude Sonnet 5' |
| Claude Sonnet 5Later report, 28 Sep 2026, in the Claude Sonnet 5.5 system card: different task set or version. Setup: run by Zapier; private set, release 1.0.6 | 10.7% | AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Claude Sonnet 5' |
| Claude Opus 5First report, Jul 2026. Setup: max effort; Zapier leaderboard, private held-out set | 26.0% | Announcementbenchmark table (image), row 'Business workflows, AutomationBench', column 'Opus 5' |
| Claude Opus 5Later report, 1 Sep 2026, in the Claude Fable 5.1 and Mythos 5.1 post: no change stated. Setup: Zapier leaderboard, private held-out set; max effort | 26.9% | Announcementbenchmark table (HTML), row 'Business workflows, AutomationBench', column 'Opus 5' |
| DeepSeek-V4-Pro GAFirst report, Aug 2026. Setup: public set | 31.8% | Announcementtable image, row 'AutomationBench (Public)', column 'DeepSeek-V4-Pro-0813' |
| DeepSeek-V4-Pro GALater report, 10 Sep 2026, in the DeepSeek-V4.1-Flash post: no change stated. Setup: set not stated | 43.2% | Announcementlater report: DeepSeek-V4.1-Flash post, benchmark table image (second image), row 'Automation-Bench', column 'DeepSeek V4-Pro 0813' |
| GPT-6 AstraFirst report, Sep 2026 | 41.4% | AnnouncementProfessional table, row 'AutomationBench', column 'GPT‑6 Astra' |
| GPT-6 AstraLater report, 22 Sep 2026, in the GPT-6 Sol and Luna post: different effort. Setup: low effort; AutomationBench 1.0.6 | 30.3% | AnnouncementAutomationBench table (Model (and effort) / Score / Cost per task), row 'GPT-6 Astra (low)', column 'Score' |
| Claude Opus 5.5First report, Sep 2026. Setup: run by Zapier, without fallback models | 40.0% | Announcementbenchmark table, row 'AutomationBench', column 'Opus 5.5' |
| Claude Opus 5.5Later report, 28 Sep 2026, in the Claude Sonnet 5.5 system card: grading changed. Setup: run by Zapier; refused tasks re-run with default fallbacks; private set, release 1.0.6 | 42.5% | AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Claude Opus 5.5' |
BrowseComp
DeepSWE v1.1
FrontierCode 1.1, main set
GPQA Diamond
HLE, no tools
HLE, with tools
LiveCodeBench
MCP Atlas
| Model | Score | Sources |
|---|---|---|
| GLM-5First report, Feb 2026. Setup: 500-task public set; thinking mode; 10-minute timeout per task; Gemini 3 Pro judge | 67.8% | Announcementbenchmark table, row 'MCP-Atlas Public Set', column 'GLM-5 (Thinking)' |
| GLM-5Later report, 7 Apr 2026, in the GLM-5.1 post: no change stated. Setup: 500-task public set; Gemini 3 Pro judge | 69.2% | Announcementbenchmark table near the end, row 'MCP-Atlas Public Set', column 'GLM-5' |
MMLU-Pro
| Model | Score | Sources |
|---|---|---|
| Llama 3.1 405BFirst report, Jul 2024. Setup: 5-shot chain of thought | 73.3% | Announcementbenchmark table (image), row 'MMLU PRO (5-shot, CoT)', column 'Llama 3.1 405B' |
| Llama 3.1 405BLater report, 5 Apr 2025, in the Llama 4 Scout and Maverick post: different runs or shots. Setup: 0-shot | 73.4% | Announcement'Llama 4 Scout instruction-tuned benchmarks' table (image), row 'MMLU Pro', column 'Llama 3.1 405B' |
OSWorld 2.0, offline set, partial score
| Model | Score | Sources |
|---|---|---|
| GPT-5.6First report, Jul 2026. Setup: set, scoring and task release not stated | 62.6% | Announcementcomputer-use/agentic eval table (HTML), row 'OSWorld 2.0', column 'GPT‑5.6 Sol' |
| GPT-5.6Later report, 3 Sep 2026, in the GPT-6 Astra post: different task set or version. Setup: task release v2026.08.08 | 65.7% | Announcement'Computer Use' table, row 'OSWorld 2.0 (v2026.08.08, offline set, partial score)', column 'GPT-5.6 Sol2' |
| Claude Opus 5First report, Jul 2026. Setup: task release not stated | 70.6% | Announcementbenchmark table image, row 'Computer use / OSWorld 2.0', column 'Opus 5' |
| Claude Opus 5Later report, 1 Sep 2026, in the Claude Fable 5.1 and Mythos 5.1 post: different task set or version. Setup: partial score; August 2026 task release, not comparable to earlier OSWorld 2.0 scores | 75.4% | Announcementbenchmark table (HTML), row 'Computer use / OSWorld 2.0 [2]', column 'Opus 5', the value tagged 'partial' |
SWE-bench Pro
SWE-bench Verified
Terminal-Bench 2.0
Terminal-Bench 2.1
TB-Science 0.1
| Model | Score | Sources |
|---|---|---|
| GPT-6 AstraFirst report, Sep 2026 | 64.6% | AnnouncementAcademic table, row 'Terminal-Bench Science 0.1', column 'GPT‑6 Astra' |
| GPT-6 AstraLater report, 29 Sep 2026, in the GPT-6.1 Sol post: different effort. Setup: maximum effort | 68.1% | Announcement'Scientific research' section, paragraph after the Terminal-Bench Science 0.1 cost sentence: 'GPT-6 Astra still achieves the highest score among the models tested at ...' |