Who reports which benchmark
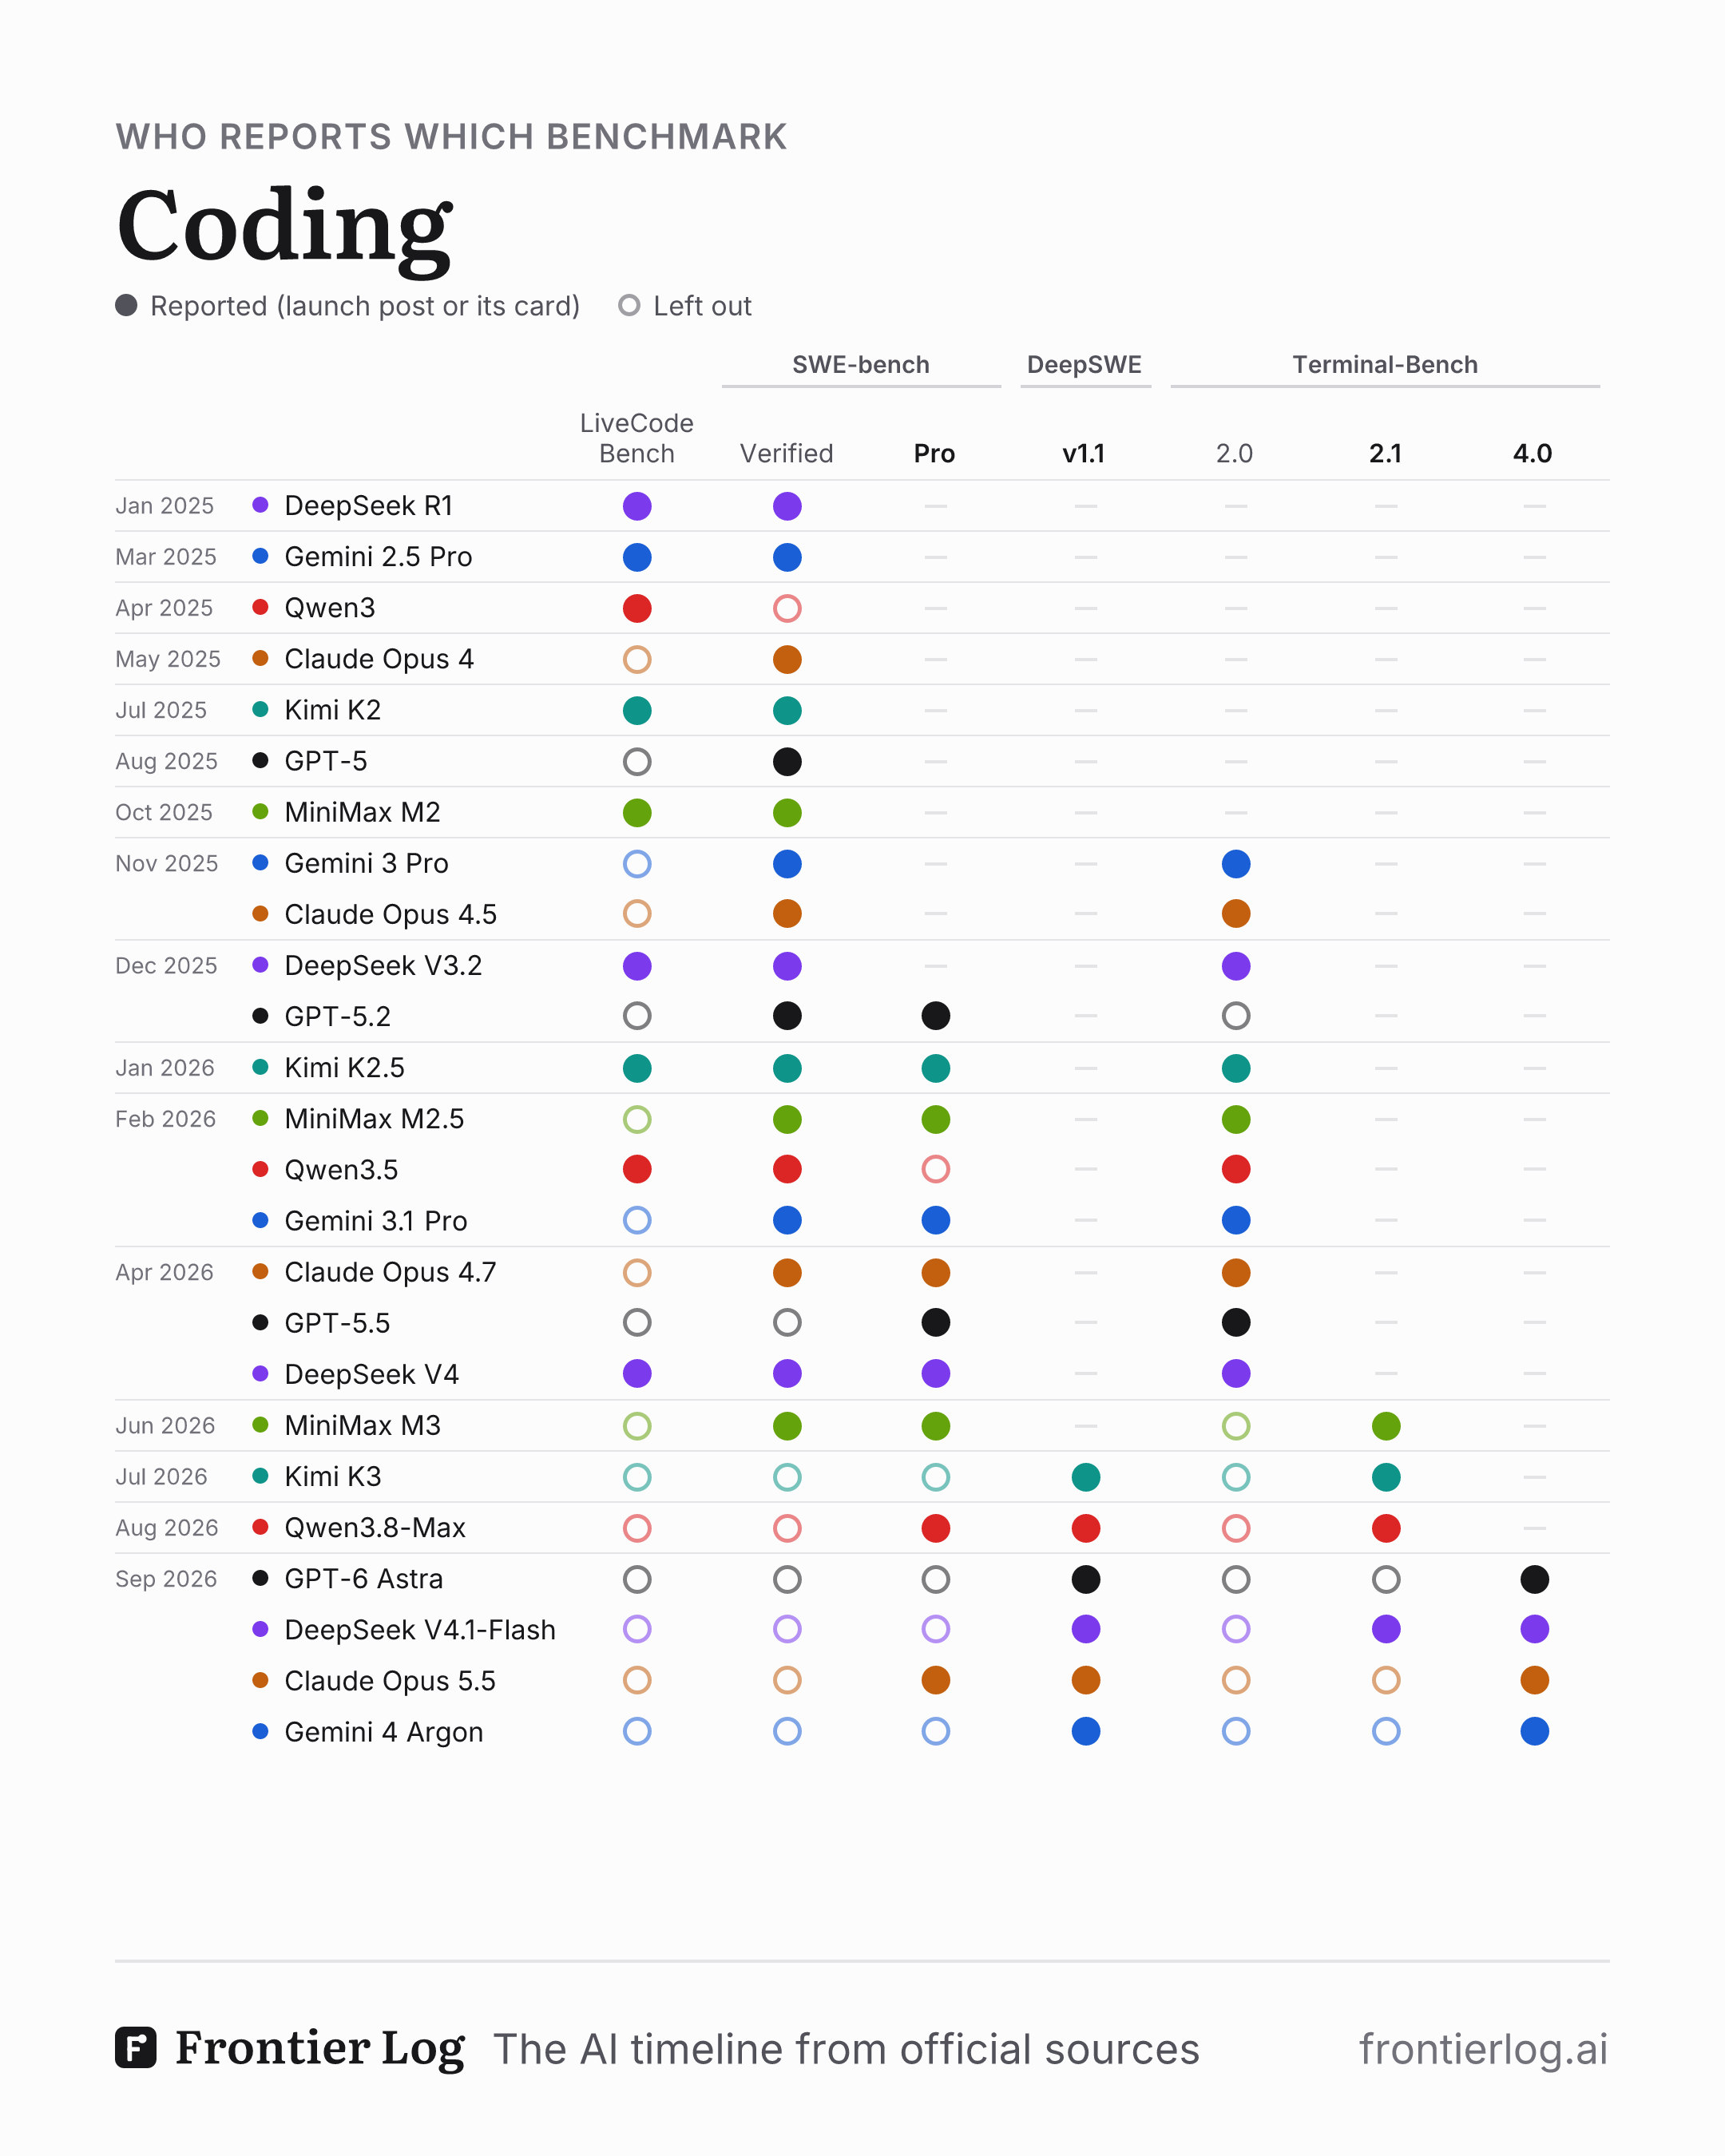
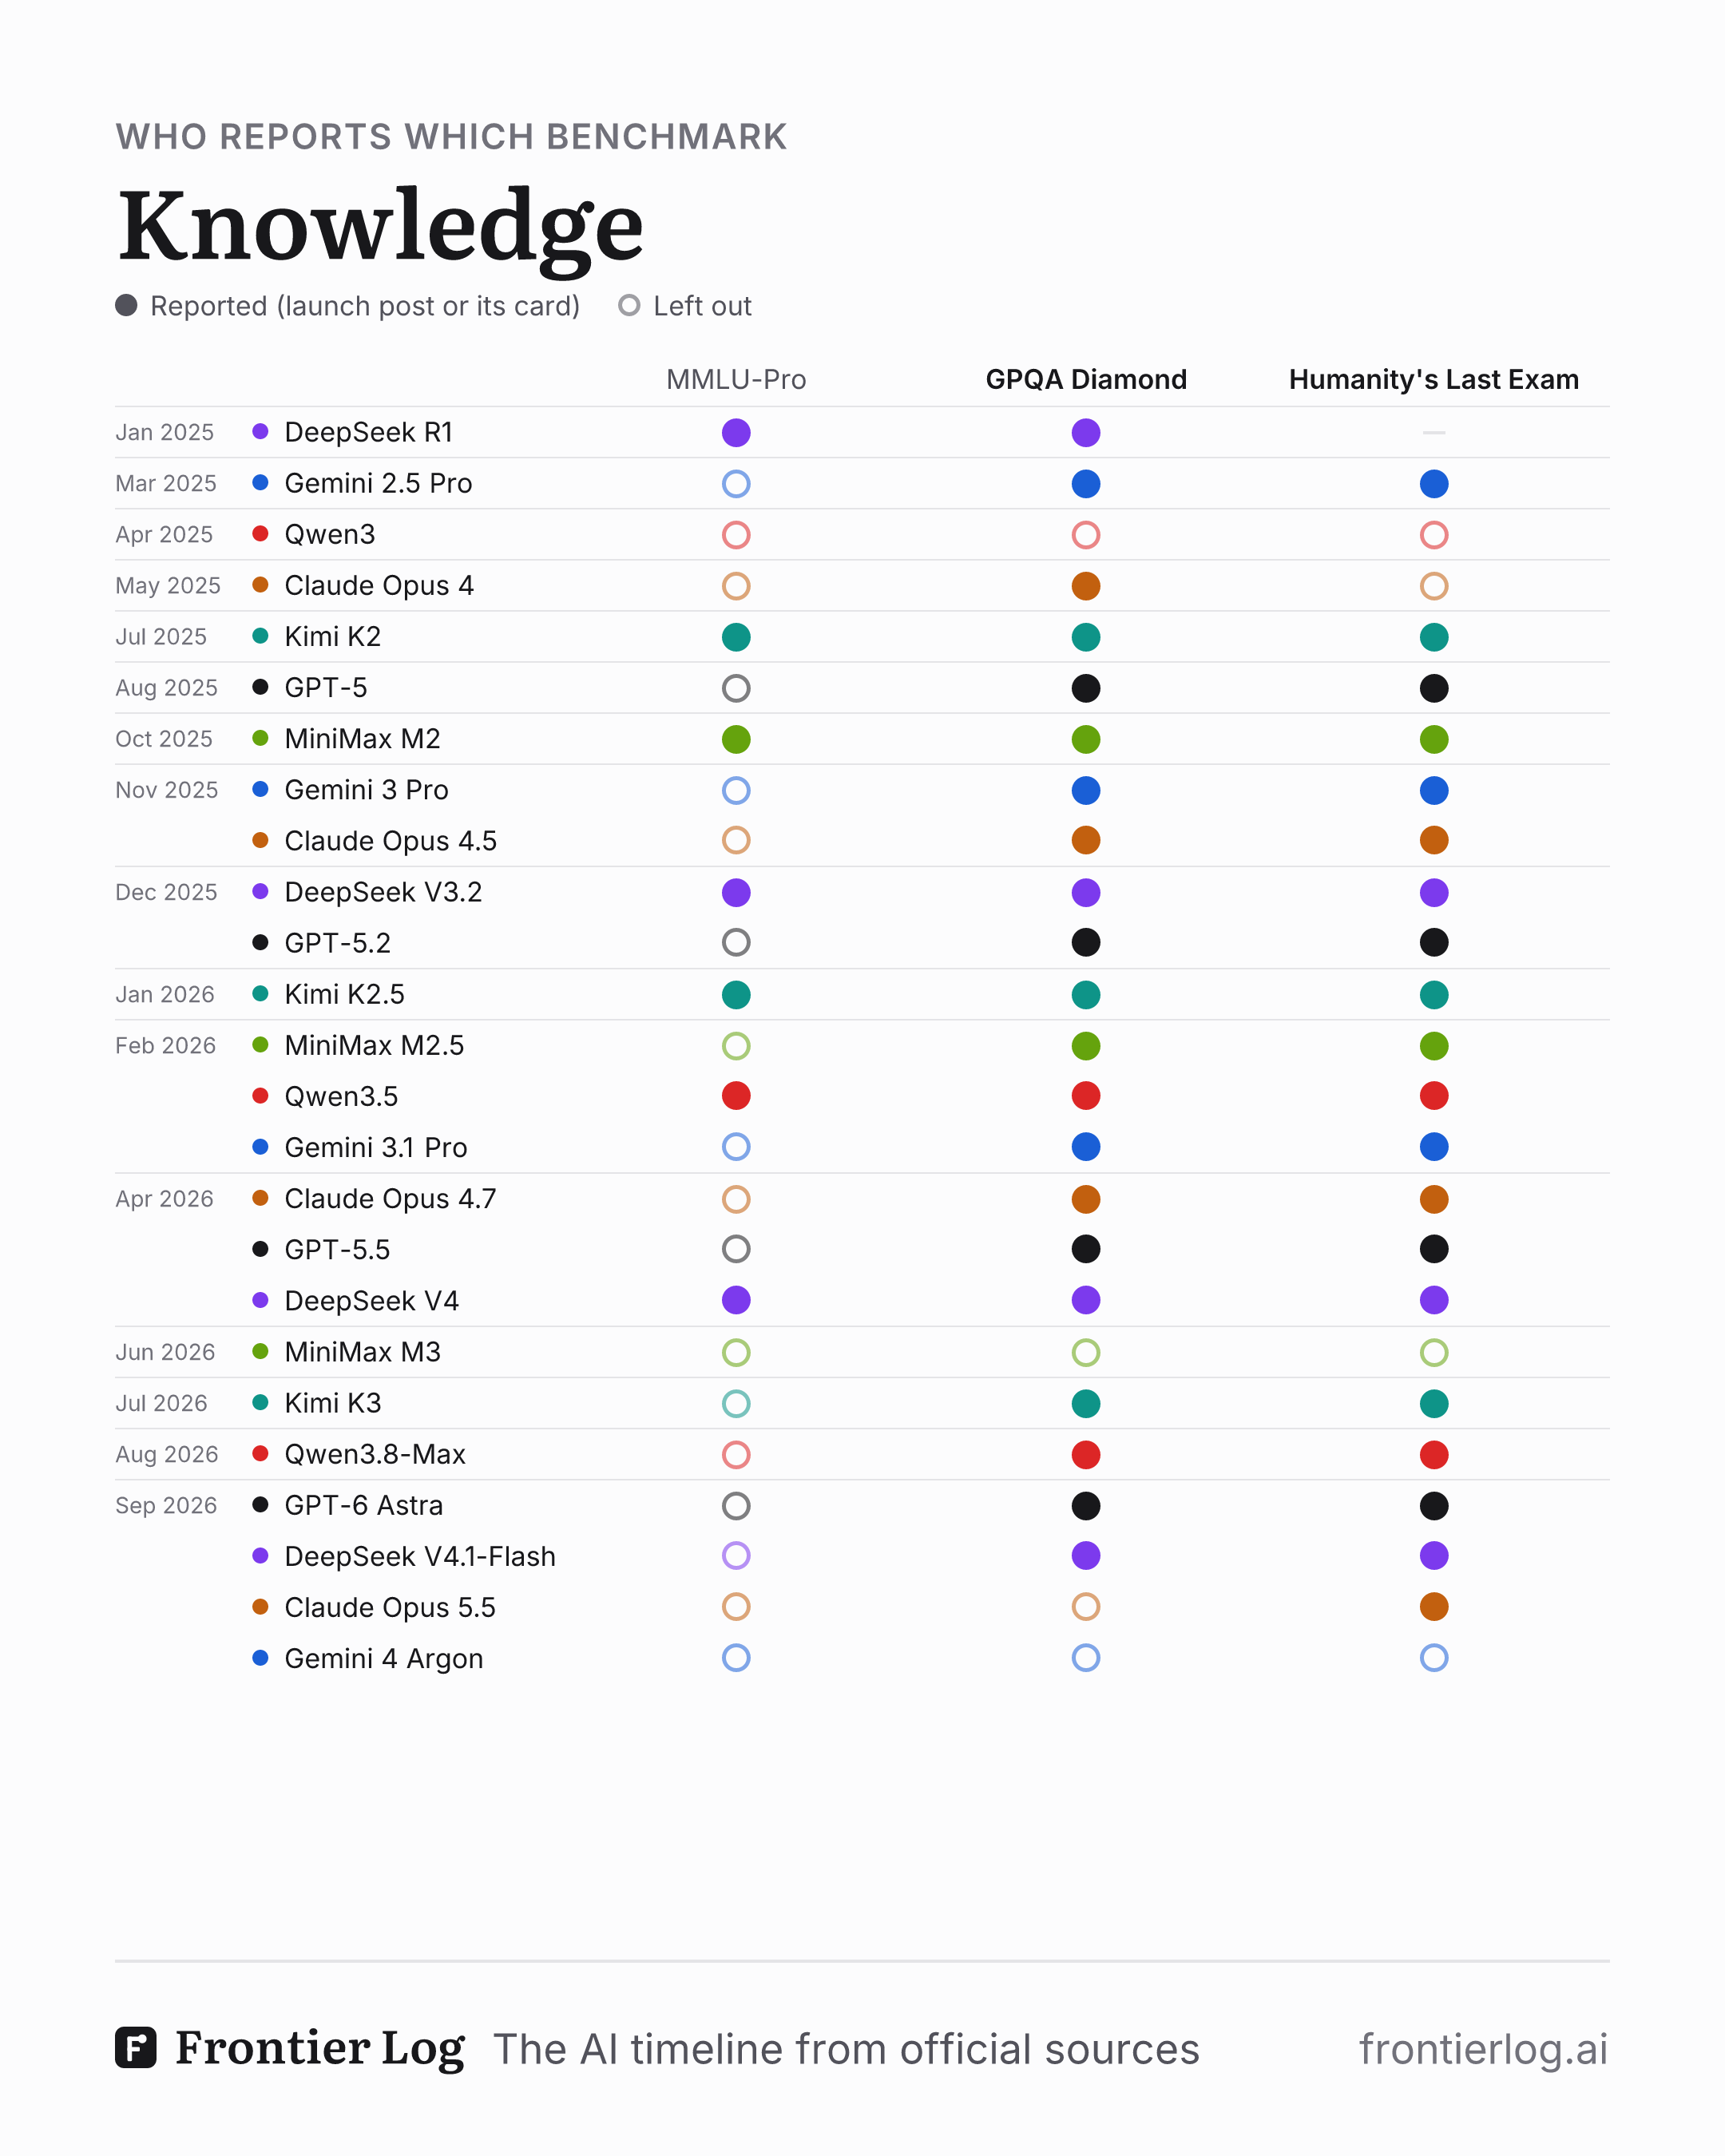
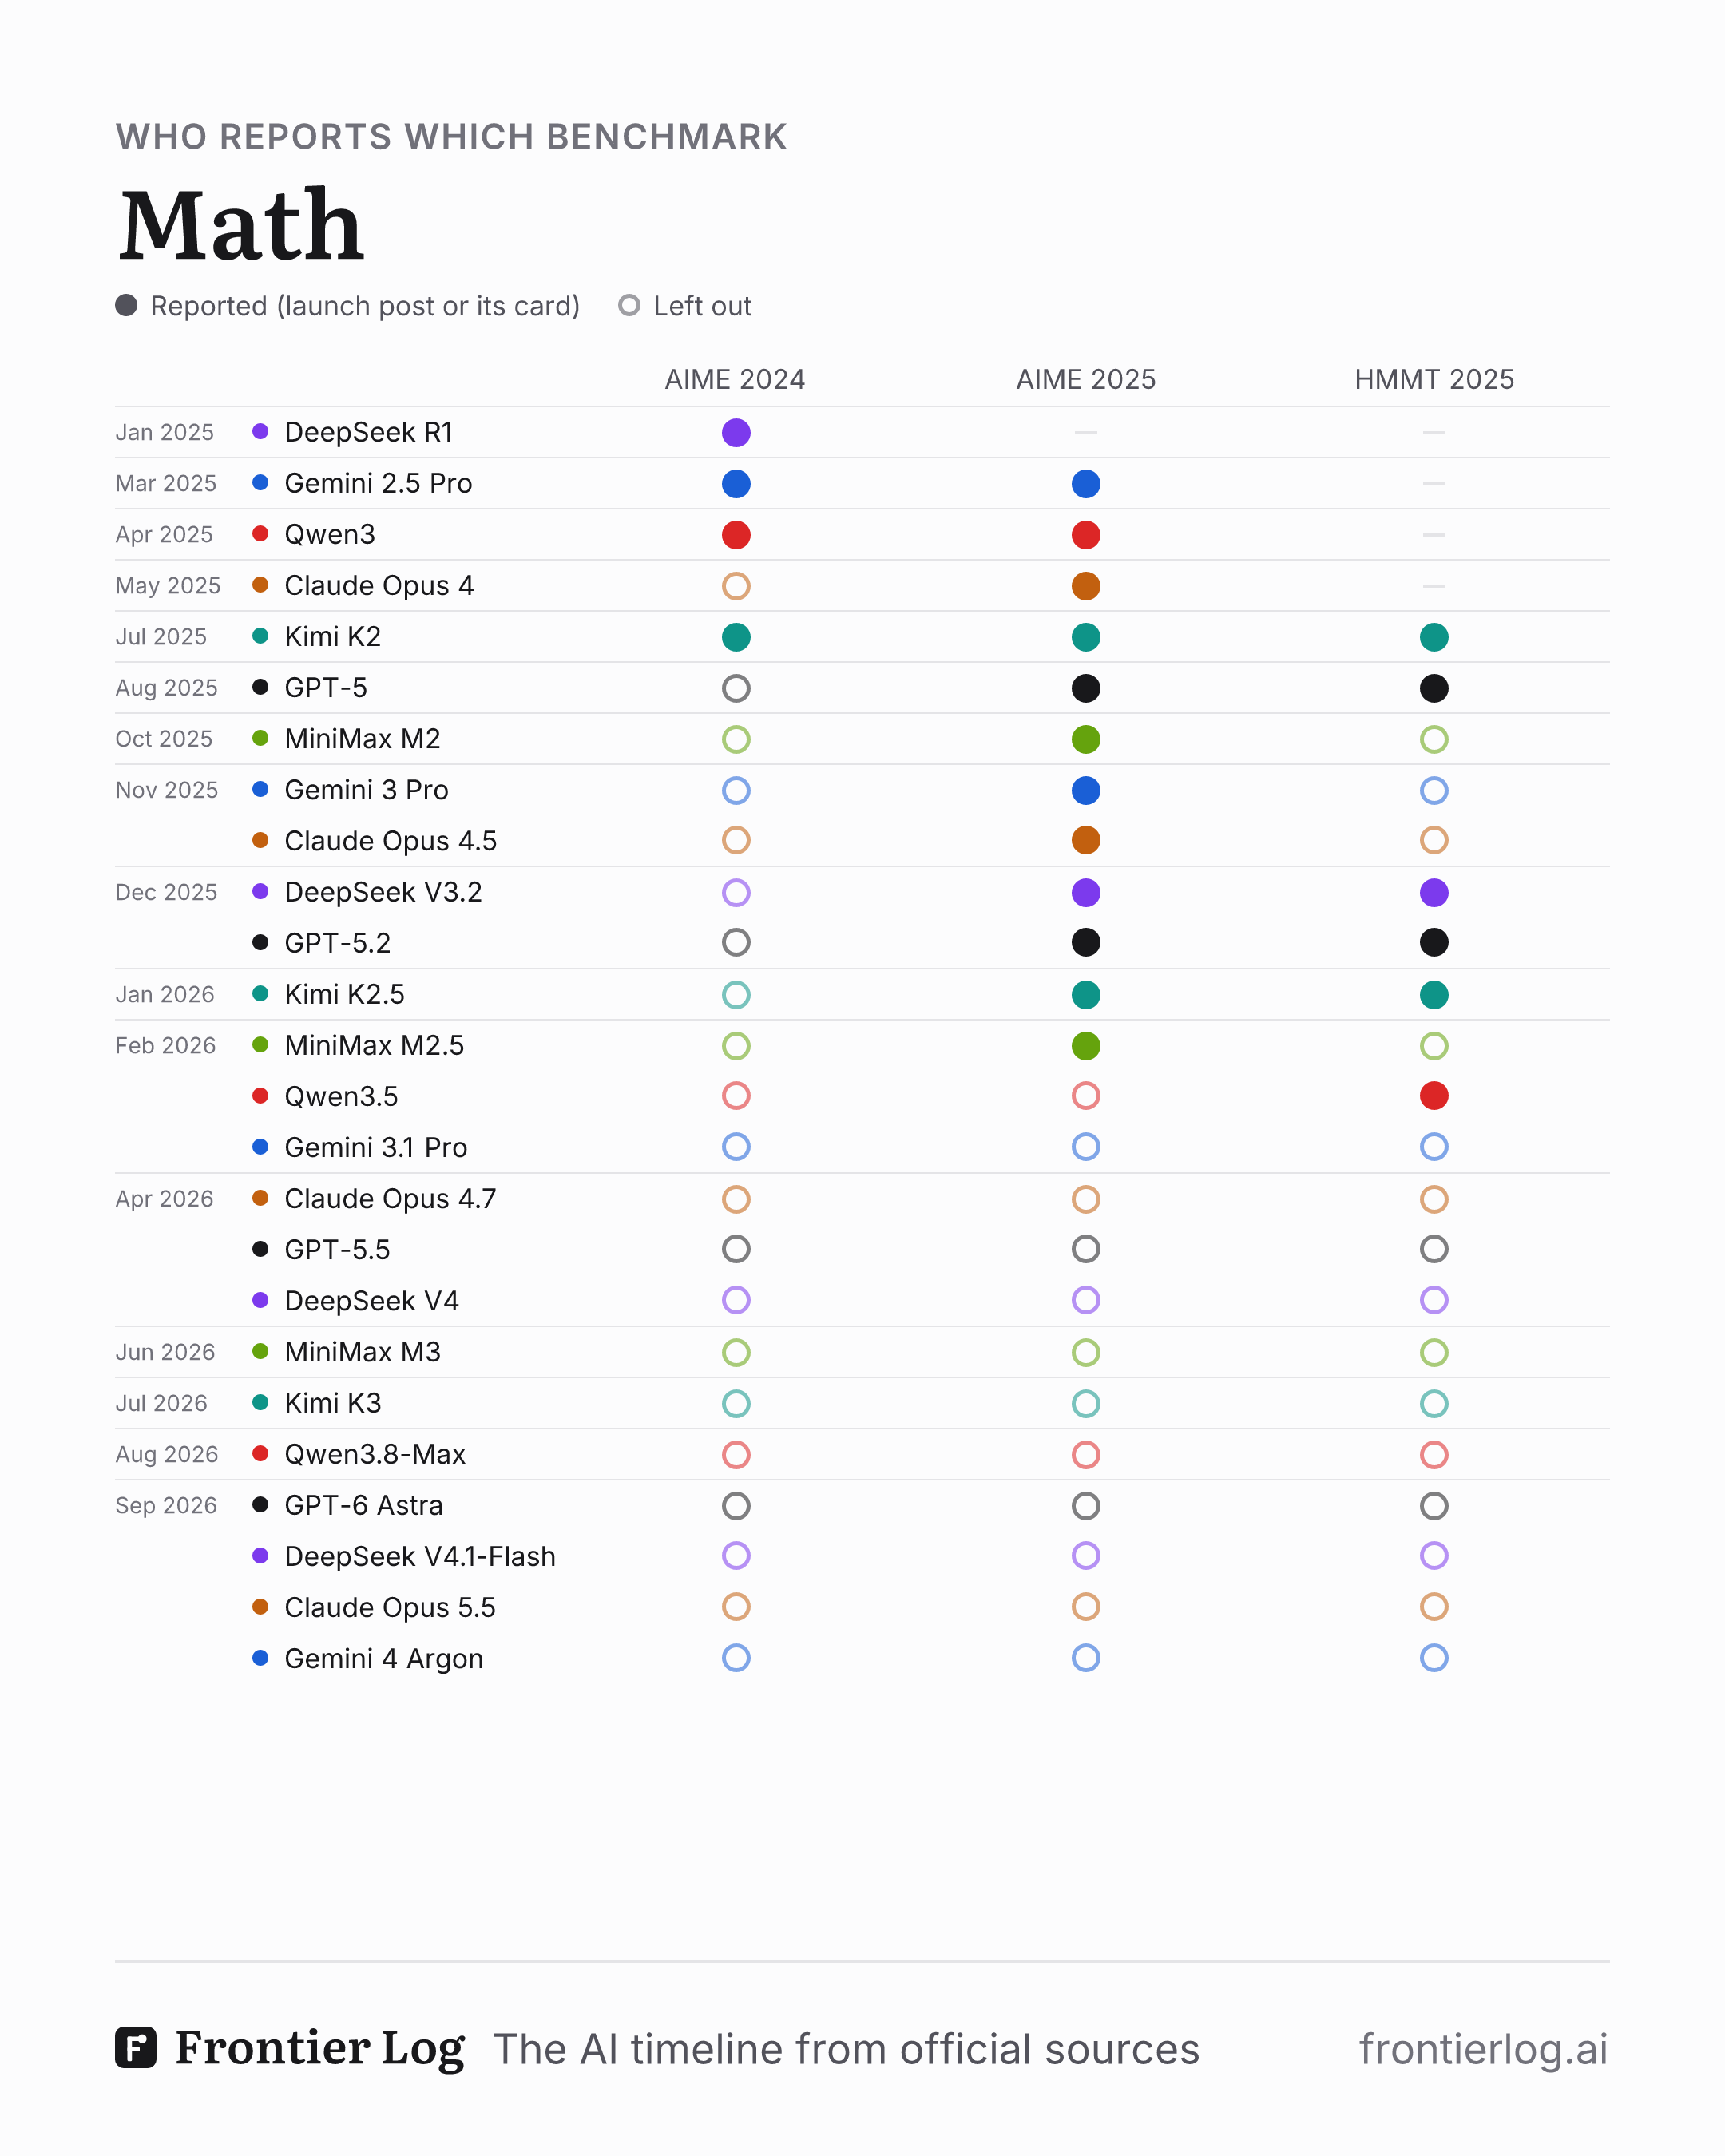
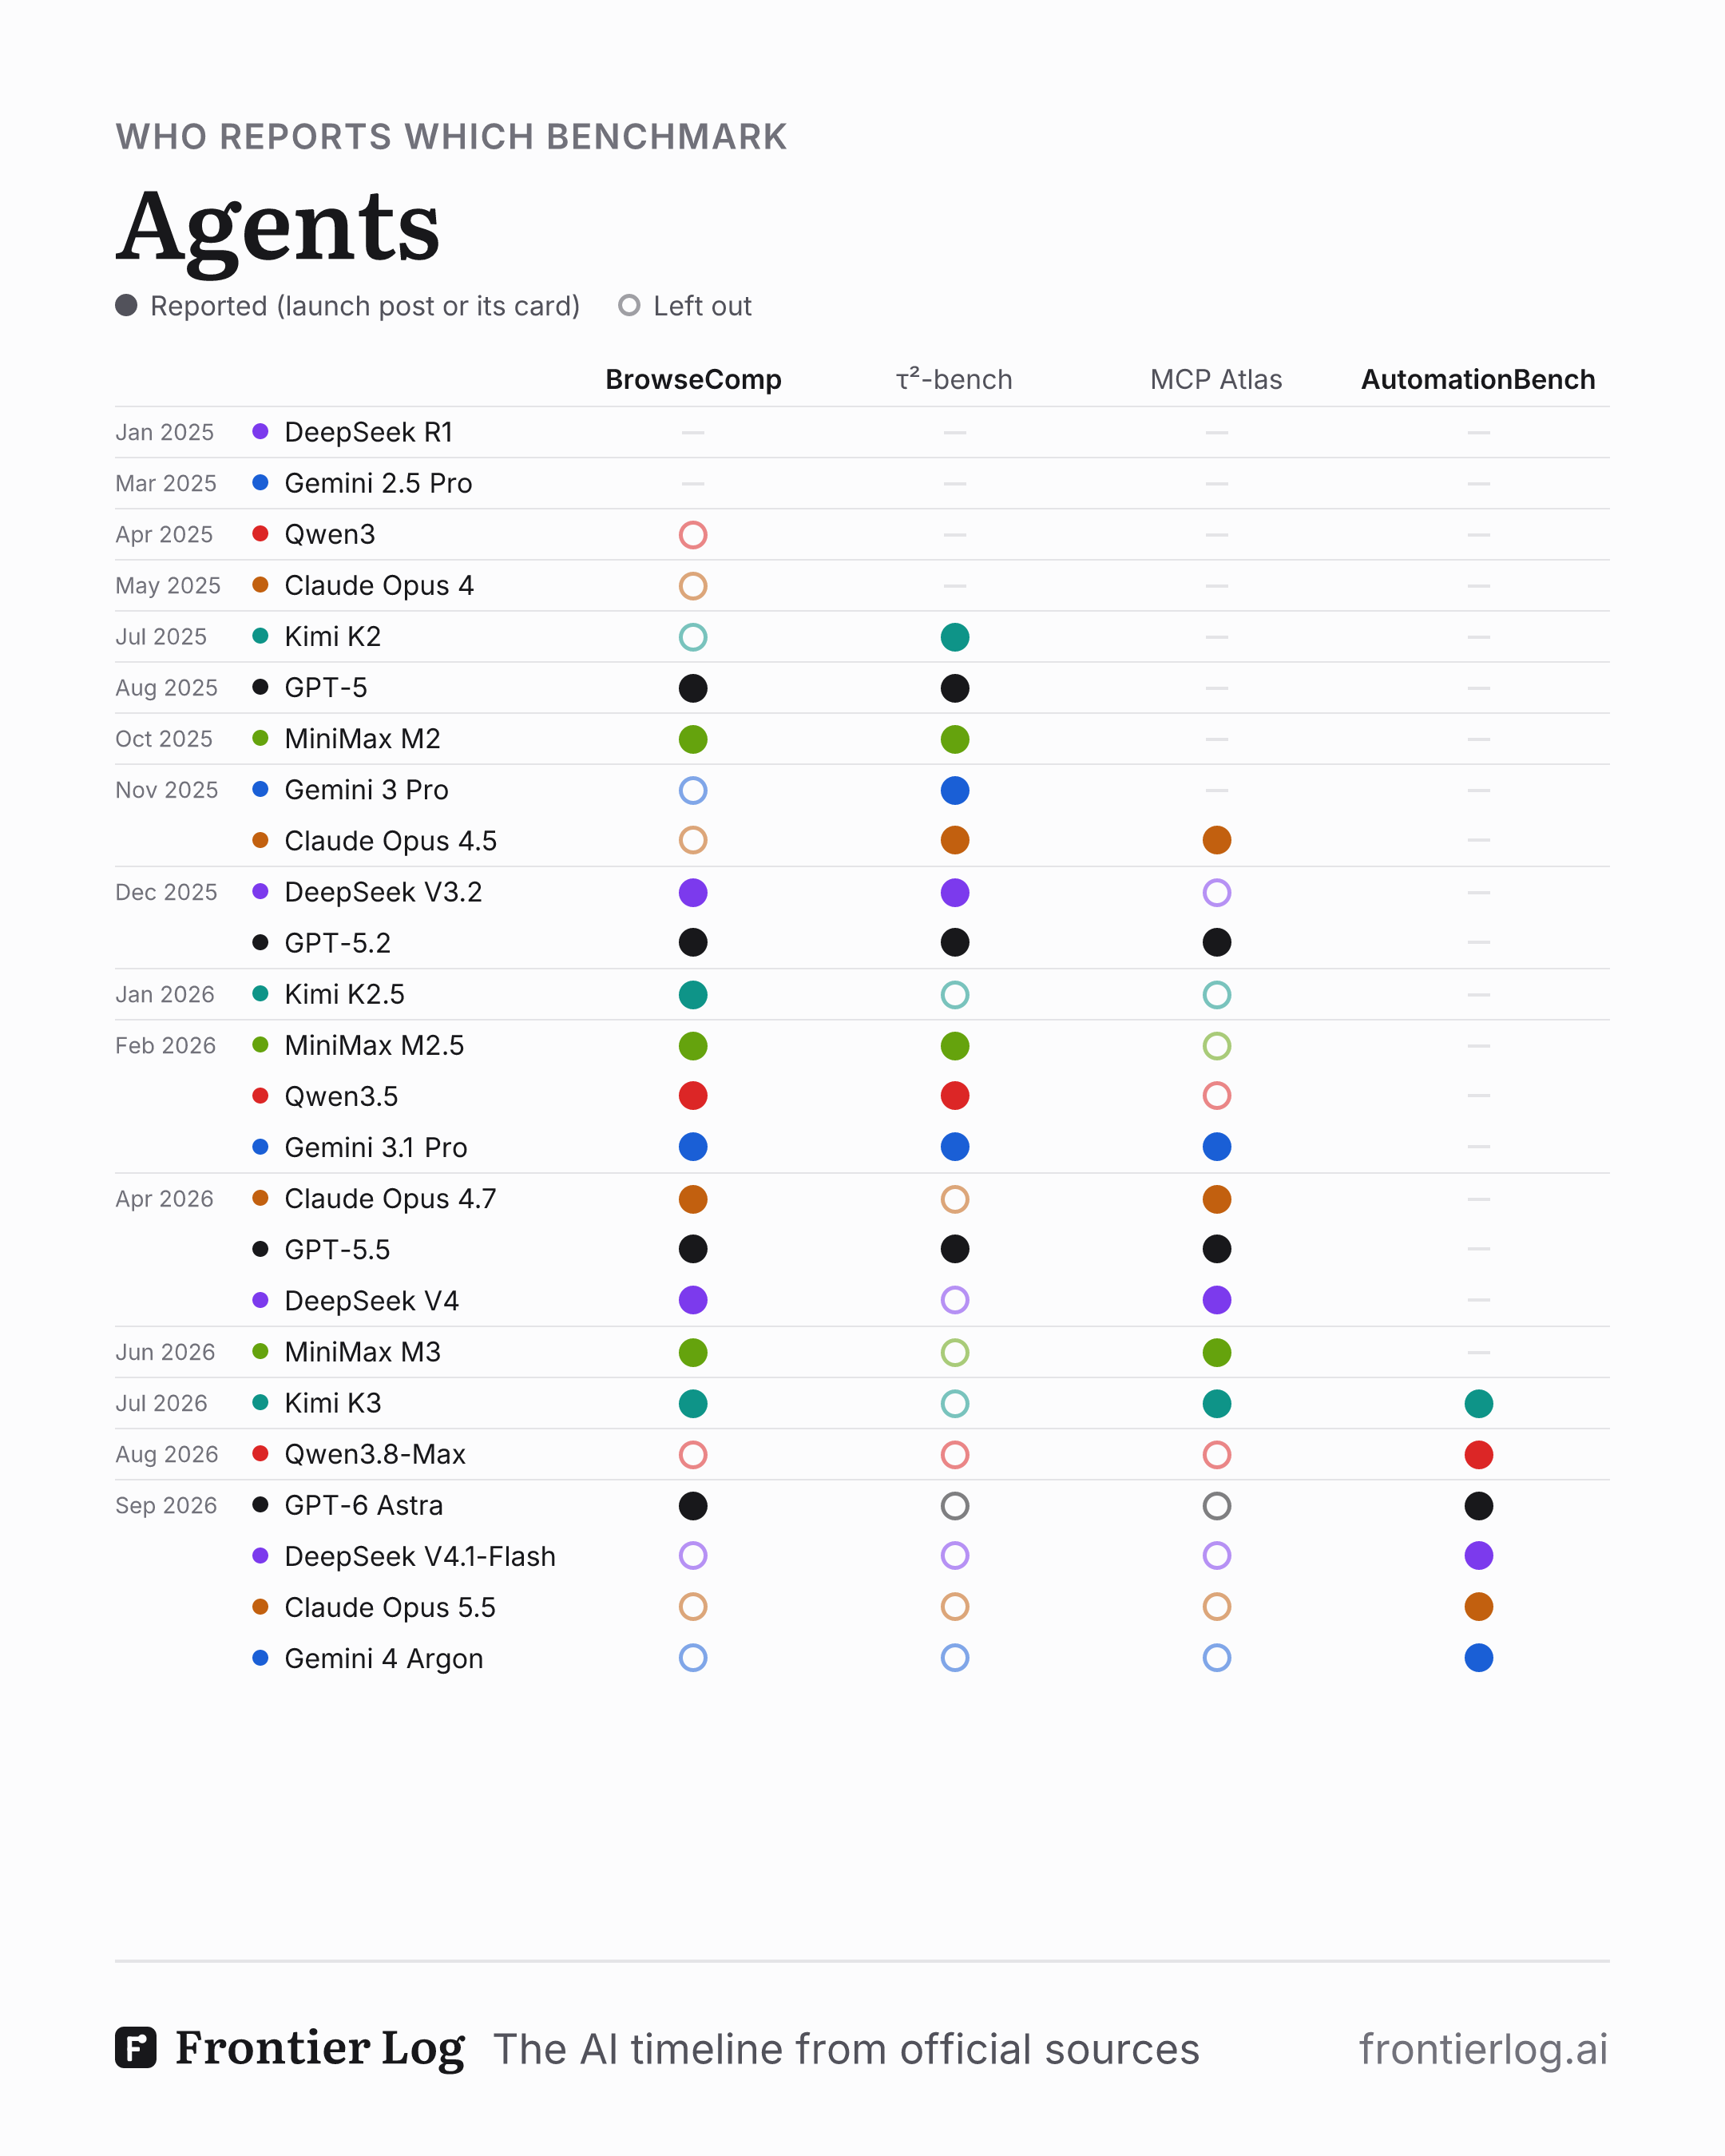
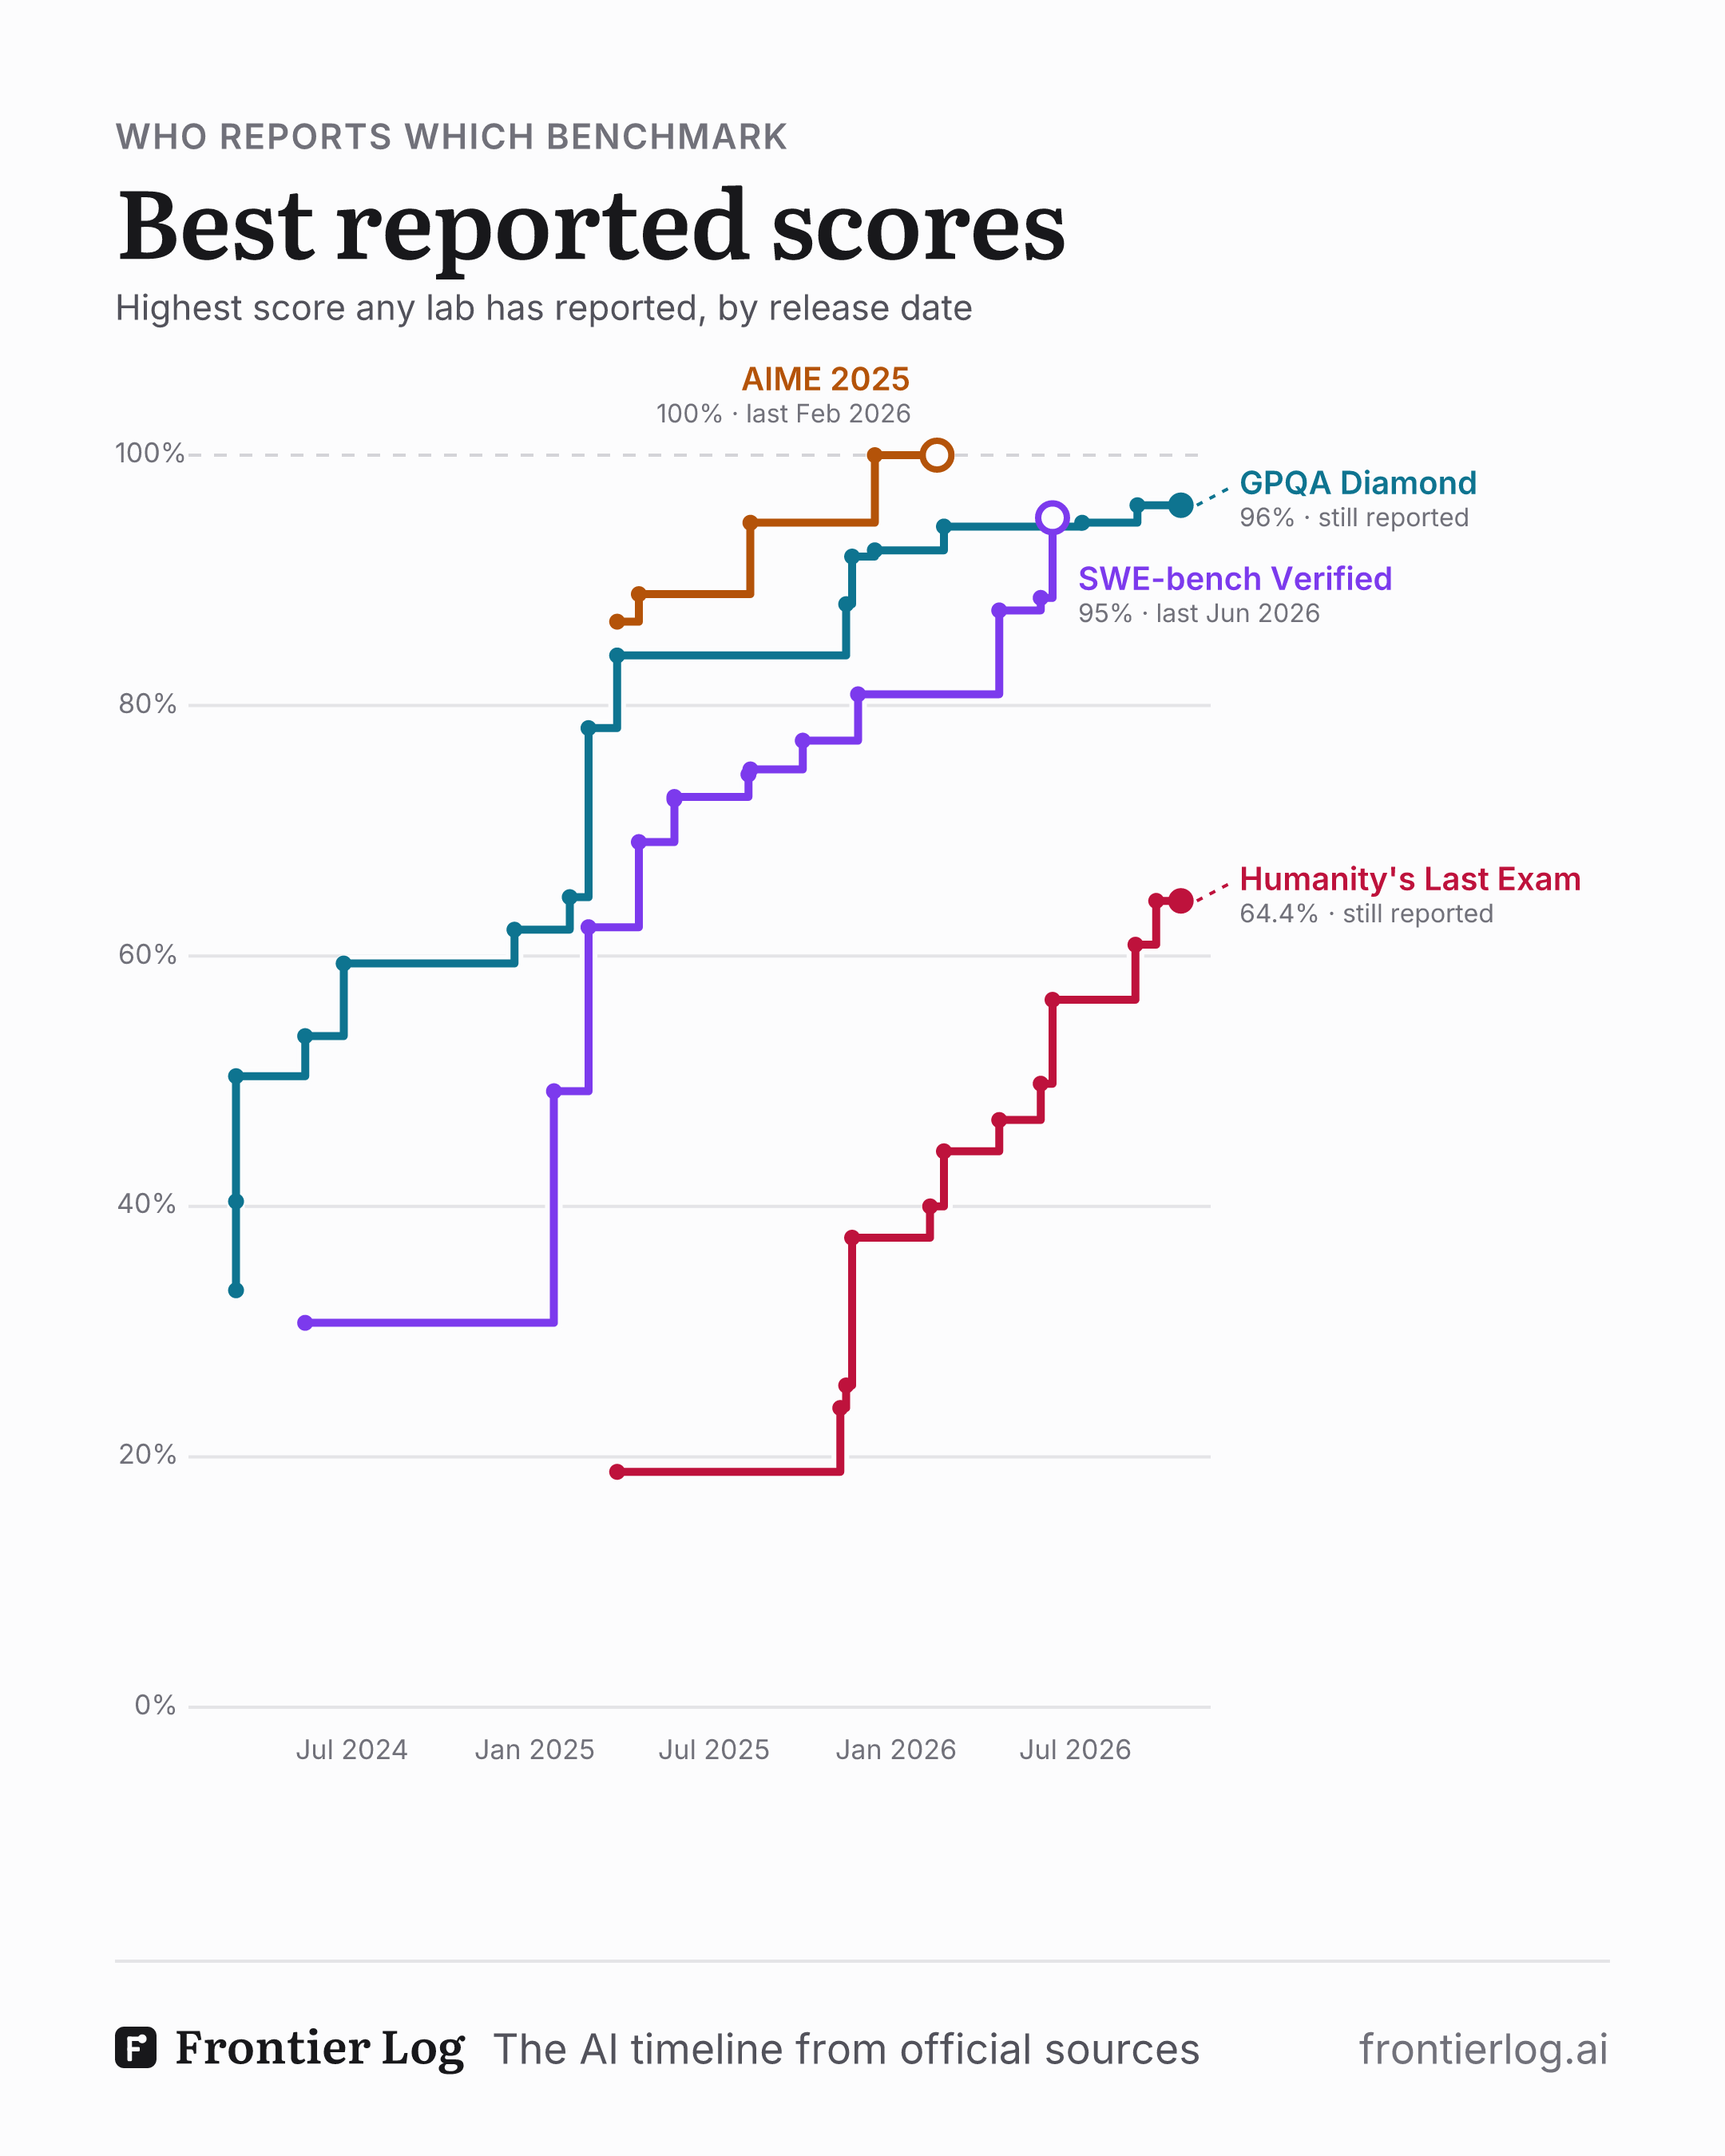
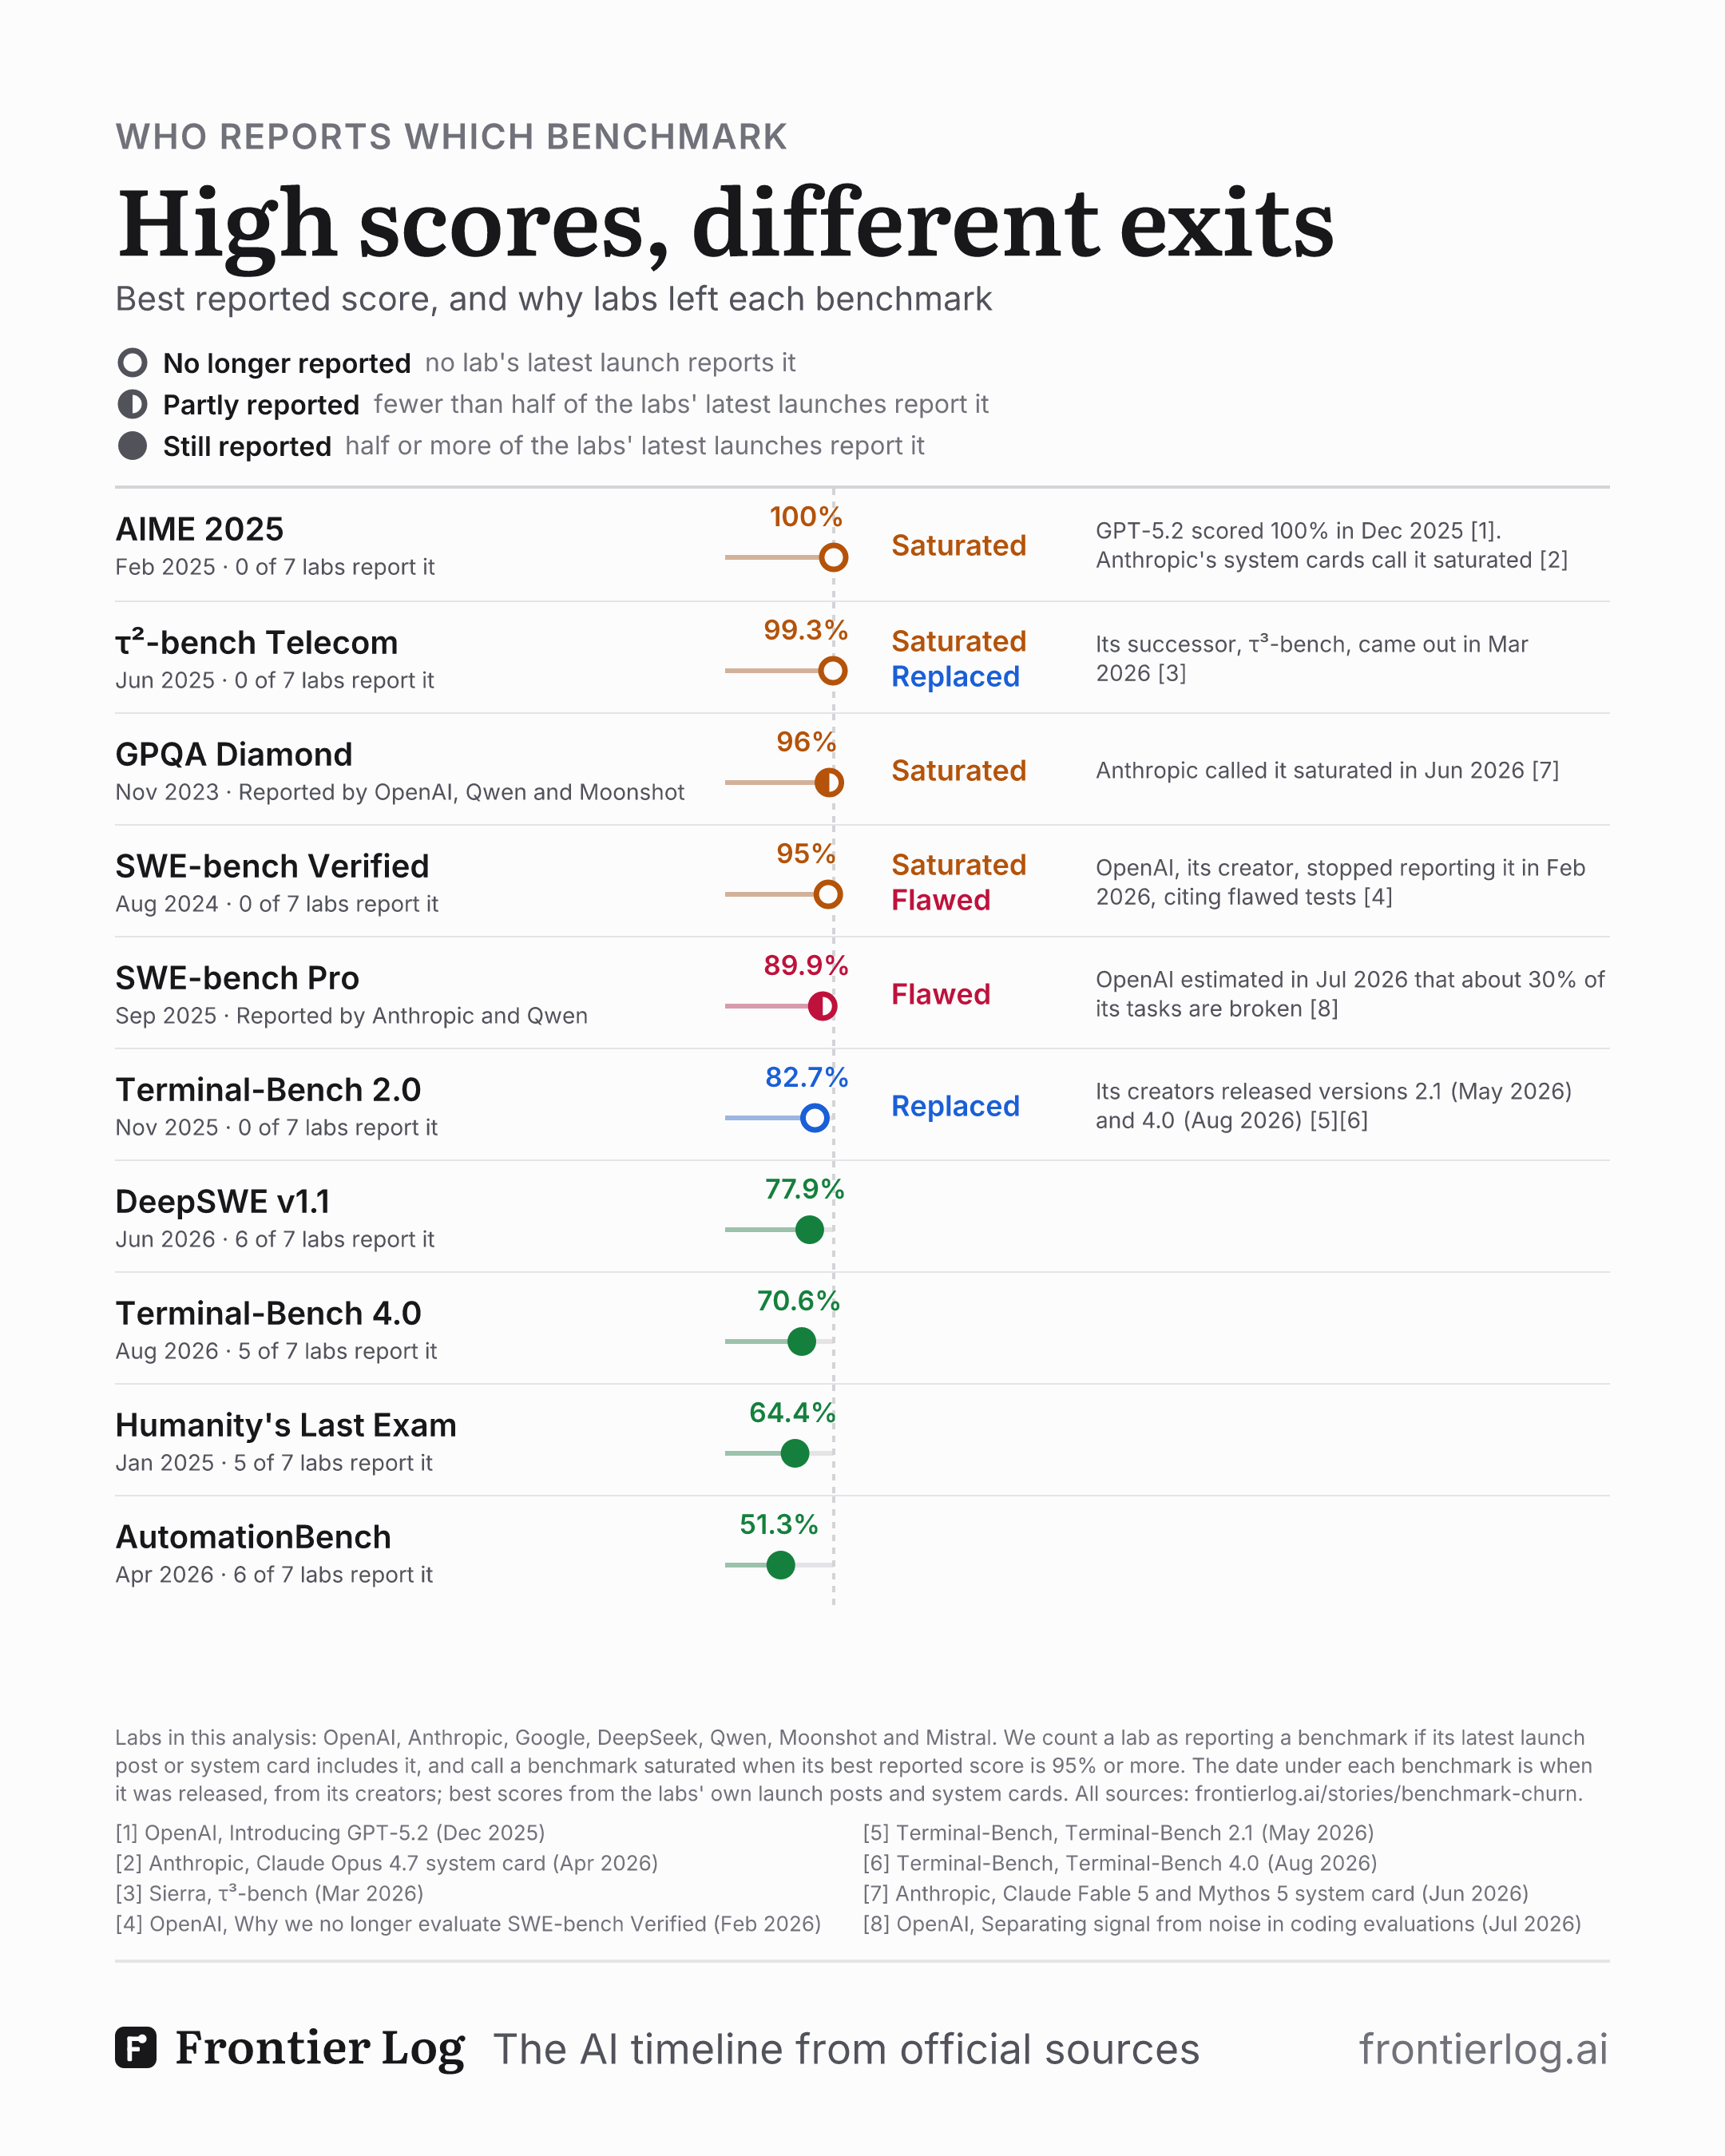
Why
| Benchmark | Best score | Best by |
|---|---|---|
| AIME 2025Released 12 Feb 2025 GPT-5.2 scored 100% in Dec 2025 [1] Anthropic's system cards call it saturated [2] | 100.0% | GPT-5.2 |
| τ²-bench TelecomReleased 9 Jun 2025 Its successor, τ³-bench, came out in Mar 2026 [3] | 99.3% | Claude Opus 4.6 |
| SWE-bench VerifiedReleased 13 Aug 2024 OpenAI, its creator, stopped reporting it in Feb 2026, citing flawed tests [4] | 95% | Claude Fable 5 and Mythos 5 |
| Terminal-Bench 2.0Released 7 Nov 2025 | 82.7% | GPT-5.5 |
| GPQA DiamondReleased 20 Nov 2023 Anthropic called it saturated in Jun 2026 [7] | 96.0% | GPT-6 Astra |
| SWE-bench ProReleased 19 Sep 2025 OpenAI estimated in Jul 2026 that about 30% of its tasks are broken [8] | 89.9% | Claude Opus 5.5 |
| DeepSWE v1.1Released 14 Jun 2026 | 77.9% | Gemini 4 Argon |
| Terminal-Bench 4.0Released 28 Aug 2026 | 70.6% | Claude Sonnet 5.5 |
| Humanity's Last ExamReleased 23 Jan 2025 | 64.4% | Claude Opus 5.5 |
| AutomationBenchReleased 20 Apr 2026 | 51.3% | Gemini 4 Argon |
Sources
- OpenAI, Introducing GPT-5.2 (Dec 2025)
- Anthropic, Claude Opus 4.7 system card (Apr 2026)
- Sierra, τ³-bench (Mar 2026)
- OpenAI, Why we no longer evaluate SWE-bench Verified (Feb 2026)
- Terminal-Bench, Terminal-Bench 2.1 (May 2026)
- Terminal-Bench, Terminal-Bench 4.0 (Aug 2026)
- Anthropic, Claude Fable 5 and Mythos 5 system card (Jun 2026)
- OpenAI, Separating signal from noise in coding evaluations (Jul 2026)
GPQA Diamond
SWE-bench Verified
AIME 2025
Humanity's Last Exam, no tools
SWE-bench Pro
| Model | Score | Sources |
|---|---|---|
| Claude Opus 5.5 | 89.9% | AnnouncementSection 8.1 Evaluation summary, Table 8.1.A, row 'SWE-bench Pro', column 'Claude Opus 5.5'The source doesn't say whether this is the public or the commercial set |
DeepSWE v1.1
| Model | Score | Sources |
|---|---|---|
| Gemini 4 Argon | 77.9% | Announcementbenchmark table (image), row 'DeepSWE v1.1', column 'Gemini 4 Argon' |
Terminal-Bench 2.0
| Model | Score | Sources |
|---|---|---|
| GPT-5.5 | 82.7% | Announcementheadline eval table (HTML, first table), row 'Terminal-Bench 2.0', column 'GPT‑5.5' |
Terminal-Bench 4.0
| Model | Score | Sources |
|---|---|---|
| Claude Sonnet 5.5 | 70.6% | Announcementbenchmark table, row 'Terminal-Bench 4.0', column 'Sonnet 5.5' |
τ²-bench Telecom
| Model | Score | Sources |
|---|---|---|
| Claude Opus 4.6 | 99.3% | Announcementbenchmark table (image), row 'Agentic tool use, τ2-bench', Telecom line, column 'Opus 4.6' |
AutomationBench
| Model | Score | Sources |
|---|---|---|
| Gemini 4 Argon | 51.3% | Announcementbenchmark table (image), row 'AutomationBench', 'Score', column 'Gemini 4 Argon' |
Launches
Gemini 4 Argon on the timeline