AI Labs Report One Benchmark Four Ways
From May 10 to Nov 10, 2026, labs reported Humanity's Last Exam, SWE-bench Pro and OSWorld 2.1 in four setups each, from task sets, scoring rules and tool use.
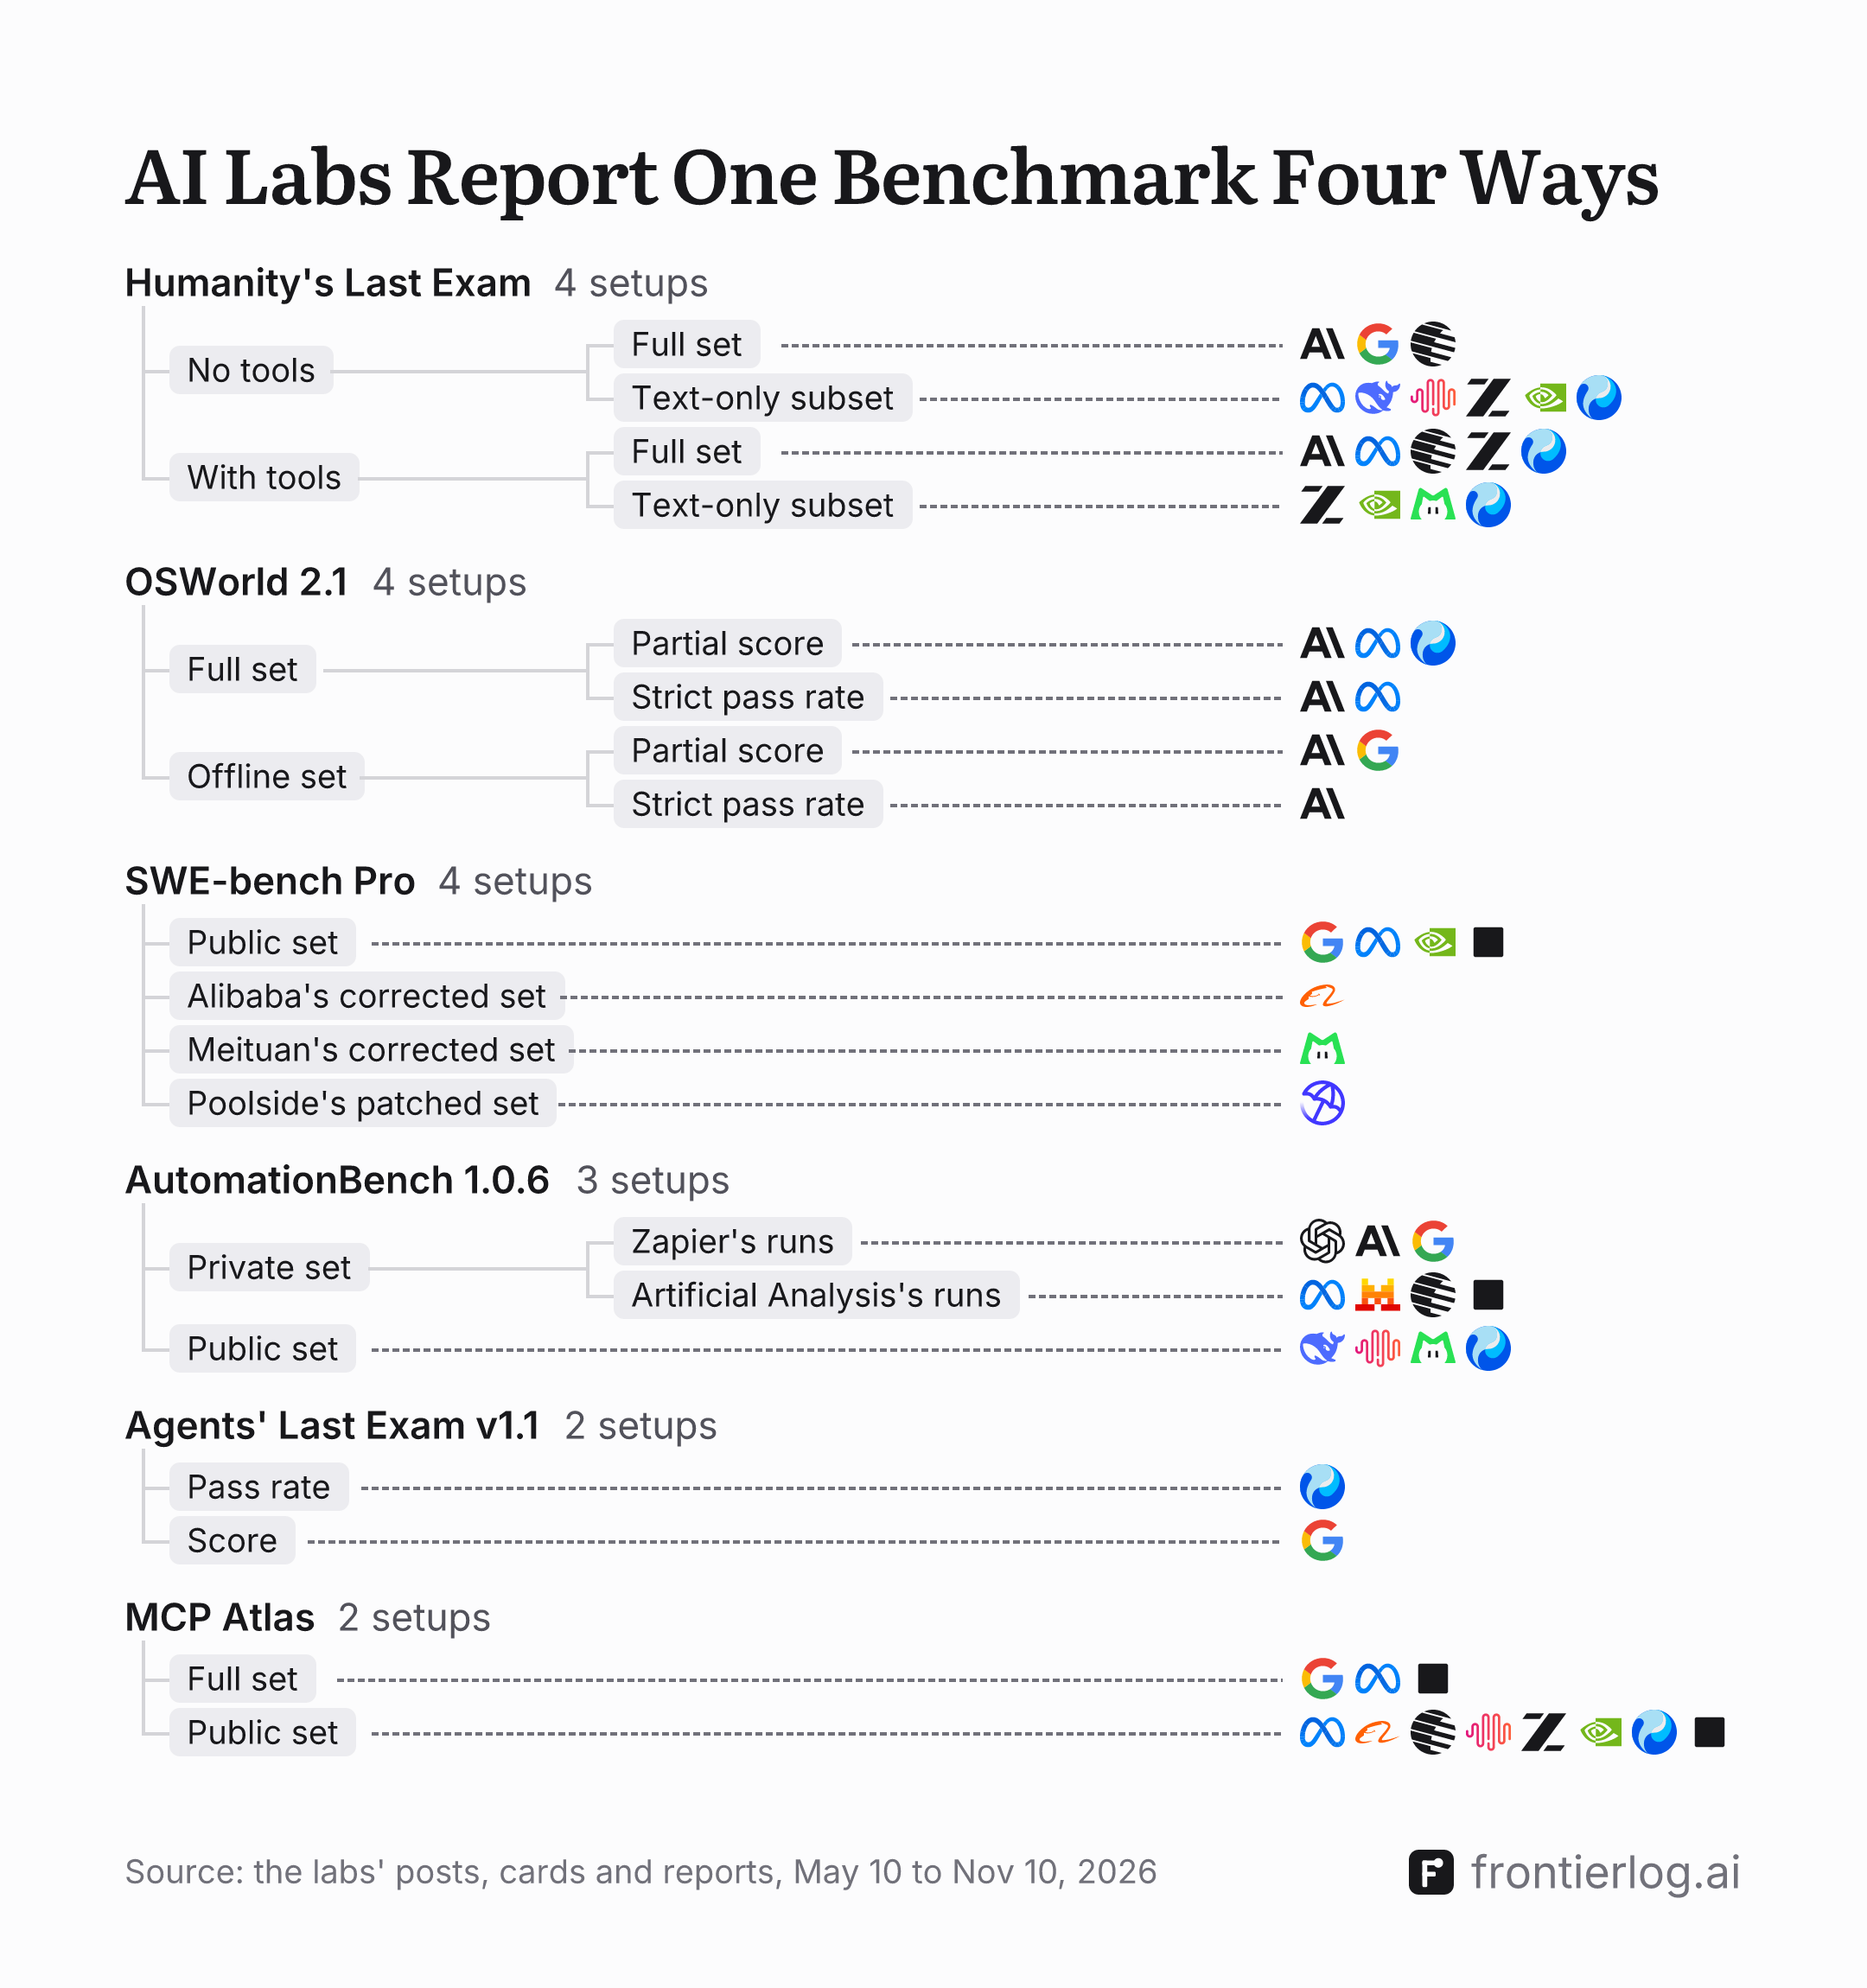
When labs report the same version of a benchmark, they often report it in different setups. In launch posts, model cards and technical reports from May 10 to Nov 10, 2026, 10 labs reported Humanity's Last Exam in four setups. They ran it with tools or without, and ran each on the full set or on a text-only subset. Labs also reported SWE-bench Pro and OSWorld 2.1 in four setups each, AutomationBench 1.0.6 in three, and Agents' Last Exam v1.1 and MCP Atlas in two each.
Four setups on Humanity's Last Exam
Without tools, Anthropic, Google and Moonshot AI reported the full set. NVIDIA's report gives a full-set figure without saying whether it used tools, so the count leaves it out. Meta, DeepSeek, MiniMax, Z.ai, NVIDIA and Tencent reported the text-only subset.
With tools, Anthropic, Meta, Moonshot AI, Z.ai and Tencent reported the full set. Z.ai, NVIDIA, Meituan and Tencent reported the text-only subset.
Three labs ran their own SWE-bench Pro sets
On SWE-bench Pro, Google, Meta, NVIDIA and Thinking Machines reported the public set of 731 tasks. Alibaba, Meituan and Poolside each reported a set it had corrected or patched itself.
Task sets and scoring on agent tests
OSWorld 2.1 runs on its full set or on an offline set, and each can be scored with a partial score or a strict pass rate. Anthropic reported all four setups, the full set in its Claude Sonnet 5.5 system card and the offline set in its Claude Fable 5.2 system card. Meta reported both scores on the full set, and Tencent reported the partial score. Google reported only the partial score on the offline set. OpenAI's GPT-6.1 Terra post charts the offline set without naming the scoring, so the count leaves it out. An earlier story set out these OSWorld setups model by model.
On AutomationBench 1.0.6, OpenAI, Anthropic and Google printed Zapier's own runs on its private set. That set has 657 tasks, Anthropic's Claude Fable 5.2 system card says. Meta, Mistral, Moonshot AI and Thinking Machines printed Artificial Analysis's runs, on what its methodology calls a private 657-task split of release 1.0.6. Artificial Analysis gives each task "the percentage of objectives the model completed", unless the model breaks a guardrail, its methodology says. DeepSeek, MiniMax, Meituan and Tencent reported the public set. A separate story covers who runs AutomationBench.
On Agents' Last Exam v1.1, Tencent gave a pass rate and Google gave a score. Tencent's post doesn't name the task set. Google's evaluation document says its figures are "self-computed on the 122-task v1.1 benchmark".
Two sizes of MCP Atlas
On MCP Atlas, Google, Meta and Thinking Machines reported the full set of 1,000 tasks. Eight labs reported the public set of 500 tasks, among them Alibaba, MiniMax and Tencent. Meta and Thinking Machines printed figures on both.
How the setups were counted
The count takes every result the site records from the labs' own launch posts, model cards and technical reports dated May 10 to Nov 10, 2026, on the latest version of each benchmark. Each result counts once, for the lab that published the document the site records as its source. That document may give figures for other labs' models. A setup is the task set and the scoring rule or measure that the document, the methodology it cites or another of the lab's documents names. Results whose documents don't name the set, the scoring or the measure are left out. Earlier versions, such as OSWorld 2.0 and earlier AutomationBench releases, are left out too. Other settings change a score as well, such as the agent harness and the effort setting, and the image leaves them out. An earlier story measured how much the harness version moves a score.
Humanity's Last Exam, no tools, full set
| Model | Score | Sources |
|---|---|---|
| Gemini 3.5 FlashGemini 3.5 Flash, reported by Google | 40.2% | Announcementbenchmark table (image), row 'Reasoning, Humanity's Last Exam', column 'Gemini 3.5 Flash' |
| Kimi K3.1 ProKimi K3.1 Pro, reported by Moonshot AI | 51.1% | Announcement'Benchmarks' table (rendered by the page's script), section 'Reasoning & Knowledge & Multimodal', row 'HLE-Full', column 'Kimi K3.1 Pro (max)' |
| Claude Fable 5.2Claude Fable 5.2, reported by Anthropic | 73.2% | Claude Fable 5.2 and Claude Mythos 5.2 System CardSection 8.1 Evaluation summary, Table 8.1.A, row 'Humanity's Last Exam, No tools', column 'Fable 5.2' |
Humanity's Last Exam, no tools, text-only subset
Humanity's Last Exam, with tools, full set
| Model | Score | Sources |
|---|---|---|
| Muse Spark 1.1Muse Spark 1.1, reported by Meta | 62.1% | Announcementbenchmark table (image), row 'Humanity's Last Exam (w/ tools)', column 'Muse Spark 1.1' |
| GLM-5.3-FlashGLM-5.3-Flash, reported by Z.ai | 55.3% | Announcementmain benchmark table (second table), AGENTIC block, row 'HLE w/ Tools', column 'GLM-5.3-Flash' |
| Kimi K3.1 ProKimi K3.1 Pro, reported by Moonshot AI | 70.0% | Announcement'Benchmarks' table (rendered by the page's script), section 'Agentic', row 'HLE-Full w/ tools', column 'Kimi K3.1 Pro (max)' |
| Hy4Hy4, reported by Tencent | 59.1% | Announcement'Appendix: benchmark results' table image, row 'HLE-Full (with tools)', column 'Hy4' |
| Claude Fable 5.2Claude Fable 5.2, reported by Anthropic | 74.2% | Announcementbenchmark table (HTML), row 'Multidisciplinary reasoning, Humanity's Last Exam (with tools)', column 'Fable 5.2' |
Humanity's Last Exam, with tools, text-only subset
| Model | Score | Sources |
|---|---|---|
| GLM-5.2GLM-5.2, reported by Z.ai | 54.7% | Announcement'Full Benchmark Table', row 'HLE w/ Tools', column 'GLM-5.2' |
| Hy4 previewHy4 preview, reported by Tencent | 55.4% | Announcement'Appendix: Benchmark Results' table image, row 'HLE (with tools, text-only)', column 'Hy4 preview' |
| Nemotron 3.5 Super VL 120B-A12BNemotron 3.5 Super VL 120B-A12B, reported by NVIDIA | 46.01% | Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AITable 10 (PDF page 23), row 'HLE (with tools, text)', column 'N3.5-Super 120B-A12B' (first column) |
| LongCat-2.5LongCat-2.5, reported by Meituan | 63.1% | Announcement'Evaluations' section table at the end of the post (rendered by the page's script; load https://longcat.ai/blog/longcat-2.5 in a browser and scroll to the end), row 'HLE w/tools' under 'General Agent', column 'LongCat-2.5' |
OSWorld 2.1, full set, partial score
| Model | Score | Sources |
|---|---|---|
| Claude Sonnet 5.5Claude Sonnet 5.5, reported by Anthropic | 80.1% | Announcementbenchmark table (HTML), row 'Computer use / OSWorld 2.1', column 'Sonnet 5.5', the value tagged 'partial' |
| Hy4Hy4, reported by Tencent | 78.9% | Announcement'Appendix: benchmark results' table image, row 'OSWorld 2.1 (Full, partial score)', column 'Hy4' |
| Muse EmberMuse Ember, reported by Meta | 69.5% | Announcement'Muse Ember evaluation results' table (HTML), row 'Multimodal / OSWorld 2.1', column 'Muse Ember (max)', the value marked '(partial)' |
OSWorld 2.1, full set, strict pass rate
| Model | Score | Sources |
|---|---|---|
| Claude Sonnet 5.5Claude Sonnet 5.5, reported by Anthropic | 43.5% | Claude Sonnet 5.5 System Cardsection 8.13.3 OSWorld 2.1, text (PDF page 130), the Claude Sonnet 5.5 strict pass rate |
| Muse EmberMuse Ember, reported by Meta | 33.8% | Announcement'Muse Ember evaluation results' table (HTML), row 'Multimodal / OSWorld 2.1', column 'Muse Ember (max)', the value marked '(binary)' |
OSWorld 2.1, offline set, partial score
| Model | Score | Sources |
|---|---|---|
| Claude Fable 5.1Claude Fable 5.1, reported by Anthropic | 83.5% | Introducing Claude Fable 5.2 and Claude Mythos 5.2benchmark table (HTML), row 'Computer use, OSWorld 2.1 (offline set, partial)', column 'Fable 5.1' |
| Gemini 4 ArgonGemini 4 Argon, reported by Google | 74.7% | Gemini 4 Carbon: our next frontier modellater report: Gemini 4 Carbon post, benchmark table (image), row 'OSWorld-2.1', 'Offline subset', column 'Gemini 4 Argon' |
OSWorld 2.1, offline set, strict pass rate
| Model | Score | Sources |
|---|---|---|
| Claude Fable 5.1Claude Fable 5.1, reported by Anthropic | 47.6% | Claude Fable 5.2 and Claude Mythos 5.2 System CardSection 8.13.3 'OSWorld 2.1 offline set', paragraph after the setup, the sentence on models re-evaluated under the same conditions, Claude Fable 5.1's strict pass rate |
SWE-bench Pro, public set (731 tasks)
| Model | Score | Sources |
|---|---|---|
| InklingInkling, reported by Thinking Machines | 54.3% | Announcementsection 'Benchmarking Inkling', main benchmark table, row 'SWEBench Pro' with subtitle 'Public' (Agentic (coding)), column 'Inkling effort=0.99' (the Inkling vs Inkling-Small table later prints the same value) |
| Gemini 3.5 Flash-LiteGemini 3.5 Flash-Lite, reported by Google | 54.2% | Announcementchart 'Gemini 3.5 Flash-Lite, Compared to 3 Flash' (image), panel 'Agentic Software Engineering Tasks, SWE-Bench Pro (Public)', bar '3.5 Flash-Lite' value label |
| Muse Glimmer 30BMuse Glimmer 30B, reported by Meta | 51.2% | Muse Glimmer: an open-weight model built for local agentsbenchmark table (image), row 'SWE-Bench Pro', column 'Muse Glimmer-30B, High Reasoning' |
| Nemotron 3.5 Super VL 120B-A12BNemotron 3.5 Super VL 120B-A12B, reported by NVIDIA | 49.45% | nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4 model card (launch-day revision)'Agentic Coding Benchmarks' image, 'SWE-Bench Pro' panel, value label of the 'Claude Code' bar |
SWE-bench Pro, Alibaba's corrected set
| Model | Score | Sources |
|---|---|---|
| Qwen3.8-Omni-FlashQwen3.8-Omni-Flash, reported by Alibaba | 63.3% | Announcementtext benchmark table (Coding and Agent block), row 'SWE-bench Pro', column 'Qwen3.8-Omni-Flash' |
SWE-bench Pro, Meituan's corrected set
| Model | Score | Sources |
|---|---|---|
| LongCat-2.0LongCat-2.0, reported by Meituan | 59.5% | Announcement'Evaluations' section table (rendered by the page's script; load it in a browser), row 'SWE-bench Pro' under 'CODE AGENT', column 'LongCat-2.0' |
SWE-bench Pro, Poolside's patched set
| Model | Score | Sources |
|---|---|---|
| Laguna XS 2.1Laguna XS 2.1, reported by Poolside | 47.6% | Announcementevaluation chart 'SWE-Bench Pro' (Resolved tasks on SWE-Bench Pro), bar 'Laguna XS 2.1 (33B-A3B)', value label (animates up from 0.0 when scrolled into view; also in the bar's aria-label) |
AutomationBench 1.0.6, private set, Zapier's runs
| Model | Score | Sources |
|---|---|---|
| GPT-6.1 SolGPT-6.1 Sol, reported by OpenAI | 36.1% | AnnouncementAutomationBench chart under "Professional work" (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point) |
| Gemini 4 CarbonGemini 4 Carbon, reported by Google | 53.9% | Announcementbenchmark table (image), row 'AutomationBench', 'Zapier', column 'Gemini 4 Carbon' |
| Claude Fable 5.2Claude Fable 5.2, reported by Anthropic | 51.4% | Announcementbenchmark table (HTML), row 'Business workflows, AutomationBench', column 'Fable 5.2' |
AutomationBench 1.0.6, private set, Artificial Analysis's runs
AutomationBench 1.0.6, public set
Agents' Last Exam v1.1, pass rate
| Model | Score | Sources |
|---|---|---|
| Hy4Hy4, reported by Tencent | 41.0% | Announcement'Appendix: benchmark results' table image, row 'Agents' Last Exam v1.1 (Pass Rate)', column 'Hy4' |
Agents' Last Exam v1.1, score
| Model | Score | Sources |
|---|---|---|
| Gemini 4 ArgonGemini 4 Argon, reported by Google | 69.0% | Gemini 4 Carbon: our next frontier modellater report: Gemini 4 Carbon post, benchmark table (image), row 'Agents' Last Exam v1.1', 'Score', column 'Gemini 4 Argon' |
MCP Atlas, full set (1,000 tasks)
| Model | Score | Sources |
|---|---|---|
| Gemini 3.5 FlashGemini 3.5 Flash, reported by Google | 83.6% | Announcementbenchmark table (image), row 'Agentic, MCP Atlas', column 'Gemini 3.5 Flash' |
| Muse Spark Open 816B-A42BMuse Spark Open 816B-A42B, reported by Meta | 89.2% | Introducing Muse Spark Open, The Most Capable US Open-Weight Model to Datescorecard (image), row 'MCP-Atlas', column 'Muse Spark Open (xhigh)' |
| Inkling 2 SmallInkling 2 Small, reported by Thinking Machines | 85.4% | Announcementsection 'Benchmarking Inkling 2 Small', main benchmark table, Search and Tools group, row 'MCP Atlas' (subtitle 'Full / Public'), column 'Inkling 2 Small' (first model column), first value in the cell (before the slash); runner: list of externally reported evals right after the main benchmark table, before 'Limitations' |
MCP Atlas, public set (500 tasks)
Sources
- Meta, Jul 9, 2026Introducing Muse Spark 1.1
- Meta, Jul 9, 2026Muse Spark 1.1 Evaluation Report
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Smarter, Faster, More Efficient
- DeepSeek, Oct 17, 2026DeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made Real
- artificialanalysis.aiartificialanalysis.ai/methodology/intelligence-benchmarking
- Google, May 19, 2026Gemini 3.5: frontier intelligence with action
- Google, Jul 21, 2026Introducing Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- Meta, Aug 12, 2026Muse Glimmer: an open-weight model built for local agents
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression
- NVIDIA, Oct 15, 2026nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4 model card (launch-day revision)
- Tencent, Nov 4, 2026Introducing Hy4
- Tencent, Aug 28, 2026Introducing Hy4 preview
- Meituan, Nov 1, 2026LongCat-2.5: Native Multimodality for Agentic Tasks
- Meituan, Jun 30, 2026Introducing LongCat-2.0
- Mistral, Oct 6, 2026Introducing Mistral Large 4
- OpenAI, Sep 29, 2026Introducing GPT-6.1 Sol
- OpenAI, Oct 26, 2026Introducing GPT-6.1 Terra
- Poolside, Jul 2, 2026Introducing Laguna XS 2.1
- Alibaba, Jun 1, 2026Qwen3.7-Plus: Multimodal Agent Intelligence
- Alibaba, Sep 18, 2026Qwen3.8-Omni-Flash: Omni Senses. Agentic Delivery.
- Meta, Aug 10, 2026Introducing Muse Glimmer: An Open Agentic Model That Runs on Your Device
- Meta, Nov 9, 2026Introducing Our Smallest, Most Efficient Model: Muse Ember
- Meta, Oct 15, 2026Introducing Muse Spark Open, The Most Capable US Open-Weight Model to Date
- Meta, Nov 9, 2026Muse Ember Evaluation Methodology
- Meta, Aug 10, 2026Muse Glimmer Evaluation Methodology
- NVIDIA, Oct 15, 2026Nemotron 3.5 Bolt 74B-A9B 24GB: A Hybrid Vision-Language Model for Local AI
- NVIDIA, Oct 15, 2026Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AI
- Google, May 19, 2026Gemini 3.5 Flash Model evaluation: approach, methodology & results
- Google, Oct 28, 2026Gemini 4 Carbon Model evaluation: approach, methodology & results
- Thinking Machines, Nov 5, 2026Inkling 2 Small Model Card
- Thinking Machines, Nov 5, 2026Introducing Inkling 2 Small
- Thinking Machines, Jul 15, 2026Inkling: Our Open-Weights Model
- Anthropic, Nov 9, 2026Claude Fable 5.2 and Claude Mythos 5.2 System Card
- Anthropic, Nov 9, 2026Introducing Claude Fable 5.2 and Claude Mythos 5.2
- Anthropic, Sep 28, 2026Introducing Claude Sonnet 5.5
- Anthropic, Sep 28, 2026Claude Sonnet 5.5 System Card
- Moonshot AI, Jul 16, 2026Kimi K3: Open Frontier Intelligence
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence
- MiniMax, Jun 1, 2026MiniMax M3: Frontier Coding, 1M Context, Native Multimodality — All in One Model
- MiniMax, Oct 19, 2026MiniMax M3.1 Flash: Redefining Agent Performance and Cost
- Z.ai, Jun 16, 2026GLM-5.2: Built for Long-Horizon Tasks
- Z.ai, Aug 26, 2026GLM-5.3-Flash: Frontier Intelligence, Flash Cost
Models
- MiniMax M2.7
- Gemini 3.5 Flash
- Qwen3.7-Plus
- Nemotron 3 Ultra 550B-A55B
- GLM-5.2
- LongCat-2.0
- Laguna XS 2.1
- Muse Spark 1.1
- Inkling
- Kimi K3
- Gemini 3.5 Flash-Lite
- Muse Glimmer 30B
- GLM-5.3-Flash
- Hy4 preview
- Claude Fable 5.1
- DeepSeek-V4.1-Flash
- Qwen3.8-Omni-Flash
- Claude Sonnet 5.5
- GPT-6.1 Sol
- Gemini 4 Argon
- Mistral Large 4
- Muse Spark Open 816B-A42B
- Nemotron 3.5 Super VL 120B-A12B
- DeepSeek-V4.1-Flash-1017
- MiniMax M3.1 Flash
- Kimi K3.1 Pro
- Gemini 4 Carbon
- LongCat-2.5
- Hy4
- Inkling 2 Small
- Claude Fable 5.2
- Muse Ember