Google Takes the Max on OSWorld 2.1
Google reports Gemini 4's OSWorld 2.1 scores as the maximum over three runs. It averages its Terminal-Bench runs, and Anthropic averages OSWorld 2.1.
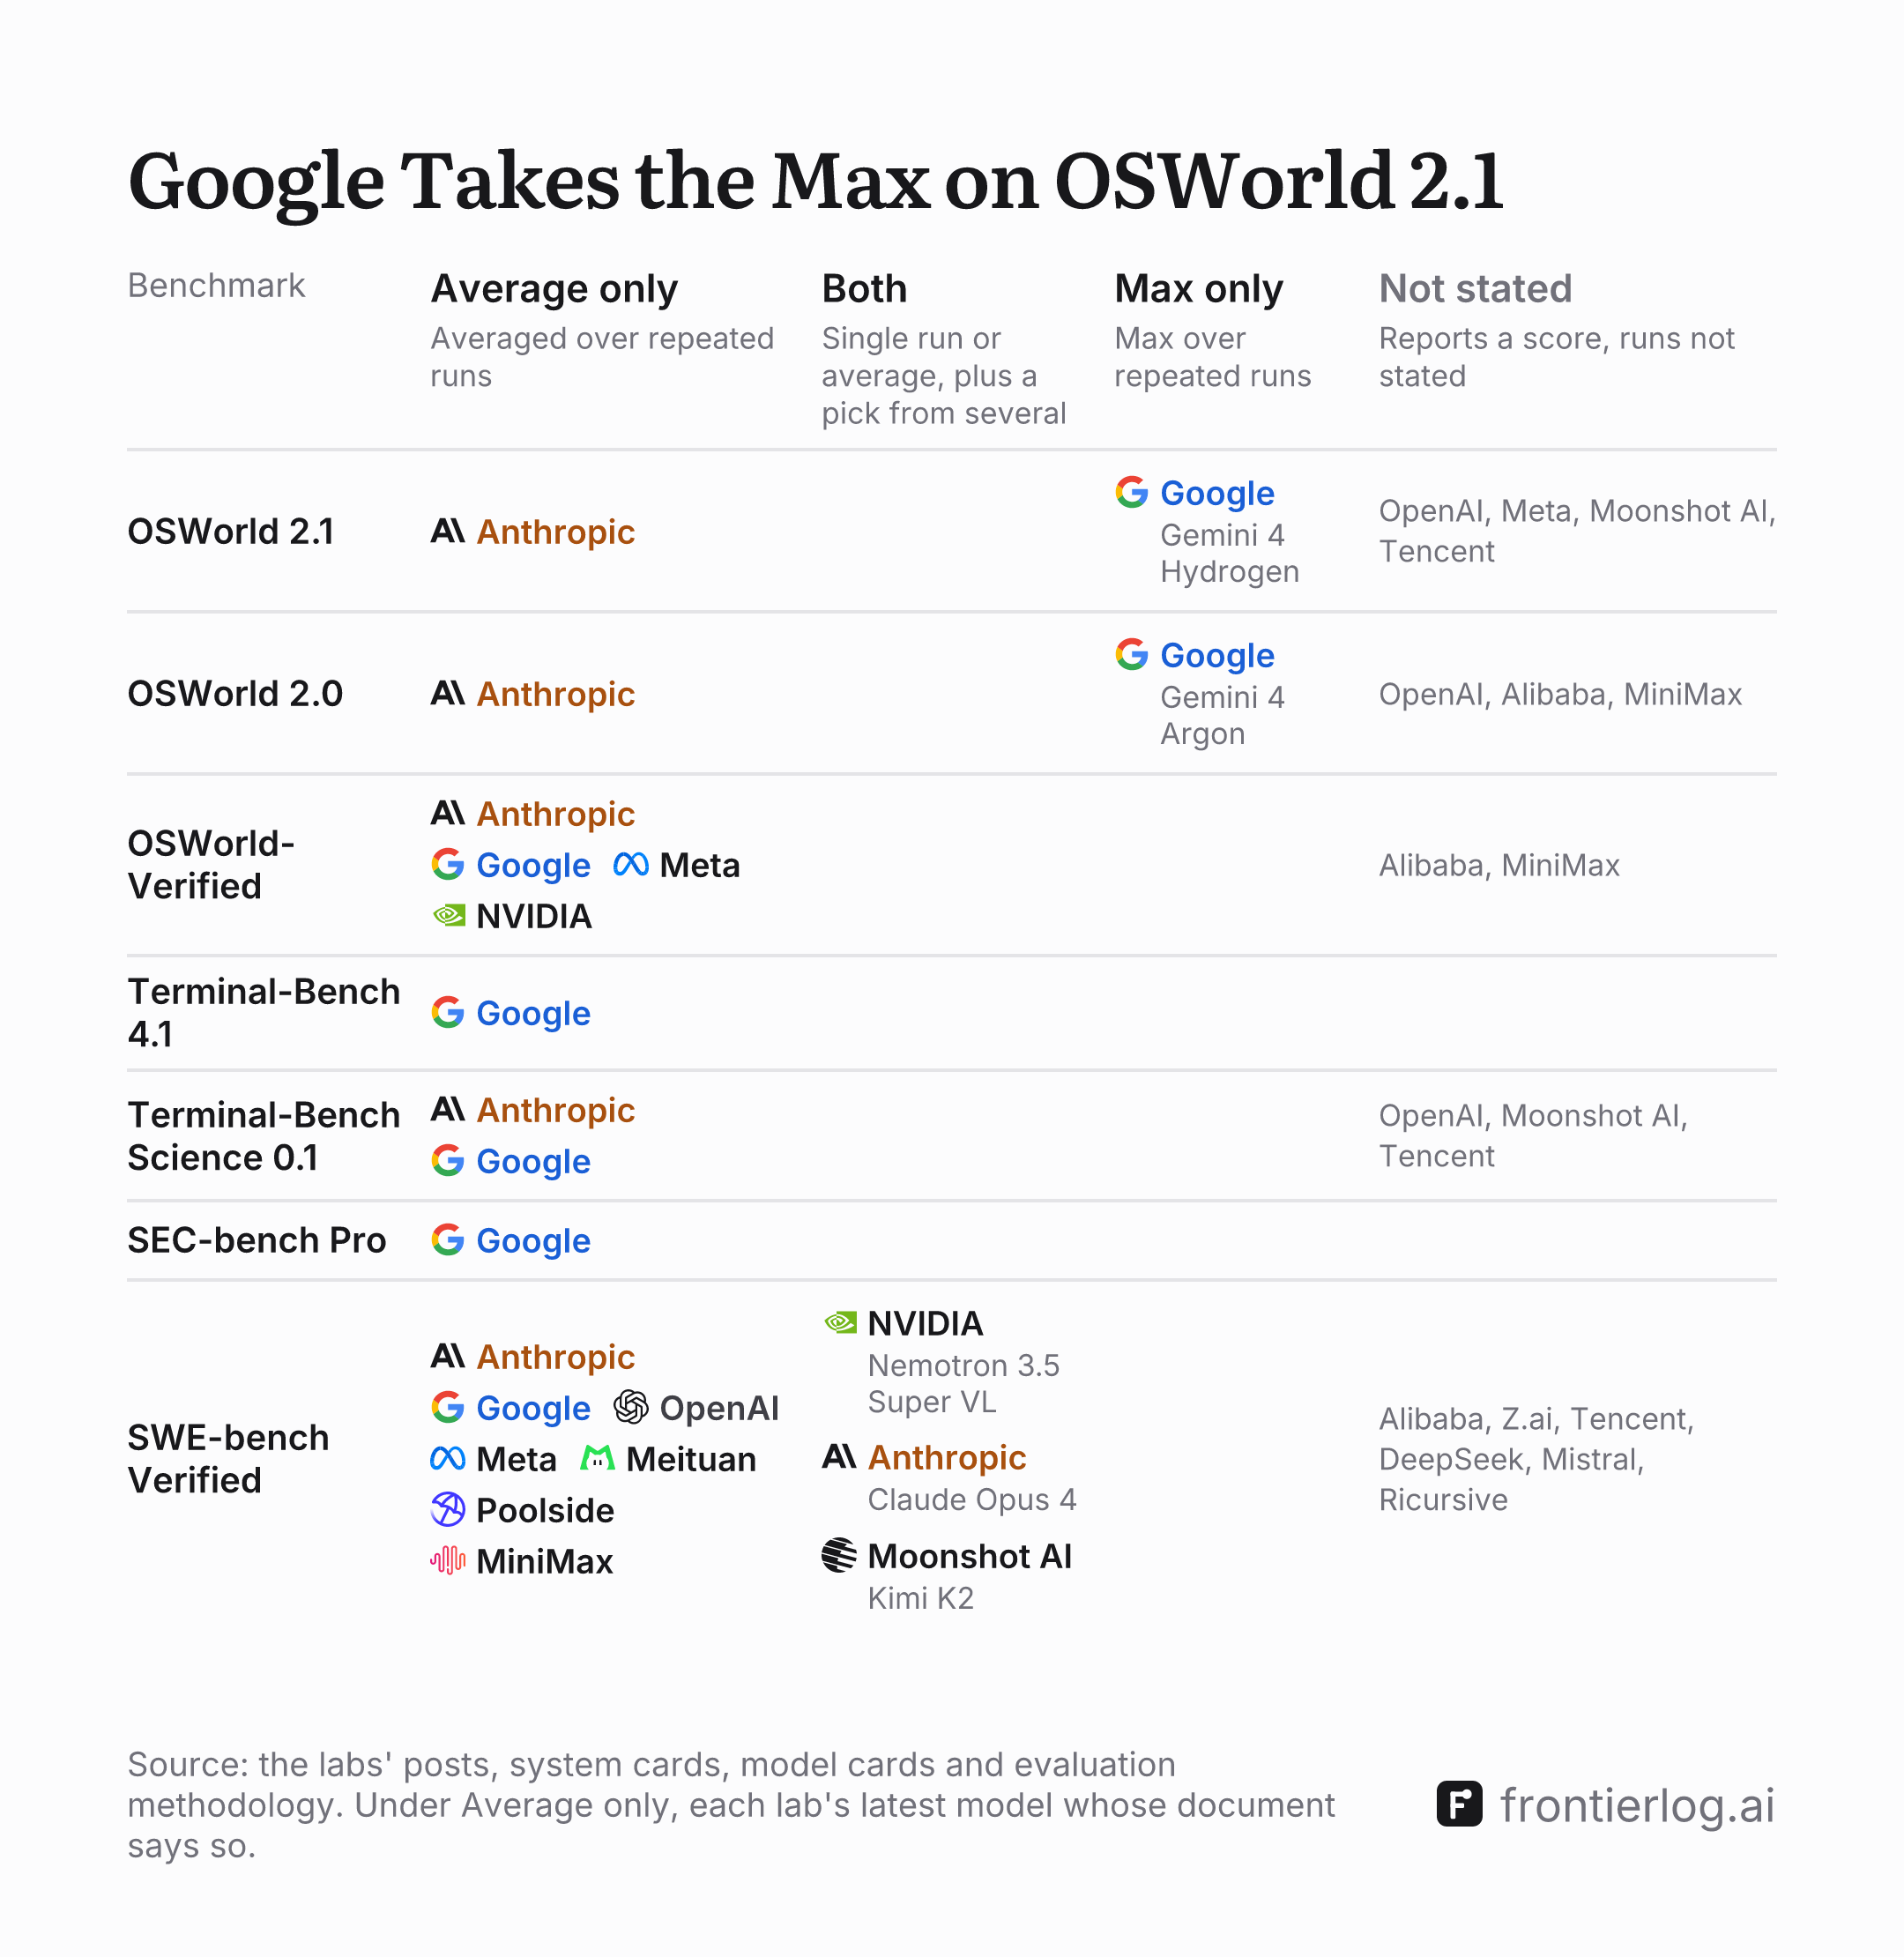
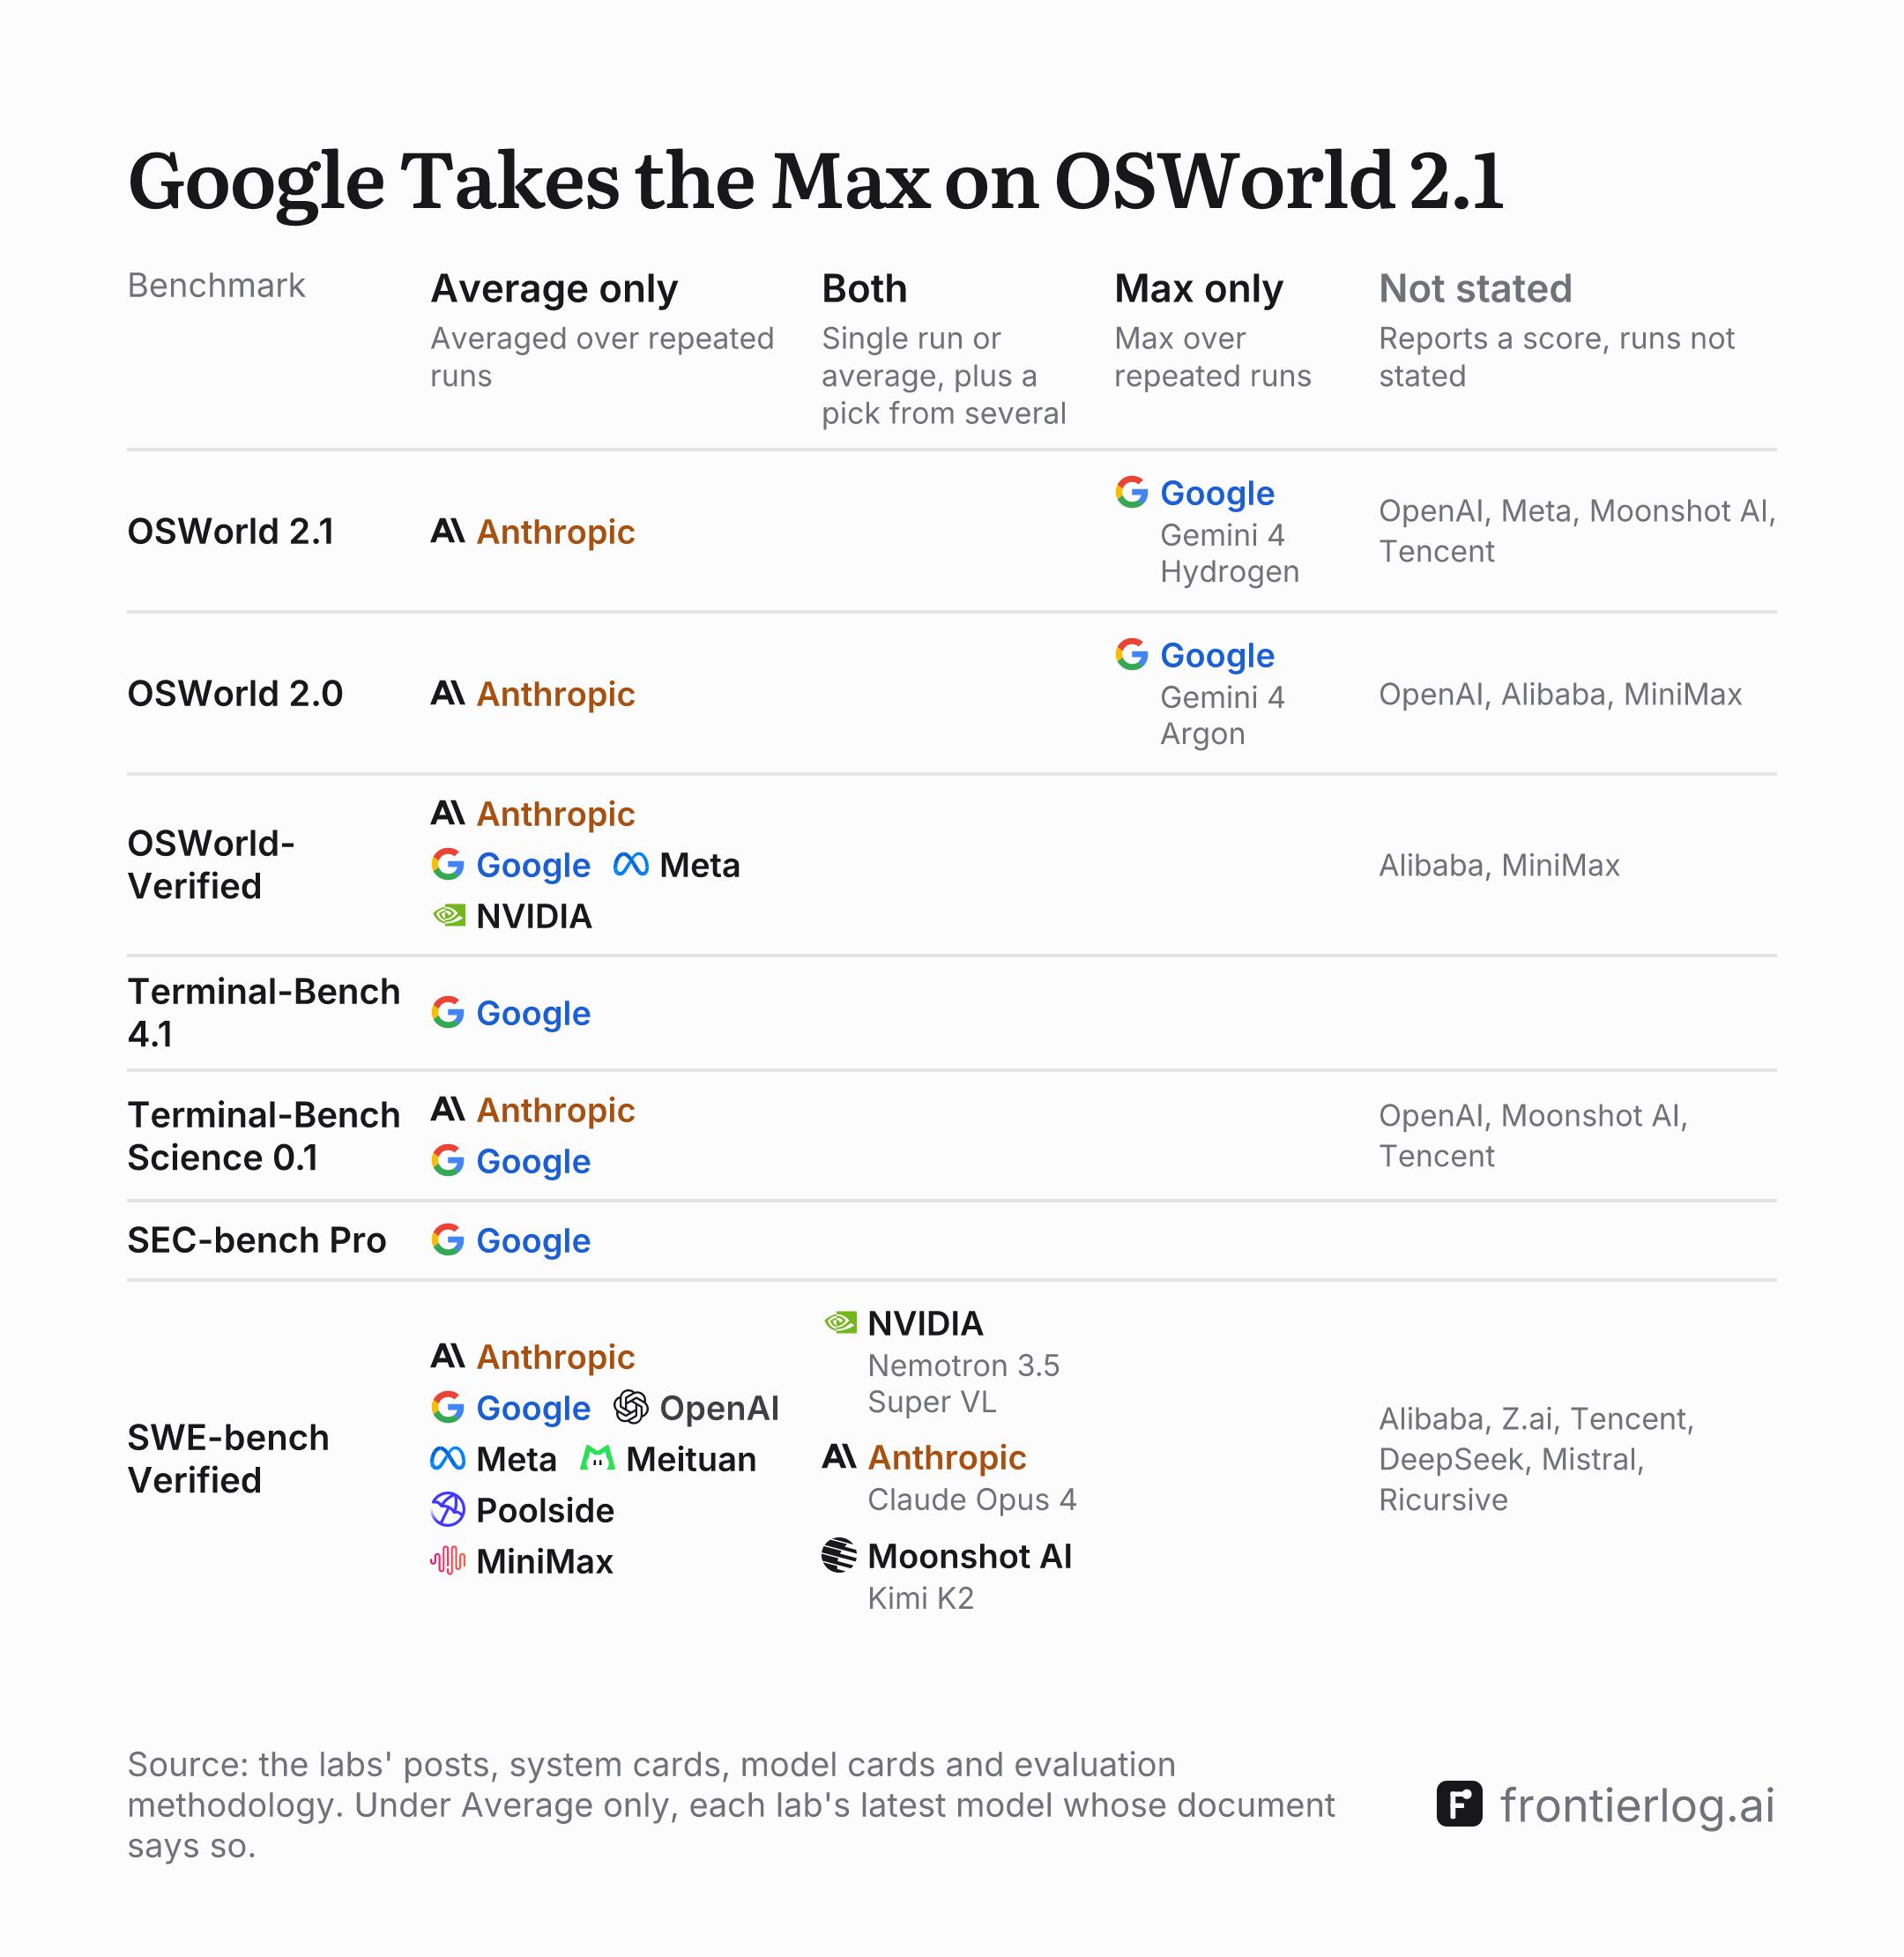
Google reports its Gemini 4 models' OSWorld 2.1 scores as the maximum over three runs. Its evaluation methodology for Gemini 4 Hydrogen, published with the model on Nov 12, says the scores are “self-computed, maxed over 3 runs with a single attempt per run”. Anthropic reports the same benchmark as an average of five attempts.
Google averages its Terminal-Bench runs
The same document states a general rule: “To reduce variance, we average over multiple trials for smaller benchmarks.” It reports Terminal-Bench 4.1 and Terminal-Bench Science 0.1 “averaged over 5 attempts per task”. The Gemini 4 Carbon methodology reports SEC-bench Pro “averaged over 3 independent attempts per task”. It uses the same “maxed over 3 runs” sentence for Gemini 4 Carbon and Gemini 4 Argon on OSWorld 2.1.
Google averaged on OSWorld-Verified, the version before OSWorld 2.0. Its methodology for Gemini 3.6 Flash on Jul 21 said the OSWorld-Verified scores were “averaged over 5 runs with a single attempt per run”.
The maximum arrived with OSWorld 2.0. Google's methodology for Gemini 3.7 Flash, a model it launched on Aug 13, reports OSWorld 2.0 “maxed over 3 runs with a single attempt per run”. Its documents for Gemini 3.8 Flash and Gemini 4 Argon repeat the sentence. Google's documents don't say whether the maximum is the best of three whole runs or the best result on each task. The Gemini 4 Hydrogen document applies the same sentence to the Claude Sonnet 5.5 score in its table, which it says Google computed itself. The table prints 83.9% for Claude Sonnet 5.5. Anthropic's Claude Haiku 5.5 system card gives the same 83.9% for Claude Sonnet 5.5 as an average of five attempts.
Anthropic averages five attempts on the same tasks
Anthropic reports OSWorld 2.1 on the same offline set of 82 tasks. Its Claude Fable 5.2 system card on Nov 9 gives each score “as Pass@1 averaged over five independent attempts per task”. Google's Gemini 4 Carbon table prints 87.2% for Claude Opus 5.5 in the same row as 81.5% for Gemini 4 Carbon. Anthropic's Claude Haiku 5.5 system card reports that 87.2% as an average of five attempts.
Four labs don't say how they combined runs
OpenAI, Meta, Moonshot AI and Tencent each report an OSWorld 2.1 score. OpenAI’s GPT-6.1 Terra post, Meta’s Muse Ember evaluation report, Moonshot AI’s Kimi K3.1 Pro post and Tencent’s Hy4 post don't say how repeated runs were combined. The benchmark's maker doesn't set a rule in its OSWorld 2.1 release notes.
Three labs printed a pick from several attempts
On SWE-bench Verified, three labs have printed a second score that draws on several attempts. Anthropic’s Claude 4 post on May 22, 2025 gave Claude Opus 4 a score “averaged over 10 trials, single-attempt patches”. It added a second score from “sampling multiple sequences and selecting the single best via an internal scoring model”. Moonshot AI’s Kimi K2 post on Jul 11, 2025 printed a “Single Attempt” row and a “Multiple Attempts” row, and its model card describes the second in the same words as Anthropic. NVIDIA’s Nemotron 3.5 technical report gives a score “averaged over three runs” and a second from three attempts, where “the same checkpoint then serves as a verifier, selecting one candidate”.
Moonshot AI also reports a maximum alone, on a benchmark outside the table. Moonshot AI’s Kimi K3.1 Pro post on Oct 24 reports ExploitBench as “the pass@5 max capability score: for each environment, the best run across 5 seeds”.
How we sorted the labs
A lab is under Average only where its own document says the score is averaged over runs, attempts or trials. The row names its latest model whose document says so. For Not stated, we read the document that reports the lab's score, its table footnotes and its methodology section. A lab is listed there when that document doesn't say how runs were combined. We left out cases a reader could take two ways, such as a metric labelled Pass@1 with no word on repeats. We also left out scores a lab took from another party's run. Inferring OpenAI's and Moonshot AI's Unstated OSWorld 2.1 Setups covers the task set and scoring behind the same scores.
| Benchmark | Lab, model | Reported | The lab's words |
|---|---|---|---|
| OSWorld 2.1 | Anthropic, Claude Fable 5.2 | Average only | “averaged over five independent attempts per task” |
| OSWorld 2.1 | Google, Gemini 4 Hydrogen | Max only | “maxed over 3 runs with a single attempt per run” |
| OSWorld 2.1 | OpenAI, GPT-6.1 Terra | Not stated | Doesn't say |
| OSWorld 2.1 | Meta, Muse Ember | Not stated | Doesn't say |
| OSWorld 2.1 | Moonshot AI, Kimi K3.1 Pro | Not stated | Doesn't say |
| OSWorld 2.1 | Tencent, Hy4 | Not stated | Doesn't say |
| OSWorld 2.0 | Anthropic, Claude Opus 5.5 | Average only | “each as pass@1 averaged over five independent runs” |
| OSWorld 2.0 | Google, Gemini 4 Argon | Max only | “maxed over 3 runs with a single attempt per run” |
| OSWorld 2.0 | OpenAI, GPT-6.1 Sol | Not stated | Doesn't say |
| OSWorld 2.0 | Alibaba, Qwen3.8-Max | Not stated | Doesn't say |
| OSWorld 2.0 | MiniMax, MiniMax M3.1 Flash | Not stated | Doesn't say |
| OSWorld-Verified | Anthropic, Claude Sonnet 5 | Average only | “first-attempt success rate, averaged over five runs” |
| OSWorld-Verified | Google, Gemini 3.6 Flash | Average only | “averaged over 5 runs with a single attempt per run” |
| OSWorld-Verified | Meta, Muse Glimmer 30B | Average only | “averaged over four attempts per task” |
| OSWorld-Verified | NVIDIA, Nemotron 3.5 Super VL | Average only | “We report the average task score, which includes partial credit, over three runs.” |
| OSWorld-Verified | Alibaba, Qwen3.8-Max | Not stated | Doesn't say |
| OSWorld-Verified | MiniMax, MiniMax M3 | Not stated | Doesn't say |
| Terminal-Bench 4.1 | Google, Gemini 4 Hydrogen | Average only | “averaged over 5 attempts per task” |
| Terminal-Bench Science 0.1 | Anthropic, Claude Fable 5.2 | Average only | “Scores are averaged over 10 trials per task” |
| Terminal-Bench Science 0.1 | Google, Gemini 4 Hydrogen | Average only | “averaged over 5 attempts per task” |
| Terminal-Bench Science 0.1 | OpenAI, GPT-6.1 Terra | Not stated | Doesn't say |
| Terminal-Bench Science 0.1 | Moonshot AI, Kimi K3.1 Pro | Not stated | Doesn't say |
| Terminal-Bench Science 0.1 | Tencent, Hy4 | Not stated | Doesn't say |
| SEC-bench Pro | Google, Gemini 4 Carbon | Average only | “averaged over 3 independent attempts per task” |
| SWE-bench Verified | Anthropic, Claude Opus 5 | Average only | “each score is an average over five trials” |
| SWE-bench Verified | Google, Gemini 3.1 Pro | Average only | “Averaged over 10x runs for SWE-Bench Verified” |
| SWE-bench Verified | OpenAI, GPT-5 | Average only | “we average over 4 tries per instance” |
| SWE-bench Verified | Meta, Muse Glimmer 30B | Average only | “we average results across 4 runs” |
| SWE-bench Verified | Meituan, LongCat-Flash-Thinking-2601 | Average only | “SWE-bench Verified (Avg@5)” |
| SWE-bench Verified | Poolside, Laguna XS 2.1 | Average only | “mean pass@1 averaged over 4 attempts per task” |
| SWE-bench Verified | MiniMax, MiniMax M3 | Average only | “Each test was run 4 times and the average was taken.” |
| SWE-bench Verified | NVIDIA, Nemotron 3.5 Super VL | Both | “we report the resolve rate averaged over three runs” and “The same checkpoint then serves as a verifier, selecting one candidate” |
| SWE-bench Verified | Anthropic, Claude Opus 4 | Both | “averaged over 10 trials, single-attempt patches” and “selecting the single best via an internal scoring model” |
| SWE-bench Verified | Moonshot AI, Kimi K2 | Both | “Single Attempt (Acc)” and “Multiple Attempts (Acc)”, the second by “selecting the single best via an internal scoring model” |
| SWE-bench Verified | Alibaba, Qwen3.7-Plus | Not stated | Doesn't say |
| SWE-bench Verified | Z.ai, GLM-5 | Not stated | Doesn't say |
| SWE-bench Verified | Tencent, Hy3 | Not stated | Doesn't say |
| SWE-bench Verified | DeepSeek, DeepSeek-V4-Pro | Not stated | Doesn't say |
| SWE-bench Verified | Mistral, Mistral Medium 3.5 | Not stated | Doesn't say |
| SWE-bench Verified | Ricursive, Ripple-65B Preview | Not stated | Doesn't say |
OSWorld 2.1, offline set, partial score
| Model | Score | Sources |
|---|---|---|
| Claude Opus 5.5Claude Opus 5.5, mean of 5 attempts | 87.2% | Claude Haiku 5.5 System Cardsection 8.9.3 OSWorld 2.1 offline subset, text (PDF page 128), the Claude Opus 5.5 partial score |
| Claude Sonnet 5.5Claude Sonnet 5.5, mean of 5 attempts | 83.9% | Introducing Claude Haiku 5.5benchmark table (HTML), row 'Computer use / OSWorld 2.1', column 'Sonnet 5.5', the value tagged 'Offline subset' |
| Gemini 4 CarbonGemini 4 Carbon, max of 3 runs | 81.5% | Announcementbenchmark table (image), row 'OSWorld-2.1', 'Offline subset', column 'Gemini 4 Carbon' |
Sources
- DeepSeek, Apr 24, 2026DeepSeek V4 Preview Release
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- deepmind.googledeepmind.google/models/evals-methodology/gemini-3-1-pro
- deepmind.googledeepmind.google/models/evals-methodology/gemini-3-6-flash
- deepmind.googledeepmind.google/models/evals-methodology/gemini-3-7-flash
- deepmind.googledeepmind.google/models/evals-methodology/gemini-3-8-flash
- deepmind.googledeepmind.google/models/evals-methodology/gemini-4-argon
- OpenAI, Aug 7, 2025GPT-5 System Card
- github.comgithub.com/xlang-ai/OSWorld-V2/releases/tag/osworld-v2.1
- Meituan, Jan 20, 2026LongCat-Flash-Thinking-2601 model card (Hugging Face)
- Moonshot AI, Jul 11, 2025Kimi-K2-Instruct model card
- Ricursive Intelligence, Nov 4, 2026ricursiveAI/Ripple-65B-Preview model card
- Tencent, Jul 6, 2026Introducing Hy3
- Tencent, Nov 4, 2026Introducing Hy4
- Mistral, May 22, 2026Remote agents in Vibe. Powered by Mistral Medium 3.5.
- OpenAI, Sep 29, 2026Introducing GPT-6.1 Sol
- OpenAI, Oct 26, 2026Introducing GPT-6.1 Terra
- Poolside, Jul 2, 2026Introducing Laguna XS 2.1
- Alibaba, Jun 1, 2026Qwen3.7-Plus: Multimodal Agent Intelligence
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- Meta, Nov 9, 2026Muse Ember Evaluation Methodology
- Meta, Aug 10, 2026Muse Glimmer Evaluation Methodology
- NVIDIA, Oct 15, 2026Nemotron 3.5 Super and Lightning: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Models for Agentic AI
- Google, Oct 28, 2026Gemini 4 Carbon Model evaluation: approach, methodology & results
- Google, Nov 12, 2026Gemini 4 Hydrogen Model evaluation: approach, methodology & results
- Anthropic, Nov 9, 2026Claude Fable 5.2 and Claude Mythos 5.2 System Card
- Anthropic, Oct 7, 2026Introducing Claude Haiku 5.5
- Anthropic, Oct 7, 2026Claude Haiku 5.5 System Card
- Anthropic, Sep 22, 2026Claude Opus 5.5 System Card
- Anthropic, Jul 24, 2026Claude Opus 5 System Card
- Anthropic, Jun 30, 2026Claude Sonnet 5 System Card
- Anthropic, May 22, 2025Introducing Claude 4
- Moonshot AI, Jul 11, 2025Kimi K2: Open Agentic Intelligence
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence
- MiniMax, Jun 1, 2026MiniMax M3: Frontier Coding, 1M Context, Native Multimodality — All in One Model
- MiniMax, Oct 19, 2026MiniMax M3.1 Flash: Redefining Agent Performance and Cost
- Z.ai, Feb 12, 2026GLM-5: From Vibe Coding to Agentic Engineering