Inferring OpenAI's and Moonshot AI's Unstated OSWorld 2.1 Setups
OpenAI doesn't say how it scored GPT-6.1 Terra on OSWorld 2.1, and Moonshot AI doesn't name Kimi K3.1 Pro's set or scoring. Their comparisons imply both.
On OSWorld 2.1, labs report results on the full set of 108 tasks or on an offline set of 82, and with a partial score or a strict pass rate. OpenAI and Moonshot AI leave one or both of those settings out. Each lab's own comparison with competitors points to the setup it used.
The setting changes the number
One model can score far apart under two setups. In its Claude Fable 5.2 system card on Nov 9, Anthropic reports 89.3% for Claude Fable 5.2 on the OSWorld 2.1 offline set with partial scoring. The same card reports 54.6% with a strict pass rate, which counts a task only when every checkpoint passes.
OpenAI names the set but leaves out the scoring
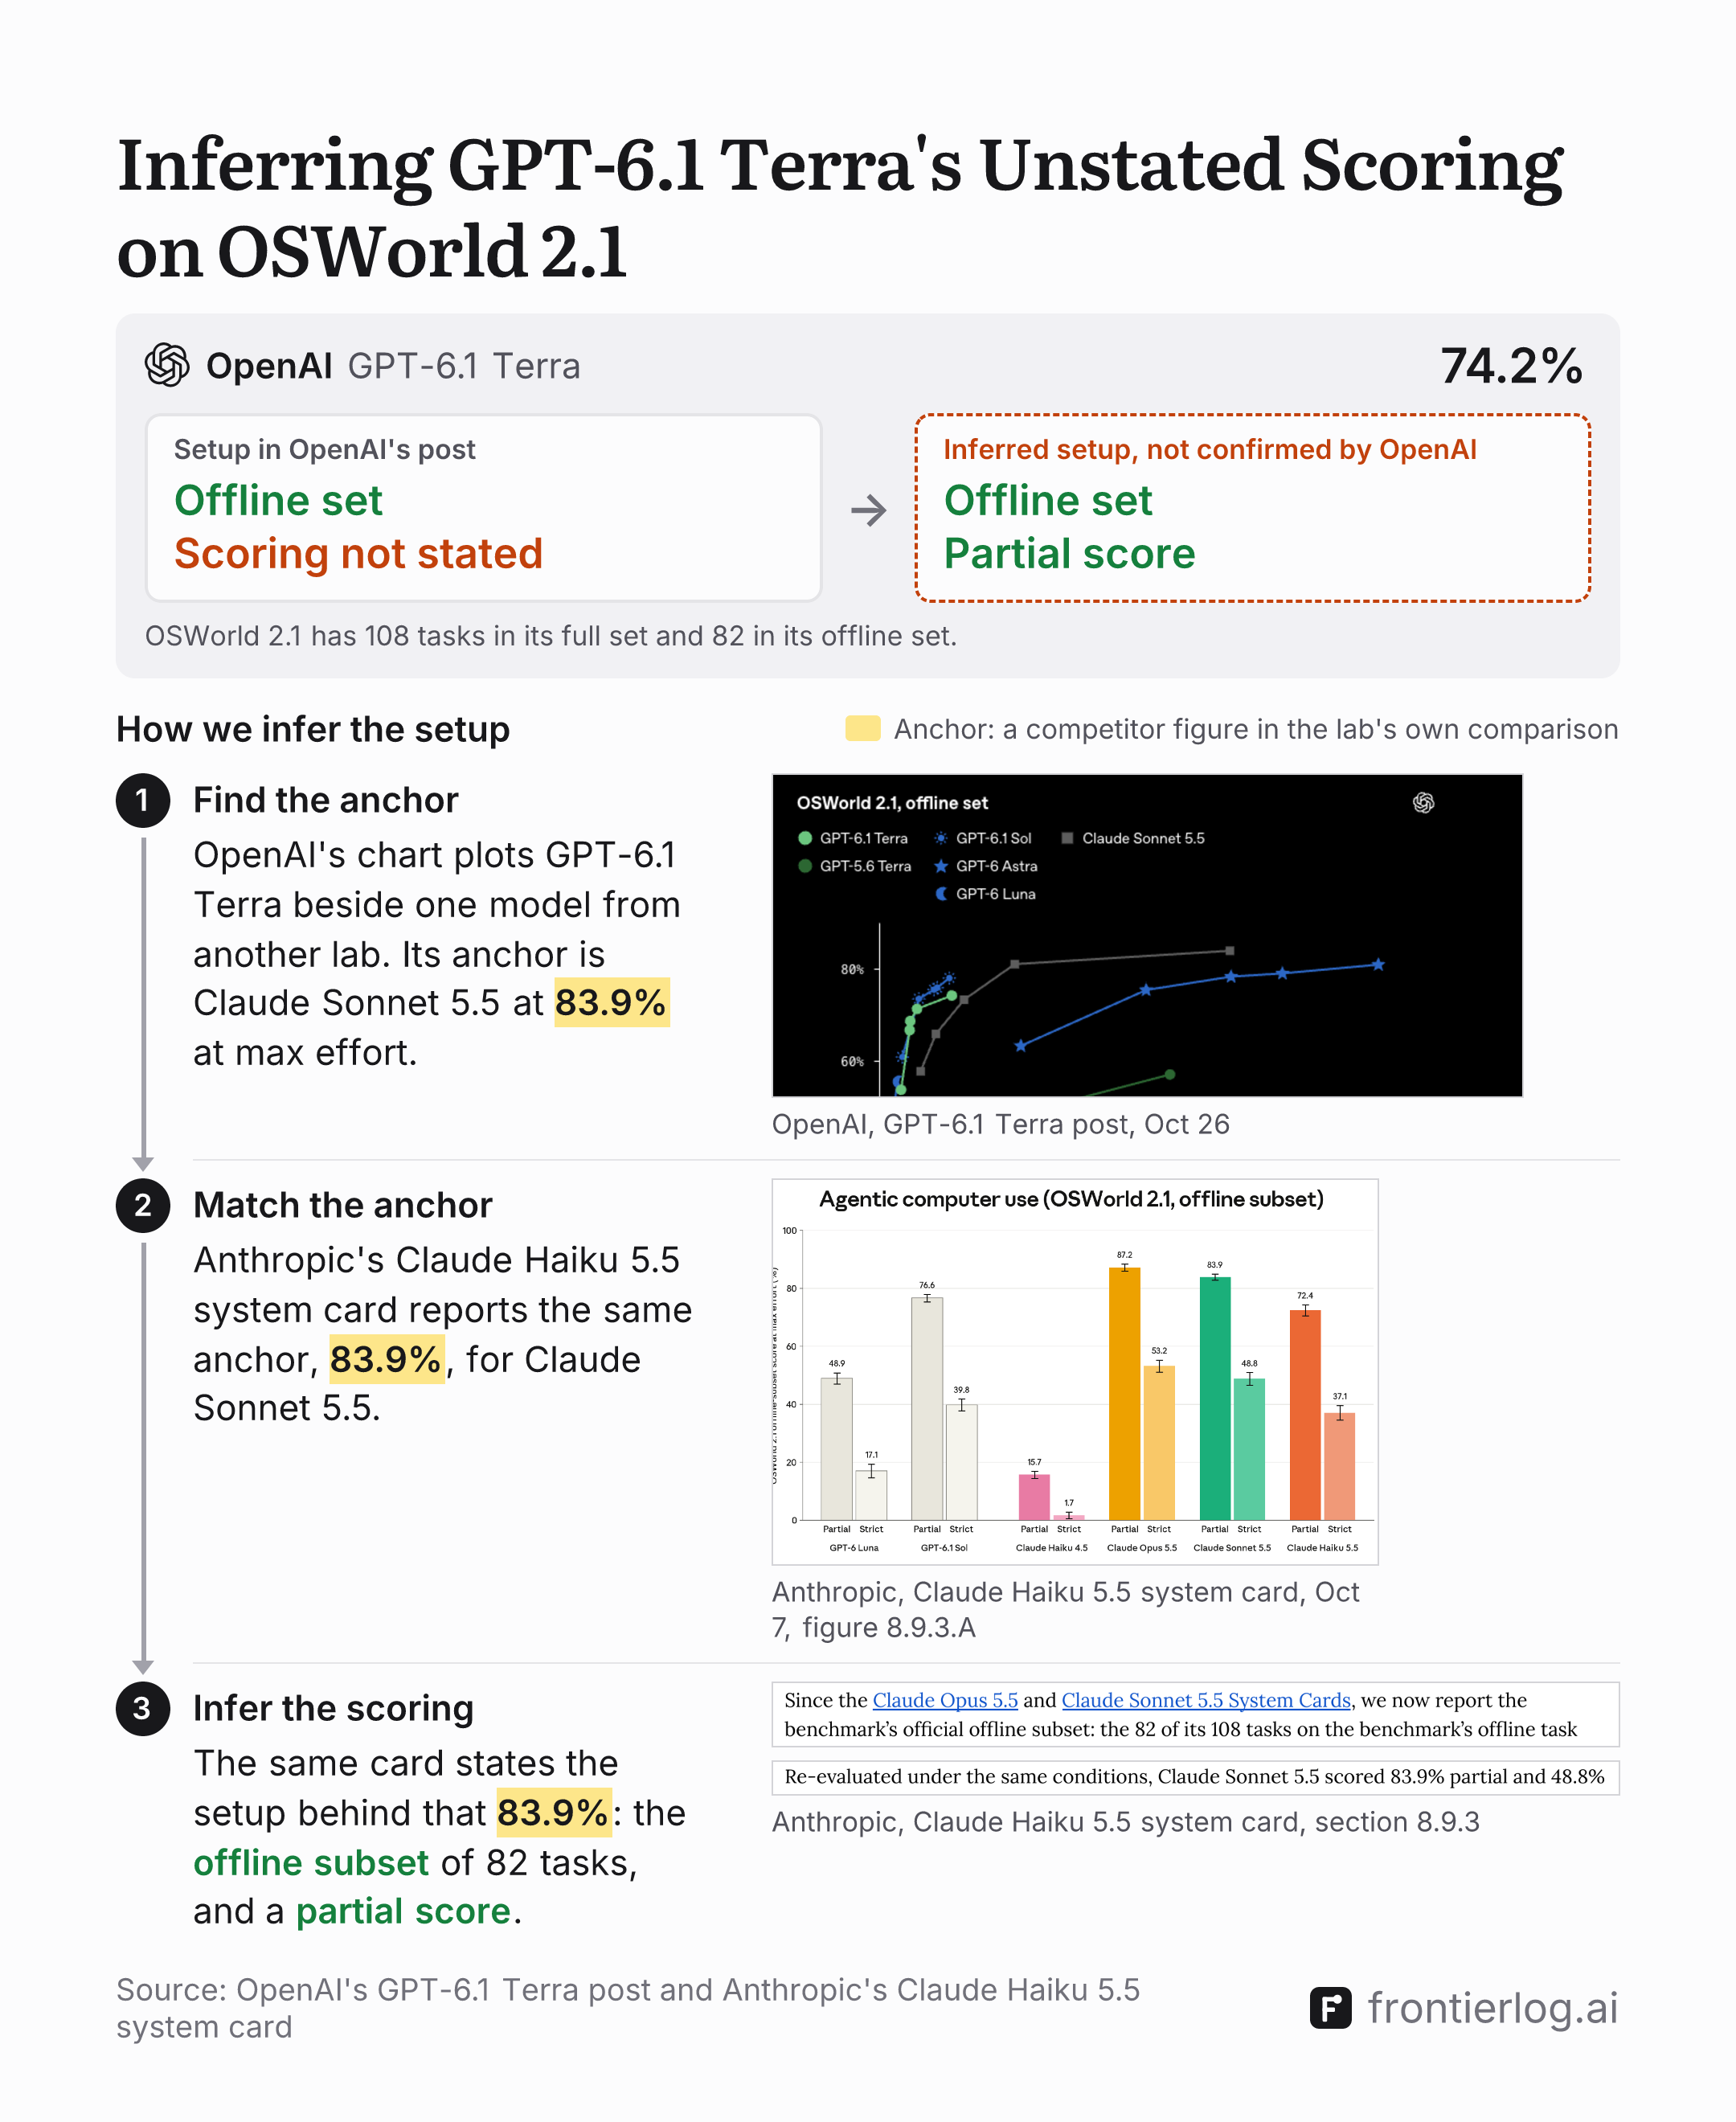
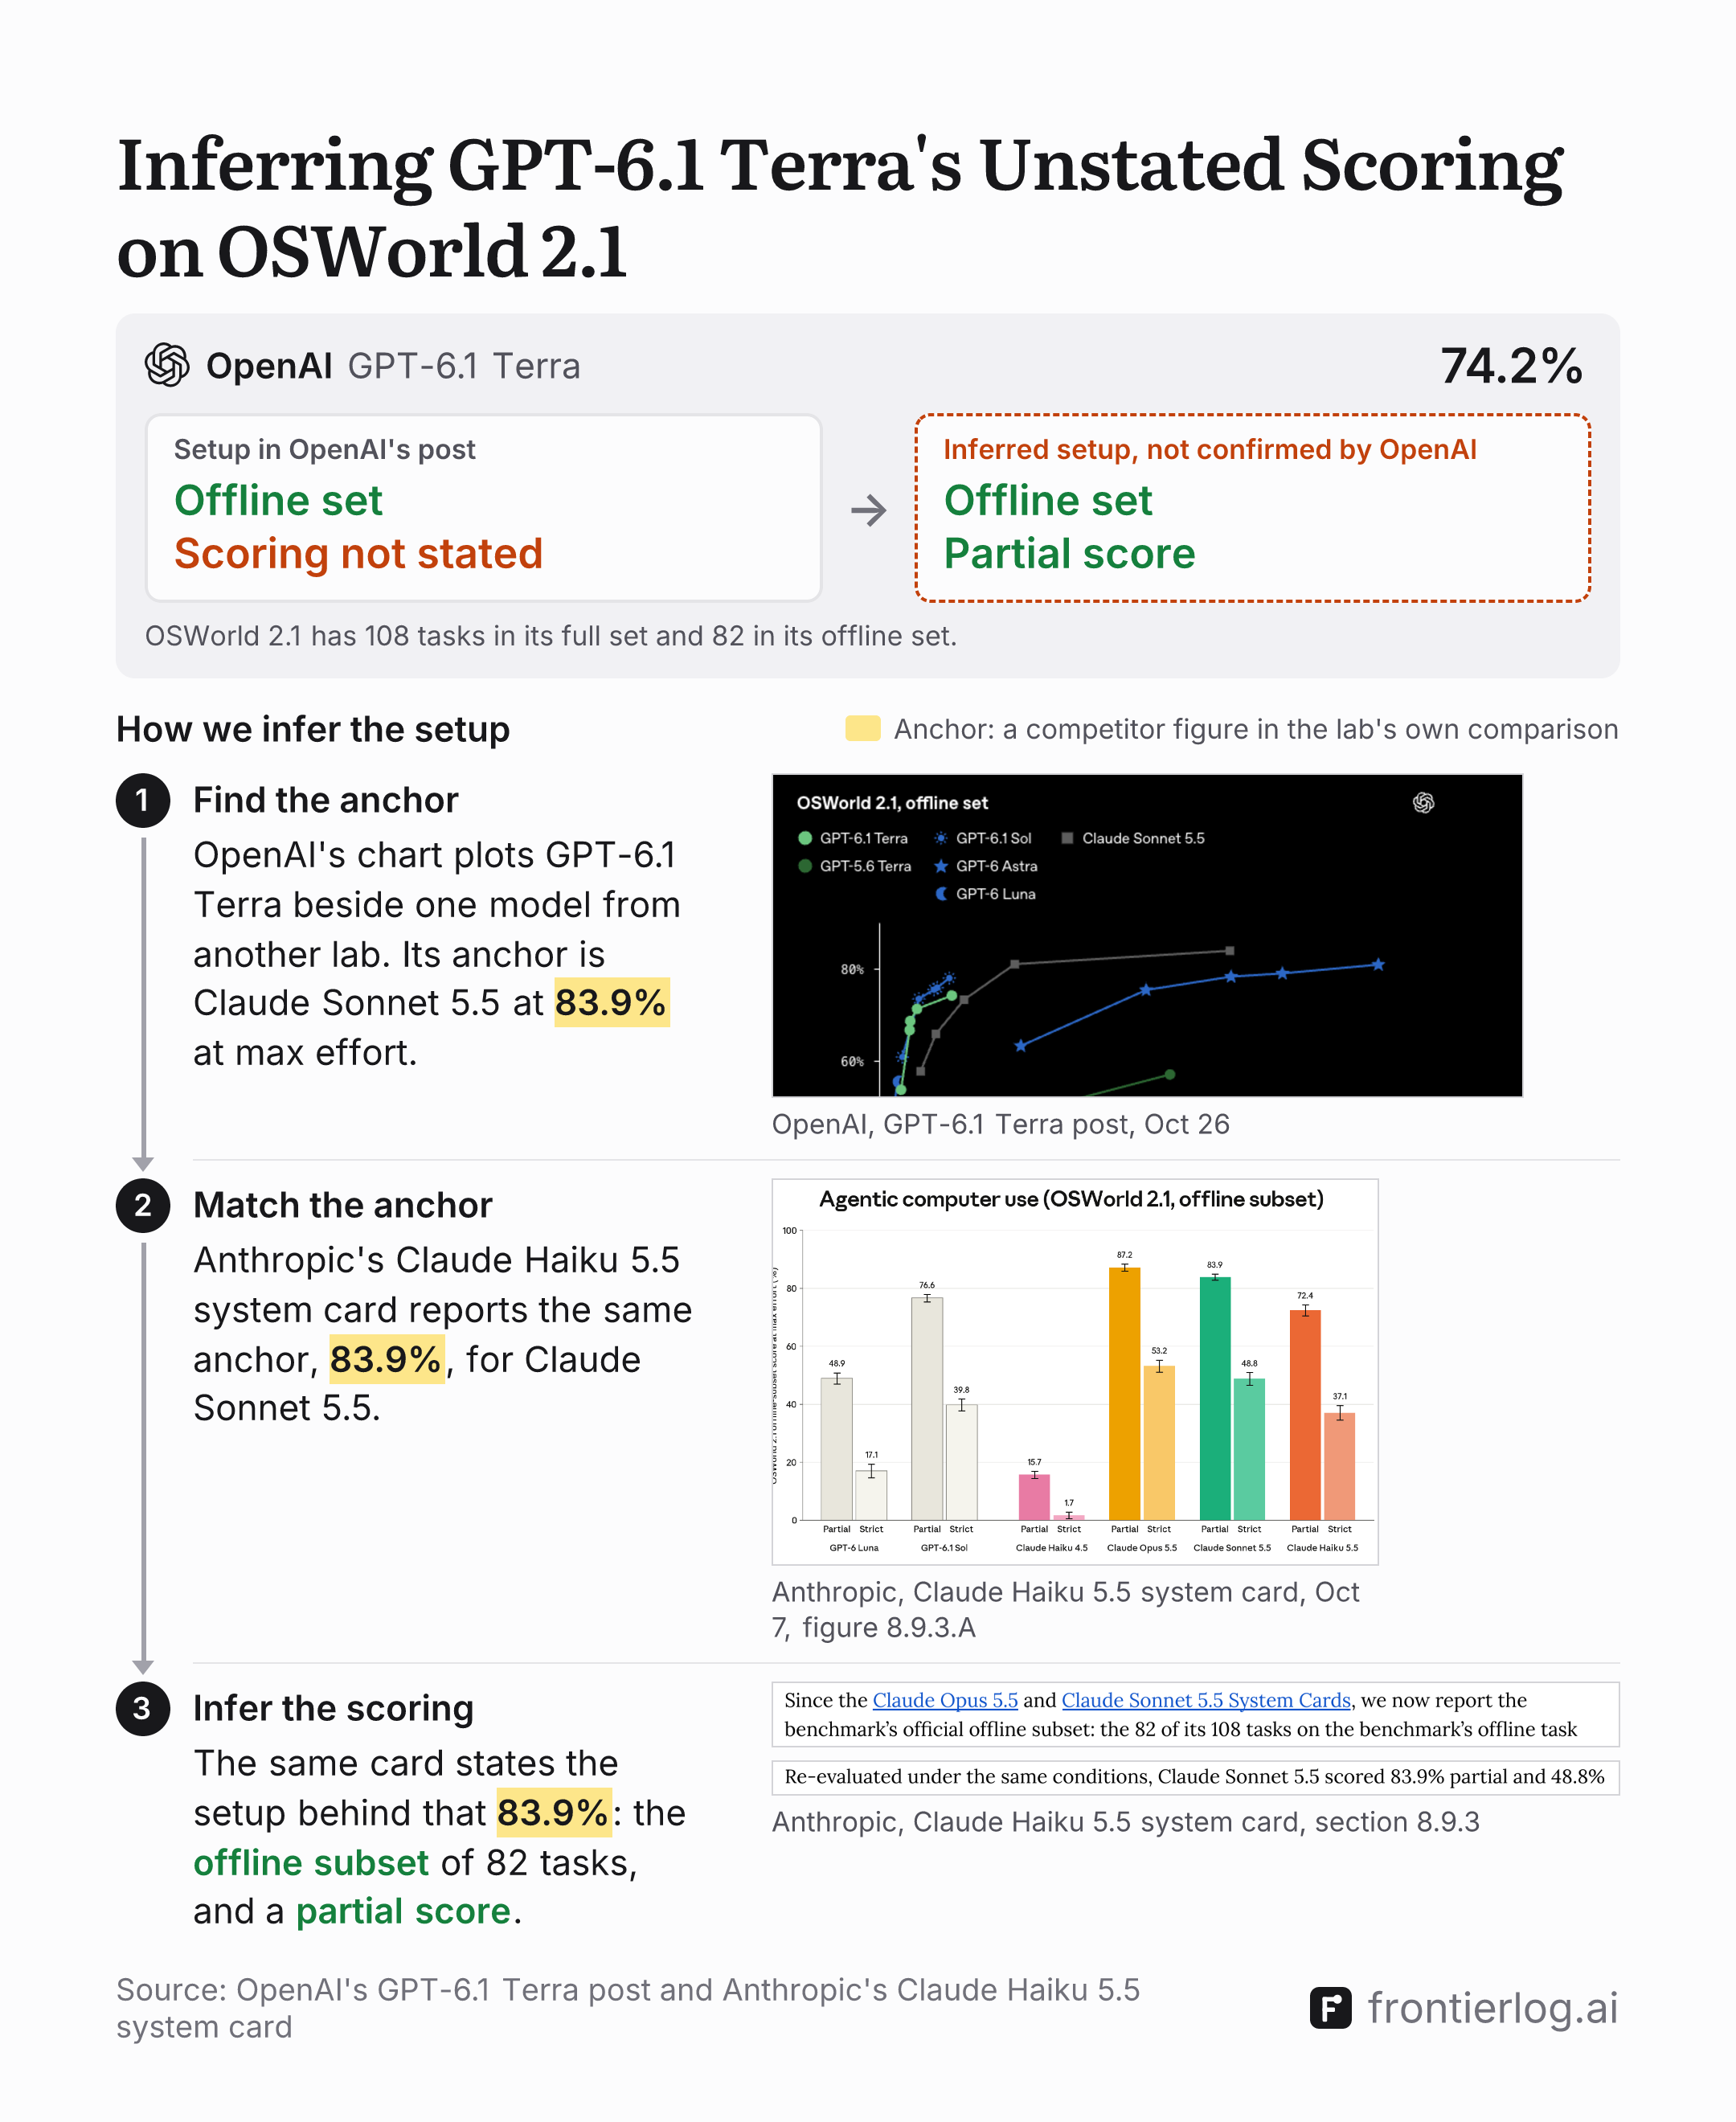
OpenAI's GPT-6.1 Terra post on Oct 26 charts GPT-6.1 Terra, GPT-6.1 Sol and GPT-6 Astra on "OSWorld 2.1, offline set". The post doesn't say whether the figures are partial scores or strict pass rates. For the earlier OSWorld 2.0, OpenAI's GPT-6.1 Sol post did say: "We report the partial reward on the offline set from the v2026.08.08 release."
Moonshot AI's Kimi K3.1 Pro post on Oct 24 reports 79.6% on OSWorld 2.1 and names neither the set nor the scoring. Its table prints the figure beside 80.7% for Claude Fable 5.1 and 81.8% for Claude Opus 5.5. Anthropic's Claude Opus 5.5 post gives the same two figures for those models as OSWorld 2.1 partial scores.
Other labs' tables fill the gap their own way
Google's Gemini 4 Carbon post on Oct 28 prints GPT-6 Astra's 80.9% in its OSWorld-2.1 row, labelled "Offline subset", beside 81.5% for Gemini 4 Carbon. Google's evaluation methodology says "We report the partial score from the offline subset". It also says the GPT-6 Astra score is "sourced from their respective published evaluations and system cards." OpenAI's own post gives the 80.9% with no scoring named.
Tencent's Hy4 post on Nov 4 prints Kimi K3.1 Pro's 79.6% and Claude Opus 5.5's 81.8% in its row "OSWorld 2.1 (Full, partial score)". The table marks its own testing with an asterisk, and neither figure carries one. Moonshot's own post doesn't name a set or a scoring for the 79.6%.
Anthropic ran OpenAI's models itself. Its Claude Fable 5.2 system card says it ran GPT-6 Astra and GPT-6.1 Sol "on the same 82 tasks through OpenAI's API, with OpenAI's own context compaction." In that run, GPT-6 Astra scored 79.5% with partial scoring and 44.9% with a strict pass rate. GPT-6.1 Sol scored 76.6% and 39.8%. These are Anthropic's runs, and they don't show how OpenAI scored its own figures.
What each lab's comparison implies
Each lab compared its unlabelled figures with competitors' figures, and other labs report most of those figures with a stated setup. OpenAI's GPT-6.1 Terra post charts its models beside Claude Sonnet 5.5, which reaches 83.9% at max effort. Anthropic's Claude Haiku 5.5 system card reports the same 83.9% as Sonnet 5.5's partial score on the offline set.
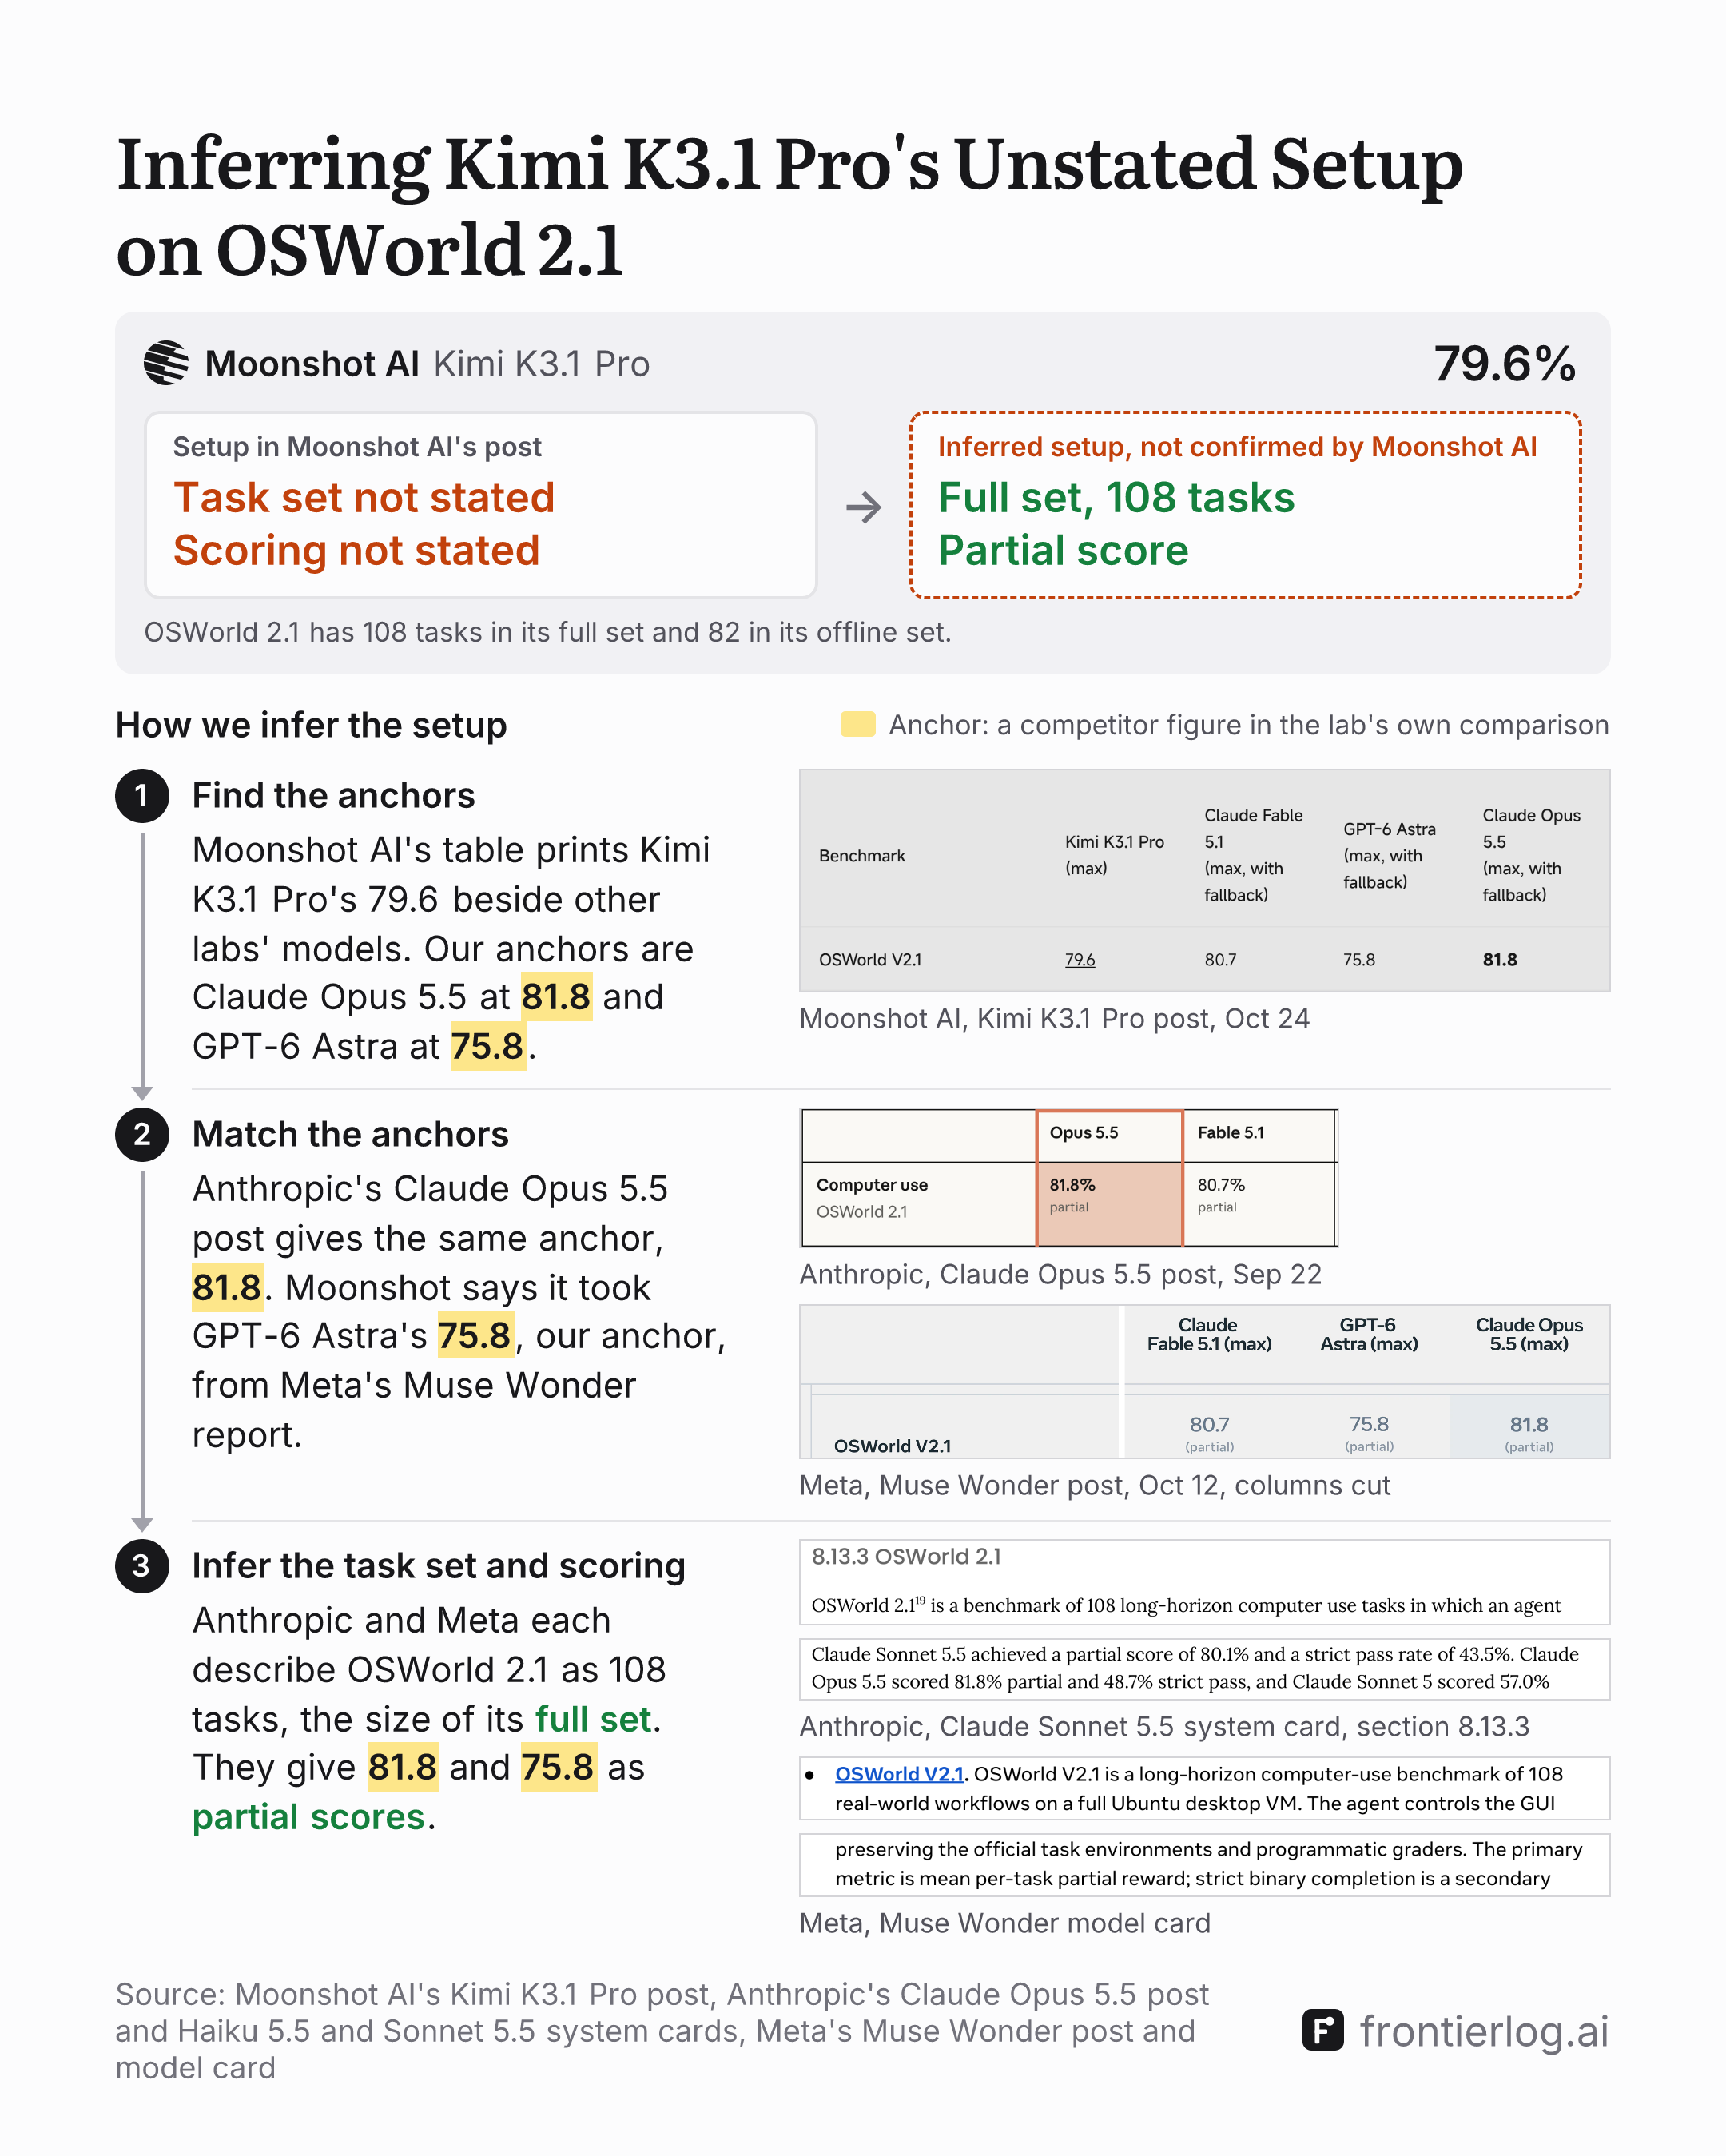
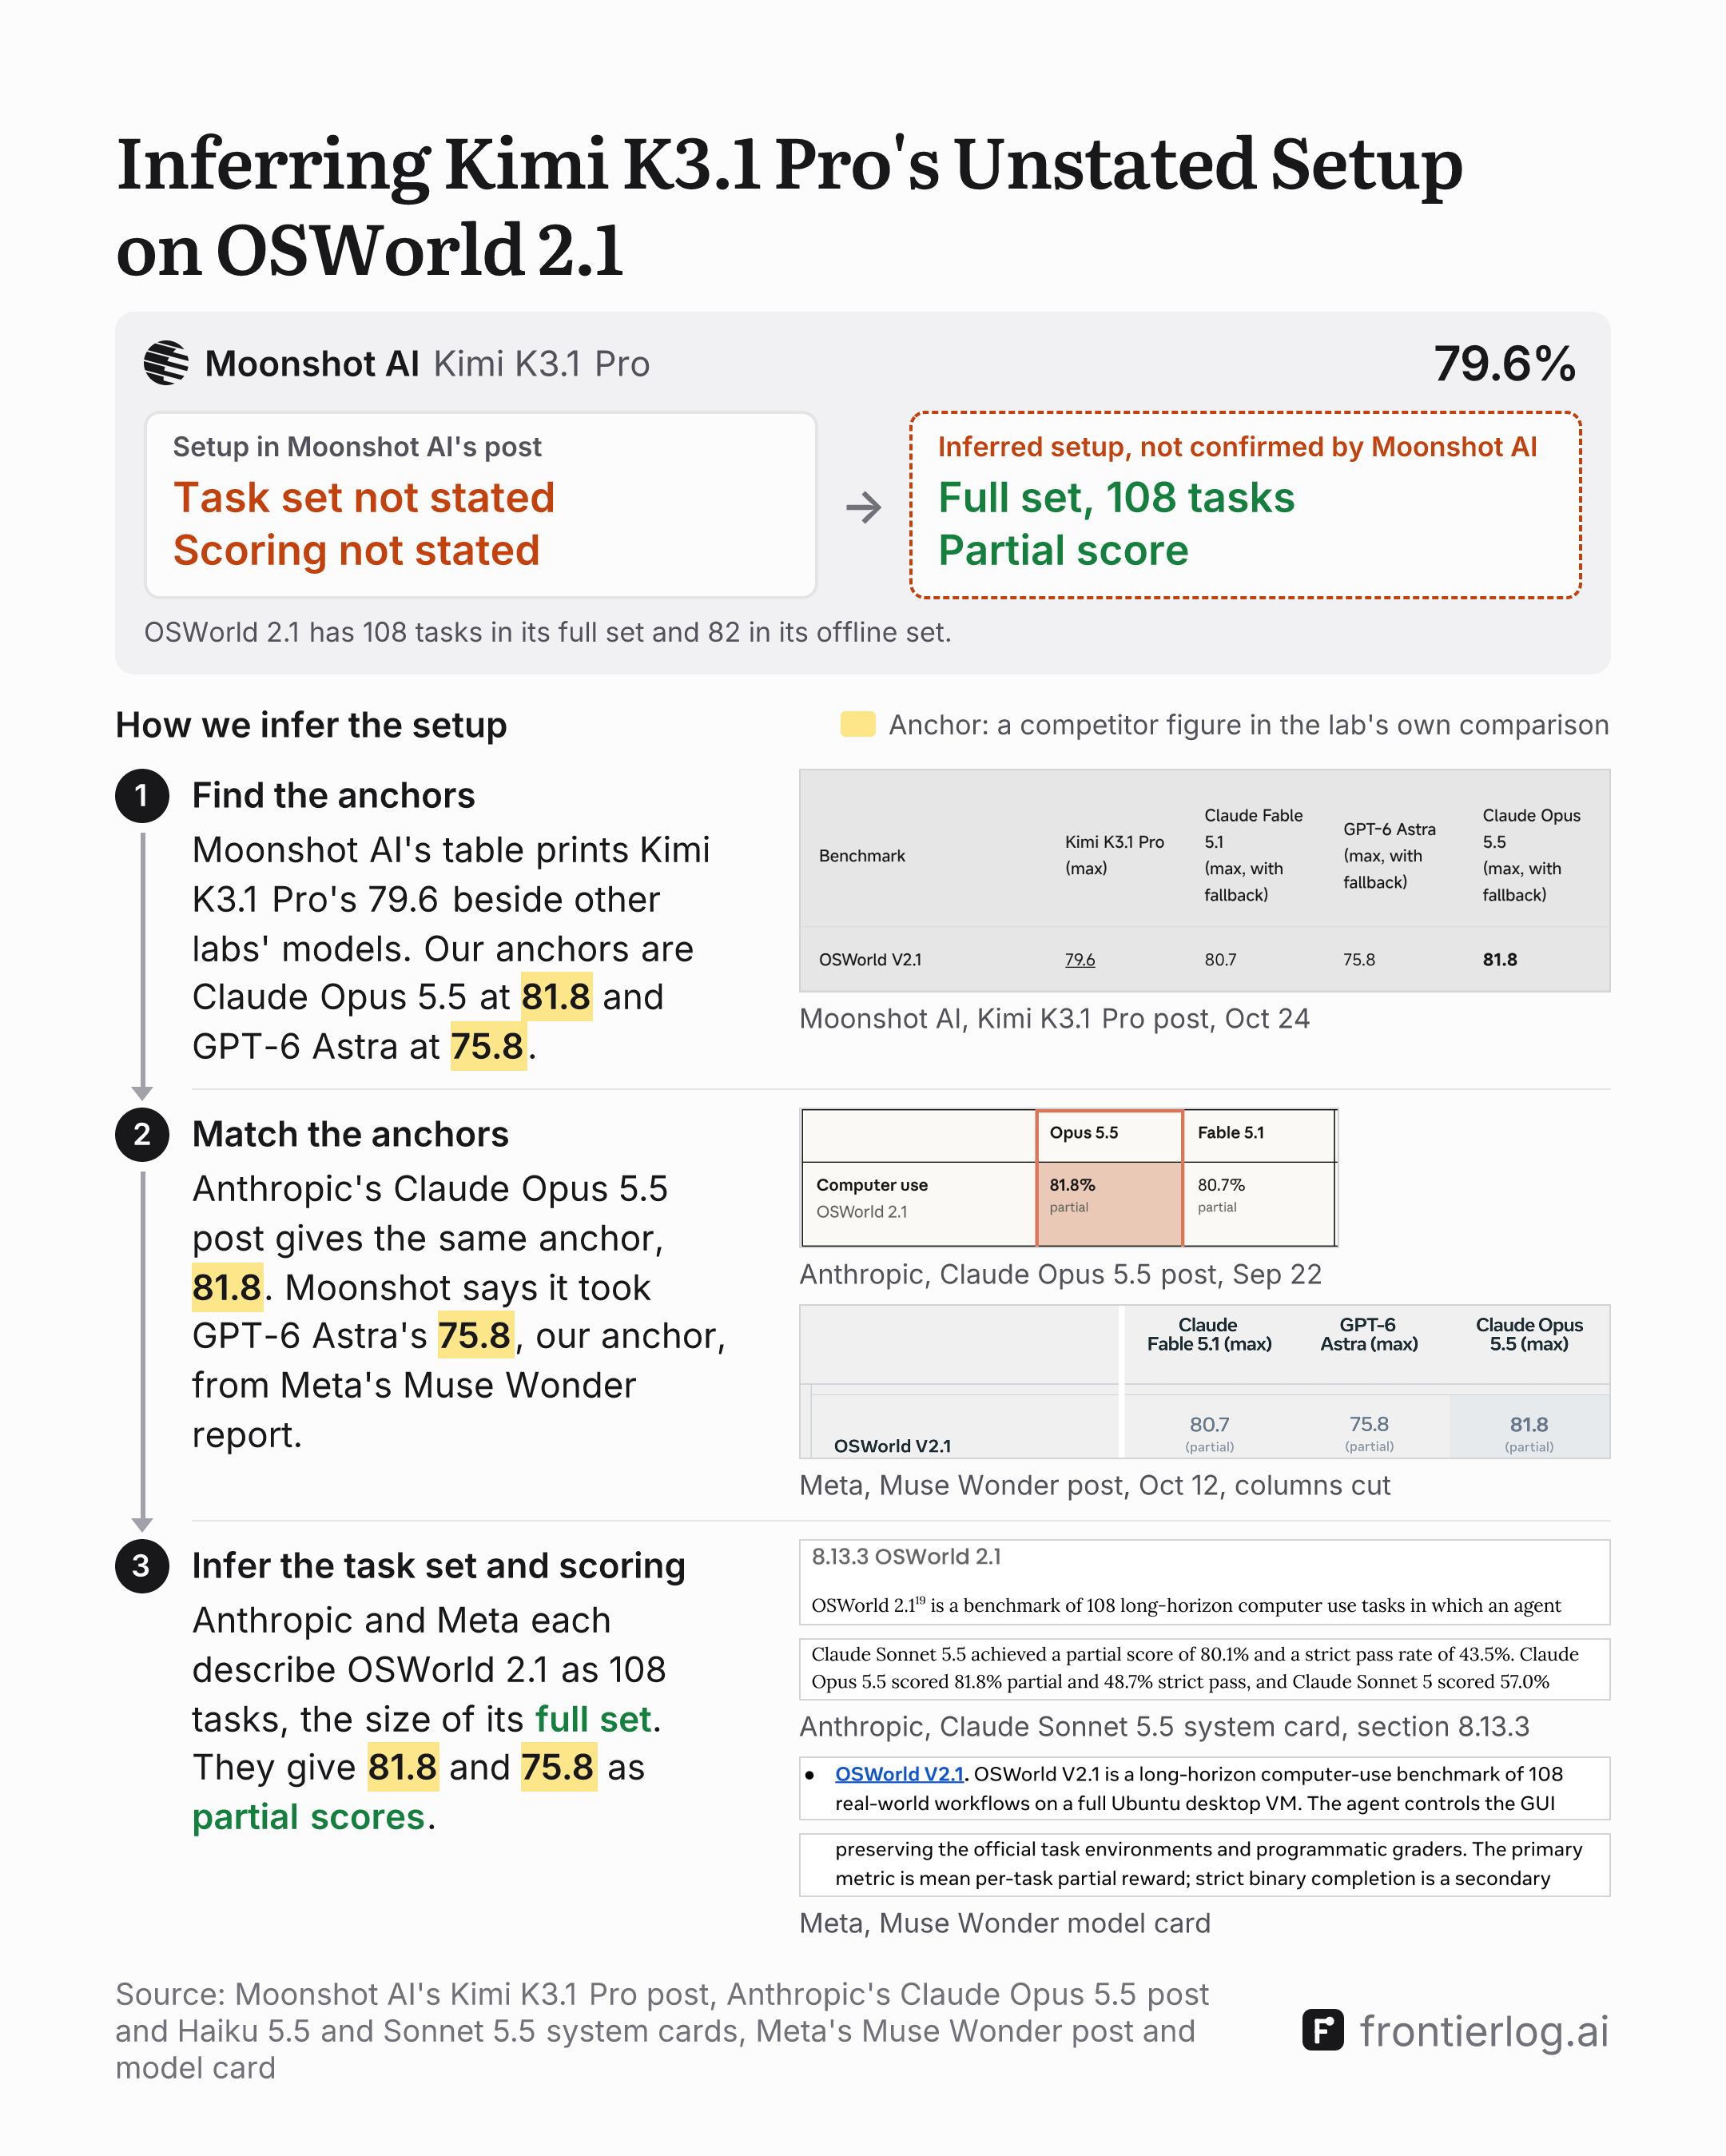
Moonshot AI's table compares Kimi K3.1 Pro with 80.7% for Claude Fable 5.1, 81.8% for Claude Opus 5.5, 75.8% for GPT-6 Astra and 69.3% for DeepSeek-V4.1-Flash-1017. Anthropic's Claude Sonnet 5.5 system card describes OSWorld 2.1 as 108 tasks and gives Opus 5.5's 81.8% as a partial score. Moonshot says the GPT-6 Astra figure is "taken from Muse Wonder's technical report". Meta's Muse Wonder table gives 75.8% as a partial score, and its model card describes OSWorld V2.1 as "108 real-world workflows". No lab states a setup for the DeepSeek figure, and DeepSeek reports no OSWorld 2.1 result of its own.
From these matches we infer a partial score on the offline set for GPT-6.1 Terra, and a partial score on the full set of 108 tasks for Kimi K3.1 Pro. Neither lab states these setups. OpenAI's post doesn't name a source for its Claude Sonnet 5.5 figures. Moonshot's footnote names its own harness, the Kimi Agent harness. Until each lab confirms its setup, the inference stays unconfirmed.
How we infer a setup
We infer a setup only from a figure that a lab prints in its own comparison. Another lab must report the same figure with its setup stated. The tables below list each document and where in it the figure appears. Neither OpenAI nor Moonshot AI has confirmed the setups we infer. AI Labs Report One Benchmark Four Ways counts the setups labs report. AI Labs Run AutomationBench and OSWorld in Different Ways shows which setups each lab uses.
OSWorld 2.1, full set, partial score
| Model | Score | Sources |
|---|---|---|
| Hy4Hy4 | 78.9% | Announcement'Appendix: benchmark results' table image, row 'OSWorld 2.1 (Full, partial score)', column 'Hy4' |
| Muse EmberMuse EmberOSWorld 2.1 paragraph, p.4: “We run all 108 tasks in a common internal framework” | 69.5% | Announcement'Muse Ember evaluation results' table (HTML), row 'Multimodal / OSWorld 2.1', column 'Muse Ember (max)', the value marked '(partial)' |
OSWorld 2.1, full set, strict pass rate
| Model | Score | Sources |
|---|---|---|
| Muse EmberMuse EmberOSWorld 2.1 paragraph, p.4: “We run all 108 tasks in a common internal framework” | 33.8% | Announcement'Muse Ember evaluation results' table (HTML), row 'Multimodal / OSWorld 2.1', column 'Muse Ember (max)', the value marked '(binary)' |
OSWorld 2.1, offline set, partial score
OSWorld 2.1, offline set, strict pass rate
OSWorld 2.1, offline set, scoring not stated
OSWorld 2.1, task set and scoring not stated
| Model | Score | Sources |
|---|---|---|
| Kimi K3.1 ProKimi K3.1 Pro | 79.6% | Announcement'Benchmarks' table (rendered by the page's script), row 'OSWorld V2.1', column 'Kimi K3.1 Pro (max)' (first column) |
OSWorld 2.1 offline set, OpenAI models run by Anthropic
| Model | Value | Sources |
|---|---|---|
| GPT-6 AstraGPT-6 Astra, partial score, run by Anthropic | 79.5% | Claude Fable 5.2 and Claude Mythos 5.2 System CardSection 8.13.3 'OSWorld 2.1 offline set', Figure 8.13.3.A, bar 'GPT-6 Astra', 'Partial' (value label 79.5) |
| GPT-6 AstraGPT-6 Astra, strict pass rate, run by Anthropic | 44.9% | Claude Fable 5.2 and Claude Mythos 5.2 System CardSection 8.13.3 'OSWorld 2.1 offline set', Figure 8.13.3.A, bar 'GPT-6 Astra', 'Strict' (value label 44.9) |
| GPT-6.1 SolGPT-6.1 Sol, partial score, run by Anthropic | 76.6% | Claude Fable 5.2 and Claude Mythos 5.2 System CardSection 8.13.3 'OSWorld 2.1 offline set', Figure 8.13.3.A, bar 'GPT-6.1 Sol', 'Partial' (value label 76.6) |
| GPT-6.1 SolGPT-6.1 Sol, strict pass rate, run by Anthropic | 39.8% | Claude Fable 5.2 and Claude Mythos 5.2 System CardSection 8.13.3 'OSWorld 2.1 offline set', Figure 8.13.3.A, bar 'GPT-6.1 Sol', 'Strict' (value label 39.8) |
OSWorld 2.1, OpenAI's own figure for GPT-6 Astra
| Model | Score | Sources |
|---|---|---|
| GPT-6 AstraGPT-6 Astra, offline set, scoring not stated | 80.9% | Introducing GPT-6.1 Terra"OSWorld 2.1, offline set" chart (score vs cost per task; no value labels): point 'GPT-6 Astra', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point) |
OSWorld 2.1 offline subset, in Google's Gemini 4 Carbon table
| Model | Value | Sources |
|---|---|---|
| GPT-6 AstraGPT-6 Astra, as Google printed it | 80.9% | Gemini 4 Carbon: our next frontier modelbenchmark table (image), row 'OSWorld-2.1', 'Offline subset', column 'GPT-6 Astra' |
OSWorld 2.1, in Moonshot AI's Kimi K3.1 Pro table
| Model | Value | Sources |
|---|---|---|
| Claude Fable 5.1 and Mythos 5.1Claude Fable 5.1, as Moonshot printed it | 80.7% | Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence'Benchmarks' table (rendered by the page's script), row 'OSWorld V2.1', column 'Claude Fable 5.1 (max, with fallback)' |
| Claude Opus 5.5Claude Opus 5.5, as Moonshot printed it | 81.8% | Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence'Benchmarks' table (rendered by the page's script), row 'OSWorld V2.1', column 'Claude Opus 5.5 (max, with fallback)' |
OSWorld 2.1 full set, partial score, Anthropic's own figures
OSWorld 2.1, in Tencent's Hy4 table
| Model | Value | Sources |
|---|---|---|
| Claude Opus 5.5Claude Opus 5.5, as Tencent printed it | 81.8% | Introducing Hy4'Appendix: benchmark results' table image, row 'OSWorld 2.1 (Full, partial score)', column 'Claude Opus 5.5' (no asterisk) |
| Kimi K3.1 ProKimi K3.1 Pro, as Tencent printed it | 79.6% | Introducing Hy4'Appendix: benchmark results' table image, row 'OSWorld 2.1 (Full, partial score)', column 'Kimi K3.1 Pro' (no asterisk) |
OSWorld 2.1 offline set, the competitor in OpenAI's GPT-6.1 Terra chart
| Model | Value | Sources |
|---|---|---|
| Claude Sonnet 5.5Claude Sonnet 5.5, max effort, as OpenAI charted it | 83.9% | Introducing GPT-6.1 Terra'OSWorld 2.1, offline set' chart (score vs cost; no value labels): point 'Claude Sonnet 5.5', effort 'Max', read from the point's aria-label |
| Claude Sonnet 5.5Claude Sonnet 5.5, offline set, partial score, as Anthropic reports it | 83.9% | Introducing Claude Haiku 5.5benchmark table (HTML), row 'Computer use / OSWorld 2.1', column 'Sonnet 5.5', the value tagged 'Offline subset' |
OSWorld 2.1, GPT-6 Astra in Moonshot AI's and Meta's tables
OSWorld 2.1, DeepSeek-V4.1-Flash-1017 in Moonshot AI's table
| Model | Value | Sources |
|---|---|---|
| DeepSeek-V4.1-Flash-1017DeepSeek-V4.1-Flash-1017, as Moonshot printed it | 69.3% | Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence'Benchmarks' table (rendered by the page's script), row 'OSWorld V2.1', column 'DeepSeek-V4.1-Flash-1017 (max)' |
OSWorld 2.1, in Anthropic's Claude Sonnet 5.5 system card
| Model | Value | Sources |
|---|---|---|
| Claude Opus 5.5Claude Opus 5.5, partial score, 108 tasks | 81.8% | Claude Sonnet 5.5 System CardSection 8.13.3 'OSWorld 2.1' (a benchmark of '108 long-horizon computer use tasks'), text: 'Claude Opus 5.5 scored 81.8% partial and 48.7% strict pass' |
Sources
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- Tencent, Nov 4, 2026Introducing Hy4
- OpenAI, Sep 29, 2026Introducing GPT-6.1 Sol
- OpenAI, Oct 26, 2026Introducing GPT-6.1 Terra
- Meta, Nov 9, 2026Introducing Our Smallest, Most Efficient Model: Muse Ember
- Meta, Oct 12, 2026Muse Wonder: A Frontier Model For Personal & Professional AI Agents
- Meta, Nov 9, 2026Muse Ember Evaluation Methodology
- Meta, Oct 12, 2026Muse Wonder model card
- Google, Oct 28, 2026Gemini 4 Carbon Model evaluation: approach, methodology & results
- Anthropic, Nov 9, 2026Claude Fable 5.2 and Claude Mythos 5.2 System Card
- Anthropic, Nov 9, 2026Introducing Claude Fable 5.2 and Claude Mythos 5.2
- Anthropic, Oct 7, 2026Introducing Claude Haiku 5.5
- Anthropic, Oct 7, 2026Claude Haiku 5.5 System Card
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- Anthropic, Sep 28, 2026Claude Sonnet 5.5 System Card
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence