AI Labs Run AutomationBench and OSWorld in Different Ways
Labs that report AutomationBench and OSWorld 2.1 choose different task sets and scoring rules. Only Anthropic reports all four OSWorld setups for one model.
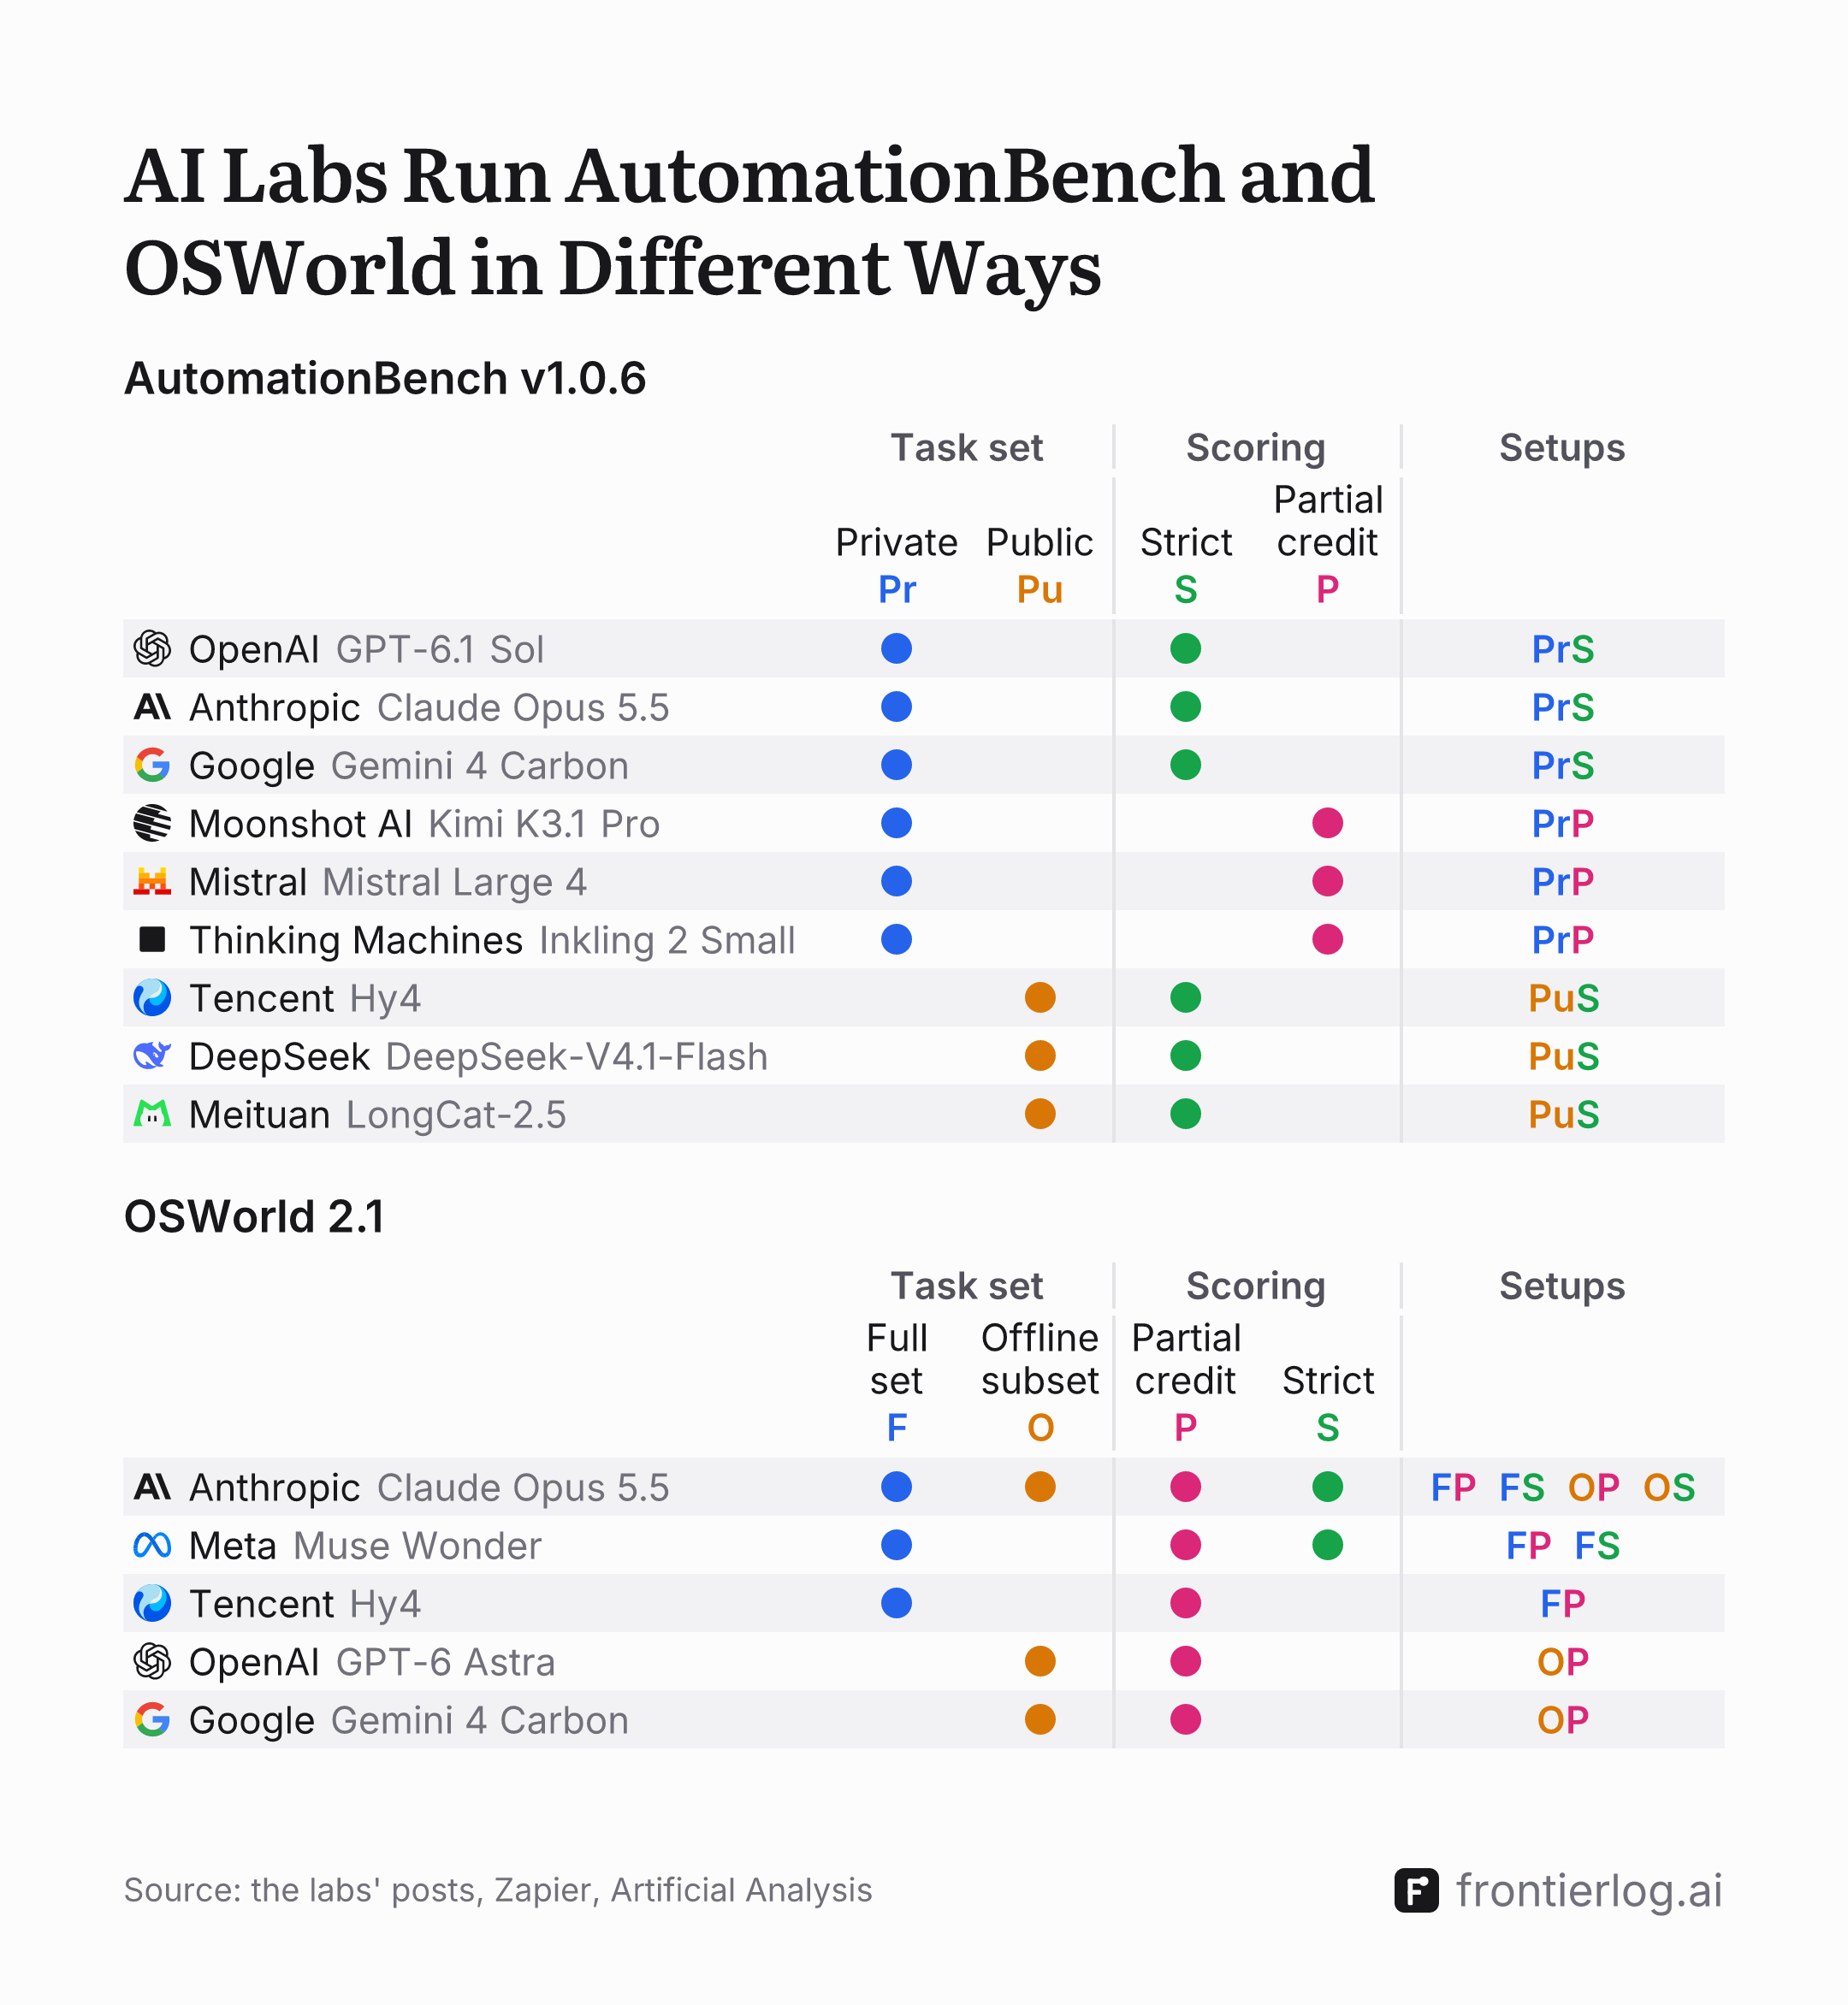
When two labs report the same benchmark, they often ran it in different ways. On AutomationBench, Zapier's test of AI agents on business workflows, the labs' figures come from two task sets, scored in two ways. On OSWorld 2.1, a test of agents using a computer, they come from a full set and an offline subset, each scored two ways. Of the labs we cover, only Anthropic reports all four OSWorld setups for one model.
Three setups on AutomationBench
Zapier scores its leaderboard on a private task set it doesn't release, and counts a task as passed only when it is completed correctly. Its README says the private set "is purposely harder" than the 600 public tasks. Anthropic's Claude Sonnet 5.5 system card says its results are on "Zapier's private evaluation set", and Claude Opus 5.5 scored 40.0% there. Google's figure of 53.9% for Gemini 4 Carbon uses the private set, its methodology says. OpenAI's GPT-6.1 Sol post links its AutomationBench figures to Zapier's leaderboard and gives 36.1% at max effort.
Tencent, DeepSeek and Meituan report their own runs on the public tasks. Tencent's Hy4 scored 56.2%, DeepSeek's V4.1-Flash 54.8% and Meituan's LongCat-2.5 51.8%. DeepSeek gives the figure as pass@1, the share of tasks passed on one attempt, and names the public set in its technical report.
Moonshot AI, Mistral and Thinking Machines print Artificial Analysis's version instead. Its methodology says it runs a private 657-task split. A task earns the share of its objectives completed, or 0 if the model breaks a guardrail or the task errors, so a task can earn partial credit. Kimi K3.1 Pro scored 73.3% there, Mistral Large 4 59.9% and Inkling 2 Small 45.6%.
Four setups on OSWorld 2.1
OSWorld 2.1 gives a partial score for each task and a strict pass rate, on its full task set or on an 82-task subset that runs with no internet access. Anthropic reports Claude Opus 5.5 in all four: 81.8% on the full set with partial credit and 48.7% strict, 87.2% on the offline subset with partial credit and 53.2% strict. Meta reports Muse Wonder on 108 tasks, 72.6% with partial credit and 34.3% strict. Tencent reports Hy4 at 78.9% with partial credit.
OpenAI and Google report only the offline subset. OpenAI's GPT-6.1 Terra post charts GPT-6 Astra at 80.9% at max effort without naming the scoring. Its GPT-6.1 Sol post says of the earlier OSWorld 2.0 that "we report the partial reward on the offline set". Google's Gemini 4 Carbon post prints the same 80.9% for GPT-6 Astra on its offline-subset row, next to 81.5% for Gemini 4 Carbon. Its methodology says it reports "the partial score from the offline subset".
What the matrix leaves out
The image marks the task set and scoring rule behind each lab's figure, as the lab's post, the methodology it cites, the benchmark's own scoring or another lab's report of the same figure states them. Each column is a setting at least two labs report, and every AutomationBench figure is one its source, or the leaderboard or methodology it draws on, ties to release v1.0.6. Other settings change a score too: the agent harness, the effort setting, the number of runs and fallback models. The image leaves them out.
Some labs report a figure without enough detail to place it. MiniMax and Ricursive name the AutomationBench public set but not the scoring. Meta's Muse Spark 1.3 figure, on "the public v3 task set", and Alibaba's Qwen3.8-Max figure don't name an AutomationBench release. Z.ai doesn't name a set and says it incorporated "the fix for the null-type handling issue". Moonshot AI reports Kimi K3.1 Pro on OSWorld 2.1 without naming the set or the scoring.
AutomationBench, private set, strict
| Model | Score | Sources |
|---|---|---|
| Claude Opus 5.5Claude Opus 5.5, run by Zapier without fallback models | 40.0% | Announcementbenchmark table, row 'AutomationBench', column 'Opus 5.5' |
| GPT-6.1 SolGPT-6.1 Sol, max effort | 36.1% | AnnouncementAutomationBench chart under "Professional work" (score vs cost per task; no value labels): point 'GPT-6.1 Sol', effort 'Max', read from the point's aria-label (load the page in a browser and hover or inspect the SVG point) |
| Gemini 4 CarbonGemini 4 Carbon | 53.9% | Announcementbenchmark table (image), row 'AutomationBench', 'Zapier', column 'Gemini 4 Carbon' |
AutomationBench, private set, partial credit (Artificial Analysis)
AutomationBench, public set, strict
OSWorld 2.1
Sources
- Zapier, AutomationBench leaderboard, read Nov 8, 2026, Nov 8, 2026zapier.com/benchmarks
- Zapier, AutomationBench README, release 1.0.6, Aug 4, 2026github.com/zapier/AutomationBench/blob/4a8e106/README.md
- OpenAI, Sep 29, 2026Introducing GPT-6.1 Sol
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- Tencent, Nov 4, 2026Introducing Hy4
- Meituan, Nov 1, 2026LongCat-2.5: Native Multimodality for Agentic Tasks
- Meta, Sep 2, 2026Introducing Muse Spark 1.3
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- Artificial Analysis, methodology page, read Nov 8, 2026, Nov 8, 2026artificialanalysis.ai/methodology/intelligence-benchmarking
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence
- Mistral, Oct 6, 2026Introducing Mistral Large 4
- Thinking Machines, Nov 5, 2026Inkling 2 Small Model Card
- Meta, Oct 12, 2026Muse Wonder: A Frontier Model For Personal & Professional AI Agents
- Anthropic, Sep 28, 2026Claude Sonnet 5.5 System Card
- Anthropic, Oct 7, 2026Claude Haiku 5.5 System Card
- Google, evaluation methodology, Oct 28, 2026deepmind.google/models/evals-methodology/gemini-4-carbon
- OpenAI, Oct 26, 2026Introducing GPT-6.1 Terra
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Smarter, Faster, More Efficient
- MiniMax, Oct 19, 2026MiniMax M3.1 Flash: Redefining Agent Performance and Cost
- Ricursive Intelligence, Nov 4, 2026Introducing Ripple-65B Preview, a Frontier Open-Weight Model
- Z.ai, Aug 14, 2026GLM-5.3: Frontier Coding with Emergent Cyber Capabilities
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression