Kimi K3.1 Pro
Post-trained Kimi K3 and Moonshot's most capable 3T-class open-weight model, with a 1M-token context window and a faster Highspeed variant.
Introducing Kimi K3.1 Pro, our most capable 3T-class open-weight model with 1M-token context and major advances in coding, 3D modeling, and financial research.
Official source
Kimi K3.1 Pro Tech Blog: Advancing Open Intelligencekimi.ai · published
Follow-ups
Kimi K3.1 Pro
| Benchmark | Score | Source check |
|---|---|---|
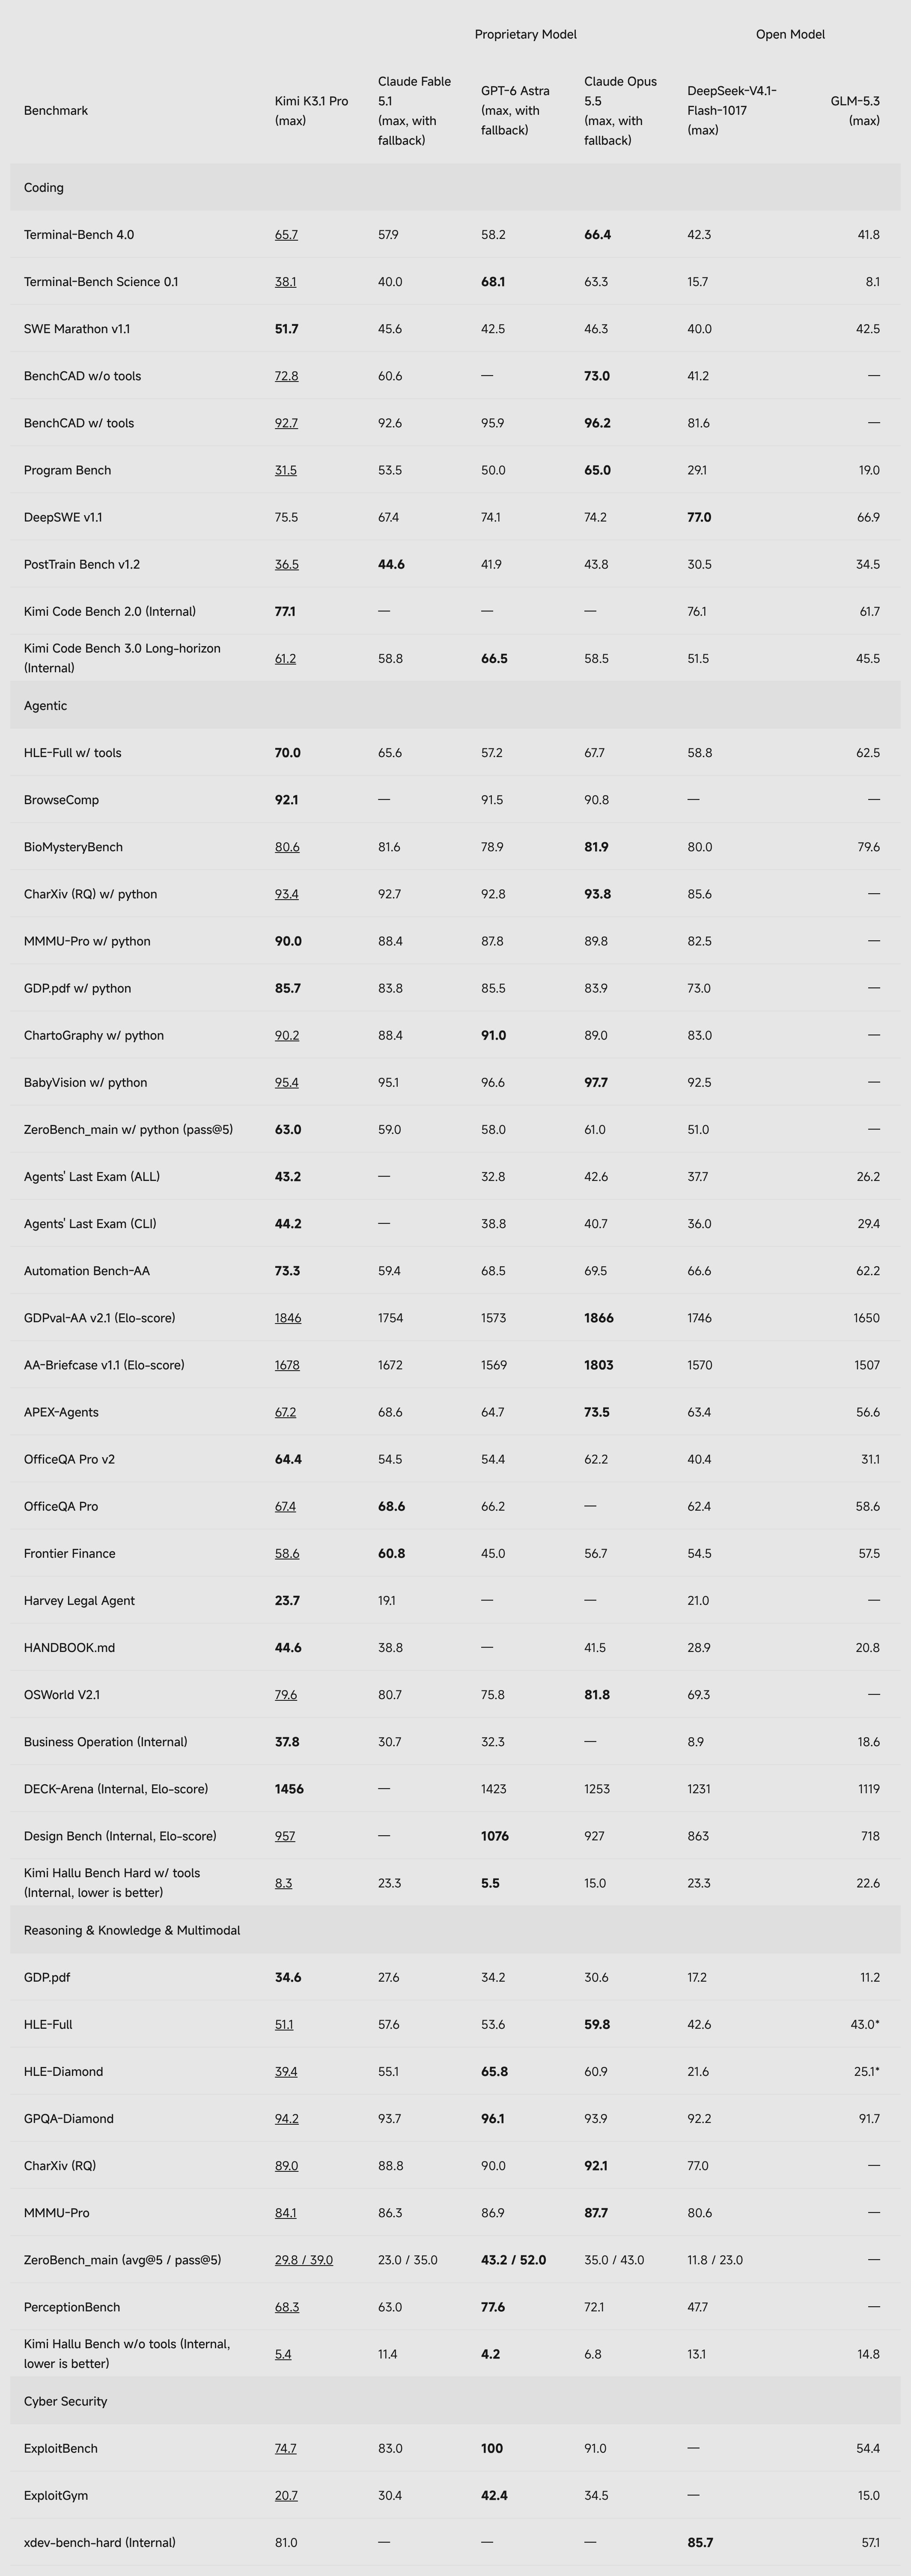
| Humanity's Last ExamNo tools · full set; max reasoning effort | 51.1% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Humanity's Last ExamWith tools · full set; max reasoning effort | 70.0% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| GPQA Diamondmax reasoning effort | 94.2% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| BrowseCompmax reasoning effort; context compaction at 200K tokens; 500-step limit | 92.1% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 4.0Claude Code harness; max reasoning effort | 65.7% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench Science 0.1Claude Code harness; max reasoning effort | 38.1% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| DeepSWE v1.1Claude Code harness; max reasoning effort | 75.5% | CheckedA person checked this number against its source on 24 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
Sources
Reported by Moonshot AI
- Kimi K3.1 Pro Tech Blog: Advancing Open Intelligencekimi.ai · 24 Oct 2026
Our capture of the source