Who Leads Terminal-Bench 4.0 Depends on Who Ran It
Vals AI ranks Claude Opus 5.5 first on Terminal-Bench 4.0. Artificial Analysis, running the same harness, ranks Kimi K3.1 Pro first.
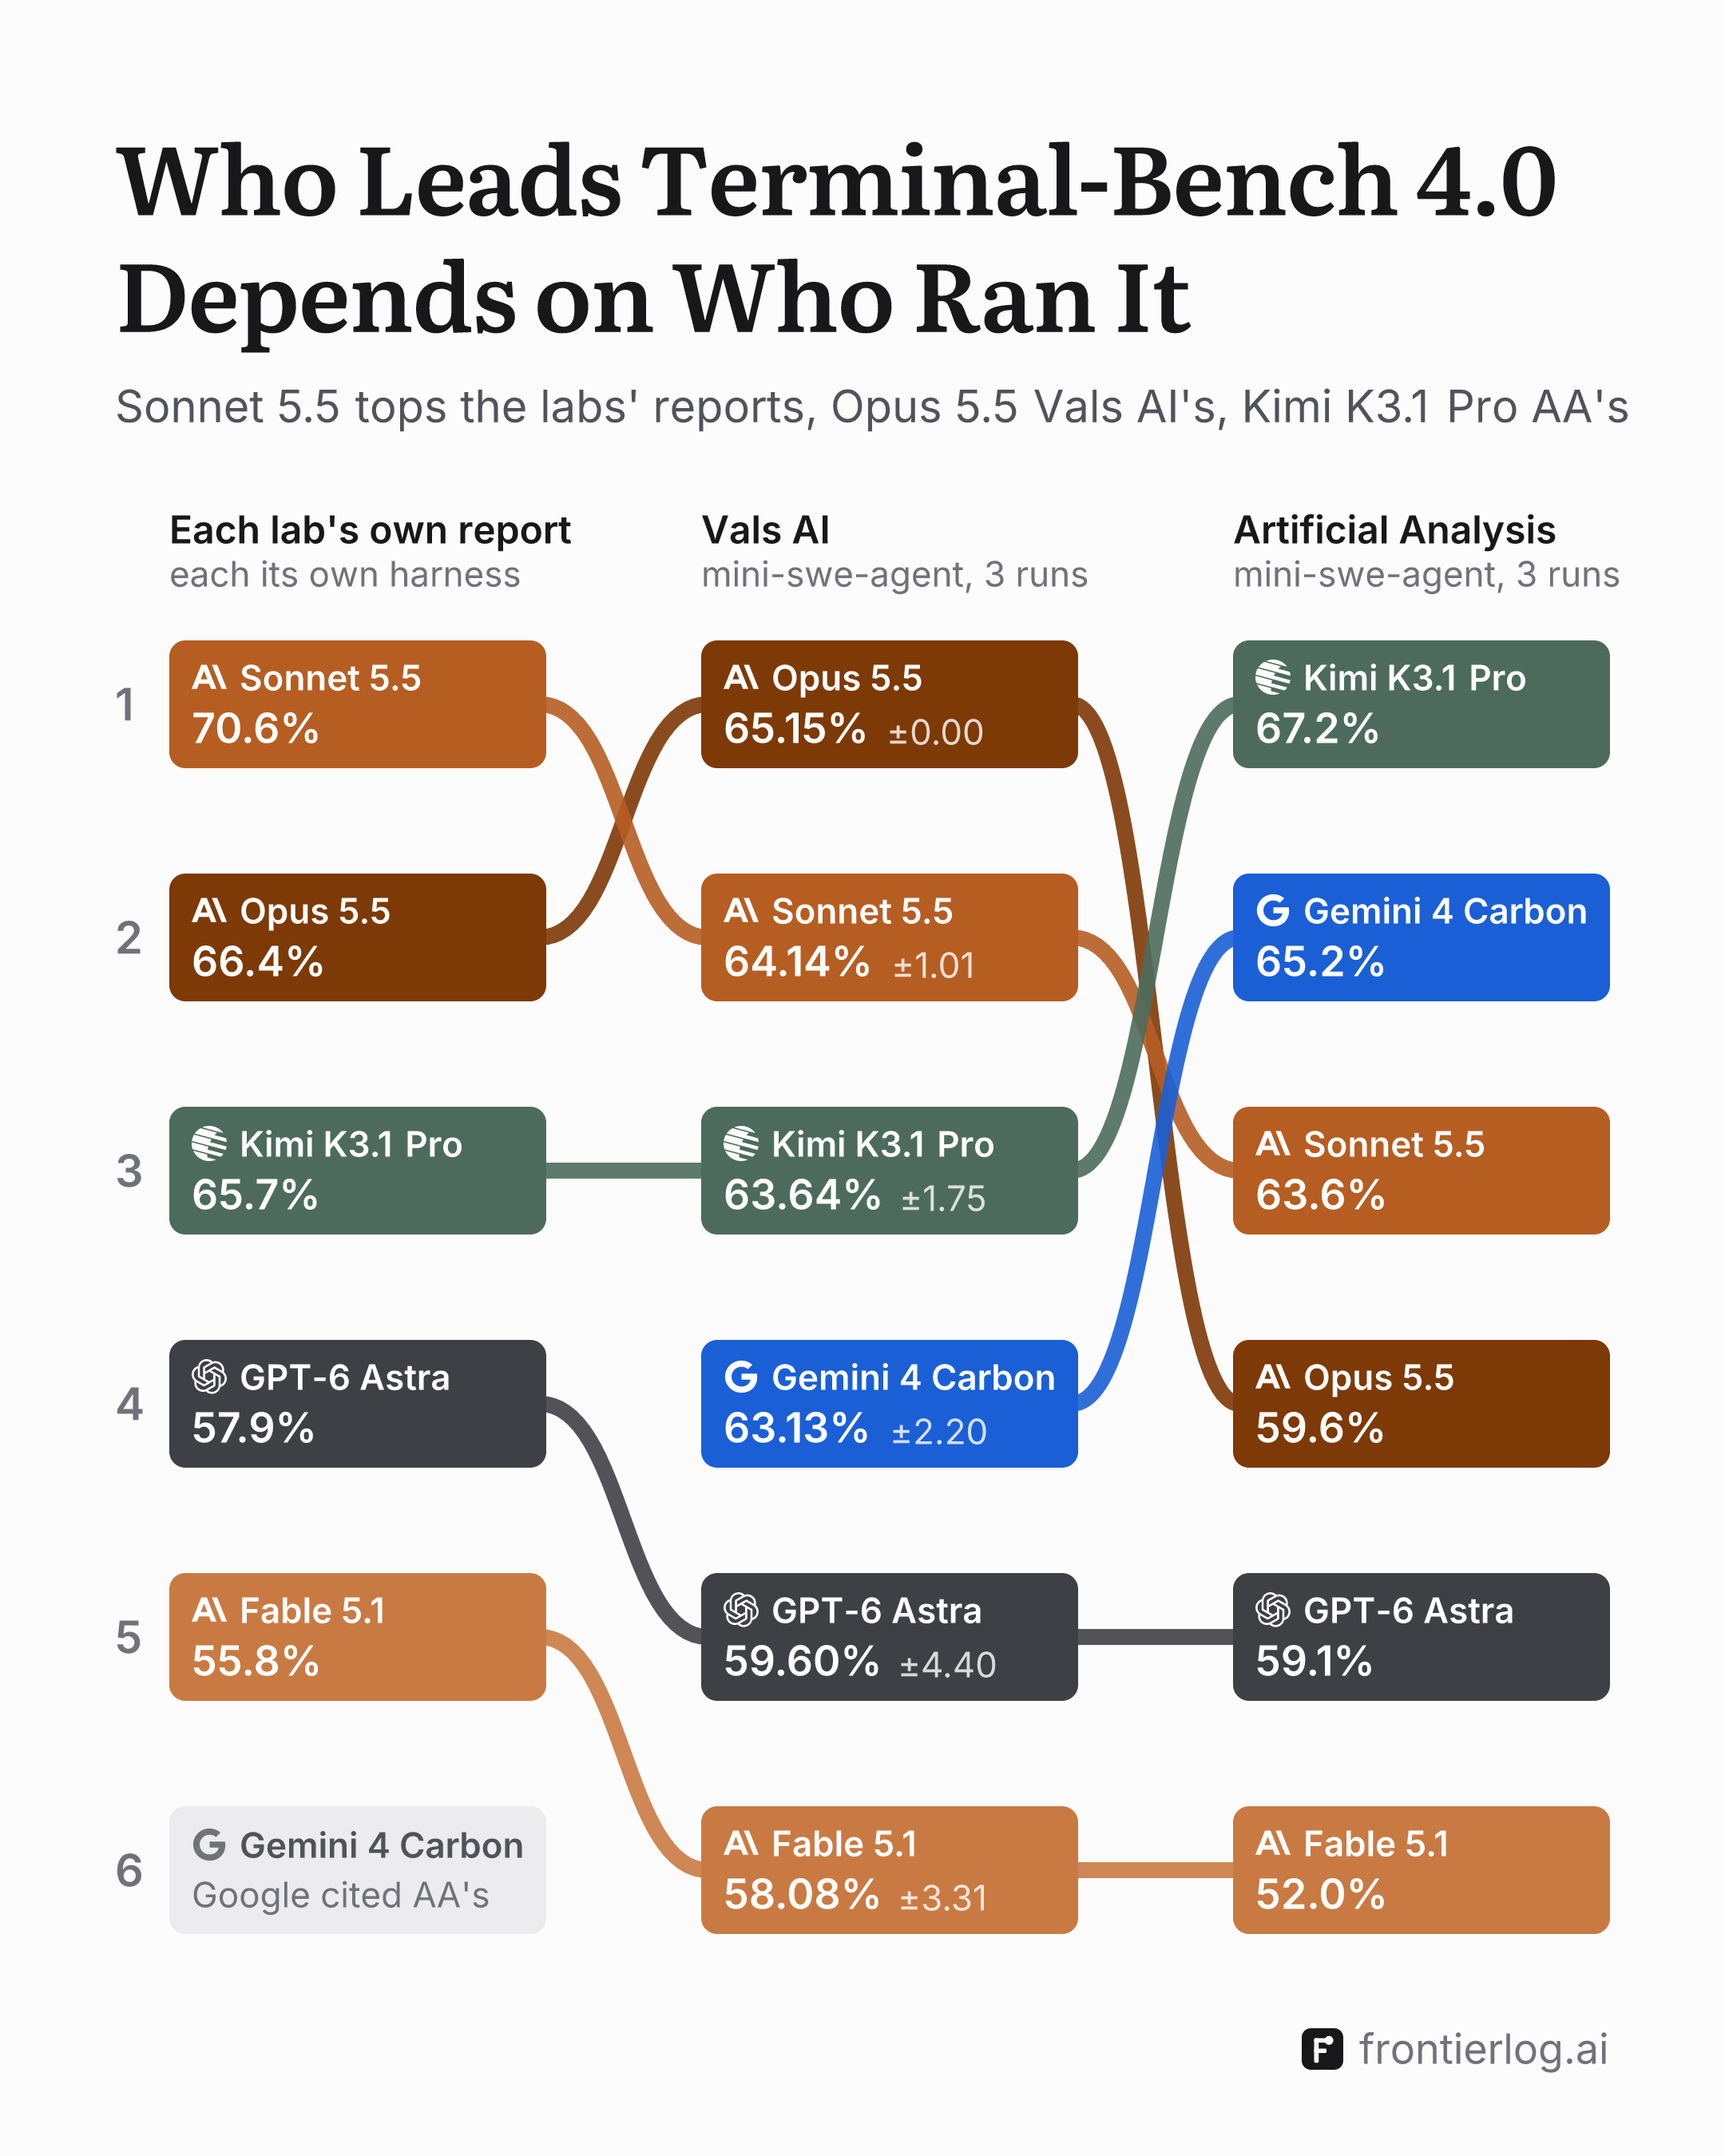
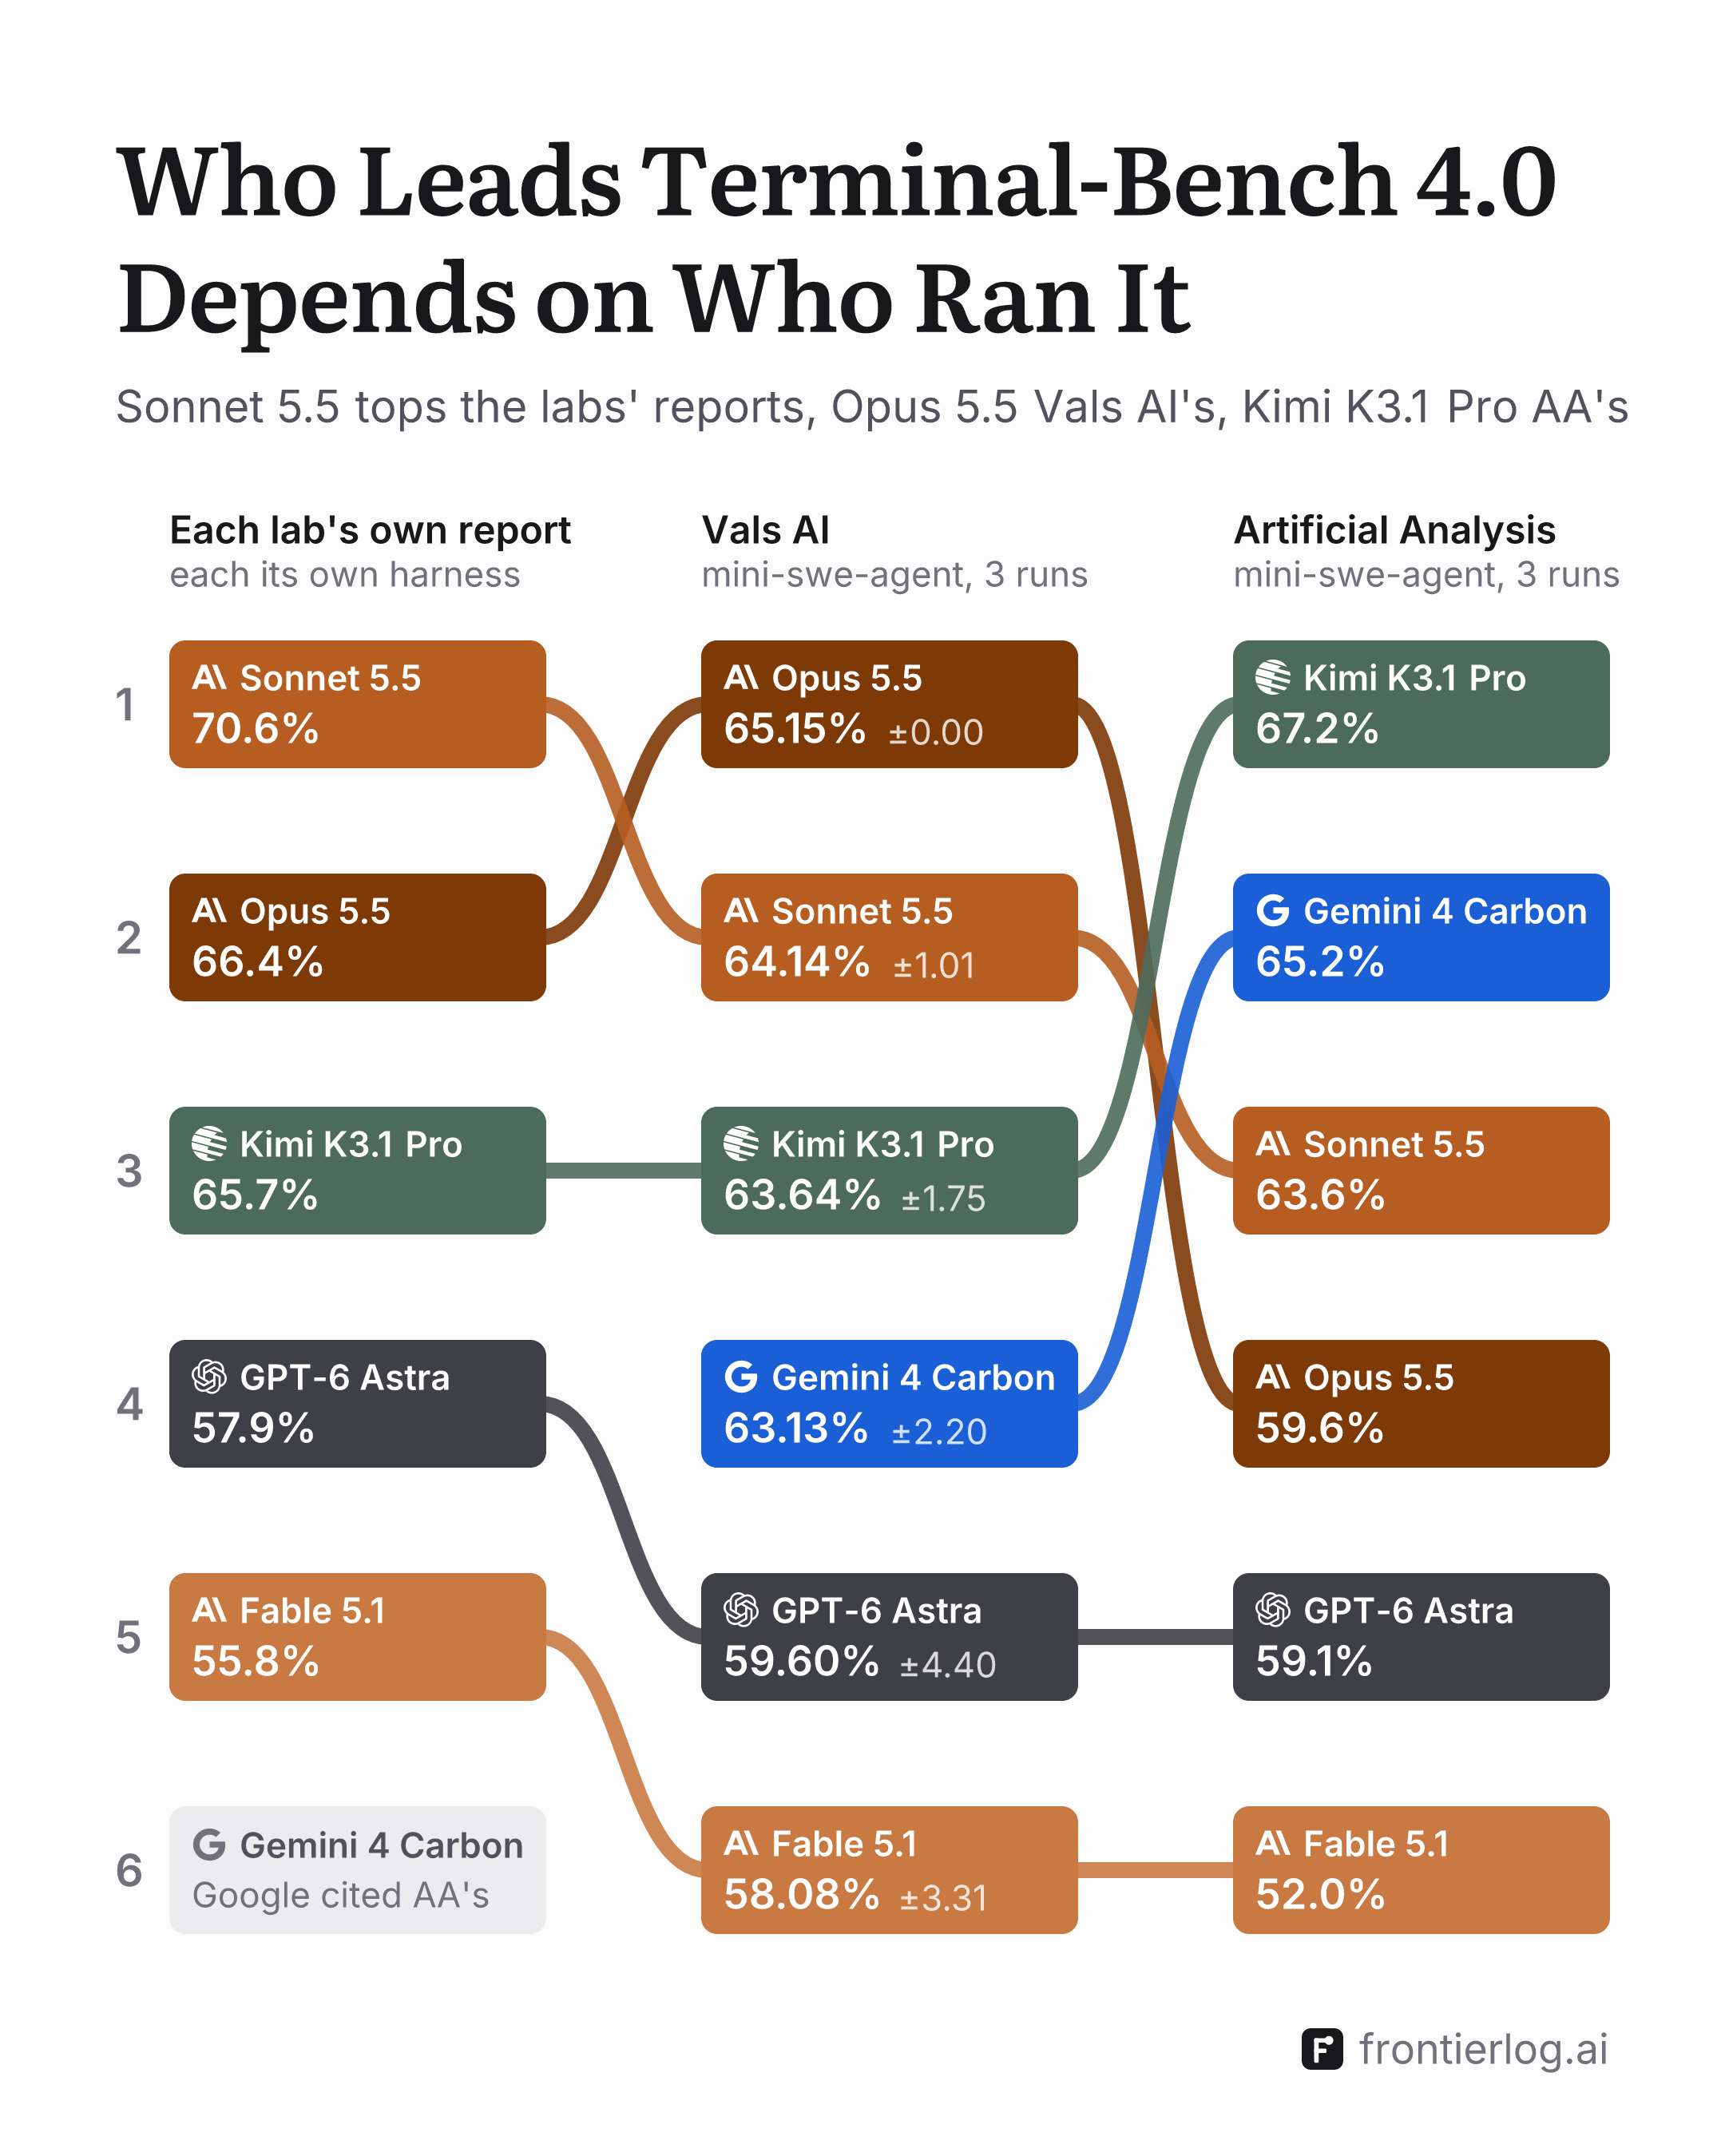
Vals AI and Artificial Analysis both publish Terminal-Bench 4.0 scores run with the same agent harness, mini-swe-agent, on all 66 of the benchmark's tasks. On Oct 29 they put different models first. Vals AI ranks Claude Opus 5.5 first at 65.15%, and Artificial Analysis ranks Kimi K3.1 Pro first at 67.2%, with Opus 5.5 fourth at 59.6%. Of the scores the labs reported for their own models, the highest is the 70.6% Anthropic reported for Claude Sonnet 5.5.
Same harness, different limits
Vals AI's methodology runs each model through the benchmark three times and reports the mean, with error bars showing "the standard error across those three runs". It says "there is no step or cost limit", and each task has an 8-hour agent time limit. Artificial Analysis's methodology reports pass@1 "averaged over 3 repeats per task", limits the agent to 500 steps and follows each task's own timeout. Its page prints no error bars.
Vals AI ran Opus 5.5 at "max" effort, with Claude Opus 5 and Claude Opus 4.8 "as server-side fallbacks for refusals", its model page says. It ran Kimi K3.1 Pro at max effort (model page) and Gemini 4 Carbon at high (model page). Artificial Analysis labels its Claude runs "Max, Default Fallback" and its Carbon run "High".
Within Vals AI's error bars
Vals AI's top four sit within 2.02 points: Opus 5.5 at 65.15% (±0.00), Sonnet 5.5 at 64.14% (±1.01), Kimi K3.1 Pro at 63.64% (±1.75) and Gemini 4 Carbon at 63.13% (±2.20). GPT-6 Astra's 59.60% carries the widest error bar, ±4.40.
Vals AI's own launch write-up of Sep 22, on its Opus 5.5 model page printed a Terminal-Bench 4.0 score of 61.62% for the model; its leaderboard now prints 65.15%.
The labs' own reports
Anthropic reported 66.4% for Opus 5.5 at "xhigh" effort, with a standard error of ±2.6 points and its production safeguards enabled, and 55.8% for Fable 5.1. Moonshot reported 65.7% for Kimi K3.1 Pro, evaluated with the Claude Code harness. OpenAI reported 57.9% for GPT-6 Astra. Google printed no Terminal-Bench 4.0 score of its own for Gemini 4 Carbon: its launch table used Artificial Analysis's 65.2% (Gemini 4 Carbon's Table Moves Rivals' Scores).
This story quotes Vals AI's and Artificial Analysis's published figures directly, an exception to Frontier Log's rule of recording only the labs' own reports, and makes no claim about which ranking is right. For how much the harness alone can move a score, see Does the Harness Version Change a Model's Score?.
Terminal-Bench 4.0, each lab's own report
Terminal-Bench 4.0, run by Vals AI
Terminal-Bench 4.0, Vals AI's standard error
Terminal-Bench 4.0, run by Artificial Analysis
Sources
- Anthropic, Sep 28, 2026Introducing Claude Sonnet 5.5
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- Anthropic, Sep 1, 2026Introducing Claude Fable 5.1 and Claude Mythos 5.1
- Vals AI, benchmark pagevals.ai/benchmarks/terminal-bench-4
- Vals AI, model pagevals.ai/models/anthropic_claude-opus-5-5
- Vals AI, model pagevals.ai/models/kimi_kimi-k3.1-pro
- Vals AI, model pagevals.ai/models/google_gemini-4-carbon
- Artificial Analysis, evaluation pageartificialanalysis.ai/evaluations/terminalbench-4-0
- Artificial Analysis, methodology pageartificialanalysis.ai/methodology/intelligence-benchmarking