Gemini 4 Carbon's Table Moves Rivals' Scores
Google's Gemini 4 Carbon table took Terminal-Bench 4.0 scores from Artificial Analysis; a month earlier, Argon's table had Claude Opus 5.5 6.8 points higher.
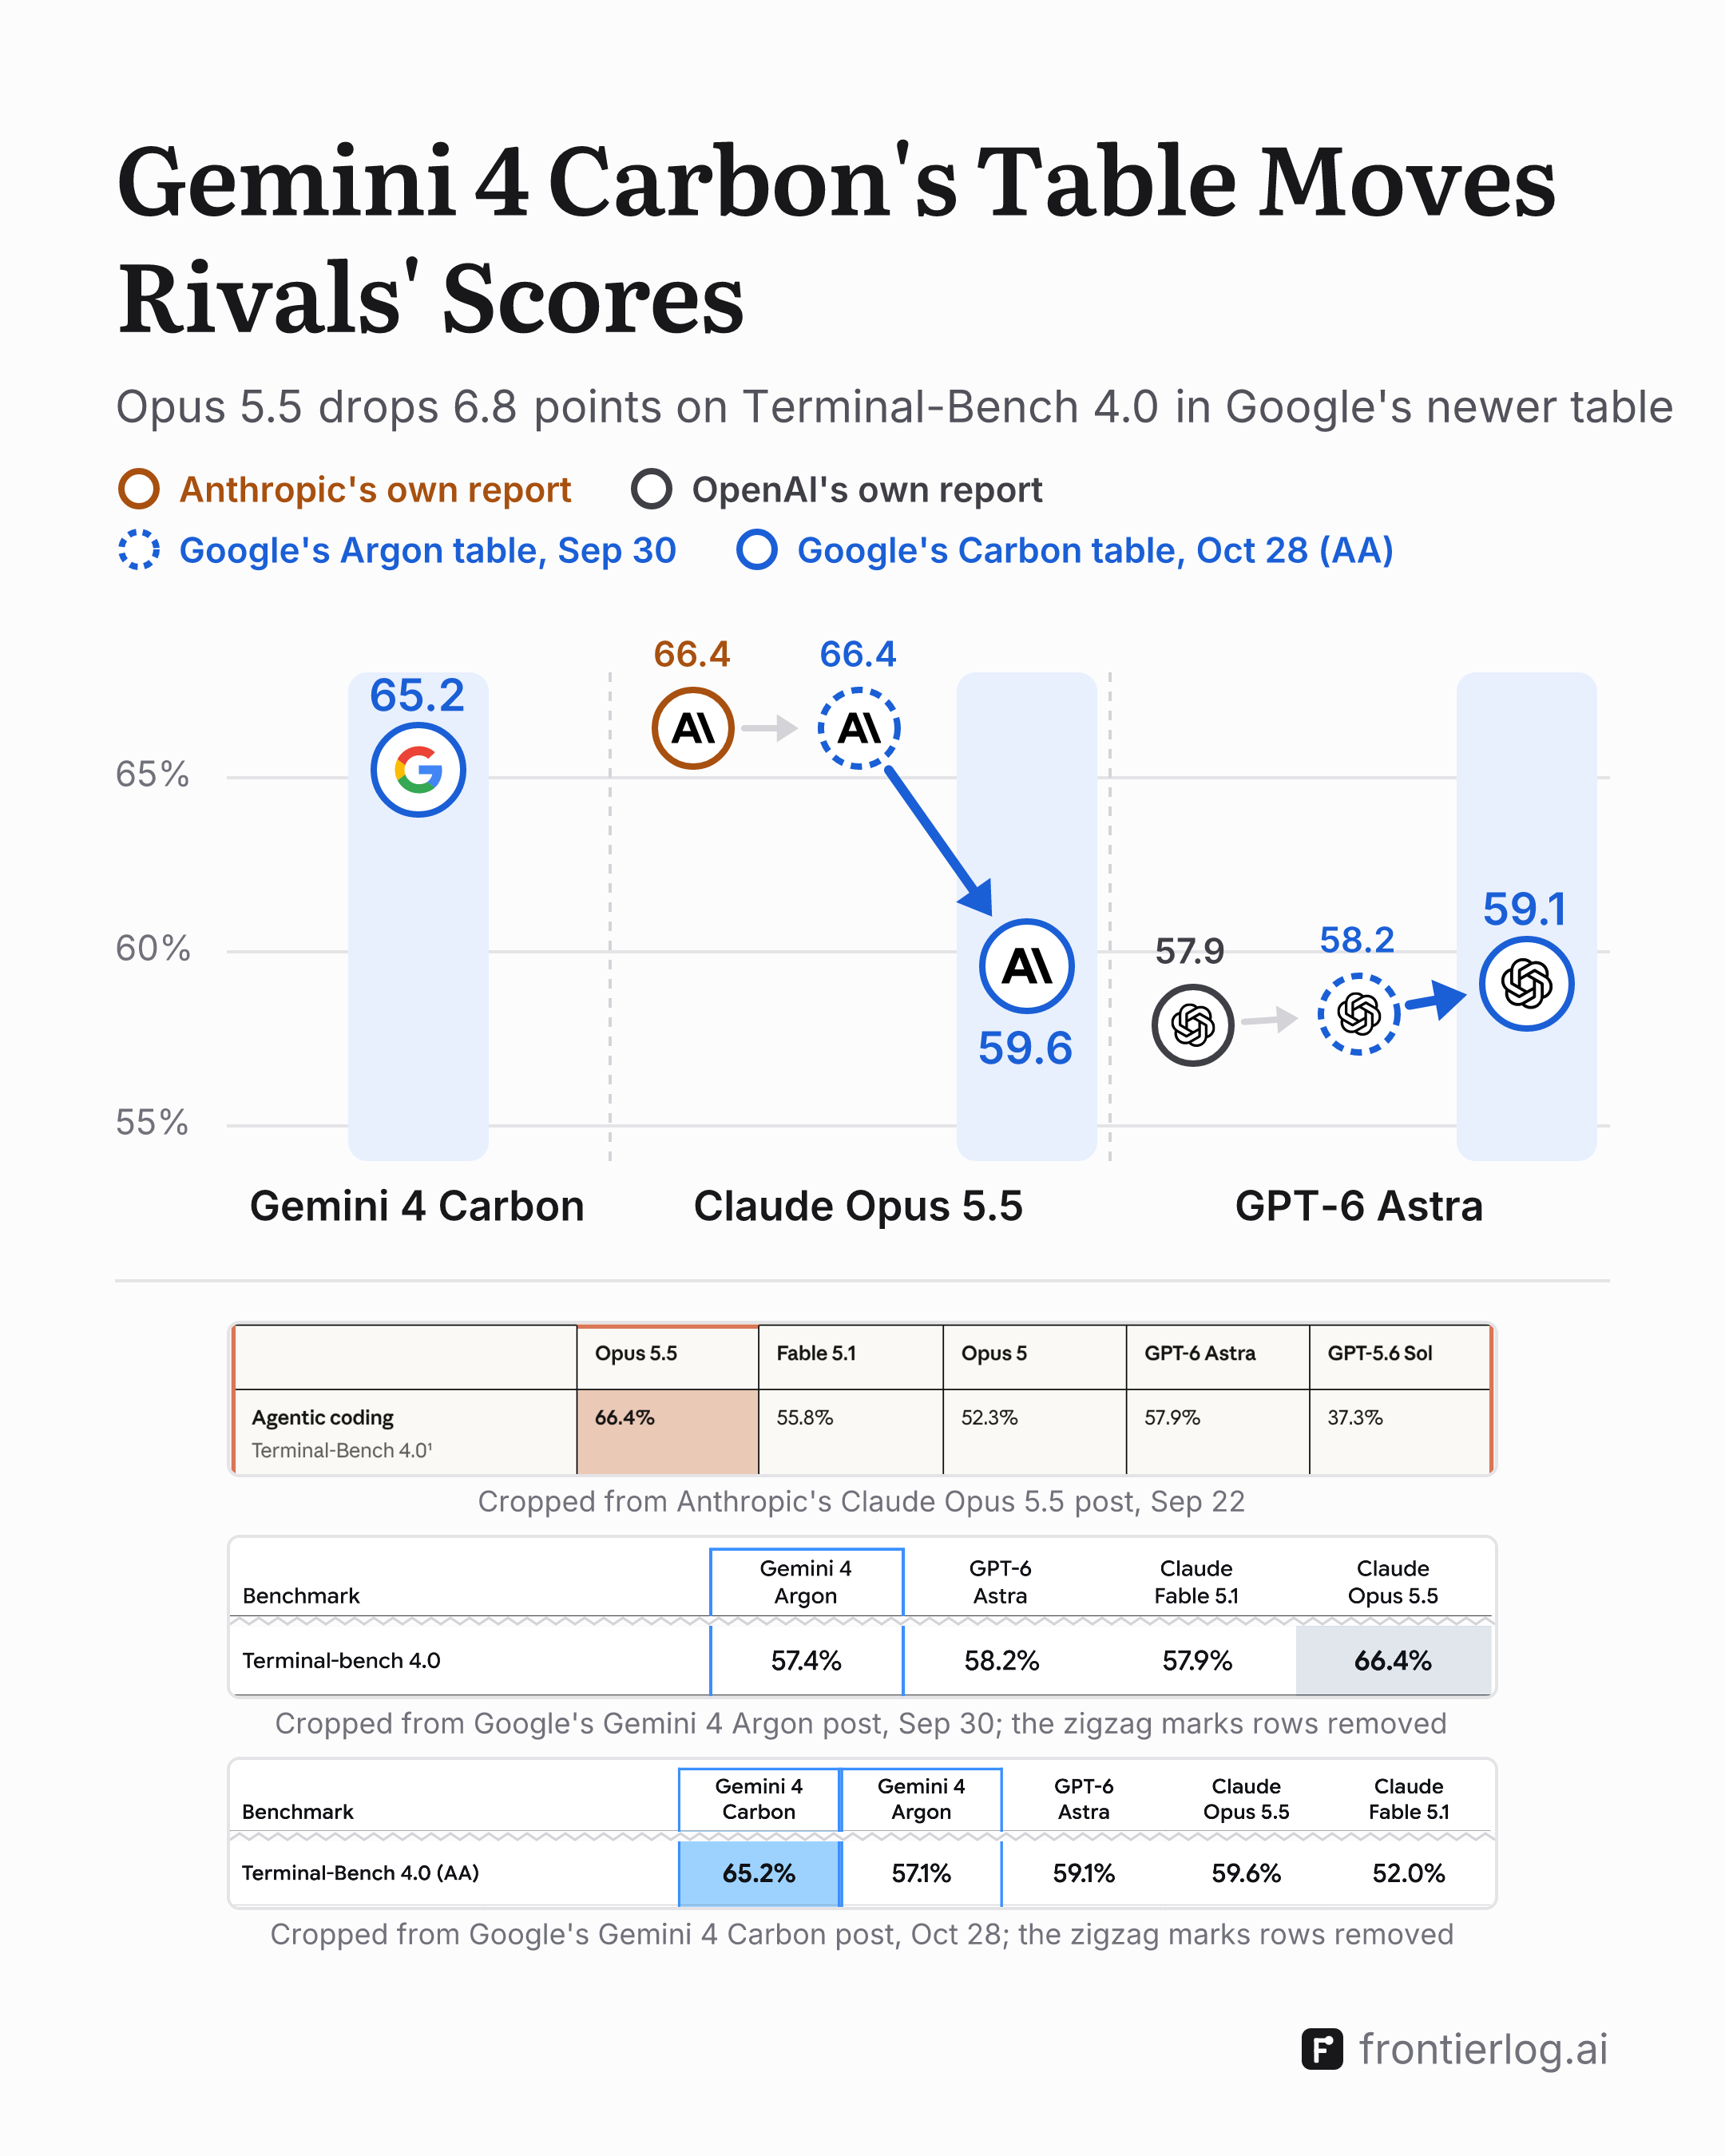
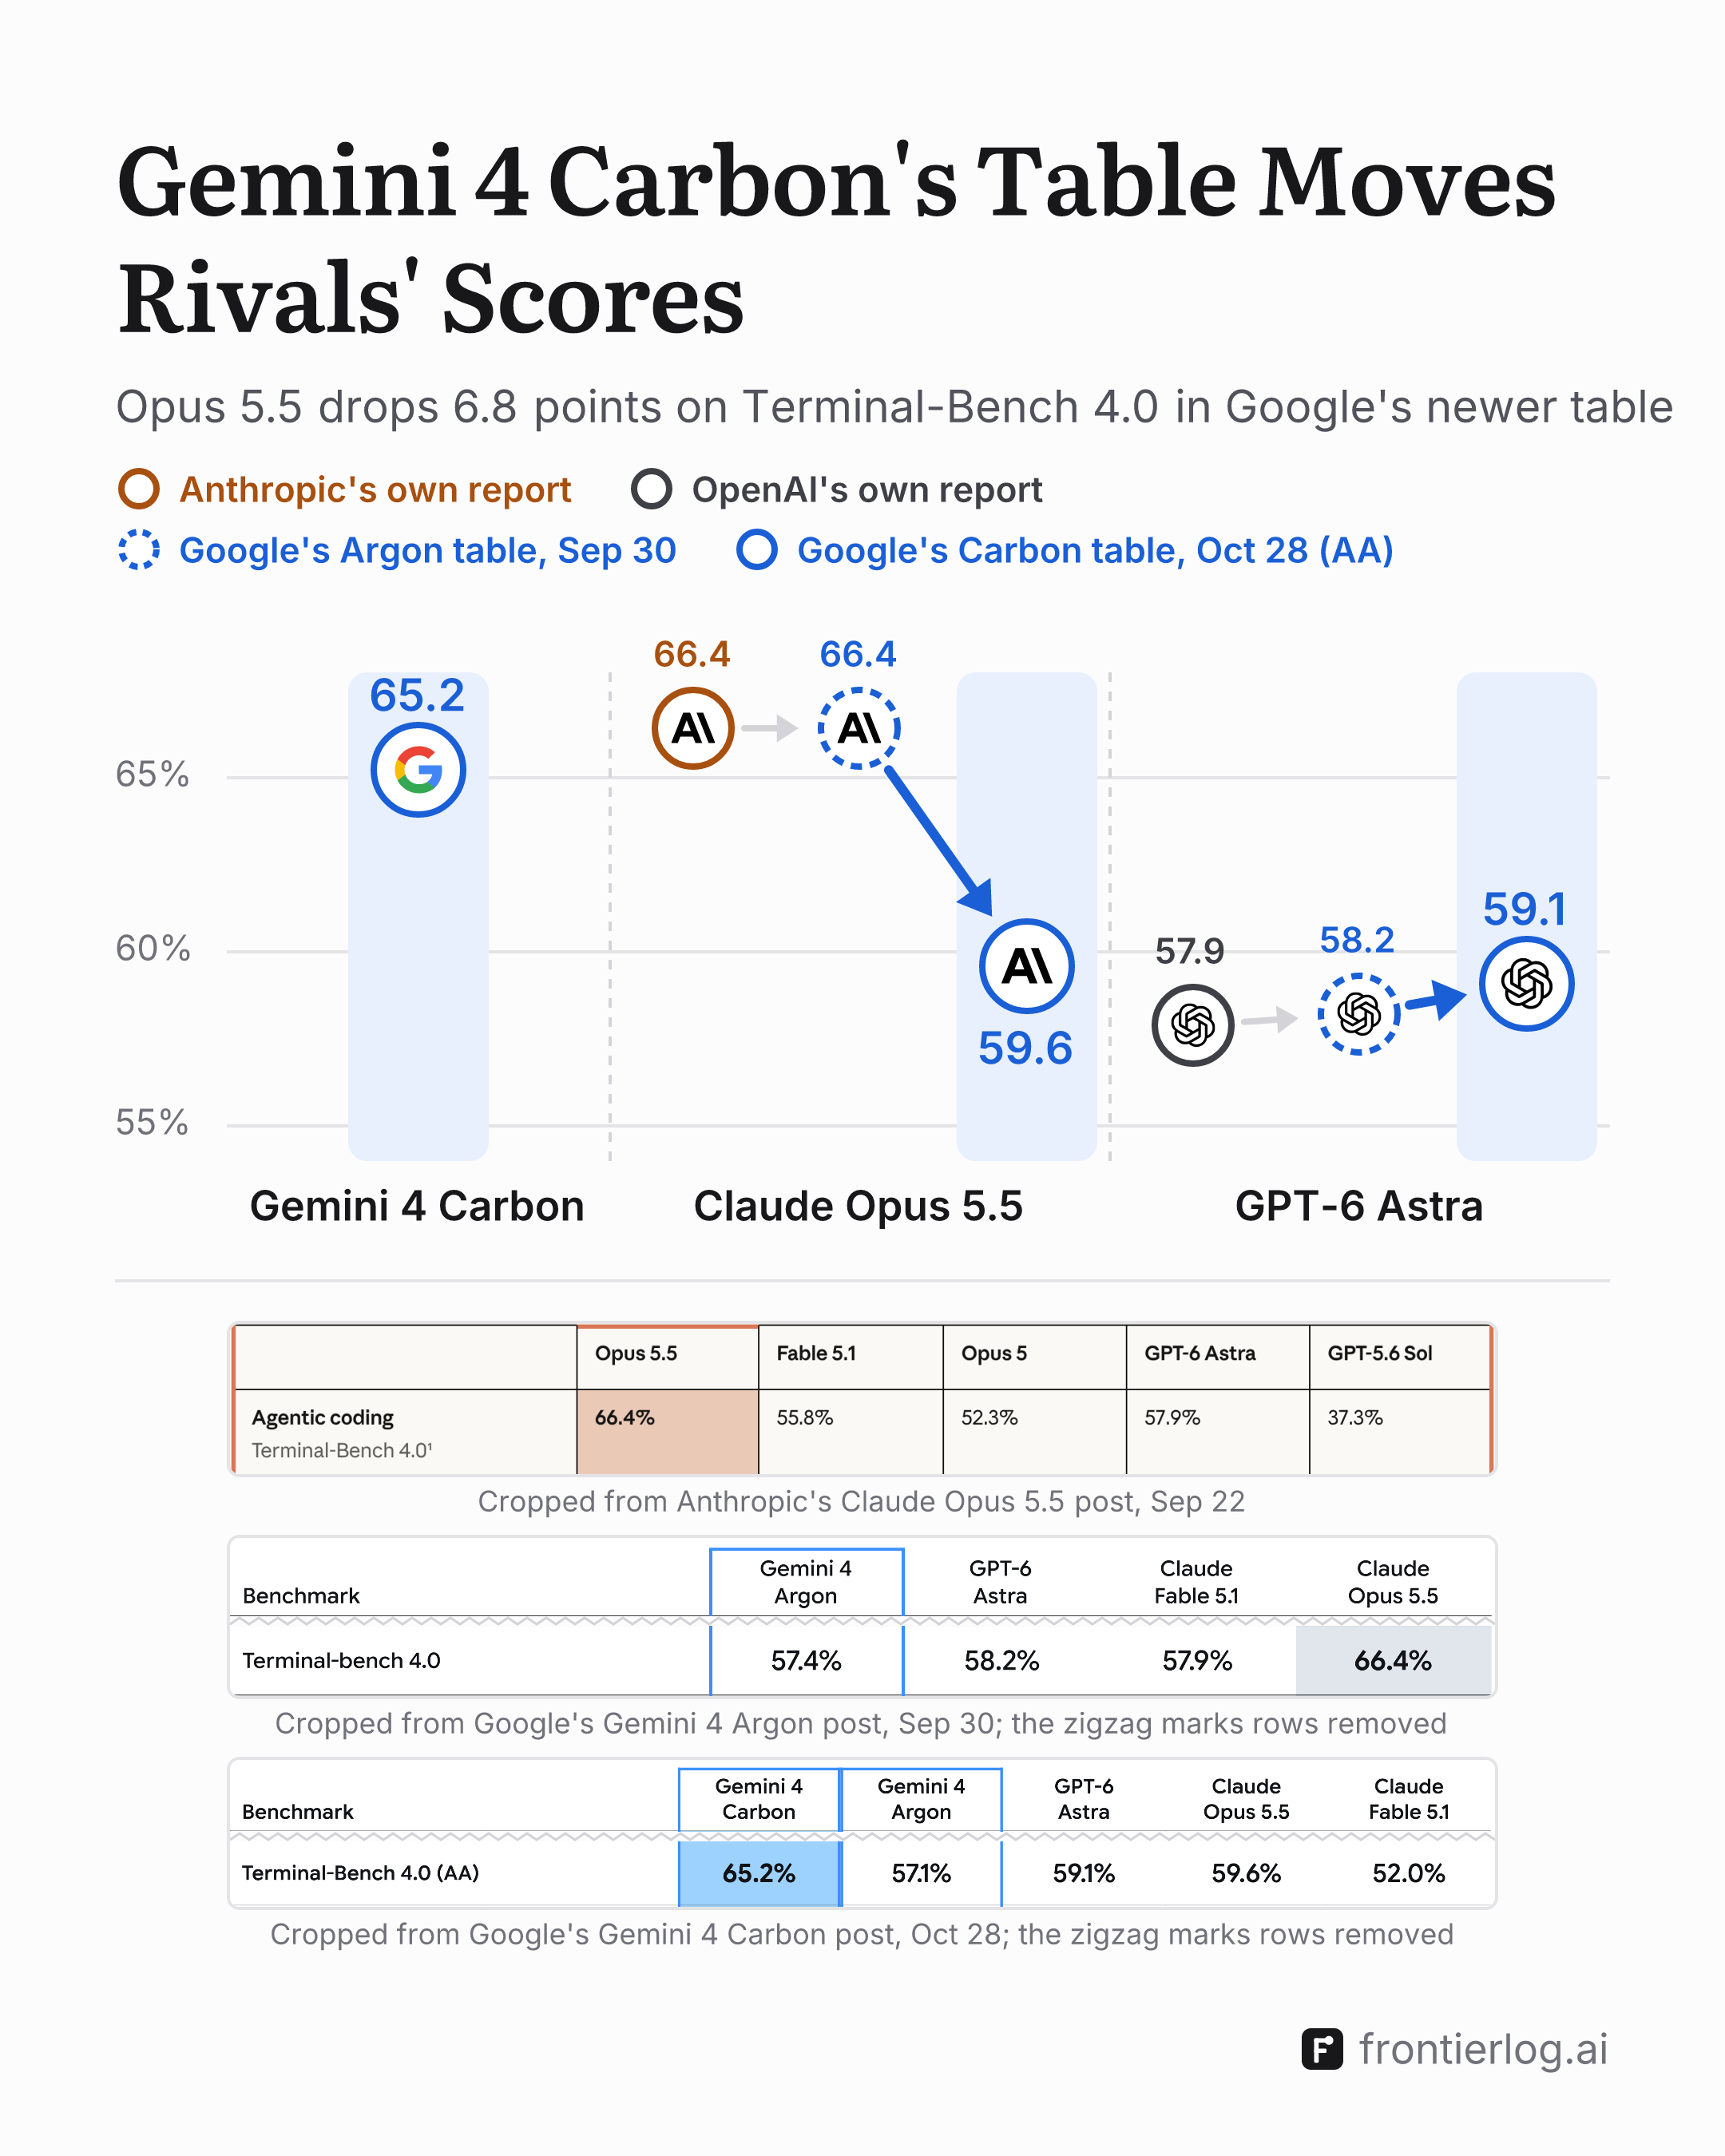
Google launched Gemini 4 Carbon on Oct 28 with a table comparing it with Gemini 4 Argon, GPT-6 Astra, Claude Opus 5.5 and Claude Fable 5.1. Its Terminal-Bench 4.0 row is marked "(AA)": Google's evaluation document says the results "are sourced from Artificial Analysis" for every model, Carbon included. Argon’s launch table printed the same row for the same four models on Sep 30, from other sources.
Three figures for most models
For Claude Opus 5.5, Anthropic reported 66.4% at its "xhigh" effort setting, and Argon's table printed the same 66.4%. Carbon's table prints 59.6%, 6.8 points lower. For Claude Fable 5.1, Anthropic reported 55.8%, Argon's table printed 57.9% and Carbon's prints 52.0%.
GPT-6 Astra moves the other way: OpenAI reported 57.9%, Argon's table printed 58.2% and Carbon's prints 59.1%. Google's own Argon scored 57.4% in Google's run at its launch and 57.1% in Artificial Analysis's figure in Carbon's table.
Where each table's figures came from
Argon's evaluation document says Google computed Argon's score itself and took the others "from the official public leaderboard", using "the highest scoring thinking level for each model as reported by the Terminal Bench authors". Carbon's document gives no harness or effort setting for the Artificial Analysis figures.
Carbon's own 65.2% is also Artificial Analysis's figure, and it is the top score in Carbon's row. In Argon's table, the top score was Opus 5.5's 66.4%.
For Gemini 3.8 Flash on Sep 2, Google took other models' Terminal-Bench 2.1 scores "from the public leaderboard and Artificial Analysis", its evaluation document says, without marking which came from where.
Two other launches printed AA's runs
Of the 70 flagship launch posts in Frontier Log's reporting inventory, from January 2025 to mid-October 2026, two printed Artificial Analysis's runs of benchmarks made by others. MiniMax-M2’s model card in October 2025 headed its table "Metric (AA)" and said all other models' scores came from Artificial Analysis. Mistral Large 4, on Oct 6, labelled its Terminal-Bench 4.0 chart "AA - Terminal-Bench 4". Benchmarks that Artificial Analysis builds itself, such as GDPval-AA, appear far more often.
For how much the agent harness alone can move one model's score, see Does the Harness Version Change a Model's Score?.
Terminal-Bench 4.0, each lab's own report
Terminal-Bench 4.0, in Google's Gemini 4 Argon table
| Model | Value | Sources |
|---|---|---|
| Gemini 4 ArgonGemini 4 Argon, computed by Google | 57.4% | Announcementbenchmark table (image), row 'Terminal-bench 4.0', column 'Gemini 4 Argon' |
| Gemini 4 ArgonGPT-6 Astra, from the public leaderboard | 58.2% | Announcementbenchmark table (image), row 'Terminal-bench 4.0', column 'GPT-6 Astra' |
| Gemini 4 ArgonClaude Opus 5.5, from the public leaderboard | 66.4% | Announcementbenchmark table (image), row 'Terminal-bench 4.0', column 'Claude Opus 5.5' |
| Gemini 4 ArgonClaude Fable 5.1, from the public leaderboard | 57.9% | Announcementbenchmark table (image), row 'Terminal-bench 4.0', column 'Claude Fable 5.1' |
Terminal-Bench 4.0, in Google's Gemini 4 Carbon table, from Artificial Analysis
| Model | Value | Sources |
|---|---|---|
| Gemini 4 CarbonGemini 4 Carbon, from Artificial Analysis | 65.2% | Announcementbenchmark table (image), row 'Terminal-Bench 4.0 (AA)', column 'Gemini 4 Carbon' |
| Gemini 4 CarbonGemini 4 Argon, from Artificial Analysis | 57.1% | Announcementbenchmark table (image), row 'Terminal-Bench 4.0 (AA)', column 'Gemini 4 Argon' |
| Gemini 4 CarbonGPT-6 Astra, from Artificial Analysis | 59.1% | Announcementbenchmark table (image), row 'Terminal-Bench 4.0 (AA)', column 'GPT-6 Astra' |
| Gemini 4 CarbonClaude Opus 5.5, from Artificial Analysis | 59.6% | Announcementbenchmark table (image), row 'Terminal-Bench 4.0 (AA)', column 'Claude Opus 5.5' |
| Gemini 4 CarbonClaude Fable 5.1, from Artificial Analysis | 52.0% | Announcementbenchmark table (image), row 'Terminal-Bench 4.0 (AA)', column 'Claude Fable 5.1' |
Timeline
- MiniMax MiniMax-M2's model card prints every model's scores from Artificial Analysis, under the heading 'Metric (AA)'MiniMax, model card, launch-day revision
- Google Gemini 3.8 Flash's table takes other models' Terminal-Bench 2.1 scores from the leaderboard and Artificial AnalysisGoogle, model evaluation document
- Google Gemini 4 Argon's table computes Argon's Terminal-Bench scores itself and takes other models' from the leaderboardGoogle, model evaluation document
- Mistral AI Mistral Large 4's Terminal-Bench 4.0 chart is labelled 'AA - Terminal-Bench 4'Mistral AI, blog post
- Google Gemini 4 Carbon's table takes both Terminal-Bench rows from Artificial Analysis for every modelGoogle, model evaluation document
Sources
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- Google, model evaluation document, Oct 28, 2026Gemini 4 Carbon Model evaluation: approach, methodology & results
- Google, Sep 30, 2026Gemini 4 Argon: our next era of frontier intelligence
- Google, model evaluation document, Sep 30, 2026storage.googleapis.com/deepmind-media/gemini/gemini_4_argon_model_evaluation.pdf
- Google, Sep 2, 2026Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
- Google, model evaluation document, Sep 2, 2026storage.googleapis.com/deepmind-media/gemini/gemini_3-8_flash_model_evaluation.pdf
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- Anthropic, Sep 1, 2026Introducing Claude Fable 5.1 and Claude Mythos 5.1
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- Mistral AI, blog post, Oct 6, 2026Introducing Mistral Large 4
- MiniMax, model card, launch-day revision, Oct 27, 2025huggingface.co/MiniMaxAI/MiniMax-M2/blob/44cefa66f81ec7ffebcb580c02985726ef4d829e/README.md