OpenAI, Anthropic and Google Report the Harder AutomationBench Set
OpenAI, Anthropic and Google report Zapier's runs on AutomationBench's private set. The other labs that name a set report their own runs on the public set.
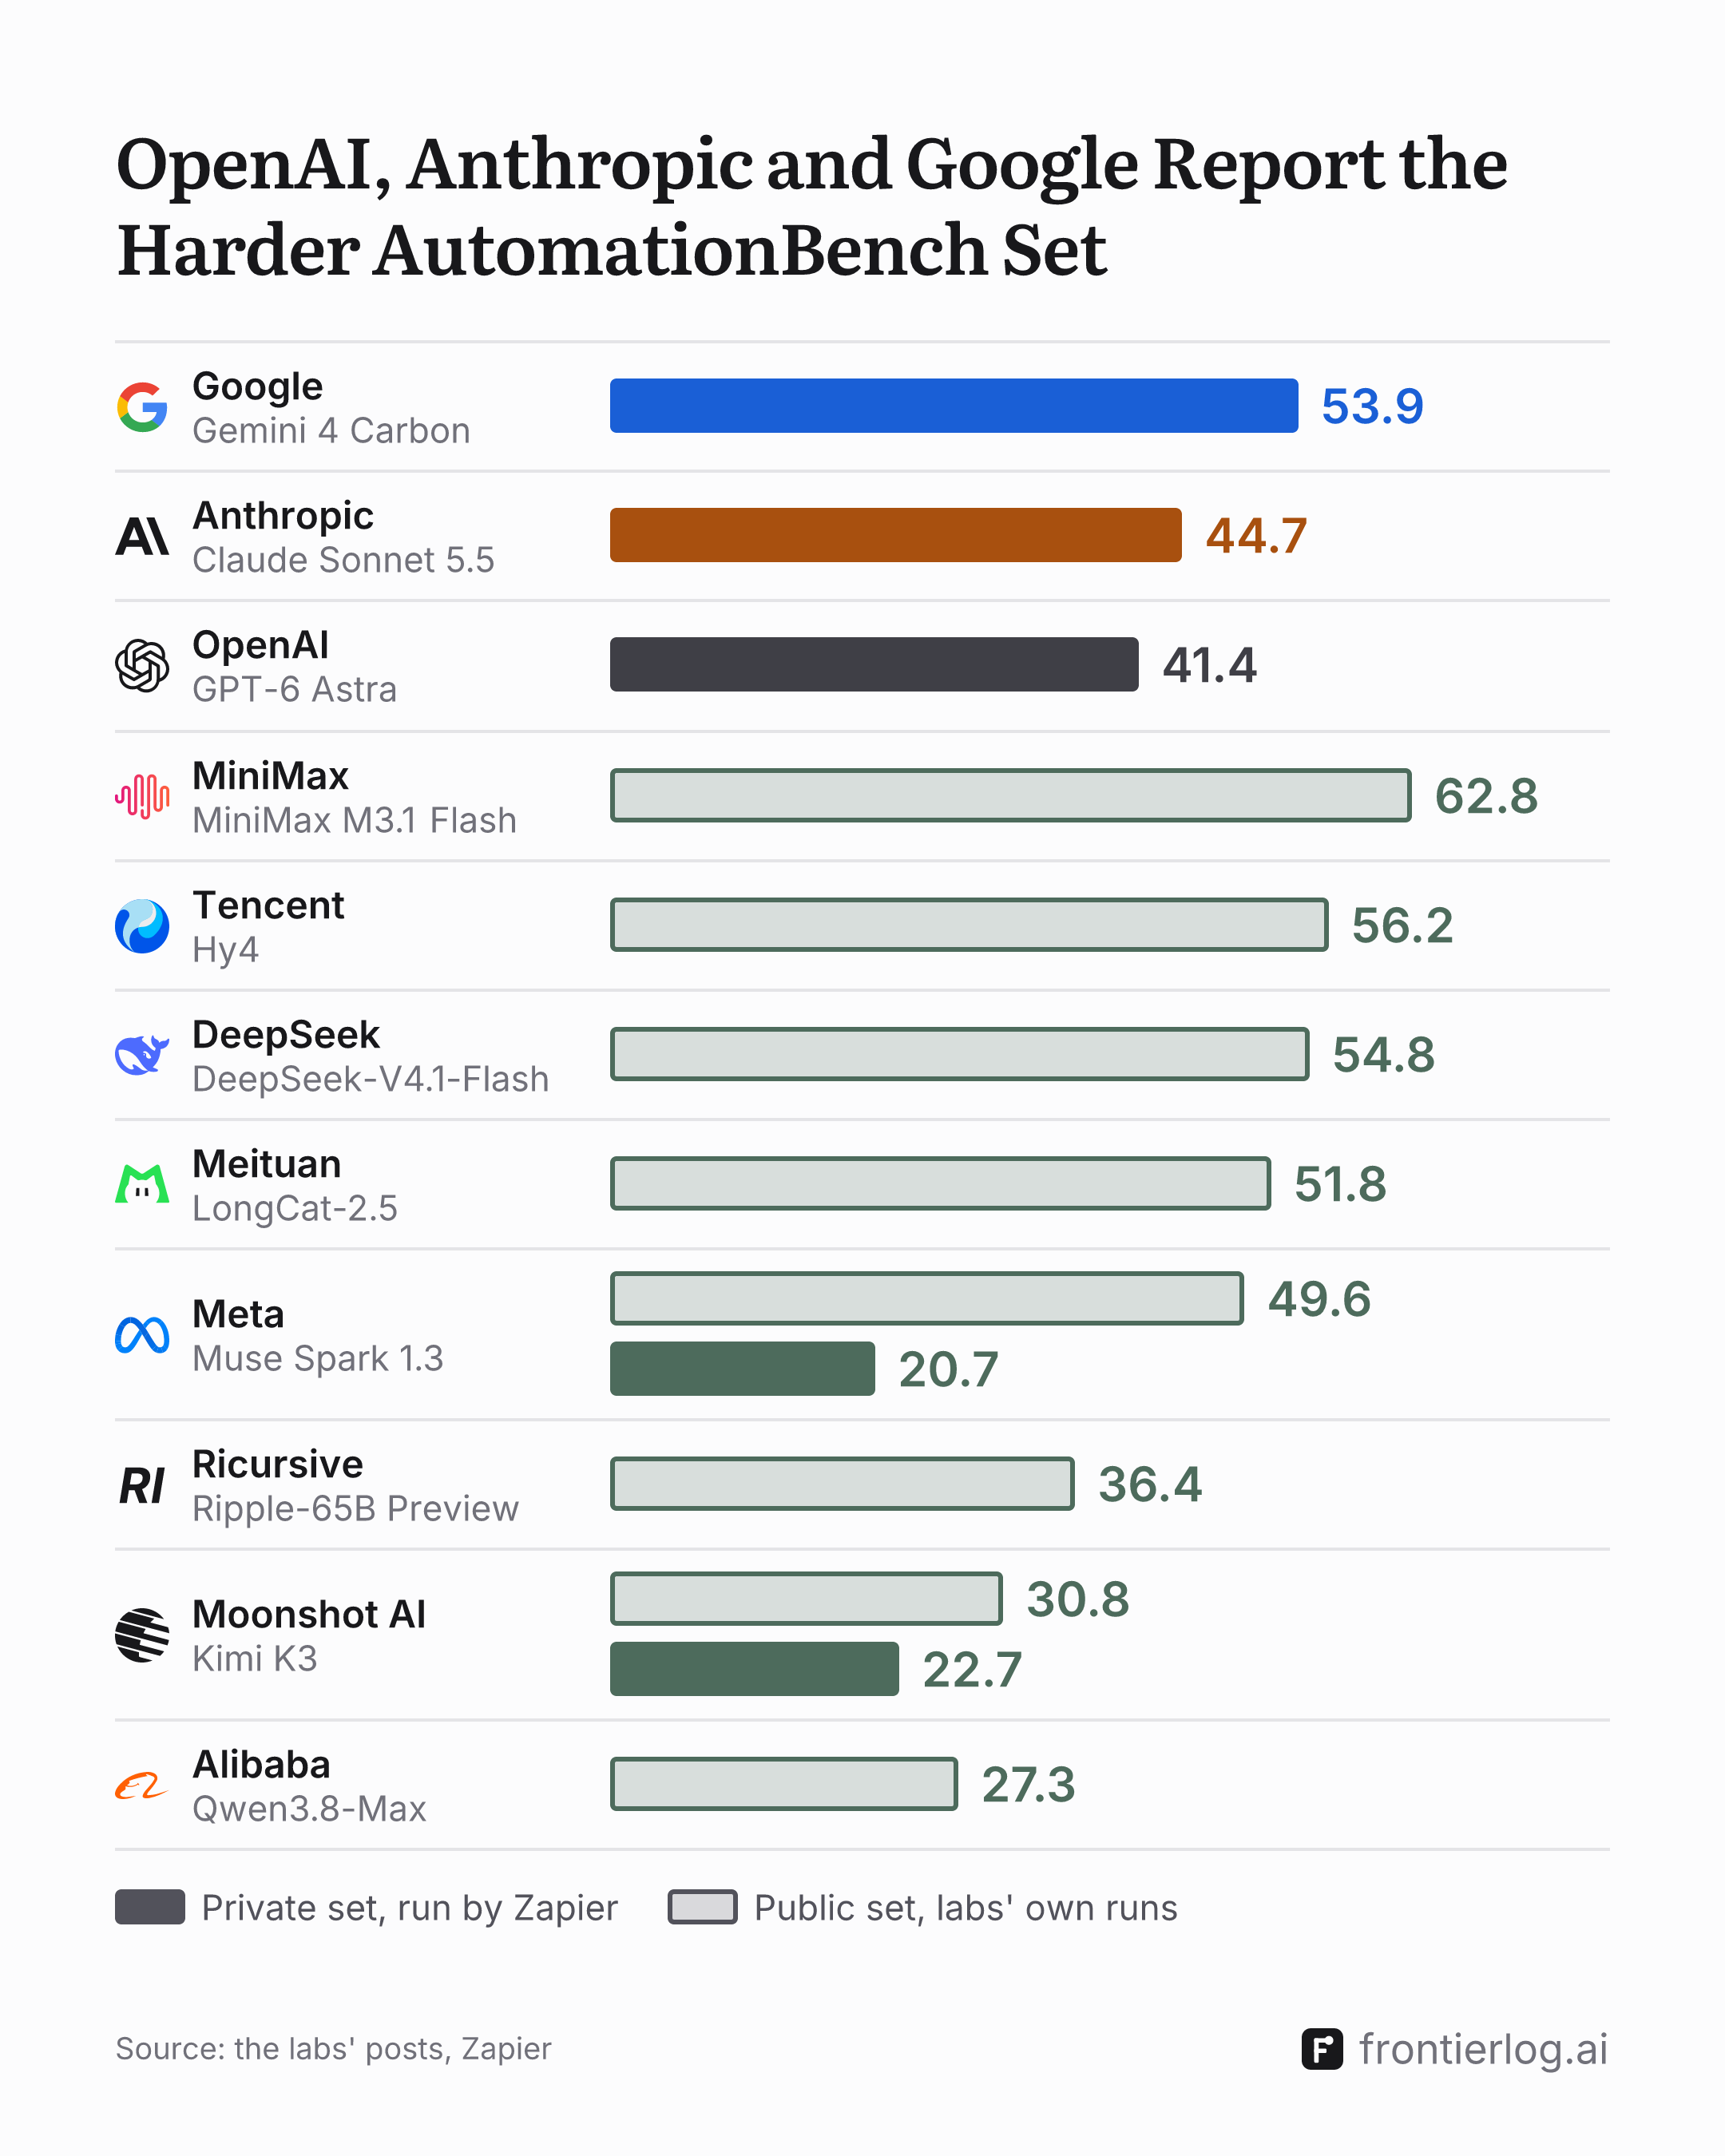
AutomationBench, Zapier's test of AI agents on business workflows, has two task sets. Zapier scores its leaderboard on a private set it doesn't release, and its README says that set "is purposely harder" than the 600 public tasks anyone can run. In their launch posts, OpenAI, Anthropic and Google report Zapier's runs on the private set. The other labs that name a set give their own runs on the public set, and no lab reports both.
Zapier keeps one set private
Zapier's leaderboard page says its "scores run against a held-out private evaluation set" and that "the public 600-task set is for research and experimentation". The README adds that scores measured on the public set "may not match the official leaderboard 1:1". In release 1.0.6, dated Jul 31, Zapier's changelog says "Private tasks were made a bit harder to compensate for bug fixes".
Who reports which set
Google's Gemini 4 Carbon post of Oct 28 gives 53.9%, and its evaluation methodology says the results "use the private set and are sourced from the official Zapier public leaderboard". Anthropic's Claude Sonnet 5.5 system card gives 44.7% and says the results "are on release 1.0.6 of Zapier's private evaluation set". OpenAI's GPT-6 Astra post of Sep 3 gives 41.4% and doesn't name a set. Its GPT-6.1 Sol post of Sep 29 shows the same figure in its chart and links it to Zapier's leaderboard.
The public-set scores come from the labs' own runs. MiniMax M3.1 Flash scored 62.8% on Oct 19, "evaluated on the 600 publicly released tasks". Tencent's Hy4 scored 56.2% on Nov 4, and DeepSeek's V4.1-Flash scored 54.8% on Sep 10. Meituan's LongCat-2.5 scored 51.8% and Meta's Muse Spark 1.3 49.6%, which Meta ran on "the public v3 task set". Ricursive's Ripple-65B Preview, Moonshot's Kimi K3 and Alibaba's Qwen3.8-Max also report the public set.
Most labs name the set beside the figure or in a linked document. Some name only a release: Z.ai's GLM-5.3 posts say "v1.0.6", and DeepSeek's Oct 17 post says "V1.0.6". DeepSeek's Oct 17 post gives 60.5% for V4.1-Flash-1017, and that result and Z.ai's are filed under set not stated. Moonshot's Kimi K3.1 Pro post and Thinking Machines' Inkling 2 Small post report AutomationBench-AA, a version Artificial Analysis runs.
Rivals' scores come from the same set
The labs' comparison tables mostly keep to one set. Anthropic and Google print rivals' figures from Zapier's private leaderboard. DeepSeek, MiniMax and LongCat print Zapier's public-set runs from its README, or the rivals' own public-set figures. Tencent's Hy4 post gives its own public-set runs of its rivals, marked "our own testing", and gives Claude Opus 5.5 58.8% there. Anthropic's Claude Opus 5.5 page says its figures for Opus 5, GPT-5.6 Sol and GPT-6 Astra "come from Zapier's public leaderboard".
Some rival figures don't match any published score. Z.ai's GLM-5.3-Flash post of Aug 26 prints 52.3% for Gemini 3.7 Flash. Google's own figure is 30.4%, and its evaluation methodology says that figure uses the private set. Zapier's README doesn't list the model. Meta's Muse Spark 1.3 scorecard gives GPT-5.6 Sol 46.7%, where Zapier's README gives 45.83%.
The same models score lower on the private set
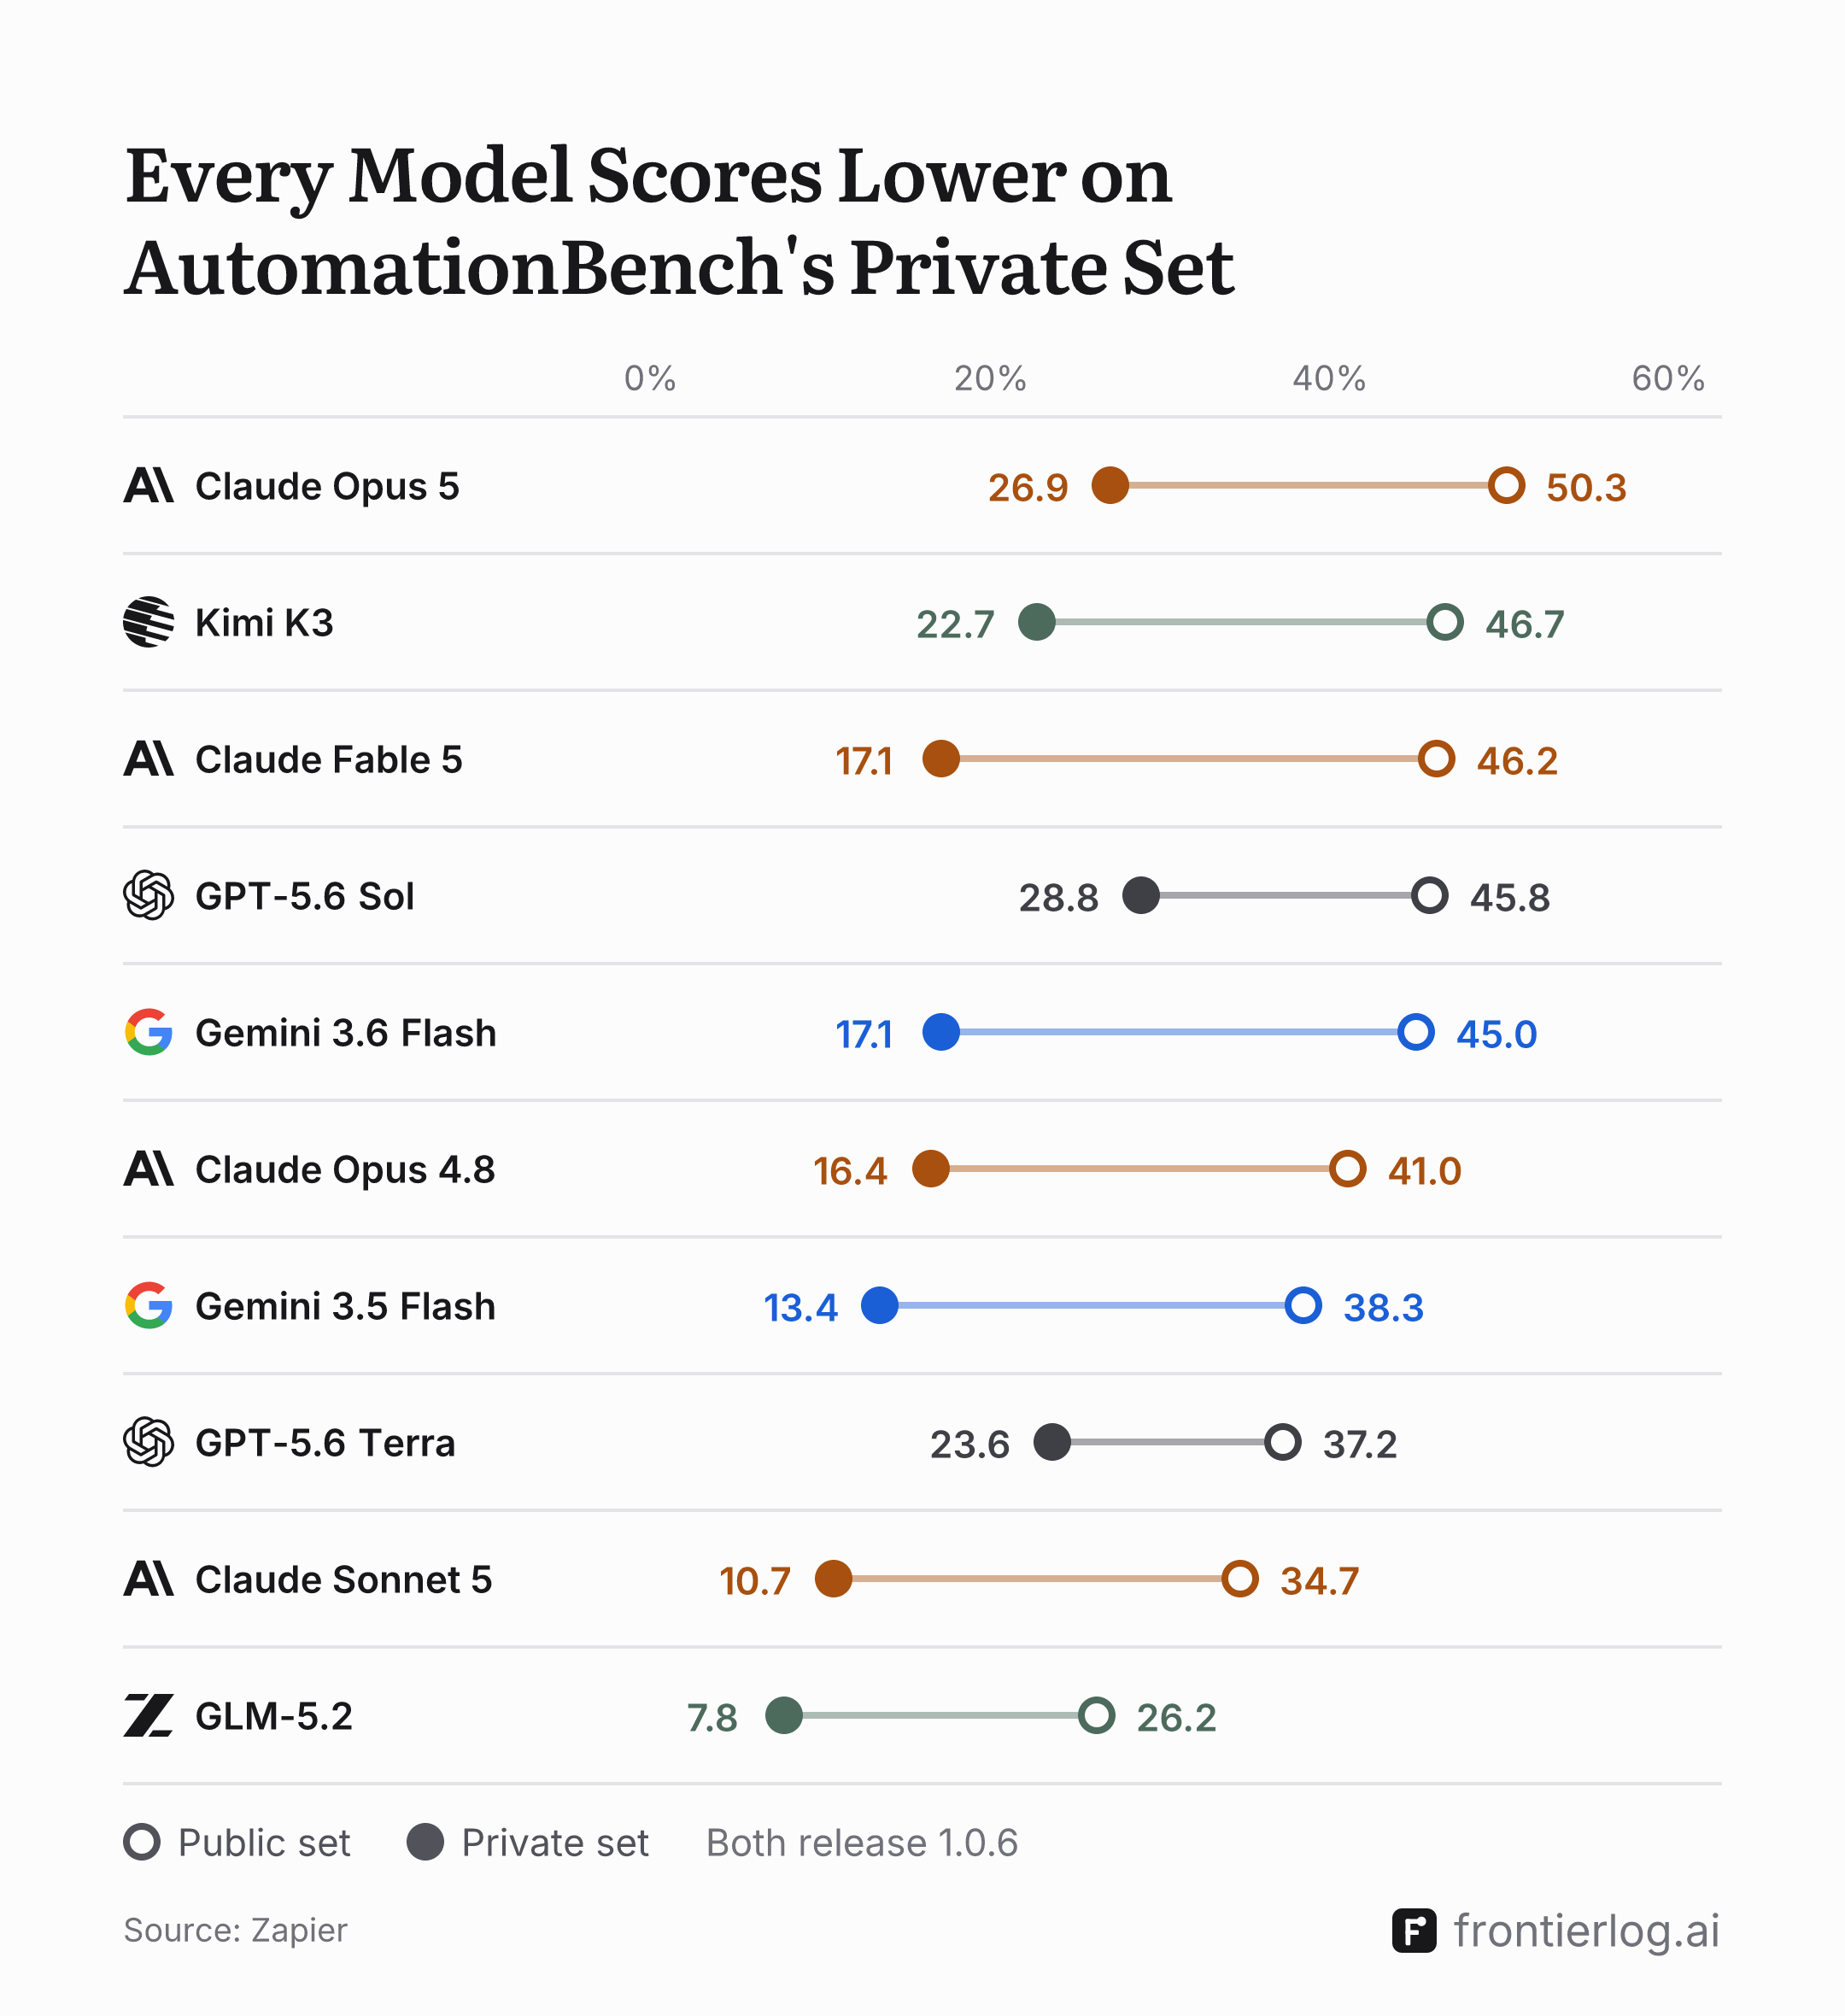
Zapier's README lists its own public-set runs of 10 models at release 1.0.6. Each of them scores lower on the private leaderboard, by 14 to 29 points. Claude Opus 5 scored 50.3% on the public set and 26.9% on the private set. The widest gap is Claude Fable 5's, 46.2% against 17.1%, and the README notes its public score "is after the July 2026 stricter classifier".
Kimi K3 has two public-set figures. Moonshot gave 30.8% on Jul 16, before release 1.0.6, and Zapier's 1.0.6 README gives 46.7%. Zapier's leaderboard also lists Muse Spark 1.3 at 20.7% on the private set, against Meta's 49.6% on the public set.
Our earlier story, China Leads on AutomationBench, compared scores from both sets.
AutomationBench private set, the labs' reports
AutomationBench public set, the labs' reports
AutomationBench public set, run by Zapier
AutomationBench private set, Zapier's leaderboard
Sources
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Smarter, Faster, More Efficient
- Google, Aug 13, 2026Introducing Gemini 3.7 Flash
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- Google, evaluation methodology, Aug 13, 2026deepmind.google/models/evals-methodology/gemini-3-7-flash
- Google, evaluation methodology, Oct 28, 2026deepmind.google/models/evals-methodology/gemini-4-carbon
- Zapier, AutomationBench README, release 1.0.6, Aug 4, 2026github.com/zapier/AutomationBench/blob/4a8e106/README.md
- Zapier, AutomationBench changelog, Aug 4, 2026github.com/zapier/AutomationBench/blob/6d21054/CHANGELOG.md
- Tencent, Nov 4, 2026Introducing Hy4
- Meituan, Nov 1, 2026LongCat-2.5: Native Multimodality for Agentic Tasks
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- OpenAI, Sep 29, 2026Introducing GPT-6.1 Sol
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- Meta, Sep 2, 2026Introducing Muse Spark 1.3
- Thinking Machines, Nov 5, 2026Introducing Inkling 2 Small
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- Anthropic, Sep 28, 2026Claude Sonnet 5.5 System Card
- Moonshot AI, Jul 16, 2026Kimi K3: Open Frontier Intelligence
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence
- MiniMax, Oct 19, 2026MiniMax M3.1 Flash: Redefining Agent Performance and Cost
- Ricursive Intelligence, Nov 4, 2026Introducing Ripple-65B Preview, a Frontier Open-Weight Model
- Z.ai, Aug 26, 2026GLM-5.3-Flash: Frontier Intelligence, Flash Cost
- Zapier, AutomationBench leaderboard, release 1.0.6, read Nov 7, 2026, Nov 7, 2026zapier.com/benchmarks