Frontier Log

China Leads on AutomationBench

AutomationBench scores from Chinese labs and from OpenAI, Anthropic and Google, by release date, as each lab reports them.
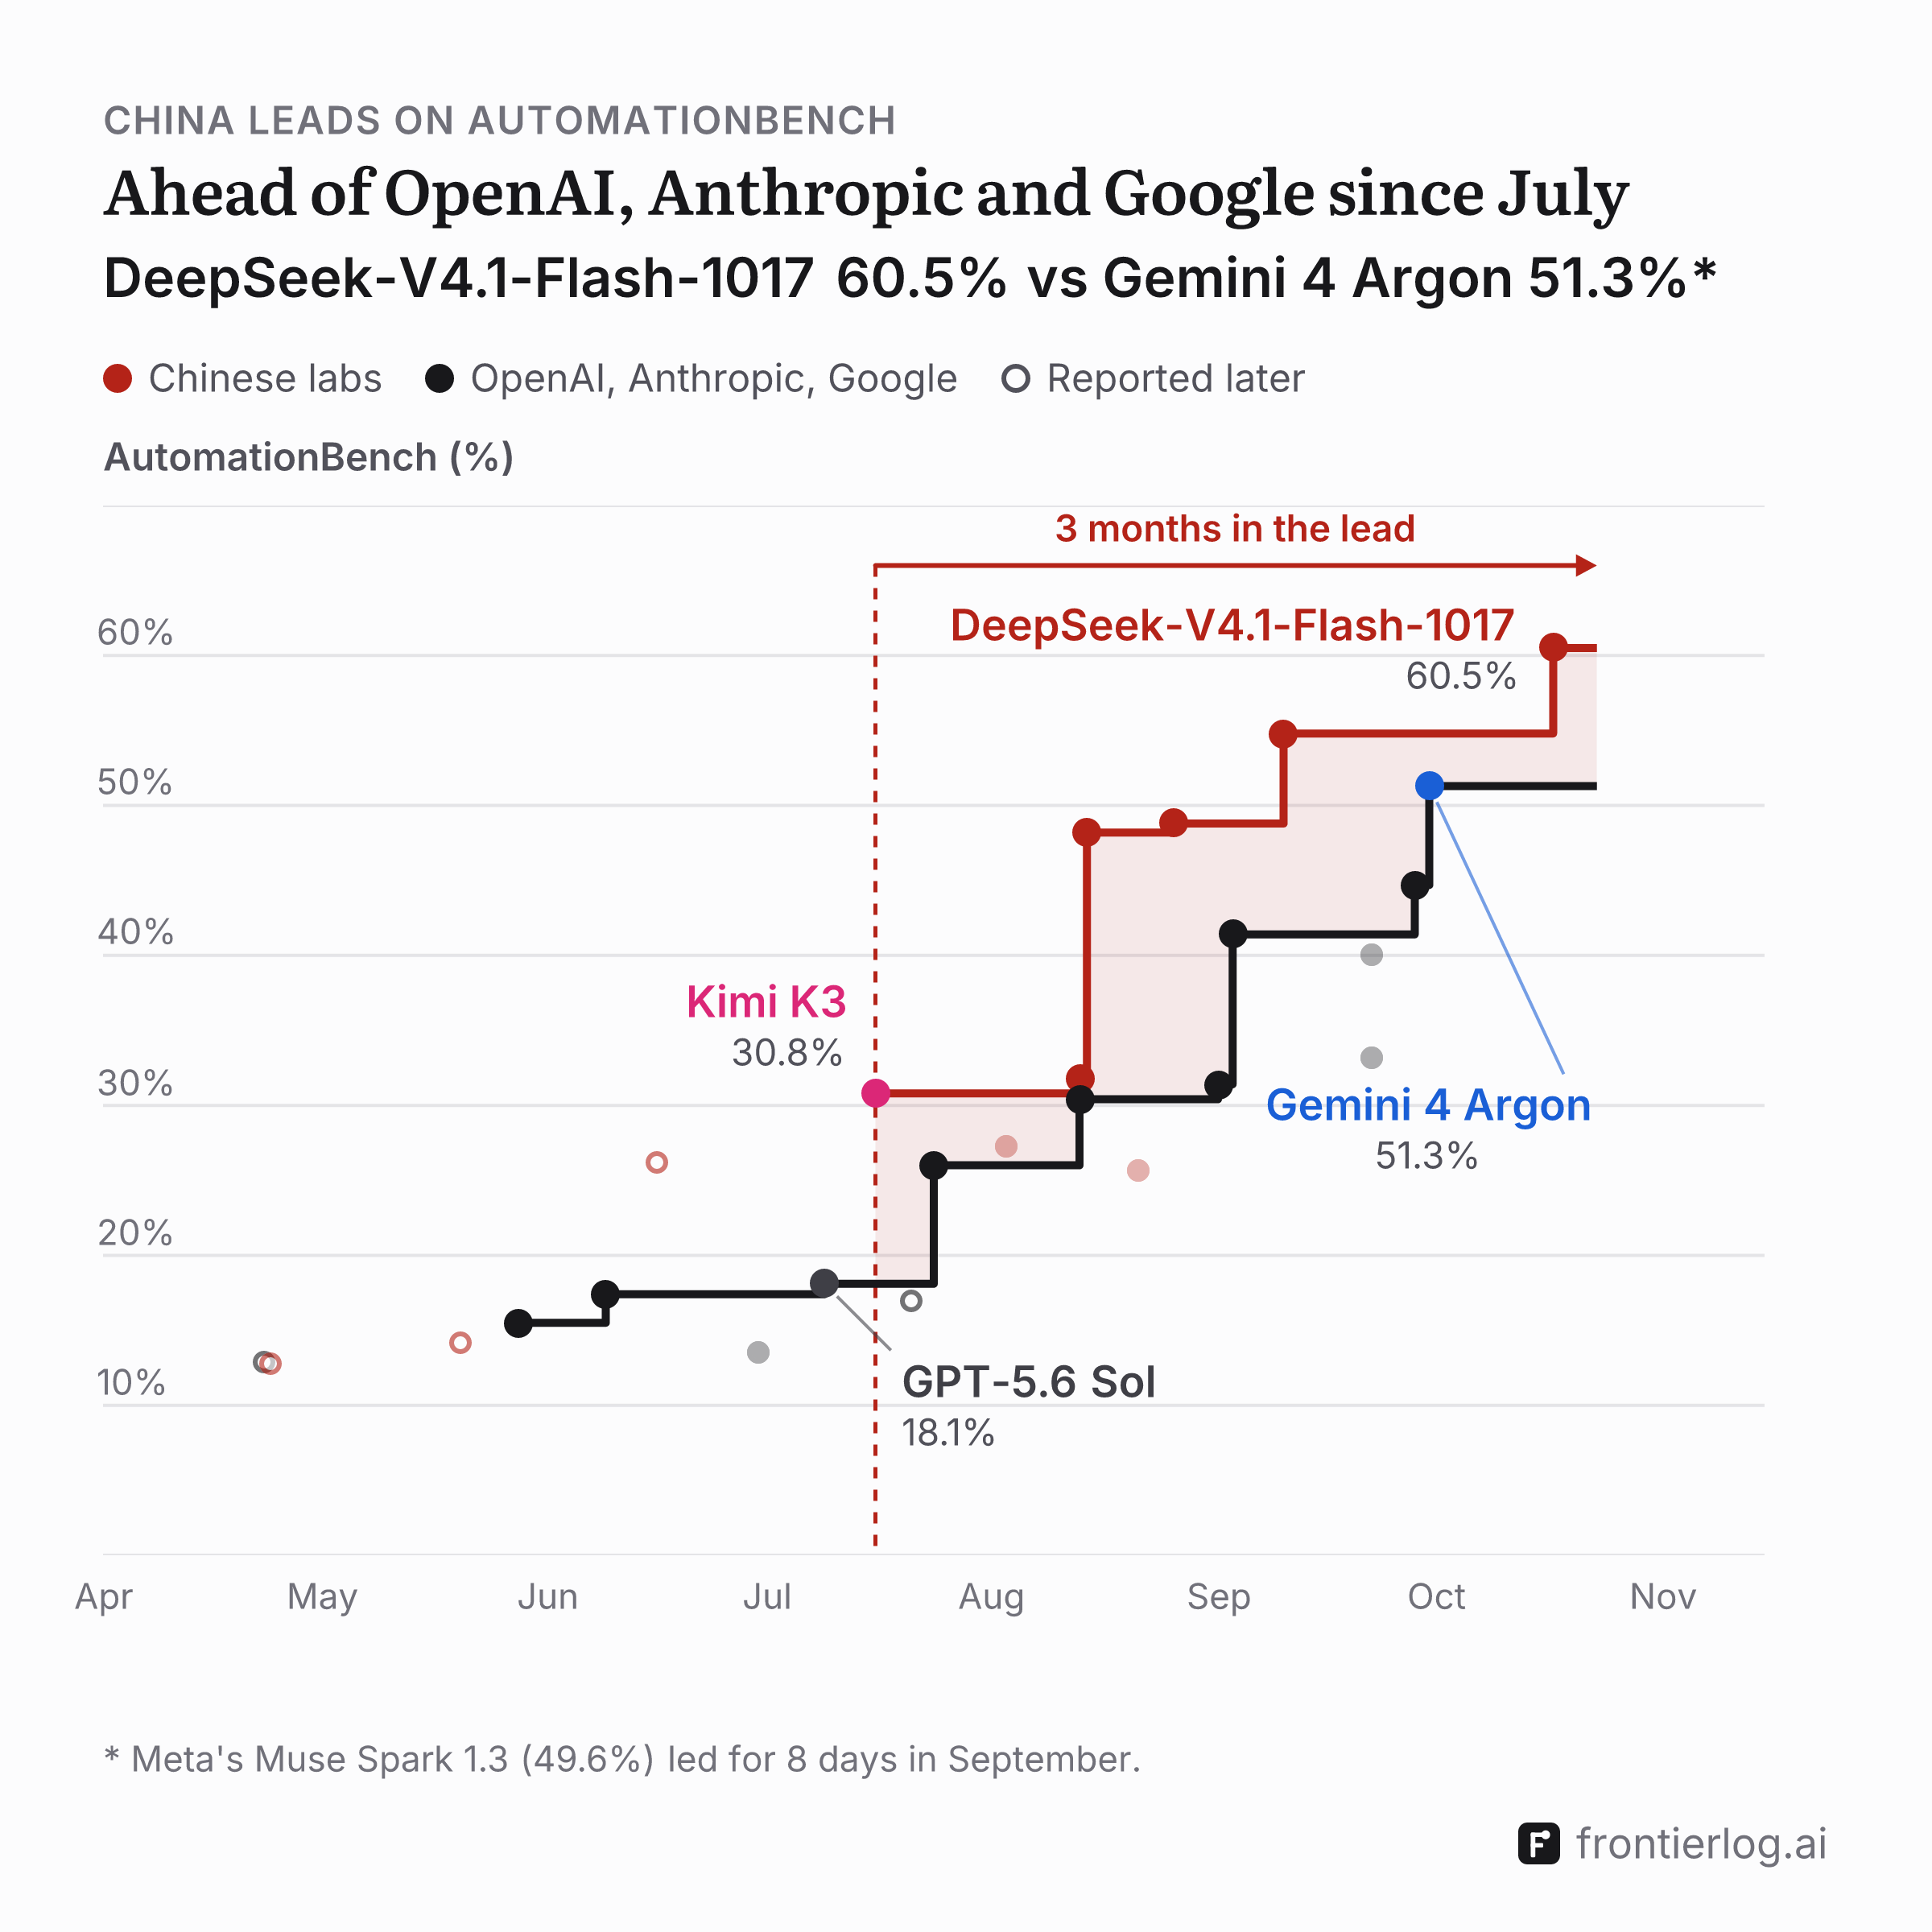
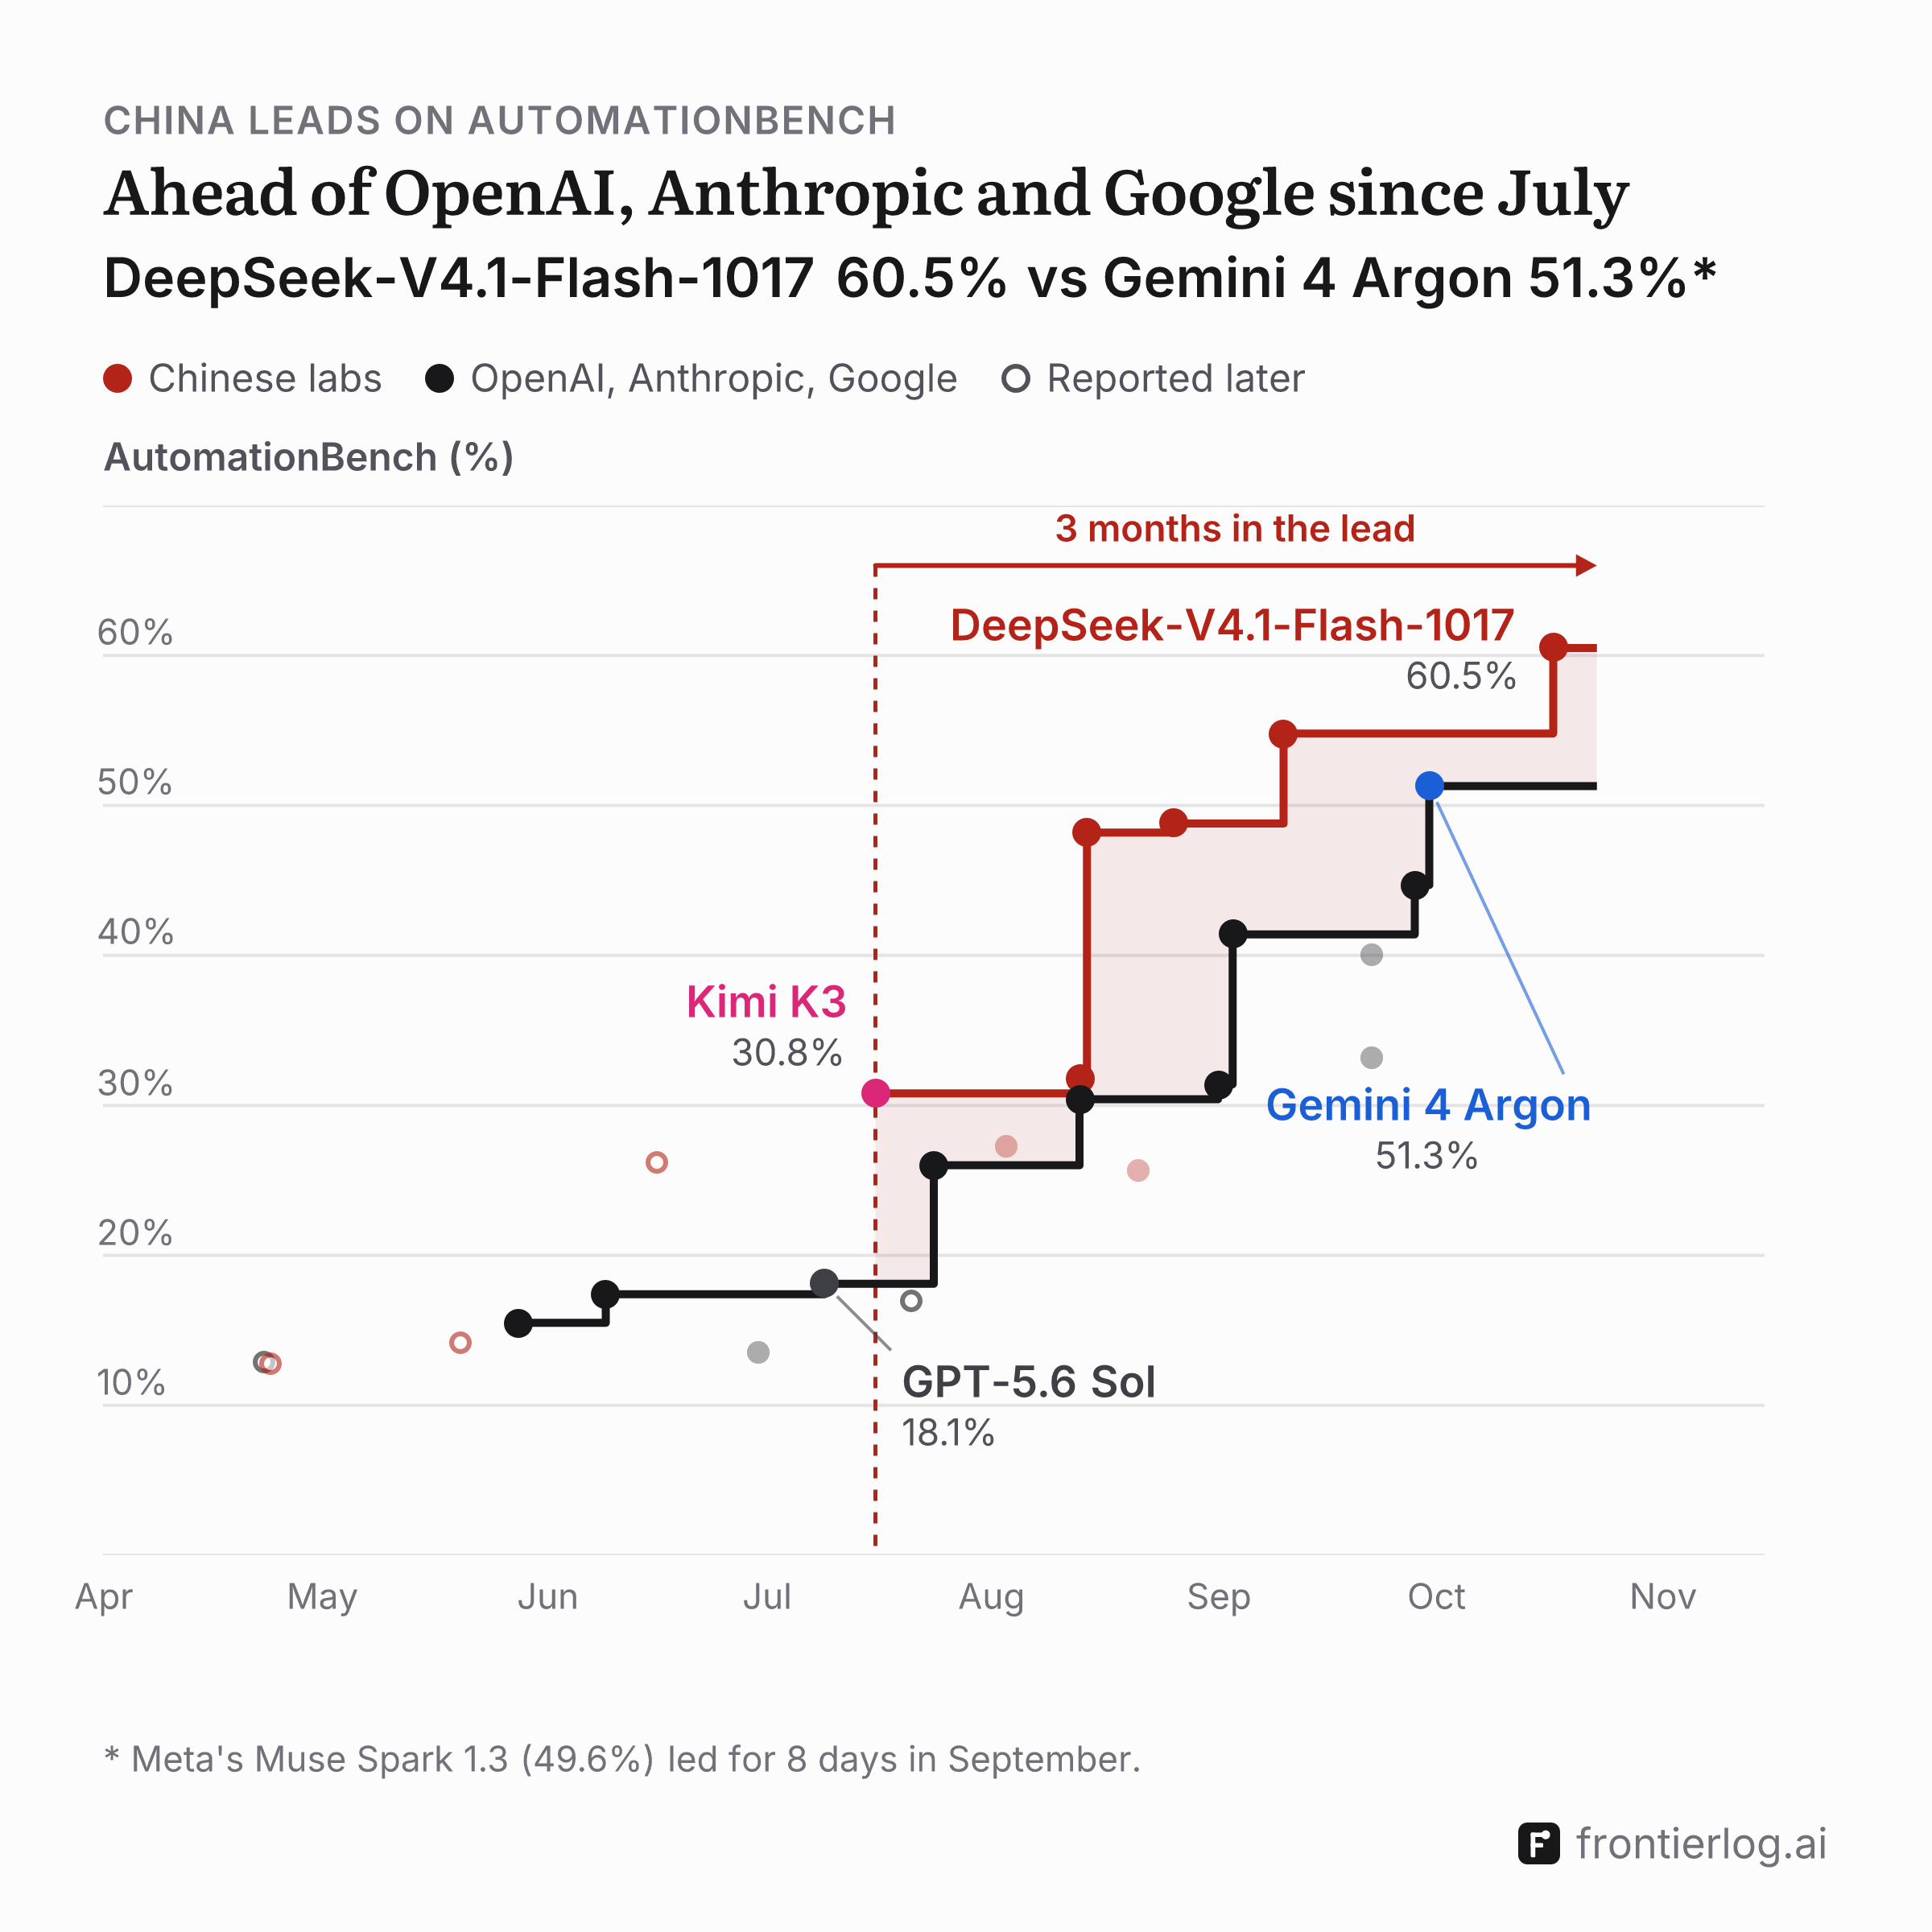
AutomationBench by release date, April to October 2026: the record from Chinese labs' own launch reports against the record from OpenAI, Anthropic and Google, as step lines. Kimi K3 takes the lead on July 16 at 30.8%, against GPT-5.6 Sol's 18.1%, and the Chinese line stays above since, through GLM-5.3 (48.2%), DeepSeek-V4.1-Flash (54.8%) and DeepSeek-V4.1-Flash-1017 (60.5%); the US line rises to Gemini 4 Argon's 51.3%. The lead is shaded and marked 3 months. Hollow dots are scores labs reported later for older models. Note: Meta's Muse Spark 1.3 (49.6%) led for 8 days in September.

Ahead of OpenAI, Anthropic and Google since July

DeepSeek-V4.1-Flash-1017 60.5% vs Gemini 4 Argon 51.3%*

Chinese labs have reported a higher AutomationBench score than OpenAI, Anthropic and Google since Kimi K3 in July: 30.8% against GPT-5.6 Sol's 18.1%. Today DeepSeek-V4.1-Flash-1017 leads Gemini 4 Argon, 60.5% to 51.3%.

* Meta's Muse Spark 1.3 (49.6%) led for 8 days in September.
Download

AutomationBench, Chinese labs

ModelScoreSources
DeepSeek V4 Preview12.8%Announcementlater report: DeepSeek-V4-Pro GA post, table image, row 'AutomationBench (Public)', column 'DeepSeek-V4-Pro-Preview'
Qwen3.7-Max14.2%AnnouncementQwen3.8 post, 'Full Benchmark Table', row 'Automation-Bench (Pass@1)', column 'Qwen3.7-Max'
GLM-5.226.2%Announcement'Performance across comparison models' table, row 'AutomationBench v1.0.6', column 'GLM-5.2'
Kimi K330.8%Announcement'Full Benchmark Table', row 'Automation Bench' (Agentic), column 'Kimi K3 (max)'
Qwen3.8-Max27.3%Announcement'Full Benchmark Table' (first, language/agent HTML table), General Agent section, row 'Automation-Bench (Pass@1)', column 'Qwen3.8-Max'
DeepSeek-V4-Pro GA31.8%Announcementtable image, row 'AutomationBench (Public)', column 'DeepSeek-V4-Pro-0813'
GLM-5.348.2%Announcement'Performance across comparison models' table, row 'AutomationBench v1.0.6', column 'GLM-5.3'
DeepSeek-V4-Flash-Vision-Exp25.7%Announcementtable image, section 'Text-Based Agent Evaluation', row 'AutomationBench (Public)', column 'DeepSeek V4-Flash-Vision-Exp'
GLM-5.3-Flash48.8%Announcementmain benchmark table (second table), AGENTIC block, row 'AutomationBench v1.0.6', column 'GLM-5.3-Flash'
DeepSeek-V4.1-Flash54.8%Announcementbenchmark table image (second image), row 'Automation-Bench', column 'DeepSeek V4.1-Flash' (the first chart image, v4.1_260910_benchmark.png, prints the same value label)
DeepSeek-V4.1-Flash-101760.5%Announcementbenchmark table image (first image), row 'Automation-Bench V1.0.6', column 'DeepSeek V4.1-Flash-1017'

AutomationBench, OpenAI, Anthropic and Google

ModelScoreSources
GPT-5.512.9%Announcementtool-use table (columns GPT-5.6 Sol, Terra, Luna, GPT-5.5, ...), row 'AutomationBench', column 'GPT-5.5'
Claude Opus 4.815.5%AnnouncementSection 8.1, Table 8.1.A (evaluation summary), row 'Automation Bench', column 'Claude Opus 4.8'
Claude Fable 5 and Mythos 517.4%AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Fable 5'
Claude Sonnet 513.5%AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Claude Sonnet 5'
GPT-5.618.1%Announcementtool-use table (columns GPT-5.6 Sol, Terra, Luna, GPT-5.5, ...), row 'AutomationBench', column 'GPT-5.6 Sol'
Gemini 3.6 Flash and 3.5 Flash-Lite17.0%Announcementbenchmark table (image), row 'AutomationBench (Private set)', column 'Gemini 3.6 Flash'
Claude Opus 526.0%Announcementbenchmark table (image), row 'Business workflows, AutomationBench', column 'Opus 5'
Gemini 3.7 Flash30.4%Announcementbenchmark table (image), row 'AutomationBench (Private set)', column 'Gemini 3.7 Flash'
Claude Fable 5.1 and Mythos 5.131.4%Announcementbenchmark table (HTML), row 'Business workflows, AutomationBench', column 'Fable 5.1'
GPT-6 Astra41.4%AnnouncementProfessional table, row 'AutomationBench', column 'GPT‑6 Astra'
Claude Opus 5.540.0%Announcementbenchmark table, row 'AutomationBench', column 'Opus 5.5'
GPT-6 Sol and Luna33.2%AnnouncementAutomationBench table (Model (and effort) / Score / Cost per task), row 'GPT-6 Sol (xhigh)', column 'Score'
Claude Sonnet 5.544.7%AnnouncementSection 8.1, Table 8.1.A, row 'AutomationBench', column 'Claude Sonnet 5.5'
Gemini 4 Argon51.3%Announcementbenchmark table (image), row 'AutomationBench', 'Score', column 'Gemini 4 Argon'

AutomationBench, Meta

ModelScoreSources
Muse Spark 1.2 and Muse Code38.2%AnnouncementMuse Spark 1.3 scorecard (image), row 'AutomationBench', column 'Muse Spark 1.2 (xhigh)'
Muse Spark 1.349.6%Announcementscorecard (image), row 'AutomationBench', column 'Muse Spark 1.3 (max)'

Related events