GLM-5.3
- Made by
- Z.ai
- Released
- Announced in
- GLM-5.3: Frontier Coding with Emergent Cyber Capabilitiesz.ai
- Event
- GLM-5.3
- API record
- /api/v1/models/glm-5-3
Benchmark results
| Benchmark | Score | Source check |
|---|---|---|
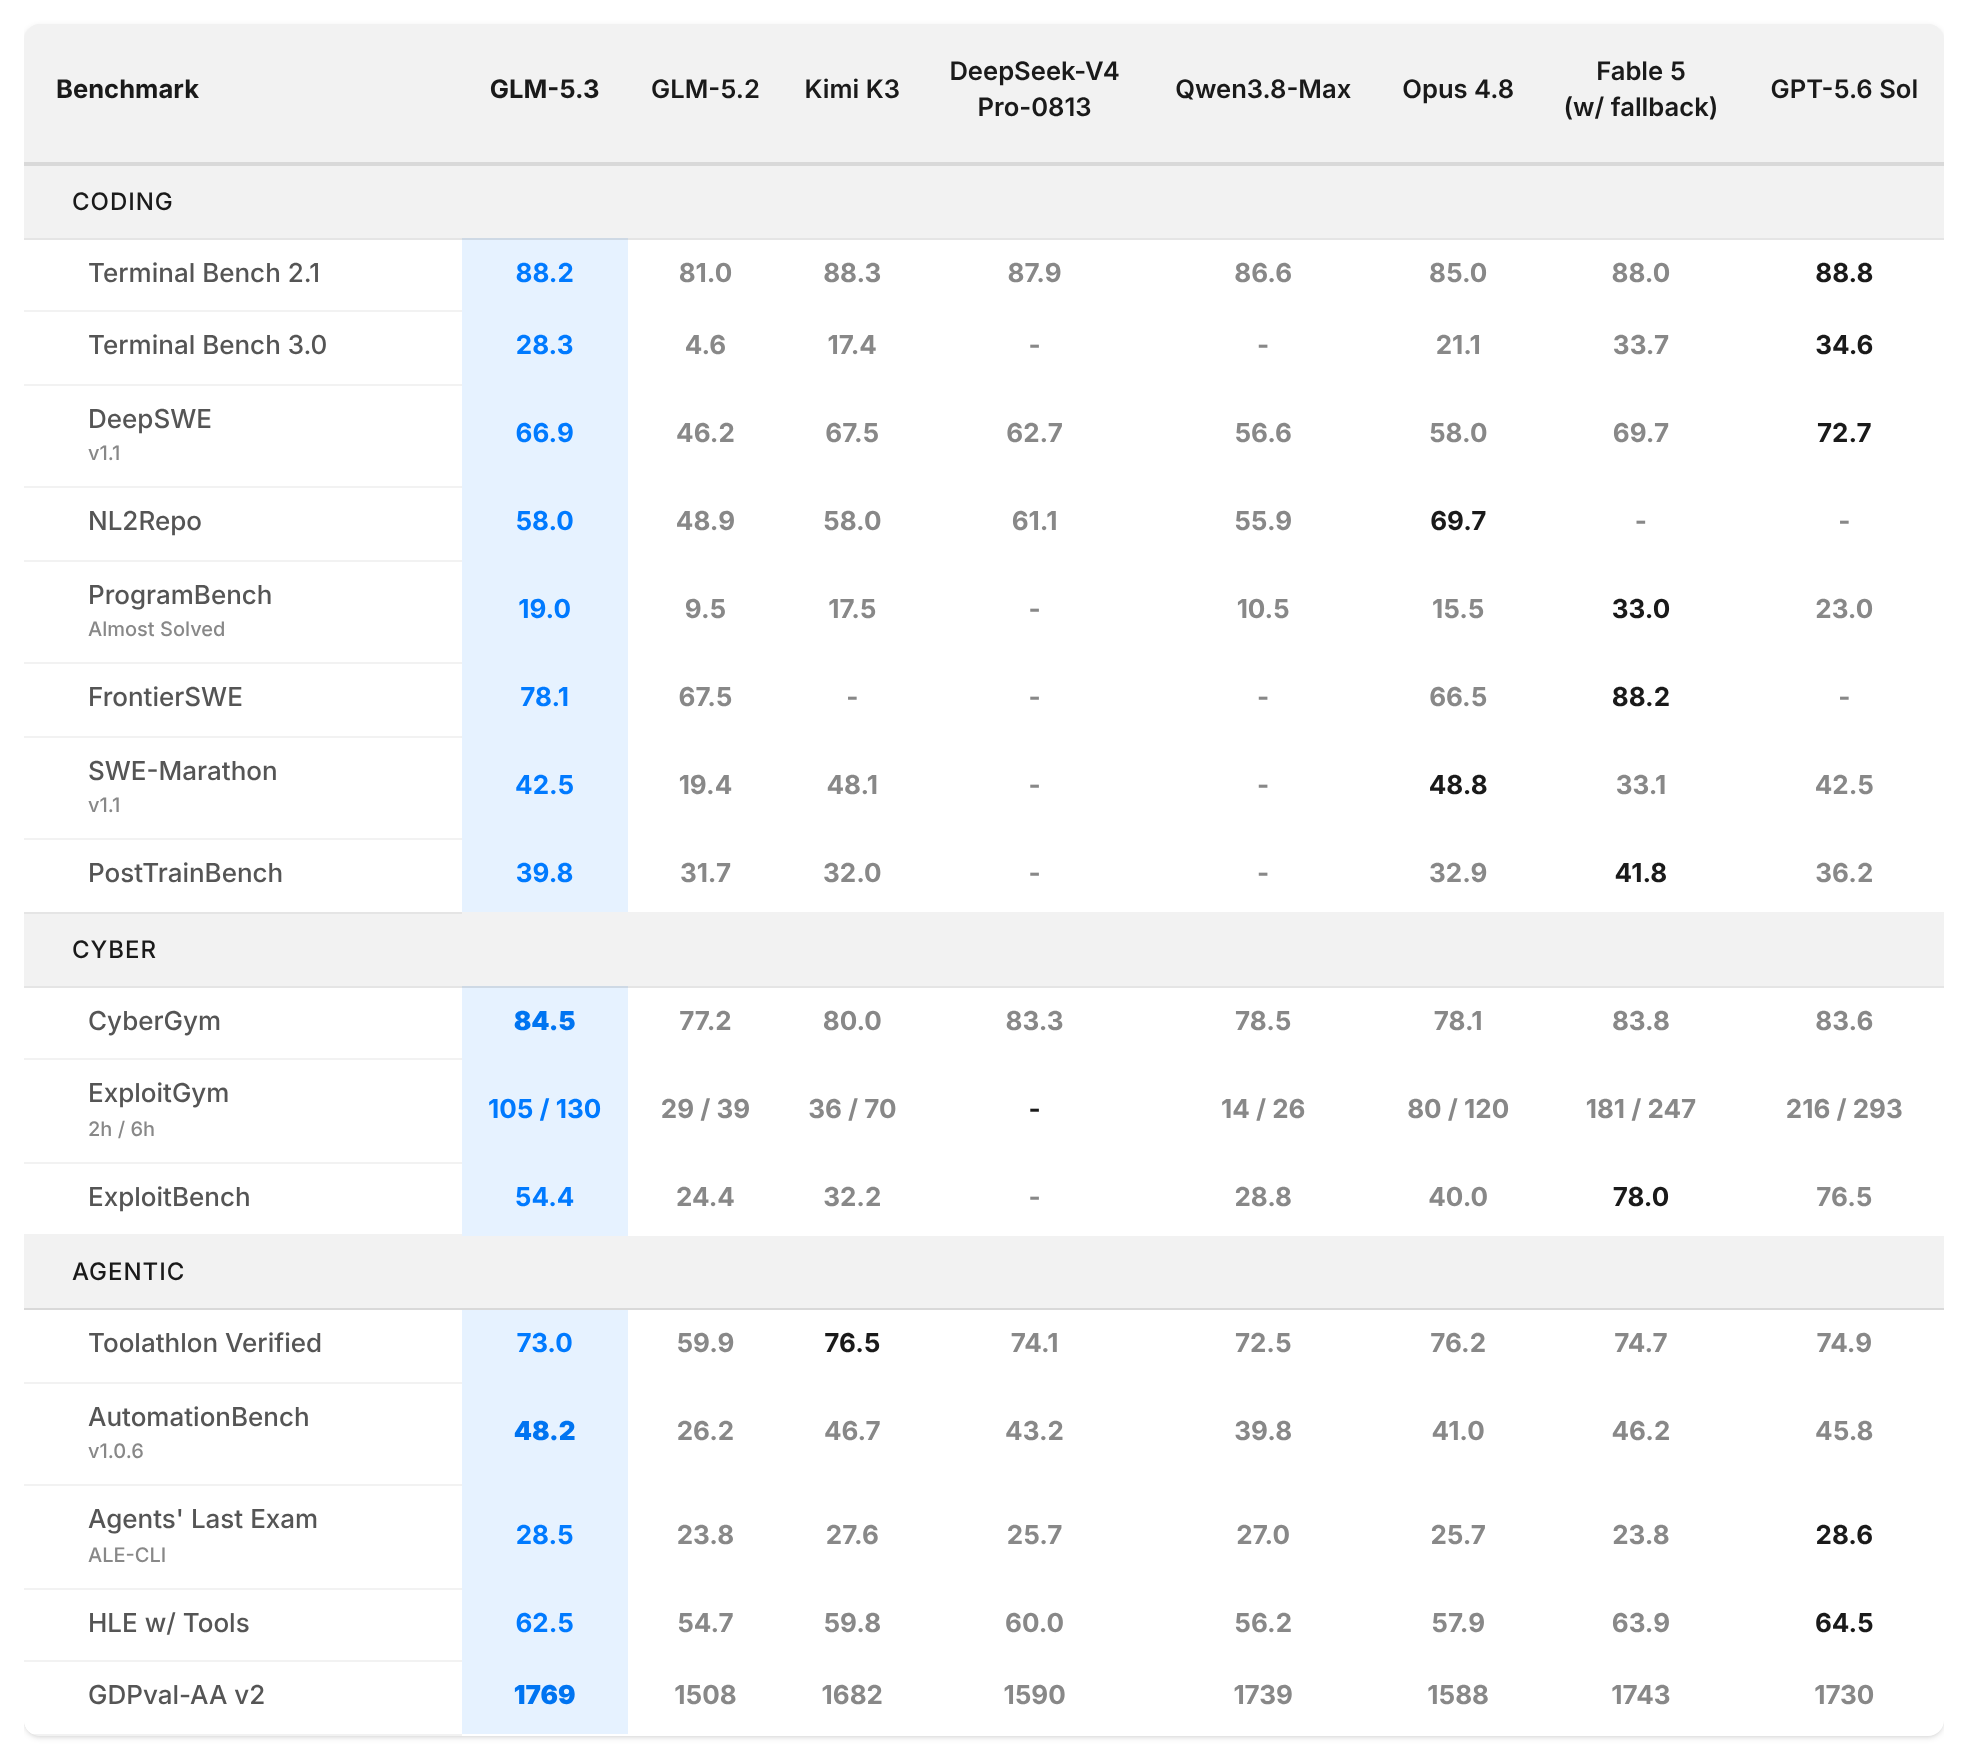
| Humanity's Last ExamWith tools · 300,000-token context with context management; GPT-5.6 Luna judge | 62.5% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
| AutomationBenchAutomationBench v1.0.6 with a fix for null-type handling | 48.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| DeepSWE v1.1mini-swe-agent harness; 6h timeout; 400K context | 66.9% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced. |
| Terminal-Bench 2.1Claude Code harness; 6h timeout | 88.2% | CheckedA person checked this number against its source on 19 Oct 2026. This confirms the number matches what the lab published, not that the score was reproduced.CorroboratedThe same number is printed in 1 other lab document: 1 |
Sources
Reported by Z.ai
- GLM-5.3: Frontier Coding with Emergent Cyber Capabilitiesz.ai · 14 Aug 2026
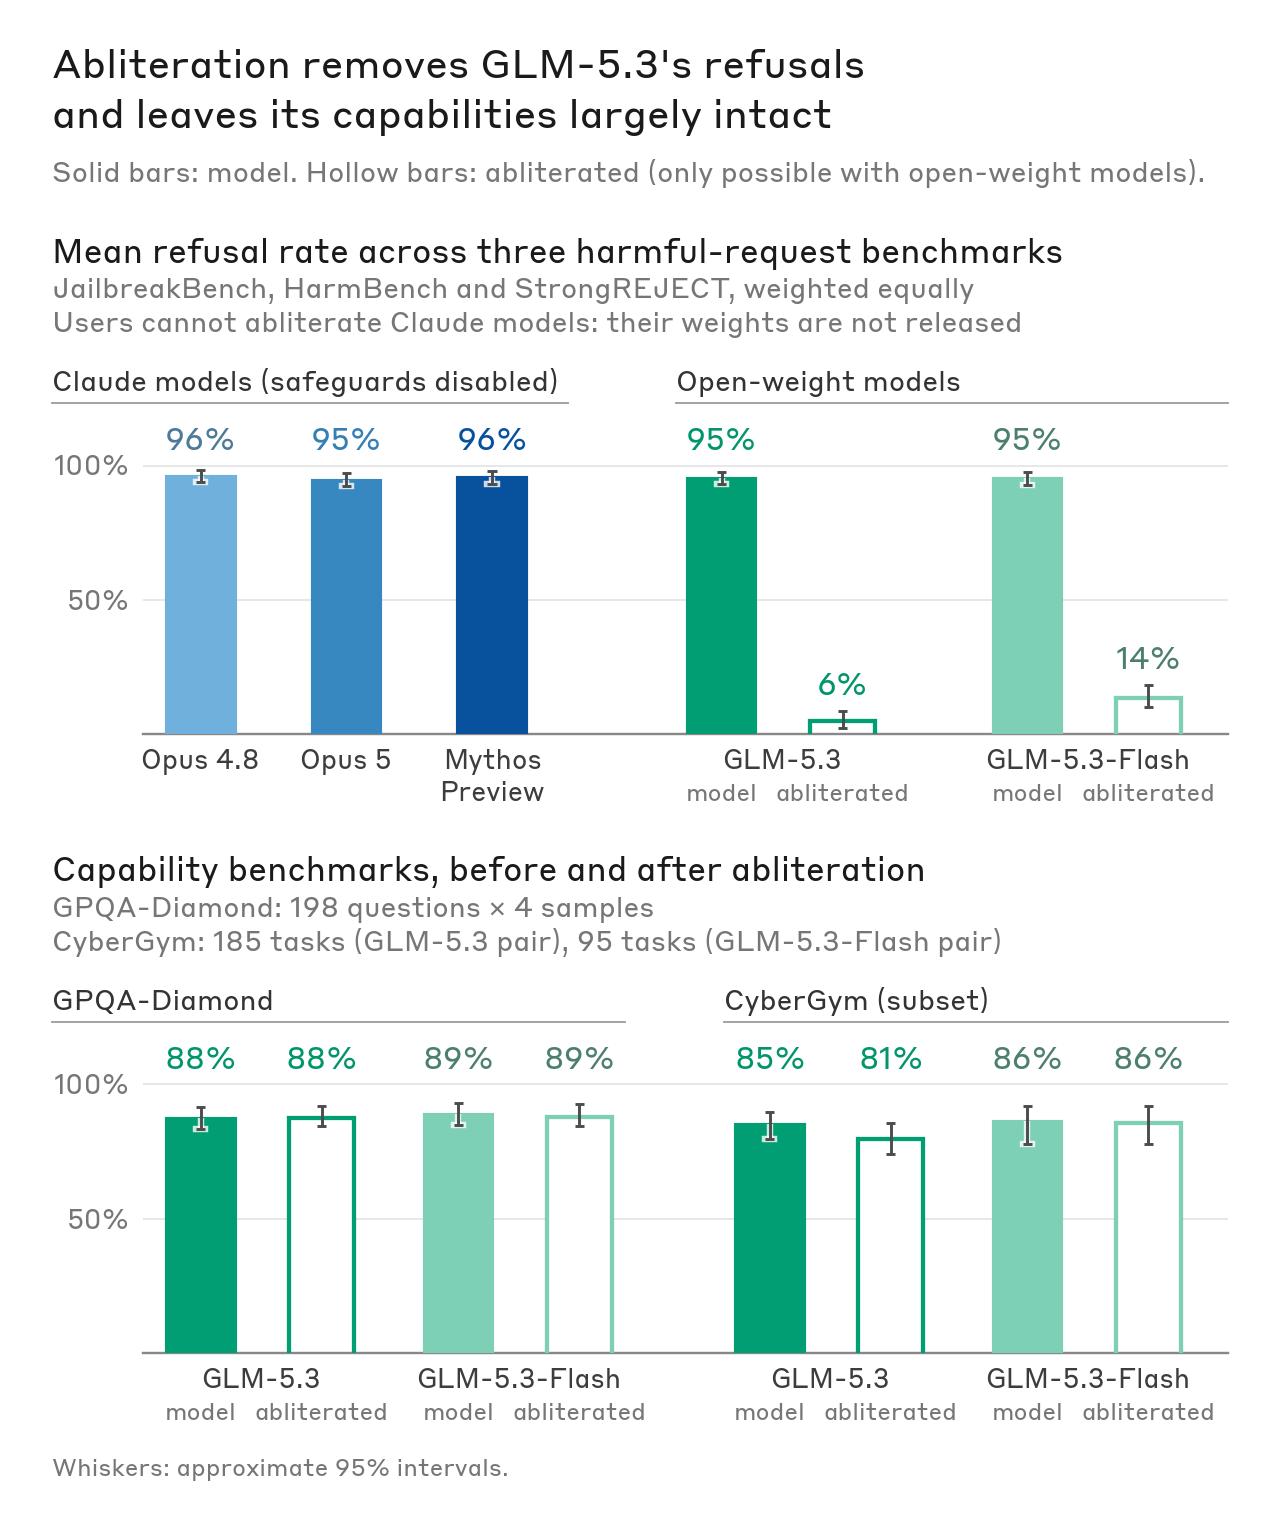
Our capture of the source - GLM-5.3 and the spread of advanced cyber capabilitiesanthropic.com · 29 Sep 2026
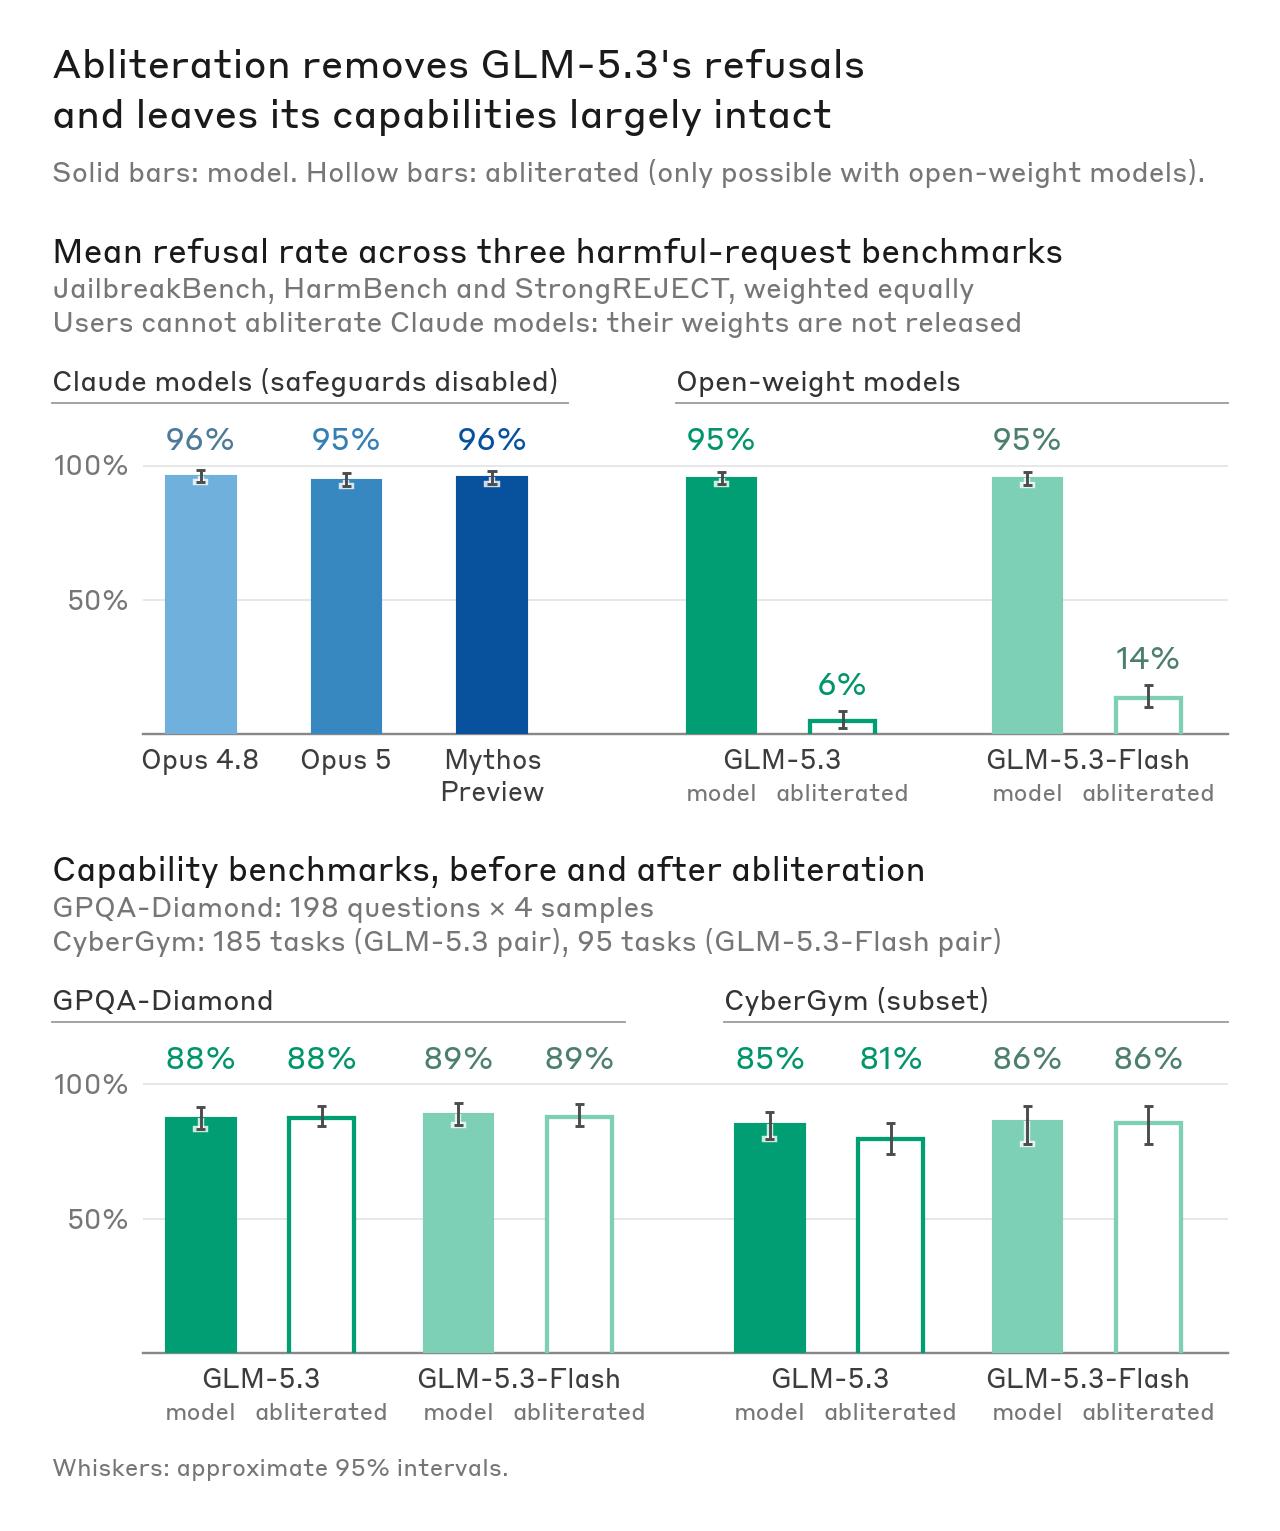
Original image