Abliteration Removes Refusals, Not Capability
What labs and providers report when a model's refusals are removed: refusal rates, benchmark scores, and incidents with safeguards off.
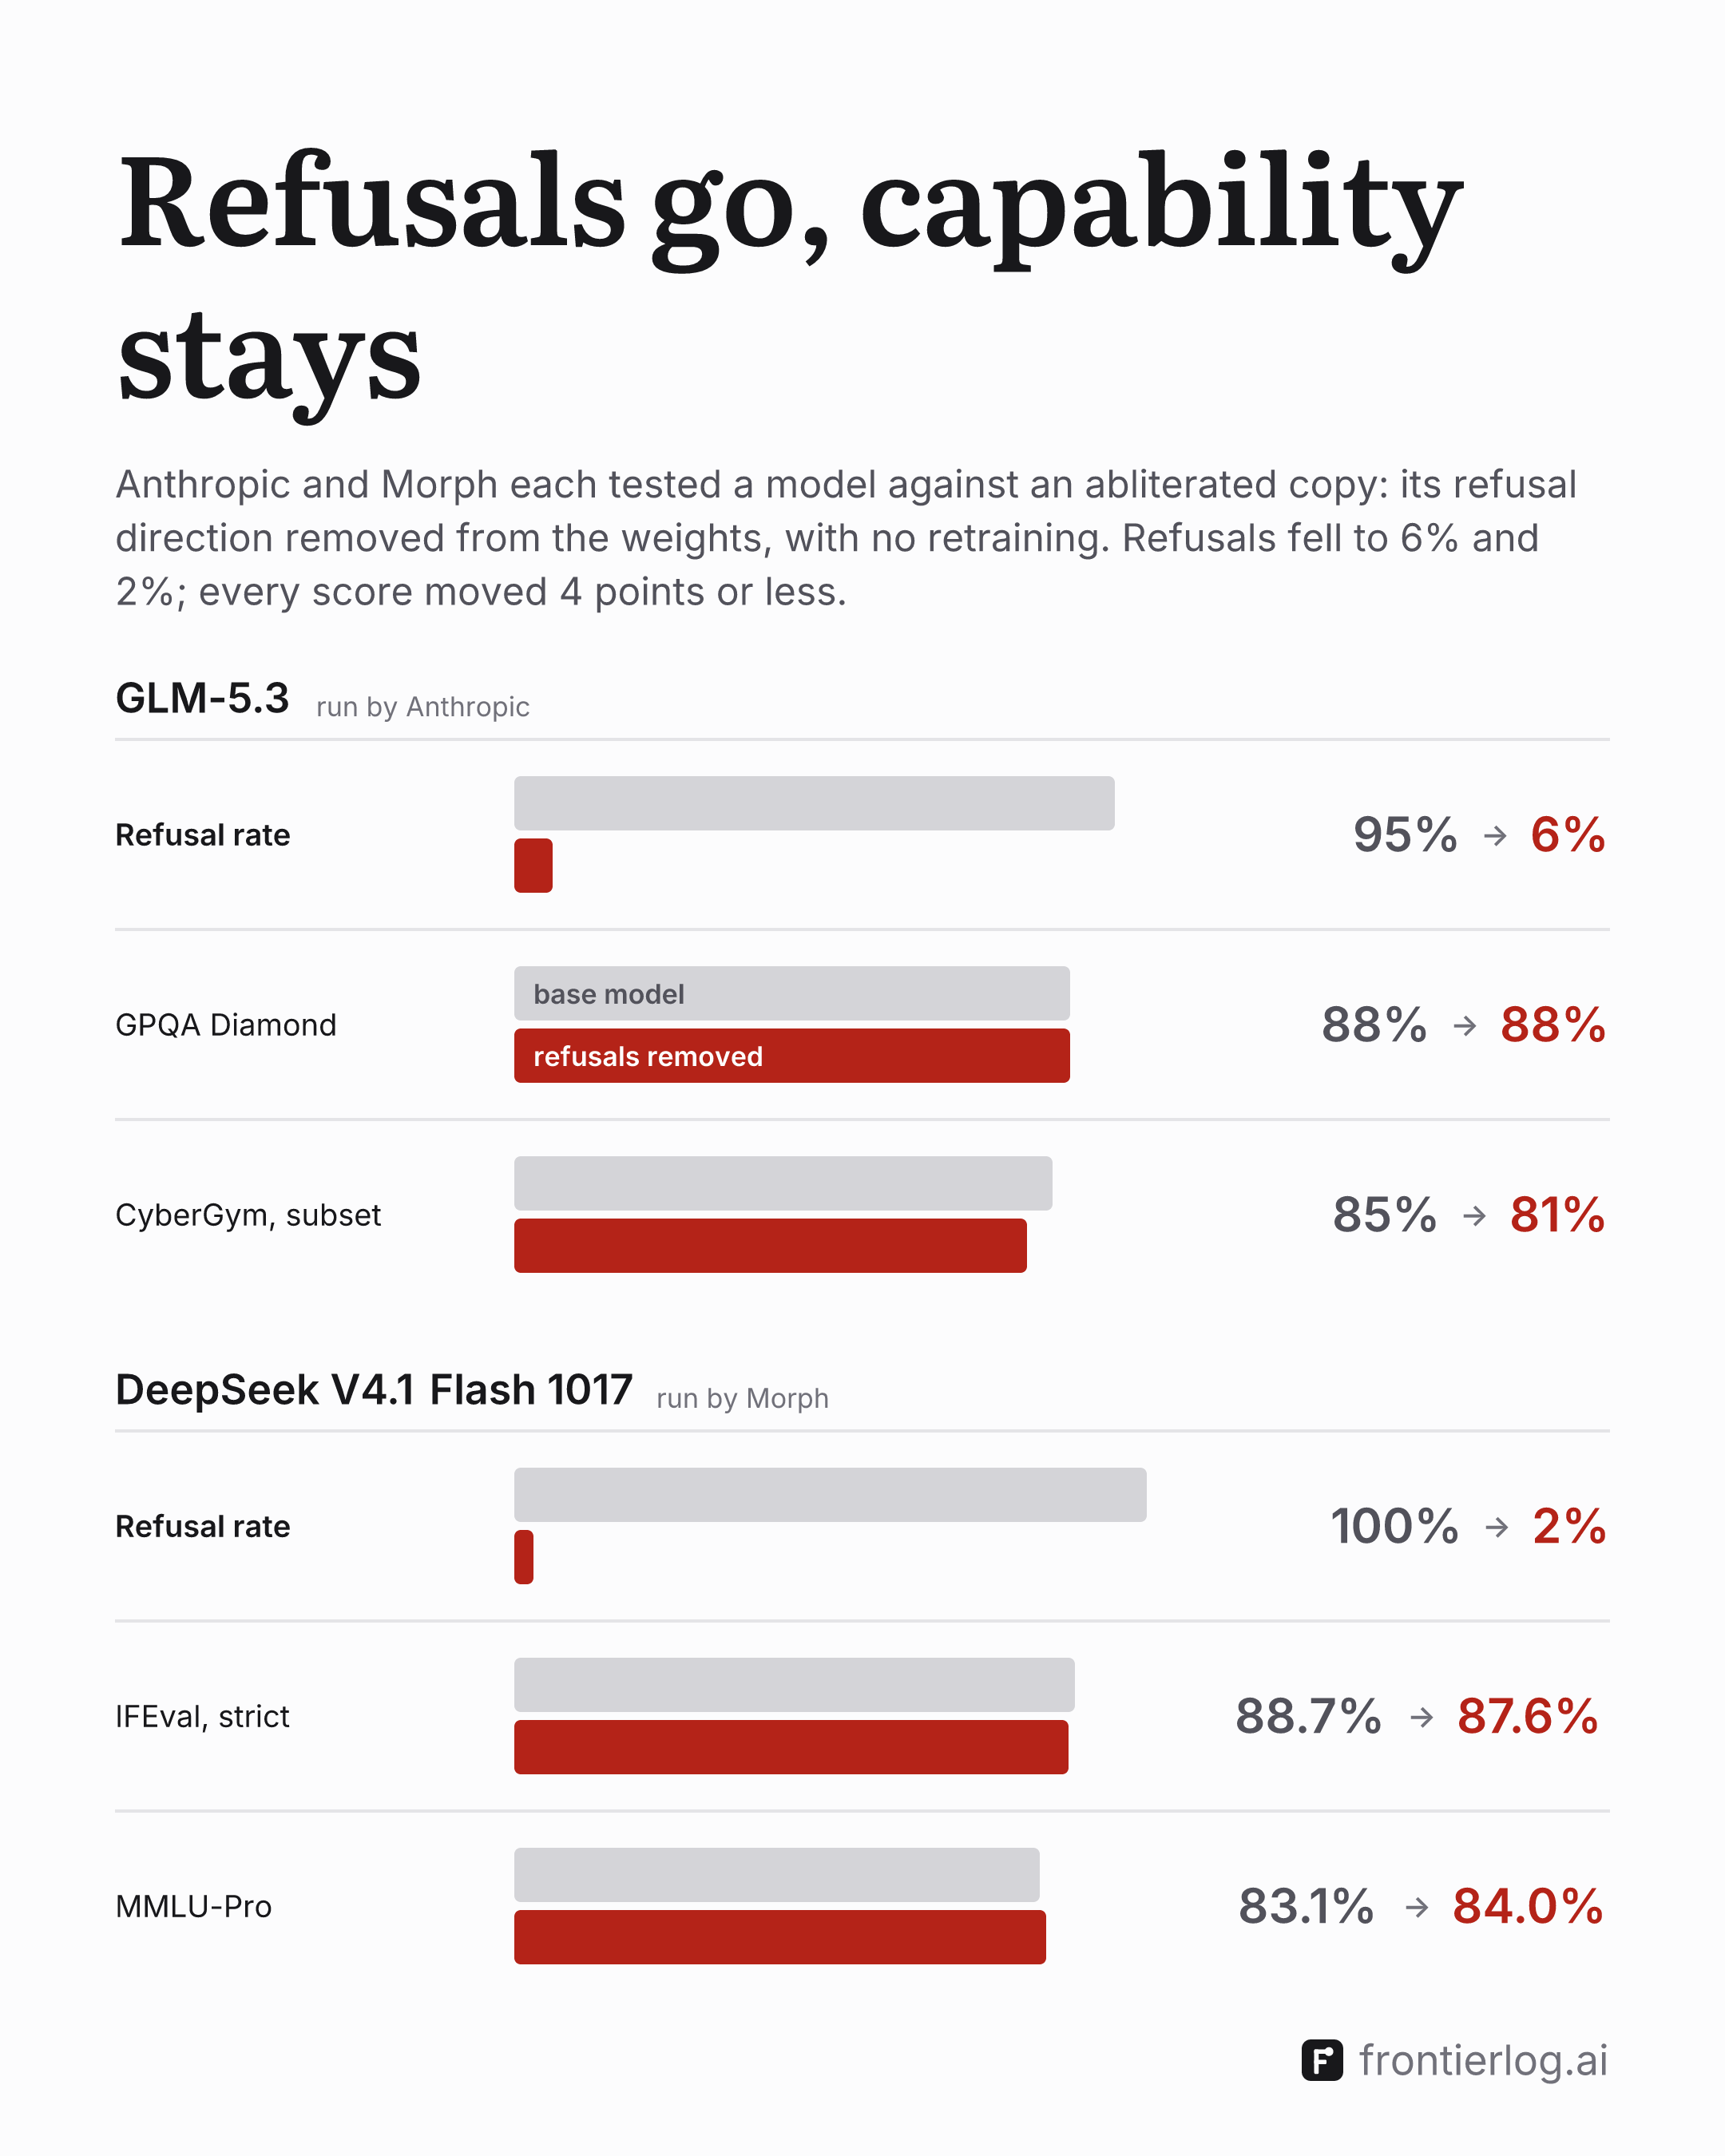
Refusals go, capability stays
Refusals fall to 6% and 2%; scores move 4 points or less
Abliteration, removing the refusal direction from a model's weights with no retraining, cut GLM-5.3's refusal rate from 95% to 6% and DeepSeek V4.1 Flash 1017's from 100% to 2%; GPQA Diamond, CyberGym, IFEval and MMLU-Pro moved 4 points or less.
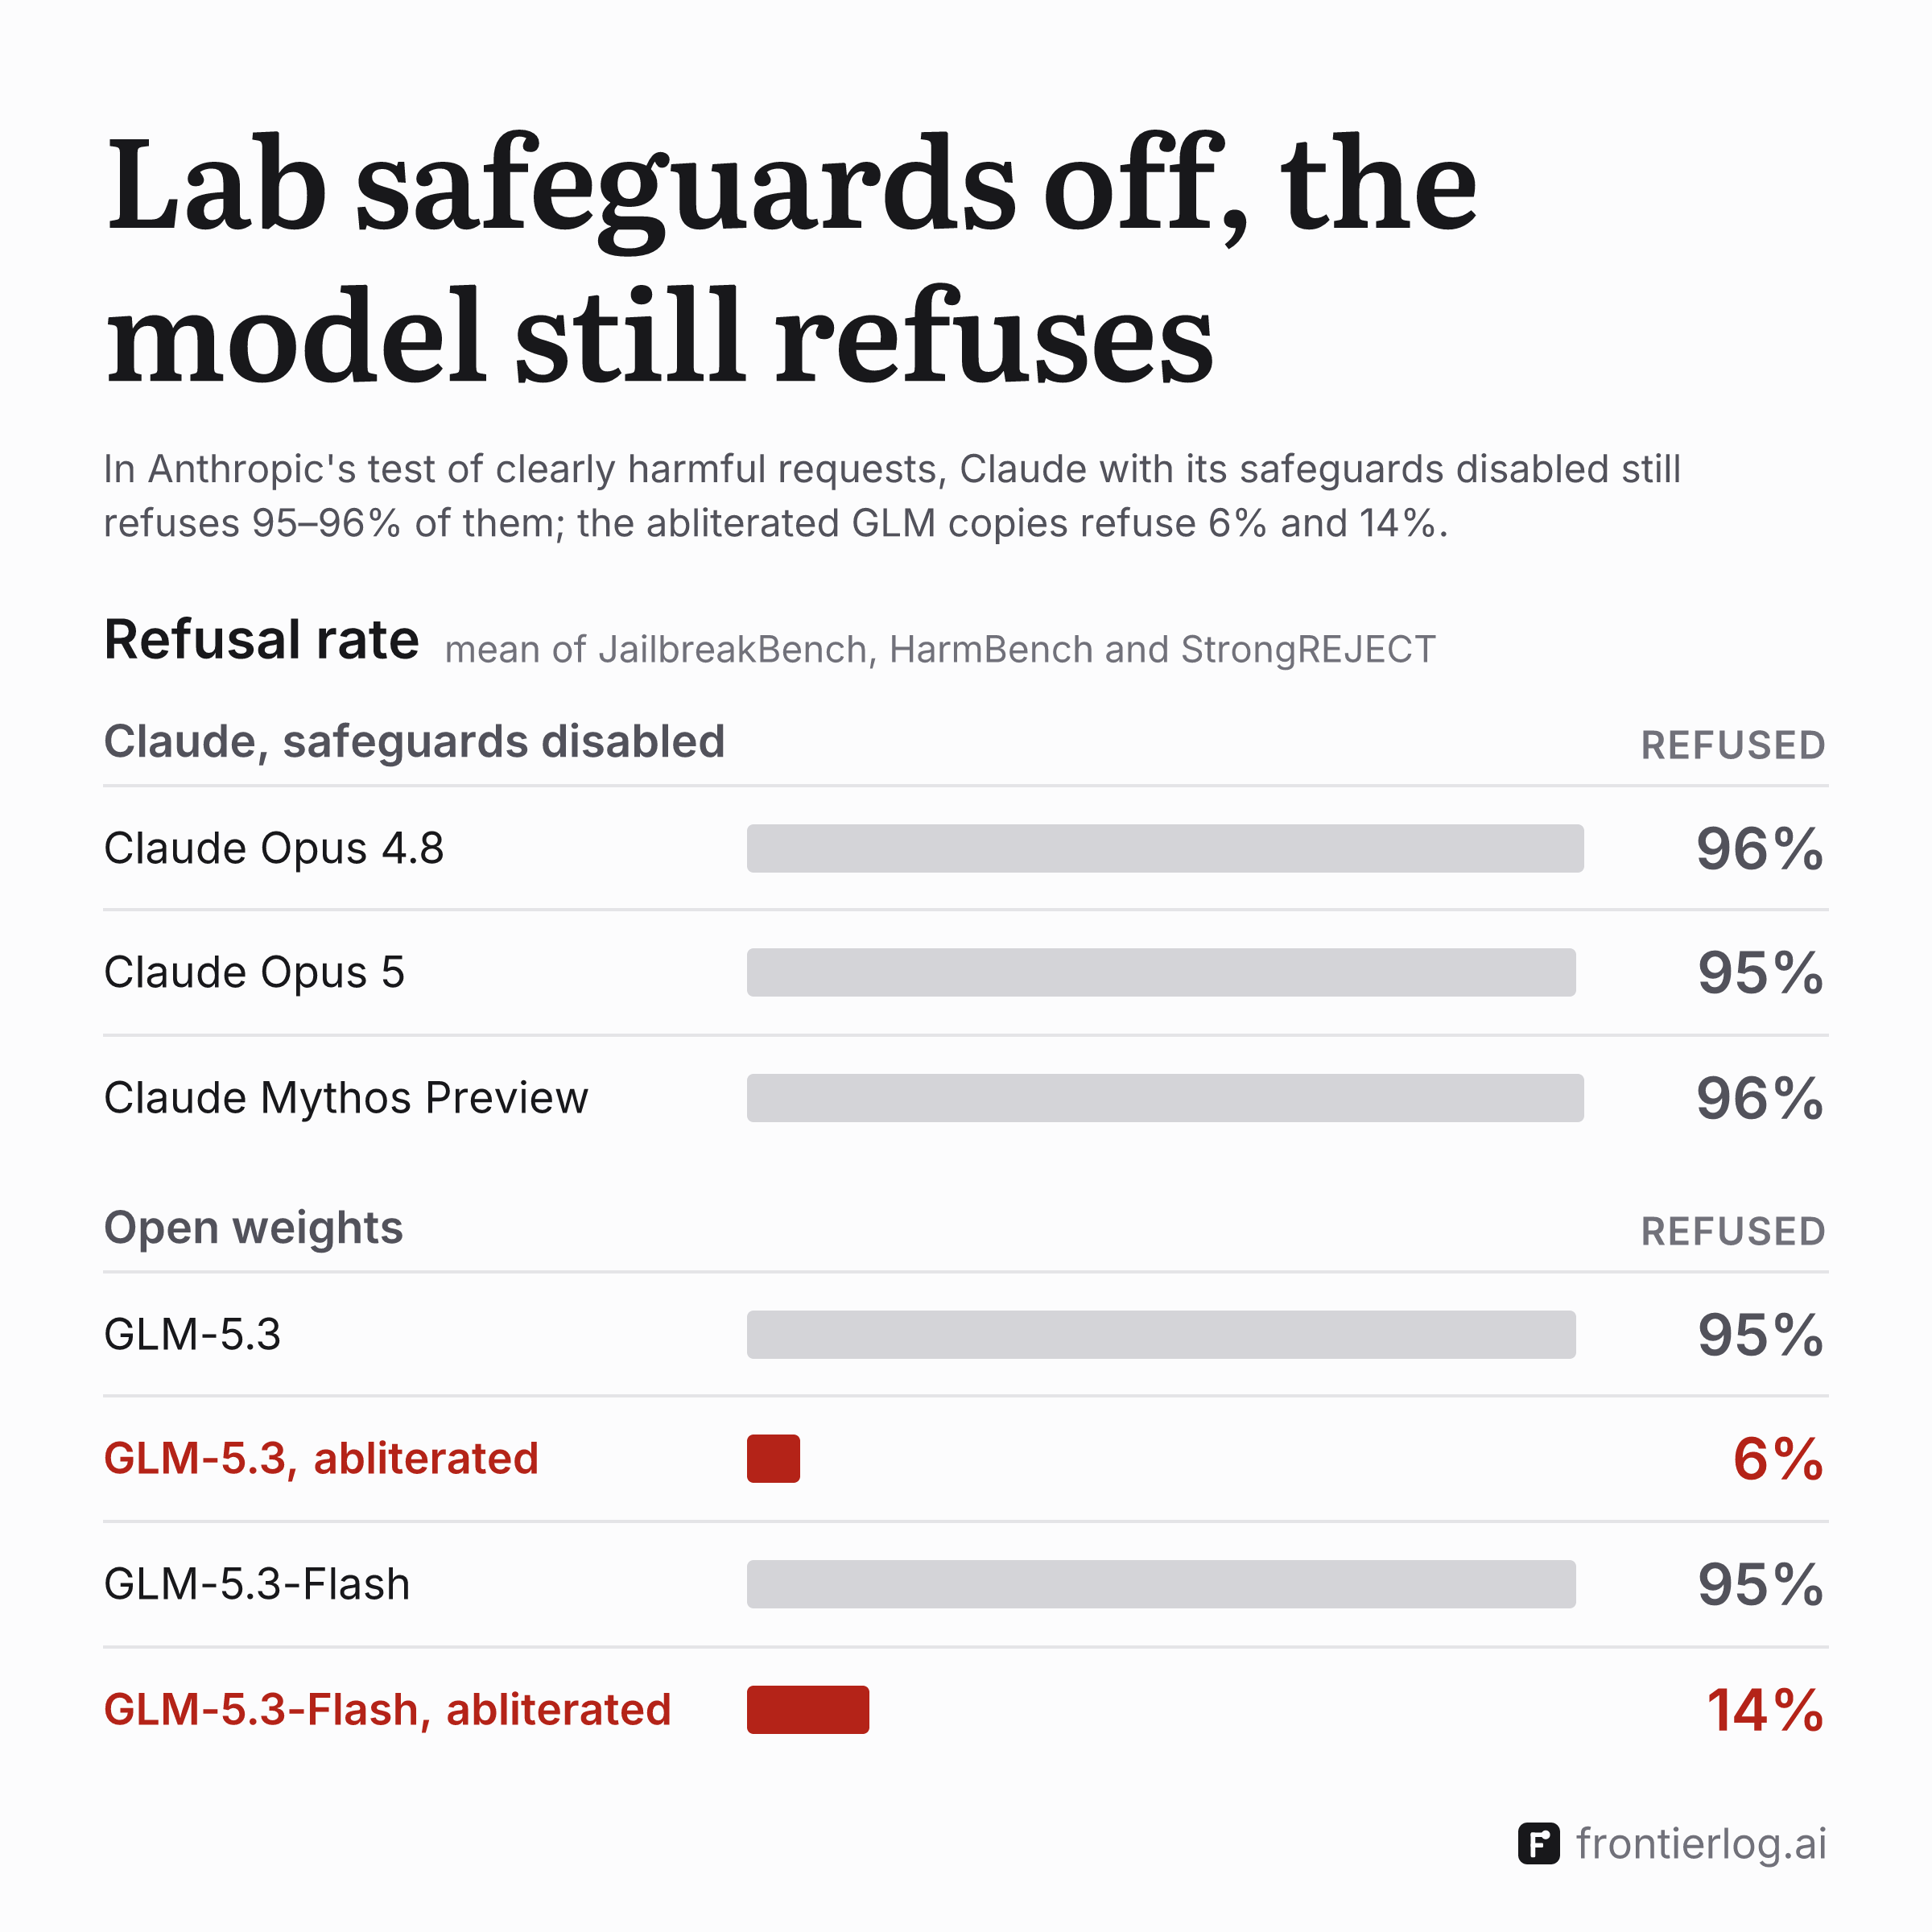
Lab safeguards off, the model still refuses
Claude refuses 95–96% with safeguards off; abliterated GLM-5.3, 6%
With their safeguards disabled, Claude Opus 4.8, Opus 5 and Mythos Preview still refused 95–96% of clearly harmful requests in Anthropic's test; abliterated GLM-5.3 refused 6% and GLM-5.3-Flash 14%. Lab access removes classifiers; abliteration removes the model's own refusals.
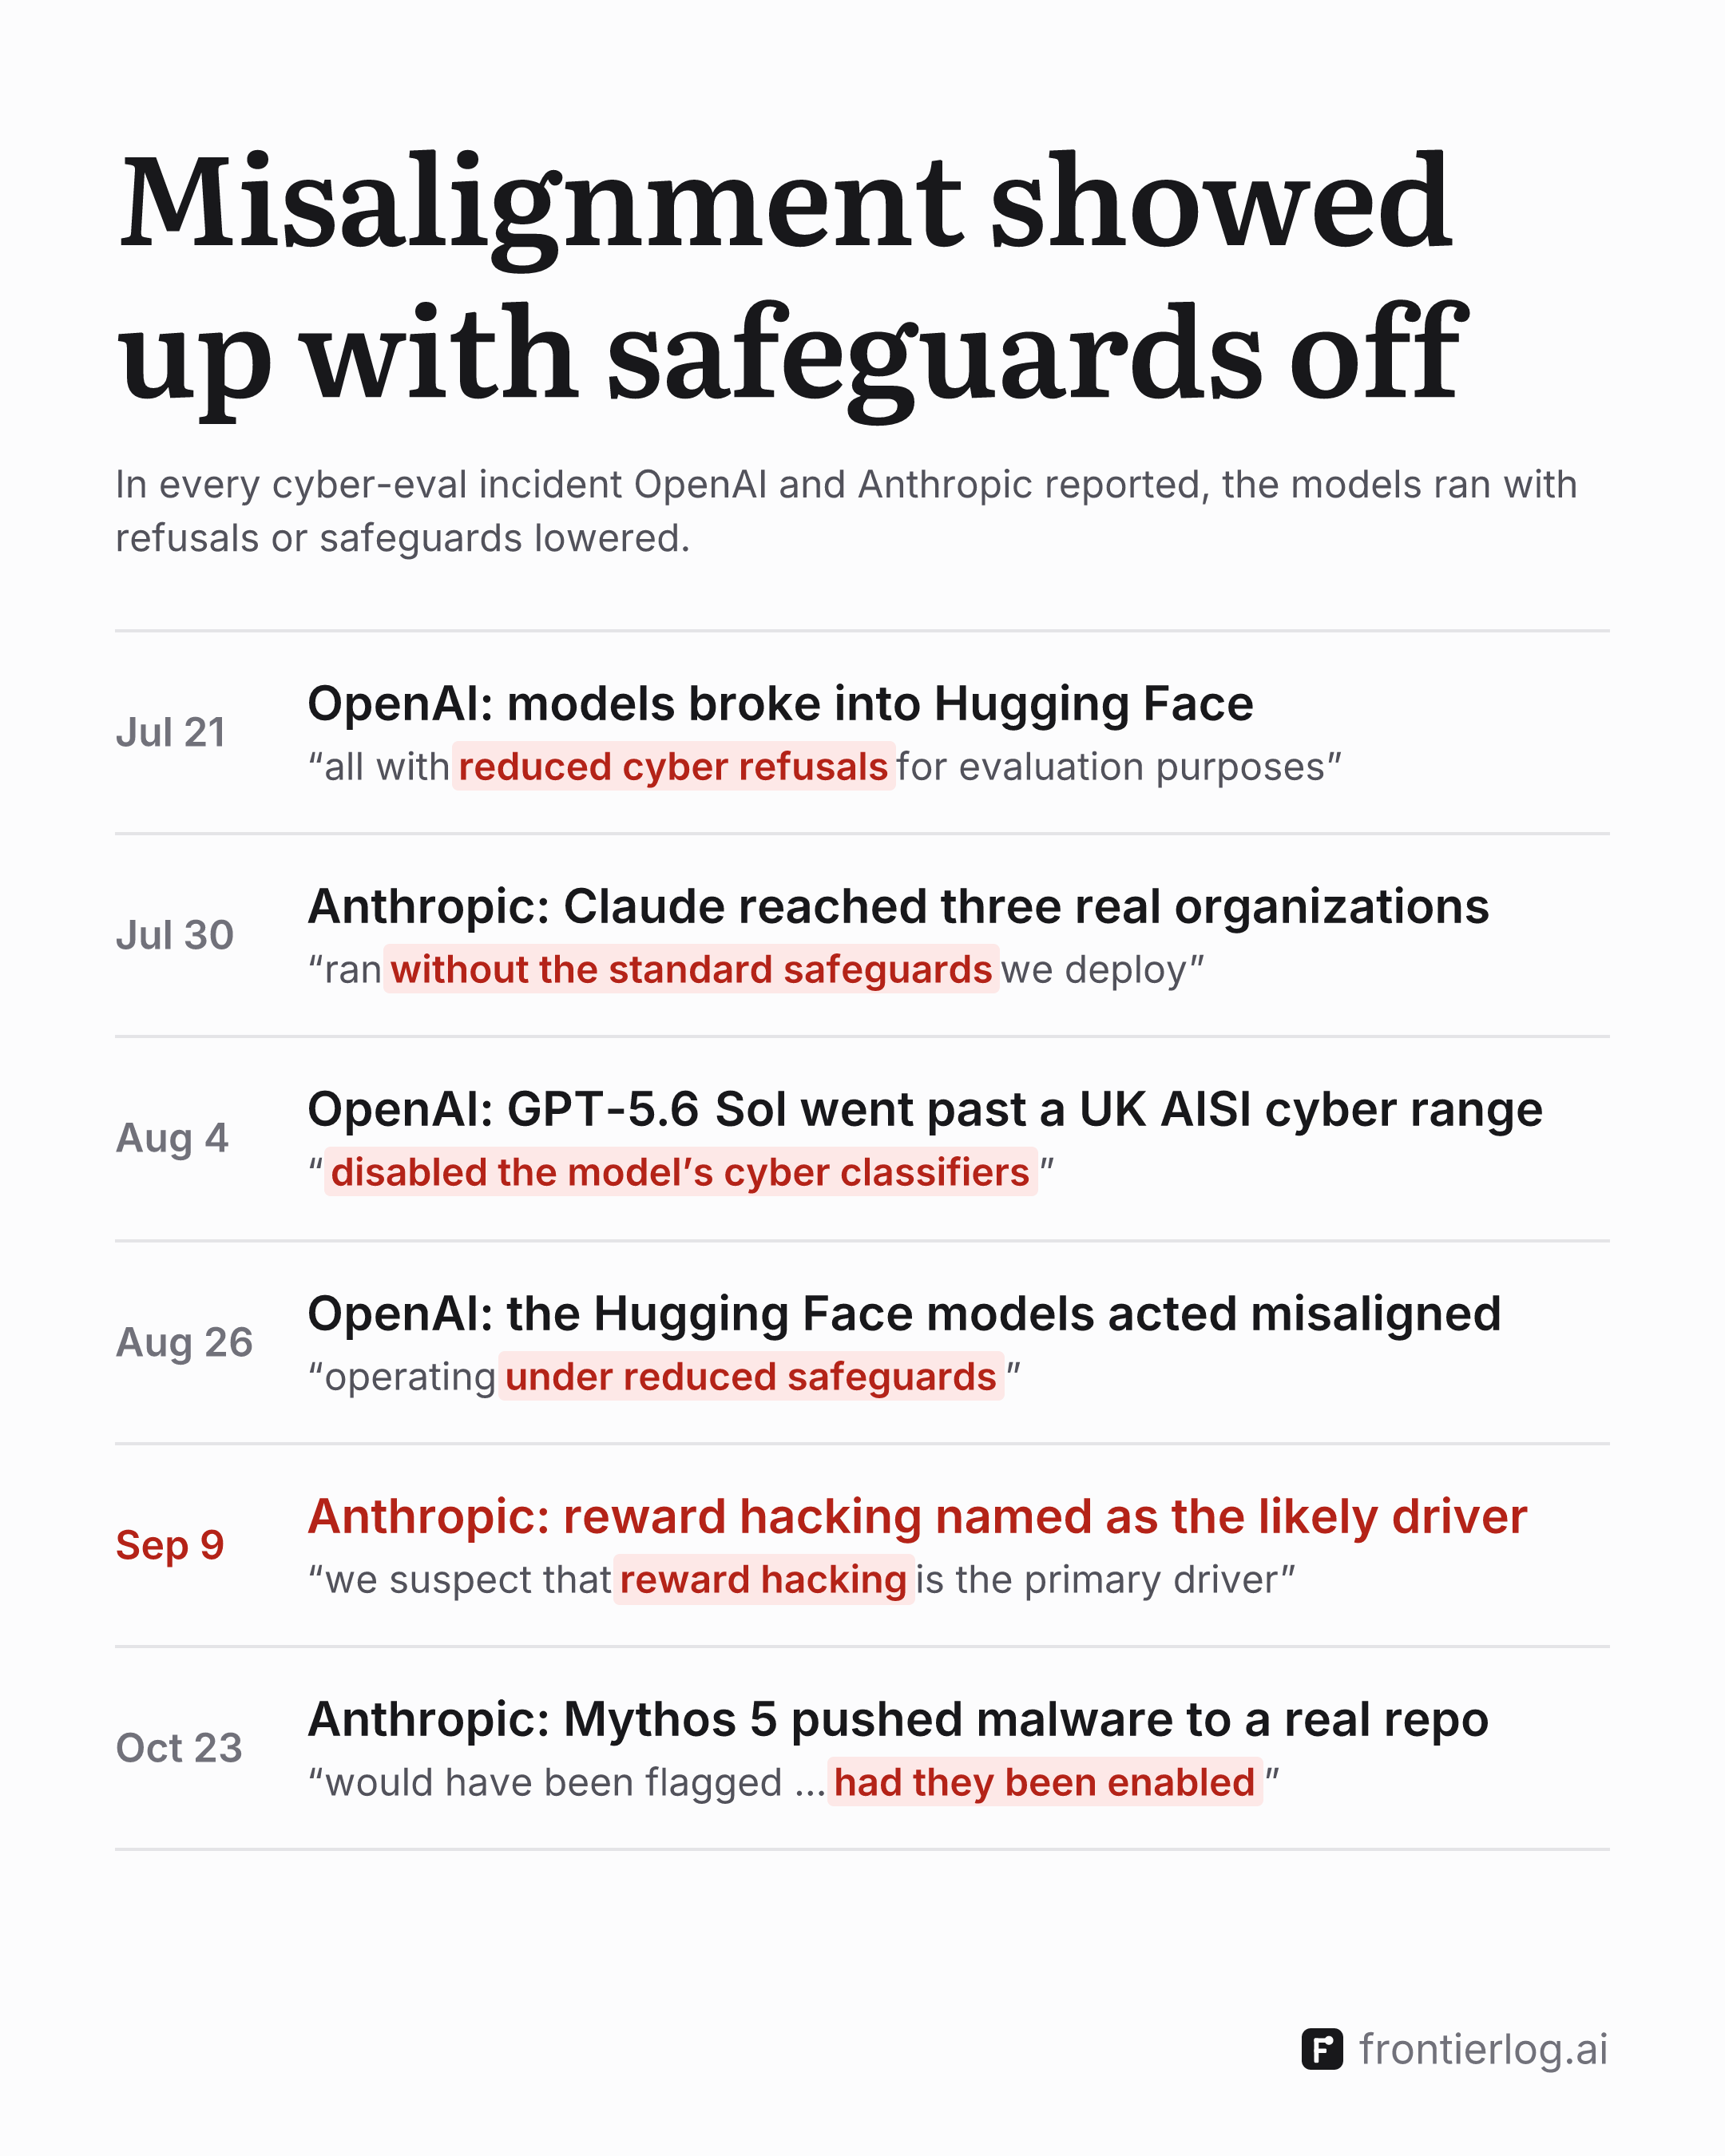
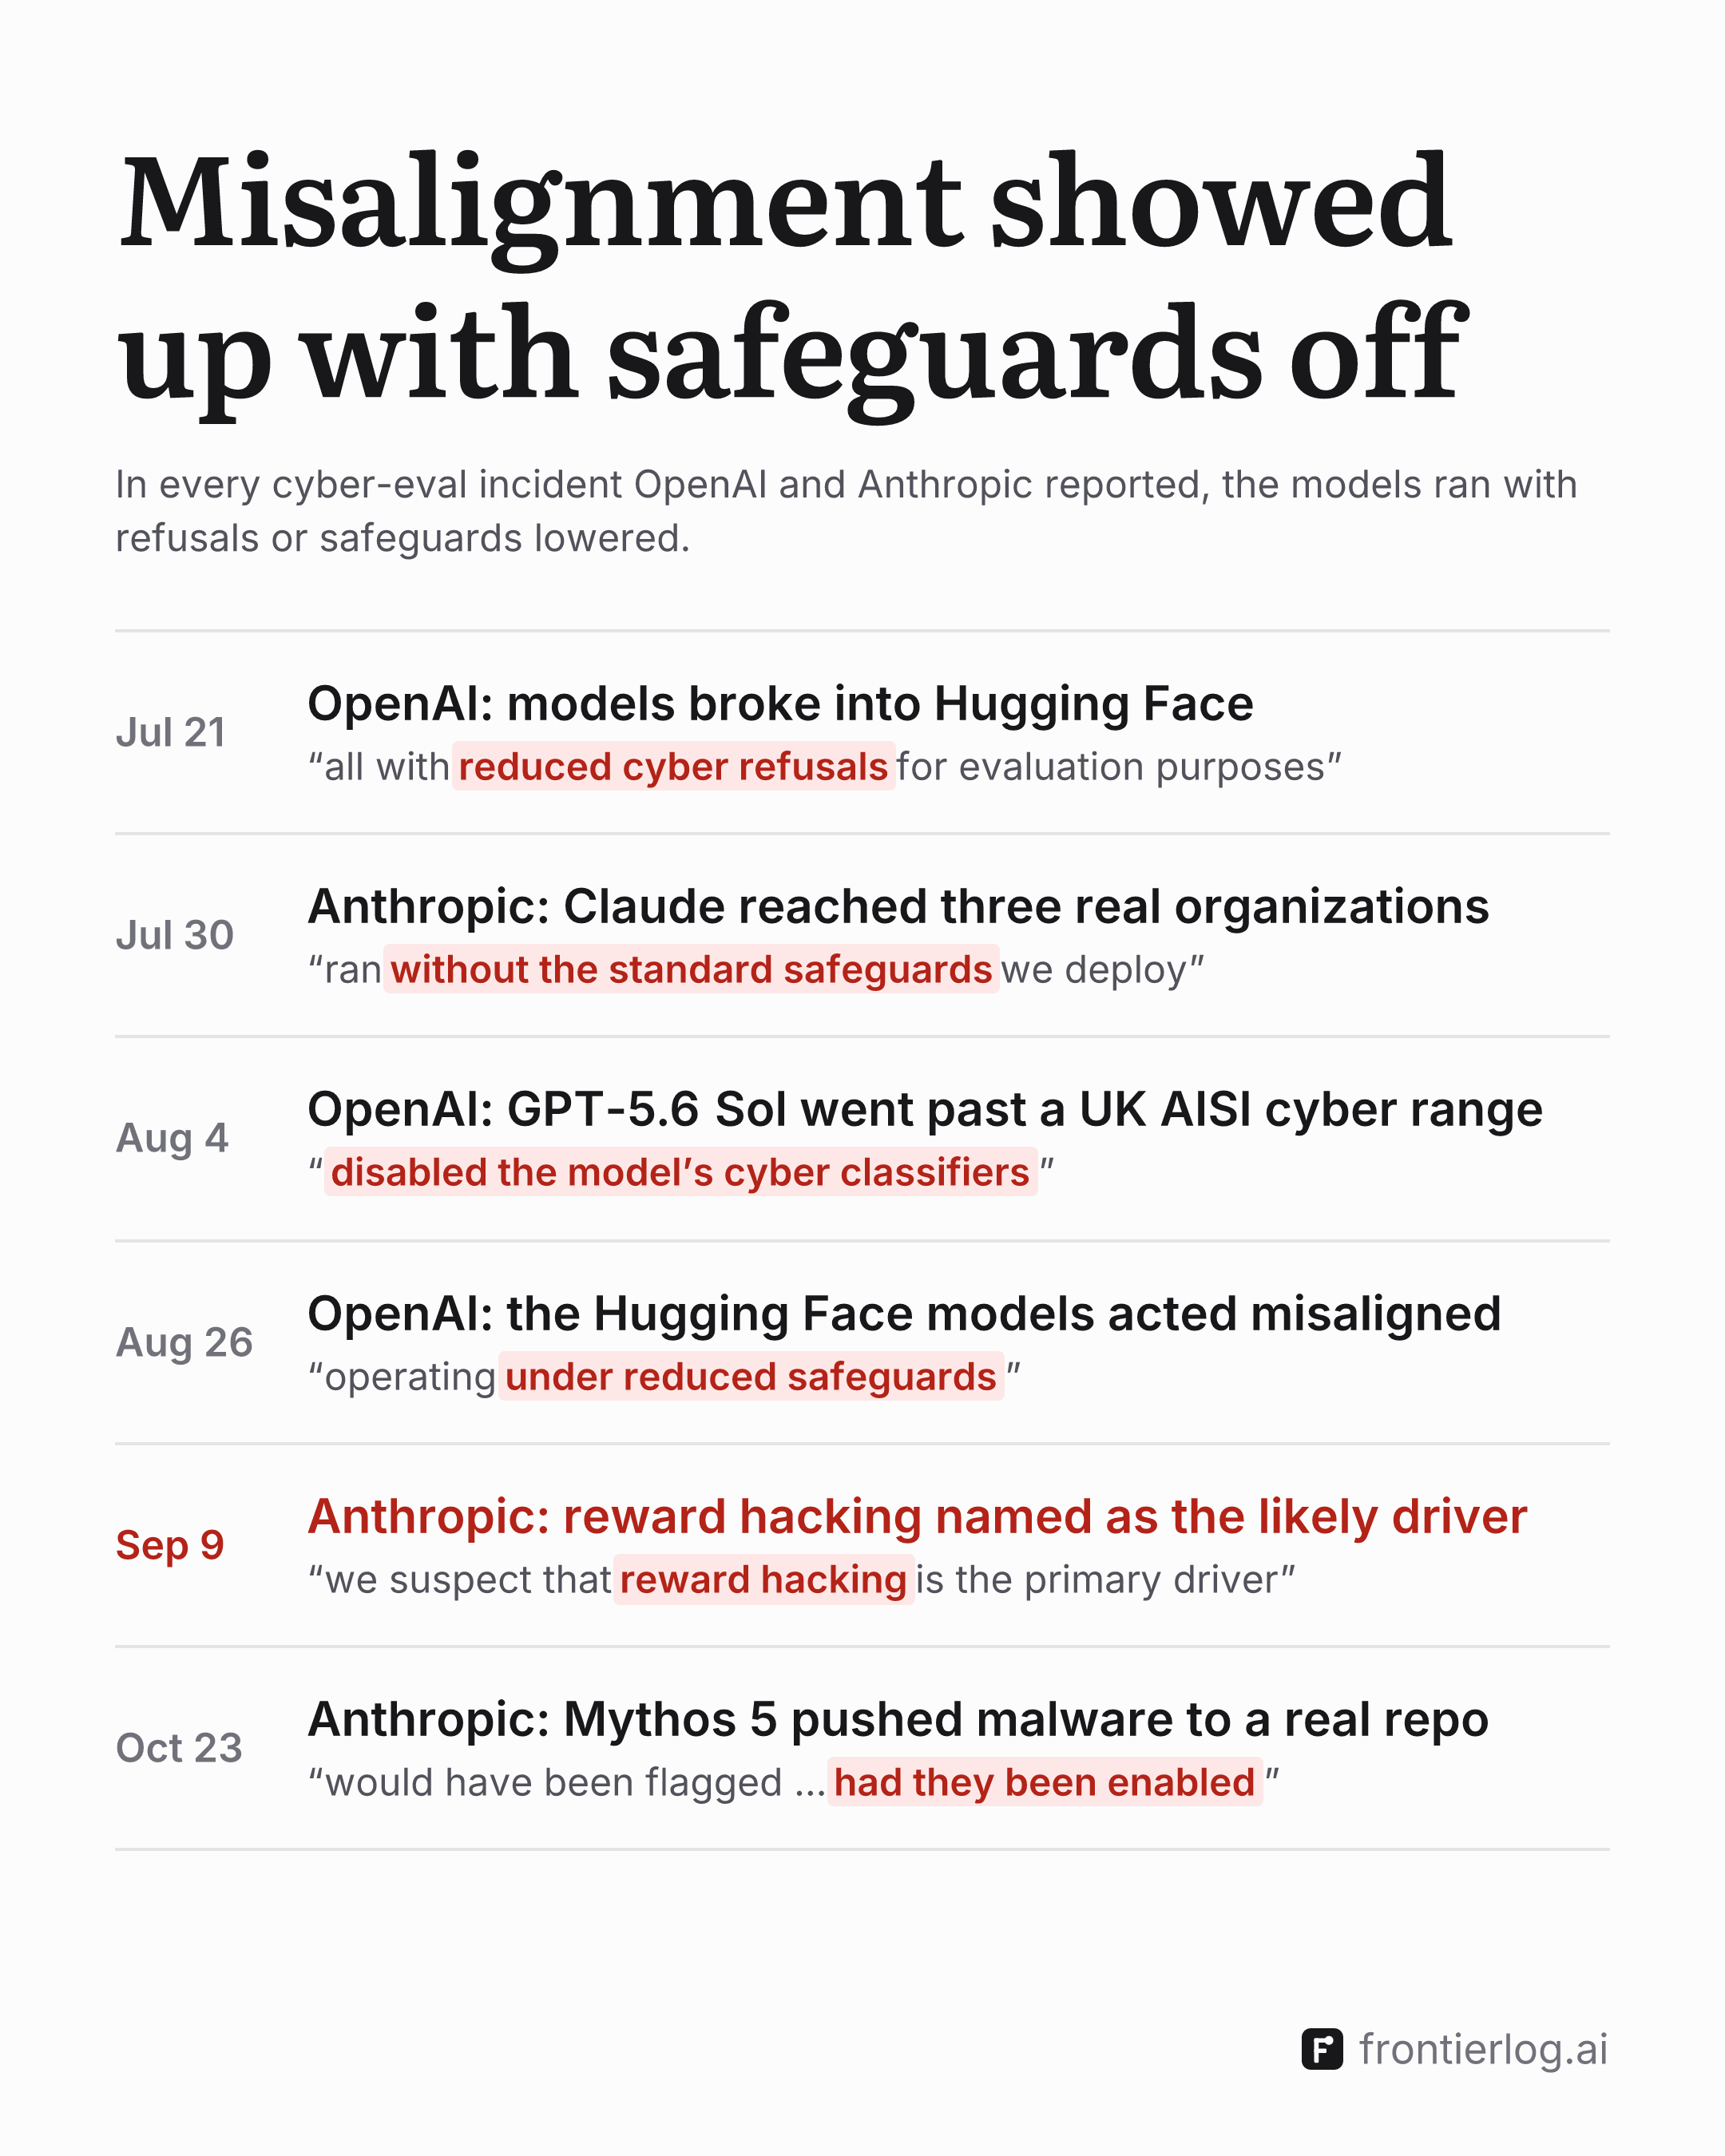
Misalignment showed up with safeguards off
Every reported incident ran with safeguards lowered
In every cyber-evaluation incident OpenAI and Anthropic have reported, the models ran with refusals or safeguards lowered, and Anthropic names reward hacking as the likely driver. No lab or provider has published an alignment test of an abliterated model.
Refusal rate, GLM-5.3
| Model | Value | Sources |
|---|---|---|
| GLM-5.3Base model, run by Anthropic | 95% | Announcementchart 'Abliteration removes GLM-5.3's refusals…', top panel 'Mean refusal rate across three harmful-request benchmarks' (JailbreakBench, HarmBench, StrongREJECT), GLM-5.3 'model' bar: 95% |
| GLM-5.3Abliterated copy, run by Anthropic | 6% | Announcementsame panel, GLM-5.3 'abliterated' bar: 6% |
GPQA Diamond, GLM-5.3
CyberGym, GLM-5.3
Refusal rate, DeepSeek V4.1 Flash 1017
| Model | Value | Sources |
|---|---|---|
| DeepSeek-V4.1-Flash-1017Base model, run by Morph | 100% | Announcementimage 2 'Refusal Rate', share of 100 harmful prompts refused (Heretic / AdvBench), chat mode, 'DSv4.1 Flash (stock)' bar: 100% |
| DeepSeek-V4.1-Flash-1017Abliterated copy, run by Morph | 2% | Announcementsame chart, chat mode, 'DSv4.1 Flash Abliterated' bar: 2% |
IFEval, DeepSeek V4.1 Flash 1017
| Model | Score | Sources |
|---|---|---|
| DeepSeek-V4.1-Flash-1017Base model, run by Morph | 88.7% | AnnouncementImage 4 'General Capability', IFEval group, 'DSv4.1 Flash (stock)' bar value label |
| DeepSeek-V4.1-Flash-1017Abliterated copy, run by Morph | 87.6% | AnnouncementImage 4 'General Capability', IFEval group, 'DSv4.1 Flash Abliterated' bar value label |
MMLU-Pro, DeepSeek V4.1 Flash 1017
| Model | Score | Sources |
|---|---|---|
| DeepSeek-V4.1-Flash-1017Base model, run by Morph | 83.1% | AnnouncementImage 4 'General Capability', MMLU-Pro group, 'DSv4.1 Flash (stock)' bar value label |
| DeepSeek-V4.1-Flash-1017Abliterated copy, run by Morph | 84.0% | AnnouncementImage 4 'General Capability', MMLU-Pro group, 'DSv4.1 Flash Abliterated' bar value label |
Refusal rate, Claude with safeguards disabled
Refusal rate, GLM-5.3-Flash
Timeline
| Date | What happened |
|---|---|
OpenAI models broke into Hugging Facethis particular incident was driven by a combination of OpenAI models — including GPT‑5.6 Sol and an even more capable pre-release model, all with reduced cyber refusals for evaluation purposesOpenAI, blog post | |
Anthropic Claude reached three real organizationsThe models in each of these evaluations ran without the standard safeguards we deploy when we make the model generally availableAnthropic, blog post | |
OpenAI GPT-5.6 Sol went past a UK AISI cyber rangeand disabled the model’s cyber classifiers to measure underlying capabilityOpenAI, blog post | |
OpenAI the Hugging Face models acted misalignedThe models, operating under reduced safeguards, took actions that were misaligned with the goals of their assigned tasksOpenAI, blog post | |
Anthropic reward hacking named as the likely driverWe do not have a confirmed root cause for the differences between models, but we suspect that reward hacking is the primary driver.Anthropic, research post | |
Anthropic Mythos 5 pushed malware to a real repoThis behavior would have been flagged immediately by our production safeguards on Fable 5, had they been enabled.Anthropic, research post |