AutomationBench Scores Depend on Who Runs the Test
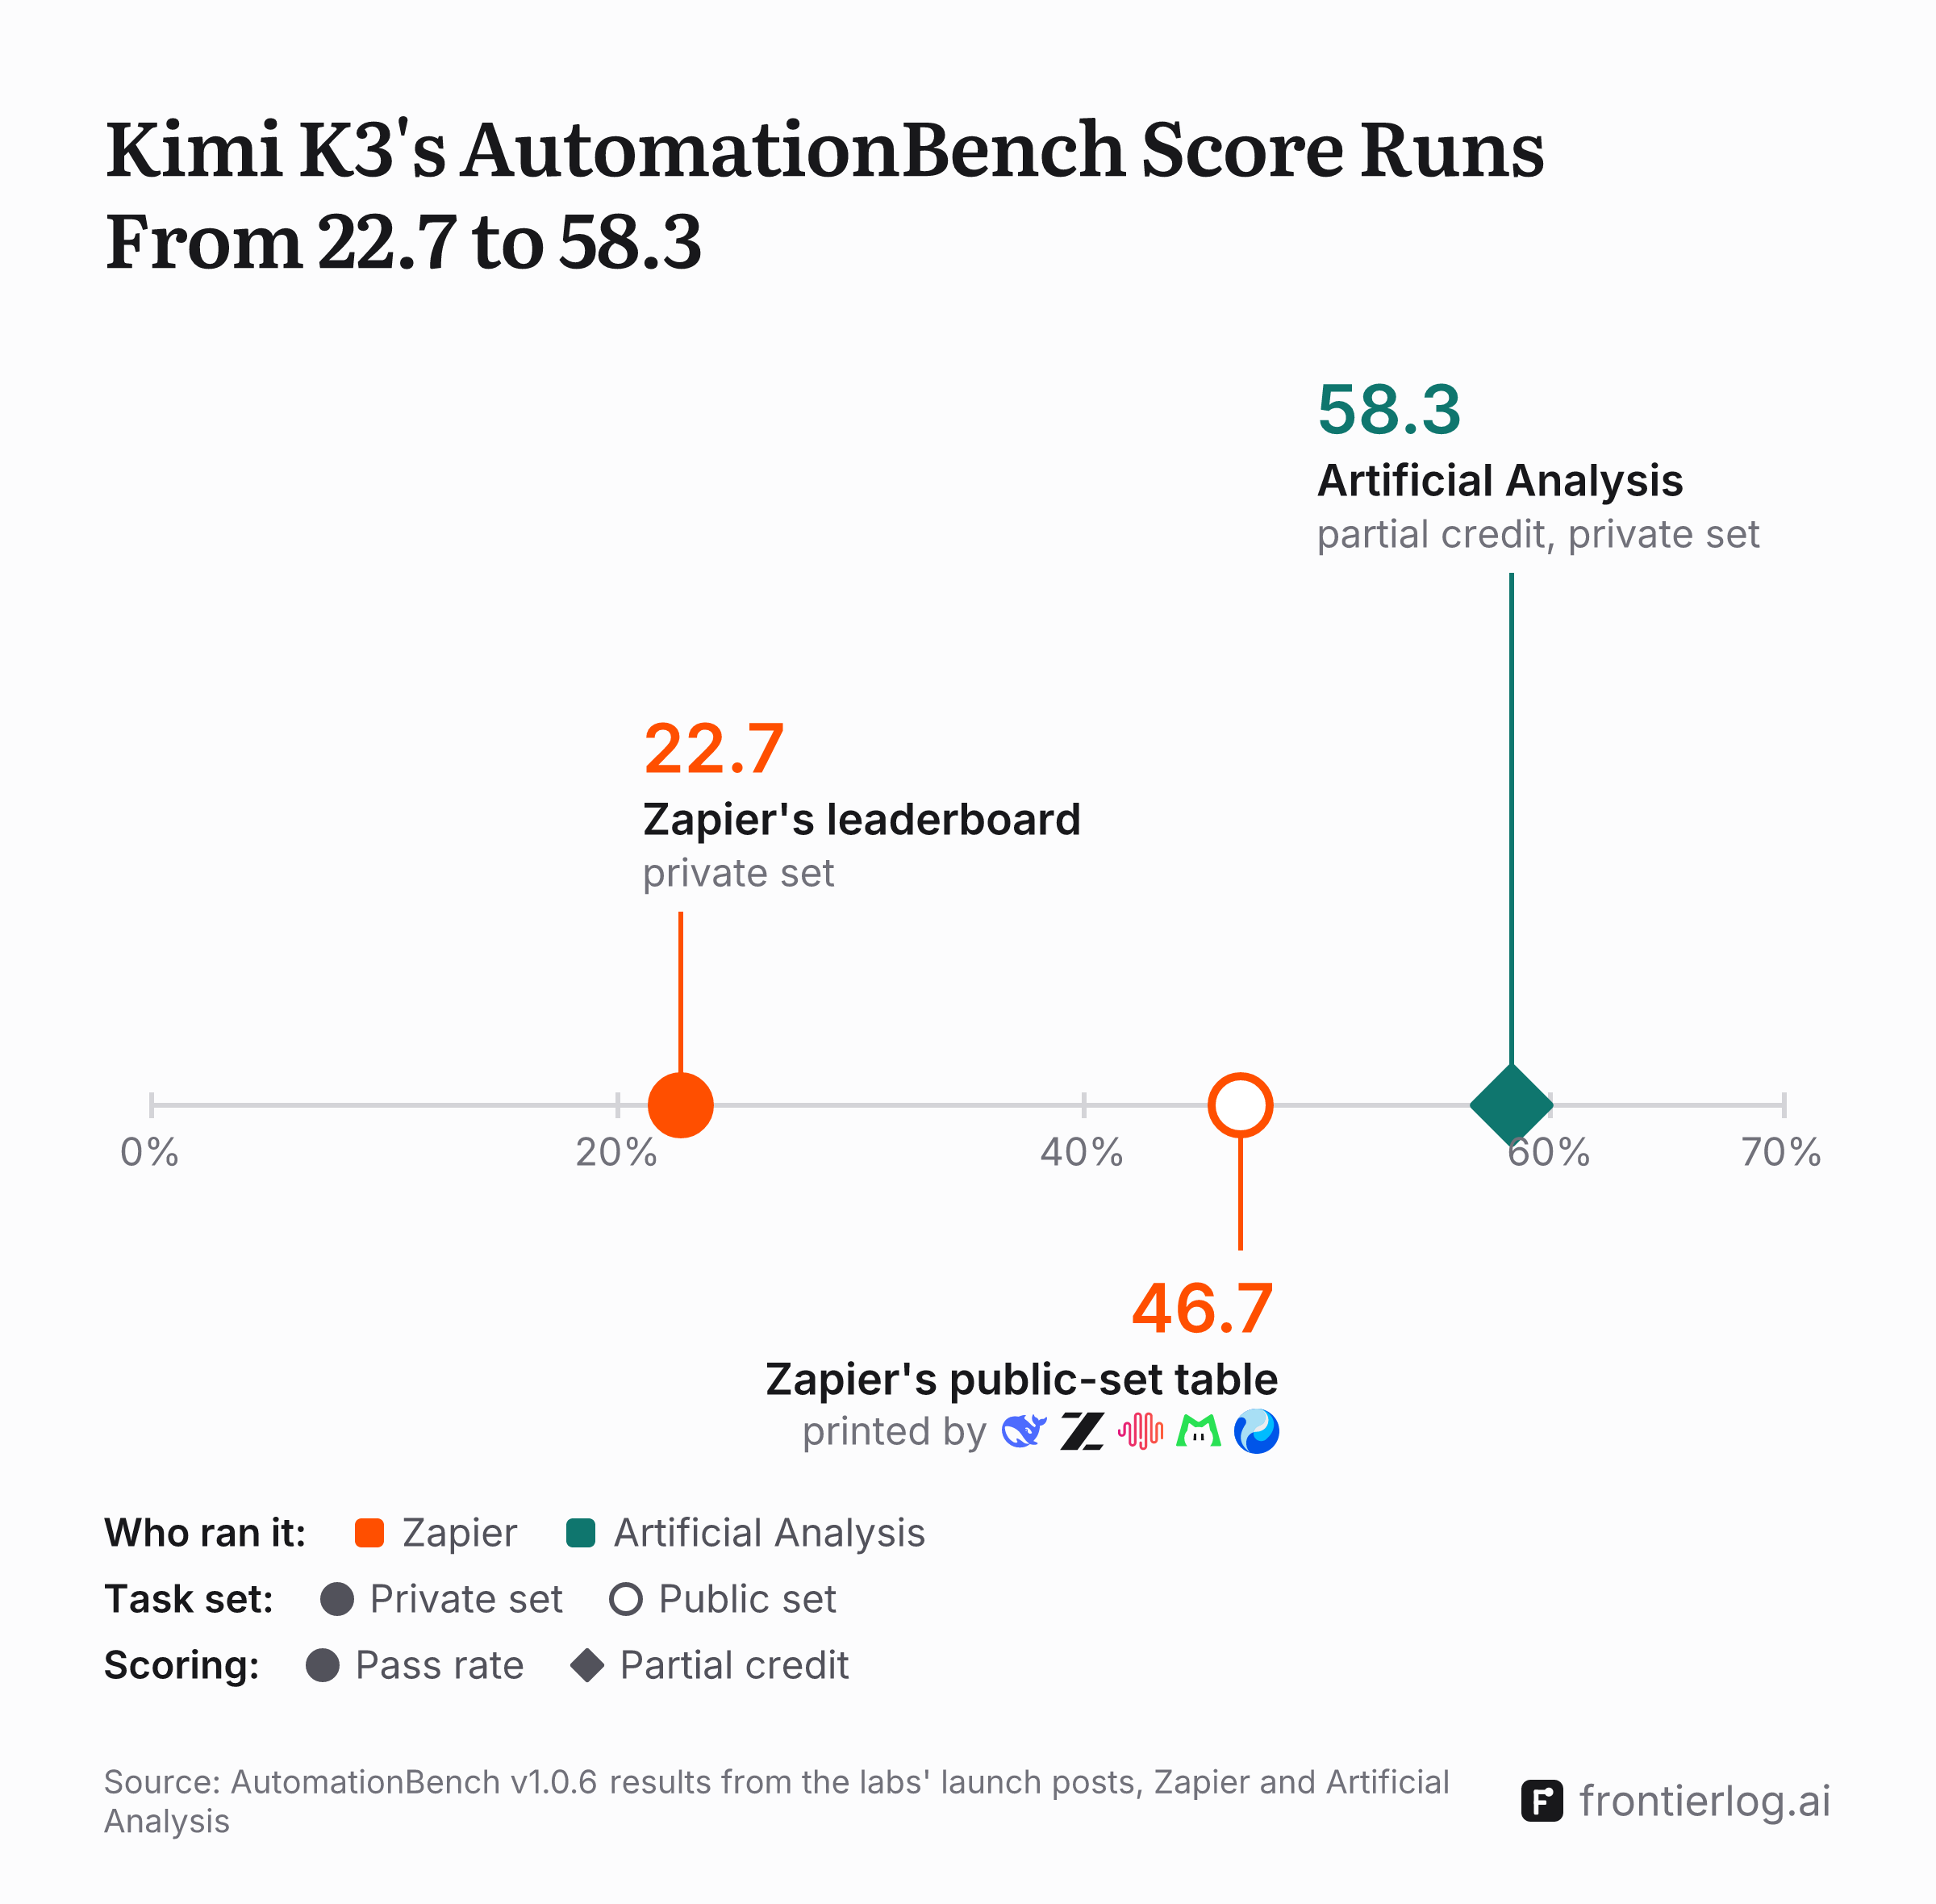
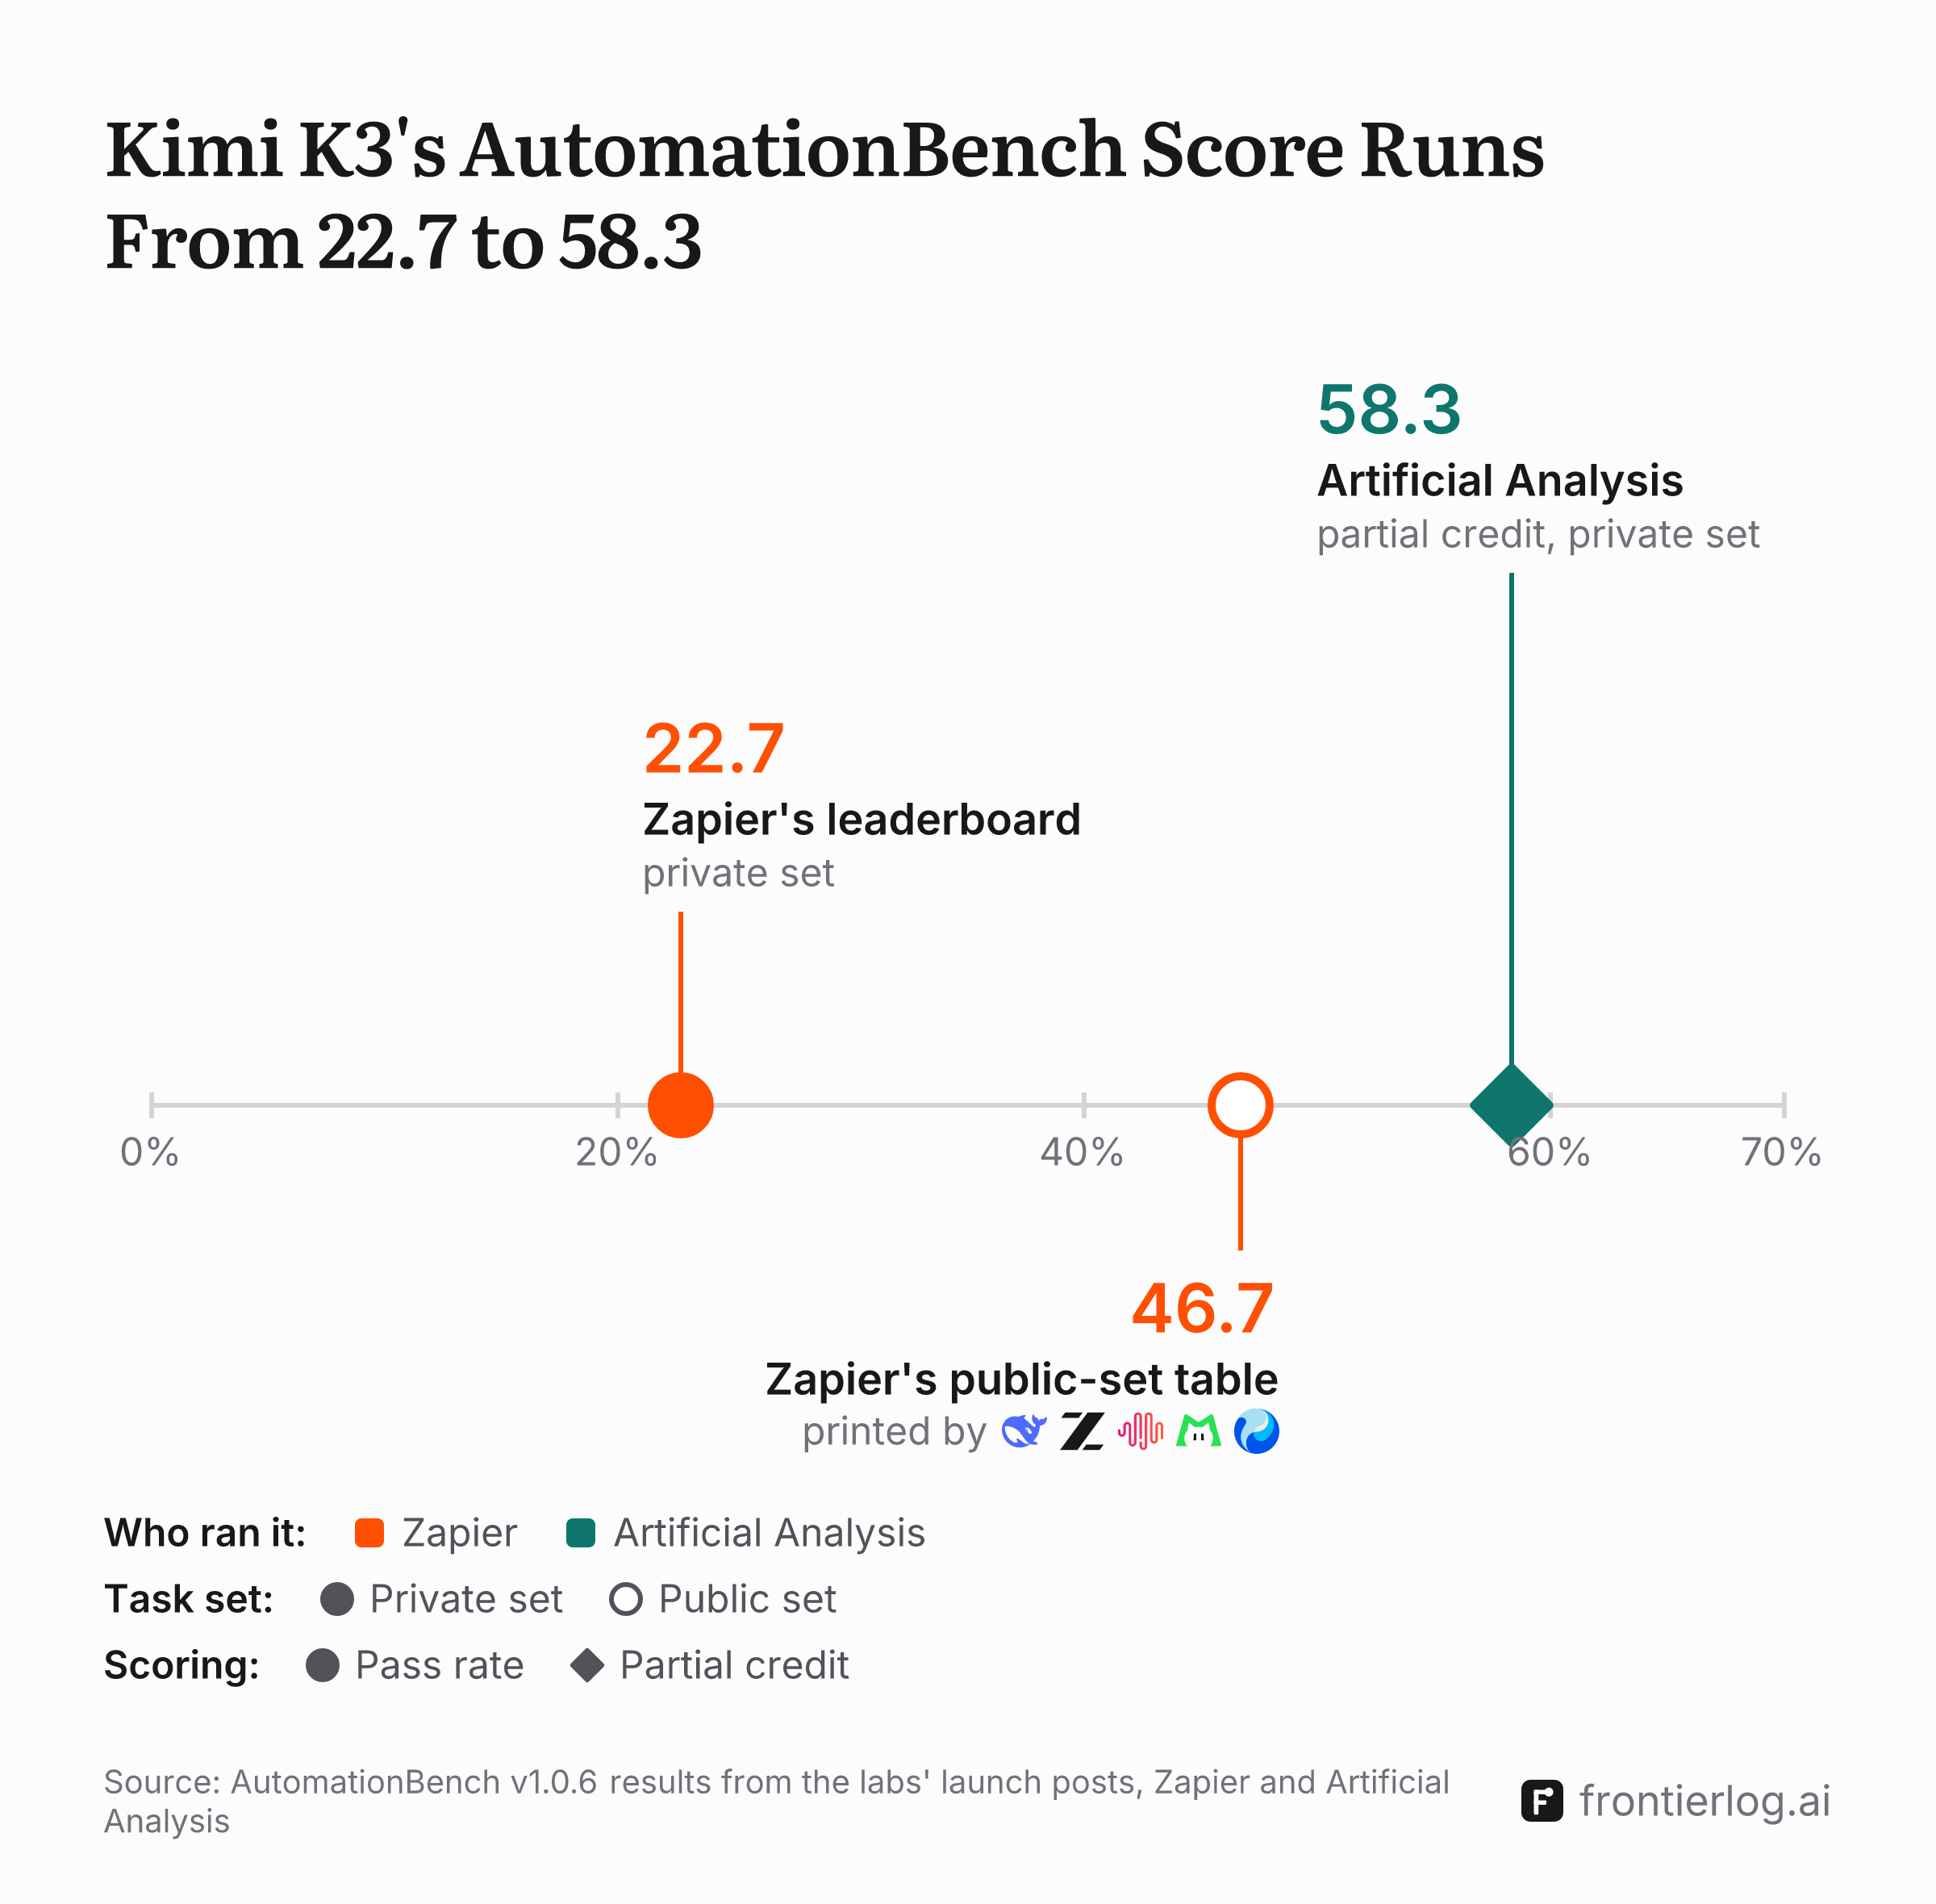
Labs' AutomationBench figures come from their own runs, others' tables, Zapier or Artificial Analysis, and sit up to 35.6 points apart with partial credit.
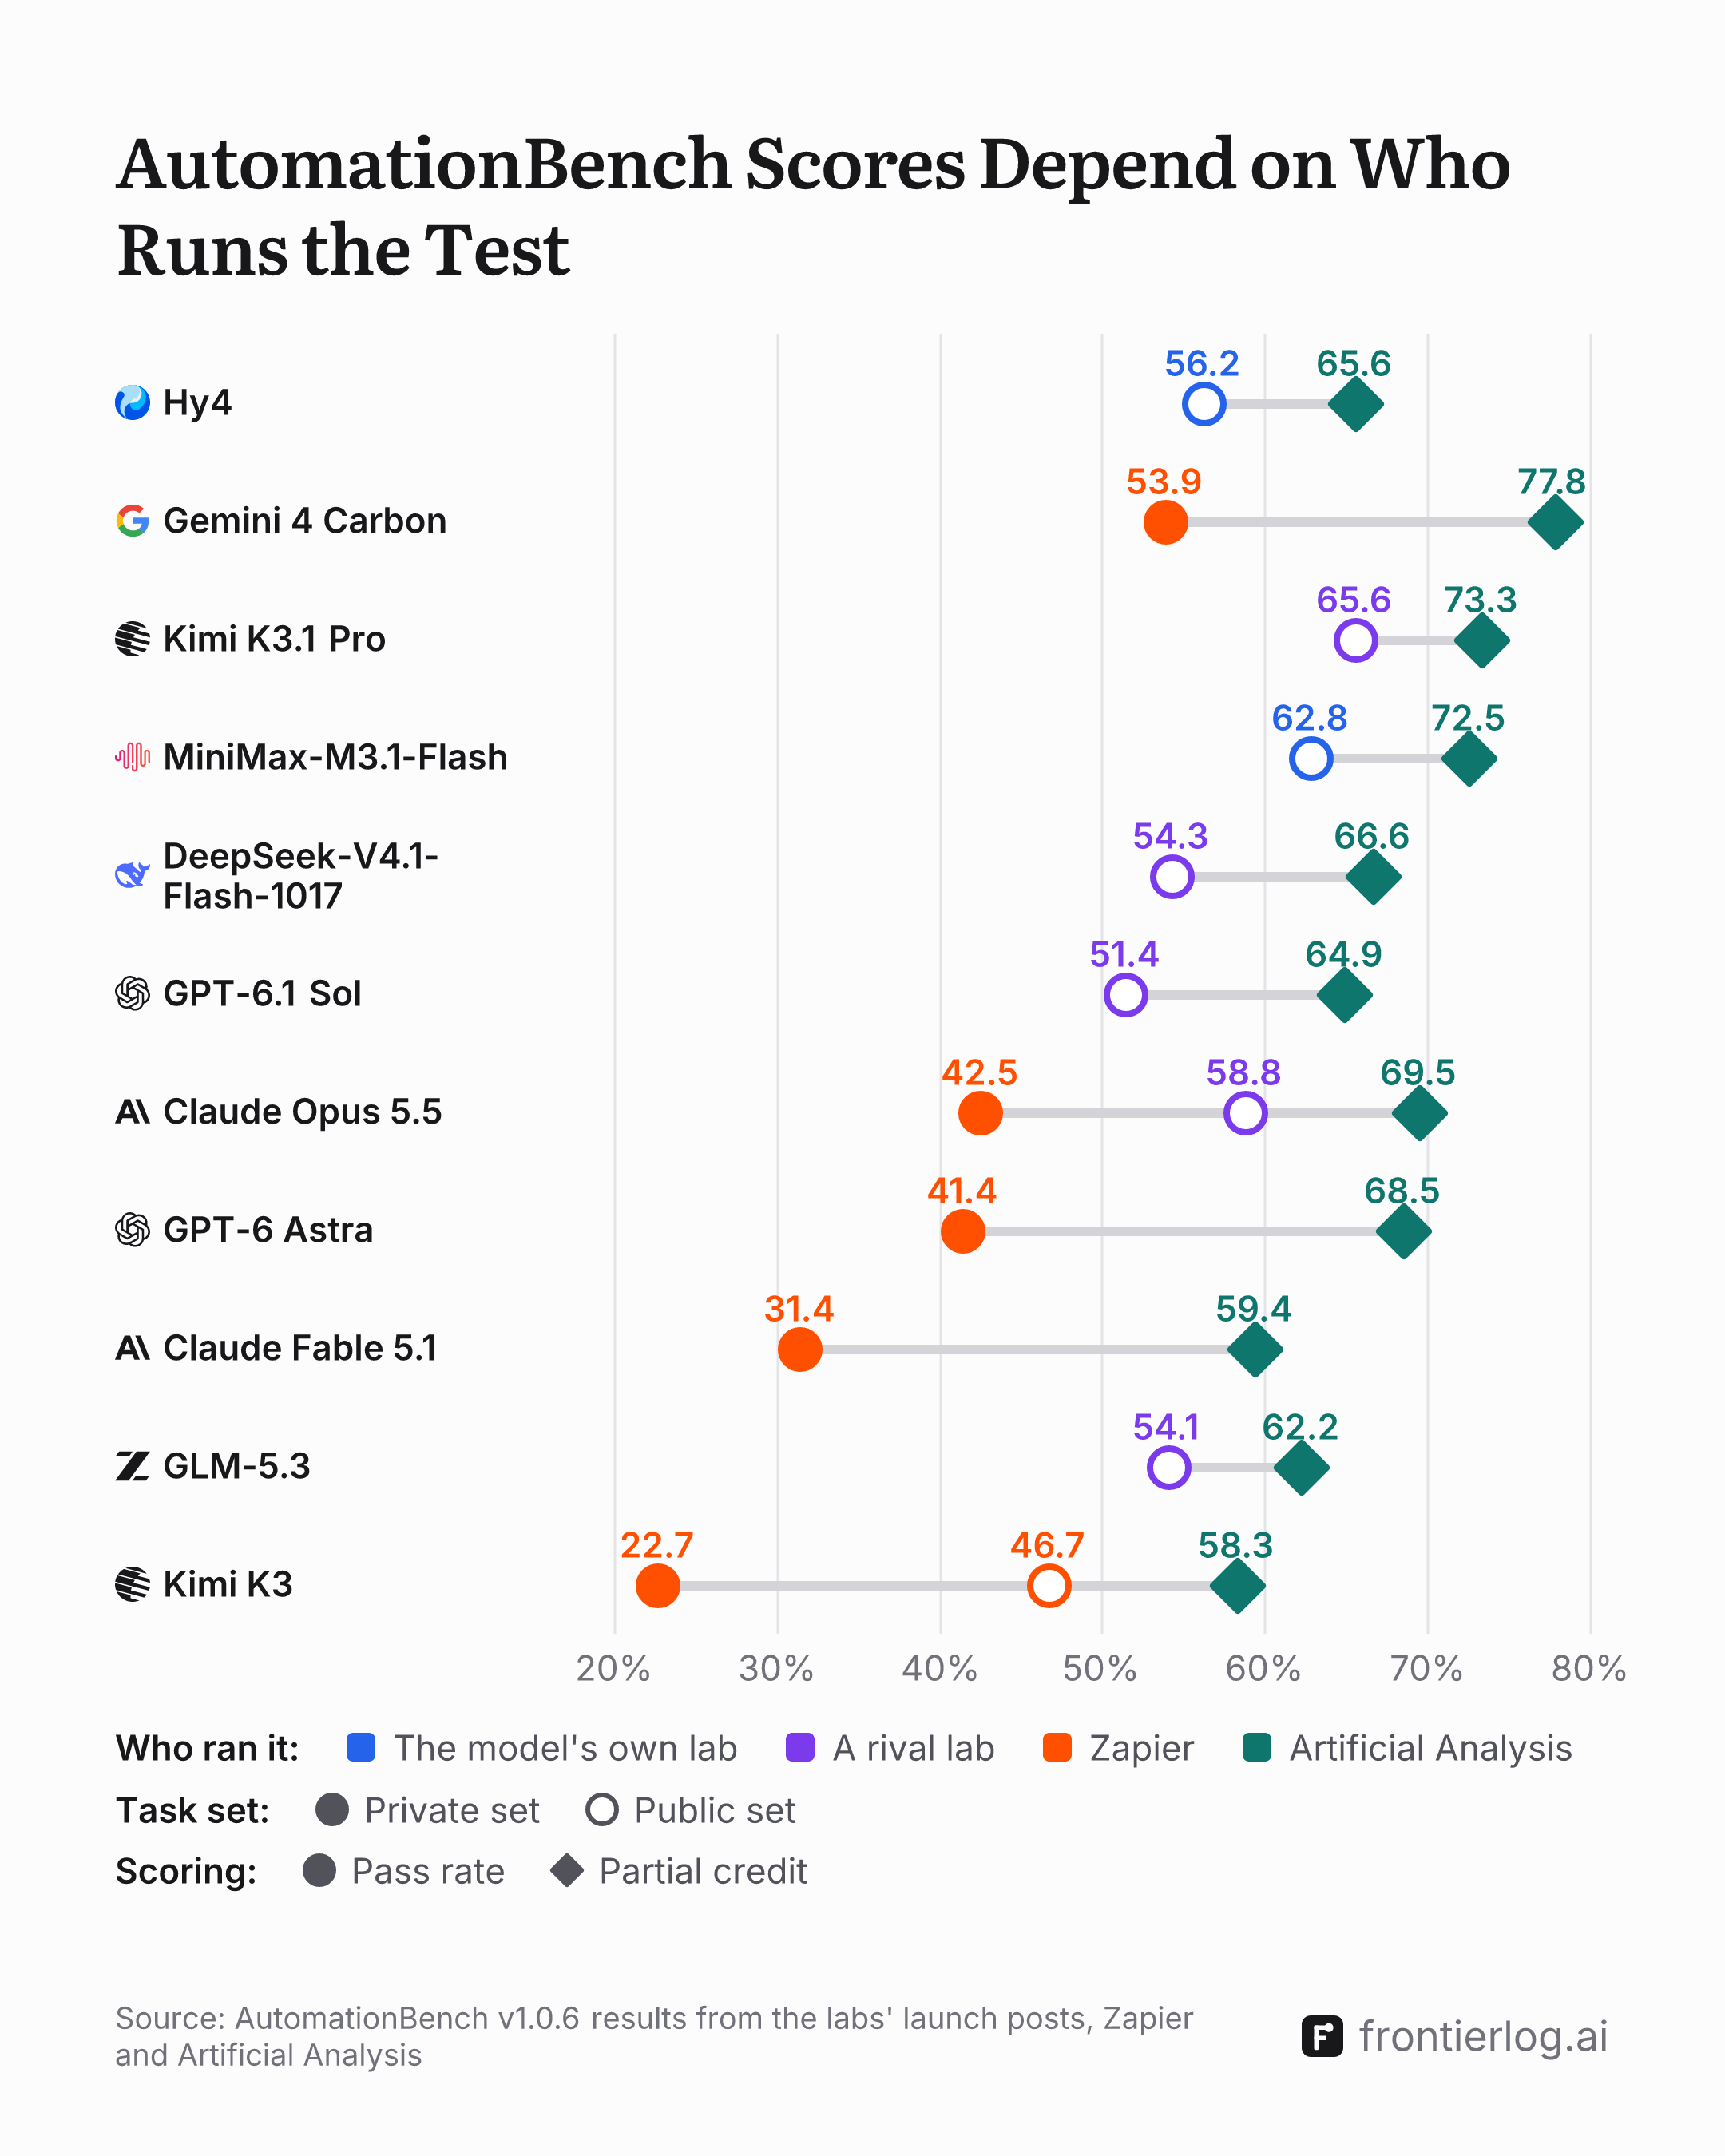
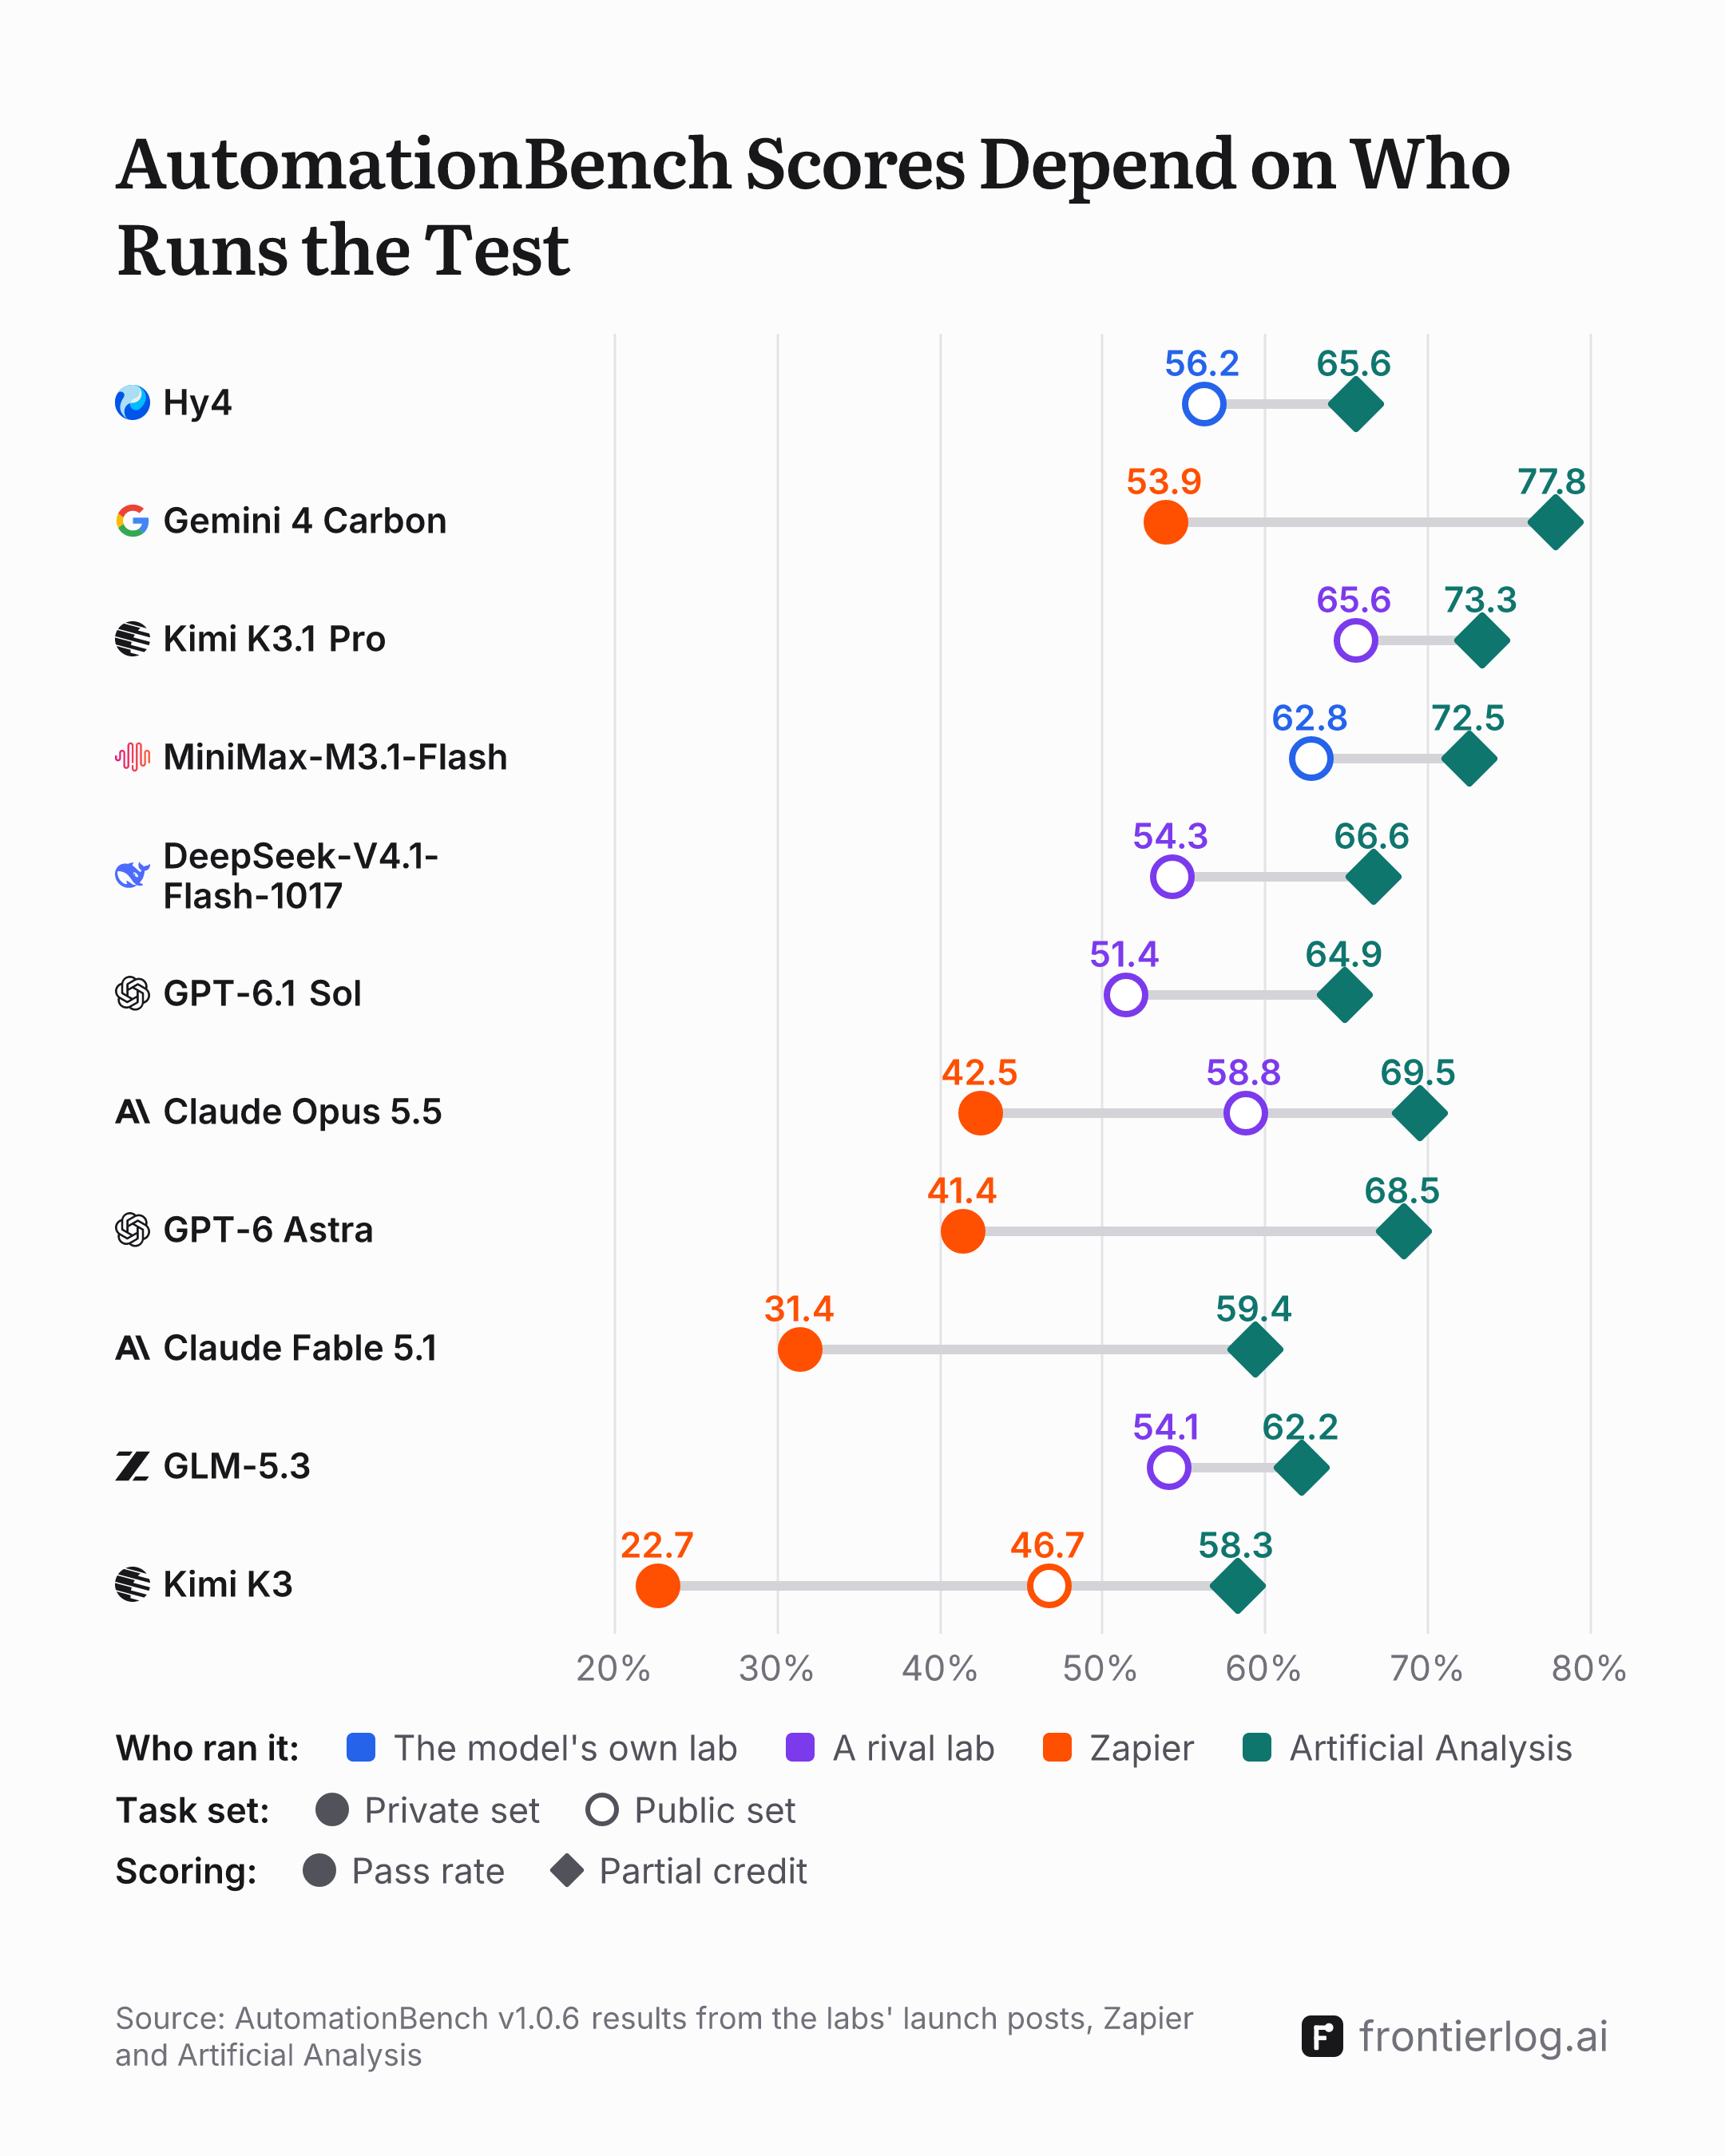
When a lab launches a model, its benchmark table puts the model beside its rivals. On AutomationBench, Zapier's test of business workflows, those figures come from four places. The lab may run the test itself or print a figure someone else published. It may also cite Zapier's own runs, or use Artificial Analysis, a third party that didn't make the benchmark. The same model can get very different figures depending on which one a table uses. Kimi K3 is at 22.7% on Zapier's leaderboard, 30.8% in Moonshot AI's own post and 58.3% in Thinking Machines' card for Inkling 2 Small on Nov 5.
The lab runs the test
In its Kimi K3 post, Moonshot AI ran every model on AutomationBench itself. Its Jul 16 post says "All models are evaluated on the 600-task public subset, following the official GitHub setup in all other respects." Tencent's Hy4 tables mix its own runs with figures it took from others, and mark its own with a star: "* indicating our own testing," says its Nov 4 post. Meituan's LongCat-2.5 post marks the other way round. Its starred figures "are from public technical report, blog posts or the official benchmark leaderboards, otherwise are self-run and are indicative only."
A lab that runs a rival chooses the task set, the harness and the settings. Its figure can differ from the rival lab's own. Tencent's run puts DeepSeek-V4.1-Flash-1017 at 54.3%, and DeepSeek's own post gives 60.5%. Tencent's run puts GLM-5.3 at 54.1%, and Z.ai's post gives 48.2%. Tencent's Aug 28 table had run GLM-5.3 at 49.4%. Its Nov 4 notes say "Certain Hy4-preview benchmark scores may differ from previously reported results following updates to the evaluation harness, judge model, and anti-hacking mechanisms."
Printing someone else's figure
Some tables print figures identical to ones another party published, without naming the source. DeepSeek's Aug 13 table and Alibaba's Qwen3.8-Max post give Claude Opus 4.8 27.2% on the public set, the same figure as Moonshot AI's run. Alibaba also gives GPT-5.6 Sol Moonshot AI's 29.7%. Alibaba's footnote says "Automation-Bench: Evaluated on the 600-task public subset."
Later tables print other public-set figures for the same models, identical to the table on Zapier's GitHub page. DeepSeek, Z.ai, MiniMax, Meituan and Tencent give GPT-5.6 Sol 45.8%, and Z.ai and Meituan give Claude Opus 4.8 41.0%. Zapier's page says those pass rates are on "the 600-task public benchmark," with "each model run at its highest available reasoning effort."
Anthropic says its competitor figures "are drawn from the respective developers' published system cards or benchmark leaderboards." OpenAI's GPT-6 Sol and Luna post says "Evaluations of competitor models were taken from publicly available reports."
The benchmark's maker runs it
Zapier keeps a second set of tasks private. Its leaderboard says its scores "run against a held-out private evaluation set." The GitHub page says the private set "is purposely harder and is not released, so scores you measure locally may not match the official leaderboard 1:1." Anthropic and Google report private-set figures. Anthropic's Claude Opus 5.5 post says its "AutomationBench results were run and reported by Zapier." Zapier ran them without fallback models, so safeguard interventions counted as failures. Anthropic says "this resulted in a lower score than Claude Opus 5.5 would achieve in practice." Google's Gemini 4 Carbon methodology says its results "use the private set and are sourced from the official Zapier public leaderboard." A separate story sets out which labs report which set.
Zapier's private-set figures change over time. The GitHub page says: "When we make changes that affect scores, we try to rerun all models on the benchmark and update scores when they change outside run to run variance." OpenAI's GPT-5.6 post gave GPT-5.6 Sol 18.1% and doesn't name a task set. Zapier's leaderboard now shows 28.8%, the figure Anthropic's Opus 5.5 post prints. Anthropic's Claude Opus 5 card gave Claude Opus 5 26.0% and the leaderboard now shows 26.9%. Its Claude Opus 4.8 card gave Opus 4.8 15.5%, its Opus 5 card gave 17.0%, and the leaderboard now shows 16.4%. The leaderboard says "Run-to-run variance is typically within 1%." Zapier's leaderboard now lists Claude Opus 5.5 at 42.5% and Claude Haiku 5.5 at 12.0% with "default fallbacks", where Anthropic's Opus 5.5 post gave 40.0% from runs without them. For Haiku 5.5 it notes "Initial results based on the launch version of Haiku 5.5." Zapier's leaderboard lists Claude Fable 5.1 twice: 22.4% alone, and 31.4% "with Opus 5 Fallback", where "Opus 5 handled ~40% of tasks (260 of 657)".
A third party runs it
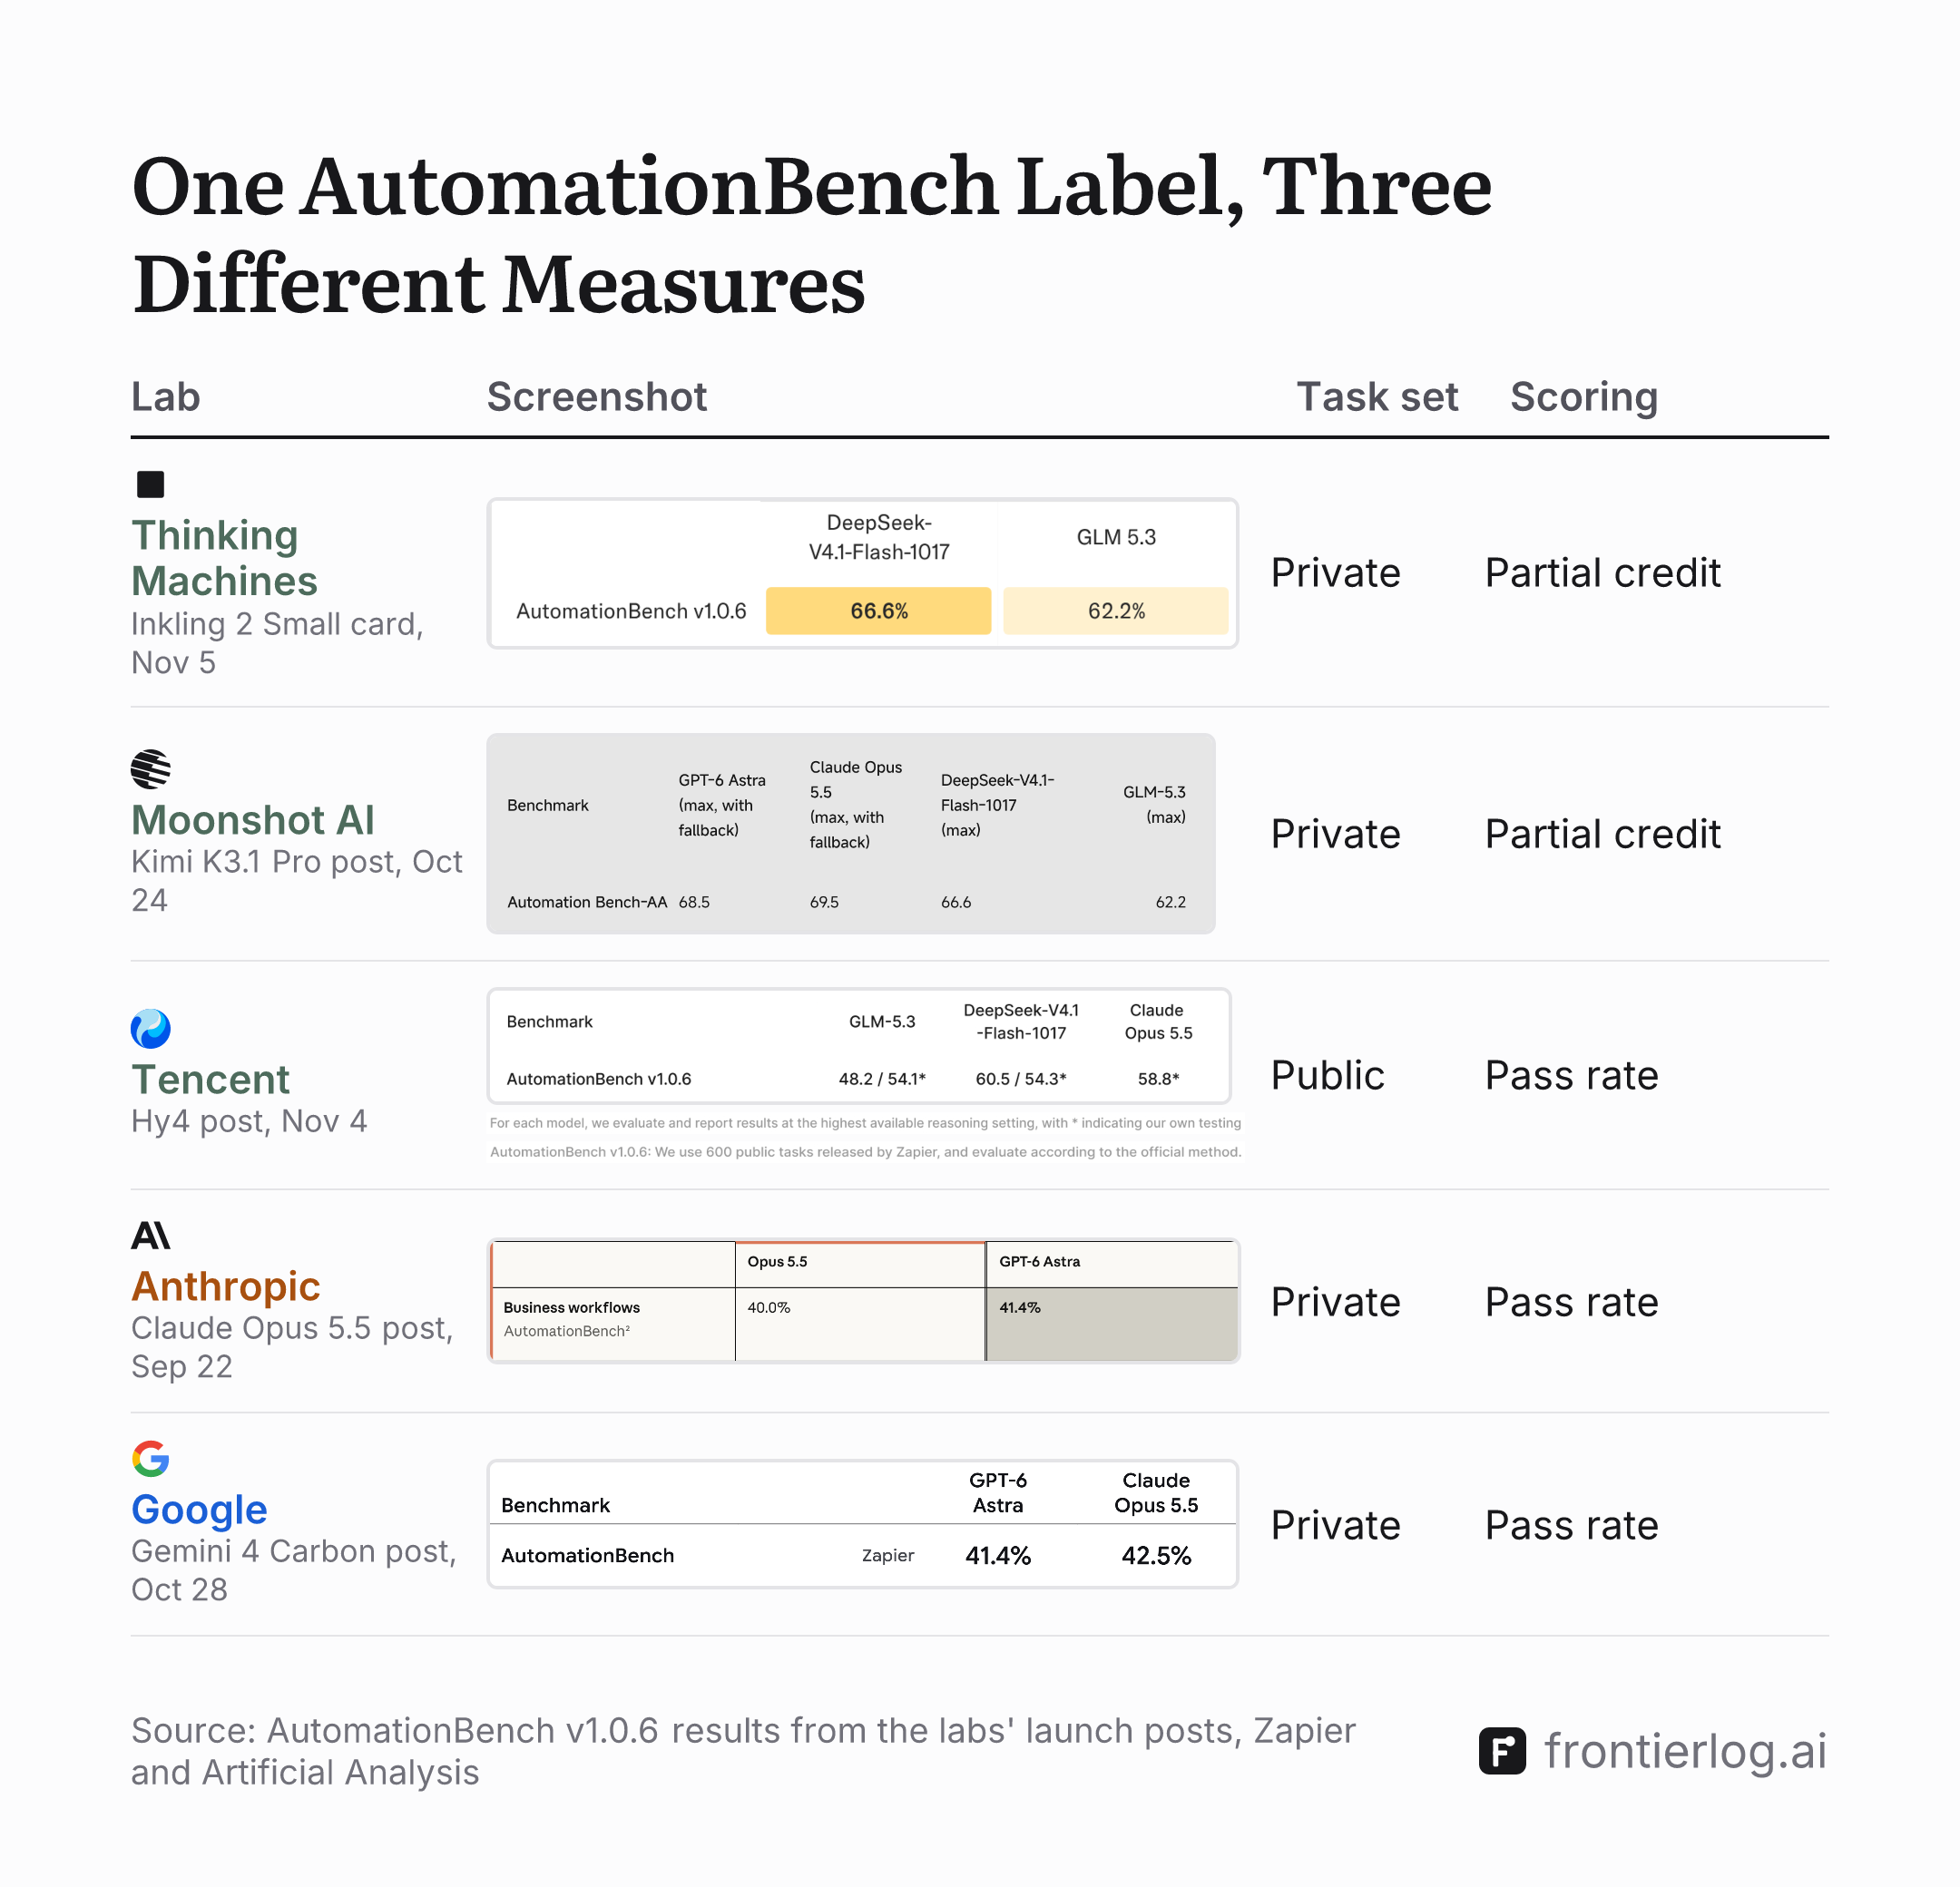
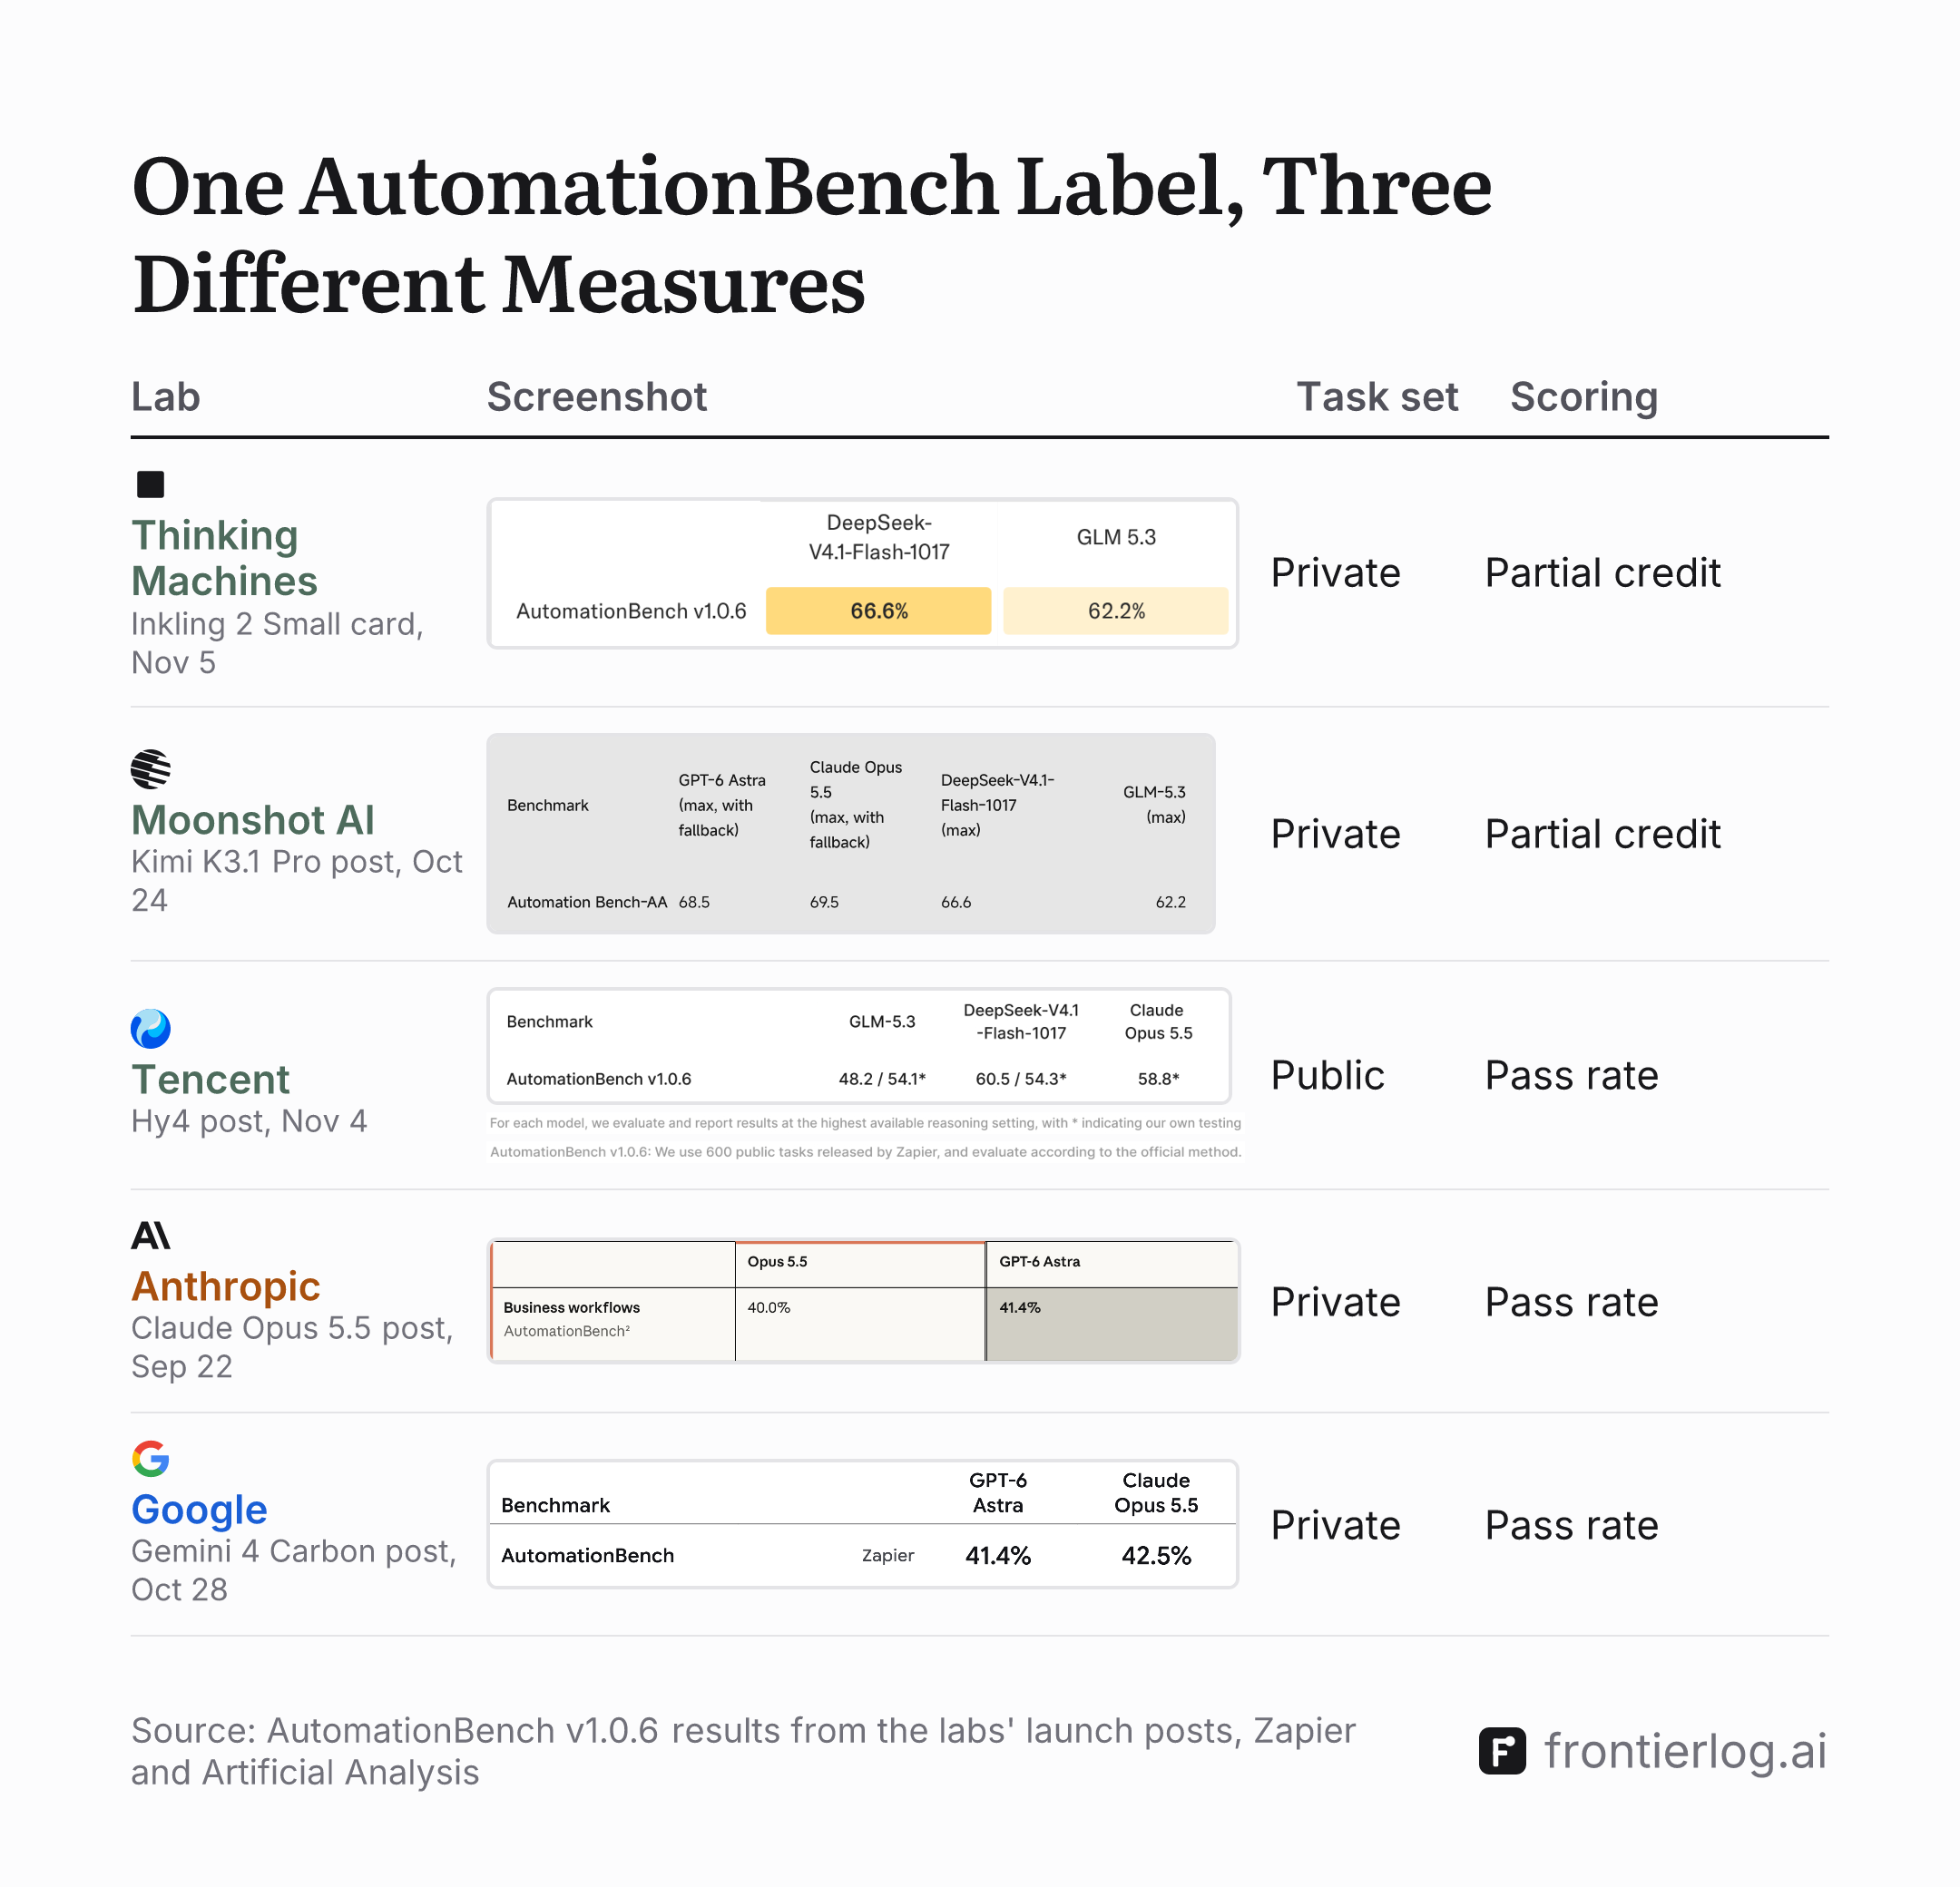
Thinking Machines takes its figures from outside runs, for its own model as well as its rivals. Its launch post says "To improve consistency, we rely on externally reported evaluations for both internal and external models when applicable," and lists AutomationBench-AA under Artificial Analysis. Its model card gives Kimi K3 58.3%, GLM-5.3 62.2% and DeepSeek-V4.1-Flash-1017 66.6%. Each is higher than the figure in the model's own lab's post. Artificial Analysis's methodology page says "We evaluate a private 657-task held-out split from AutomationBench dataset version 1.0.6." It also scores tasks differently from Zapier's pass rates. A task that breaks no guardrail "receives the percentage of objectives the model completed."
Thinking Machines' model card labels its row "AutomationBench v1.0.6". Moonshot AI's Kimi K3.1 Pro post prints the same figures for DeepSeek-V4.1-Flash-1017 and GLM-5.3, 66.6% and 62.2%, under "Automation Bench-AA". It says "AutomationBench-AA scores are cited from https://artificialanalysis.ai/". Tencent's Hy4 post uses the label "AutomationBench v1.0.6" for its own runs of the same two models, 54.3% and 54.1%, on "600 public tasks released by Zapier". Anthropic's Claude Opus 5.5 post and Google's Gemini 4 Carbon post also label their row AutomationBench, for Zapier's private-set pass rates. GPT-6 Astra and Claude Opus 5.5 score 41.4% and 42.5% in Google's table, and 68.5% and 69.5% in Artificial Analysis's figures.
Versions differ too
Most tables name AutomationBench v1.0.6: DeepSeek's Oct 17 table, Z.ai's, Tencent's, MiniMax's, Meituan's and Thinking Machines' card. Moonshot AI's Jul 16 post, DeepSeek's Aug 13 table and Alibaba's Qwen3.8-Max table don't name a version. Z.ai adds that it evaluates "incorporating the fix for the null-type handling issue introduced in PR #13." Its post gives GLM-5.3 48.2%, and DeepSeek's and MiniMax's tables print 48.8%. Zapier released v1.0.6 on Jul 31. Its changelog says the release "corrected additional task fairness (public and private)" and that "Private tasks were made a bit harder to compensate for bug fixes." On the public set, Zapier's own table moved Claude Opus 4.8 from 30.3% to 41.0%, GPT-5.6 Sol from 29.2% to 45.8% and Claude Fable 5 from 25.8% to 46.2% between v1.0.5 (Jul 16) and v1.0.6. The images draw only v1.0.6 figures, so they leave out Moonshot AI's 30.8% for Kimi K3, from its Jul 16 post.
Which labs use which
Across all benchmarks, the posts this story cites show each approach below. Every lab runs its own models too. The benchmark makers and third parties named are the ones each lab names in those posts or in its results on this site.
| Lab | Runs rivals | Prints others' figures | Benchmark maker runs | Third party runs |
|---|---|---|---|---|
| OpenAI | - | Yes | Zapier, ARC Prize Foundation | - |
| Anthropic | - | Yes | Zapier, Cognition, Scale AI, ARC Prize Foundation | - |
| Yes | Yes | Zapier, Cognition, Surge AI, ARC Prize Foundation, Datacurve, Proximal, Vals AI, Andon Labs | Artificial Analysis | |
| Meta | - | - | Scale AI, Datacurve | - |
| Moonshot AI | Yes | Yes | Datacurve, the FrontierSWE leaderboard | Artificial Analysis |
| Tencent | Yes | Yes | - | - |
| Meituan | Yes | Yes | - | - |
| MiniMax | - | Yes | - | Artificial Analysis |
| DeepSeek | - | Same figures | - | - |
| Alibaba | - | Yes | The FrontierSWE leaderboard | - |
| Z.ai | - | Same figures | Proximal | Artificial Analysis |
| Thinking Machines | - | - | Scale AI, Datacurve, Surge AI | Artificial Analysis, Vals AI |
| Mistral AI | - | - | - | Artificial Analysis, All Hands AI |
"Same figures" marks a table that prints figures identical to ones another party published, without naming their source. A dash means we found no such case in the posts this story cites.
AutomationBench, run by the model's own lab
| Model | Score | Sources |
|---|---|---|
| Kimi K3Kimi K3, run by Moonshot AI | 30.8% | Announcement'Full Benchmark Table', row 'Automation Bench' (Agentic), column 'Kimi K3 (max)' |
| GLM-5.3GLM-5.3, run by Z.ai | 48.2% | Announcement'Performance across comparison models' table, row 'AutomationBench v1.0.6', column 'GLM-5.3' |
| Muse Spark 1.3Muse Spark 1.3, run by Meta | 49.6% | Announcementscorecard (image), row 'AutomationBench', column 'Muse Spark 1.3 (max)' |
| DeepSeek-V4.1-Flash-1017DeepSeek-V4.1-Flash-1017, run by DeepSeek | 60.5% | Announcementbenchmark table image (first image), row 'Automation-Bench V1.0.6', column 'DeepSeek V4.1-Flash-1017' |
| MiniMax M3.1 FlashMiniMax-M3.1-Flash, run by MiniMax | 62.8% | Announcementbenchmark table image (first image), row 'Automation-Bench v1.0.6', column 'MiniMax M3.1 Flash' |
| Hy4Hy4, run by Tencent | 56.2% | Announcement'Appendix: benchmark results' table image, row 'AutomationBench v1.0.6', column 'Hy4' |
AutomationBench, Zapier's private-set leaderboard
AutomationBench, Zapier's public-set table, in other labs' tables
| Model | Value | Sources |
|---|---|---|
| GLM-5.3Claude Opus 4.8, Zapier's public-set figure, in Z.ai's table | 41.0% | Announcementbenchmark table, row 'AutomationBench v1.0.6', column 'Claude Opus 4.8' |
| DeepSeek-V4.1-Flash-1017Kimi K3, Zapier's public-set figure, in DeepSeek's table | 46.7% | Announcementbenchmark table (image), row 'Automation-Bench V1.0.6', column 'Kimi-K3' |
| DeepSeek-V4.1-Flash-1017GPT-5.6 Sol, Zapier's public-set figure, in DeepSeek's table | 45.8% | Announcementbenchmark table (image), row 'Automation-Bench V1.0.6', column 'GPT-5.6-Sol' |
| DeepSeek-V4.1-Flash-1017Claude Opus 5, Zapier's public-set figure, in DeepSeek's table | 50.3% | Announcementbenchmark table (image), row 'Automation-Bench V1.0.6', column 'Opus-5' |
AutomationBench, run by a rival lab
AutomationBench, run by Artificial Analysis
AutomationBench, labelled 'Automation Bench-AA' in Moonshot AI's Kimi K3.1 Pro post
| Model | Value | Sources |
|---|---|---|
| Kimi K3.1 ProDeepSeek-V4.1-Flash-1017, labelled Automation Bench-AA | 66.6% | Announcement'Benchmarks' table, row 'Automation Bench-AA', column 'DeepSeek-V4.1-Flash-1017 (max)' |
| Kimi K3.1 ProGLM-5.3, labelled Automation Bench-AA | 62.2% | Announcement'Benchmarks' table, row 'Automation Bench-AA', column 'GLM-5.3 (max)' |
Sources
- DeepSeek, Aug 13, 2026DeepSeek-V4-Pro GA Release
- DeepSeek, Oct 17, 2026DeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made Real
- artificialanalysis.aiartificialanalysis.ai/evaluations/automationbench-aa
- artificialanalysis.aiartificialanalysis.ai/methodology/intelligence-benchmarking
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- github.comgithub.com/zapier/AutomationBench
- Tencent, Nov 4, 2026Introducing Hy4
- Tencent, Aug 28, 2026Introducing Hy4 preview
- Meituan, Nov 1, 2026LongCat-2.5: Native Multimodality for Agentic Tasks
- OpenAI, Jul 9, 2026GPT-5.6: Frontier intelligence that scales with your ambition
- OpenAI, Sep 22, 2026Introducing GPT-6 Sol and Luna
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- Meta, Sep 2, 2026Introducing Muse Spark 1.3
- Google, Sep 30, 2026Gemini 4 Argon Model evaluation: approach, methodology & results
- Google, Oct 28, 2026Gemini 4 Carbon Model evaluation: approach, methodology & results
- Thinking Machines, Nov 5, 2026Inkling 2 Small Model Card
- Thinking Machines, Nov 5, 2026Introducing Inkling 2 Small
- Anthropic, May 28, 2026Claude Opus 4.8 System Card
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- Anthropic, Sep 22, 2026Claude Opus 5.5 System Card
- Anthropic, Jul 24, 2026Claude Opus 5 System Card
- Anthropic, Sep 28, 2026Claude Sonnet 5.5 System Card
- Moonshot AI, Jul 16, 2026Kimi K3: Open Frontier Intelligence
- Moonshot AI, Oct 24, 2026Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence
- MiniMax, Oct 19, 2026MiniMax M3.1 Flash: Redefining Agent Performance and Cost
- Z.ai, Aug 14, 2026GLM-5.3: Frontier Coding with Emergent Cyber Capabilities
- zapier.comzapier.com/benchmarks