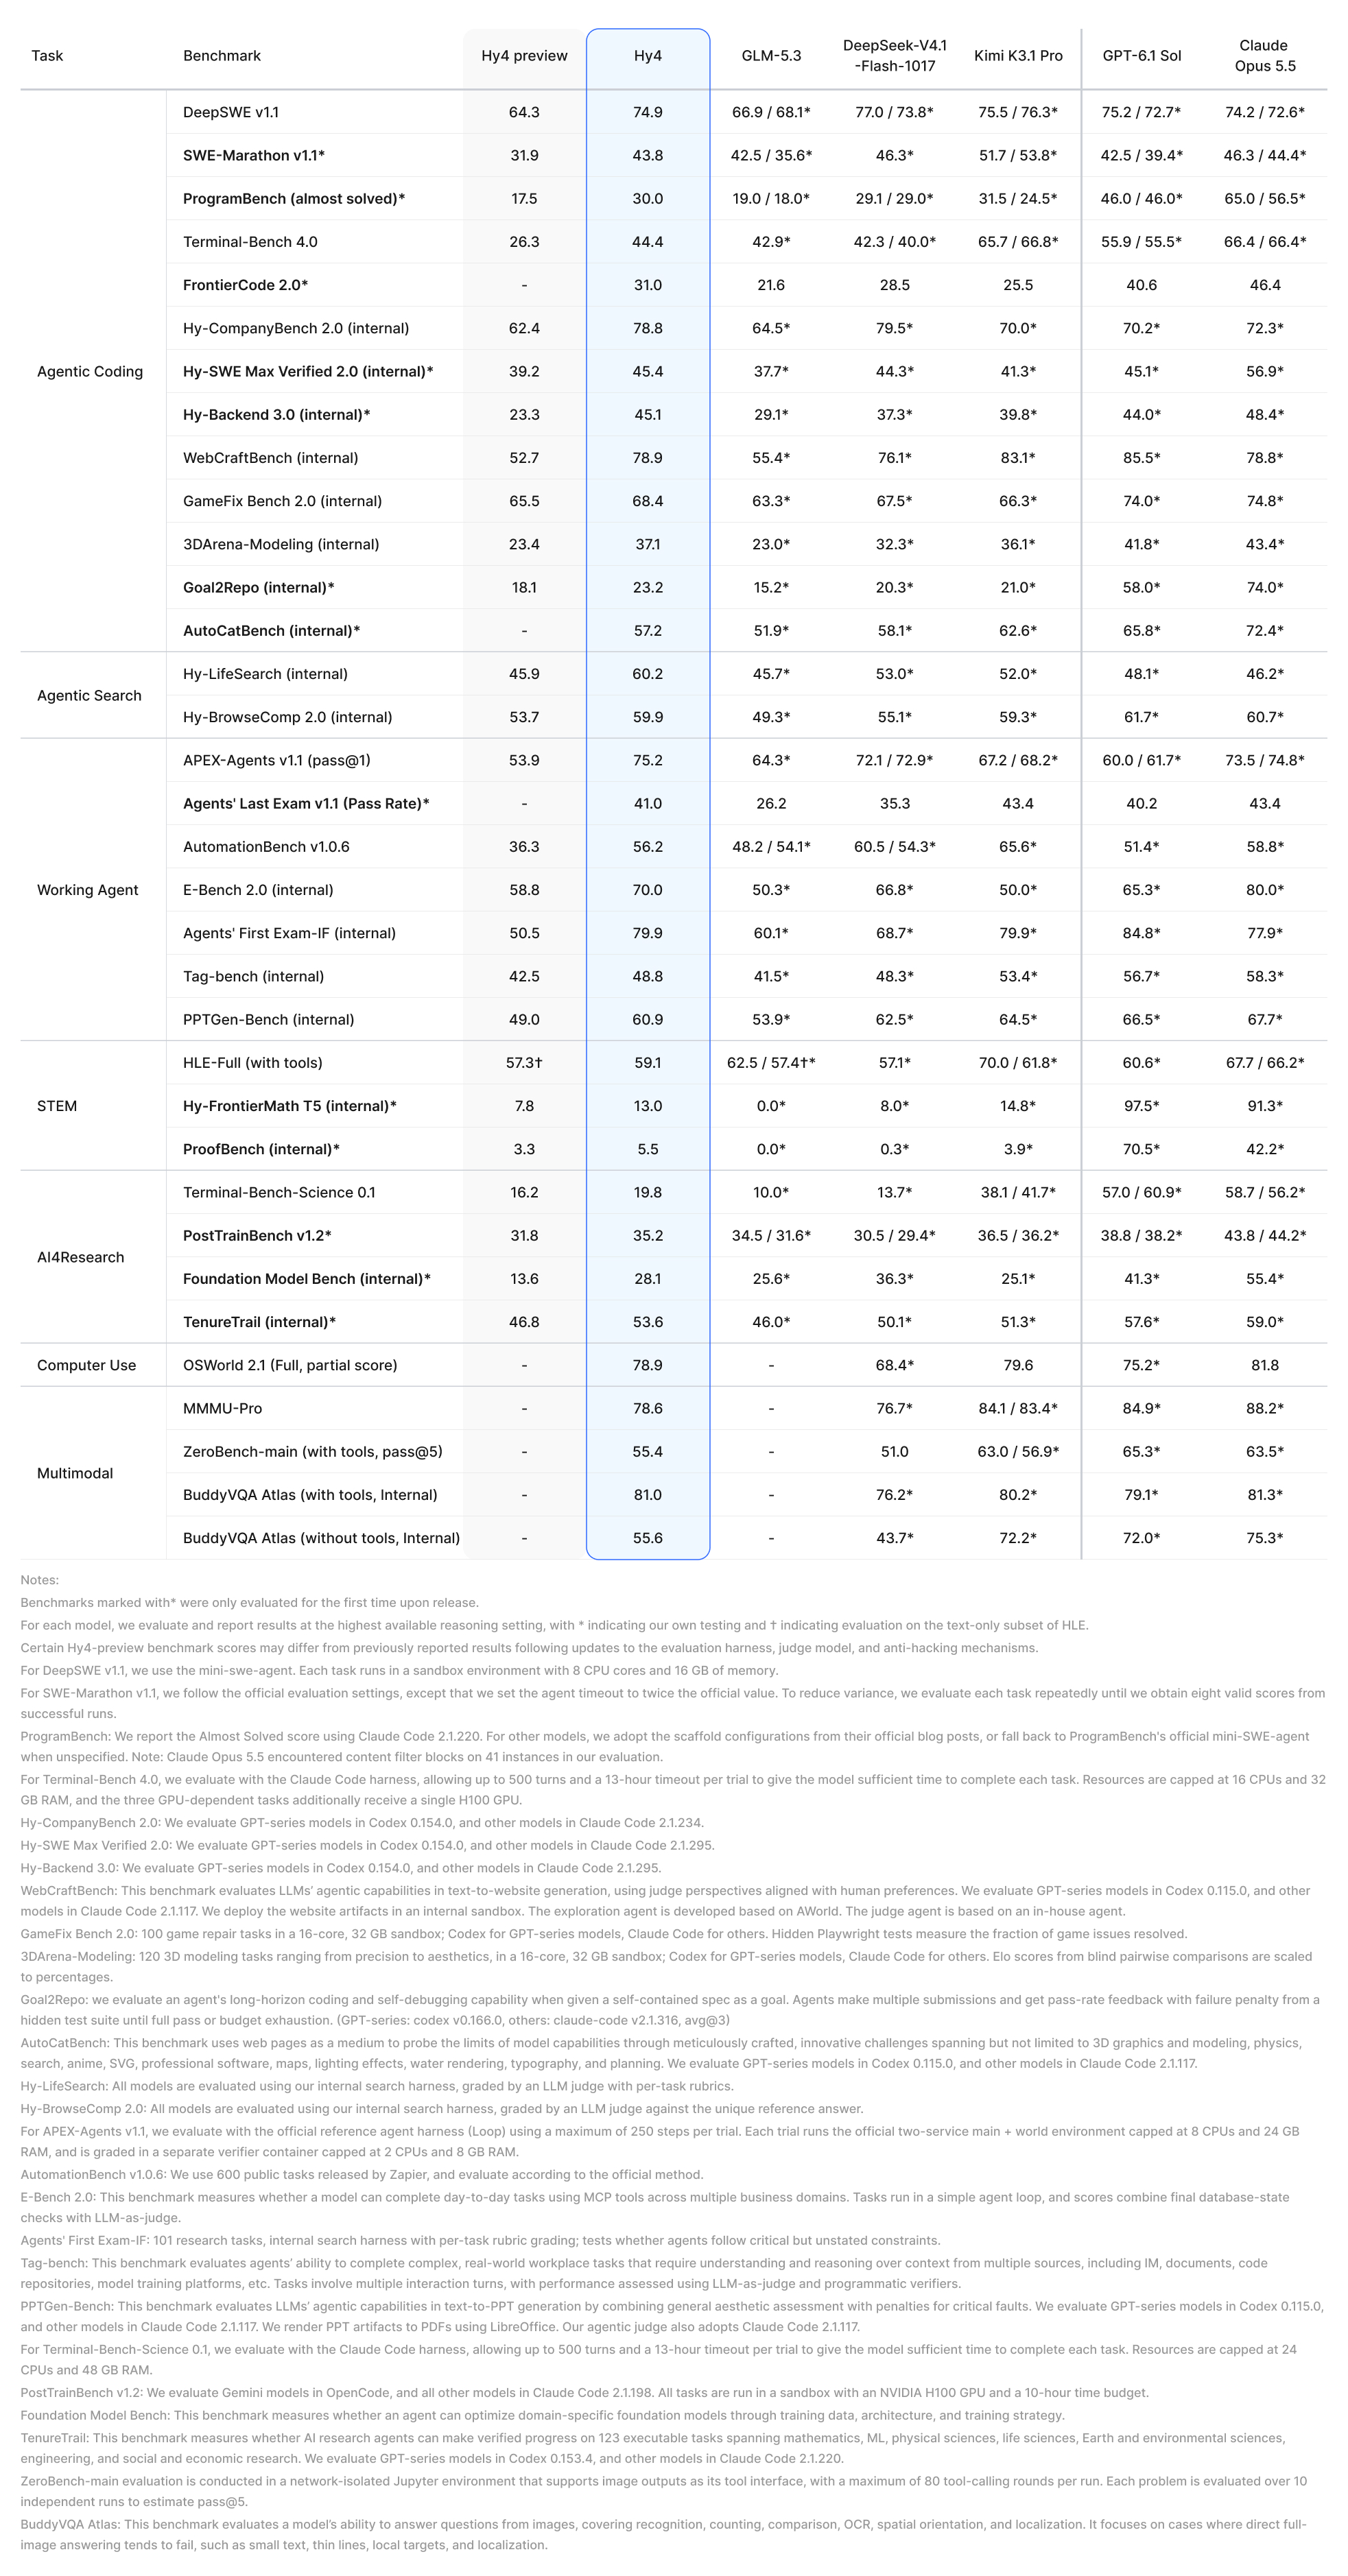
55.4%Checked A person checked this number against its source on 9 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
re-evaluated at Hy4 launch; text-only subset · reported later, in Introducing Hy4
57.3%Checked A person checked this number against its source on 8 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
SWE-bench ProSet not stated · SWE-agent scaffold; highest reasoning setting
65.7%Checked A person checked this number against its source on 9 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
92.3%Checked A person checked this number against its source on 9 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
Terminal-Bench 4.0re-evaluated at Hy4 launch; Claude Code harness; up to 500 turns and a 13h timeout per trial · reported later, in Introducing Hy4
26.3%Checked A person checked this number against its source on 8 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
16.2%Checked A person checked this number against its source on 8 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
36.3%Checked A person checked this number against its source on 8 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
32.1%Checked A person checked this number against its source on 8 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
64.3%Corroborated The same number is printed in 2 other lab documents: 12
Terminal-Bench 2.1Claude Code harness; up to 500 turns and a 12h timeout per trial; highest reasoning setting
85.4%Corroborated The same number is printed in 1 other lab document: 1
MCP AtlasPublic set (500 tasks) · 500-task public set; 100-tool-call budget; Gemini 3.1 Pro Preview judge; highest reasoning setting
83.7%Checked A person checked this number against its source on 9 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
CyberGymharness not stated; highest reasoning setting
78.4%Checked A person checked this number against its source on 9 Nov 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.
Agents' Last Exam v1CLI subset, pass rate · 105-task CLI subset; Claude Code harness; up to 12h per task; highest reasoning setting
22.8%Corroborated The same number is printed in 1 other lab document: 1