FrontierCode 2.0's Top Open Model Depends on the Harness
Mistral Large 4 leads open models on FrontierCode 2.0 in Mistral's Vibe harness but trails DeepSeek and GLM-5.3 in Artificial Analysis's Stirrup harness.
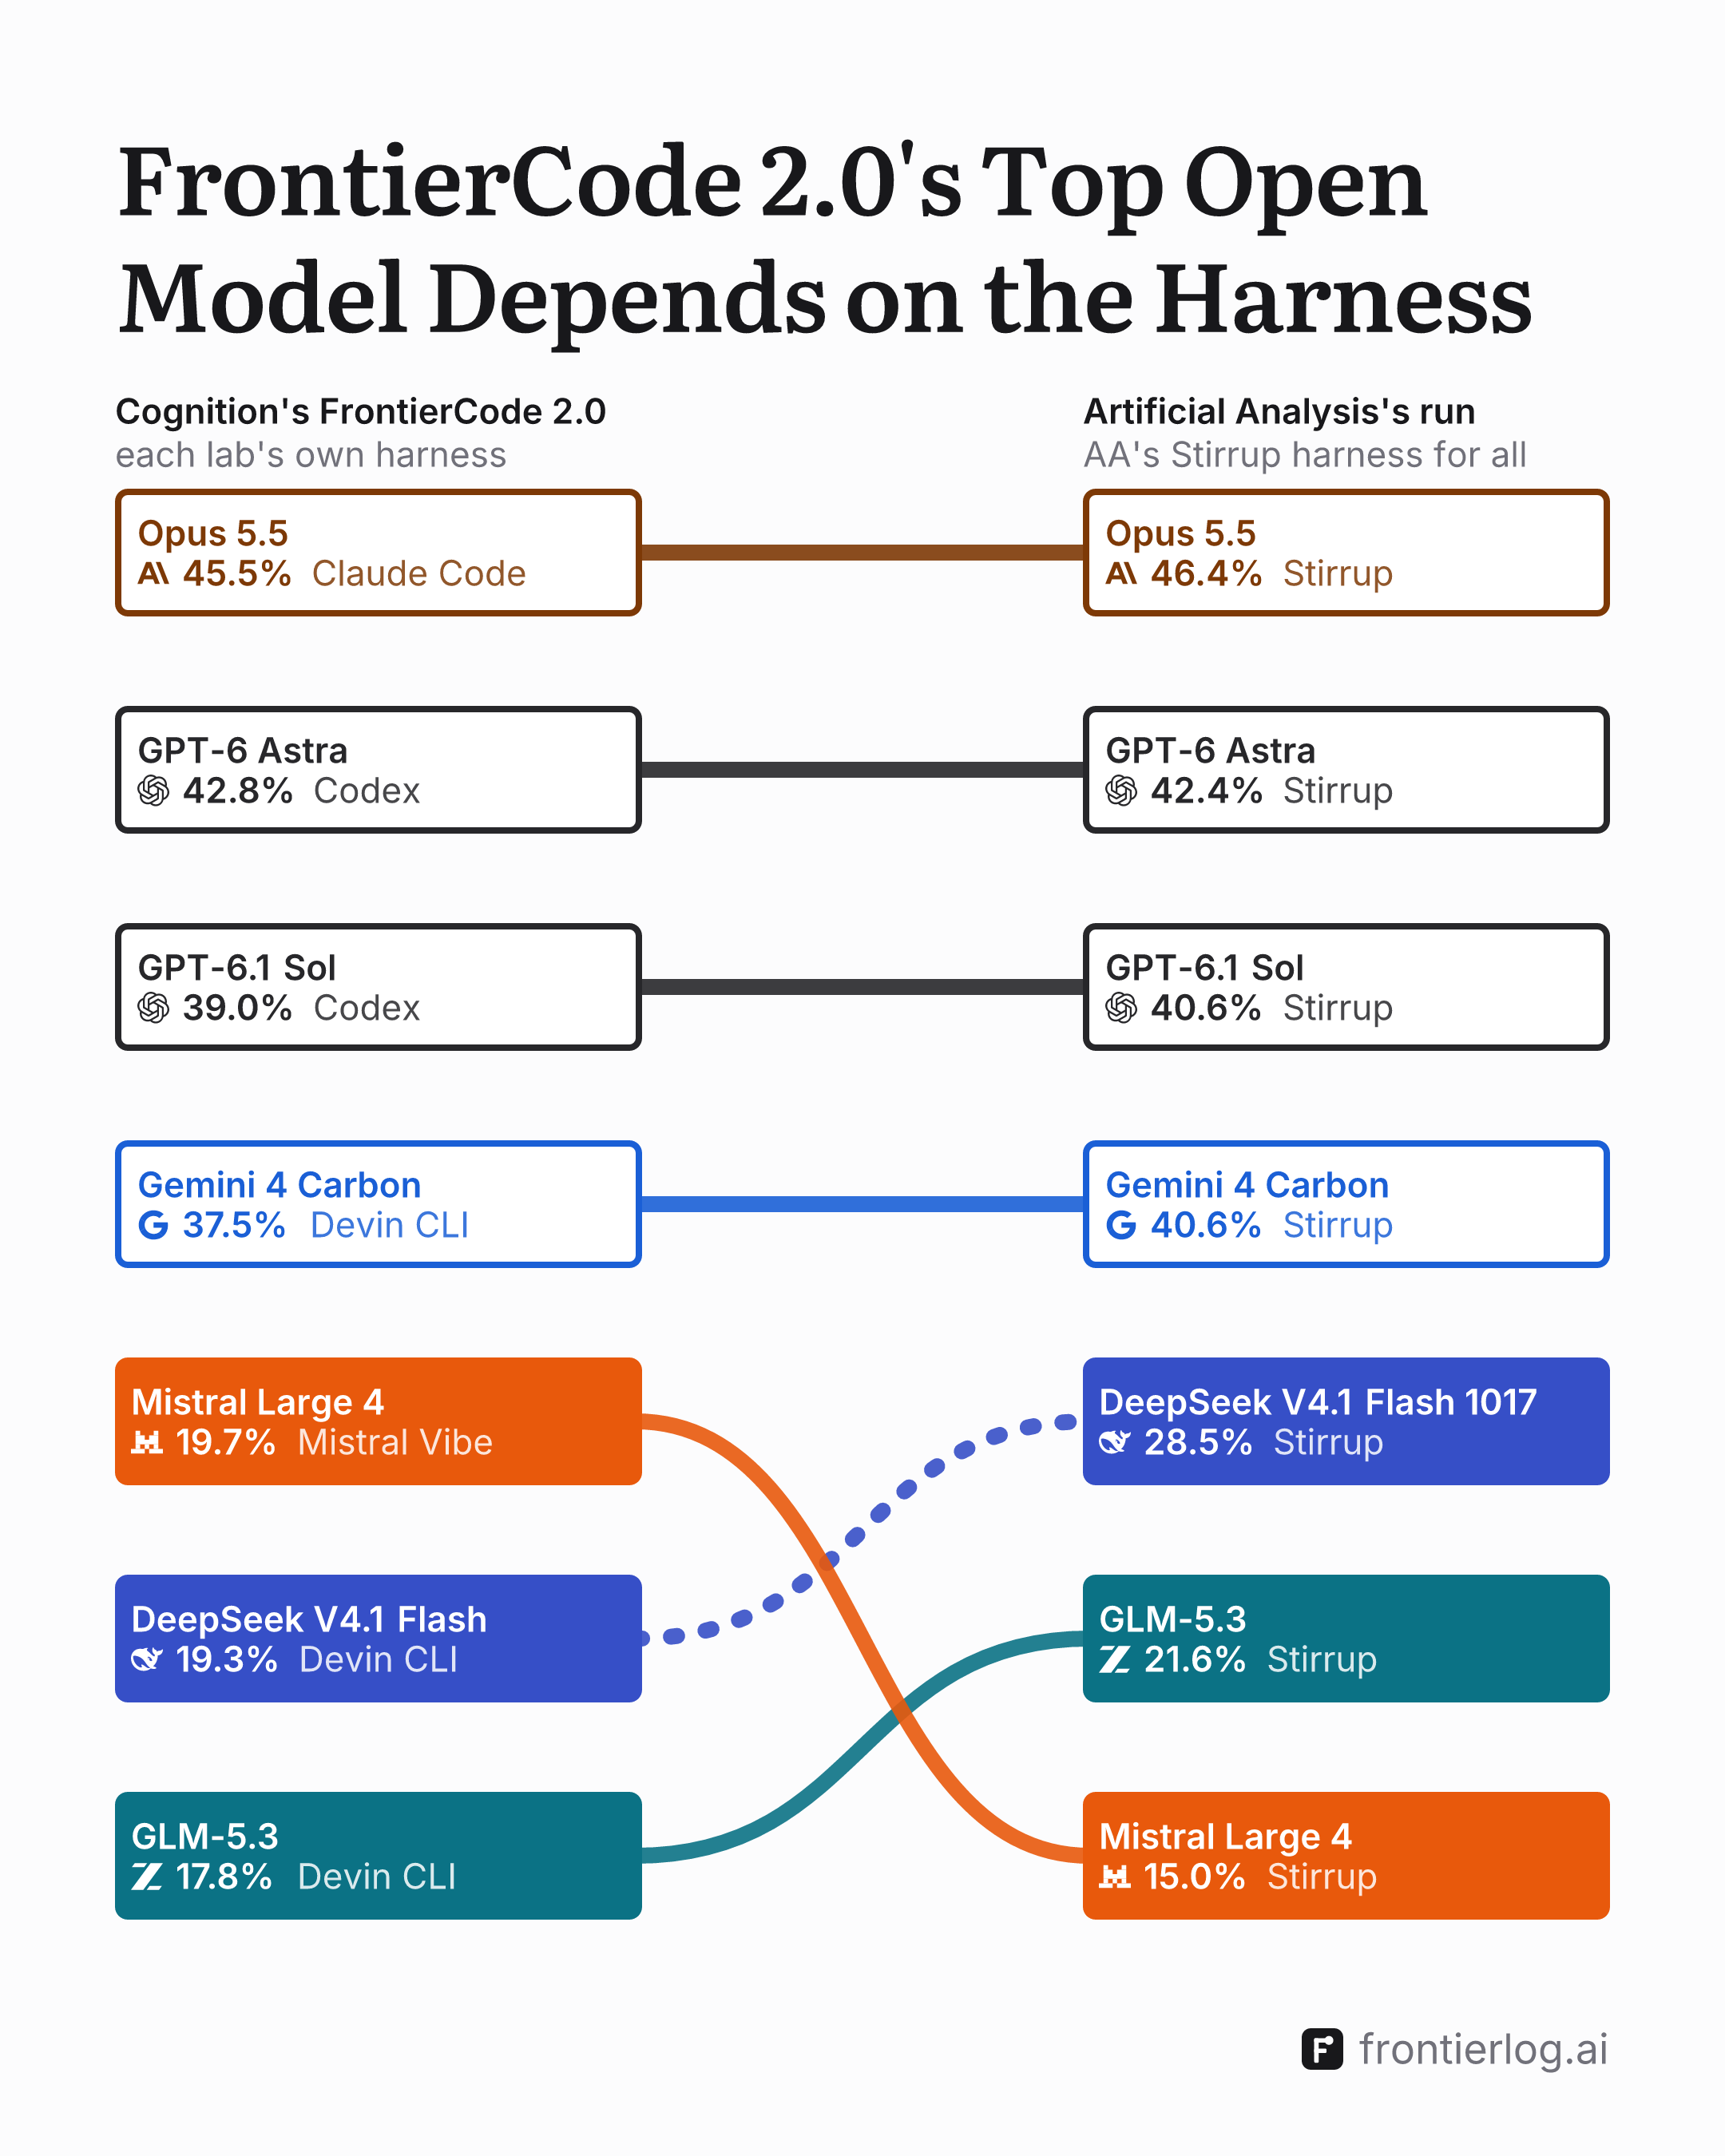
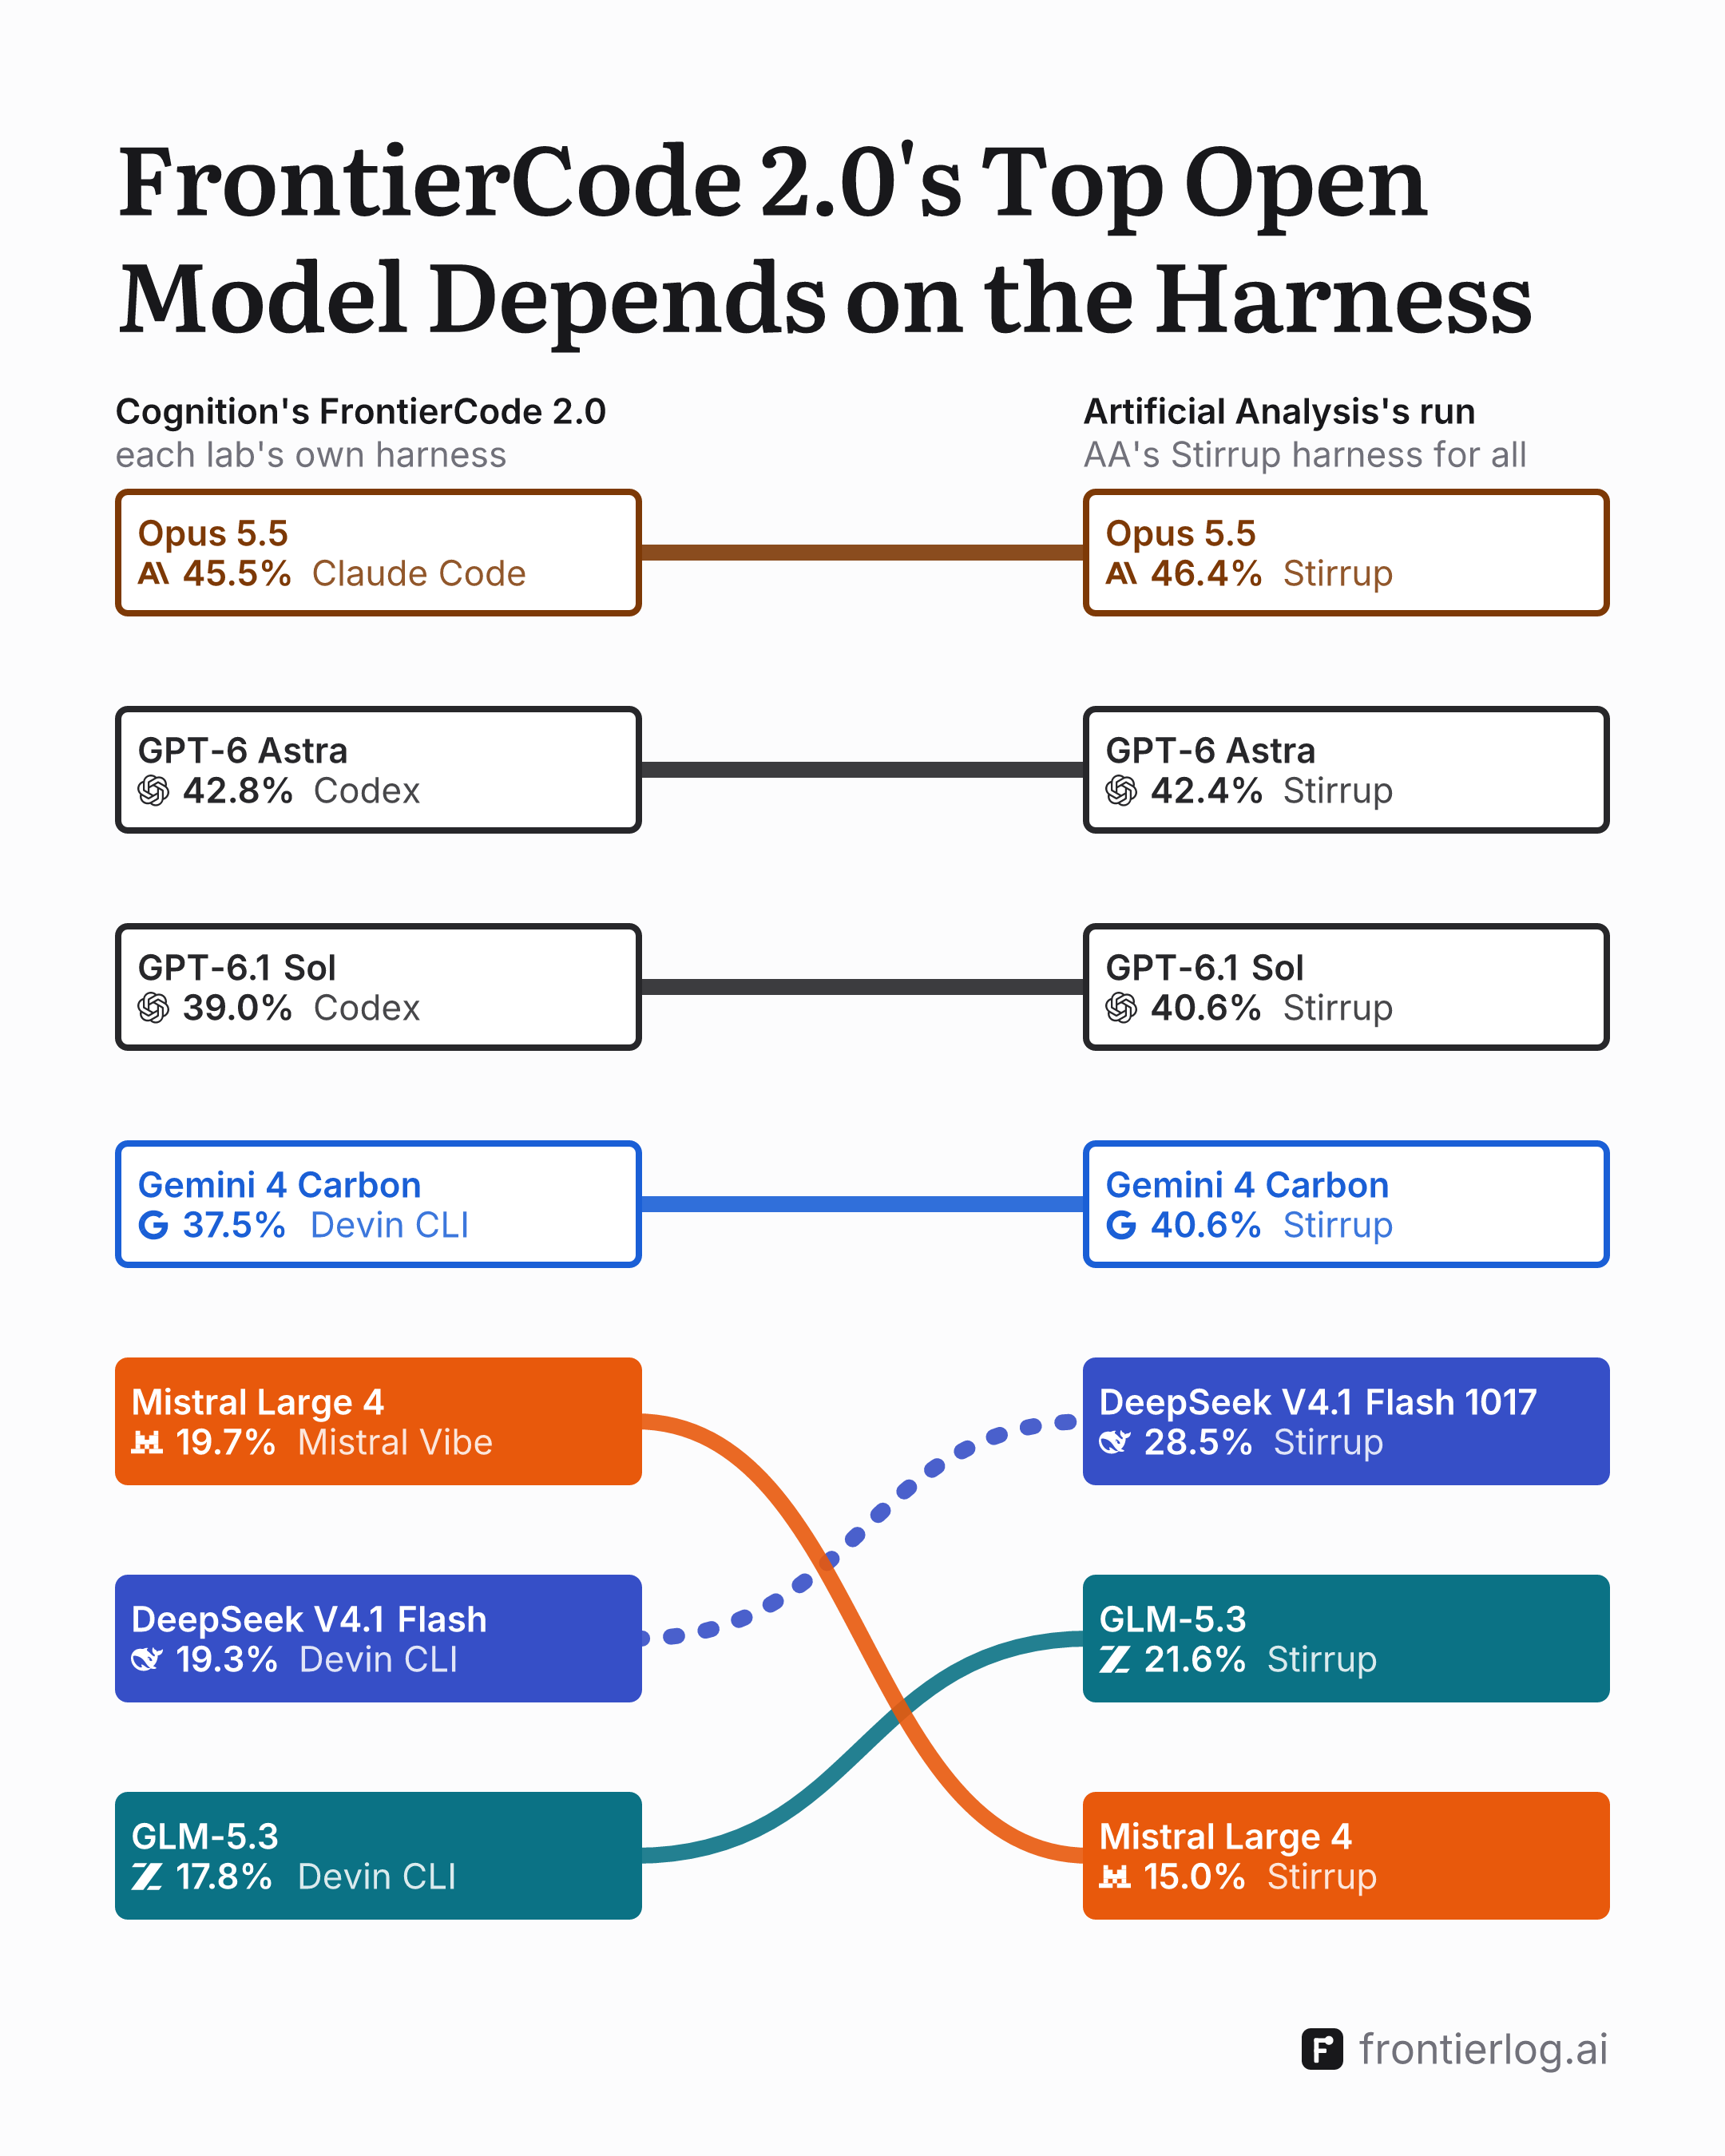
Mistral released the weights of Mistral Large 4 on Oct 29 and said that on Cognition's FrontierCode 2.0 benchmark, which grades whether a repository maintainer would merge an agent's change, the model "leads with a score of 19.7%" (Mistral's post). On Cognition's leaderboard, that score comes from Mistral's own agent harness, Mistral Vibe, while the other open models there ran in Cognition's Devin CLI. Artificial Analysis, which runs FrontierCode 2.0 in its own harness for every model, prints 15.0% for Large 4, behind DeepSeek V4.1 Flash 1017 at 28.5% and GLM-5.3 at 21.6%.
The harness changed two days before the weights
Cognition added Mistral Large 4 (Preview) to the leaderboard on Oct 13. On Oct 27, the day its results moved to FrontierCode 2.0, a 132-task suite, its changelog says it "Updated Mistral Large 4 to the Mistral Vibe harness (low, medium, and high reasoning), replacing the Devin CLI preview results." The same entry notes that "Points are shaped by evaluation harness." The leaderboard no longer shows the Devin CLI results.
Each lab's harness on Cognition's board
Cognition runs closed models in their labs' own harnesses: Claude Opus 5.5 in Claude Code at 45.5%, and GPT-6 Astra at 42.8% and GPT-6.1 Sol at 39.0% in Codex. It runs Gemini 4 Carbon in Devin CLI, at 37.5% on high effort. Among the open models, Large 4 at 19.7% leads DeepSeek V4.1 Flash at 19.3% and GLM-5.3 at 17.8%, both in Devin CLI.
One harness for every model
Artificial Analysis says it runs "every task three times with our Stirrup agent harness, capped at 500 turns", with GPT-6 Luna (medium) as the judge (its FrontierCode 2.0 page). Stirrup is its open-source harness. In that run Opus 5.5 scores 46.4% and GPT-6 Astra 42.4%, and GPT-6.1 Sol and Gemini 4 Carbon both print 40.6%, with Sol listed first. Artificial Analysis ran the Oct 17 update of DeepSeek's model, V4.1 Flash 1017, not the release on Cognition's board.
This story quotes Cognition's and Artificial Analysis's published figures directly, an exception to Frontier Log's rule of recording only the labs' own reports, and makes no claim about which ranking is right. Each model is shown at the same reasoning effort in both columns. Earlier stories in this series cover Terminal-Bench 4.0 by who ran it, Gemini 4 Carbon's launch table and harness versions.
FrontierCode 2.0, Cognition's leaderboard
FrontierCode 2.0, run by Artificial Analysis
| Model | Value | Sources |
|---|---|---|
| GLM-5.3GLM-5.3, max, Stirrup | 21.6% | Announcement'FrontierCode 2.0: Score' chart, bar 'GLM-5.3 (max)' |
| GPT-6 AstraGPT-6 Astra, max, Stirrup | 42.4% | Announcement'FrontierCode 2.0: Score' chart, bar 'GPT-6 Astra (max)' |
| Claude Opus 5.5Opus 5.5, max, Stirrup | 46.4% | Announcement'FrontierCode 2.0: Score' chart, bar 'Claude Opus 5.5 (max with fallback)' |
| GPT-6.1 SolGPT-6.1 Sol, max, Stirrup | 40.6% | Announcement'FrontierCode 2.0: Score' chart, bar 'GPT-6.1 Sol (max)' |
| Mistral Large 4Mistral Large 4, high, Stirrup | 15.0% | Announcement'FrontierCode 2.0: Score' chart, bar 'Mistral Large 4 (high)' |
| DeepSeek-V4.1-Flash-1017DeepSeek V4.1 Flash 1017, max, Stirrup | 28.5% | Announcement'FrontierCode 2.0: Score' chart, bar 'DeepSeek V4.1 Flash 1017 (max)' |
| Gemini 4 CarbonGemini 4 Carbon, high, Stirrup | 40.6% | Announcement'FrontierCode 2.0: Score' chart, bar 'Gemini 4 Carbon (high)' |
Sources
- Mistral AI, blog postmistral.ai/news/mistral-large-4-oss
- Cognition, leaderboardcognition.com/frontiercode
- Artificial Analysis, evaluation pageartificialanalysis.ai/evaluations/frontiercode-2-0
- Artificial Analysis, GitHub repositorygithub.com/ArtificialAnalysis/Stirrup
Related
Events
Models
- Mistral Large 4
- DeepSeek-V4.1-Flash
- DeepSeek-V4.1-Flash-1017
- GLM-5.3
- Claude Opus 5.5
- GPT-6 Astra
- GPT-6.1 Sol
- Gemini 4 Carbon
Stories
- Who Leads Terminal-Bench 4.0 Depends on Who Ran It
- Gemini 4 Carbon's Table Moves Rivals' Scores
- Does the Harness Version Change a Model's Score?