Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
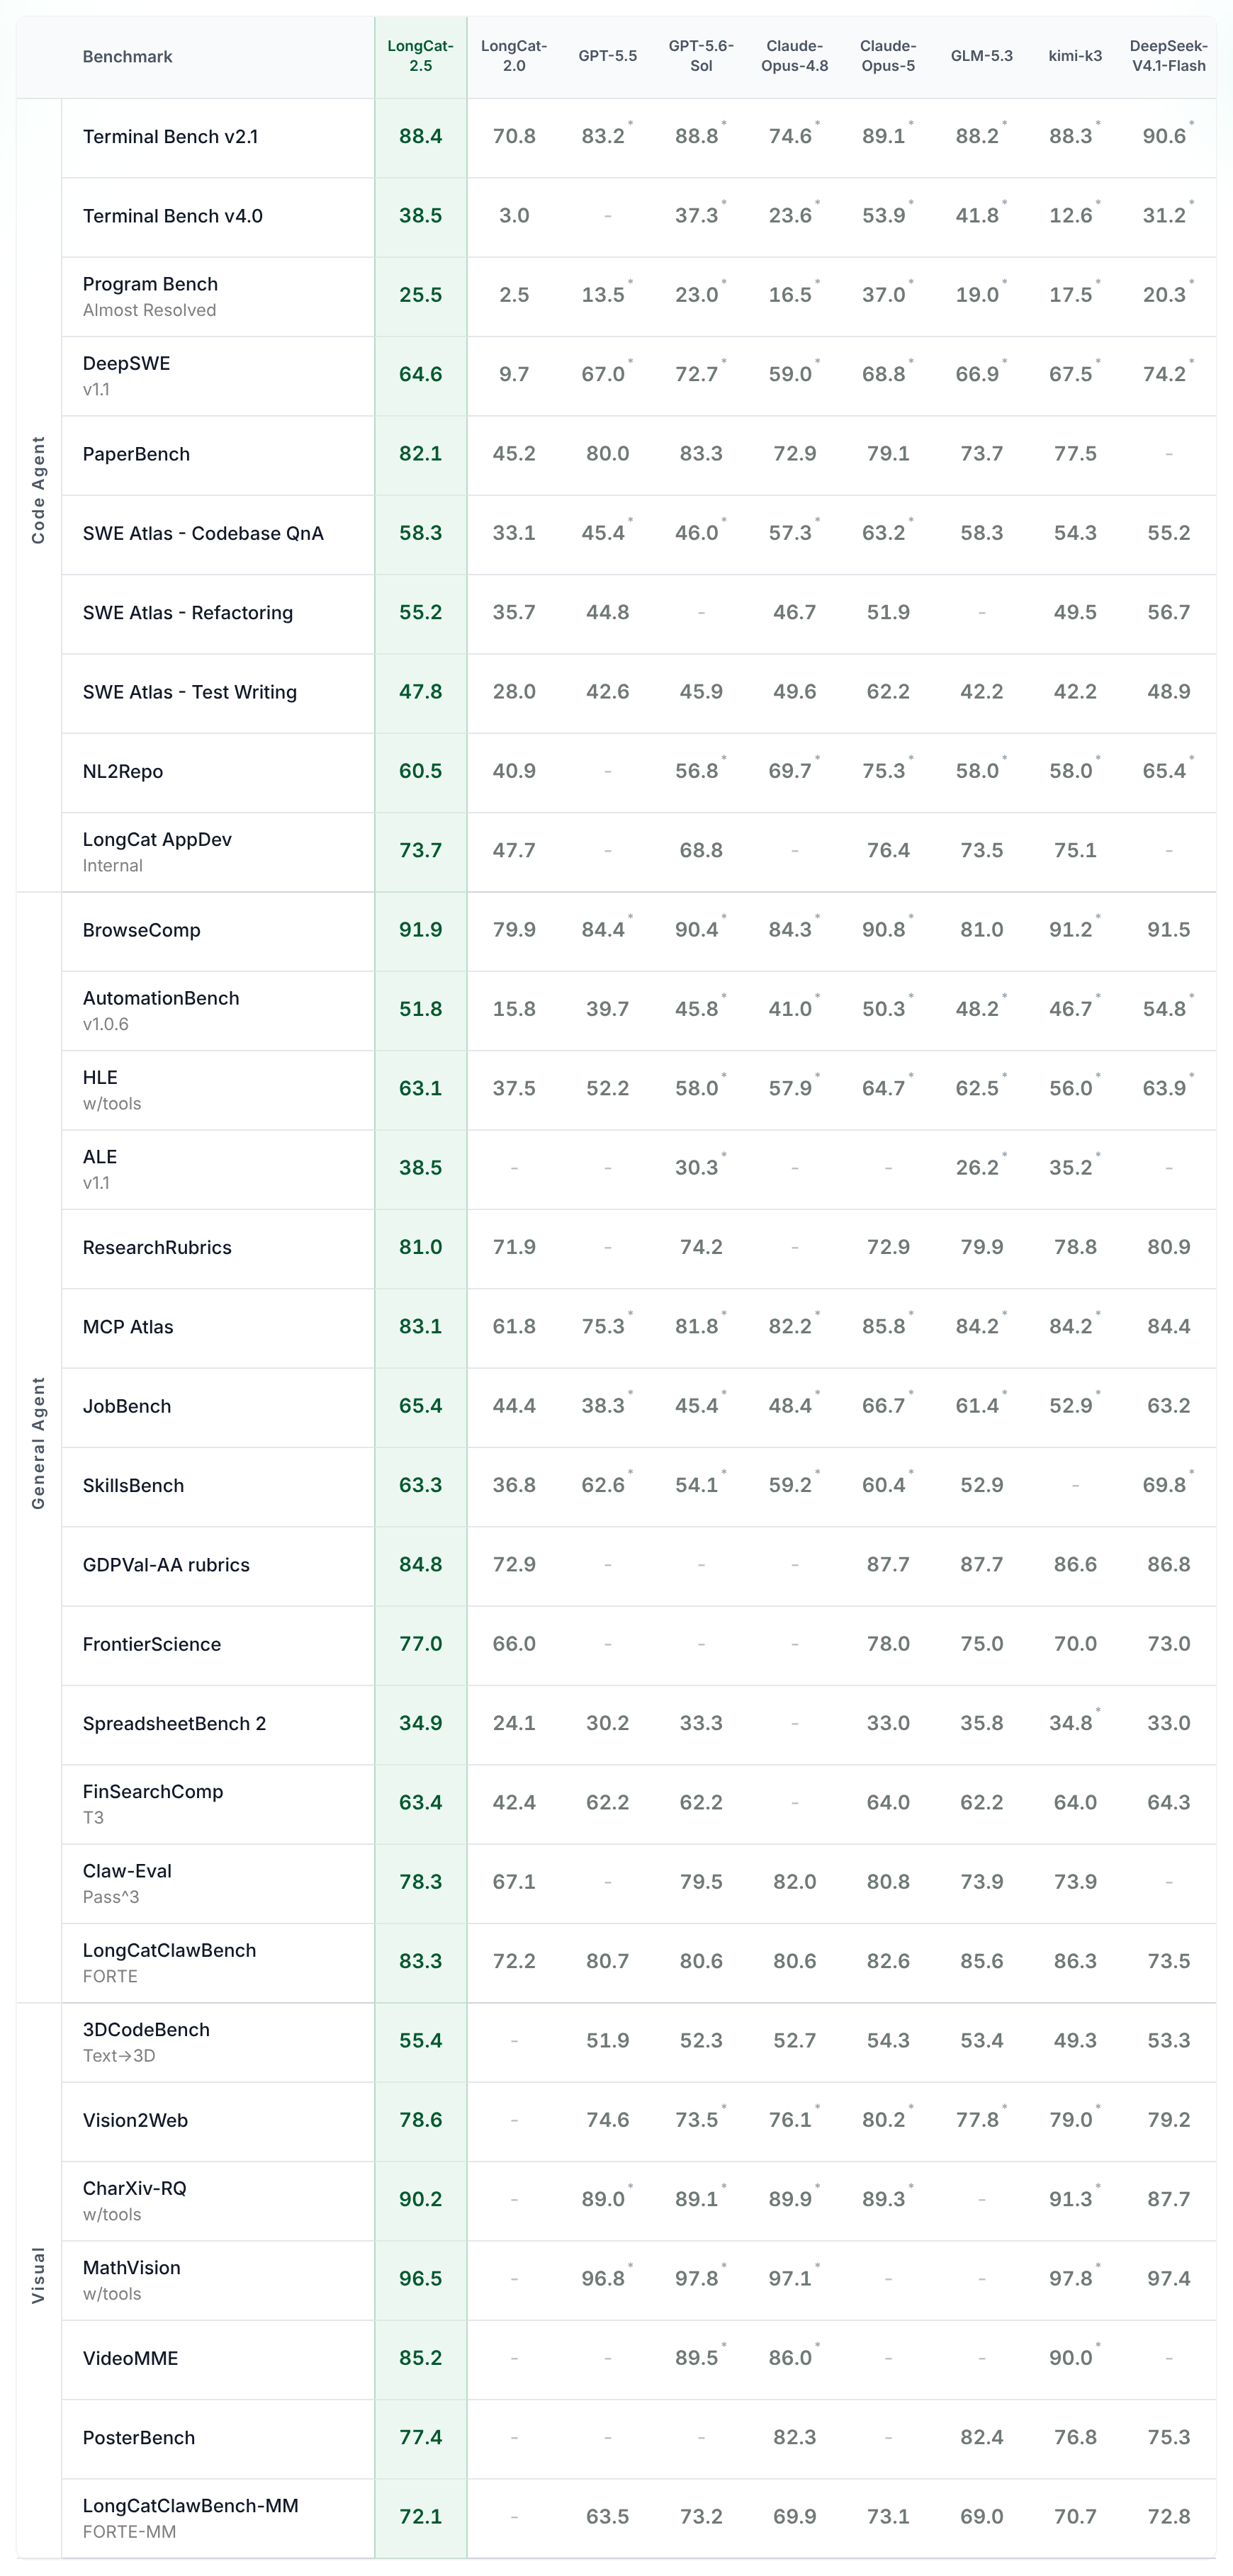
BrowseCompcustom harness with context discarding at 256K; search and browse tools only; up to 1,024 rounds
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
AutomationBenchpublic v1.0.6 set, all 600 tasks; official evaluation code
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
DeepSWE v1.1mini-swe-agent harness; 1M context; average of 3 runs
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.
Agents' Last Exam v1.1Measure not stated · thinking on; harness and task count not stated
Checked A person checked this number against its source on 2 Nov 2026. This confirms the number matches what the lab published, not that the score was reproduced.