Inferring GPT-5.6 Sol's Unstated Setup on OSWorld 2.0
OpenAI doesn't name the OSWorld 2.0 release or the scoring behind GPT-5.6 Sol's 62.6%. Its own comparison with Claude Opus 4.8 points to both.
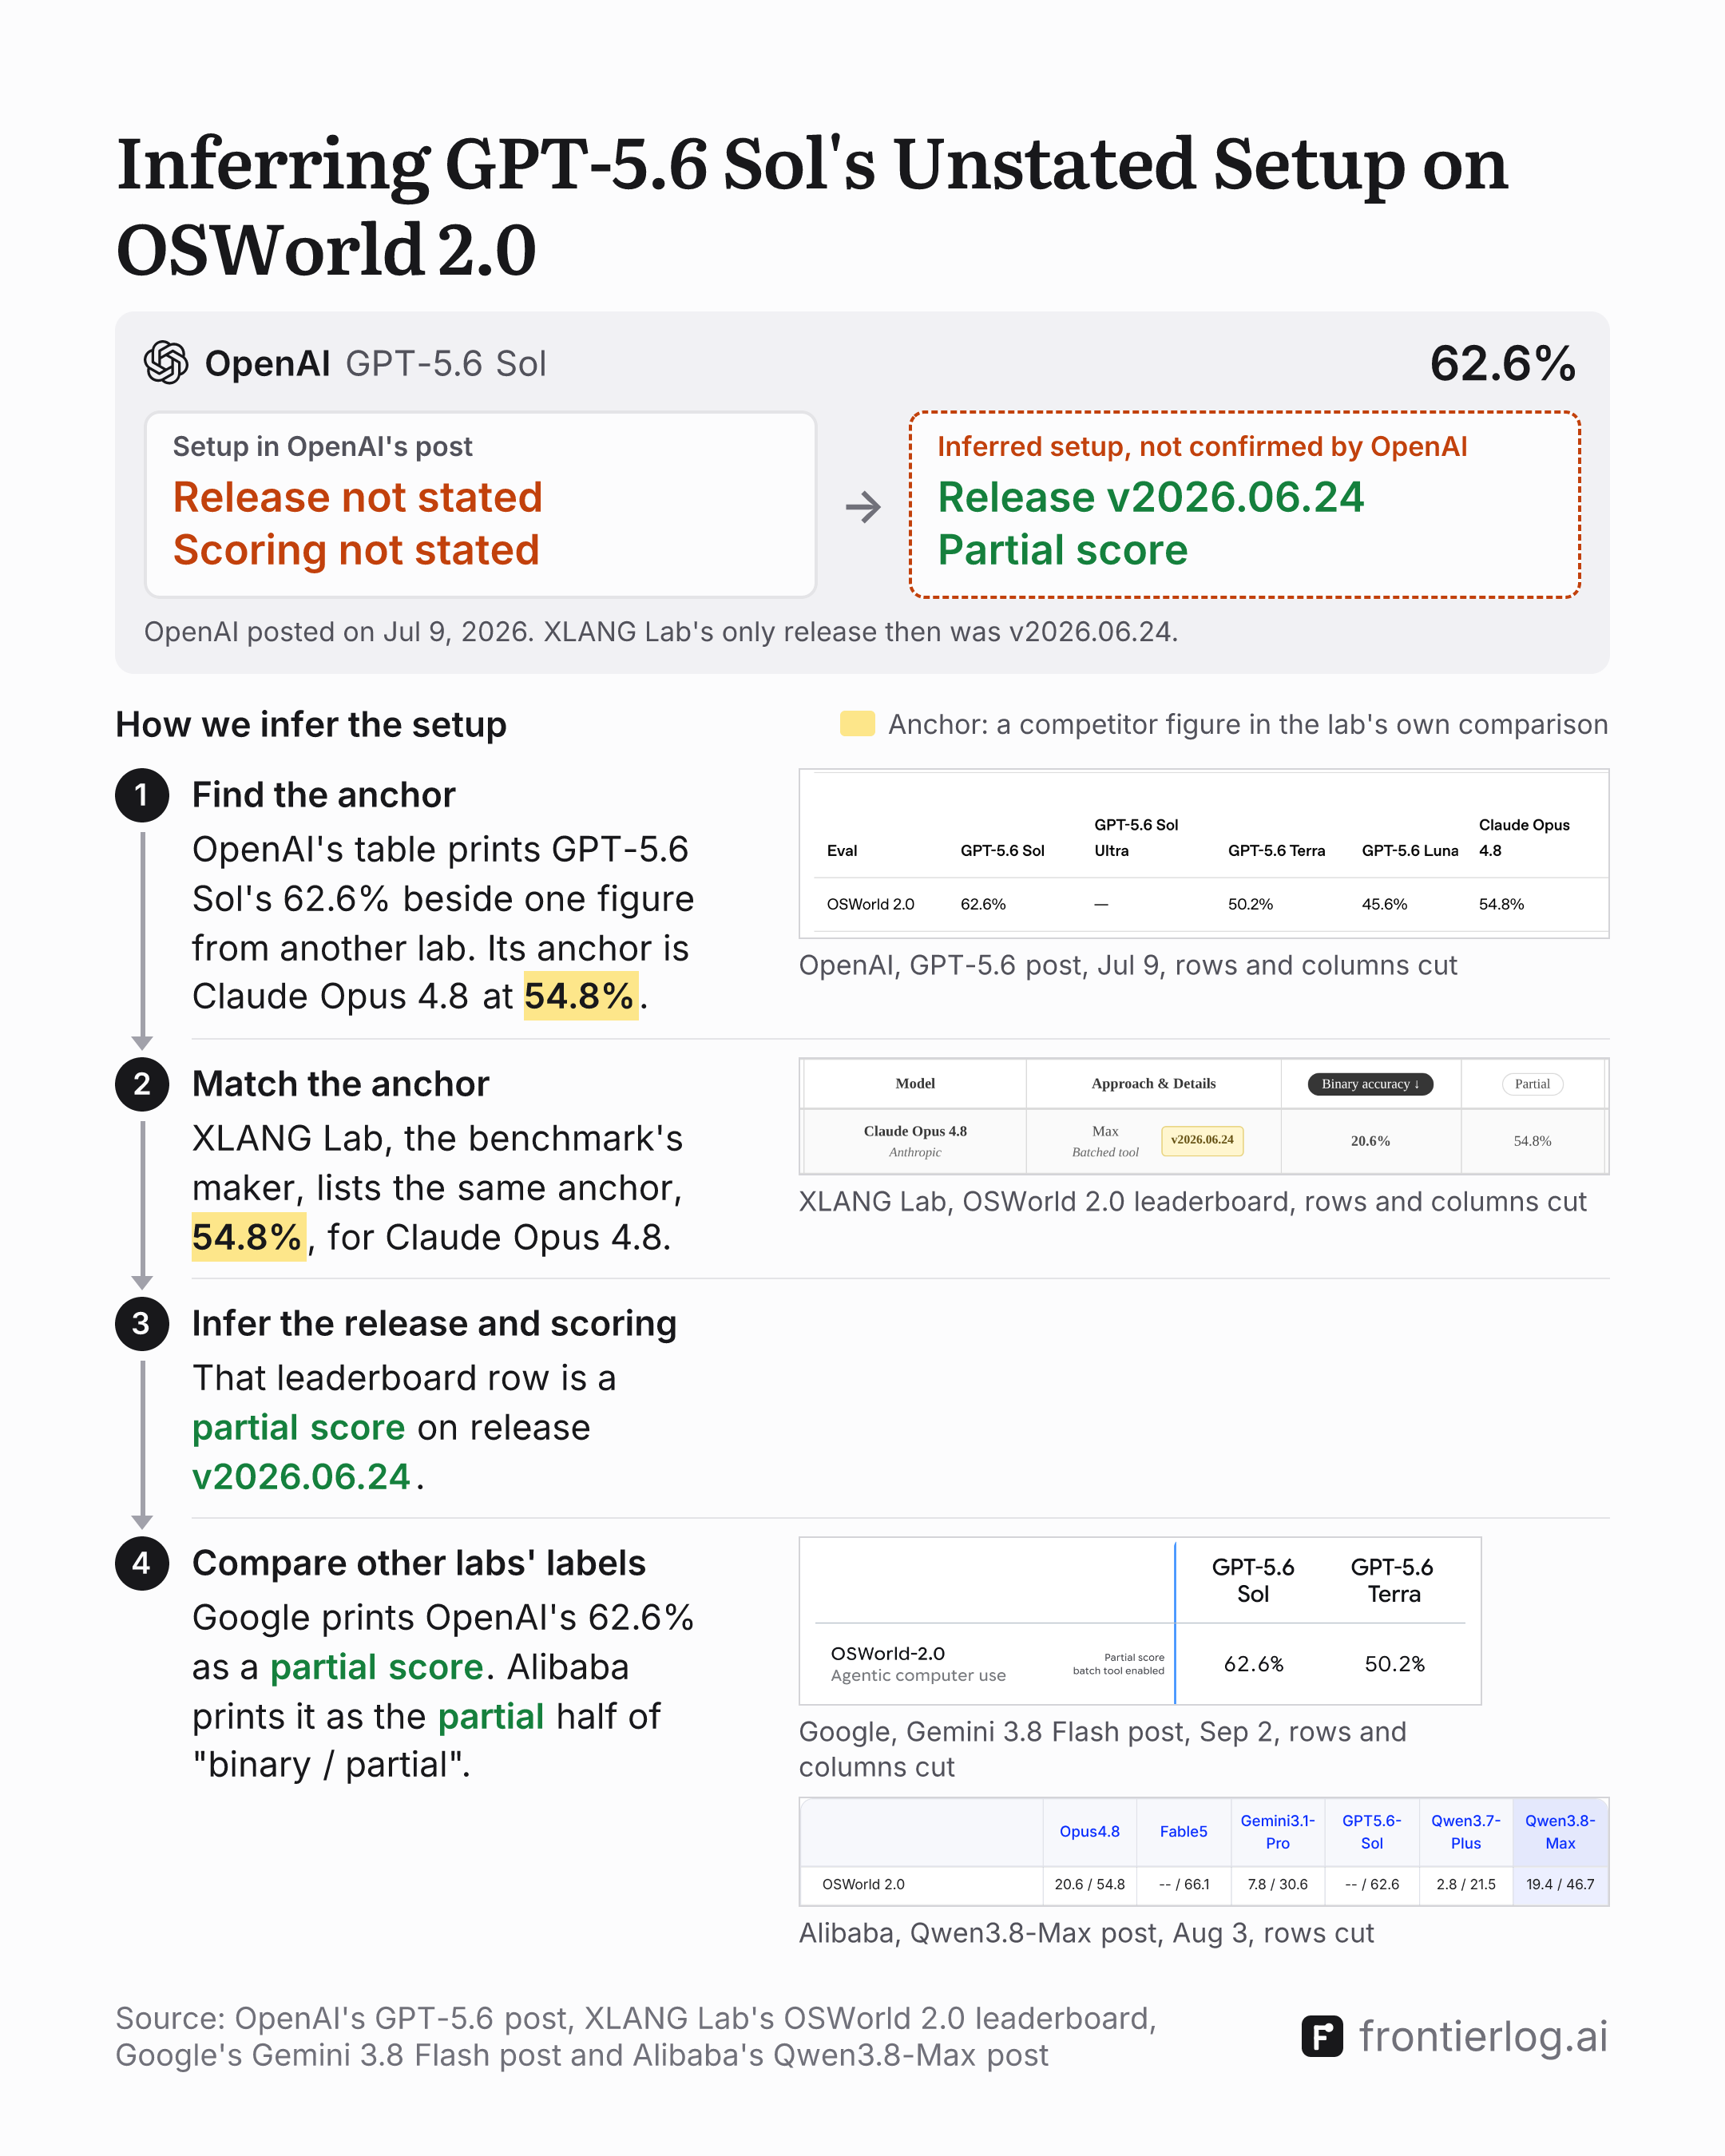
OpenAI reported 62.6% for GPT-5.6 Sol on OSWorld 2.0 in its GPT-5.6 post on Jul 9, 2026. The post doesn't name the release of the benchmark or the scoring behind the figure. OpenAI's own comparison with a competitor points to both.
The scoring changes the number
XLANG Lab, which makes OSWorld 2.0, scores each run two ways. Its leaderboard lists Claude Opus 4.8 at 54.8% as a partial score and at 20.6% as binary accuracy, both on release v2026.06.24. The same page calls binary completion "our primary binary-completion metric".
XLANG published v2026.06.24 on Jun 26 and v2026.08.08 on Aug 9. OpenAI and Anthropic both posted their figures between those two dates.
OpenAI's table carries one competitor
OpenAI's table prints 62.6% for GPT-5.6 Sol and 50.2% for GPT-5.6 Terra in its OSWorld 2.0 row. Claude Opus 4.8 is the only model from another lab with a figure in that row, at 54.8%. XLANG's leaderboard lists the same 54.8% for Claude Opus 4.8 as a partial score on v2026.06.24, at max effort with a batched tool. The row also prints 47.5% for OpenAI's GPT-5.5, and the table under the leaderboard page's chart lists 47.5% as GPT-5.5's partial reward on v2026.06.24 at xhigh effort. The page's ranked table lists GPT-5.5 at xhigh effort with a batch tool at 49.5%.
From these matches we infer a partial score on release v2026.06.24 for GPT-5.6 Sol and GPT-5.6 Terra. OpenAI named a setup later. Its GPT-6 Astra post on Sep 3 reports GPT-5.6 Sol at 65.7% on "OSWorld 2.0 (v2026.08.08, offline set, partial score)". XLANG's leaderboard lists GPT-5.6 Sol on v2026.08.08 at 62.72% as a partial score and 27.34% as binary accuracy.
Other labs label the figure a partial score
Google's Gemini 3.8 Flash post on Sep 2 prints 62.6% for GPT-5.6 Sol and 50.2% for GPT-5.6 Terra in a row labelled "Partial score, batch tool enabled". Google's evaluation methodology says its own runs "were completed before the official OSWorld 2.0 team's 08.08 patch to be compatible with competitor's self-reported numbers."
Alibaba's Qwen3.8-Max post on Aug 3 prints the GPT-5.6 Sol cell as "-- / 62.6". Its footnote says "Scores are reported as “binary / partial.”" OpenAI's own post gives the 62.6% with no scoring named.
Anthropic reprinted the figure two weeks later
Anthropic's Claude Opus 5 post on Jul 24 prints 62.6% for GPT-5.6 Sol beside 70.6% for Claude Opus 5 and 66.1% for Claude Fable 5. The same row prints 55.7% for Claude Opus 4.8, where OpenAI's table prints 54.8%. The Claude Opus 5 system card says the GPT-5.6 Sol score is "sourced from" OpenAI's release post. The card calls its own 70.6% a "first-attempt success rate, averaged over five runs" and names neither a release nor a partial or strict score.
Alibaba's table prints the Claude Fable 5 cell as "-- / 66.1". Anthropic ran Claude Fable 5 again for its Claude Fable 5.1 system card on Sep 1, on "the authors' August 2026 task release with their subsequent task fixes" and Anthropic's own fixes. That run scored 72.9% as a partial score and 36.1% as a strict pass rate. The card says these results "supersede the OSWorld 2.0 figures in the Claude Opus 5 System Card". We don't infer a setup for Anthropic's July figures. The only figure from another lab in Anthropic's row is OpenAI's 62.6%, and that figure's setup is itself inferred.
How we infer a setup
We infer a setup only from a figure that a lab prints in its own comparison. Another document must report the same figure with its setup stated. Here that document is the benchmark maker's leaderboard. Other labs' labels for the figure are shown beside the inference and aren't its basis. OpenAI hasn't confirmed the setup we infer. Inferring OpenAI's and Moonshot AI's Unstated OSWorld 2.1 Setups traces two results on the later version the same way.
OSWorld 2.0, release and scoring not stated
| Model | Score | Sources |
|---|---|---|
| Claude Opus 4.8Claude Opus 4.8, as Anthropic reports it | 55.7% | Introducing Claude Opus 5benchmark table image, row 'Computer use / OSWorld 2.0', column 'Opus 4.8' |
| Claude Fable 5Claude Fable 5 | 66.1% | Introducing Claude Opus 5benchmark table image, row 'Computer use / OSWorld 2.0', column 'Fable 5' |
| GPT-5.6 SolGPT-5.6 Sol | 62.6% | Announcementcomputer-use/agentic eval table (HTML), row 'OSWorld 2.0', column 'GPT‑5.6 Sol' |
| GPT-5.6 TerraGPT-5.6 Terra | 50.2% | Announcementcomputer-use/agentic eval table (HTML), row 'OSWorld 2.0', column 'GPT‑5.6 Terra' |
| Claude Opus 5Claude Opus 5 | 70.6% | Announcementbenchmark table image, row 'Computer use / OSWorld 2.0', column 'Opus 5' |
OSWorld 2.0, Claude Opus 4.8 in OpenAI's table and on XLANG's leaderboard
| Model | Value | Sources |
|---|---|---|
| Claude Opus 4.8Claude Opus 4.8, as OpenAI printed it | 54.8% | GPT-5.6: Frontier intelligence that scales with your ambitioncomputer-use eval table (HTML), row 'OSWorld 2.0', column 'Claude Opus 4.8' |
| Claude Opus 4.8Claude Opus 4.8, partial score on v2026.06.24, on XLANG's leaderboard | 54.8% | osworld-v2.xlang.aiLeaderboard table, row 12 'Claude Opus 4.8', 'Max', 'Batched tool', 'v2026.06.24', column 'Partial' (binary accuracy 20.6%) |
| Claude Opus 4.8Claude Opus 4.8, binary accuracy on v2026.06.24, on XLANG's leaderboard | 20.6% | osworld-v2.xlang.aiLeaderboard table, row 12 'Claude Opus 4.8', 'Max', 'Batched tool', 'v2026.06.24', column 'Binary accuracy' |
OSWorld 2.0, GPT-5.5 in OpenAI's table and on XLANG's leaderboard page
| Model | Value | Sources |
|---|---|---|
| GPT-5.5GPT-5.5, as OpenAI printed it | 47.5% | GPT-5.6: Frontier intelligence that scales with your ambitioncomputer-use eval table (HTML), row 'OSWorld 2.0', column 'GPT-5.5' |
| GPT-5.5GPT-5.5, xhigh effort, partial reward on v2026.06.24, in the table under XLANG's chart | 47.5% | osworld-v2.xlang.aichart's model table, row 'GPT-5.5', 'xhigh', 'v2026.06.24', column 'Partial reward' (binary reward 13.9%) |
| GPT-5.5GPT-5.5, xhigh effort, batch tool, partial score on v2026.06.24, in XLANG's ranked table | 49.5% | osworld-v2.xlang.aiLeaderboard table, row 18 'GPT-5.5', 'Xhigh', 'Batch tool', 'v2026.06.24', column 'Partial' (binary accuracy 13.0%) |
OSWorld 2.0 v2026.08.08, GPT-5.6 Sol on XLANG's leaderboard
| Model | Value | Sources |
|---|---|---|
| GPT-5.6GPT-5.6 Sol, partial score, on XLANG's leaderboard | 62.72% | osworld-v2.xlang.aiLeaderboard table, row 9 'GPT-5.6 Sol', 'Max', 'Batch tool', 'v2026.08.08', column 'Partial' |
| GPT-5.6GPT-5.6 Sol, binary accuracy, on XLANG's leaderboard | 27.34% | osworld-v2.xlang.aiLeaderboard table, row 9 'GPT-5.6 Sol', 'Max', 'Batch tool', 'v2026.08.08', column 'Binary accuracy' |
OSWorld 2.0, GPT-5.6 Sol in Google's and Alibaba's tables
| Model | Value | Sources |
|---|---|---|
| GPT-5.6GPT-5.6 Sol, as Google printed it | 62.6% | Introducing Gemini 3.8 Flash and 3.8 Flash Cyberbenchmark table (image), row 'OSWorld-2.0', 'Partial score, batch tool enabled', column 'GPT-5.6 Sol' |
| GPT-5.6GPT-5.6 Terra, as Google printed it | 50.2% | Introducing Gemini 3.8 Flash and 3.8 Flash Cyberbenchmark table (image), row 'OSWorld-2.0', 'Partial score, batch tool enabled', column 'GPT-5.6 Terra' |
| GPT-5.6GPT-5.6 Sol, as Alibaba printed it | 62.6% | Qwen3.8-Max: A New Bar for Coding and Cowork'Full Benchmark Table' (multimodal), row 'OSWorld 2.0', column 'GPT5.6-Sol', cell '-- / 62.6', footnote 7 'Scores are reported as binary / partial' |
OSWorld 2.0, GPT-5.6 Sol in Anthropic's Claude Opus 5 table
| Model | Value | Sources |
|---|---|---|
| GPT-5.6GPT-5.6 Sol, as Anthropic printed it | 62.6% | Introducing Claude Opus 5benchmark table image, row 'Computer use / OSWorld 2.0', column 'GPT-5.6 Sol' |
OSWorld 2.0 v2026.08.08, offline set, partial score, in OpenAI's GPT-6 Astra post
| Model | Score | Sources |
|---|---|---|
| GPT-5.6 SolGPT-5.6 Sol | 65.7% | GPT-6 Astra: A new generation of intelligence'Computer Use' table, row 'OSWorld 2.0 (v2026.08.08, offline set, partial score)', column 'GPT-5.6 Sol2' |
OSWorld 2.0, Anthropic's re-run of Claude Fable 5 on the August 2026 task release
OSWorld 2.0, Claude Fable 5 in Alibaba's table
| Model | Value | Sources |
|---|---|---|
| Claude Fable 5 and Mythos 5Claude Fable 5, as Alibaba printed it | 66.1% | Qwen3.8-Max: A New Bar for Coding and Cowork'Full Benchmark Table' (multimodal), row 'OSWorld 2.0', column 'Fable5', cell '-- / 66.1', footnote 7 'Scores are reported as binary / partial' |
Sources
- Google, Sep 2, 2026Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
- XLANG Lab, GitHub release, Jun 26, 2026github.com/xlang-ai/OSWorld-V2/releases/tag/v2026.06.24
- XLANG Lab, GitHub release, Aug 9, 2026github.com/xlang-ai/OSWorld-V2/releases/tag/v2026.08.08
- OpenAI, Jul 9, 2026GPT-5.6: Frontier intelligence that scales with your ambition
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- XLANG Lab, leaderboard, Oct 15, 2026osworld-v2.xlang.ai
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- Google DeepMind, evaluation methodology, Sep 3, 2026storage.googleapis.com/deepmind-media/gemini/gemini_3-8_flash_model_evaluation.pdf
- Anthropic, Sep 1, 2026Claude Fable 5.1 and Claude Mythos 5.1 System Card
- Anthropic, Sep 1, 2026Introducing Claude Fable 5.1 and Claude Mythos 5.1
- Anthropic, Jul 24, 2026Claude Opus 5 System Card
- Anthropic, Jul 24, 2026Introducing Claude Opus 5