Tracing GPT-5.6 Sol's Unstated Task Set on Agents' Last Exam v1
OpenAI doesn't name the task set behind GPT-5.6 Sol's 53.6 on Agents' Last Exam, and its chart's costs point to all tasks on the maker's leaderboard.
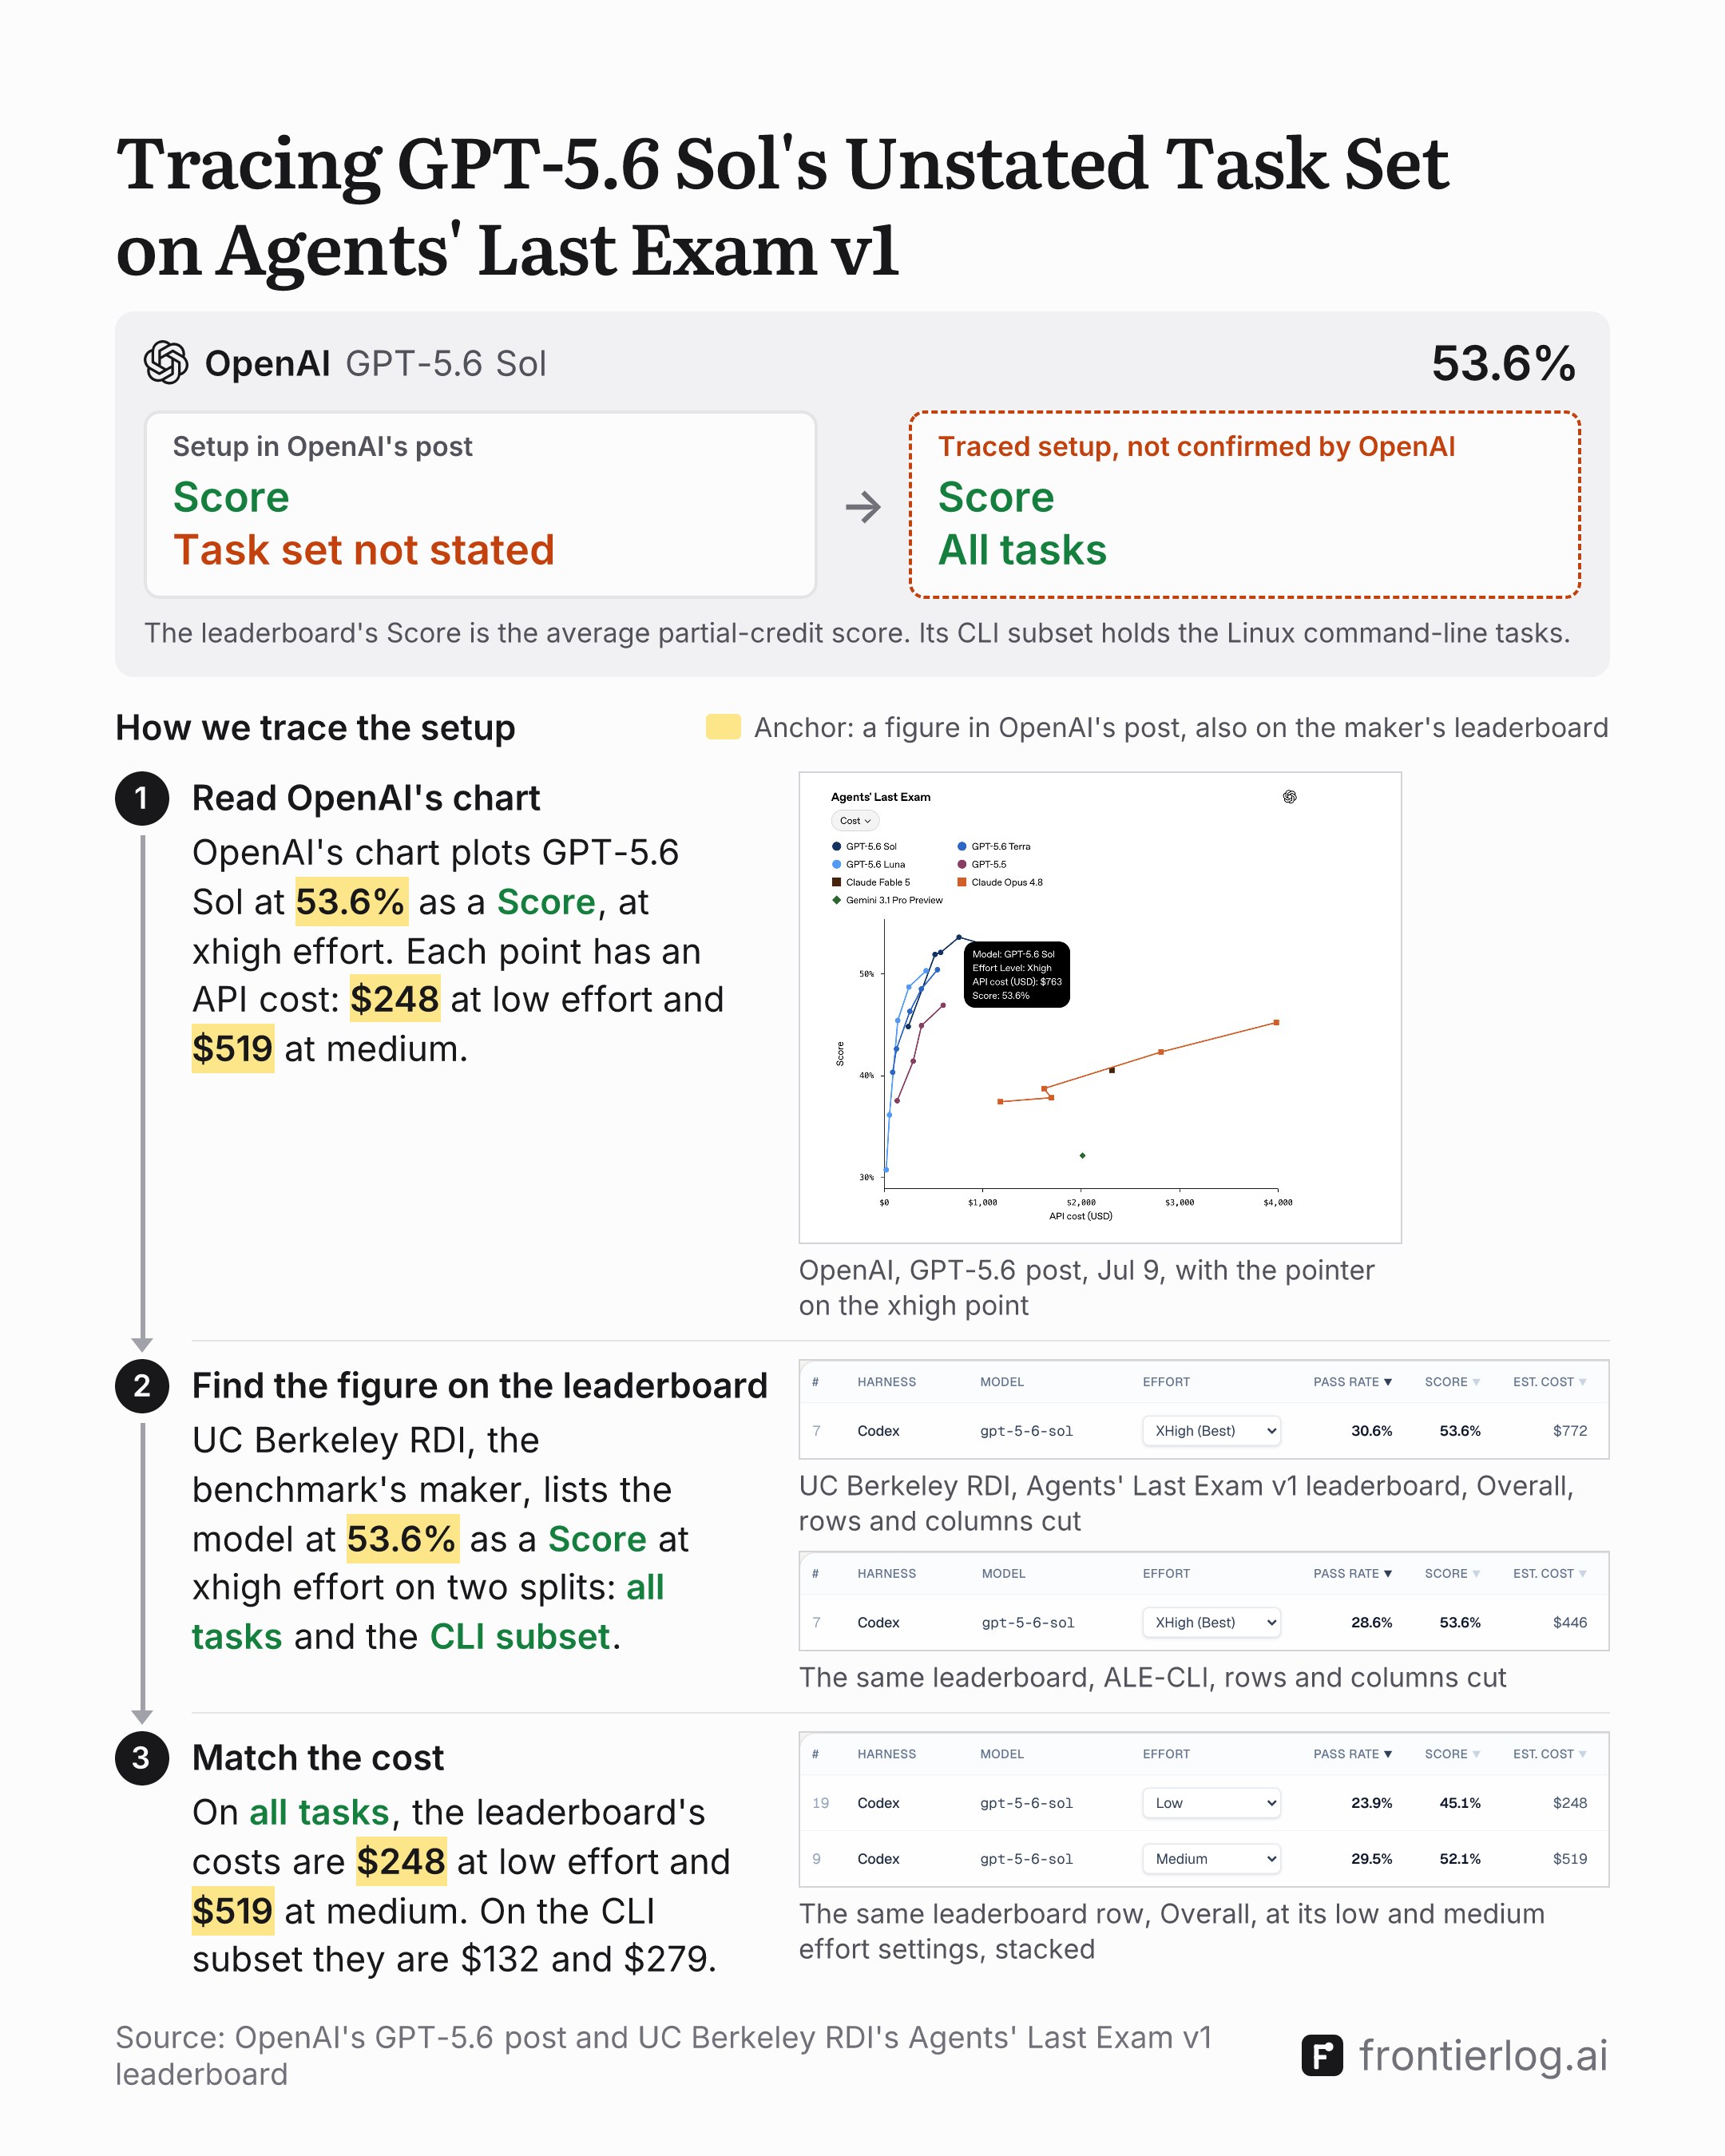
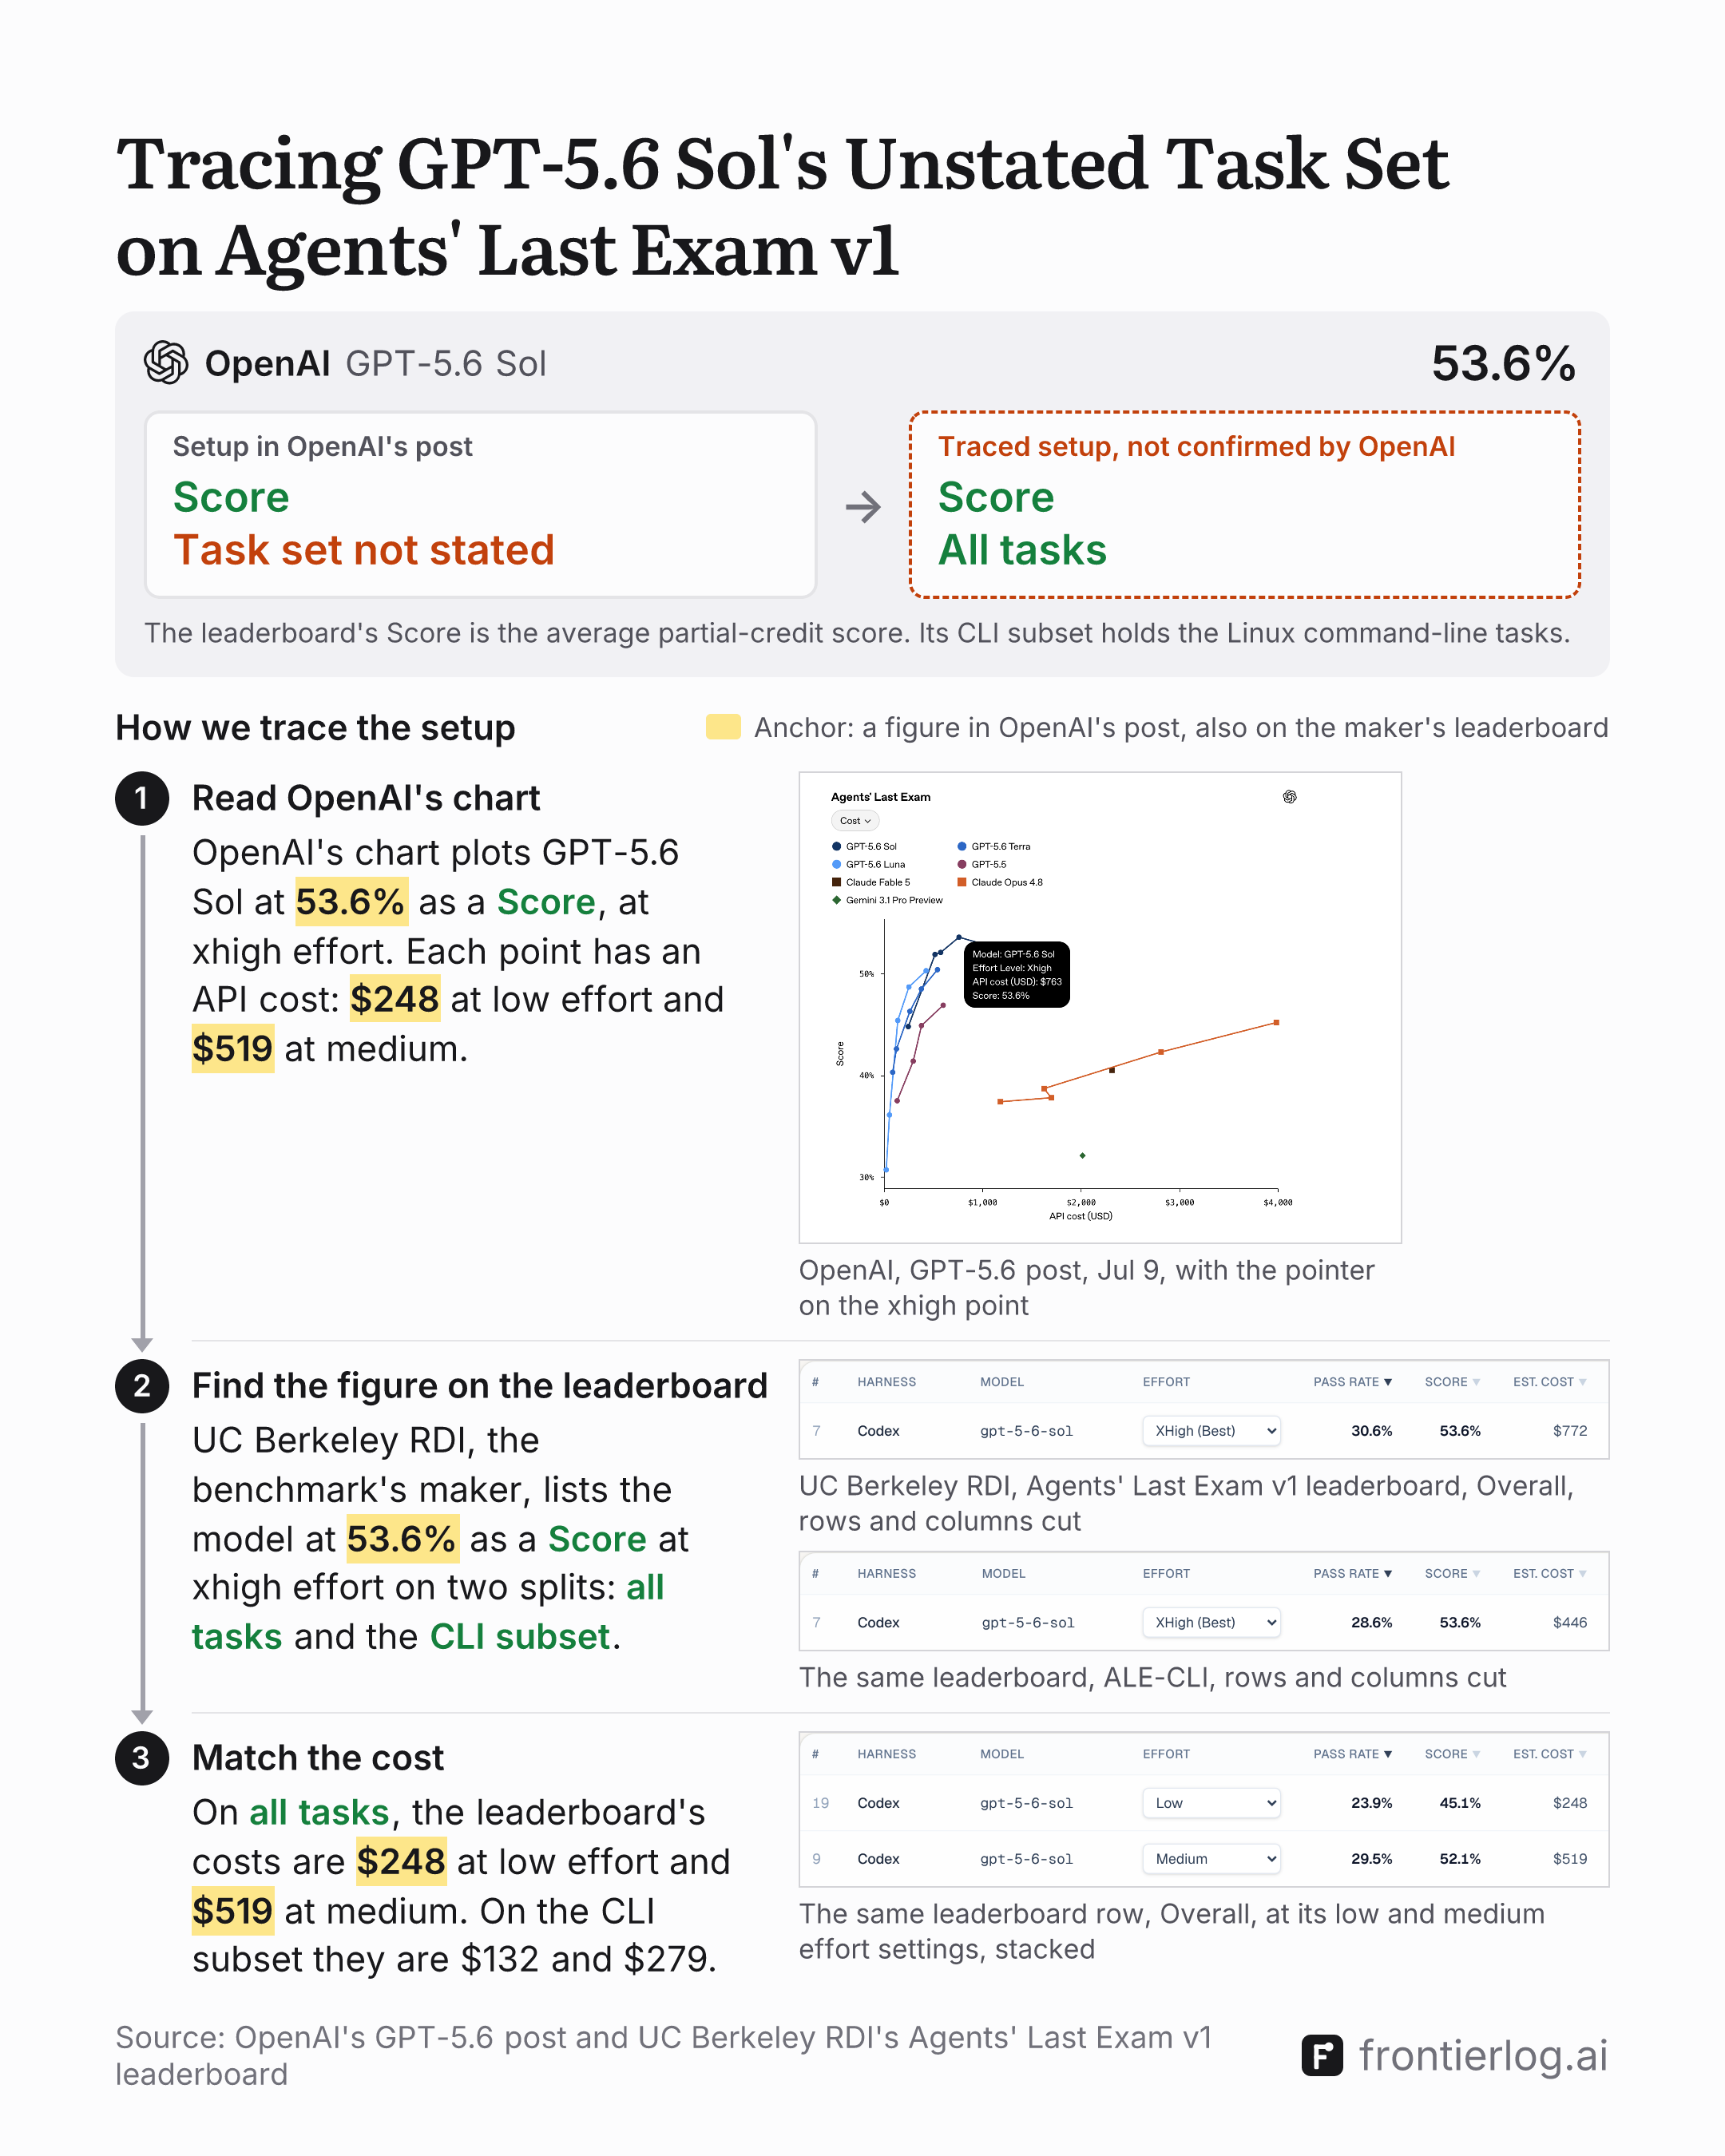
OpenAI reported 53.6 for GPT-5.6 Sol on Agents' Last Exam in its GPT-5.6 post on Jul 9, 2026, and called the figure "a new high". The chart under that sentence labels the figure a Score at xhigh effort. The post doesn't define the term or name the task set. The leaderboard of the benchmark's maker and the costs in OpenAI's chart point to all tasks.
The leaderboard lists 53.6% as a Score
UC Berkeley RDI makes Agents' Last Exam and publishes a leaderboard for version 1 with two measures. The page is marked as archived, and the current leaderboard covers version 1.1. The page says: "Pass Rate is the share of runs that earned a perfect score; Score is the average partial-credit score." On its Overall split, the leaderboard lists GPT-5.6 Sol on the Codex harness at xhigh effort with a Score of 53.6% and a Pass Rate of 30.6%. We read the leaderboard on Nov 13, 2026.
The same Score appears on two splits
The leaderboard has five splits. One is ALE-CLI, which it describes as "the subset of tasks that run on Linux and can be completed through command-line interaction alone". On ALE-CLI, GPT-5.6 Sol has the same Score at xhigh effort, 53.6%, and a Pass Rate of 28.6%. The model's Scores on the three other splits differ. OpenAI's headline figure matches the leaderboard's Score on Overall and on ALE-CLI, so the Score doesn't settle the task set.
The chart's costs point to all tasks
OpenAI's chart gives an API cost for each point. For GPT-5.6 Sol it shows $248 at low effort, $519 at medium, $577 at high, $763 at xhigh and $1,087 at max. The leaderboard's estimated costs on the Overall split at those efforts are $248, $519, $576, $772 and $1,084. On ALE-CLI they are $132, $279, $343, $446 and $597. The chart's costs equal the Overall costs at low and medium effort and sit within $9 of them at the other three. OpenAI's post says it estimates API cost "by looking at the production behavior of our models, and simulating offline". The leaderboard says its cost is "runner-logged cost where available, otherwise computed from token counts at list prices". From the costs we trace the 53.6 to all tasks.
The Scores in OpenAI's later posts match the Overall split too. Its GPT-6 Astra post on Sep 3 charts GPT-5.6 Sol at 45.1% at low effort, 52.1% at medium effort and 52.4% at high effort. Its GPT-6 Sol and Luna post on Sep 22 charts 52.8% at max effort. The leaderboard's Overall Scores at those four efforts are the same four figures. Its ALE-CLI Scores at those efforts are 46.8%, 53.1%, 51.2% and 50.9%. The GPT-5.6 post's own Scores sit below the leaderboard's Overall Scores. Its chart has GPT-5.6 Sol at 44.8% at low effort, 51.9% at medium effort, 52.1% at high effort and 52.7% at max effort. Its eval table prints the 52.7%.
Other labs' figures for the model
Alibaba's Qwen3.8-Max post on Aug 3 prints GPT-5.6 Sol as "30.6 / 53.6" in a row labelled "Agents' Last Exam (Pass / Score)". Those are the leaderboard's Pass Rate and Score on the Overall split at xhigh effort. Alibaba's column is headed "GPT5.6 Sol (max)", and the leaderboard's max-effort row has 29.6% and 52.8%.
Z.ai's GLM-5.3 post on Aug 14 prints 28.6 for GPT-5.6 Sol in a row labelled "Agents' Last Exam" and "ALE-CLI". The post doesn't name the measure. Its footnote describes Z.ai's own run of the 105 tasks with the Claude Code harness at max effort. The leaderboard's ALE-CLI Pass Rate for GPT-5.6 Sol at xhigh effort is 28.6%. DeepSeek's V4.1 tech report on Sep 10 prints 26.7 for GPT-5.6 Sol in a row labelled "Agents' Last Exam(Pass@1)", under a column headed "Max". The report says it evaluates on ALE-CLI. The leaderboard's ALE-CLI Pass Rate at max effort is 26.7%.
How we trace a setup
We trace a setup by matching the lab's figures to the leaderboard of the benchmark's maker, where the measure and the task set are stated. The leaderboard doesn't say who ran each row. OpenAI's post links the benchmark's site and doesn't say the figure comes from its leaderboard. OpenAI's GPT-6 Astra post says its "GPT evaluations were run in our research environment or via our API". OpenAI hasn't confirmed the setup we trace. Inferring GPT-5.6 Sol's Unstated Setup on OSWorld 2.0 traces another of the model's results.
Agents' Last Exam v1, GPT-5.6 Sol in OpenAI's posts
Agents' Last Exam v1 leaderboard, Overall split
Agents' Last Exam v1 leaderboard, ALE-CLI split
Agents' Last Exam v1, GPT-5.6 Sol in other labs' tables
| Model | Value | Sources |
|---|---|---|
| GPT-5.6GPT-5.6 Sol, as Z.ai printed it | 28.6% | GLM-5.3: Frontier Coding with Emergent Cyber Capabilities'Performance across comparison models' table, row 'Agents' Last Exam' / 'ALE-CLI', column 'GPT-5.6 Sol' |
| GPT-5.6GPT-5.6 Sol, as DeepSeek printed it | 26.7% | DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache CompressionTable 3, p.33, row 'Agents' Last Exam(Pass@1)', column 'GPT-5.6 Sol', 'Max' |
| GPT-5.6GPT-5.6 Sol, pass, as Alibaba printed it | 30.6% | Qwen3.8-Max: A New Bar for Coding and Cowork'Full Benchmark Table', General Agent block, row 'Agents' Last Exam (Pass / Score)', column 'GPT5.6 Sol (max)', first of the two values |
| GPT-5.6GPT-5.6 Sol, score, as Alibaba printed it | 53.6% | Qwen3.8-Max: A New Bar for Coding and Cowork'Full Benchmark Table', General Agent block, row 'Agents' Last Exam (Pass / Score)', column 'GPT5.6 Sol (max)', second of the two values |
Agents' Last Exam v1, API cost of GPT-5.6 Sol in OpenAI's chart
Agents' Last Exam v1 leaderboard, estimated cost of GPT-5.6 Sol
Sources
- UC Berkeley RDI, leaderboard, Nov 13, 2026agents-last-exam.org/leaderboard/v1
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression
- OpenAI, Jul 9, 2026GPT-5.6: Frontier intelligence that scales with your ambition
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- OpenAI, Sep 22, 2026Introducing GPT-6 Sol and Luna
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- Z.ai, Aug 14, 2026GLM-5.3: Frontier Coding with Emergent Cyber Capabilities