Who Makes the Benchmarks AI Labs Report
Data and evaluation companies made 24% of the benchmarks AI labs reported at launch in late 2026, up from 4% in early 2025.
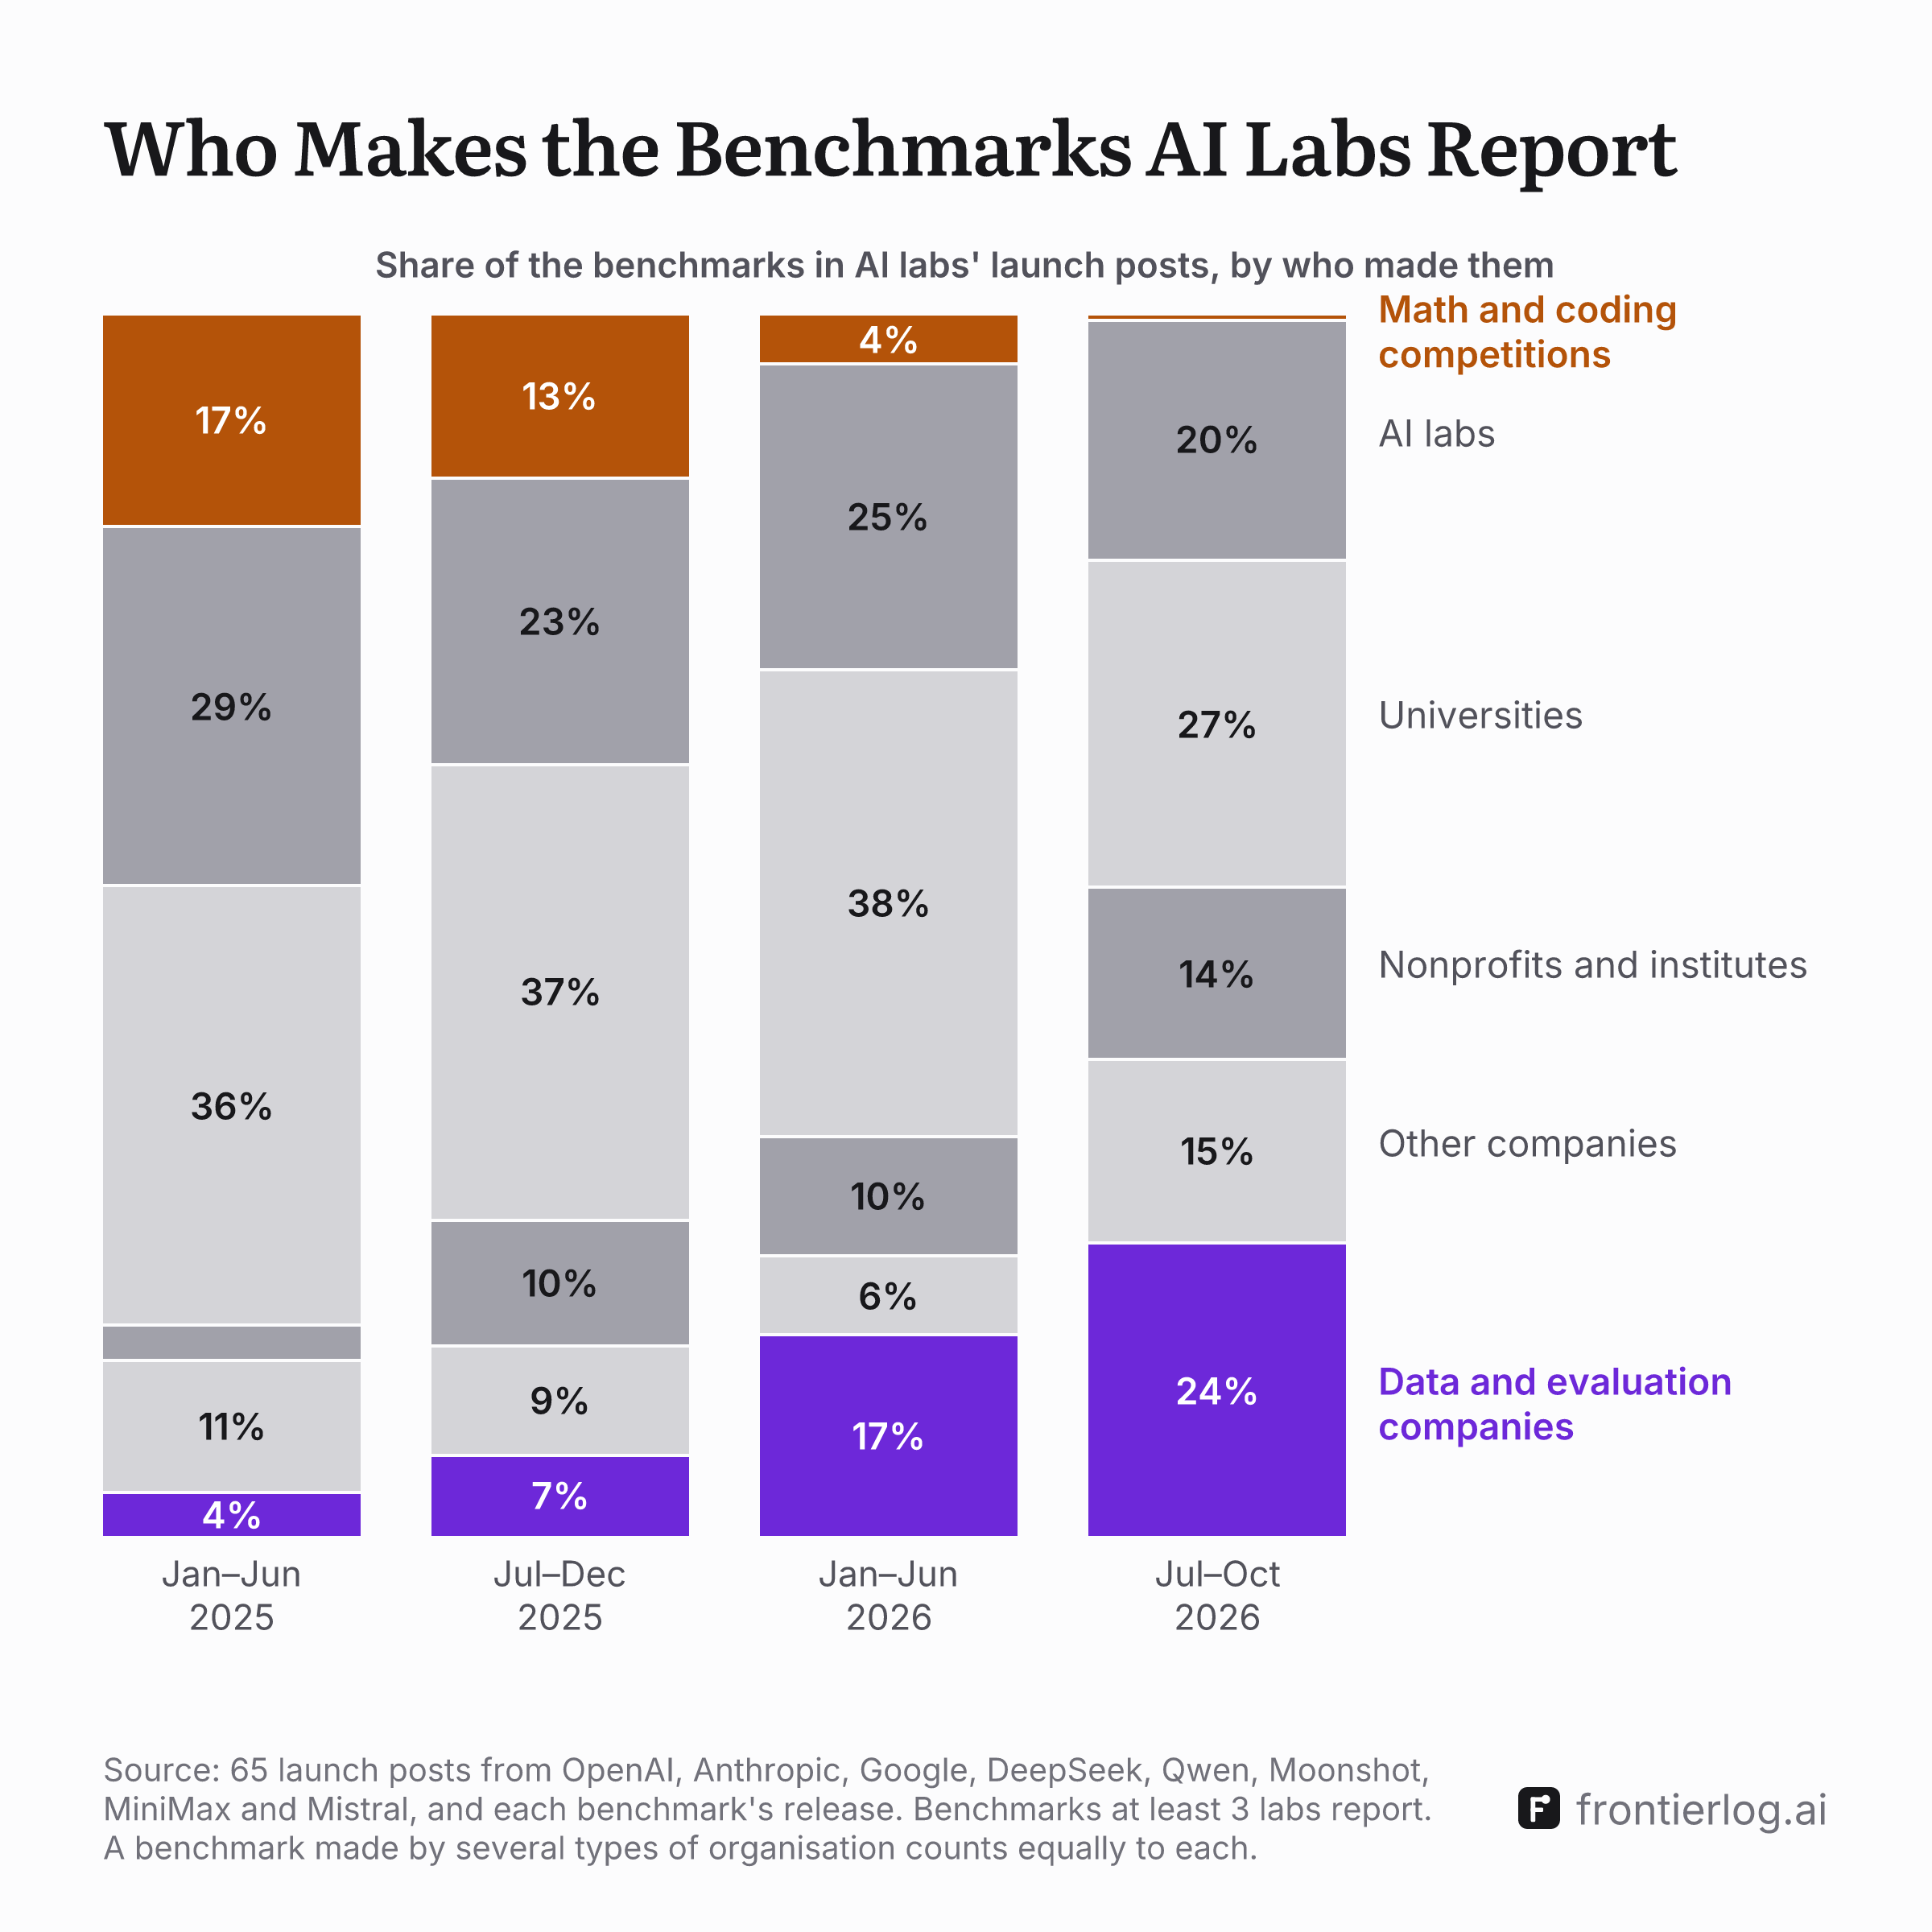
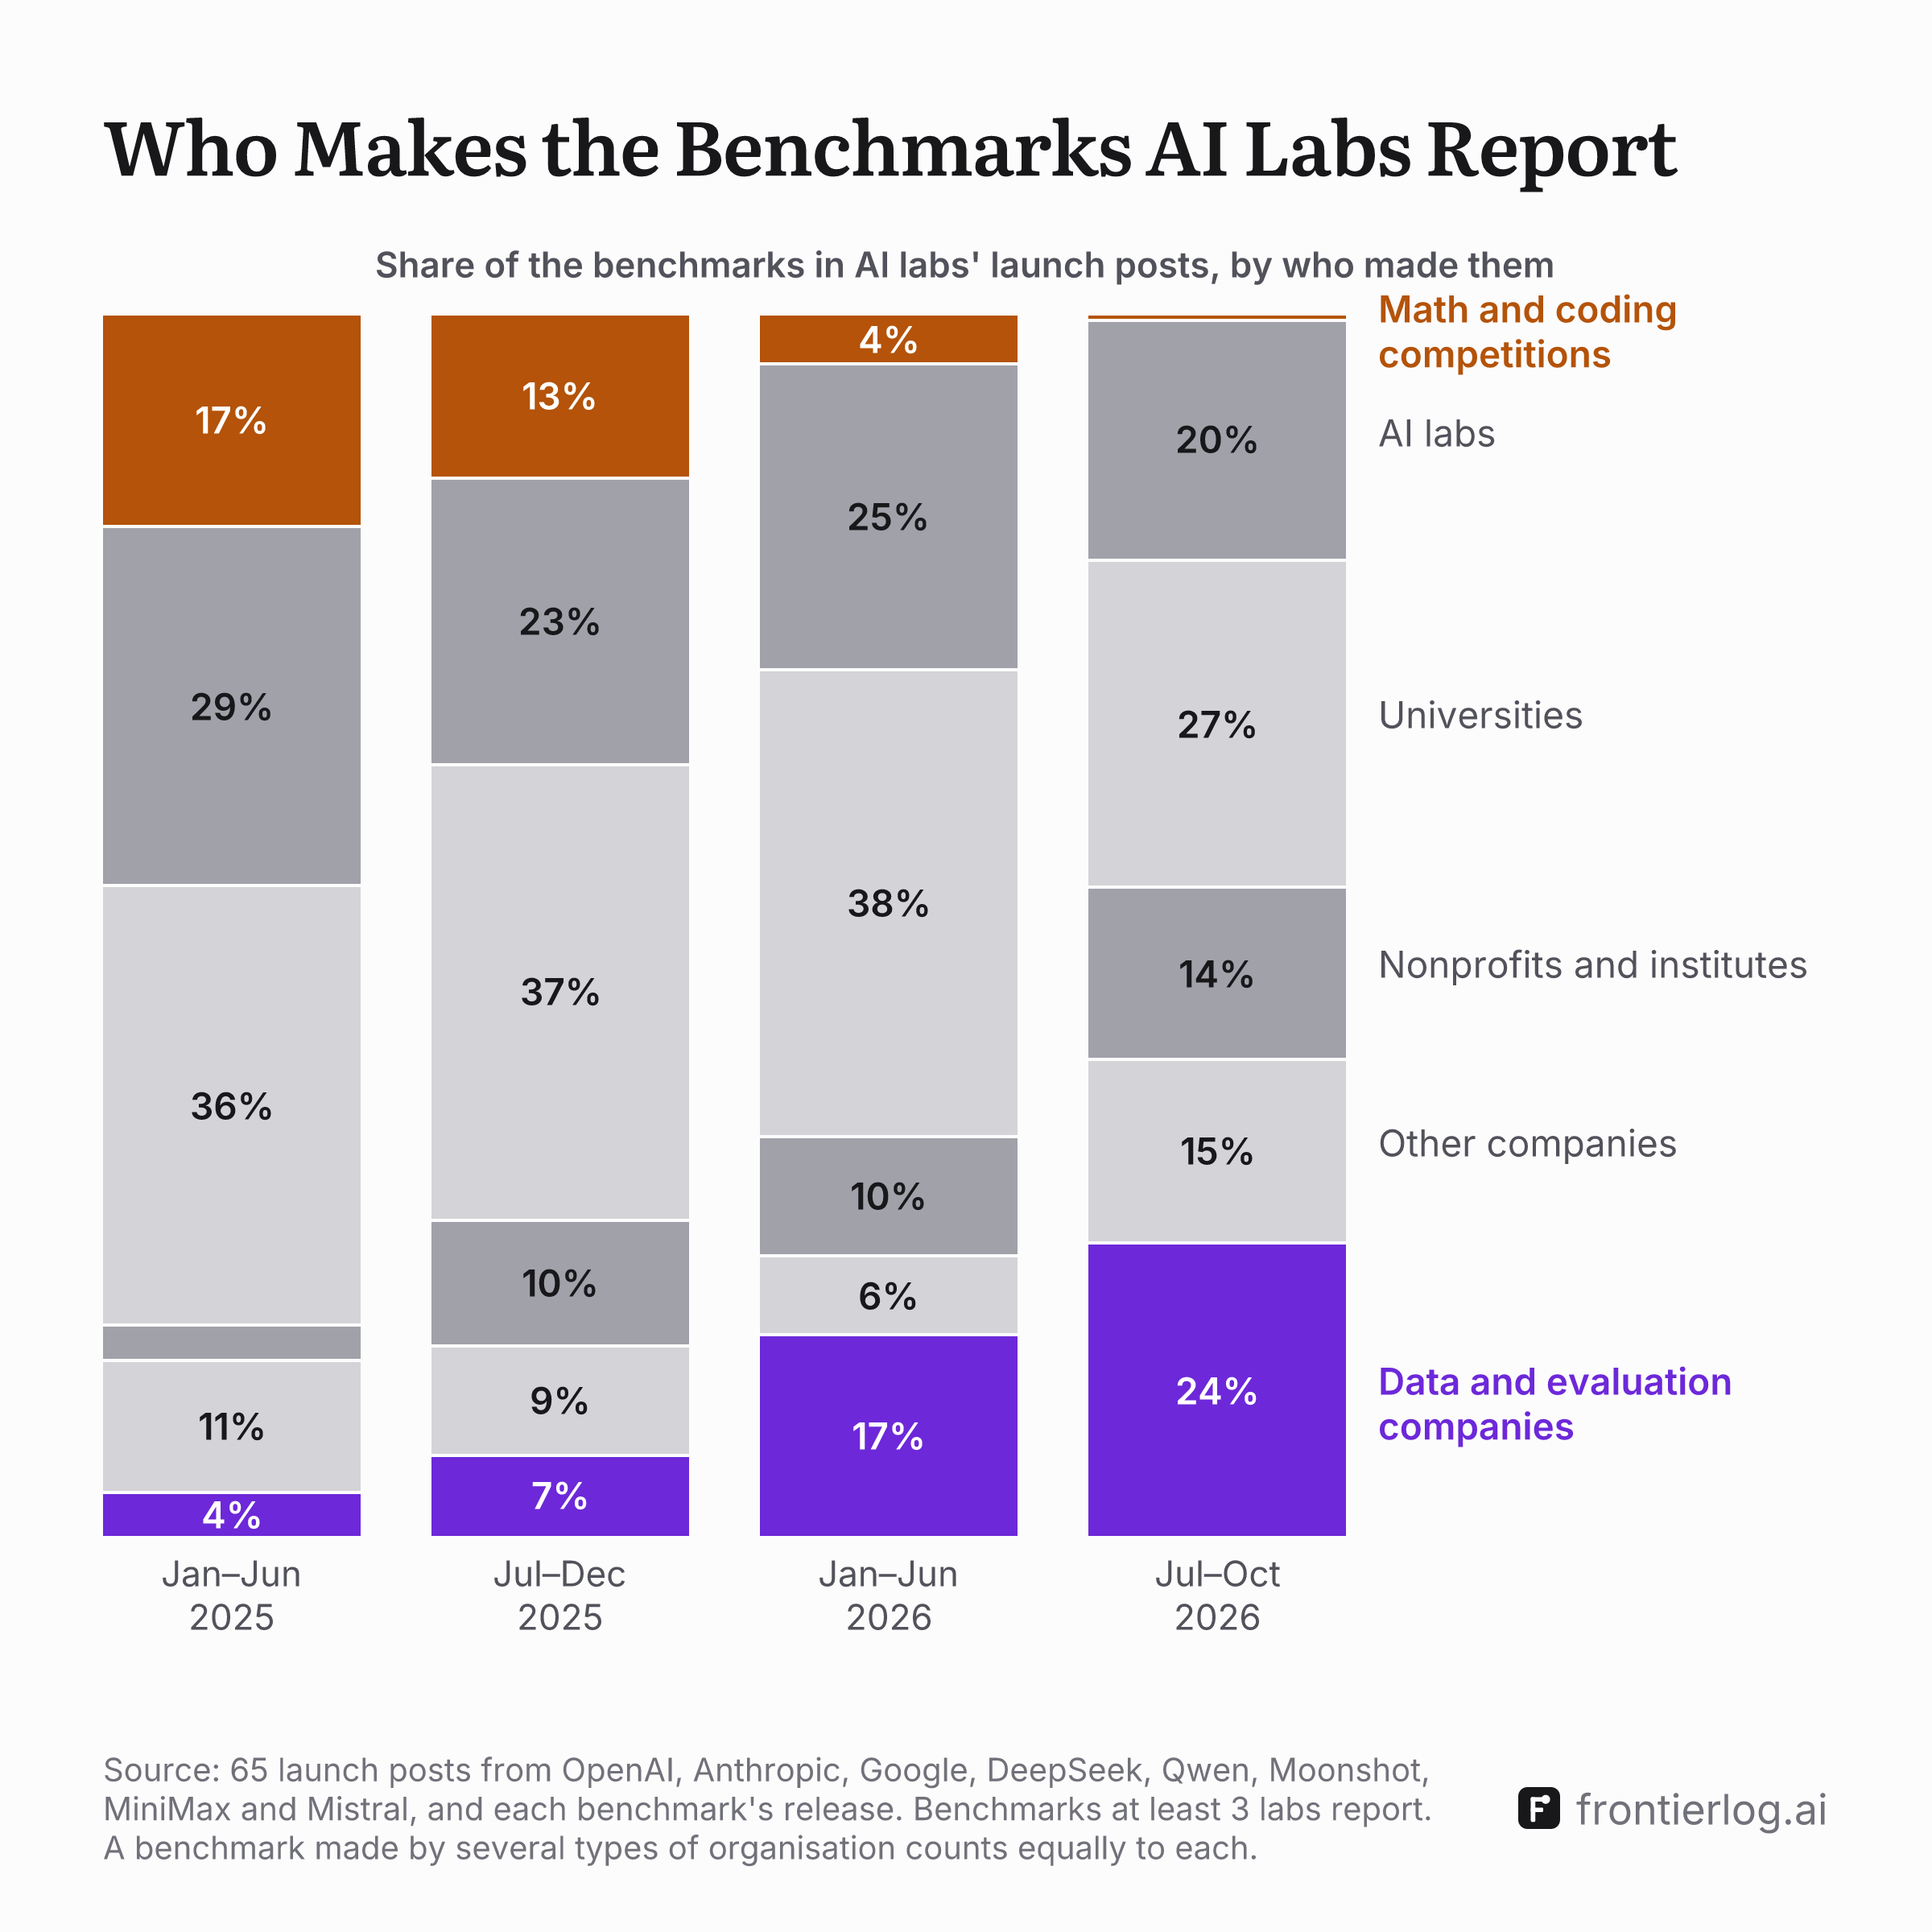
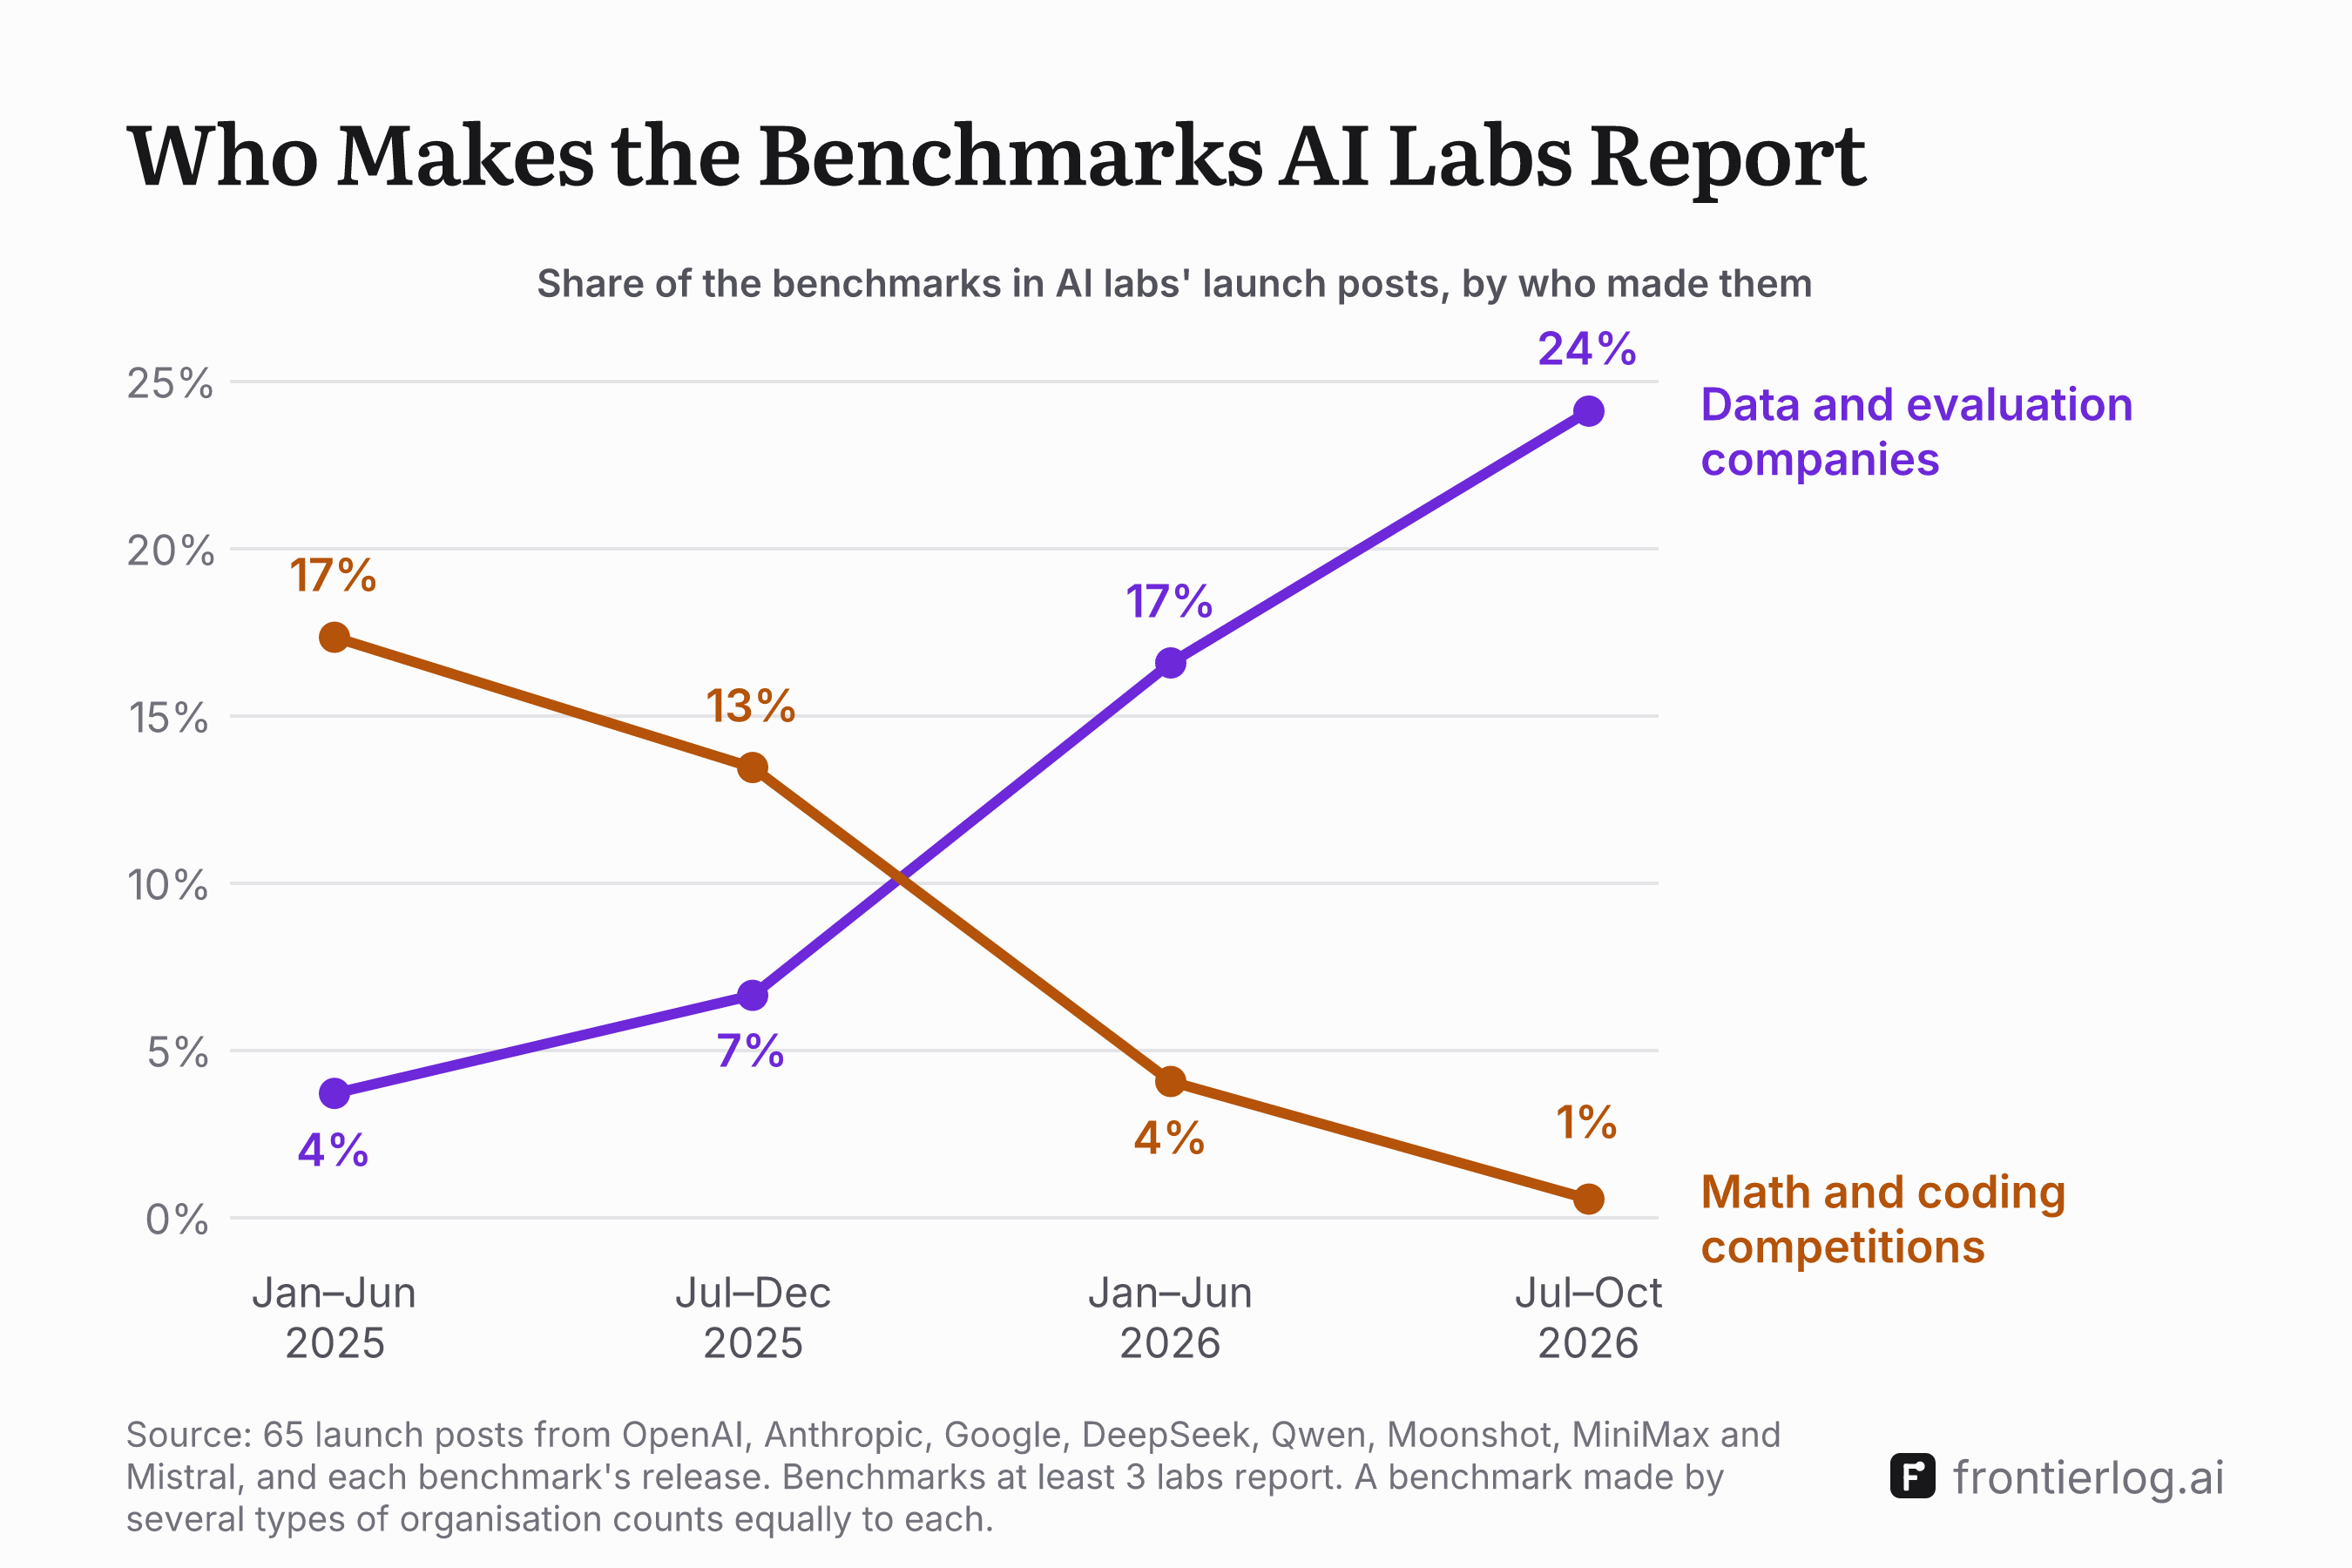
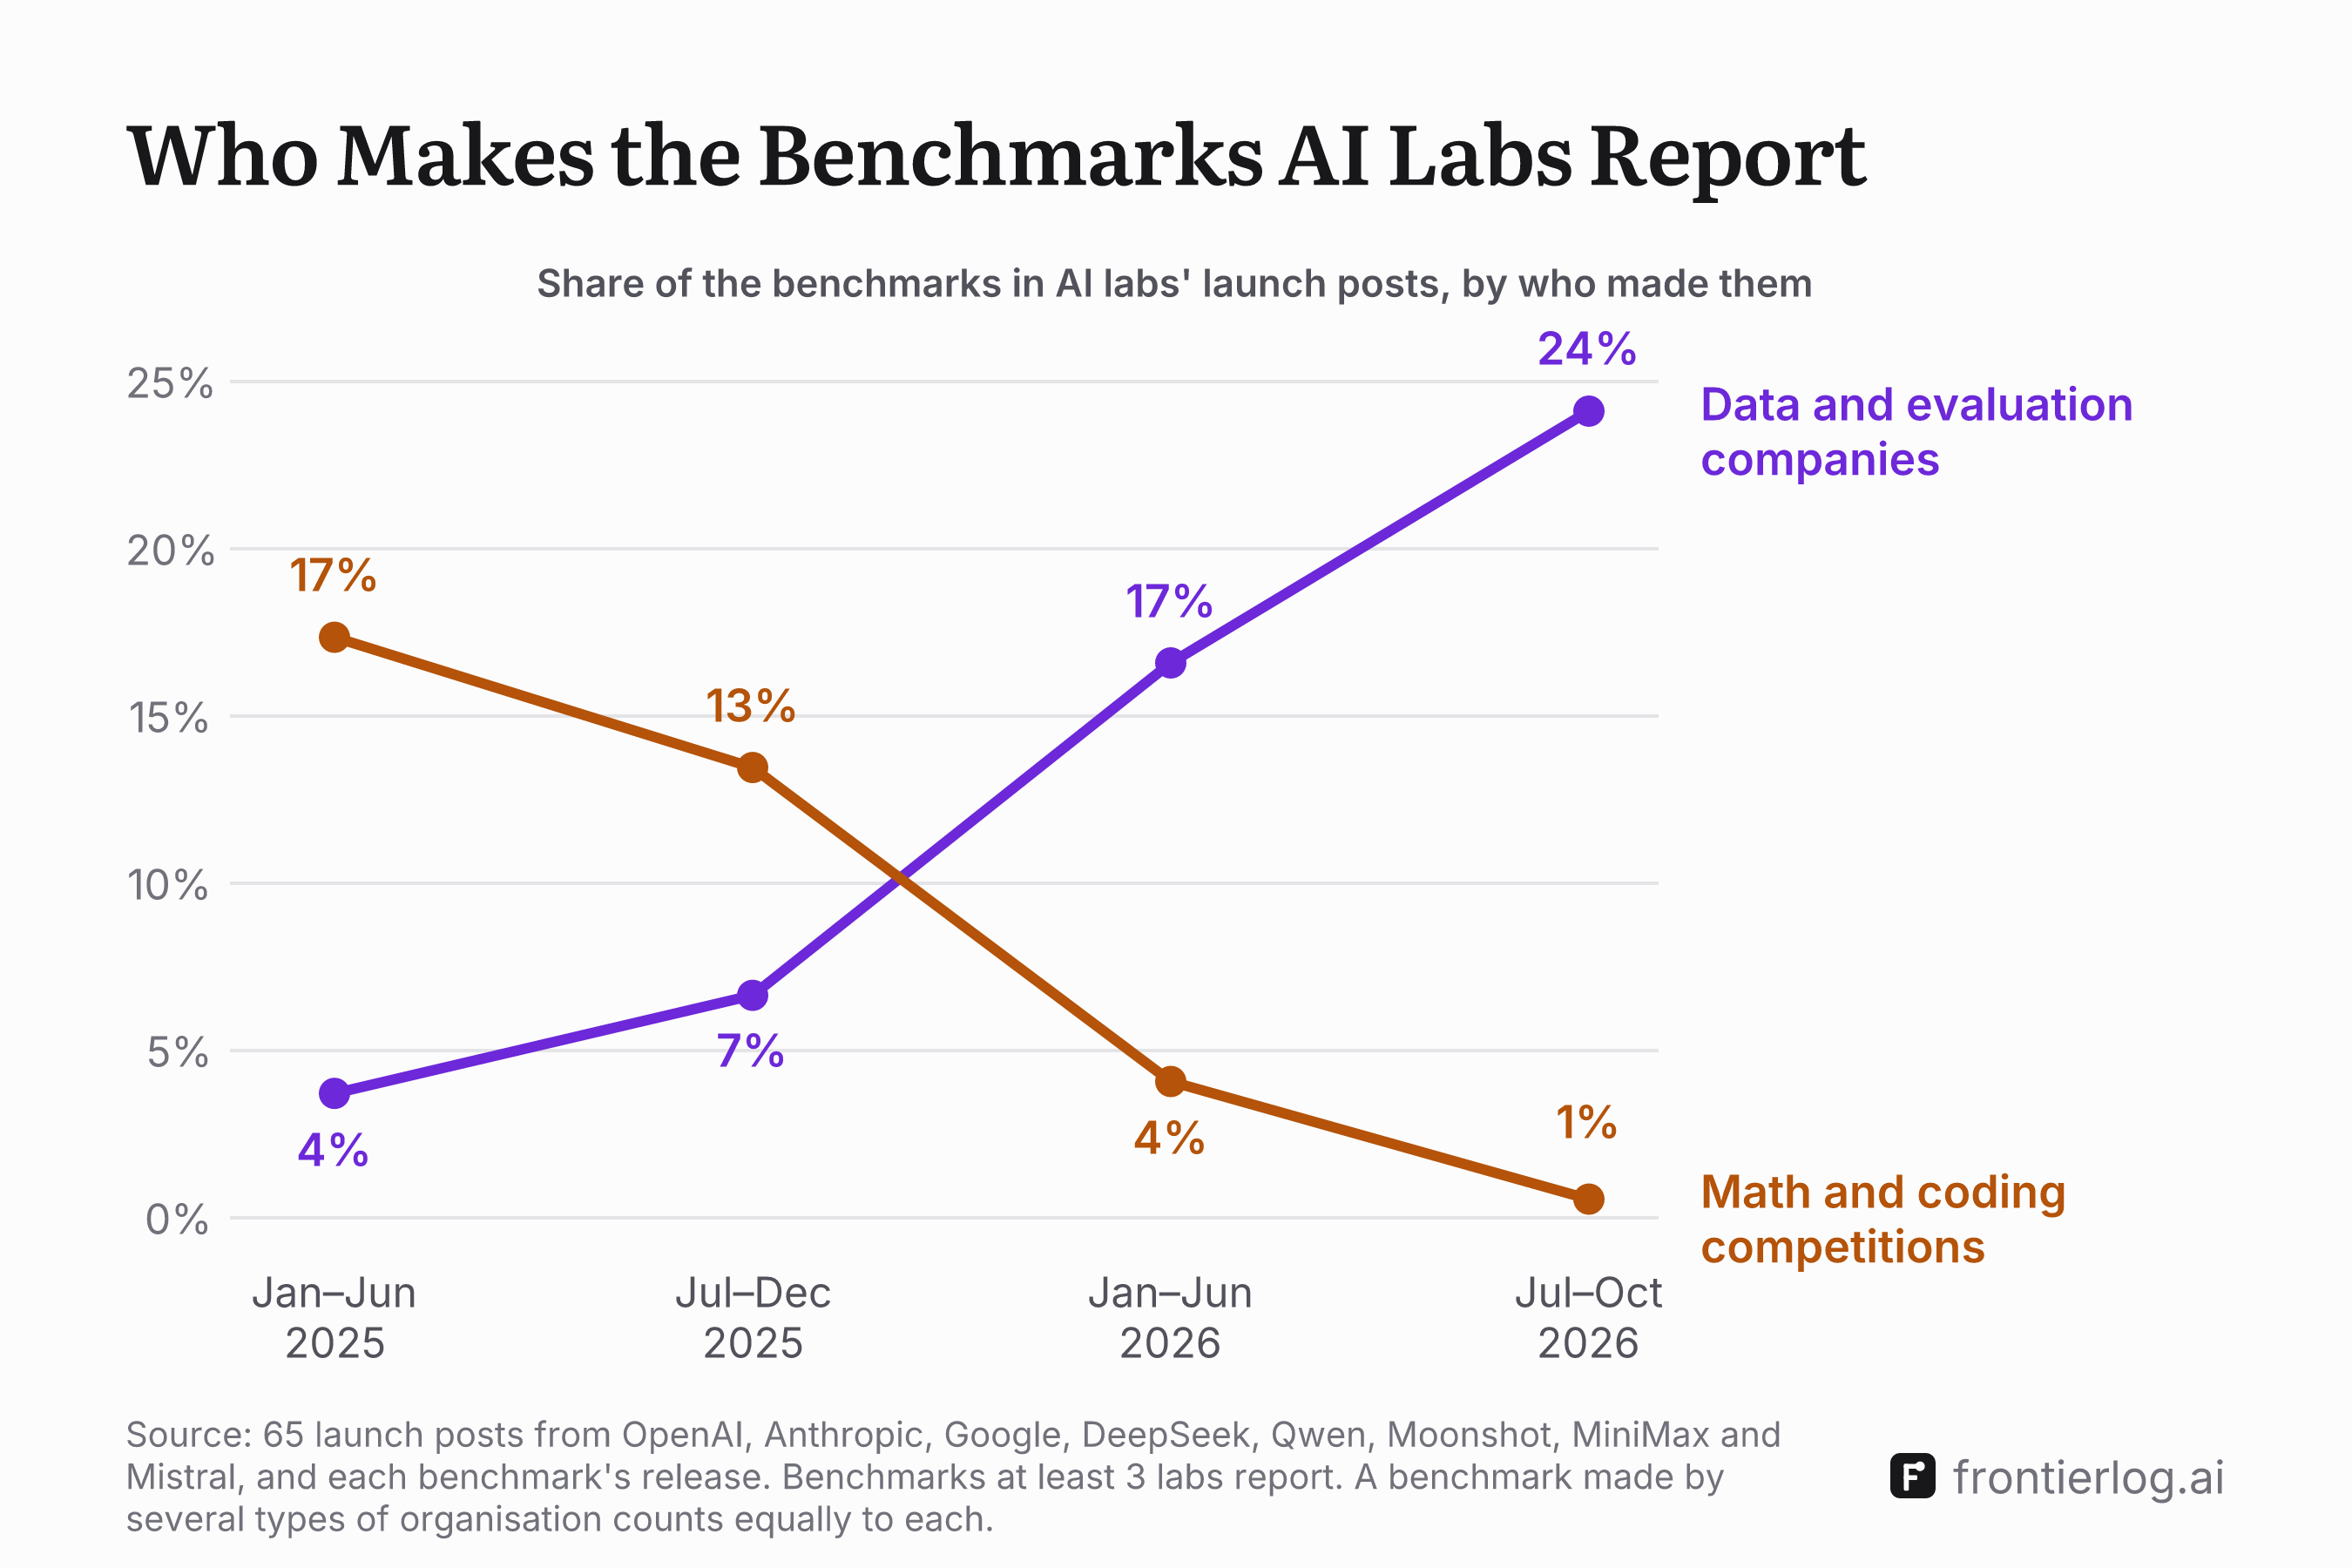
AI labs show what a new model can do with scores on benchmarks, and other organisations make most of those benchmarks. Across 65 launch posts from eight labs since January 2025, data and evaluation companies made a growing share of the benchmarks the labs reported. That share rose from 4% in the first half of 2025 to 24% from July to October 2026. Benchmarks run by math and coding competitions fell from 17% to 1% over the same time.
Data companies' benchmarks spread
Scale AI says it provides "high-quality data and full-stack technologies that power the world's leading models" on its about page. It released SWE-bench Pro and MCP Atlas on Sep 19, 2025, and it made Humanity's Last Exam with the Center for AI Safety. In 2026 the labs also reported DeepSWE from Datacurve, Chartography from Surge AI and FrontierSWE from Proximal. They reported benchmarks from the evaluation companies Artificial Analysis and Vals AI and from the data company Mercor too.
All 12 launch posts from July to October 2026 reported at least one benchmark that a data or evaluation company made.
Competition-run benchmarks dropped out
In the first half of 2025, 12 of the 16 launch posts reported a benchmark that a competition runs: the AIME and HMMT math contests or Codeforces programming rounds. From July 2026, only one launch post did. DeepSeek's post for DeepSeek-V4.1-Flash on Sep 10 reported Codeforces.
Other benchmarks also draw on contest problems, such as LiveCodeBench, MathArena Apex and Google DeepMind's IMO-AnswerBench. They count under the universities and labs that made them.
Universities kept the largest share
Universities' share stayed between 36% and 38% until mid-2026 and was 27% from July, still the largest of any type. The AI labs' share fell from 29% in the first half of 2025 to 20% from July 2026. OpenAI made BrowseComp, and it made SWE-bench Verified with the authors of SWE-bench.
How we counted
Frontier Log's reporting inventory records every benchmark in 65 flagship launch posts from OpenAI, Anthropic, Google, DeepSeek, Qwen, Moonshot, MiniMax and Mistral. It also records the cards and reports each post links. We counted 72 benchmarks with 91 versions in all. At least three labs report each of them, in these posts or in other launches our data holds. Each benchmark counts once per launch.
We took each benchmark's makers from its paper's author affiliations or its release post. A benchmark whose makers are of several types counts equally to each type. IFEval comes from Google and Yale University, so it counts half to AI labs and half to universities.
We typed each maker other than a university from its own description of itself. Argonne National Laboratory, the Max Planck Institute for Intelligent Systems and Thoughtful Lab don't describe themselves on a page we could read, so we left them out of the types.
We also left out authors listed as independent, Harbor, the Terminal-Bench team's own framework, and ExploitGym's industry partners. Its paper limits their role to feedback, model access and help running some experiments. Agents' Last Exam lists 88 affiliations. The makers table quotes at least one of them for each type they add. We couldn't find the OpenAGI Research Foundation's own site, and a high school among them fits none of the types.
SWE-bench Multilingual's page names its authors, and their affiliations come from the SWE-smith paper the page asks readers to cite.
| Creator | Jan–Jun 2025 | Jul–Dec 2025 | Jan–Jun 2026 | Jul–Oct 2026 |
|---|---|---|---|---|
| Data and evaluation companies | 4% | 7% | 17% | 24% |
| Math and coding competitions | 17% | 13% | 4% | 1% |
| AI labs | 29% | 23% | 25% | 20% |
| Universities | 36% | 37% | 38% | 27% |
| Nonprofits and institutes | 3% | 10% | 10% | 14% |
| Other companies | 11% | 9% | 6% | 15% |
| Launch posts | 16 | 18 | 19 | 12 |
Launches
Creators
| Benchmark | Made by | Types |
|---|---|---|
| AA-LCR | AA-LCR was created through a rigorous multi-phase process involving several members of the Artificial Analysis research team and more than a dozen undergraduate studentshuggingface.co | Data and evaluation company |
| Agents' Last ExamAgents' Last Exam v1, Agents' Last Exam v1.1 | 1. University of California, Berkeley … 6. Snorkel AI 7. SciLifeLab 8. HubSpot … 43. Amazon … 54. Meta … 75. U.S. National Institutes of Healtharxiv.org | University, Data and evaluation company, Nonprofit, Other company, AI lab |
| Aider Polyglot | December 21, 2024 o1 tops aider’s new polyglot leaderboardaider.chat | Other company |
| AIMEAIME 2024, AIME 2025 | Mathematical Association of America … 2024-25 AIME Thresholds Are Availablemaa.org | Competition |
| APEX-Agents | Bertie Vidgen Austin Mann … Brendan Foody Osvald Nitski Mercor apex@mercor.comarxiv.org | Data and evaluation company |
| ARC-AGI-1ARC-AGI-1 | François Chollet ∗ Google, Inc. fchollet@google.comarxiv.org | AI lab |
| ARC-AGI-2ARC-AGI-2 | By Greg Kamradt … Today we’re excited to launch ARC-AGI-2 … The ARC Prize Foundation adapts this into our definition for measuring AGIarcprize.org | Nonprofit |
| AutomationBenchAutomationBench 1.0.6, AutomationBench, release not specified | By Anna Marie Clifton · April 20, 2026 Today we're releasing AutomationBench … We initially built AutomationBench for internal use, to help evaluate which models to deploy across Zapierzapier.com | Other company |
| BabyVision | 1 UniPat AI 2 xbench 3 Alibaba Group 4 MoonShot AI 5 StepFun 6 Peking University 7 Tsinghua University 8 University of Wisconsin–Madison 9 Princeton University 10 Nanyang Technological Universityarxiv.org | Other company, AI lab, University |
| BrowseCompBrowseComp | Jason Wei∗ Zhiqing Sun∗ Spencer Papay … Amelia Glaese OpenAIarxiv.org | AI lab |
| BrowseComp-ZH | 1 Hong Kong University of Science and Technology (Guangzhou) 2 Peking University 3 Mindverse AI 4 Alibaba Group 5 Zhejiang University 6 Zhejiang University of Technology 7 MBZUAI 8 NIO 9 HSBC 10 Harvard T.H. Chan School of Public Healtharxiv.org | University, Other company, AI lab |
| ChartographyChartography | THE SURGE AI BLOG … Chartography is our benchmark for professional chart understanding .surgehq.ai | Data and evaluation company |
| CharXiv Reasoning | Princeton Language and Intelligence (PLI), Princeton University … University of Wisconsin, Madison … The University of Hong Kongarxiv.org | University |
| Chinese SimpleQA | Yancheng He∗ , Shilong Li∗ , Jiaheng Liu∗† … Bo Zheng Taobao & Tmall Group of Alibabaarxiv.org | AI lab |
| Claw-Eval | 1 State Key Laboratory of Multimedia Information Processing, School of Computer Science, Peking University 2 The University of Hong Kongarxiv.org | University |
| Codeforces | I focused on three areas, which are being developed to the present day: contests (rounds and championships), social network (communication: blogs, comments, votes) and trainings.codeforces.com | Competition |
| CyberGymCyberGym | Zhun Wang∗ , Tianneng Shi∗ , Jingxuan He, Matthew Cai, Jialin Zhang, Dawn Song University of California, Berkeleyarxiv.org | University |
| DeepSWEDeepSWE v1.1 | Wenqi Huang, Peter Jiang · June 14, 2026 … @misc{datacurve2026deepswev11, … © 2026 Datacurvedeepswe.datacurve.ai | Data and evaluation company |
| ExploitGymExploitGym | 1 UC Berkeley 2 Max Planck Institute for Security and Privacy 3 UC Santa Barbara 4 Arizona State University 5 Anthropic 6 OpenAI 7 Google … The benchmark design and experimental methodology are developed by the academic authors. Industry partners provided feedback on the benchmark design, facilitated access to their models, and assisted with running select experiments.arxiv.org | University, Nonprofit |
| Finance Agent | Rayan Krishnan Vals AI, Inc. … Shirley Wu Stanford University … Langston Nashold Vals AI, Inc. … Antoine Bigeard Vals AI, Inc.arxiv.org | Data and evaluation company, University |
| FrontierCodeFrontierCode 1.1, FrontierCode 2.0 | FrontierCode 2.0 By The Cognition Team 2026.10.27 … We are excited to introduce FrontierCode 2.0 , a new generation of our coding benchmark seriescognition.com | AI lab |
| FrontierSWEFrontierSWE, release not specified, FrontierSWE v2 | FrontierSWE is developed by the Proximal team in collaboration with external collaborators.frontierswe.com | Data and evaluation company |
| GDPval-AA | GDPval-AA v2.1 is Artificial Analysis' evaluation framework for OpenAI's GDPval dataset. … GDPval-AA v2.1 uses 220 tasks developed by OpenAI in collaboration with industry professionalsartificialanalysis.ai | Data and evaluation company, AI lab |
| GPQA DiamondGPQA Diamond | 1 New York University 2 Cohere 3 Anthropic, PBCarxiv.org | University, AI lab |
| GraphWalksGraphWalks | openai / graphwalks … GraphWalks: a multi hop reasoning long context benchmark … 4/12/2025: Initial dataset publishedhuggingface.co | AI lab |
| GSM8KGSM8K | Karl Cobbe∗ … karl@openai.com … John Schulman joschu@openai.comarxiv.org | AI lab |
| HealthBench | Rahul K. Arora Jason Wei … Karan Singhal∗ OpenAIarxiv.org | AI lab |
| HMMTHMMT February 2025 | HMMT February 2025 February 15, 2025 Team Roundhmmt-archive.s3.amazonaws.com | Competition |
| Humanity's Last ExamHumanity's Last Exam, HLE-Diamond | Organizing Team … 1 Center for AI Safety, 2 Scale AIarxiv.org | Nonprofit, Data and evaluation company |
| IFBenchIFBench | α Allen Institute for Artificial Intelligence β University of Washingtonarxiv.org | Nonprofit, University |
| IFEvalIFEval | Jeffrey Zhou§∗ Tianjian Lu♮ … Le Hou♮† ♮ Google § Yale Universityarxiv.org | AI lab, University |
| IMO-AnswerBench | † Work previously conducted under Google DeepMind … © 2025 Google DeepMind. All rights reservedarxiv.org | AI lab |
| LiveCodeBenchLiveCodeBench v5, LiveCodeBench v6, LiveCodeBench, release not specified | † UC Berkeley $ MIT ‡ Cornellarxiv.org | University |
| LongBench v2 | 1 Tsinghua University 2 Zhipu.AIarxiv.org | University, AI lab |
| LVBench | 1 Zhipu AI 2 Tsinghua University ‡ Peking Universityarxiv.org | AI lab, University |
| MATH-500 | Hunter Lightman∗ Vineet Kosaraju∗ Yura Burda∗ Harri Edwards … Karl Cobbe∗ OpenAIarxiv.org | AI lab |
| MathArena Apex | Created by SRI Lab at ETH Zurich , INSAITmatharena.ai | University |
| MathVista | 1 UCLA, 2 University of Washington, 3 Microsoft Research, Redmondarxiv.org | University, AI lab |
| MCP AtlasMCP Atlas | By The Scale Research Team · September 19, 2025 … We introduce MCP-Atlas , an agentic leaderboardscale.com | Data and evaluation company |
| MCPMark | 1 TRAIL, National University of Singapore 2 EvalSys 3 LobeHub 4 Shanghai Jiao Tong University 5 Fudan Universityarxiv.org | University, Nonprofit, Other company |
| MMLU | Dan Hendrycks UC Berkeley Collin Burns Columbia University Steven Basart UChicago Andy Zou UC Berkeley Mantas Mazeika UIUC Dawn Song UC Berkeley Jacob Steinhardt UC Berkeleyarxiv.org | University |
| MMLU-ProMMLU-Pro | 1 University of Waterloo, 2 University of Toronto, 3 Carnegie Mellon Universityarxiv.org | University |
| MMMLU | openai / OpenAI … We translated the MMLU’s test set into 14 languages using professional human translators.huggingface.co | AI lab |
| MMMU | 1 IN.AI Research, 2 University of Waterloo, 3 The Ohio State University, 4 Independent, 5 Carnegie Mellon University, 6 University of Victoria, 7 Princeton Universityarxiv.org | Other company, University |
| MMMU-ProMMMU-Pro | This paper introduces MMMU-Pro, a robust version of the Massive Multi-discipline Multimodal Understanding and Reasoning (MMMU) benchmark … MMMU Teamarxiv.org | Other company, University |
| MRCR | OpenAI MRCR … This eval is inspired by the MRCR eval first introduced by Gemini ( https://arxiv.org/pdf/2409.12640v2 ).huggingface.co | AI lab |
| MultiChallenge | Ved Sirdeshmukh∗, Kaustubh Deshpande∗ … Summer Yue, Chen Xing Scale AIarxiv.org | Data and evaluation company |
| NL2Repo | 1 ByteDance Seed China, 2 M-A-P, 3 2077AI, 4 Humanlaya Data, 5 Nanjing University, 6 Peking University, 7 Beijing University of Posts and Telecommunications, 8 Beihang Universityarxiv.org | AI lab, Nonprofit, Data and evaluation company, University |
| OfficeQA | by The Databricks AI Research Team … we've created and are open-sourcing OfficeQAdatabricks.com | Other company |
| OmniDocBench | 1 Shanghai AI Laboratory 2 Abaka AI 3 2077AIarxiv.org | AI lab, Data and evaluation company, Nonprofit |
| OSWorld 2.0OSWorld 2.0, release not specified, OSWorld 2.0 (v2026.08.08), OSWorld 2.1 | XLANG Lab and Collaborators … 1 XLANG Lab, University of Hong Kong 2 University of California, San Diego … 5 Mila – Québec AI Institute 6 Uniphore 7 Snorkel AI … 9 Alibaba Qwen … 11 Simular 12 NeoCognitionarxiv.org | University, Nonprofit, Other company, Data and evaluation company, AI lab |
| OSWorld-VerifiedOSWorld-Verified | Introducing OSWorld-Verified Author XLANG Lab Date Jul 28, 2025xlang.ai | University |
| PaperBench | Giulio Starace * Oliver Jaffe * … Tejal Patwardhan * OpenAIarxiv.org | AI lab |
| PostTrainBench | 1 ELLIS Institute Tübingen 2 Max Planck Institute for Intelligent Systems 3 Tübingen AI Center 4 University of Tübingen 5 Thoughtful Lab.arxiv.org | Nonprofit, University |
| SciCode | 1 University of Illinois Urbana-Champaign 2 Argonne National Laboratory 3 Carnegie Mellon University 4 University of North Carolina at Chapel Hill 5 Massachusetts Institute of Technology 6 Harvard University 7 University of Chicago 8 University of Texas at Austin 9 Stanford University 10 Princeton University 11 The NSF AI Institute for Artificial Intelligence and Fundamental Interactionsarxiv.org | University |
| ScreenSpot-Pro | 1 National University of Singapore 2 East China Normal University 3 Hong Kong Baptist Universityarxiv.org | University |
| Seal-0 | Thinh Pham Nguyen Nguyen Weiyuan Chen Pratibha Zunjare Yu-Min Tseng Tu Vu Virginia Techarxiv.org | University |
| SEC-bench ProSEC-bench Pro 260505, SEC-bench Pro, release not specified | Hwiwon Lee Jiawei Liu Dongjun Kim Ziqi Zhang Chunqiu Steven Xia Lingming Zhang University of Illinois Urbana-Champaignarxiv.org | University |
| SimpleQA | Jason Wei∗ Nguyen Karina∗ … John Schulman William Fedus OpenAIarxiv.org | AI lab |
| SWE-bench Multilingual | Kabir Khandpur, Kilian Lieret, Carlos E. Jimenez, Ofir Press, John Yangswebench.com | University |
| SWE-bench ProSWE-bench Pro | Xiang Deng*, Jeff Da* … Bing Liu, Brad Kenstler Scale AIarxiv.org | Data and evaluation company |
| SWE-bench VerifiedSWE-bench Verified | We’ve collaborated with the authors of SWE-bench to address those issues in a new release of the benchmarkopenai.com | AI lab, University |
| Terminal-BenchTerminal-Bench 1.0, Terminal-Bench 2.0, Terminal-Bench 2.1, Terminal-Bench 4.0 | Today we are releasing the first version of Terminal-Bench … Written by Mike Merrill , Alex Shaw , Chris Rytting , Ludwig Schmidt , and Andy Konwinski … Hosted by Stanford / Harbor / Laude Institutetbench.ai | University, Nonprofit |
| Terminal-Bench-ScienceTerminal-Bench Science 0.1 | Terminal-Bench-Science is a benchmark led by researchers at Stanford University and built by the team behind Terminal-Bench in collaboration with domain experts from a range of scientific disciplines and research institutions around the world. … Hosted by Stanford / Harbor / Laude Institutetbench.ai | University, Nonprofit |
| Toolathlon | 1 The Hong Kong University of Science and Technology 2 All Hands AI 3 Carnegie Mellon University 4 Duke Universityarxiv.org | University, Other company |
| Video-MME | 1 USTC, 2 XMU, 3 HKU, 4 PKU, 5 CUHK, 6 ECNUarxiv.org | University |
| Video-MMMU | 1 S-Lab, Nanyang Technological University 2 Carnegie Mellon Universityarxiv.org | University |
| WideSearch | Ryan Wong∗ , Jiawei Wang∗ … Ke Wang† ByteDance Seedarxiv.org | AI lab |
| ZebraLogic | 1 University of Washington 2 Allen Institute for AI 3 Stanford Universityarxiv.org | University, Nonprofit |
| ZeroBench | 1 University of Cambridge, 2 University of Alberta, Independent Researcher, 4 The University of Hong Kong, 5 University of Tübingen, 6 University of Oxford, 7 Auburn University.arxiv.org | University |
| τ-bench | Shunyu Yao∗ Noah Shinn Pedram Razavi Karthik Narasimhan Sierraarxiv.org | Other company |
| τ²-benchτ²-bench | Victor Barres ∗ Sierra … Honghua Dong ∗ † Sierra & University of Toronto & Vector Institute … Xujie Si University of Toronto & Vector Institute … Soham Ray Sierra … Karthik Narasimhan Sierraarxiv.org | Other company, University, Nonprofit |
Makers other than universities
| Maker | In its own words | Type |
|---|---|---|
| Abaka AI | Abaka AI provides comprehensive data processing support, covering the whole AI data lifecycleabaka.ai | Data and evaluation company |
| Artificial Analysis | Artificial Analysis is the independent benchmarking company for AI.artificialanalysis.ai | Data and evaluation company |
| Datacurve | Datacurve is pioneering the research and data collection infrastructure that will teach AI how to shoulder the work humanity has long endured.datacurve.ai | Data and evaluation company |
| Humanlaya Data | Humanlaya AI | The Standard in AI Benchmarkinghumanlaya.com | Data and evaluation company |
| Mercor | Mercor is organizing human intelligence to power the AI economy.mercor.com | Data and evaluation company |
| Proximal | Proximal is a new data company.proximal.ai | Data and evaluation company |
| Scale AI | We provide high-quality data and full-stack technologies that power the world's leading modelsscale.com | Data and evaluation company |
| Snorkel AI | Snorkel AI builds specialized training data, benchmarks, and evaluation environments that help frontier models and agents perform in high-stakes domains.snorkel.ai | Data and evaluation company |
| Surge AI | The RLHF data we generate embodies the richnesses and subtleties of the world …surgehq.ai | Data and evaluation company |
| Vals AI | The independent evaluator of artificial intelligence.vals.ai | Data and evaluation company |
| Alibaba | Alibaba Cloud provides Qwen models, a series of large language models (LLMs) and multimodal models (MLLMs), to the open-source community.alibabacloud.com | AI lab |
| Alibaba Qwen | Alibaba Cloud provides Qwen models, a series of large language models (LLMs) and multimodal models (MLLMs), to the open-source community.alibabacloud.com | AI lab |
| Amazon | Amazon Nova is a family of foundation models and services that delivers frontier intelligence and industry-leading price performance.aws.amazon.com | AI lab |
| Anthropic | Anthropic is an AI safety and research companyanthropic.com | AI lab |
| ByteDance Seed | Advancing the frontier of intelligence, in service of humanityseed.bytedance.com | AI lab |
| Cognition | Learn about Cognition, the applied AI lab behind Devin, and our mission to expand human capacity through autonomous software engineering.cognition.com | AI lab |
| Cohere | Cohere builds foundational models and AI solutions that help teams turn everyday effort into extraordinary impact.cohere.com | AI lab |
Our mission is to organize the world’s information and make it universally accessible and usefulabout.google | AI lab | |
| Google DeepMind | Google DeepMind brings together two of the world's leading AI labs — Google Brain and DeepMind — into a single, focused team led by our CEO Demis Hassabis.deepmind.google | AI lab |
| Meta | Build with Meta's AI models and tools.dev.meta.ai | AI lab |
| Microsoft Research | Microsoft Research conducts fundamental science and technology research that benefits humanity, advances AI and state-of-the-art computing, and creates new foundations and breakthroug…microsoft.com | AI lab |
| Moonshot AI | Welcome to Moonshot AI. Our mission is to seek the optimal conversion from energy to intelligence.moonshot.ai | AI lab |
| NeoCognition | NeoCognition is an AI agent lab for specialized intelligence.neocognition.io | AI lab |
| OpenAI | OpenAI is an AI research and deployment company. Our mission is to ensure that artificial general intelligence benefits all of humanity.openai.com | AI lab |
| Shanghai AI Laboratory | 上海人工智能实验室是我国人工智能领域的新型科研机构shlab.org.cn | AI lab |
| StepFun | 阶跃星辰坚定自研超级模型stepfun.com | AI lab |
| Zhipu AI | With the mission of 'Teach machines to think like humans, benefit humanity with reliable AI', Zhipu is committed to pioneering the next generation of cognitive intelligence models, with a strong focus on innovation in China.zhipuai.cn | AI lab |
| 2077AI | The 2077AI Foundation, is at the forefront of AI data standardization and progression.2077ai.com | Nonprofit |
| Ai2 | We are a Seattle based non-profit AI research institute founded in 2014 by the late Paul Allen.allenai.org | Nonprofit |
| ARC Prize Foundation | The ARC Prize Foundation is a non-profit dedicated to accelerating the development of Artificial General Intelligence (AGI).arcprize.org | Nonprofit |
| Center for AI Safety | Our mission is to reduce societal-scale risks from artificial intelligence.safe.ai | Nonprofit |
| ELLIS Institute Tübingen | Founded in 2023, the ELLIS Institute Tübingen has established itself as a leading center for foundational AI research …institute-tue.ellis.eu | Nonprofit |
| EvalSys | EvalSys is an evolving open-source community on a mission to track and advance model agentic capabilities.evalsys.org | Nonprofit |
| Laude Institute | Built by and for impact researchers, Laude Institute operates at the intersection of academia and industry to catalyze research that reaches people's hands.laude.org | Nonprofit |
| M-A-P | Multimodal Art Projection (M-A-P) is an open-source AI research community.m-a-p.ai | Nonprofit |
| Max Planck Institute for Security and Privacy | Our mission is to design, build, and analyze security and privacy technologies from foundations through systems to society.mpi-sp.org | Nonprofit |
| Mila – Québec AI Institute | Mila acquired the status of non-profit organization in 2018mila.quebec | Nonprofit |
| National Institutes of Health | A part of the U.S. Department of Health and Human Services, NIH is the largest biomedical research agency in the world.nih.gov | Nonprofit |
| SciLifeLab | SciLifeLab is an institution for the advancement of molecular biosciences in Sweden, funded as a national research infrastructure by the Swedish government.scilifelab.se | Nonprofit |
| Vector Institute | Vector is an independent not-for-profit corporation that works closely with its partner universities …vectorinstitute.ai | Nonprofit |
| Aider | AI pair programming in your terminalaider.chat | Other company |
| All Hands AI | We build AI software development agents for everyone, in the open.github.com | Other company |
| Databricks | Databricks is the data and AI companydatabricks.com | Other company |
| HSBC | Headquartered in London, HSBC is one of the largest banking and financial services organisations in the world.hsbc.com | Other company |
| HubSpot | HubSpot's customer platform includes all the marketing, sales, customer service, and CRM software you need to grow your business.hubspot.com | Other company |
| IN.AI Research | We focus on developing and evaluating intelligent agents.in.ai | Other company |
| LobeHub | LobeHub brings Super-Agents onto your team.lobehub.com | Other company |
| Mindverse AI | We Create AI as Your Digital Selfmindverse.ai | Other company |
| NIO | We are more than an automotive company.nio.com | Other company |
| Sierra | Sierra helps the great companies of the world show up at their best.sierra.ai | Other company |
| Simular | Simular is a research-driven company chasing one goal: full machine autonomy.simular.ai | Other company |
| UniPat AI | Our mission is to accelerate AI's evolution towards real-world automation. The next leap—from capable models to productive and trustworthy systems—comes from training AI in realistic scenarios.unipat.ai | Other company |
| Uniphore | Uniphore | The Business AI Companyuniphore.com | Other company |
| xbench | xbench is HSG’s evergreen benchmark for AI agents.hsgcap.com | Other company |
| Zapier | As the leader in easy automation, Zapier empowers businesses to automate workflows and move data across 9,000+ apps .zapier.com | Other company |
| Codeforces | I focused on three areas, which are being developed to the present day: contests (rounds and championships), social network (communication: blogs, comments, votes) and trainings.codeforces.com | Competition |
| Harvard-MIT Mathematics Tournament | To engage a diverse community of students and support them in reaching beyond traditional math curriculumshmmt.org | Competition |
| Mathematical Association of America | You may learn more about the AIME and our invitational competitions here.maa.org | Competition |
Sources
- about.googleabout.google/company-info
- aider.chataider.chat
- aider.chataider.chat/2024/12/21/polyglot.html
- DeepSeek, Jan 20, 2025DeepSeek-R1 Release
- DeepSeek, Mar 25, 2025DeepSeek-V3-0324 Release
- DeepSeek, May 28, 2025DeepSeek-R1-0528 Release
- DeepSeek, Aug 21, 2025DeepSeek-V3.1 Release
- DeepSeek, Sep 22, 2025DeepSeek-V3.1-Terminus
- DeepSeek, Sep 29, 2025Introducing DeepSeek-V3.2-Exp
- DeepSeek, Dec 1, 2025DeepSeek-V3.2 Release
- DeepSeek, Apr 24, 2026DeepSeek V4 Preview Release
- DeepSeek, Aug 13, 2026DeepSeek-V4-Pro GA Release
- DeepSeek, Sep 10, 2026DeepSeek-V4.1-Flash: Smarter, Faster, More Efficient
- DeepSeek, Oct 17, 2026DeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made Real
- arcprize.orgarcprize.org/about
- arcprize.orgarcprize.org/blog/announcing-arc-agi-2-and-arc-prize-2025
- artificialanalysis.aiartificialanalysis.ai/about
- artificialanalysis.aiartificialanalysis.ai/evaluations/gdpval-aa
- arxiv.orgarxiv.org/abs/1911.01547v1
- arxiv.orgarxiv.org/abs/2009.03300v1
- arxiv.orgarxiv.org/abs/2110.14168v1
- arxiv.orgarxiv.org/abs/2305.20050v1
- arxiv.orgarxiv.org/abs/2310.02255v1
- arxiv.orgarxiv.org/abs/2311.07911v1
- arxiv.orgarxiv.org/abs/2311.12022v1
- arxiv.orgarxiv.org/abs/2311.16502v1
- arxiv.orgarxiv.org/abs/2403.07974v1
- arxiv.orgarxiv.org/abs/2405.21075v1
- arxiv.orgarxiv.org/abs/2406.01574v1
- arxiv.orgarxiv.org/abs/2406.08035v1
- arxiv.orgarxiv.org/abs/2406.12045v1
- arxiv.orgarxiv.org/abs/2406.18521v1
- arxiv.orgarxiv.org/abs/2407.13168v1
- arxiv.orgarxiv.org/abs/2409.02813v1
- arxiv.orgarxiv.org/abs/2411.04368v1
- arxiv.orgarxiv.org/abs/2411.07140v1
- arxiv.orgarxiv.org/abs/2412.07626v1
- arxiv.orgarxiv.org/abs/2412.15204v1
- arxiv.orgarxiv.org/abs/2501.13826v1
- arxiv.orgarxiv.org/abs/2501.14249v1
- arxiv.orgarxiv.org/abs/2501.17399v1
- arxiv.orgarxiv.org/abs/2502.01100v1
- arxiv.orgarxiv.org/abs/2502.09696v1
- arxiv.orgarxiv.org/abs/2504.01848v1
- arxiv.orgarxiv.org/abs/2504.07981v1
- arxiv.orgarxiv.org/abs/2504.12516v1
- arxiv.orgarxiv.org/abs/2504.19314v1
- arxiv.orgarxiv.org/abs/2504.21798v1
- arxiv.orgarxiv.org/abs/2505.08775v1
- arxiv.orgarxiv.org/abs/2506.01062v1
- arxiv.orgarxiv.org/abs/2506.02548v1
- arxiv.orgarxiv.org/abs/2506.07982v1
- arxiv.orgarxiv.org/abs/2507.02833v1
- arxiv.orgarxiv.org/abs/2508.00828v1
- arxiv.orgarxiv.org/abs/2508.07999v1
- arxiv.orgarxiv.org/abs/2509.16941v1
- arxiv.orgarxiv.org/abs/2509.24002v1
- arxiv.orgarxiv.org/abs/2510.25726v1
- arxiv.orgarxiv.org/abs/2511.01846v1
- arxiv.orgarxiv.org/abs/2512.12730v1
- arxiv.orgarxiv.org/abs/2601.06521v1
- arxiv.orgarxiv.org/abs/2601.14242v1
- arxiv.orgarxiv.org/abs/2603.08640v1
- arxiv.orgarxiv.org/abs/2604.06132v1
- arxiv.orgarxiv.org/abs/2605.11086v1
- arxiv.orgarxiv.org/abs/2605.26548v1
- arxiv.orgarxiv.org/abs/2606.05405v1
- arxiv.orgarxiv.org/abs/2606.29537v1
- aws.amazon.comaws.amazon.com/nova
- Google, Feb 19, 2026Gemini 3.1 Pro: A smarter model for your most complex tasks
- Google, Sep 30, 2026Gemini 4 Argon: our next era of frontier intelligence
- Google, Mar 25, 2025Gemini 2.5: Our most intelligent AI model
- Google, Feb 5, 2025Gemini 2.0 is now available to everyone
- Google, Jun 5, 2025Try the latest Gemini 2.5 Pro before general availability.
- Google, May 6, 2025Build rich, interactive web apps with an updated Gemini 2.5 Pro
- Google, Nov 18, 2025A new era of intelligence with Gemini 3
- codeforces.comcodeforces.com/5years
- cognition.comcognition.com/about
- cognition.comcognition.com/blog/frontier-code-2.0
- cohere.comcohere.com/about
- datacurve.aidatacurve.ai
- deepmind.googledeepmind.google/about
- deepswe.datacurve.aideepswe.datacurve.ai/blog/deepswe-v1-1
- dev.meta.aidev.meta.ai
- evalsys.orgevalsys.org
- github.comgithub.com/All-Hands-AI
- github.comgithub.com/MoonshotAI/Kimi-k1.5
- harborframework.comharborframework.com
- hmmt-archive.s3.amazonaws.comhmmt-archive.s3.amazonaws.com/tournaments/2025/feb/team/problems.pdf
- huggingface.cohuggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507
- huggingface.cohuggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507
- huggingface.cohuggingface.co/datasets/ArtificialAnalysis/AA-LCR
- huggingface.cohuggingface.co/datasets/openai/MMMLU
- huggingface.cohuggingface.co/datasets/openai/graphwalks
- huggingface.cohuggingface.co/datasets/openai/mrcr
- huggingface.cohuggingface.co/moonshotai/Kimi-K2-Instruct-0905
- humanlaya.comhumanlaya.com
- institute-tue.ellis.euinstitute-tue.ellis.eu
- lobehub.comlobehub.com
- m-a-p.aim-a-p.ai
- maa.orgmaa.org/news/aime-thresholds-are-available
- matharena.aimatharena.ai/apex
- mila.quebecmila.quebec/en/about/about-mila
- Mistral, Oct 6, 2026Introducing Mistral Large 4
- Mistral, May 22, 2026Remote agents in Vibe. Powered by Mistral Medium 3.5.
- neocognition.ioneocognition.io
- openai.comopenai.com/about
- OpenAI, Nov 12, 2025GPT-5.1: A smarter, more conversational ChatGPT
- OpenAI, Jul 9, 2026GPT-5.6: Frontier intelligence that scales with your ambition
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- OpenAI, Feb 27, 2025Introducing GPT-4.5
- OpenAI, Aug 7, 2025Introducing GPT-5
- OpenAI, Dec 11, 2025Introducing GPT-5.2
- OpenAI, Mar 5, 2026Introducing GPT-5.4
- OpenAI, Apr 23, 2026Introducing GPT-5.5
- OpenAI, Apr 16, 2025Introducing OpenAI o3 and o4-mini
- OpenAI, Aug 13, 2024Introducing SWE-bench Verified
- proximal.aiproximal.ai
- Alibaba, Jan 28, 2025Qwen2.5-Max: Exploring the Intelligence of Large-scale MoE Model
- Alibaba, Apr 29, 2025Qwen3: Think Deeper, Act Faster
- Alibaba, Sep 24, 2025Qwen3-Max: Just Scale it
- Alibaba, Jan 26, 2026Pushing Qwen3-Max-Thinking Beyond its Limits
- Alibaba, Feb 16, 2026Qwen3.5: Towards Native Multimodal Agents
- Alibaba, Apr 2, 2026Qwen3.6-Plus: Towards Real World Agents
- Alibaba, Apr 18, 2026Qwen3.6-Max-Preview: Smarter, Sharper, Still Evolving
- Alibaba, May 20, 2026Qwen3.7: The Agent Frontier
- Alibaba, Aug 3, 2026Qwen3.8-Max: A New Bar for Coding and Cowork
- safe.aisafe.ai/about
- scale.comscale.com/about
- scale.comscale.com/blog/humanitys-last-exam-results
- scale.comscale.com/blog/mcp-atlas
- scale.comscale.com/blog/swe-bench-pro
- seed.bytedance.comseed.bytedance.com/en
- sierra.aisierra.ai
- snorkel.aisnorkel.ai
- surgehq.aisurgehq.ai/blog/chartography
- surgehq.aisurgehq.ai/products
- unipat.aiunipat.ai
- vectorinstitute.aivectorinstitute.ai/about
- 2077ai.com2077ai.com
- abaka.aiabaka.ai
- alibabacloud.comalibabacloud.com/en/solutions/generative-ai/qwen
- allenai.orgallenai.org/about
- Anthropic, Sep 1, 2026Introducing Claude Fable 5.1 and Claude Mythos 5.1
- Anthropic, Sep 22, 2026Introducing Claude Opus 5.5
- anthropic.comanthropic.com/company
- Anthropic, Feb 24, 2025Claude 3.7 Sonnet and Claude Code
- Anthropic, May 22, 2025Introducing Claude 4
- Anthropic, Jun 9, 2026Claude Fable 5 and Claude Mythos 5
- Anthropic, Aug 5, 2025Claude Opus 4.1
- Anthropic, Nov 24, 2025Introducing Claude Opus 4.5
- Anthropic, Feb 5, 2026Claude Opus 4.6
- Anthropic, Apr 16, 2026Introducing Claude Opus 4.7
- Anthropic, May 28, 2026Introducing Claude Opus 4.8
- Anthropic, Jul 24, 2026Introducing Claude Opus 5
- databricks.comdatabricks.com/blog/introducing-officeqa-benchmark-end-to-end-grounded-reasoning
- databricks.comdatabricks.com/company/about-us
- frontierswe.comfrontierswe.com/blog/v2
- hmmt.orghmmt.org
- hsbc.comhsbc.com/who-we-are
- hsgcap.comhsgcap.com
- hubspot.comhubspot.com
- in.aiin.ai
- Moonshot AI, Jul 11, 2025Kimi K2: Open Agentic Intelligence
- Moonshot AI, Jan 27, 2026Kimi K2.5: Visual Agentic Intelligence
- Moonshot AI, Apr 20, 2026Kimi K2.6: Advancing Open-Source Coding
- Moonshot AI, Nov 6, 2025Introducing Kimi K2 Thinking
- Moonshot AI, Jul 16, 2026Kimi K3: Open Frontier Intelligence
- laude.orglaude.org
- mercor.commercor.com
- microsoft.commicrosoft.com/en-us/research/about-microsoft-research
- mindverse.aimindverse.ai
- MiniMax, Jun 1, 2026MiniMax M3: Frontier Coding, 1M Context, Native Multimodality — All in One Model
- MiniMax, Jan 15, 2025MiniMax-01 is Now Open-Source: Scaling Lightning Attention for the AI Agent Era
- minimax.iominimax.io/news/minimax-m2
- MiniMax, Dec 23, 2025MiniMax M2.1: Significantly Enhanced Multi-Language Programming, Built for Real-World Complex Tasks
- MiniMax, Feb 12, 2026MiniMax M2.5: Built for Real-World Productivity.
- MiniMax, Mar 18, 2026MiniMax M2.7: Early Echoes of Self-Evolution
- MiniMax, Jun 16, 2025MiniMax-M1, the World's First Open-Source, Large-Scale, Hybrid-Attention Reasoning Model
- moonshot.aimoonshot.ai
- mpi-sp.orgmpi-sp.org
- nih.govnih.gov/about-nih
- nio.comnio.com/about
- scilifelab.sescilifelab.se/about-us
- shlab.org.cnshlab.org.cn/aboutus
- simular.aisimular.ai/about
- stepfun.comstepfun.com
- swebench.comswebench.com/multilingual.html
- tbench.aitbench.ai/news/announcement
- tbench.aitbench.ai/news/terminal-bench-science-0-1
- uniphore.comuniphore.com
- vals.aivals.ai/about
- zhipuai.cnzhipuai.cn/en/about
- xlang.aixlang.ai/blog/osworld-verified
- zapier.comzapier.com/about
- zapier.comzapier.com/blog/introducing-automationbench