Frontier Log

Claude Fable 5.2 vs GPT-6 Astra

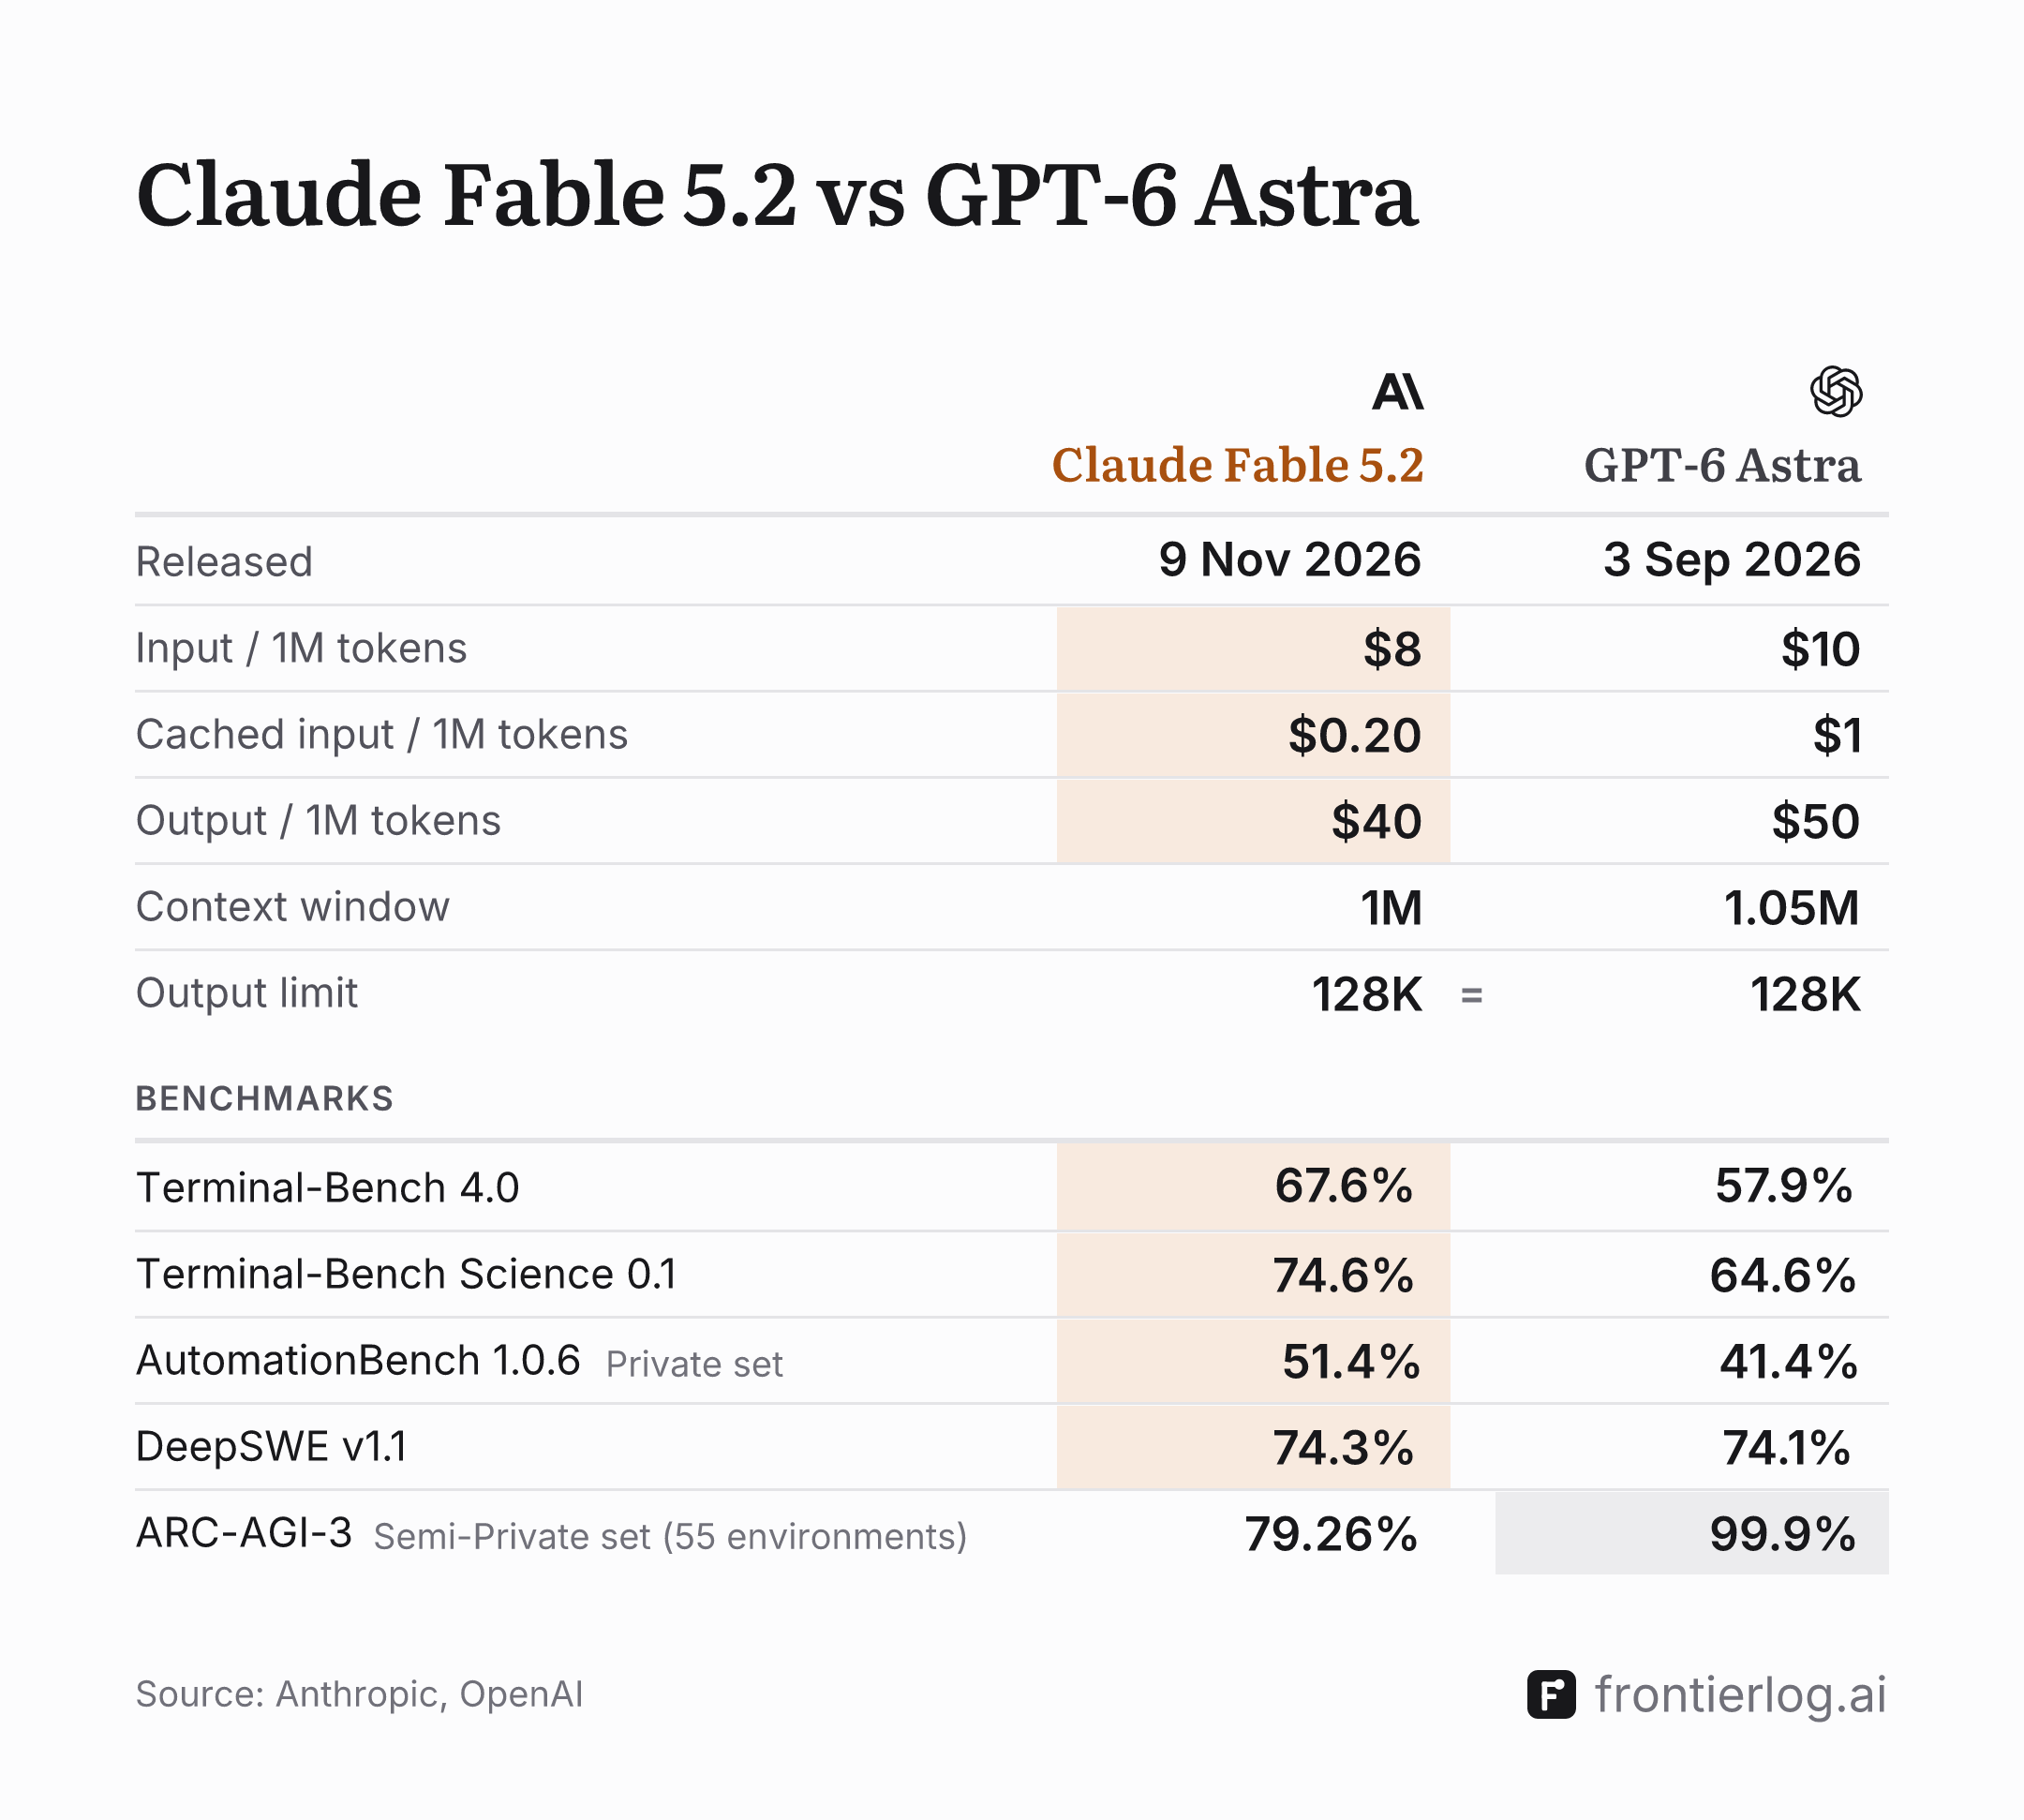
Claude Fable 5.2GPT-6 Astra
Released
Input / 1M tokens$8$10
Cached input / 1M tokens$0.20$1
Output / 1M tokens$40$50
Context window1M1.05M
Output limit128K128K
Benchmarks
Terminal-Bench 4.067.6%157.9%2
Terminal-Bench Science 0.174.6%364.6%4
AutomationBench 1.0.6 Private set51.4%541.4%6
DeepSWE v1.174.3%774.1%
ARC-AGI-3 Semi-Private set (55 environments)79.26%899.9%9

Download image

Claude Fable 5.2GPT-6 Astra
Other benchmarks
Humanity's Last Exam No tools, full set (2,500 questions)73.2%10No data
Humanity's Last Exam With tools, full set (2,500 questions)74.2%11No data
Humanity's Last Exam With tools, set not statedNo data57.2%12
SWE-bench Pro Set not stated93.0%13No data
GPQA DiamondNo data96.0%
BrowseCompNo data91.5%
ARC-AGI-2No data95.0%
OSWorld 2.1 Offline set (82 tasks), partial score89.3%14No data
OSWorld 2.1 Offline set (82 tasks), strict pass rate54.6%15No data
OSWorld 2.1 Offline set (82 tasks), scoring not statedNo data80.9%16
OSWorld 2.0 (v2026.08.08) Offline set, partial scoreNo data72.6%
FrontierCode 1.1 Main setNo data53.3%17
FrontierCode 1.1 Extended setNo data64.5%18
FrontierSWE v269.9%19No data
ARC-AGI-1 Semi-Private set (100 tasks)No data98.5%
ARC-AGI-1 Public set (400 tasks)No data98.5%
Chartography No tools73.4%20No data
Chartography With tools91.6%21No data
SEC-bench Pro, release not statedNo data85.4%
Agents' Last Exam v1 Score, all tasks (152)No data59.3%22
MMMU-Pro Vision settingNo data86.7%23

Notes

  1. Terminal-Bench 4.0, Claude Fable 5.2: Claude Code in --bare mode · max effort · 10 trials per task · no internet access · safeguards on
  2. Terminal-Bench 4.0, GPT-6 Astra: high effort
  3. Terminal-Bench Science 0.1, Claude Fable 5.2: Claude Code in --bare mode · highest available effort · averaged over 10 trials per task, per the system card · no internet access, per the system card · safeguards on, flagged requests answered by a fallback model (1.3% of requests), per the system card · standard error ±4.3 points, per the system card
  4. Terminal-Bench Science 0.1, GPT-6 Astra: max effort
  5. AutomationBench 1.0.6, Private set, Claude Fable 5.2: Run by Zapier · highest available effort · safeguards on · set and release 1.0.6 named in the system card, which prints the same figure
  6. AutomationBench 1.0.6, Private set, GPT-6 Astra: Run by Zapier · highest score at any effort · set named in the GPT-6.1 Sol post, which prints the same figure
  7. DeepSWE v1.1, Claude Fable 5.2: average of 5 trials
  8. ARC-AGI-3, Semi-Private set (55 environments), Claude Fable 5.2: Run by ARC Prize Foundation · Standard harness · high effort
  9. ARC-AGI-3, Semi-Private set (55 environments), GPT-6 Astra: OpenAI's Responses API harness, which changes two settings (retained reasoning and compaction, per OpenAI's ARC-AGI-3 harness post)
  10. Humanity's Last Exam, No tools, full set (2,500 questions), Claude Fable 5.2: max effort · thinking set to auto · average of 5 trials · 980k-token task budget per attempt, no context compaction · Claude Opus 4.6 as model grader
  11. Humanity's Last Exam, With tools, full set (2,500 questions), Claude Fable 5.2: highest available effort, max effort, per the system card · thinking set to auto, per the system card · average of 5 trials, per the system card · web search, web fetch, programmatic tool calling and code execution, HLE sources blocklisted, per the system card · 980k-token task budget per attempt, no context compaction, per the system card · Claude Opus 4.6 as model grader, flagged transcripts reviewed by Claude Opus 5, confirmed cheating graded incorrect, per the system card · safeguards on
  12. Humanity's Last Exam, With tools, set not stated, GPT-6 Astra: maximum at any effort · run in OpenAI's research environment or via its API
  13. SWE-bench Pro, Set not stated, Claude Fable 5.2: max effort · adaptive thinking · average of 5 trials
  14. OSWorld 2.1, Offline set (82 tasks), partial score, Claude Fable 5.2: highest available effort · safeguards on
  15. OSWorld 2.1, Offline set (82 tasks), strict pass rate, Claude Fable 5.2: max effort · mean of 5 attempts
  16. OSWorld 2.1, Offline set (82 tasks), scoring not stated, GPT-6 Astra: max effort
  17. FrontierCode 1.1, Main set, GPT-6 Astra: run with a developer message similar to part of its developer message in Codex
  18. FrontierCode 1.1, Extended set, GPT-6 Astra: run with a developer message similar to part of its developer message in Codex
  19. FrontierSWE v2, Claude Fable 5.2: Run by Proximal · Proximal's agent harness · highest available effort · mean of 5 trials per task, per the system card · 20-hour budget · safeguards on
  20. Chartography, No tools, Claude Fable 5.2: highest available effort · safeguards on
  21. Chartography, With tools, Claude Fable 5.2: max effort · adaptive thinking · average of 5 runs · container and image-cropping tool · Gemini 3.5 Flash grader
  22. Agents' Last Exam v1, Score, all tasks (152), GPT-6 Astra: harness not stated · best of any effort
  23. MMMU-Pro, Vision setting, GPT-6 Astra: max effort

Related

All comparisons