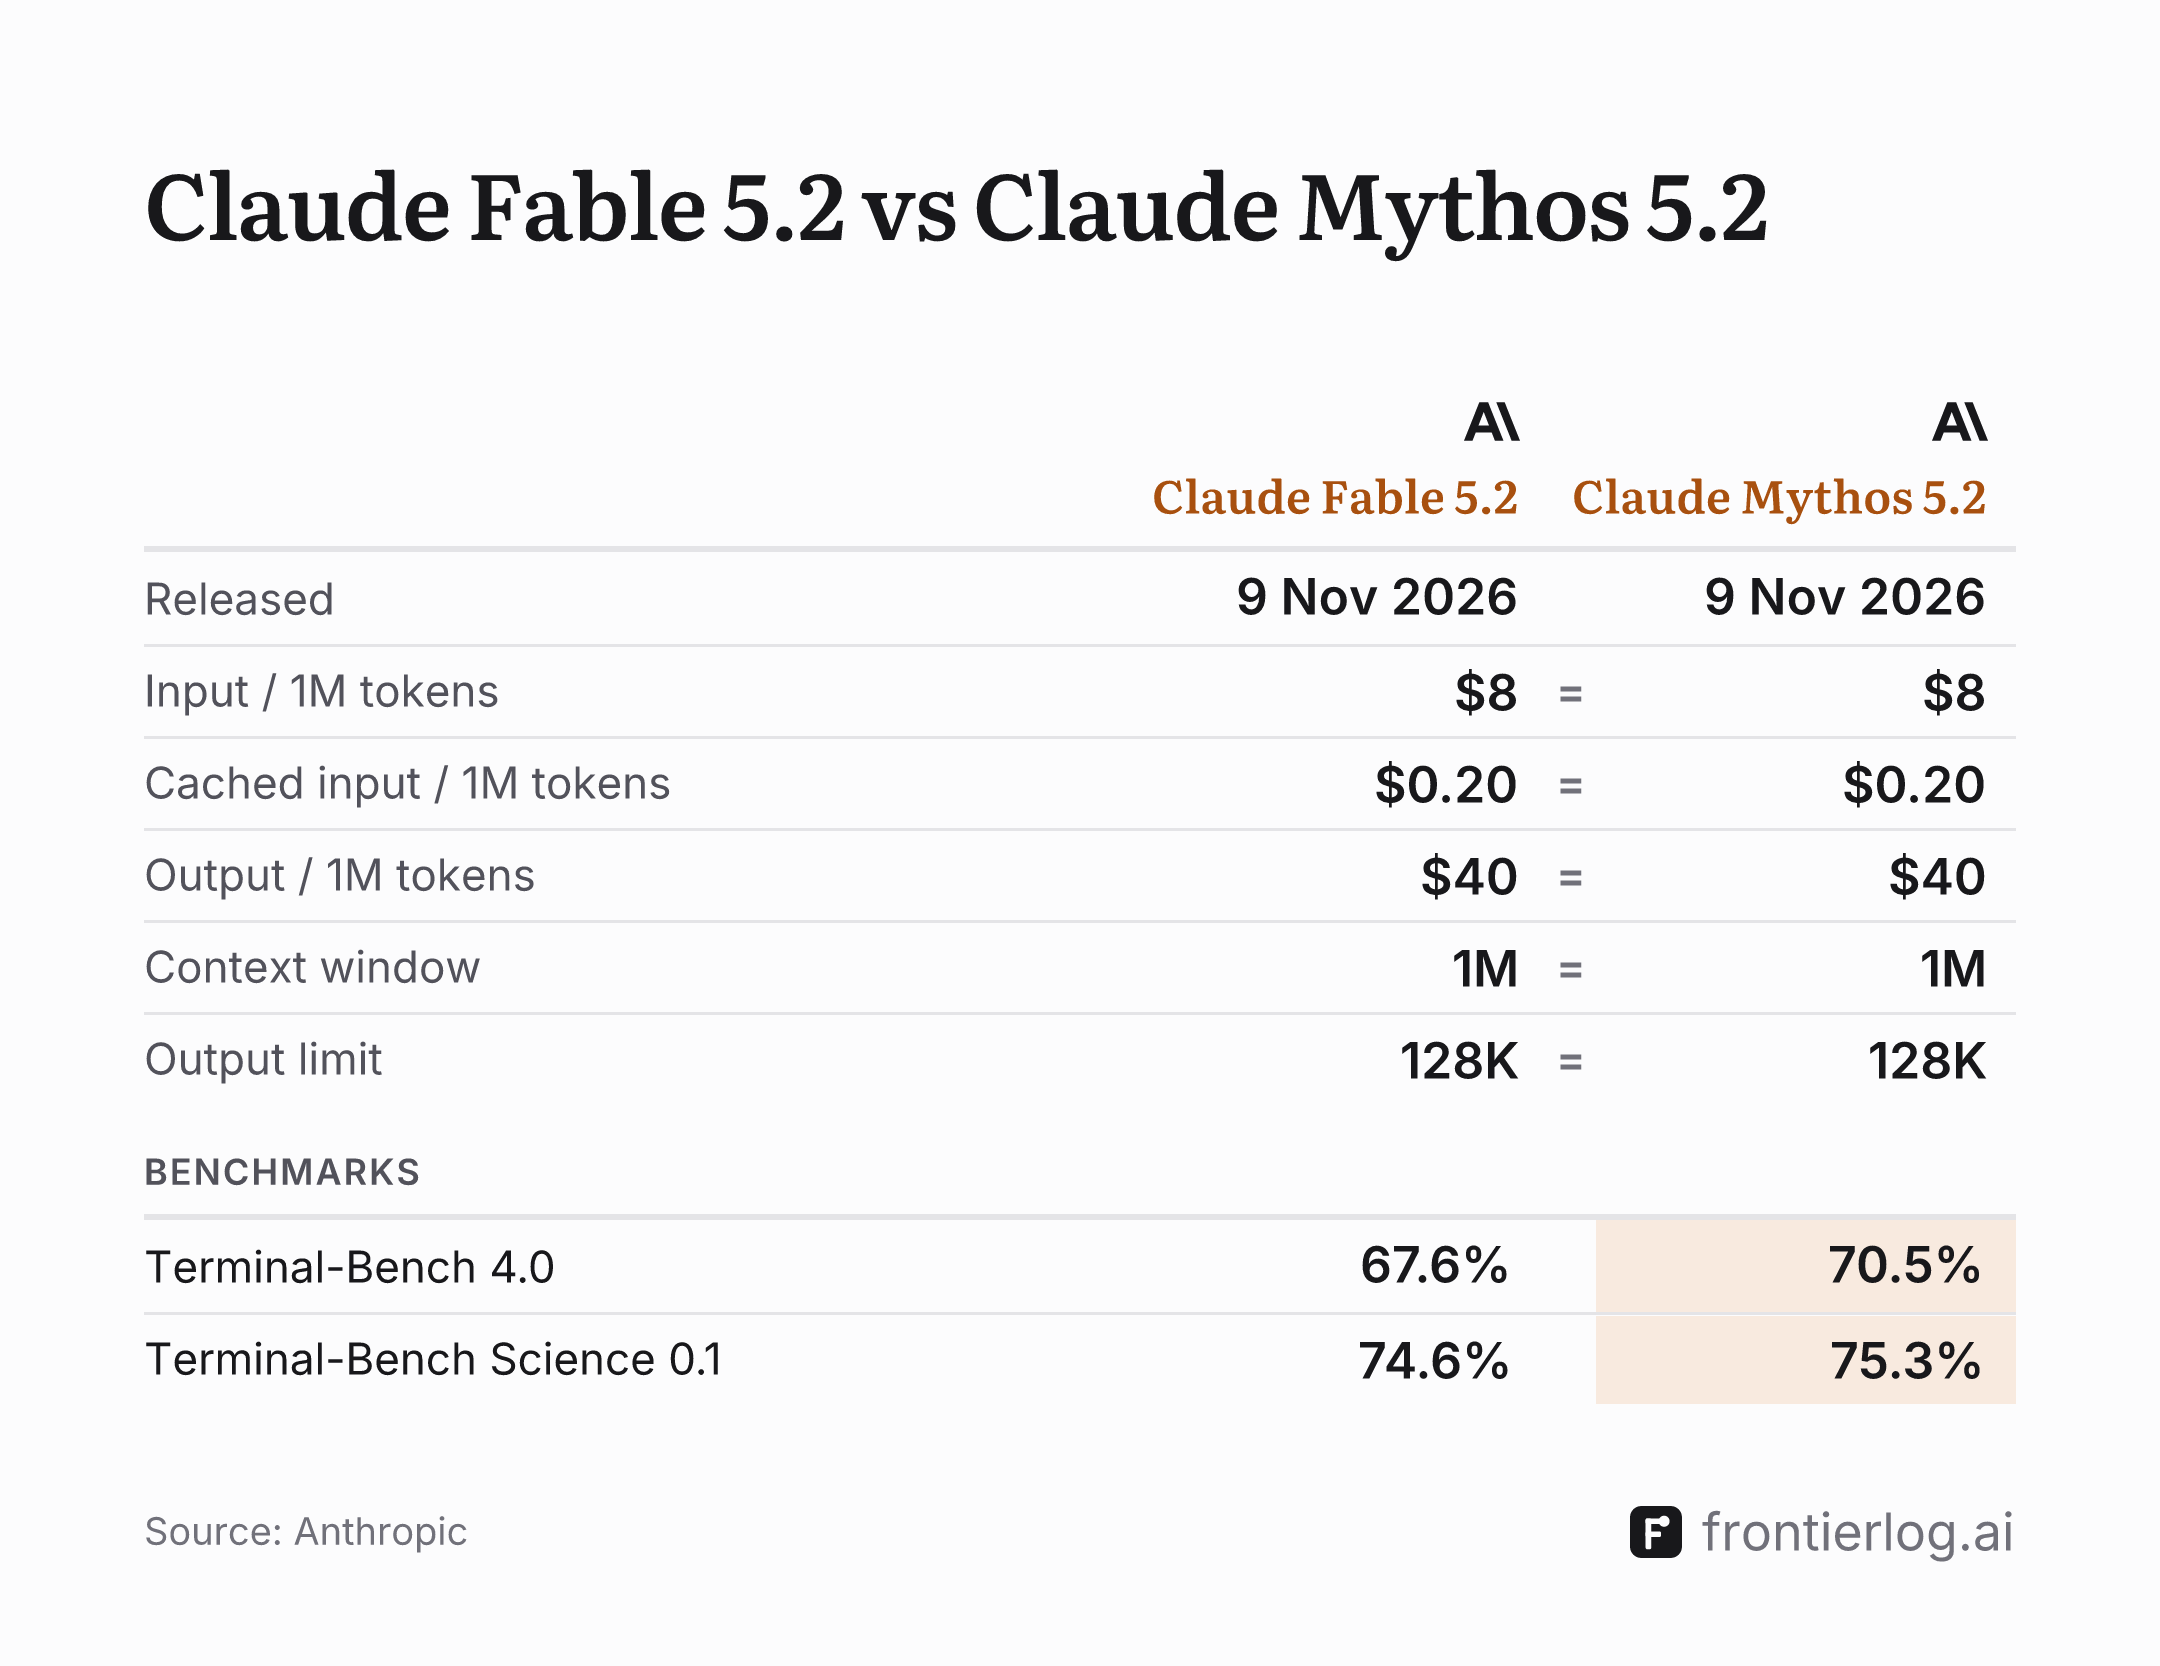
Terminal-Bench 4.0, Claude Fable 5.2: Claude Code in --bare mode · max effort · 10 trials per task · no internet access · safeguards on
Terminal-Bench 4.0, Claude Mythos 5.2: Claude Code in --bare mode · max effort · 10 trials per task · without safeguards
Terminal-Bench Science 0.1, Claude Fable 5.2: Claude Code in --bare mode · highest available effort · averaged over 10 trials per task, per the system card · no internet access, per the system card · safeguards on, flagged requests answered by a fallback model (1.3% of requests), per the system card · standard error ±4.3 points, per the system card
Terminal-Bench Science 0.1, Claude Mythos 5.2: Claude Code in --bare mode · highest available effort · averaged over 10 trials per task, per the system card · no internet access, per the system card · without safeguards, per the system card · standard error ±4.3 points, per the system card
Humanity's Last Exam, With tools, full set (2,500 questions), Claude Fable 5.2: highest available effort, max effort, per the system card · thinking set to auto, per the system card · average of 5 trials, per the system card · web search, web fetch, programmatic tool calling and code execution, HLE sources blocklisted, per the system card · 980k-token task budget per attempt, no context compaction, per the system card · Claude Opus 4.6 as model grader, flagged transcripts reviewed by Claude Opus 5, confirmed cheating graded incorrect, per the system card · safeguards on
AutomationBench 1.0.6, Private set, Claude Fable 5.2: Run by Zapier · highest available effort · safeguards on · set and release 1.0.6 named in the system card, which prints the same figure
FrontierSWE v2, Claude Fable 5.2: Run by Proximal · Proximal's agent harness · highest available effort · mean of 5 trials per task, per the system card · 20-hour budget · safeguards on
DeepSWE v1.1, Claude Fable 5.2: average of 5 trials
Chartography, With tools, Claude Fable 5.2: max effort · adaptive thinking · average of 5 runs · container and image-cropping tool · Gemini 3.5 Flash grader