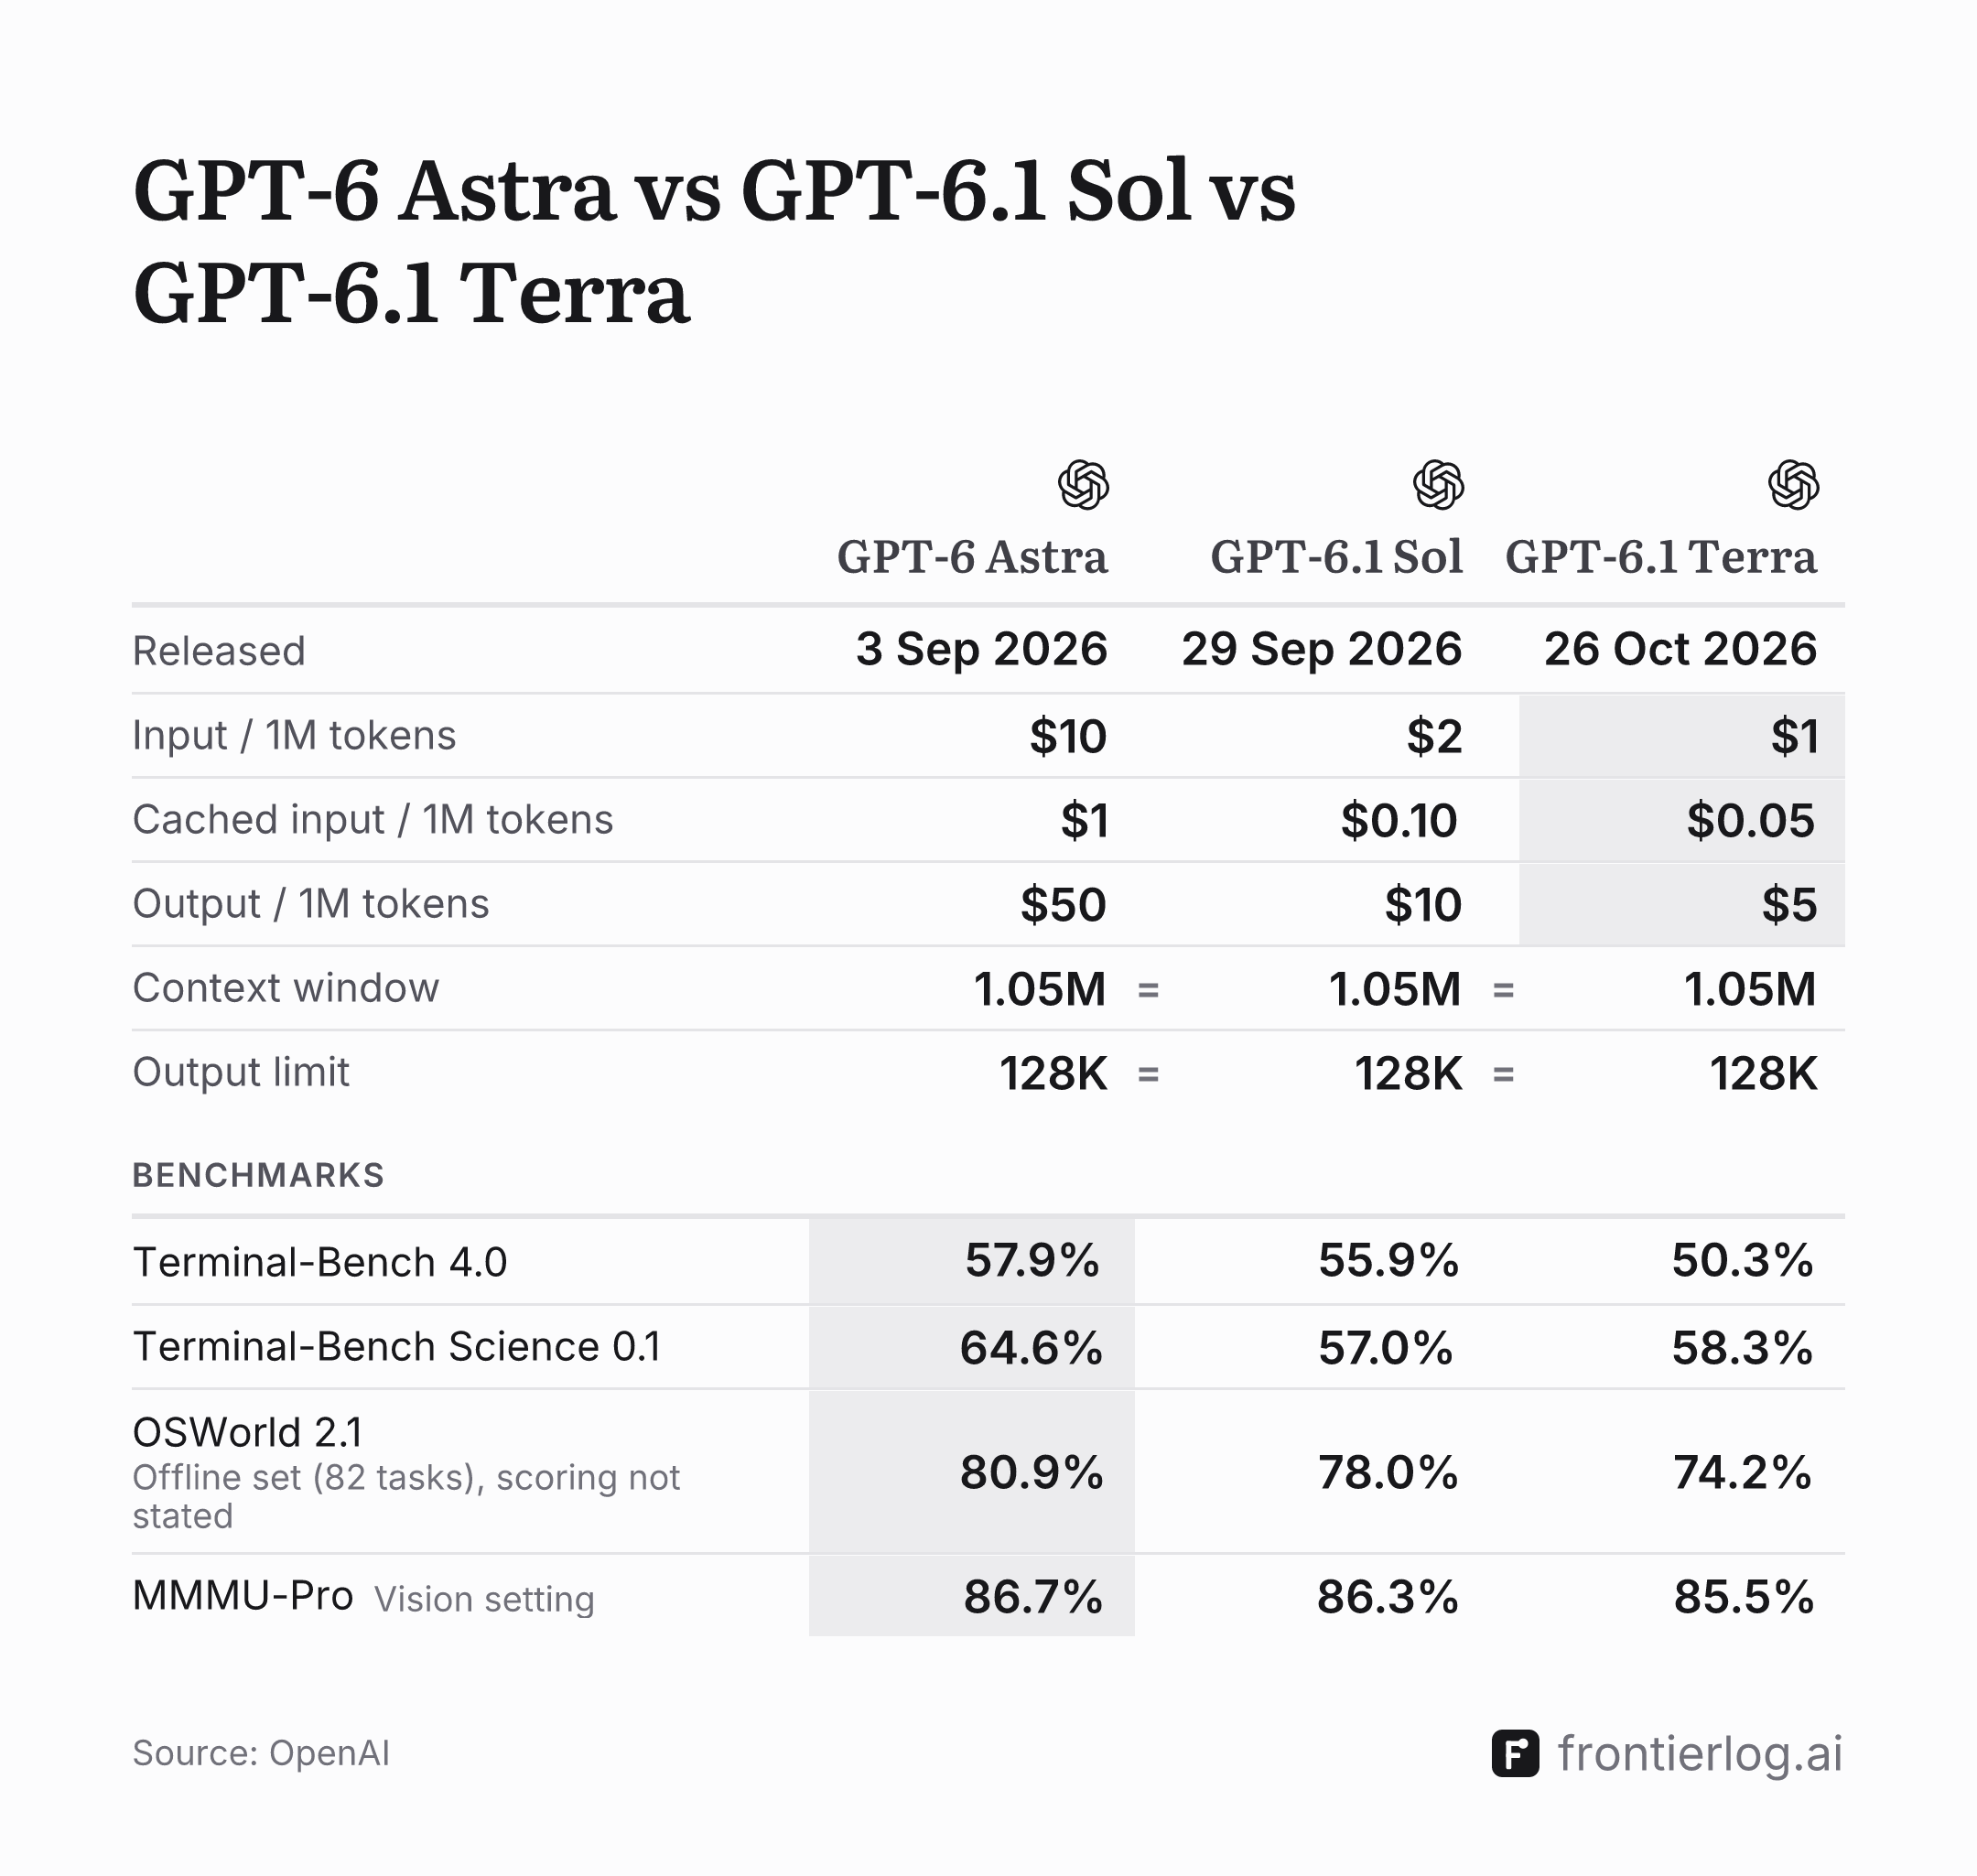
GPT-6 Astra vs GPT-6.1 Sol vs GPT-6.1 Terra GPT-6 Astra GPT-6.1 Sol GPT-6.1 Terra What it is What it is OpenAI's most capable model, for the most demanding work. An upgrade to GPT-6 Sol with near-Astra performance for complex work at a lower cost. A fast, efficient model for visual reasoning, computer use and writing. Plans Plans Pro in Chat, Work and Codex, and Plus in Work and Codex. Plus and Pro, in Work and Codex. Plus and Pro, in Work and Codex.
Sources: GPT-6 Astra · Introducing GPT-6.1 Sol · GPT-6.1 Sol · GPT-6.1 Terra · help.openai.com · Introducing GPT-6.1 Terra
Download image
Notes Terminal-Bench 4.0 , GPT-6 Astra: high effortTerminal-Bench 4.0 , GPT-6.1 Sol: max effortTerminal-Bench 4.0 , GPT-6.1 Terra: maximum effortTerminal-Bench Science 0.1 , GPT-6 Astra: max effortTerminal-Bench Science 0.1 , GPT-6.1 Sol: max effortTerminal-Bench Science 0.1 , GPT-6.1 Terra: max effortOSWorld 2.1, Offline set (82 tasks), scoring not stated , GPT-6 Astra: max effortOSWorld 2.1, Offline set (82 tasks), scoring not stated , GPT-6.1 Sol: max effortOSWorld 2.1, Offline set (82 tasks), scoring not stated , GPT-6.1 Terra: max effortMMMU-Pro, Vision setting , GPT-6 Astra: max effortMMMU-Pro, Vision setting , GPT-6.1 Sol: max effortMMMU-Pro, Vision setting , GPT-6.1 Terra: max effortHumanity's Last Exam, With tools, set not stated , GPT-6 Astra: maximum at any effort · run in OpenAI's research environment or via its APIAutomationBench 1.0.6, Private set , GPT-6 Astra: Run by Zapier · highest score at any effort · set named in the GPT-6.1 Sol post, which prints the same figureAutomationBench 1.0.6, Private set , GPT-6.1 Sol: Run by Zapier · max effortOSWorld 2.0 (v2026.08.08), Offline set, partial score , GPT-6.1 Sol: max effortFrontierCode 1.1, Main set , GPT-6 Astra: run with a developer message similar to part of its developer message in CodexFrontierCode 1.1, Extended set , GPT-6 Astra: run with a developer message similar to part of its developer message in CodexDeepSWE v1.1 , GPT-6.1 Sol: high effortARC-AGI-3, Semi-Private set (55 environments) , GPT-6 Astra: OpenAI's Responses API harness, which changes two settings (retained reasoning and compaction, per OpenAI's ARC-AGI-3 harness post)Agents' Last Exam v1, Score, all tasks (152) , GPT-6 Astra: harness not stated · best of any effortAgents' Last Exam v1, Measure and set not stated , GPT-6.1 Sol: harness not stated · max effortAgents' Last Exam v1, Measure and set not stated , GPT-6.1 Terra: harness not stated · max effortAll comparisons