Gemini 4 Neon vs GPT-6.2 Sol
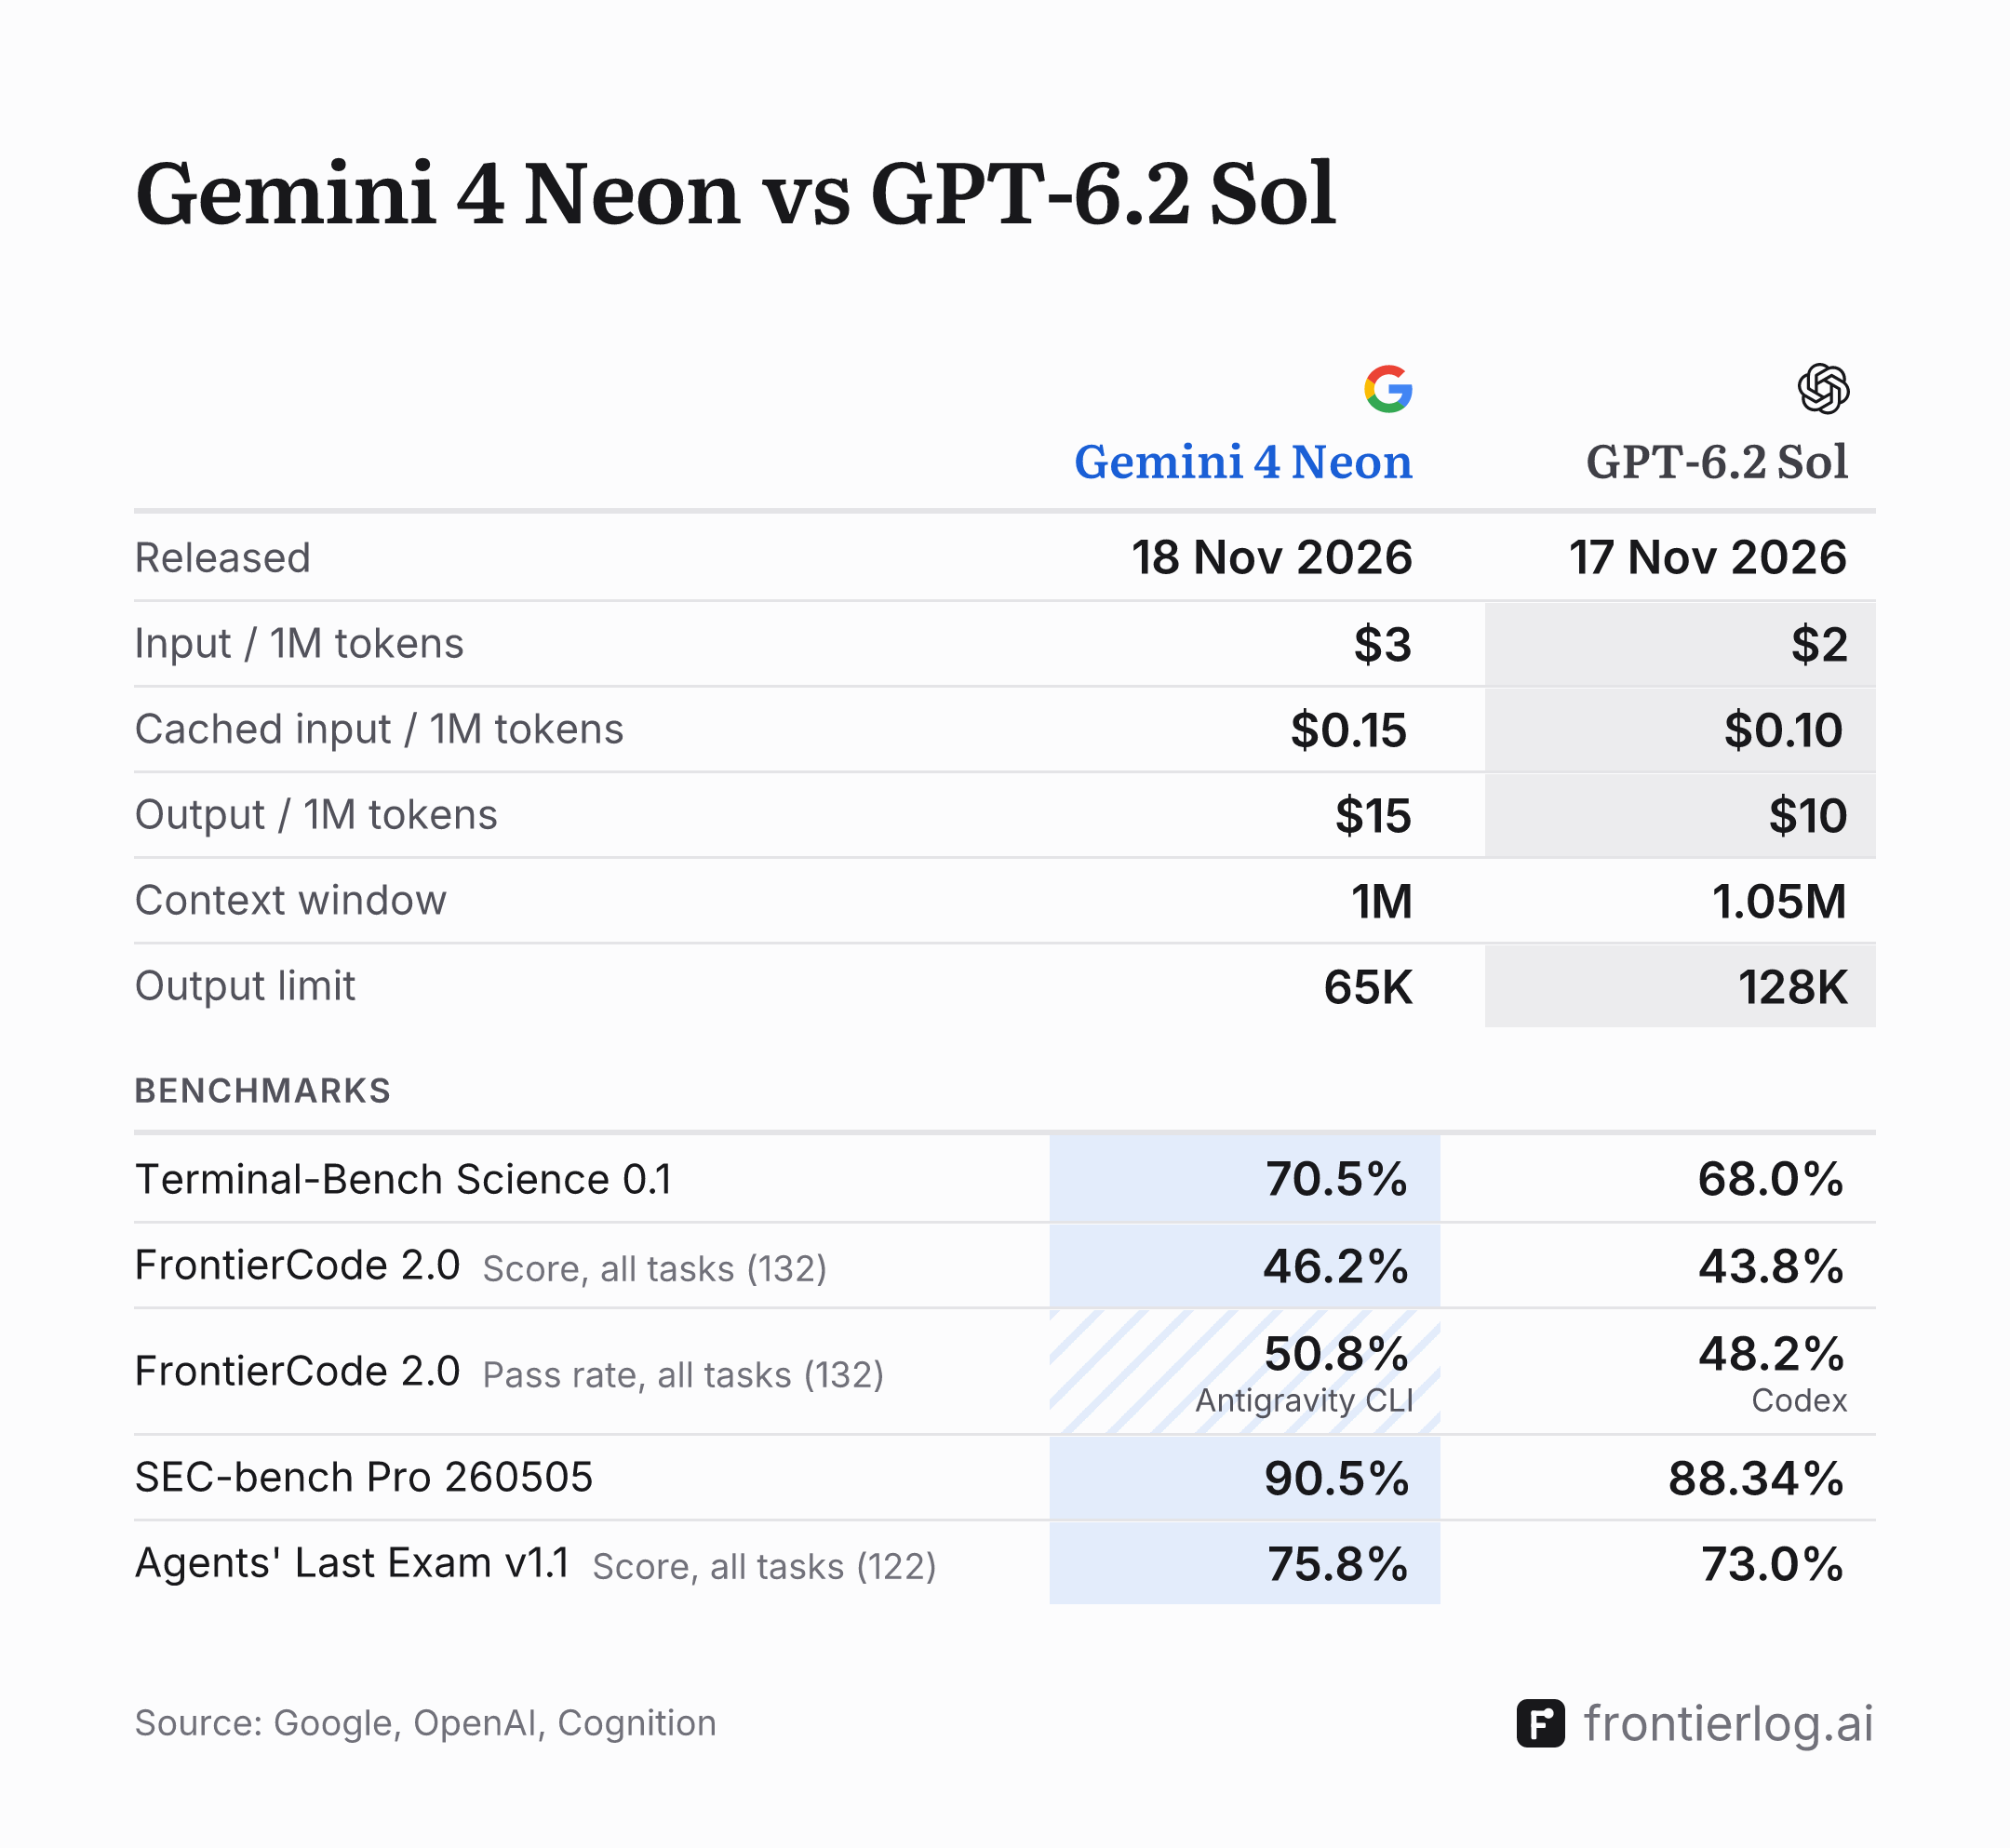
| Gemini 4 Neon | GPT-6.2 Sol | |
|---|---|---|
| Released | ||
| Lineup | Carbon = Argon › Neon › Hydrogen | Astra › Sol › Terra › Luna |
| Input / 1M tokens | $3 | $2 |
| Cached input / 1M tokens | $0.15 | $0.10 |
| Output / 1M tokens | $15 | $10 |
| Context window | 1M | 1.05M |
| Output limit | 65K | 128K |
| Benchmarks | ||
| Terminal-Bench Science 0.1 | 70.5%1 | 68.0%2 |
| FrontierCode 2.0 Score, all tasks (132) | 46.2%3 | 43.8%4 |
| FrontierCode 2.0 Pass rate, all tasks (132) | 50.8%5Antigravity CLI | 48.2%6Codex |
| SEC-bench Pro 260505 | 90.5%7 | 88.34%8 |
| Agents' Last Exam v1.1 Score, all tasks (122) | 75.8%9 | 73.0%10 |
| Gemini 4 Neon | GPT-6.2 Sol | |
|---|---|---|
| Other benchmarks | ||
| HLE-Diamond No tools | 71.3%11 | No data |
| GPQA Diamond | No data | 96.0%12 |
| Terminal-Bench 4.1 | No data | 61.5%13 |
| AutomationBench, release not specified Private set | 56.3%14 | No data |
| Chartography No tools | 73.5%15 | No data |
| GraphWalks BFS, 256K + 1M problems | 95.2%16 | No data |
| ExploitGym Mitigations off, score | 48.3%17 | No data |
Notes
- Terminal-Bench Science 0.1, Gemini 4 Neon: mini-swe-agent vision harness · highest thinking · average of 5 attempts per task
- Terminal-Bench Science 0.1, GPT-6.2 Sol: max effort
- FrontierCode 2.0, Score, all tasks (132), Gemini 4 Neon: Run by Cognition · high thinking · set and measure of the official public leaderboard the evaluation methodology cites
- FrontierCode 2.0, Score, all tasks (132), GPT-6.2 Sol: Run by Cognition · max effort
- FrontierCode 2.0, Pass rate, all tasks (132), Gemini 4 Neon: Cognition’s leaderboard, 18 Nov 2026 · Antigravity CLI · high effort
- FrontierCode 2.0, Pass rate, all tasks (132), GPT-6.2 Sol: Cognition’s leaderboard, 18 Nov 2026 · Codex · max effort
- SEC-bench Pro 260505, Gemini 4 Neon: Antigravity harness · pass@1, mean of 3 attempts · 183-task JavaScript engine split (May 2026) · LLM judge for crashes in both builds · safety filters off
- SEC-bench Pro 260505, GPT-6.2 Sol: pass@1
- Agents' Last Exam v1.1, Score, all tasks (122), Gemini 4 Neon: Antigravity-CLI version 1.4.8 harness · highest thinking · 5-hour window · safety filters on
- Agents' Last Exam v1.1, Score, all tasks (122), GPT-6.2 Sol: max effort
- HLE-Diamond, No tools, Gemini 4 Neon: Run by Artificial Analysis · GPT-5.6 Luna (medium) judge with the official HLE judge prompt, per Artificial Analysis’s methodology
- GPQA Diamond, GPT-6.2 Sol: no tools
- Terminal-Bench 4.1, GPT-6.2 Sol: Stanford University and Laude Institute’s leaderboard, 18 Nov 2026 · Codex · max effort
- AutomationBench, release not specified, Private set, Gemini 4 Neon: Run by Zapier · set of the official public leaderboard the evaluation methodology cites
- Chartography, No tools, Gemini 4 Neon: highest thinking
- GraphWalks, BFS, 256K + 1M problems, Gemini 4 Neon: highest thinking · 200 problems between 256K and 1M tokens
- ExploitGym, Mitigations off, score, Gemini 4 Neon: Antigravity harness · single attempt per task · no internet access · 10h time cap per task · safety filters off · mitigations off (the default setting), per the model evaluation