Claude Opus 5.5 vs Gemini 4 Neon
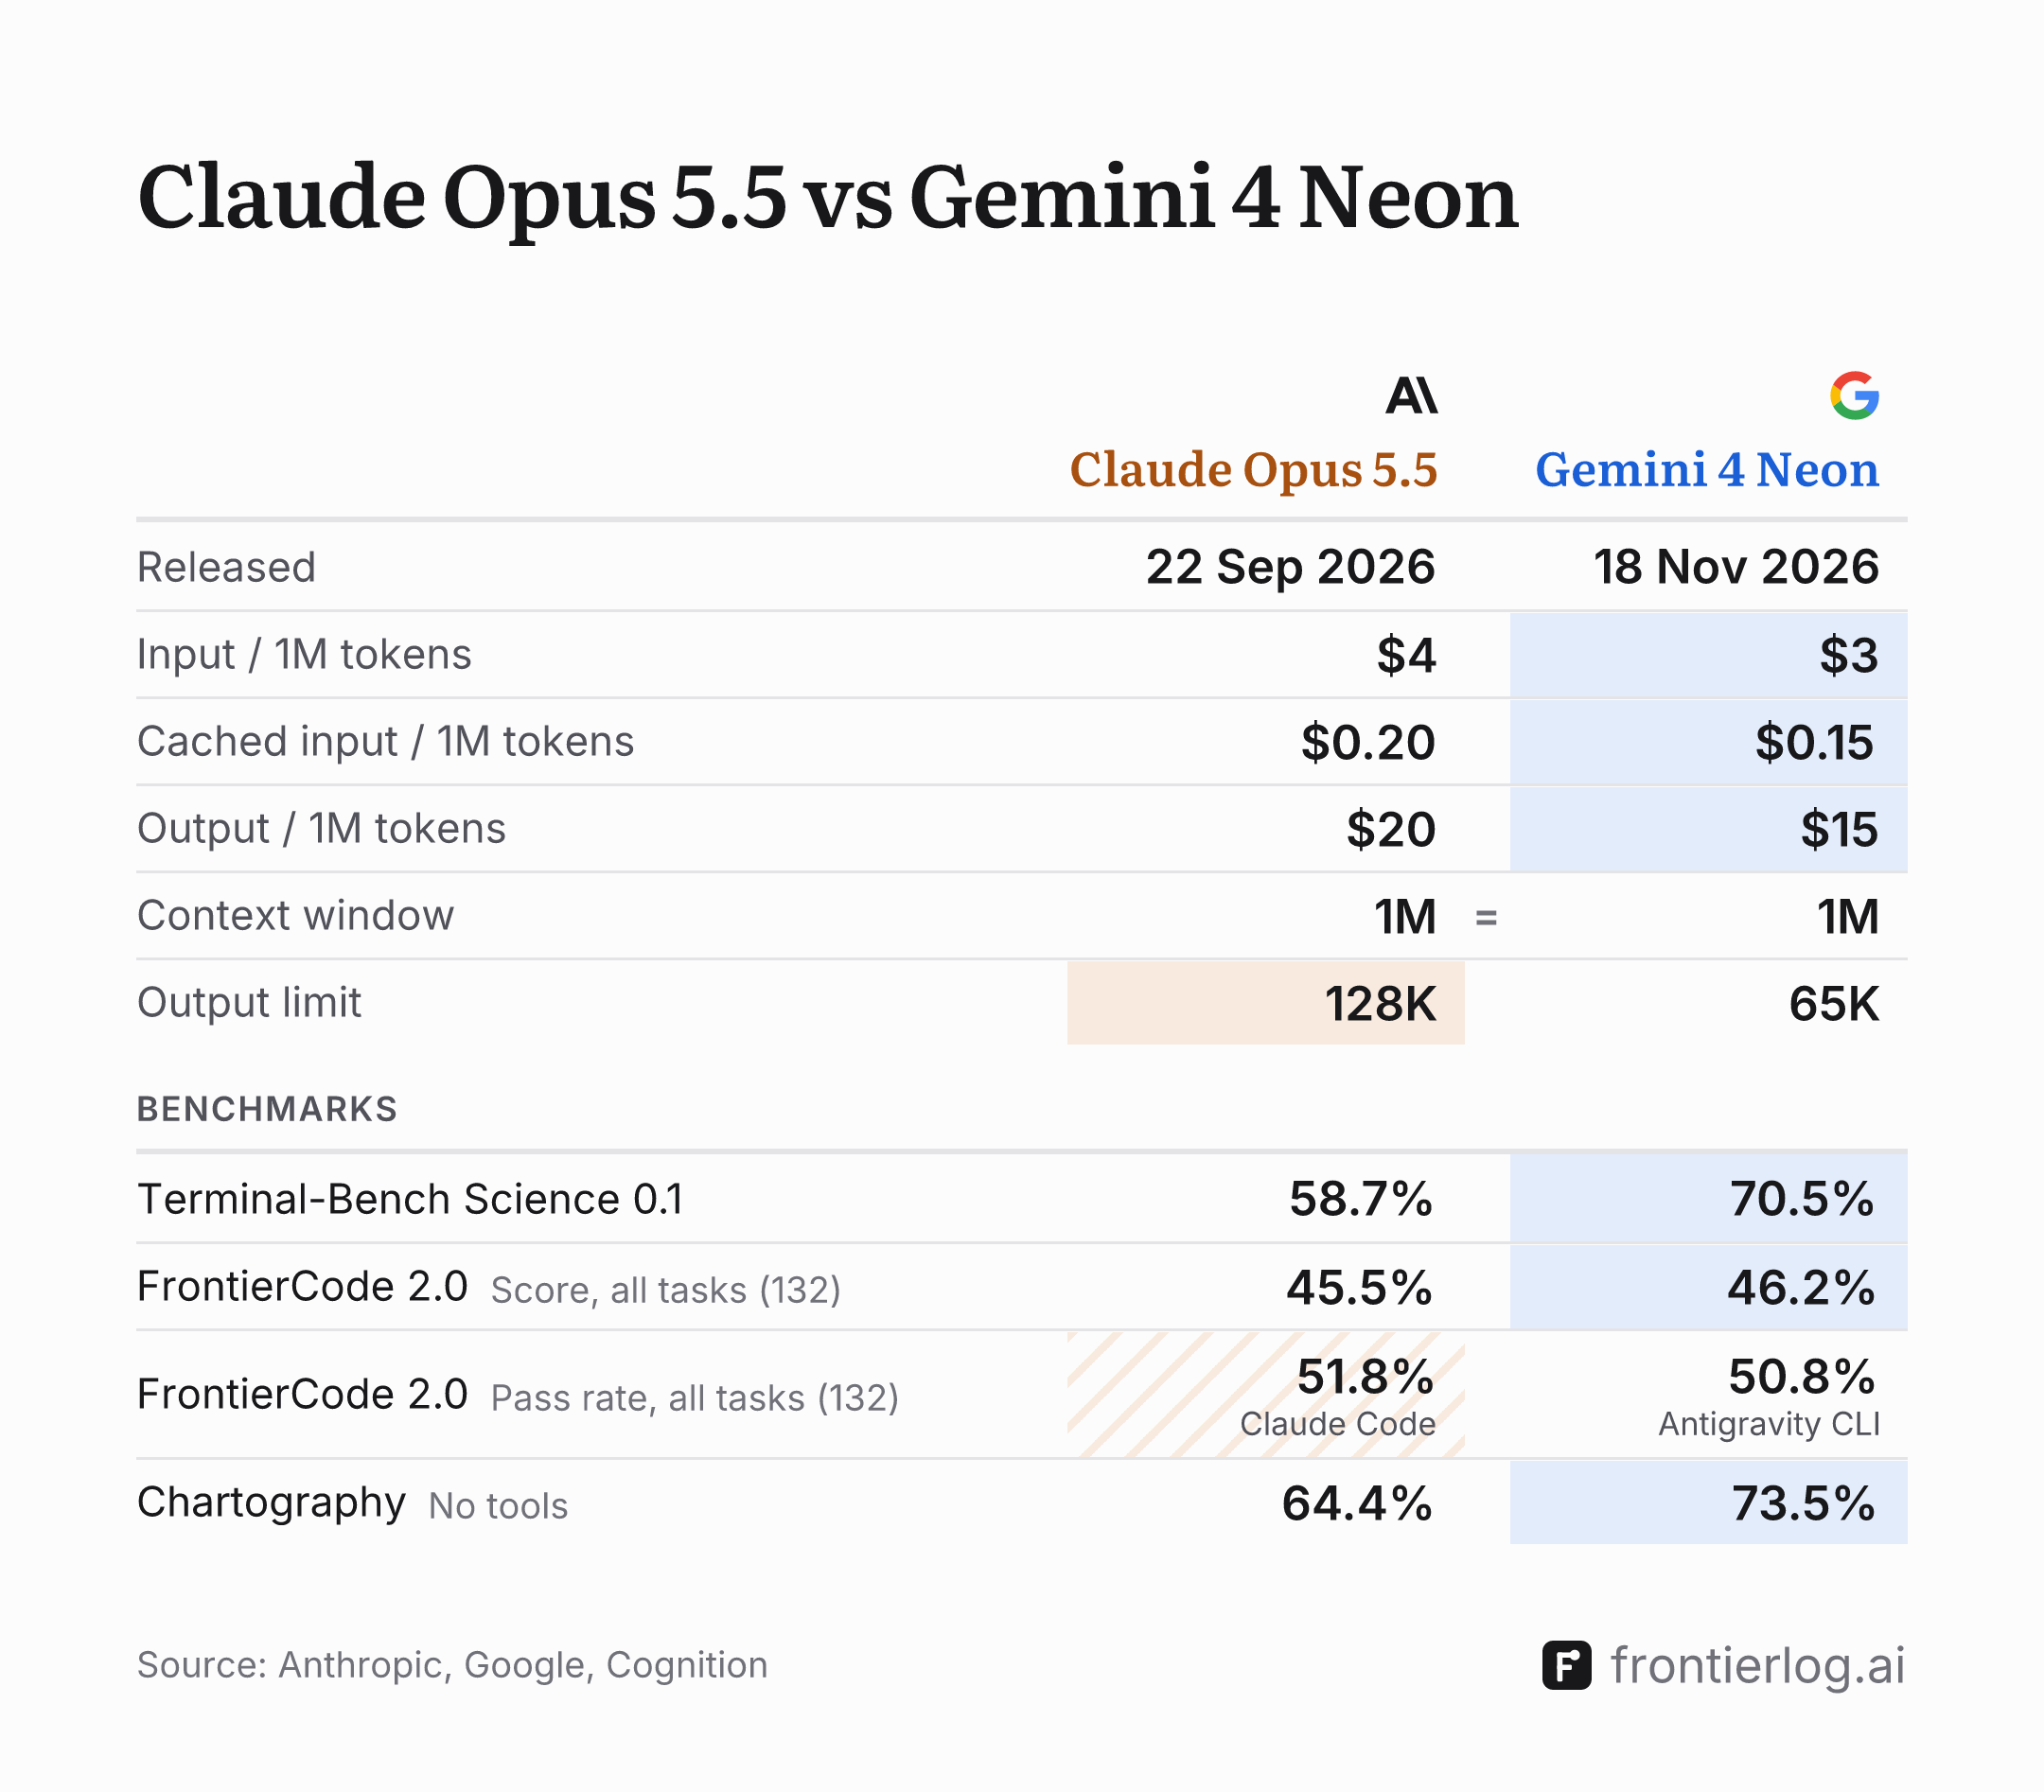
| Claude Opus 5.5 | Gemini 4 Neon | |
|---|---|---|
| Released | ||
| Lineup | Fable › Opus › Sonnet › Haiku | Carbon = Argon › Neon › Hydrogen |
| Input / 1M tokens | $4 | $3 |
| Cached input / 1M tokens | $0.20 | $0.15 |
| Output / 1M tokens | $20 | $15 |
| Context window | 1M | 1M |
| Output limit | 128K | 65K |
| Benchmarks | ||
| Terminal-Bench Science 0.1 | 58.7%1 | 70.5%2 |
| FrontierCode 2.0 Score, all tasks (132) | 45.5%3 | 46.2%4 |
| FrontierCode 2.0 Pass rate, all tasks (132) | 51.8%5Claude Code | 50.8%6Antigravity CLI |
| Chartography No tools | 64.4%7 | 73.5%8 |
| Claude Opus 5.5 | Gemini 4 Neon | |
|---|---|---|
| Other benchmarks | ||
| Humanity's Last Exam No tools, full set (2,500 questions) | 64.4% | No data |
| Humanity's Last Exam With tools, full set (2,500 questions) | 67.7%9 | No data |
| HLE-Diamond No tools | No data | 71.3%10 |
| SWE-bench Pro Set not specified | 89.9%11 | No data |
| Terminal-Bench 4.0 | 66.4%12 | No data |
| Terminal-Bench 4.1 | 65.8%13 | No data |
| AutomationBench 1.0.6 Private set | 40.0%14 | No data |
| AutomationBench, release not specified Private set | No data | 56.3%15 |
| OSWorld 2.1 Full set (108 tasks), partial score | 81.8%16 | No data |
| OSWorld 2.1 Full set (108 tasks), strict pass rate | 48.7%17 | No data |
| OSWorld 2.1 Offline set (82 tasks), partial score | 87.2%18 | No data |
| OSWorld 2.1 Offline set (82 tasks), strict pass rate | 53.2%19 | No data |
| OSWorld 2.0, release not specified Anthropic's Sep 10 files, partial | 81.8%20 | No data |
| OSWorld 2.0, release not specified Anthropic's Sep 10 files, strict | 48.7%21 | No data |
| FrontierCode 1.1 Main set | 54.6%22 | No data |
| FrontierCode 1.1 Extended set | 65.3%23 | No data |
| FrontierSWE v2 | 62.3%24 | No data |
| DeepSWE v1.1 | 74.2%25 | No data |
| Chartography With tools | 89.0%26 | No data |
| SEC-bench Pro 260505 | No data | 90.5%27 |
| Agents' Last Exam v1.1 Score, all tasks (122) | No data | 75.8%28 |
| GraphWalks BFS, 256K + 1M problems | No data | 95.2%29 |
| ExploitGym Mitigations off, score | No data | 48.3%30 |
| ExploitGym Mitigations off, successful exploits | 300 of 86931 | No data |
Notes
- Terminal-Bench Science 0.1, Claude Opus 5.5: max effort · standard error ±3.5 to 5 points
- Terminal-Bench Science 0.1, Gemini 4 Neon: mini-swe-agent vision harness · highest thinking · average of 5 attempts per task
- FrontierCode 2.0, Score, all tasks (132), Claude Opus 5.5: Run by Cognition · Claude Code, per the system card · highest-available effort, max effort in the post's FrontierCode 2.0 chart · mean@5, per the system card · Scored before Cognition updated its cheating scanner to remove false positives and rescored all results on 11 Nov 2026
- FrontierCode 2.0, Score, all tasks (132), Gemini 4 Neon: Run by Cognition · high thinking · set and measure of the official public leaderboard the evaluation methodology cites
- FrontierCode 2.0, Pass rate, all tasks (132), Claude Opus 5.5: Cognition’s leaderboard, 18 Nov 2026 · Claude Code · max effort
- FrontierCode 2.0, Pass rate, all tasks (132), Gemini 4 Neon: Cognition’s leaderboard, 18 Nov 2026 · Antigravity CLI · high effort
- Chartography, No tools, Claude Opus 5.5: max effort · adaptive thinking · average of 5 runs · Gemini 3.5 Flash grader
- Chartography, No tools, Gemini 4 Neon: highest thinking
- Humanity's Last Exam, With tools, full set (2,500 questions), Claude Opus 5.5: max effort
- HLE-Diamond, No tools, Gemini 4 Neon: Run by Artificial Analysis · GPT-5.6 Luna (medium) judge with the official HLE judge prompt, per Artificial Analysis’s methodology
- SWE-bench Pro, Set not specified, Claude Opus 5.5: max effort · adaptive thinking · average of 5 trials
- Terminal-Bench 4.0, Claude Opus 5.5: xhigh effort · standard error ±2.6 points
- Terminal-Bench 4.1, Claude Opus 5.5: Stanford University and Laude Institute’s leaderboard, 18 Nov 2026 · Claude Code · max effort
- AutomationBench 1.0.6, Private set, Claude Opus 5.5: Run by Zapier · without fallback models · set and release 1.0.6 named in the Claude Sonnet 5.5 system card, which prints the same figure
- AutomationBench, release not specified, Private set, Gemini 4 Neon: Run by Zapier · set of the official public leaderboard the evaluation methodology cites
- OSWorld 2.1, Full set (108 tasks), partial score, Claude Opus 5.5: max effort · mean of 5 runs · September 10, 2026 task files · the system card labels it OSWorld 2.0
- OSWorld 2.1, Full set (108 tasks), strict pass rate, Claude Opus 5.5: max effort · mean of 5 runs · September 10, 2026 task files
- OSWorld 2.1, Offline set (82 tasks), partial score, Claude Opus 5.5: max effort · mean of 5 attempts
- OSWorld 2.1, Offline set (82 tasks), strict pass rate, Claude Opus 5.5: max effort · mean of 5 attempts
- OSWorld 2.0, release not specified, Anthropic's Sep 10 files, partial, Claude Opus 5.5: max effort · mean of 5 runs
- OSWorld 2.0, release not specified, Anthropic's Sep 10 files, strict, Claude Opus 5.5: max effort · mean of 5 runs
- FrontierCode 1.1, Main set, Claude Opus 5.5: Run by Cognition · Claude Code harness · medium effort
- FrontierCode 1.1, Extended set, Claude Opus 5.5: Run by Cognition · Claude Code harness · medium effort
- FrontierSWE v2, Claude Opus 5.5: Run by Proximal · Proximal's agent harness · highest available effort · mean of 5 trials per task, per the system card · 20-hour budget · safeguards on
- DeepSWE v1.1, Claude Opus 5.5: average of 5 trials
- Chartography, With tools, Claude Opus 5.5: max effort · adaptive thinking
- SEC-bench Pro 260505, Gemini 4 Neon: Antigravity harness · pass@1, mean of 3 attempts · 183-task JavaScript engine split (May 2026) · LLM judge for crashes in both builds · safety filters off
- Agents' Last Exam v1.1, Score, all tasks (122), Gemini 4 Neon: Antigravity-CLI version 1.4.8 harness · highest thinking · 5-hour window · safety filters on
- GraphWalks, BFS, 256K + 1M problems, Gemini 4 Neon: highest thinking · 200 problems between 256K and 1M tokens
- ExploitGym, Mitigations off, score, Gemini 4 Neon: Antigravity harness · single attempt per task · no internet access · 10h time cap per task · safety filters off · mitigations off (the default setting), per the model evaluation
- ExploitGym, Mitigations off, successful exploits, Claude Opus 5.5: 6h wall-clock budget · agent judge confirms the intended vulnerability