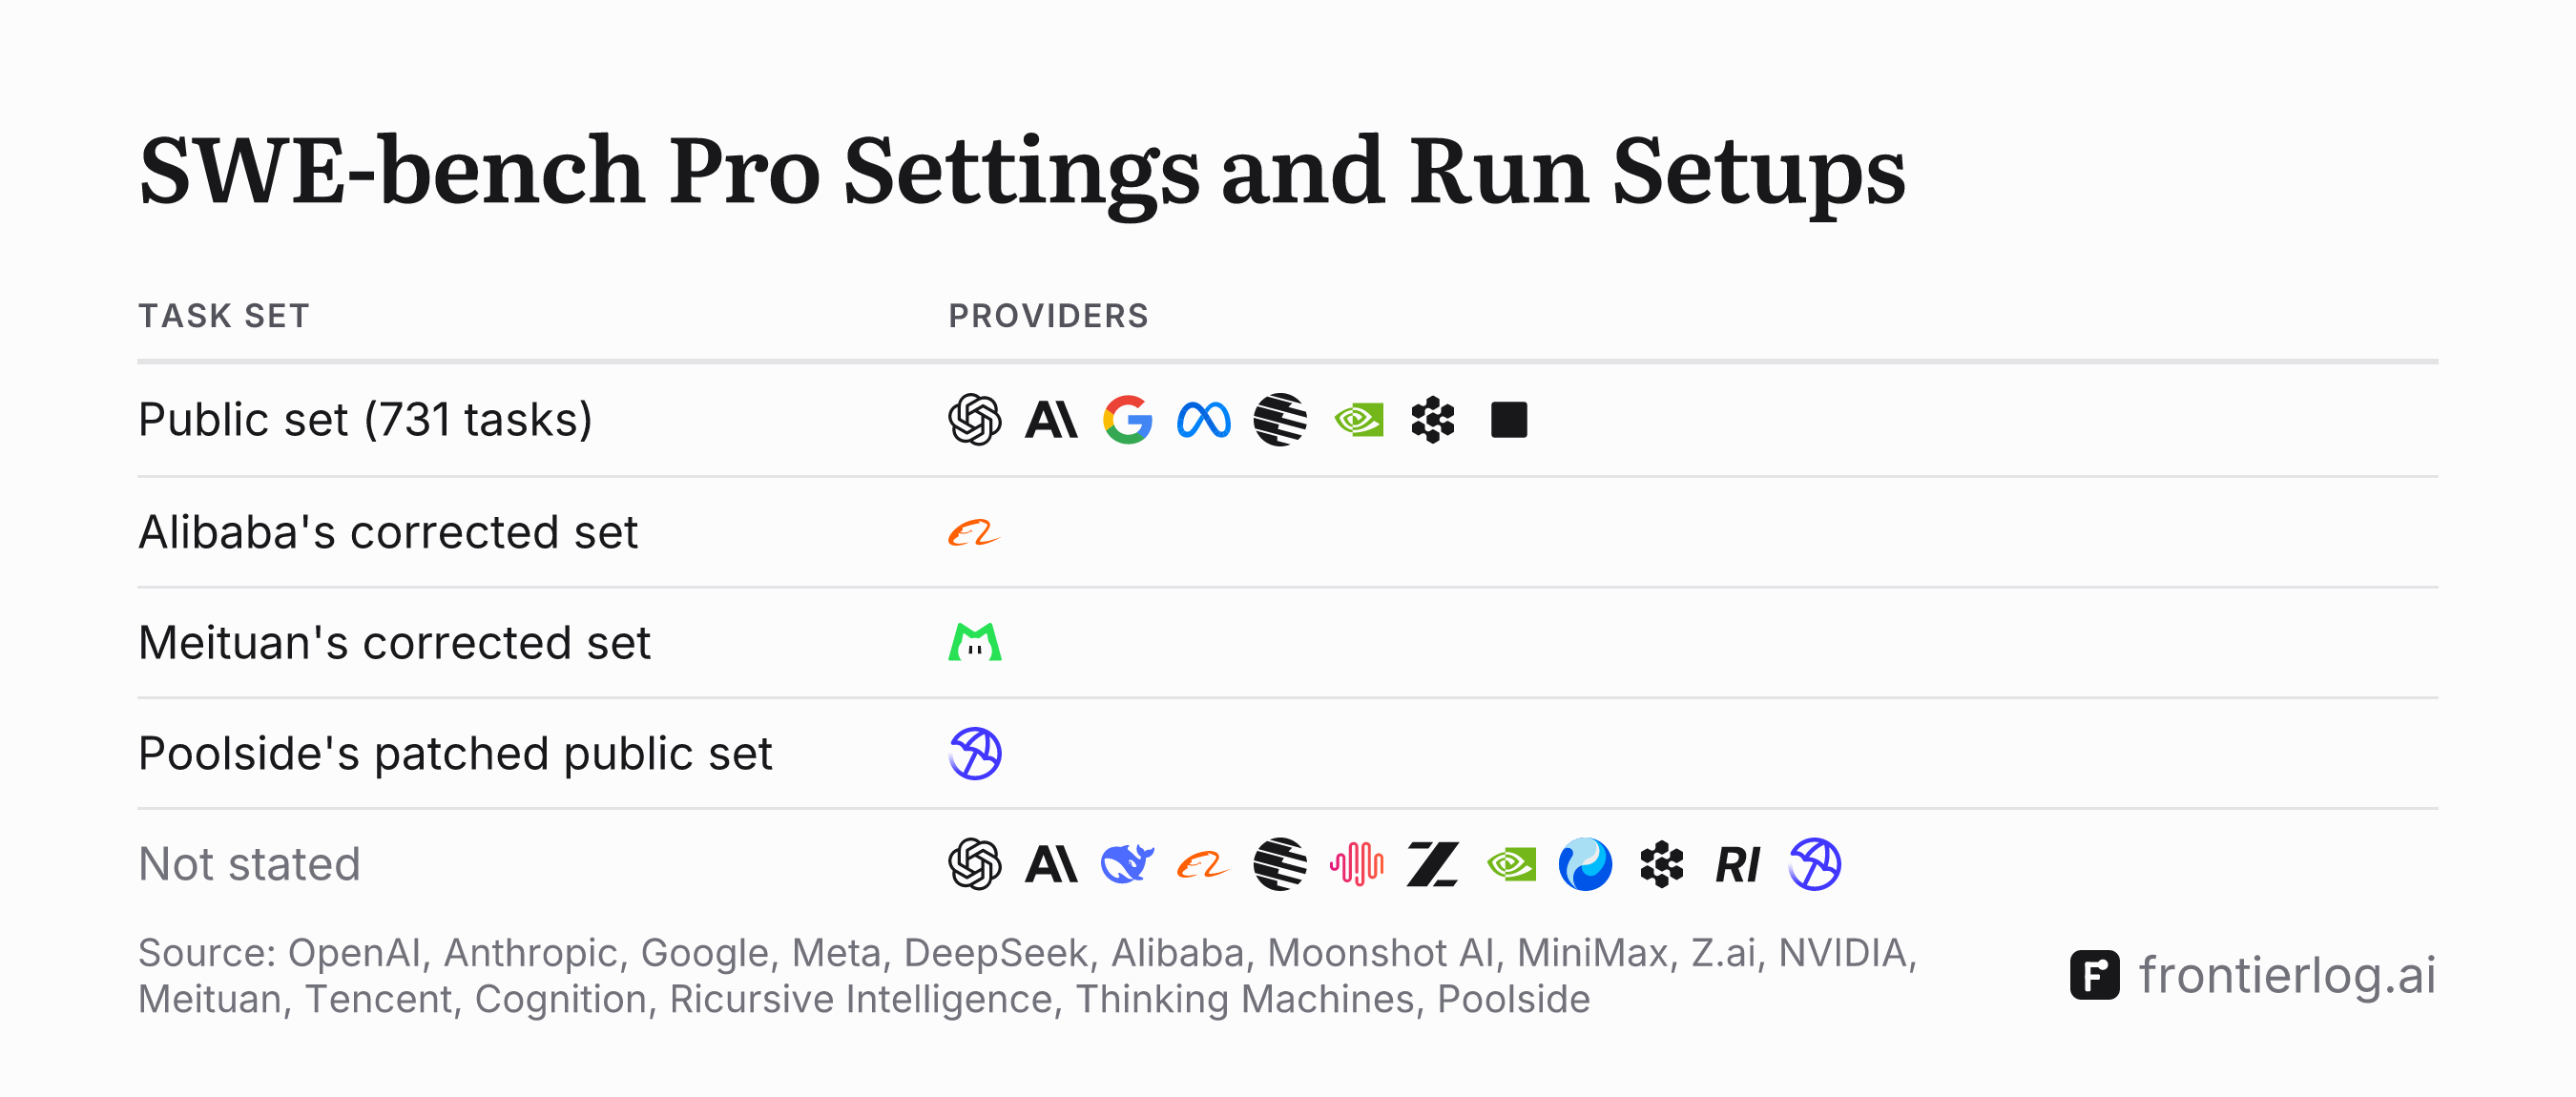
Long context update: Laguna XS.2 and M.1Corroborated The same number is printed in 1 other lab document: 1poolside harness on Harbor · pass@1 averaged over 3 runs · some task images patched · public set per the model card · reported laterOur capture
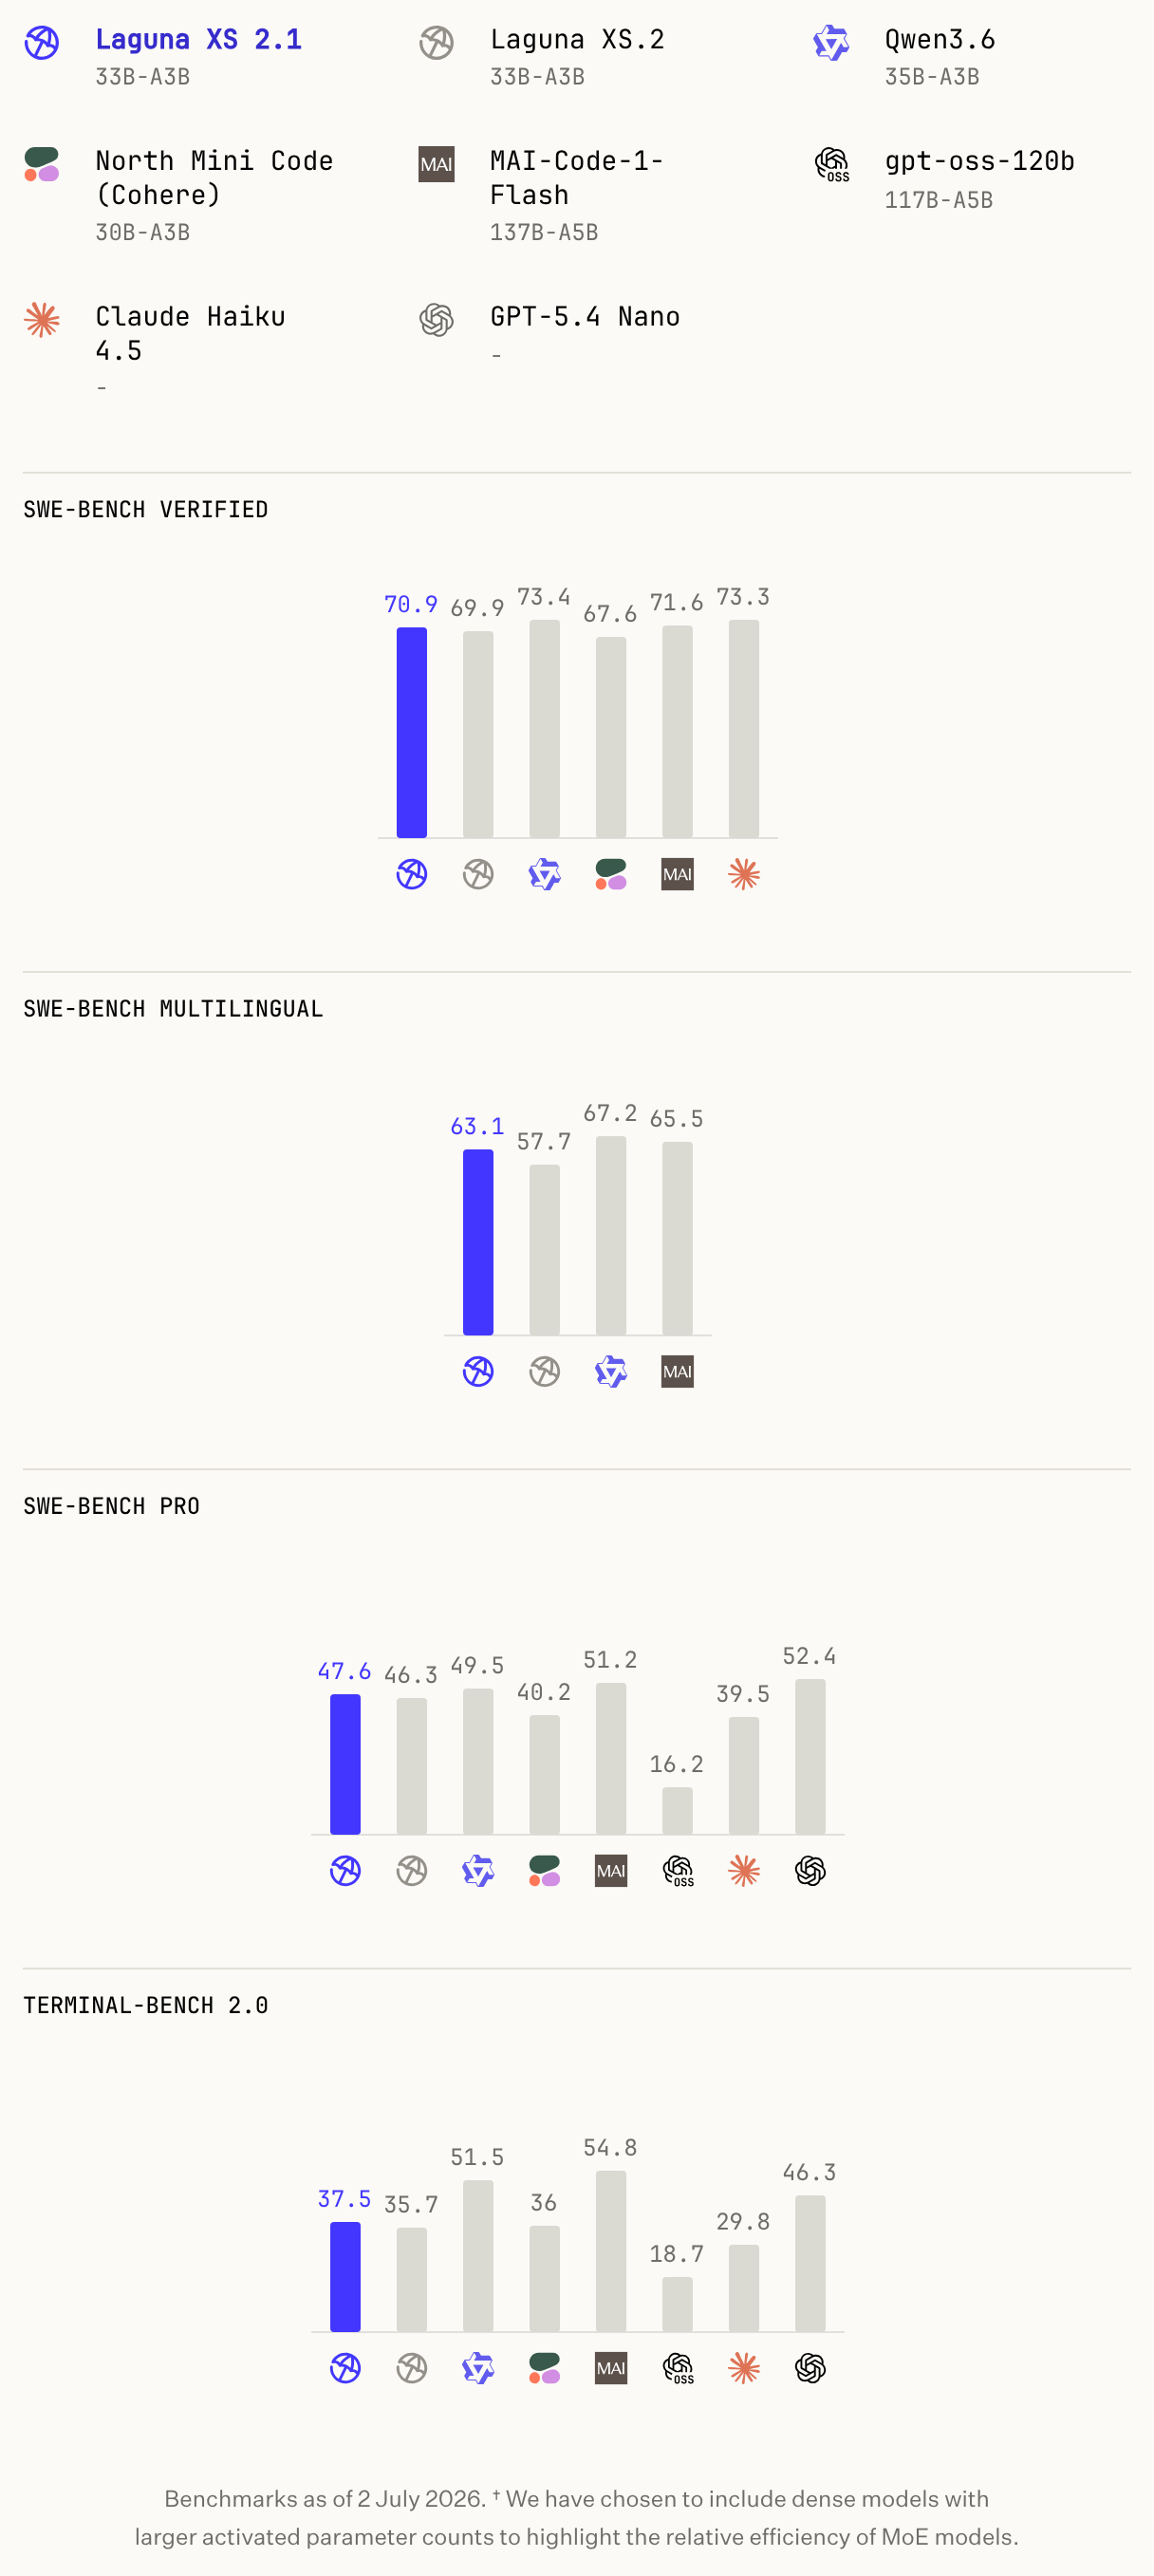
Introducing Laguna XS 2.1Checked A person checked this number against its source on 17 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.poolside harness on Harbor · pass@1 averaged over 2 attempts · some task images patched · public set per the model cardOur capture
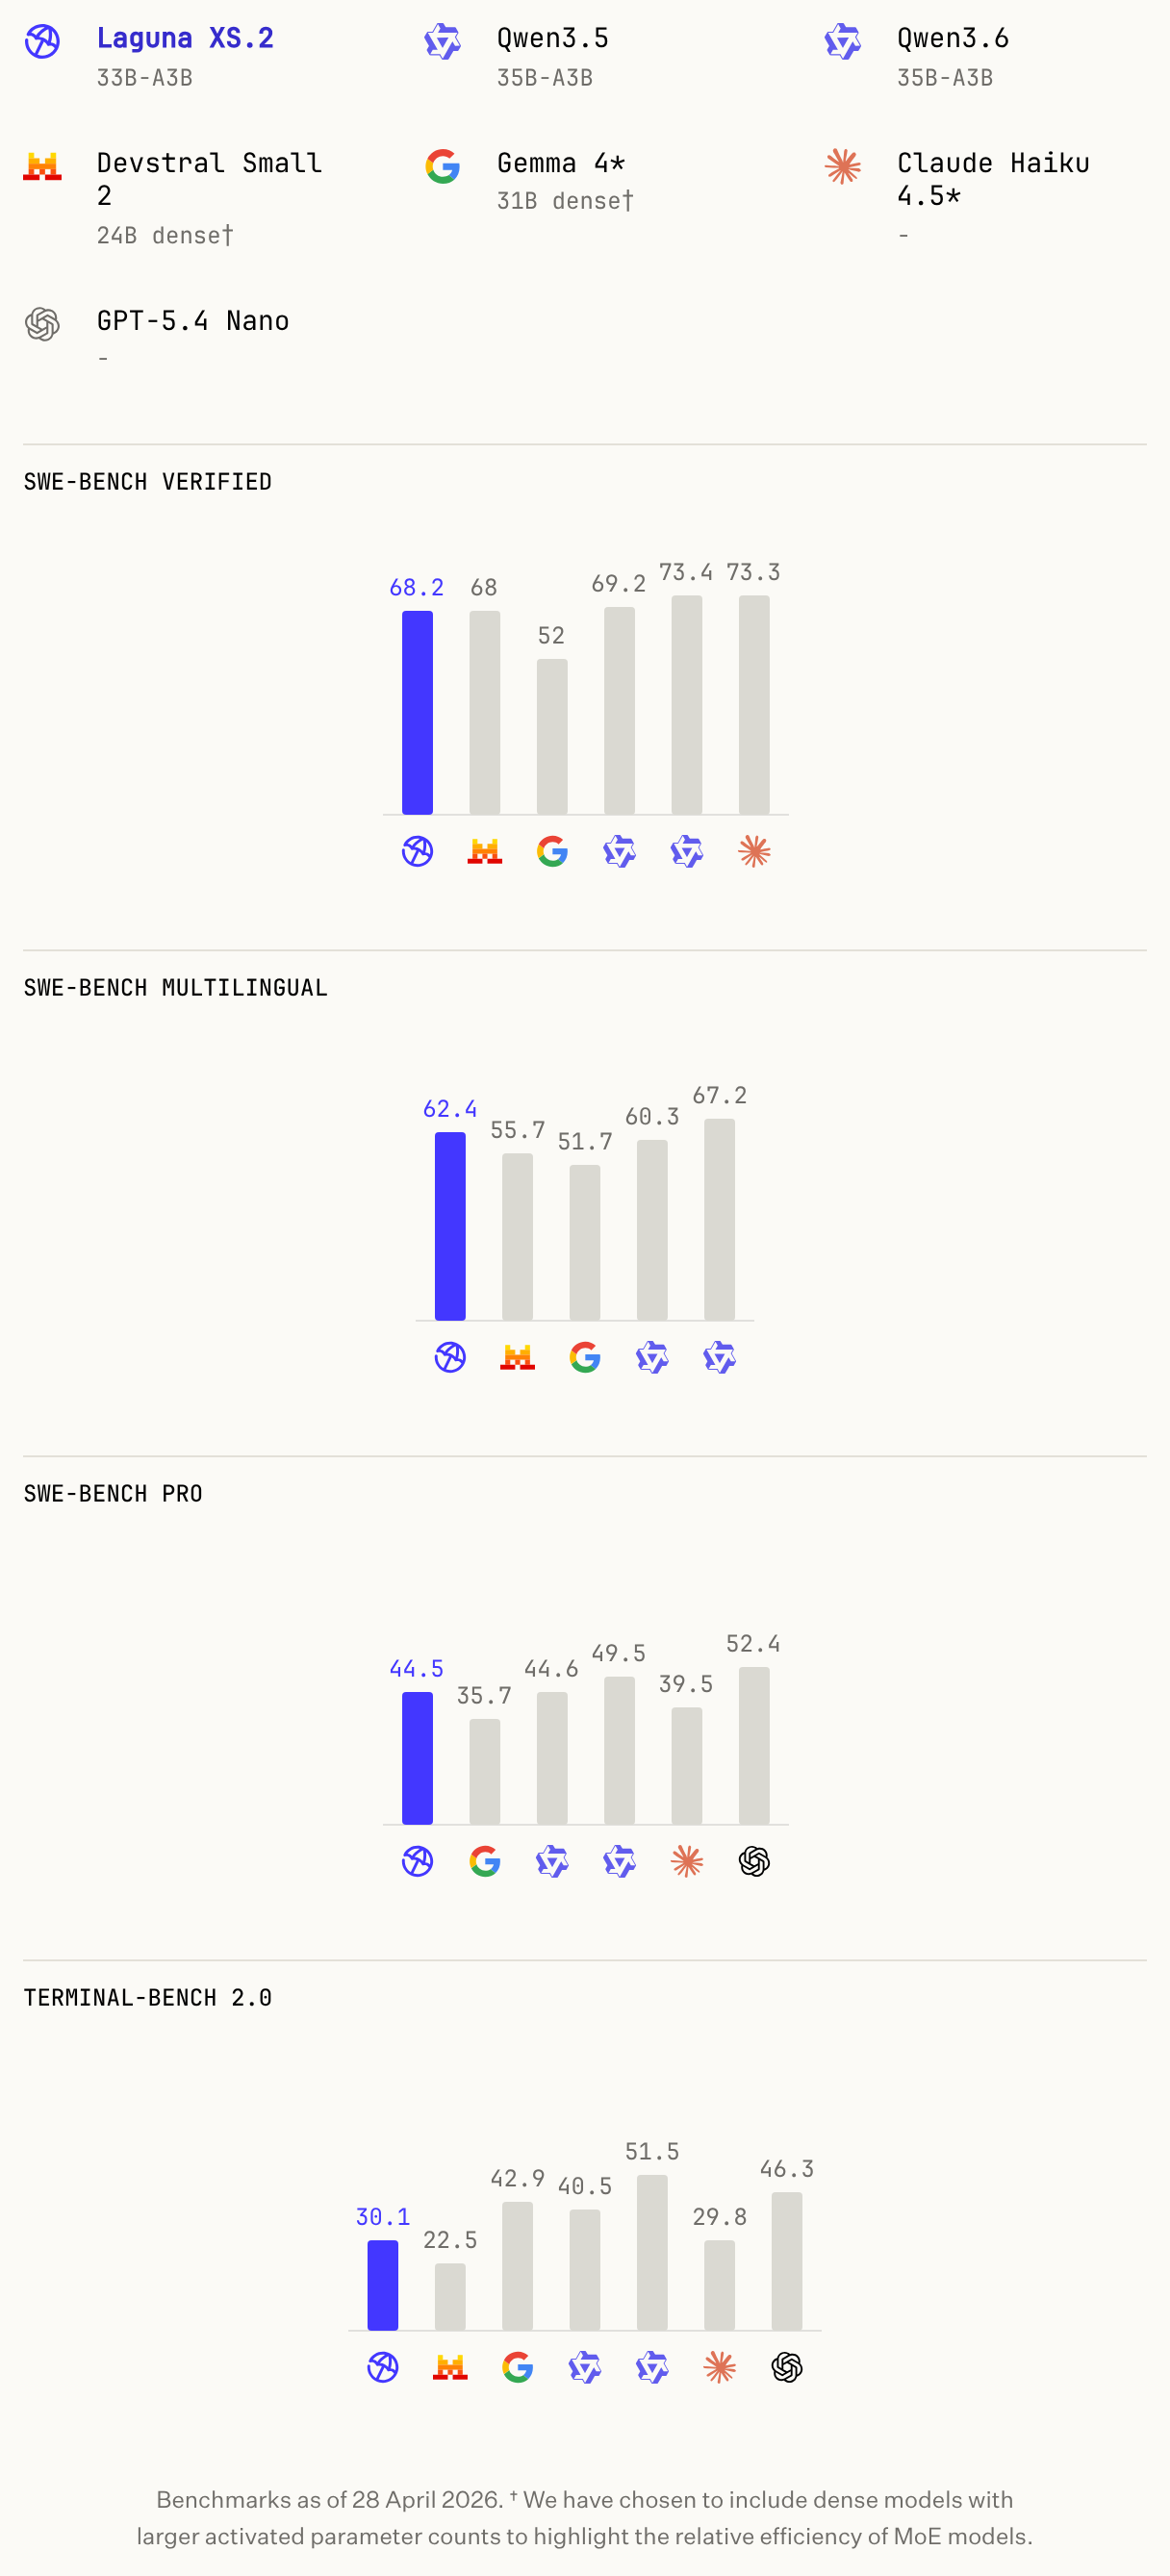
Introducing Laguna XS.2 and Laguna M.1Corroborated The same number is printed in 1 other lab document: 1poolside harness on Harbor · pass@1 averaged over 3 runs · some task images patched · public set per the model cardOur capture
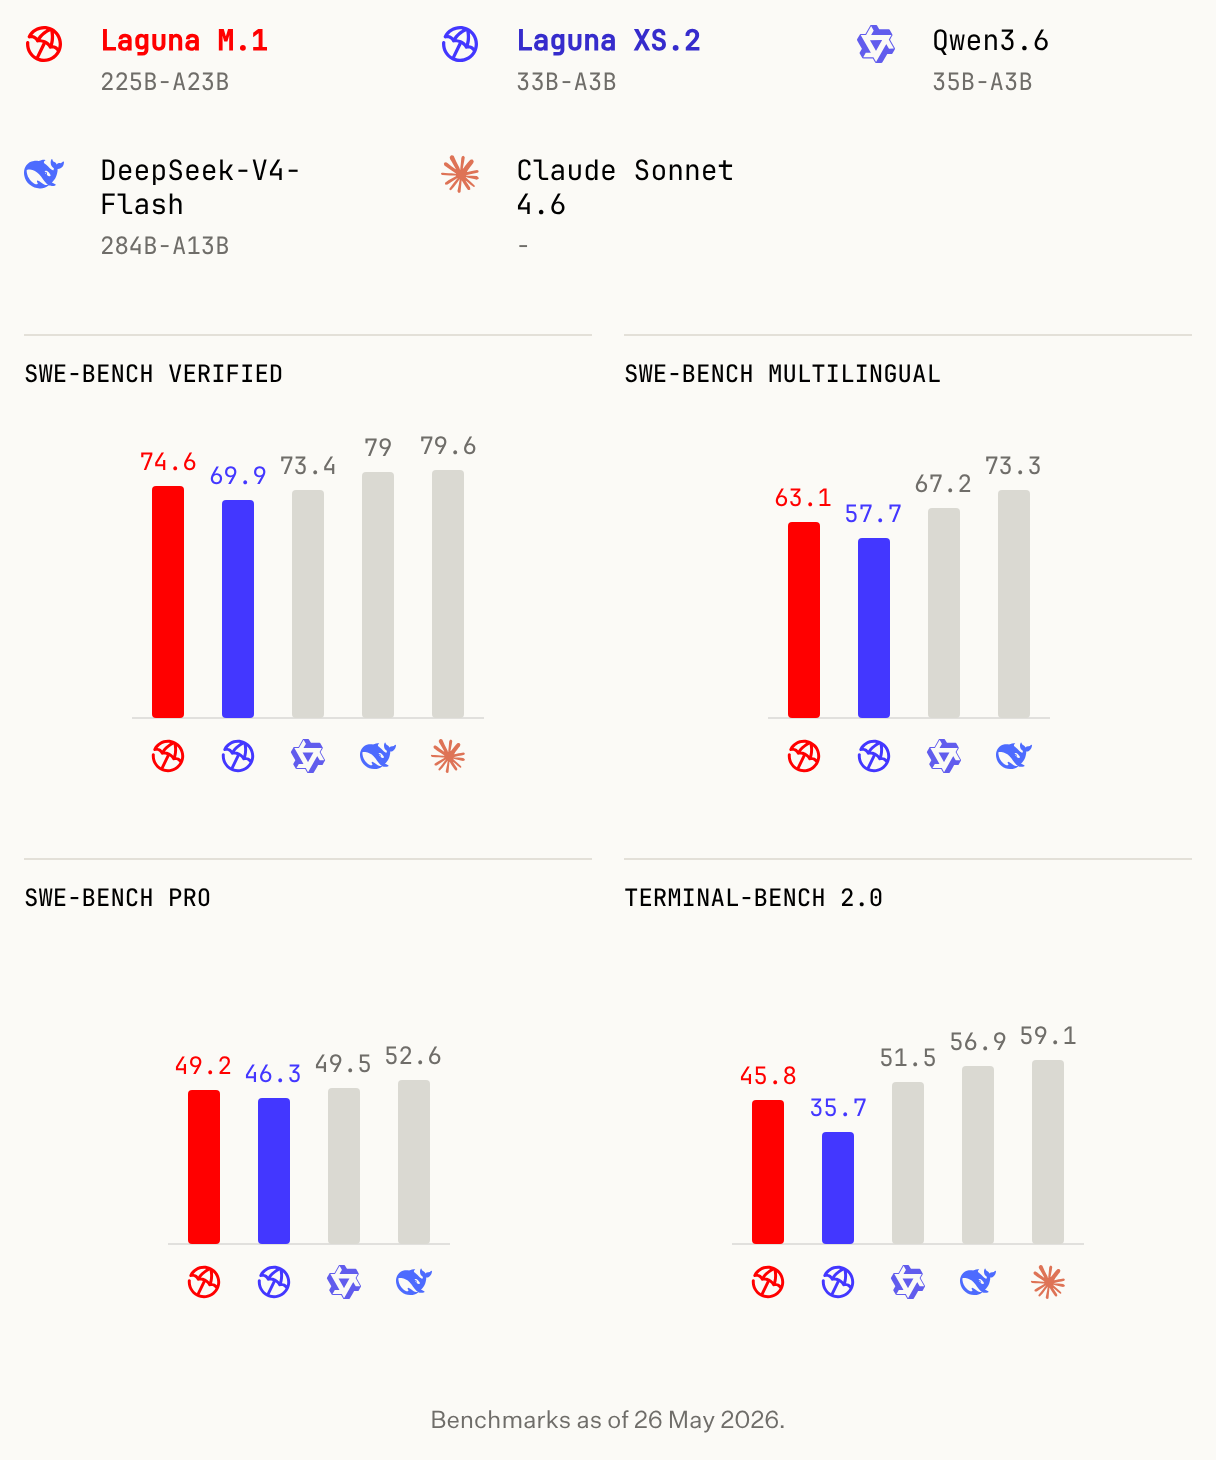
Long context update: Laguna XS.2 and M.1Corroborated The same number is printed in 2 other lab documents: 12poolside harness on Harbor · pass@1 averaged over 3 runs · some task images patched · public set per the model card · reported later · another report, not chartedOur capture