Frontier Log

Benchmark · Active

SWE-bench Pro

Created by Scale AI, 19 Sep 2025 · Higher is better · Website

0204060Jul 202659.5%LongCat-2.00204060Jul 202659.5%LongCat-2.0

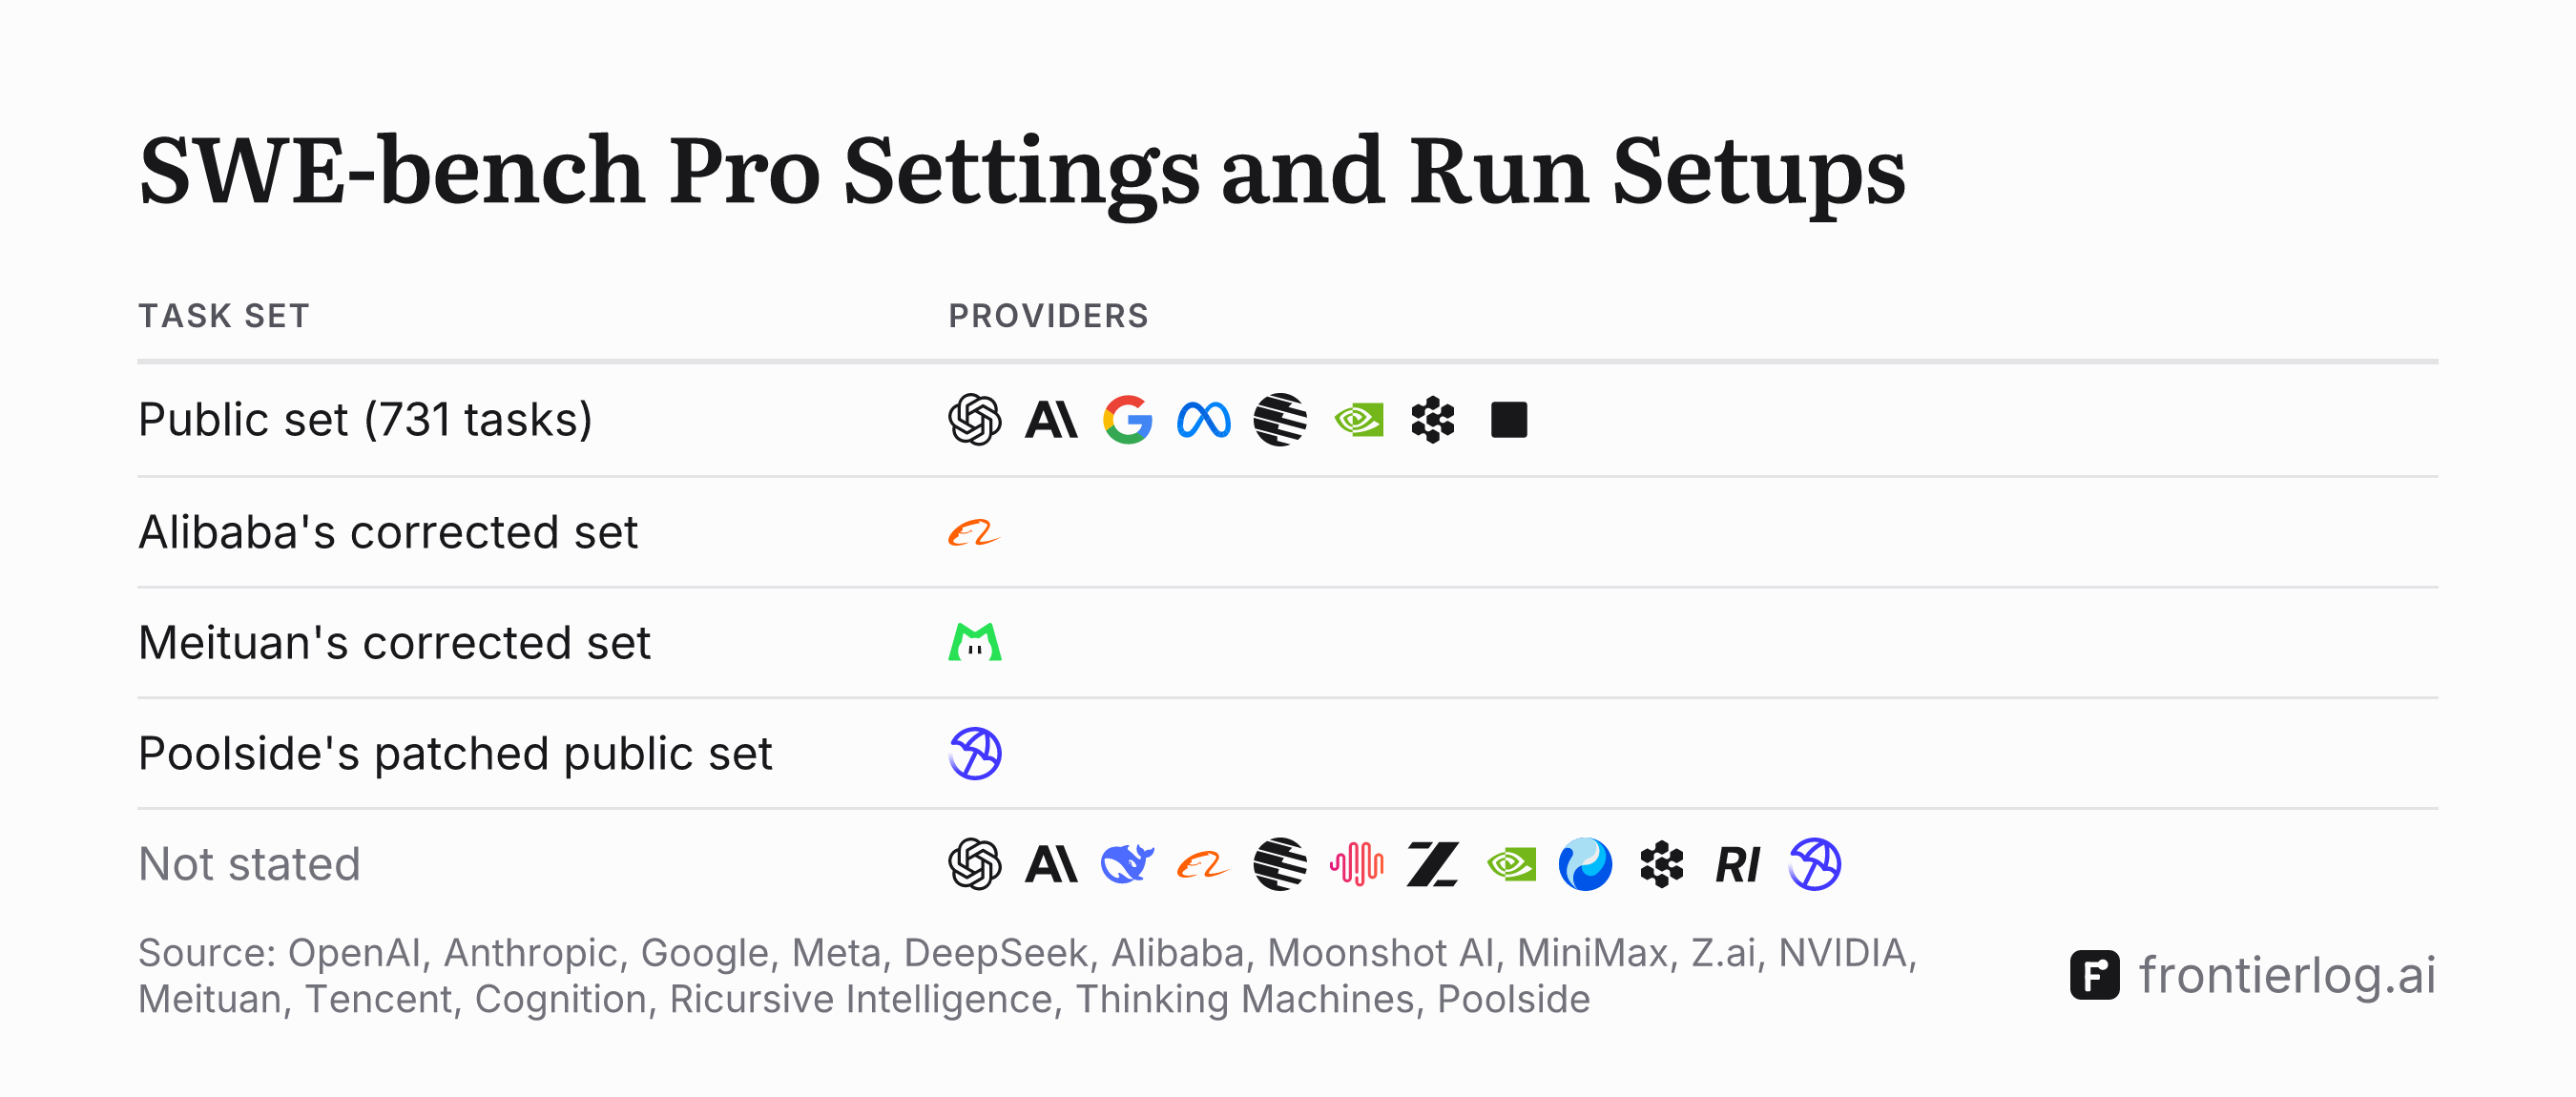
Settings and run setups

Task setProviders
Public set (731 tasks)OpenAIAnthropicGoogleMetaMoonshot AINVIDIACognitionThinking Machines
Alibaba's corrected setAlibaba
Meituan's corrected setMeituan
Poolside's patched public setPoolside
Not statedOpenAIAnthropicDeepSeekAlibabaMoonshot AIMiniMaxZ.aiNVIDIATencentCognitionRicursive IntelligencePoolside

Download image

Results

ModelScoreSource
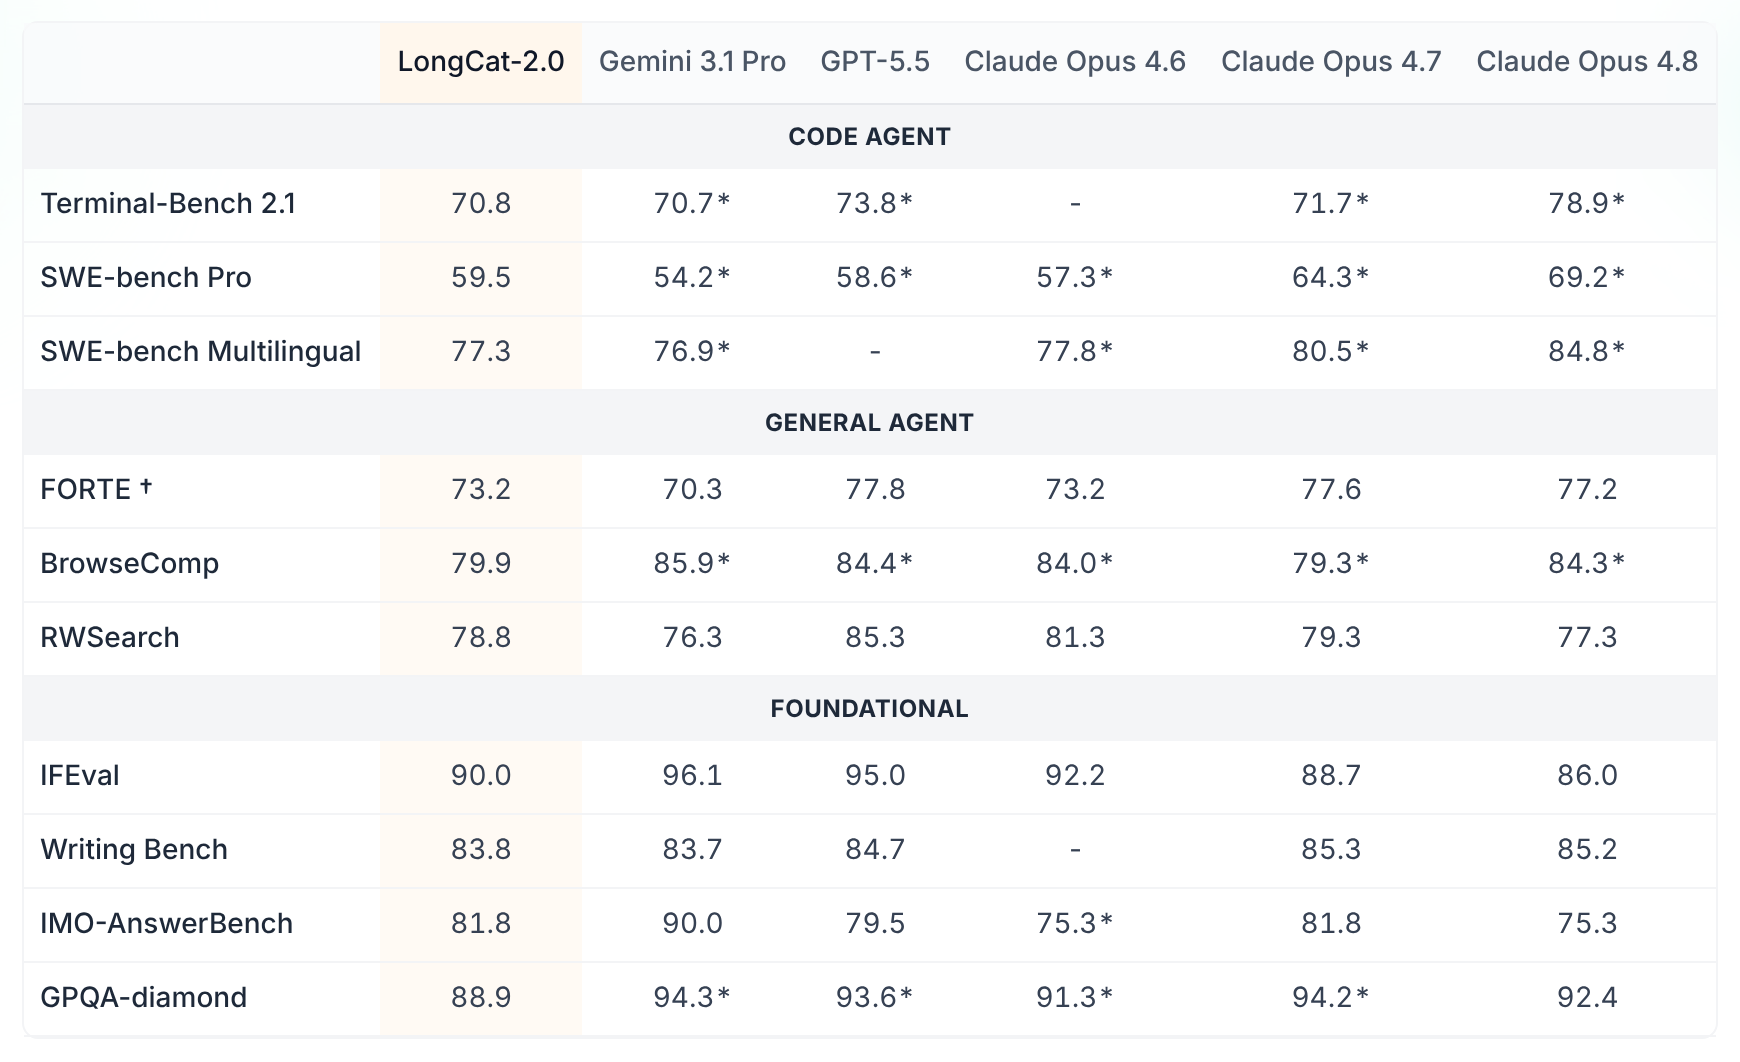
LongCat-2.030 Jun 202659.5%Introducing LongCat-2.0Checked A person checked this number against its source on 23 Oct 2026. This confirms the number matches what the lab published. It doesn't confirm that the score was reproduced.Corroborated The same number is printed in 2 other lab documents: 1 2Claude Code harnessOur capture

All benchmarks