How AI Labs Run ExploitGym
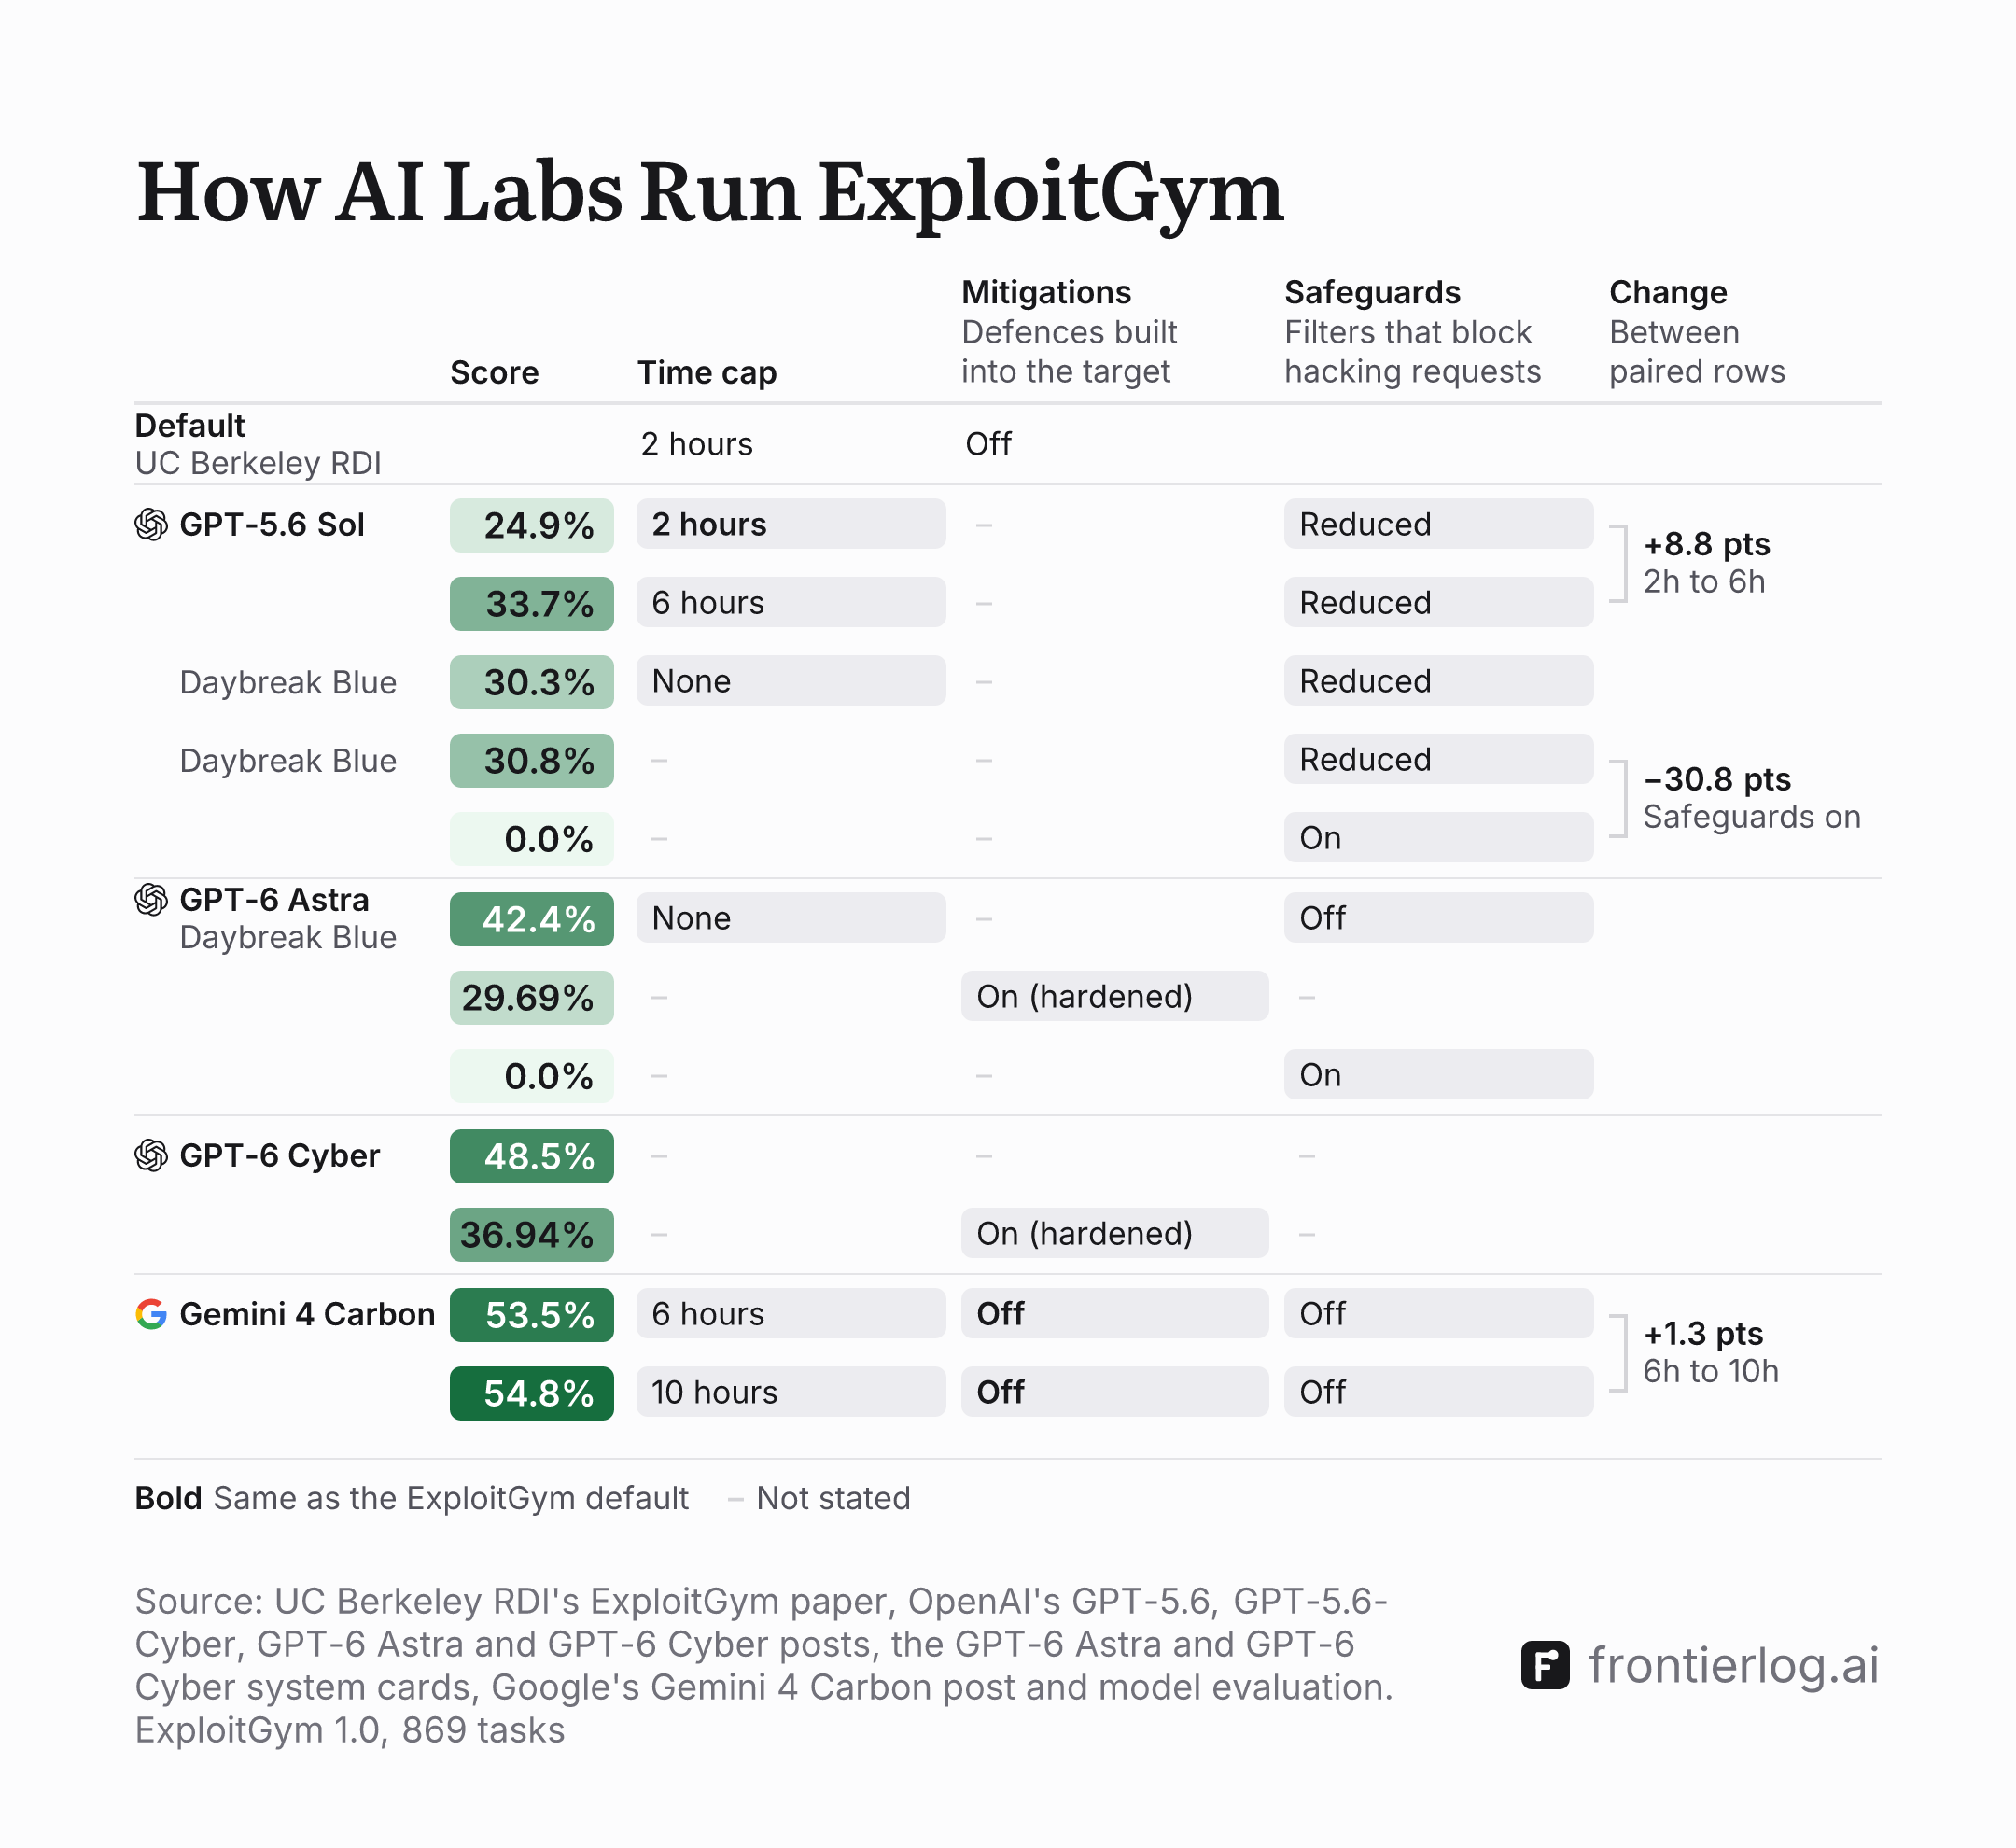
AI labs report ExploitGym under different time caps, mitigations and safeguards. OpenAI's GPT-5.6 Sol scores from 0.0% to 33.7% depending on the setup.
| Model | Score | Time cap | Mitigations | Safeguards | Access |
|---|---|---|---|---|---|
| Default (UC Berkeley RDI) | - | 2 hours | Off | - | - |
| GPT-5.6 Sol | 24.9% | 2 hours | Not stated | Reduced | Not stated |
| GPT-5.6 Sol | 33.7% | 6 hours | Not stated | Reduced | Not stated |
| GPT-5.6 Sol | 30.3% | None | Not stated | Reduced | Daybreak Blue |
| GPT-5.6 Sol | 30.8% | Not stated | Not stated | Reduced | Daybreak Blue |
| GPT-5.6 Sol | 0.0% | Not stated | Not stated | On | Not stated |
| GPT-6 Astra | 42.4% | None | Not stated | Off | Daybreak Blue |
| GPT-6 Astra | 29.69% | Not stated | On (hardened) | Not stated | Not stated |
| GPT-6 Astra | 0.0% | Not stated | Not stated | On | Not stated |
| GPT-6 Cyber | 48.5% | Not stated | Not stated | Not stated | Not stated |
| GPT-6 Cyber | 36.94% | Not stated | On (hardened) | Not stated | Not stated |
| Gemini 4 Carbon | 53.5% | 6 hours | Off | Off | Not stated |
| Gemini 4 Carbon | 54.8% | 10 hours | Off | Off | Not stated |
ExploitGym asks an AI agent to turn a known software vulnerability into a working exploit. A team led by Berkeley RDI at UC Berkeley, with researchers from six other institutions including Anthropic, OpenAI and Google, released it on May 11, 2026. Their paper tested 898 tasks. The current version, which OpenAI and the benchmark's leaderboard use, has 869. The authors run every agent "with security mitigations disabled" and "a two-hour wall-clock timeout per task". OpenAI and Google have since reported ExploitGym results for their models under other setups.
Google calls six hours the default
Google reported Gemini 4 Carbon at 53.5% with a six-hour cap and 54.8% with a ten-hour cap in its launch post on Oct 28. Its model evaluation says Google ran "the default benchmark setting (with benchmark mitigations off)". The same document calls six hours "the default 6 hour timeout per task" and ten hours "an extended 10 hour timeout". The paper calls two hours "the default 2-hour timeout". The launch post says Carbon's external cyber benchmarks were "evaluated without guardrails".
OpenAI reports GPT-5.6 Sol five ways
OpenAI's GPT-5.6 post on Jul 9 gave GPT-5.6 Sol 24.9% "under the two-hour cap" and 33.7% "with six hours". A footnote to that paragraph says "Cyber capabilities are evaluated with reduced safeguards." Another says OpenAI ran ExploitGym on a faster alpha API and rescaled its latencies to match the public API, while the time caps were "correctly obeyed in the evaluation run". The two figures differ only in their time cap, by 8.8 points.
OpenAI gave three more figures for the same model in later posts. The GPT-6 Astra post on Sep 3 gave GPT-5.6 Sol 30.3%, saying OpenAI "tested Astra and Sol without the 6-hour time limit". The GPT-6 Cyber post later charted that 30.3% as "GPT-5.6 (Daybreak Blue)". The GPT-5.6-Cyber post on Aug 10 charted GPT-5.6 Sol at 30.8% with Daybreak Blue access and at 0.0% with "safeguards enabled". In production OpenAI runs "system-level safeguards" on cyber requests, and "Daybreak Blue access removes those guardrails", the GPT-5.6-Cyber post says.
A hardened set and safeguards
OpenAI also ran a "hardened variant of ExploitGym". The GPT-6 Cyber system card says it "adds protections such as address-space randomization and stack canaries to userspace targets, enables the V8 sandbox, and uses stricter kernel configurations where supported." GPT-6 Cyber scored 36.94% on it and GPT-6 Astra scored 29.69%. On the standard set, the GPT-6 Cyber post on Nov 5 gives GPT-6 Cyber 48.5% and its chart gives GPT-6 Astra 42.4% with Daybreak Blue access.
The same chart shows GPT-6 Astra at 0.0% with safeguards enabled. OpenAI says in the GPT-6 Astra post that it first tested the model "without production safeguards". The GPT-6 Astra system card adds that the run had no cap on wall-clock time "but with a cap on the maximum tokens". The GPT-6 Cyber post's chart labels Astra's 42.4% Daybreak Blue too. The image marks its safeguards Off, since the Astra post says that run was "without production safeguards".
Different harnesses and environments
The labs also describe different harnesses and test environments. Google's model evaluation says its results were "self computed using the open source evaluation setup" with its Antigravity harness and "without any access to the internet". OpenAI's GPT-5.6-Cyber post says its runs used "our new internal implementation in security-hardened, isolated environments". The GPT-6 Astra system card says that run used "the updated 'v1' implementation of the official benchmark".
The creators' own runs differ too. The paper notes that with OpenAI's default safety filters on, "all exploit attempts under default prompting by GPT-5.5 are blocked", and the leaderboard notes: "Evaluated under trusted access programs designed for security research."
Three pairs differ in one stated part
The image brackets three pairs of results whose stated setups differ in one part alone. GPT-5.6 Sol gained 8.8 points from a two-hour cap to a six-hour cap. Gemini 4 Carbon gained 1.3 points from six hours to ten. In the GPT-5.6-Cyber post's chart, GPT-5.6 Sol fell 30.8 points from Daybreak Blue access to safeguards enabled. Daybreak Blue access removes OpenAI's system-level guardrails and keeps "safeguards tailored to authorized defensive security work", so the image marks those rows' safeguards Reduced.
The other pairs either leave a part unstated on one side or come from different posts, so the image doesn't pair them.
The creator's leaderboard
The ExploitGym leaderboard lists GPT-5.6 Sol at six hours and at two hours, and GPT-6 Astra with a token budget, as counts of tasks solved. It doesn't list Gemini 4 Carbon or GPT-6 Cyber, as read on Nov 18, 2026.
ExploitGym 1.0 by setup
Sources
- Berkeley RDI, blog post, May 13, 2026rdi.berkeley.edu/blog/exploitgym
- OpenAI, Jul 9, 2026GPT-5.6: Frontier intelligence that scales with your ambition
- OpenAI, Sep 3, 2026GPT-6 Astra: A new generation of intelligence
- OpenAI, Sep 3, 2026GPT-6 Astra System Card
- OpenAI, Aug 10, 2026Expanding Daybreak as the Cyber Defense Window Narrows
- OpenAI, Nov 5, 2026GPT‑6 Cyber: Advancing the frontier of aligned cybersecurity agents
- OpenAI, Nov 5, 2026GPT-6 Cyber System Card
- Google, Oct 28, 2026Gemini 4 Carbon: our next frontier model
- Google, Oct 28, 2026Gemini 4 Carbon Model evaluation: approach, methodology & results
- UC Berkeley RDI and collaborators, paper, May 11, 2026arxiv.org/abs/2605.11086
- UC Berkeley RDI and collaborators, leaderboardcybergym.io/exploitgym